
目录
I. Higher Peak Compute Does Not Guarantee More Completed Work
II. Training, Inference, and Agent Workloads Move Three Distinct Types of Data
III. Working Memory and Persistent Storage Serve Different Purposes
IV. Persistent Storage Creates Value Through Continuous Data Delivery, Not Capacity Alone
V. Scale-Up and Scale-Out Address Different Communication Requirements
VI. The Copper–Optics Boundary Is Determined by System Cost
VII. Pluggables, LPO, CPO, and Optical I/O Will Mature at Different Rates
VIII. Profit Pools Will Shift with Bottlenecks, but Revenue Will Materialize in Stages
IX. Three Scenarios Will Determine the Durability of Data-Movement Investment
X. Ten Public Metrics to Track
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
Chip peak performance continues to rise, but system throughput increasingly depends on whether data arrives on time. HBM, persistent storage, and interconnects are jointly defining the efficiency frontier of AI infrastructure.
I. Higher Peak Compute Does Not Guarantee More Completed Work
AI infrastructure is entering an era dominated by system efficiency. An accelerator converts transistors into useful throughput only when data is available to its compute units. If weights have not been loaded, activations are not ready, gradients are still being synchronized, the KV Cache cannot be read in time, or checkpoints have not yet been written back, additional peak compute merely increases the amount of hardware left waiting.
Generational advances in AI hardware have traditionally been measured by floating-point operations per second. This remains important, but it captures how much computation a chip can perform—not whether data can arrive on time. Real workloads span four layers: persistent storage supplies datasets and model files; DDR and CXL provide a larger-capacity intermediate tier; HBM feeds high-bandwidth data to compute cores; and networks synchronize accelerators and transfer results. If any layer falls behind, theoretical compute capacity cannot be fully realized.
This makes “effective system throughput” a more informative metric: the number of training steps, inference requests, or Agent tasks actually completed per unit of time. Compute, memory, storage, networking, and software scheduling collectively determine this outcome. Their contributions are not simply additive—the slowest segment creates waiting time, forcing the rest of the hardware either to operate at lower utilization or to rely on additional caching.
The time required to complete a task can be decomposed into compute time, memory service time, storage service time, communication time, and scheduling overhead. Some stages can overlap—for example, the next batch can be prefetched while the current batch is being processed. Final throughput is determined by the longest path that cannot be hidden. Adding GPUs shortens only compute time; if data supply and communication remain unchanged, the system becomes increasingly memory- or I/O-bound.
Arithmetic intensity helps identify the bottleneck by measuring how much computation can be performed per byte transferred. Matrix multiplication generally has high arithmetic intensity and can utilize compute cores more fully. Embedding lookups, KV Cache reads, MoE expert routing, and sparse accesses are more bandwidth-sensitive. Changes in model architecture therefore alter hardware requirements, and neither parameter count nor token volume alone provides a complete answer.
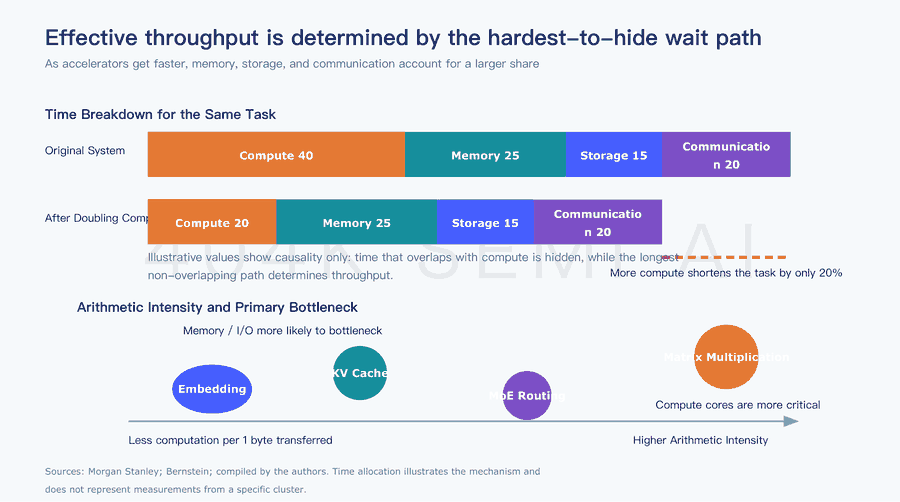
An effective-throughput model requires at least four sets of inputs. Compute variables include chip count, precision, and actual utilization. Memory variables include capacity, bandwidth, and cache-hit rates. Storage variables include hot datasets, sequential and random throughput, and checkpoint writes. Network variables include communication volume, topology, congestion, and tail latency. Market-sizing estimates in subsequent analyses should be derived from these underlying variables.
Capital expenditure is also spreading across this chain. A May 2026 U.S. semiconductor industry report estimated that the AI data-center systems market could reach approximately $1.7 trillion by 2030, comprising approximately $1.17 trillion of accelerators, $316.1 billion of AI networking, and $168.0 billion of HBM. These figures represent a high-growth scenario and should not be treated as market consensus. They nevertheless highlight an important shift: as accelerator counts increase, memory and networking will not remain at fixed ratios. To sustain utilization, systems will require more memory capacity per accelerator, greater interconnect bandwidth, and more sophisticated storage pipelines.
Industry analysis must therefore extend beyond accelerator shipments. HBM capacity per accelerator, Scale-up bandwidth within a rack, Scale-out ports across racks, and the SSD and HDD capacity required for training datasets and checkpoints collectively determine the true value of AI infrastructure. They also determine whether demand accrues to chips, storage media, switching equipment, copper connectivity, optical modules, advanced packaging, or testing.
II. Training, Inference, and Agent Workloads Move Three Distinct Types of Data
Workloads determine data structures, and data structures determine hardware bottlenecks. Training simultaneously processes weights, activations, gradients, optimizer states, and checkpoints. Inference primarily reads weights while continuously maintaining the KV Cache and temporary tensors. Agent workloads add longer contexts, external knowledge bases, tool-call results, and persistent memory. All three use compute, memory, and storage, but their data lifecycles and access patterns differ fundamentally.
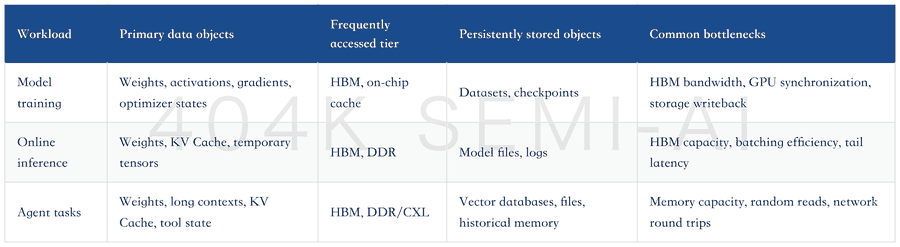
Training memory requirements are particularly easy to underestimate. In a December 2025 Bernstein expert interview, a 70-billion-parameter model was used as an example: weights consumed approximately 140GB, activations added approximately 500GB, gradients required another approximately 140GB, and total memory approached 1TB after optimizer states were included. This is an illustrative case under a specific precision, training method, and model architecture and cannot be applied mechanically to every model. It demonstrates that training retains far more data than the parameter file alone.
Training memory can be expressed simply as the sum of weights, gradients, optimizer states, activations, communication buffers, and runtime headroom. Mixed precision, optimizer selection, activation recomputation, and ZeRO sharding alter the contribution of each component. Hardware configurations must answer two questions simultaneously: whether each accelerator can accommodate its local shard and how much communication overhead cross-accelerator synchronization will incur.
Training also requires large-scale persistent storage. The expert estimated that a 1-trillion-parameter model could use a dataset of 1—5PB and that training-side storage requirements could be 100—1000 times those of a single inference run. These multiples are likewise scenario estimates from the interview. Model distillation, quantization, data reuse, and synthetic data can all change the outcome. The more robust conclusion is that training must continuously read datasets and periodically write checkpoints, creating demand for both capacity and sustained throughput, as well as write endurance.
Each inference request moves less data, but concurrency can amplify capacity pressure. Weights typically remain resident in HBM or a nearby memory tier, while the KV Cache expands with context length, concurrent requests, and model depth. Longer contexts do not directly increase all computation, but they continuously consume memory capacity and generate substantial read traffic. Providers can improve efficiency through quantization, paged memory management, cache reuse, and request batching, but each involves trade-offs among latency, accuracy, and scheduling complexity.
The key units for inference infrastructure are closer to “bytes consumed per concurrent request” and “bytes transferred per generated token.” Larger batches amortize weight reads but increase queueing time. Longer contexts enhance service value but also expand the KV Cache. If revenue growth is driven primarily by low-priced, long-context offerings, memory demand may rise faster even as profit per token fails to improve proportionately.
Agent workloads combine these two pressures. Agents require multi-turn context, retrieve documents, invoke external tools, and preserve task state. Model inference accounts for only part of the complete task; databases, object storage, and network round trips also contribute to user-perceived latency. Whether future Agent demand translates into hardware demand depends not only on token volume, but also on how much state each task retains, how much external data it accesses, and whether that data can hit shared caches.
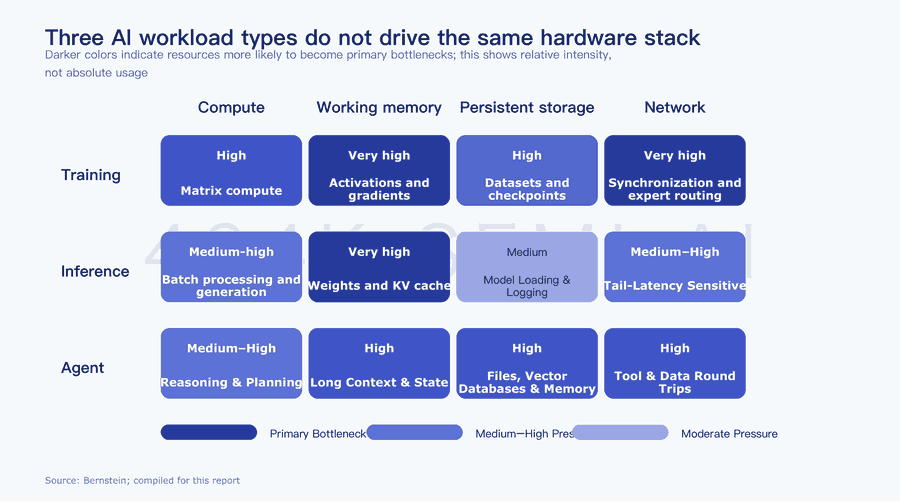
This distinction also explains why AI infrastructure demand cannot be extrapolated solely from GPU counts. Training clusters prioritize high throughput, tight synchronization, and centralized checkpointing. Online inference prioritizes high concurrency, low tail latency, and large KV Cache capacity. Agents depend more heavily on coordination across compute, memory, storage, and networking. The revenue captured by a hardware vendor depends on which data object it addresses—and whether that object is genuinely the system bottleneck.
