
目录
Executive Summary
1. Why Compute Demand Can Rise as Token Prices Fall
2. In a Theoretical 1 GW Model, Returns Depend on Throughput and Utilization
3. CoreWeave Has Cleared the Delivery Hurdle
4. CoreWeave’s Challenge Has Shifted to the Bottom Half of the Income Statement
5. Nebius Has Improved Capital Efficiency Through Contract Terms
6. Nebius’s 5 GW Must Pass Both the Construction and Financing Tests
7. Both Companies Validate the Same Demand but Bear Different Risks
8. Profits Will Shift from Model APIs to Four Other Layers
9. How to Test This Thesis Over the Next Four Quarters
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
Open-weight models are driving down model prices without slowing compute infrastructure investment. The real question is whether rising Token volumes can overcome GPU utilization, depreciation, and interest costs to generate cash for shareholders.
Executive Summary
Morgan Stanley’s scenario analysis for a 1 GW GB300 cluster indicates a 20%—60% return on invested capital for model API services and 23%—39% for GPU cloud rentals. These returns require rapid Token-volume growth, sustained improvement in per-GPU throughput, 75% cloud utilization, and GPU pricing of $7—10 per hour. Material weakness in any assumption would compress returns quickly.
Open-weight models reduce both per-Token prices and barriers to enterprise adoption. A 20% price decline requires at least 25% volume growth to preserve revenue; a 60% decline requires 150% growth. Post-training inference, multi-step agent calls, retrieval, storage, and security services can drive usage faster than user growth. Compute demand therefore depends on how much incremental usage lower prices generate—not simply on per-Token pricing.
CoreWeave has demonstrated its ability to deliver at scale: second-quarter revenue reached $2.575 billion, up 112% year over year; active power exceeded 1.5 GW, with nearly 500 MW added during the quarter; and backlog stood at $104.2 billion. Average pricing across SKUs rose approximately 25% in July, while new contracts improved margins by 5—10 percentage points, indicating that near-term supply remains tight relative to demand.
CoreWeave has yet to translate operating returns into shareholder returns. Second-quarter adjusted EBITDA was $1.51 billion, but adjusted operating income was only $128 million and net interest expense reached $640 million. The company also recorded a net loss; its magnitude was $626 million. First-half operating cash flow was $3.663 billion against $14.117 billion of equipment and capitalized software spending, leaving expansion dependent on successive rounds of debt, convertible debt, and equity financing.
Nebius is improving contract quality more rapidly. Second-quarter revenue was $582 million, up 454% year over year, while quarter-end annualized run-rate revenue for its AI cloud exceeded $3 billion. Four major contracts averaged more than $1 billion in total contract value, with annual contract value of $20 million—$25 million per MW. Approximately 70% of transactions included prepayments covering 50%—60% of the associated capital expenditure, and the expected payback period has shortened to 1 year and 10 months.
CoreWeave and Nebius both demonstrate that AI compute demand remains strong, but they also expose the final hurdle to capital returns. CoreWeave must generate operating income that consistently covers interest expense, while Nebius must convert 5 GW of contracted power into connected capacity and revenue on schedule. Over the next 4 quarters, the most important public indicators will be per-Token pricing and usage, GPU rental rates and renewals, the conversion of contracted power into active power, revenue/GW, operating income/net interest expense, and free cash flow per share.
1. Why Compute Demand Can Rise as Token Prices Fall
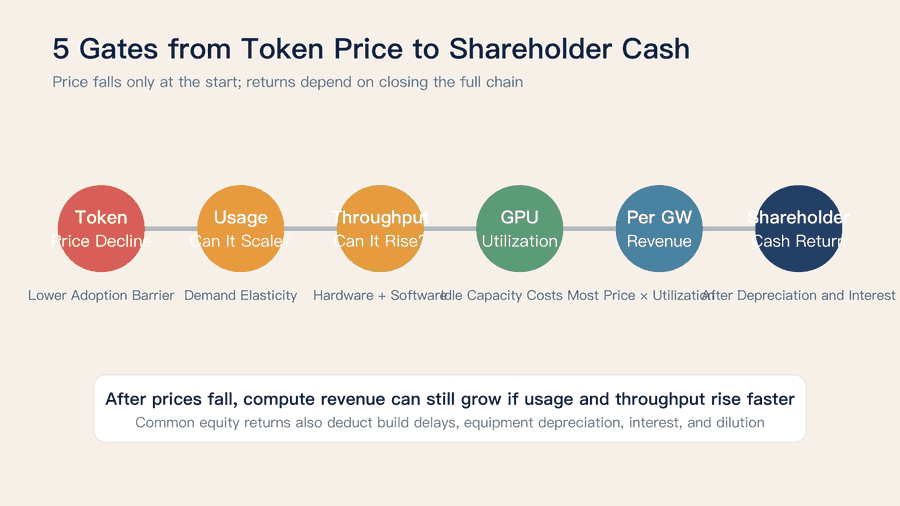
Open-weight models allow enterprises to download model weights, fine-tune them on proprietary data, and deploy them on owned hardware or rented cloud GPUs. This expands enterprise choice while exposing model developers to more direct price competition. Enterprises can compare multiple models, route requests across providers, or build in-house inference infrastructure for data-sensitive and high-volume workloads. As a result, per-Token pricing is unlikely to sustain scarcity premiums over the long term.
Lower prices explain only half of the revenue equation: model API revenue equals Token price multiplied by Token volume. Compute-provider revenue must also account for the compute consumed per Token and is further shaped by GPU utilization and rental pricing. A cheaper, easier-to-deploy model may bring more enterprises online while increasing call frequency within existing applications. Ultimate compute consumption therefore depends on the interaction among price, usage, model efficiency, and delivery architecture.
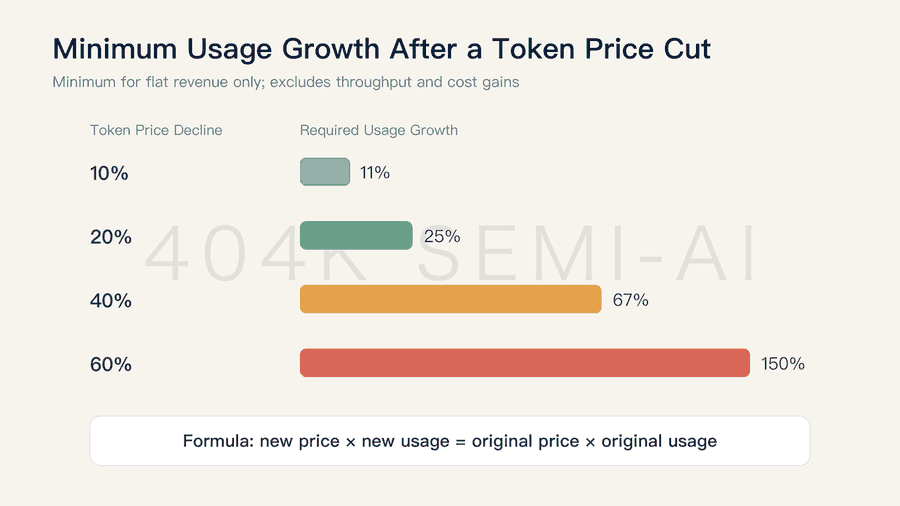
A simple revenue-neutral calculation is instructive. A 10% price decline requires approximately 11% usage growth to preserve revenue; a 20% decline requires 25%; a 40% decline requires approximately 67%; and a 60% decline requires 150%. These are merely the thresholds for preventing revenue contraction and exclude throughput gains, cloud-platform take rates, and ancillary revenue from storage, databases, and other services.
Generative AI has a distinctive usage profile: back-end Token growth can far outpace user growth. A conventional search typically involves a single request. An agentic task may first decompose an objective, retrieve information, invoke tools, validate outputs, correct errors, and only then produce an answer. The user performs one action, but the back end executes multiple model calls. Coding, video, voice, scientific simulation, and enterprise automation also require longer contexts and more intensive inference.
Open-weight models amplify this effect. As deployment costs fall, enterprises integrate models into more internal workflows, while customers whose data cannot readily leave their premises can begin adopting AI. When model capabilities are comparable, lower prices stimulate call volumes; as capabilities improve, new use cases expand the addressable market. Falling Token prices and rising aggregate Token volumes can coexist, just as unit prices for cloud storage, bandwidth, and compute have declined over time while total consumption continued to grow.
This thesis has clear limits. If open-weight models complete the same task with less compute, efficiency gains will offset part of the demand increase. If enterprises merely migrate from paid APIs to owned GPUs, total industry compute demand may remain unchanged even as revenue shifts from model companies to hardware, cloud, and power providers. If call-volume growth trails the rate of price decline, model API revenue will contract. Assessing industry conditions therefore requires tracking price, usage, and the actual compute consumed per task together.
2. In a Theoretical 1 GW Model, Returns Depend on Throughput and Utilization
Morgan Stanley evaluates open-weight models under two 1 GW scenarios. The first models a developer operating a 1 GW data center containing approximately 410,000 GB300 GPUs. Each GPU processes 2,000—3,500 Tokens per second, while average model API pricing is approximately $1.75 per 1 million Tokens. Across different combinations of throughput and usage, the estimated return on invested capital for the model API business is approximately 20%—60%.
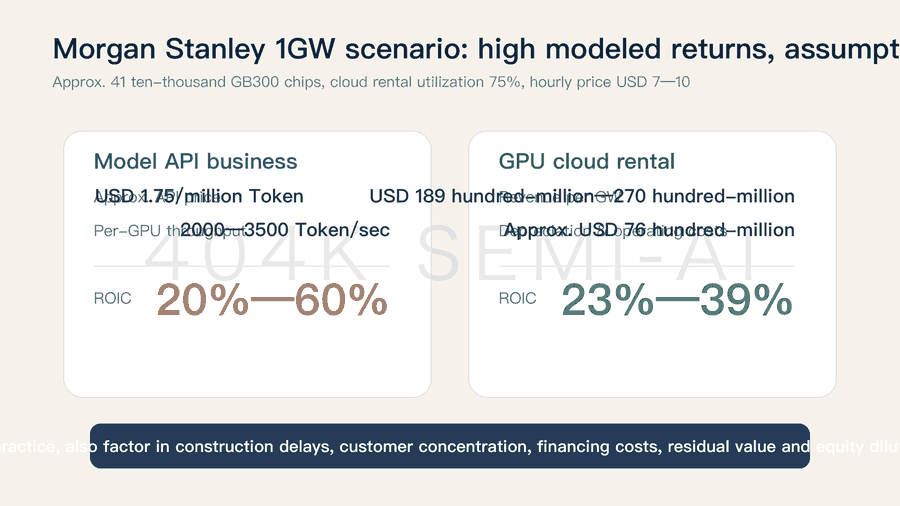
The second scenario models cloud infrastructure using the same approximately 410,000 GB300 GPUs, 75% average utilization, and GPU pricing of $7—10 per hour. Annual revenue per GW is approximately $18.9 billion—$27.0 billion. After deducting approximately $5 billion of IT equipment depreciation, $1 billion of non-IT depreciation, and $2 billion of energy and operating costs, total costs are approximately $7.6 billion. After-tax operating income is approximately $8.9 billion—$15.3 billion, implying a 23%—39% return on invested capital.
These figures show that Token prices and GPU rental rates operate in two distinct markets. Model APIs face substitution from open-weight alternatives, pressuring unit pricing. GPU rental rates are determined jointly by available power, equipment supply, delivery timelines, and customer demand. Specialized AI clouds remain capacity-constrained in 2026, so lower model prices have not immediately translated into lower GPU rental rates. CoreWeave raised average pricing by approximately 25% in July, while Nebius reported pricing for prior-generation GPUs more than 30% above first-quarter levels—evidence that the two prices can move in opposite directions.
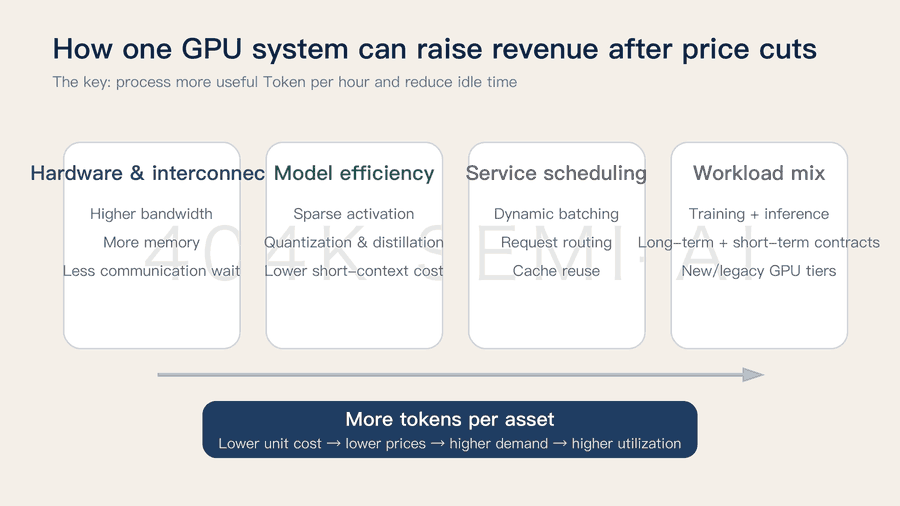
Throughput is the critical link between these markets. More Tokens processed per GPU per second reduce unit Token costs, giving model companies room to lower prices; the same GPU can also serve more requests, raising hourly output. Interconnects, memory, sparse models, quantization, batching, request routing, and caching all affect throughput. Cloud platforms can further reduce idle time by staggering training, real-time inference, offline inference, and short-duration workloads.
The theoretical model also excludes several of the costliest real-world frictions. Land, power, construction, and interest costs accrue before equipment arrives. If customer acceptance slips by one quarter, revenue is deferred while depreciation and interest continue to accumulate. The model also does not separately account for customer concentration, contract cancellations, financing structures, equity dilution, GPU residual values, or replacement capital expenditure. Hyperscalers with strong balance sheets can absorb these issues through cash flow from other businesses; for specialized AI clouds, they directly determine common-equity returns.
The 23%—39% return on invested capital for cloud infrastructure is therefore better viewed as an upper-bound benchmark for well-utilized assets. CoreWeave’s and Nebius’s results provide a real-world adjustment: demand and pricing are indeed strong, and operational clusters can generate high adjusted EBITDA, but company-level net income and free cash flow remain constrained by depreciation, interest expense, construction schedules, and financing structures.
3. CoreWeave Has Cleared the Delivery Hurdle
CoreWeave integrates customer contracts, power, data centers, GPUs, networking, and software into a purpose-built AI cloud. Its business model resembles cloud services, but execution is closer to a large-scale infrastructure project: a delay at any point prevents customer acceptance and revenue recognition. The most important development in the second quarter was CoreWeave’s demonstration that it can advance a large number of projects simultaneously within a single quarter.
