
目录
Executive Summary
1. The Real Question Raised by the Chart
2. The Compute-Demand Identity: Tasks, Length, and Compute per Token
3. When the Jevons Effect Applies
4. From Chatbots to Agents: A Structural Increase in Usage Intensity
5. What Codex User Growth Tells Us
6. OpenAI and Anthropic Revenue Provides a Second Demand Signal
7. How Revenue Translates into Compute Demand
8. NVIDIA Shows That Efficiency and Demand Can Rise Together
9. Compute Shortages Are Migrating Beyond H100
10. CoreWeave and Nebius: High Operating Leverage, Heavy Capital Constraints
11. Hyperscalers Benefit from Portfolio Advantages
12. Which Parts of the Value Chain Are Most Likely to Capture Profits
13. Three Scenarios Will Determine the Duration of This Cycle
14. Key Indicators to Track
15. Conclusion: Cheaper AI Will Expand the Compute Market, but Commercial Outcomes Will Still Diverge
The unit cost of AI is falling rapidly, but task volumes and compute intensity per task are rising even faster. Together, these forces are turning “cheaper intelligence” into greater compute consumption.
Executive Summary
AI compute demand cannot be assessed solely by the price per million tokens. Total compute can be decomposed into task volume × tokens per task × compute per token. Model, chip, and software optimizations continue to reduce the third component, while agent adoption, longer reasoning chains, and increased tool use are raising the first two. As long as task growth outpaces unit-efficiency gains, GPU hours will continue to rise.
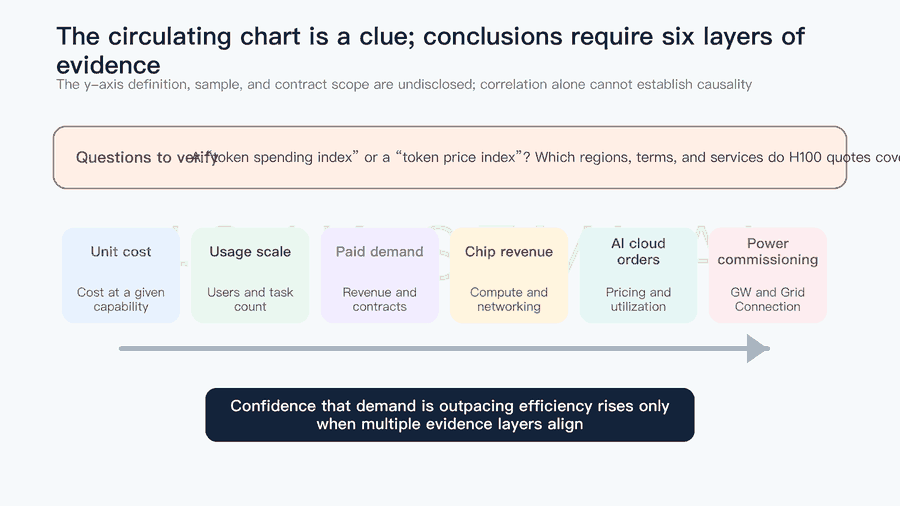
1 widely circulated chart attributed to Citadel Securities offers a directional signal, but not yet rigorous evidence. Circulating commentary initially described the same 1 curve as a “token spending index,” then as a “token price index”—two fundamentally different measures. The original methodology, geography, contract duration, and H100 configuration were not disclosed. A more robust approach is to cross-check inference costs, user scale, model-provider revenue, chip revenue, AI-cloud orders, and commissioned power capacity.
Codex user growth supports the demand-expansion thesis, but the claim that users have “surpassed 20 million” currently lacks direct disclosure. As of August 21, 2026, the latest publicly traceable milestone was 15 million active users, with no measurement period specified. The 20 million figure appears closer to an unverified number circulating publicly. Even using only 15 million, Codex’s rise from approximately 10 million users in July to 15 million by mid-August still shows programming agents rapidly entering everyday workflows.
Model-provider revenue growth is validating enterprise willingness to pay. CNBC reported that OpenAI’s annualized revenue run rate had reached approximately $40 billion, up 20% month over month in July, with enterprise revenue already exceeding consumer revenue. Anthropic’s annualized revenue run rate was approximately $65 billion at the end of July, while preliminary second-quarter revenue was approximately $11.5 billion. Neither run rate should be treated as recognized annual revenue, much less profit, but both indicate that AI has moved from experimental budgets into recurring expenditure.
Efficiency gains and rapid hardware-revenue growth can coexist. NVIDIA’s data-center revenue reached $75.2 billion in the first quarter of fiscal 2027, up 92% year over year. The company also claimed that Dynamo 1.0 could improve certain generative and agentic inference workloads on Blackwell GPUs by as much as 7x. Once unit efficiency improves, new use cases, additional users, and longer reasoning chains absorb the released capacity.
Compute scarcity is shifting from individual GPUs to the full system stack. CoreWeave management disclosed fiscal second-quarter 2026 revenue of $2.6 billion, a $104 billion backlog, 1.5GW of active power, and an annualized revenue run rate of more than $100 million for its managed inference platform. The next wave of bottlenecks will increasingly center on HBM, networking, optical interconnects, storage, power, cooling, and data-center campus delivery.
This thesis supports infrastructure demand, but does not ensure that every compute asset will be profitable. NVIDIA, hyperscalers, CoreWeave, and Nebius carry fundamentally different capital structures and margin risks. Order growth, GPU pricing, and revenue growth must still translate into utilization, depreciation, financing costs, and free cash flow. If token-volume growth slows, prices for previous-generation GPUs decline, or power capacity comes online faster than customer demand, the Jevons effect may still hold even as returns on the relevant equities deteriorate.
1. The Real Question Raised by the Chart
A recently circulated chart plots two series together: the hourly rental price of NVIDIA H100 GPUs and an AI token-related index. According to the accompanying commentary, the two curves generally moved in the same direction from December 2025 through June 2026. After July, however, the token index continued to decline sharply, while H100 rental prices stabilized at approximately $2.70 per hour and even edged higher.
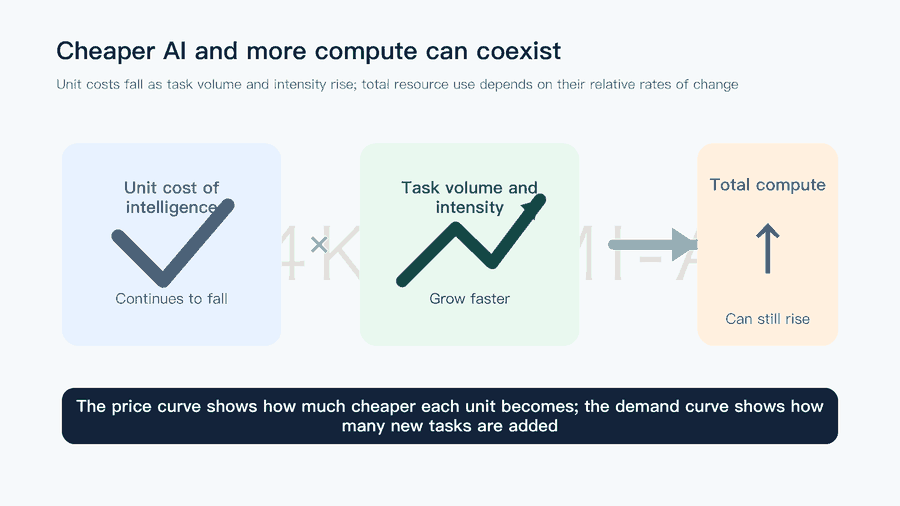
The pattern is compelling. If AI output keeps getting cheaper while the GPUs required to produce it do not, the intuitive explanation is that incremental usage is absorbing the efficiency dividend. Lower prices can drive more calls across chat, coding, search, video generation, and background agents, ultimately keeping underlying resources tight.
The problem is that the circulated version lacks a methodology that can be independently verified. A “token spending index” measures how much users spend, while a “token price index” measures the cost per unit of output. A decline in the former could indicate weakening demand; a decline in the latter could reflect improved supply-side efficiency. If even the vertical-axis definition is uncertain, the divergence between the two curves can only serve as a starting point for research.
The hourly price of an H100 is also not a standardized commodity price. On-demand instances, long-term take-or-pay contracts, bare-metal servers, full-server rentals, and cluster services bundled with networking and storage can carry widely different prices. Regional electricity costs, interconnect bandwidth, GPU memory, availability zones, utilization guarantees, and payment terms all affect quotations. As newer architectures such as Blackwell enter service, H100 demand will also be shaped by both substitution effects and incremental demand.
The chart’s greatest value, therefore, lies in the research question it raises: when the unit cost of AI falls rapidly, will usage grow even faster? Answering that question requires moving beyond a single price curve and examining a much longer chain of evidence.
2. The Compute-Demand Identity: Tasks, Length, and Compute per Token
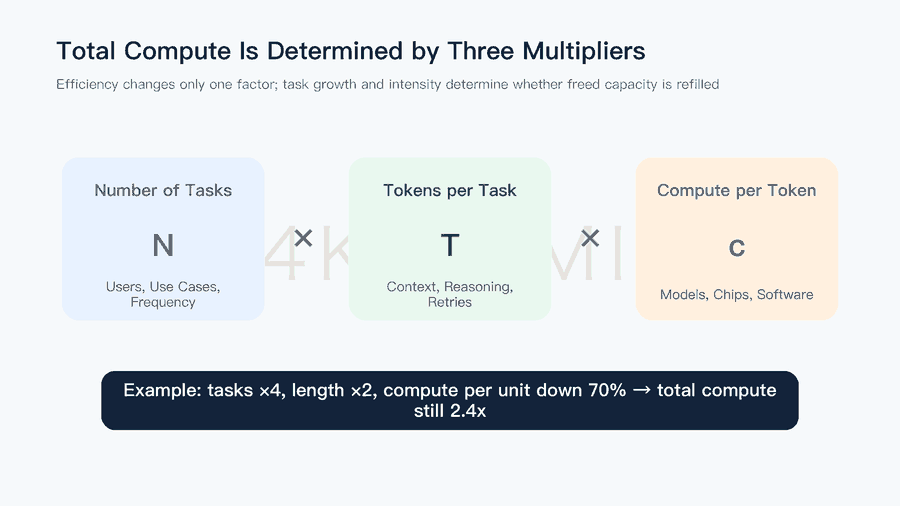
Total compute demand can be expressed through a simplified identity:
Total compute = task volume × tokens per task × compute per token.
Industry discussions often focus only on the final component. Quantization, distillation, sparsity, speculative decoding, cache reuse, compiler optimization, and next-generation GPUs can all reduce compute cost per token. Price competition then passes part of those technical gains to customers, driving API prices steadily lower.
Changes in the first two components are easier to underestimate. Lower prices make previously uneconomic, low-value model calls viable. Enterprises can turn one-off manual queries into monitoring processes that run every minute, replace single-turn Q&A; with multi-step planning, and expand an individual engineer’s assistant into an agent spanning the codebase, testing, deployment, and review.
Token consumption per task is also rising. Reasoning models generate longer internal computation traces, programming agents must read large volumes of code and logs, and multimodal systems must process images, audio, and video. When tool calls fail, agents replan, retrieve information again, and repeat execution. The final answer shown to the user may contain only a few hundred words, while multiple long-context reasoning passes have already occurred in the background.
Assume compute per token falls by 70%, task volume grows 4x, and average tokens per task rise 2x. Total compute would still reach 2.4x its original level. Looking only at token prices misses the combined multiplier from task volume and task intensity.
3. When the Jevons Effect Applies
The Jevons effect rests on a simple condition: efficiency gains reduce the effective price, and demand is sufficiently price-elastic. If a 1% decline in unit cost drives usage up by more than 1%, total resource consumption increases. In the steam-engine era, the resource was coal; in the AI era, it is GPU hours, electricity, network traffic, and storage capacity.
In “Three Observations,” Sam Altman argued that the cost of using AI at a given capability level falls roughly 10-fold every 12 months. Comparing GPT4 with GPT4O, he estimated that token prices fell by about 150-fold over the relevant period. Stanford HAI’s 2025 AI Index estimated that the inference cost of systems performing at the GPT35 level fell by more than 280-fold between November 2022 and October 2024.
Earlier OpenAI research also provides evidence for the underlying mechanism. Danny Hernandez and Tom Brown estimated that the training compute required to reach AlexNet-level performance fell 44-fold between 2012 and 2019, with algorithmic efficiency doubling roughly every 16 months. The study measured training efficiency and predates the current large-model cycle, so it cannot directly establish inference demand in 2026. Its more important implication is that algorithmic and hardware efficiency can compound, jointly reducing the cost of achieving a given capability level.
The two sets of figures are not defined identically. The former reflects observations by a model developer, while the latter attempts to hold capability constant. Together, they show that AI’s “effective price” is falling far faster than that of traditional software and many industrial products.
Price elasticity also depends on whether an application generates a positive return. A 90% cheaper chatbot response will not necessarily make users chat 10 times as much. But if a coding agent can compress several hours of repetitive work into tens of minutes, enterprises have a clear incentive to keep it running throughout the day. Value comes from completed tasks, and enterprise spending will ultimately center on cost per problem solved, accuracy, and labor savings.
In an August 2026 investor discussion, OpenAI’s CFO said enterprise customers were shifting their focus from token consumption to “cost per unit of intelligence.” This does not imply that token usage will decline. It means buyers increasingly expect output quality, speed, and business outcomes to improve together. If the cost per task falls while the set of automatable tasks expands, the volume of economically viable workloads will increase.
