
U.S. Semiconductor Deep Dive: AI Extends Visibility to 2028; After BofA’s Estimate Revisions, Who Can Still Re-rate?
目录
Too Long; Didn’t Read
I. What This BofA Report Actually Changed
II. The Aggregate Ledger: A $2.7 Trillion TAM Is Not the End-State Number, But a Constraint Ranking
III. Five Themes: Where the Next $1 Trillion Comes From
IV. Memory: The Change in Asset Attributes Behind Micron’s Target-Price Upgrade
V. WFE: The Key to a $250 Billion Equipment Cycle Is Not Intensity, but Cost per Wafer
VI. How to Rank Equipment Companies: AMAT, LRCX, KLAC, and MKSI Do Not Have the Same Elasticity
7. CPUs Return to the Main Battlefield: Intel and Arm Make Different Bets
8. Interconnect and Data Movement: What MRVL, CRDO, and ALAB Have in Common, and How They Differ
IX. Testing: TER Is the Low-Visibility, High-Elasticity Link in Back-End Validation
X. Price Target Revision List: Which Are Major Re-Ratings, and Which Are Merely Following Along
11. How This Cycle Differs From Past Semiconductor Cycles
12. Investment Ranking: Bottlenecks First, Beta Later
XIII. Risk Checklist: The Biggest Risk Is Not Slightly Lower Demand, but a Break in Visibility
XIV. What to Watch Over the Next Four Quarters
XV. Conclusion: U.S. Semiconductors Are Moving from Cyclical Recovery to Bottleneck-Asset Revaluation
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
This BofA report is not a routine target-price increase. It extends the U.S. semiconductor thesis from GPU strength to a supply-constraint framework spanning memory, equipment, CPUs, interconnect, and test: AI visibility now extends beyond 2028, and the market needs to reassess which companies are merely benefiting from capex beta and which truly control delivery bottlenecks and long-duration profits.
Too Long; Didn’t Read
The semiconductor narrative has changed. BofA extends AI from GPU demand to memory, equipment, CPUs, interconnect, test, and power constraints. The core issue is whether the supply chain can deliver.
Memory is the first gate. HBM, DRAM, and NAND are all tightening at the same time. Long-term agreements and cleanroom construction are shifting Micron from a cyclical stock into an AI compute-chain asset.
Equipment is the second gate. WFE has been revised up into supercycle territory. The variable is not just revenue, but equipment intensity per wafer, yield, and process complexity.
CPUs and interconnect are back at the main table. Agentic AI requires scheduling, memory addressing, and data movement. Intel, Arm, MRVL, CRDO, and ALAB benefit through different mechanisms.
Target-price revisions need to be tiered. MU is about memory assetization; AMAT/LRCX/KLAC are about equipment profits; TER is about test complexity. Investors cannot simply buy the AI label.
The biggest risk is a pullback in visibility. If cloud capex slows, memory LTAs loosen, or supply is released in concentration in 2028, high-valuation segments will be repriced first.
Investment ranking should follow bottlenecks. Start with memory and equipment, then look at CPUs, interconnect, test, and advanced packaging. Track prices, orders, cloud budgets, and customer qualifications; if they weaken together, the bottleneck trade is starting to unwind.
I. What This BofA Report Actually Changed
On the surface, this report is a target-price revision across BofA’s U.S. semiconductor coverage. The real change is a migration in the valuation anchor. BofA moves AI semiconductors from a “GPU demand curve” to a “scarce capacity curve”: the semiconductor industry is no longer just about incremental compute chips, but whether an entire supply chain can deliver at the same time.
Over the past two years, the easiest AI semiconductor story for the market to understand was GPUs. As long as demand for large-model training and inference continued to rise, GPUs, HBM, advanced packaging, and server systems would have orders. But by mid-2026, the issue had become more complex. GPUs remain important, but they no longer determine on their own whether AI clusters can be deployed. Memory bandwidth, standard DRAM, NAND/eSSD, server CPUs, Ethernet interconnect, test equipment, WFE, EUV, cleanrooms, power, and advanced packaging have all been pulled into the same delivery chain.
The core of BofA’s revision is bringing the period beyond 2028 into the valuation foreground. Previously, many semiconductor companies traded on 2026 or 2027 earnings revisions. Now BofA is pushing the valuation basis for multiple companies toward 2028 or even 2030. This is not simply “looking further out.” It means the market believes AI demand is not a one-year order pulse, but a force that will require the supply chain to lock in capacity, equipment, yield, and customers in advance.
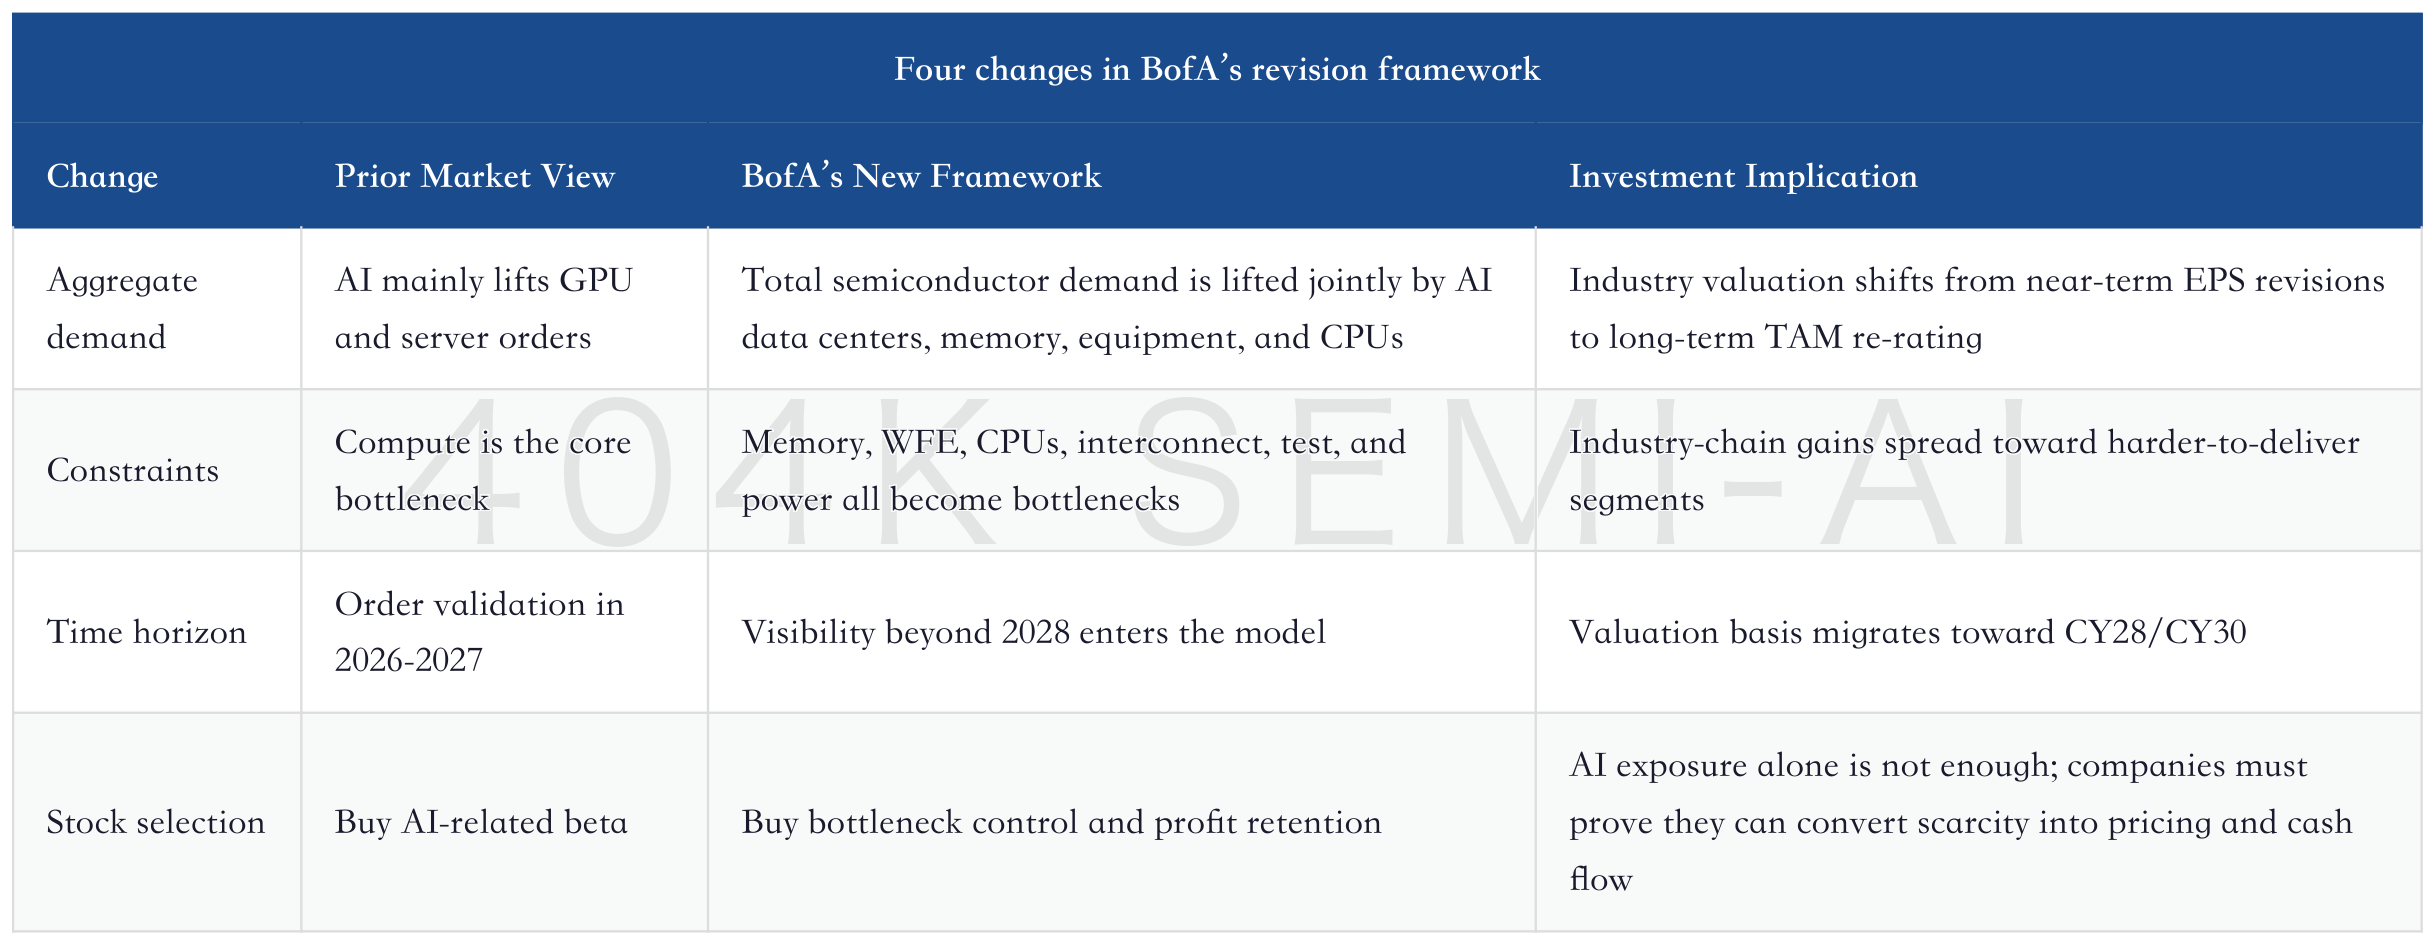
This is also why the report should not be written up as a “target-price list.” Target prices are only the result. What is worth unpacking is how BofA redefines the semiconductor cycle. It argues that the chip industry took roughly half a century to reach its first trillion dollars in sales, while AI may add another trillion-dollar-scale increment over the next few years. If that view is correct, semiconductors are not merely returning to the last cyclical peak; they are entering a new cycle in which capex, supply constraints, and product mix all rise together.
II. The Aggregate Ledger: A $2.7 Trillion TAM Is Not the End-State Number, But a Constraint Ranking
BofA raises its 2030 global semiconductor TAM estimate to $2.7 trillion, implying a 2025-2030 CAGR of roughly 28%. That number is large, but the truly important point is not the figure itself. It is the structure: memory, AI data-center systems, server silicon, networking, and equipment all contribute incremental growth, while consumer electronics remains weak.
Under BofA’s model, AI data-center systems could approach $1.7 trillion by 2030, versus only about $273 billion in 2025. Core semiconductors excluding memory are estimated at roughly $1.1 trillion by 2030, with a 2025-2030 CAGR of about 14%. Server silicon has the highest growth rate, while networking also benefits meaningfully. PCs and smartphones remain weak; autos and industrials are more about content growth and inventory normalization.
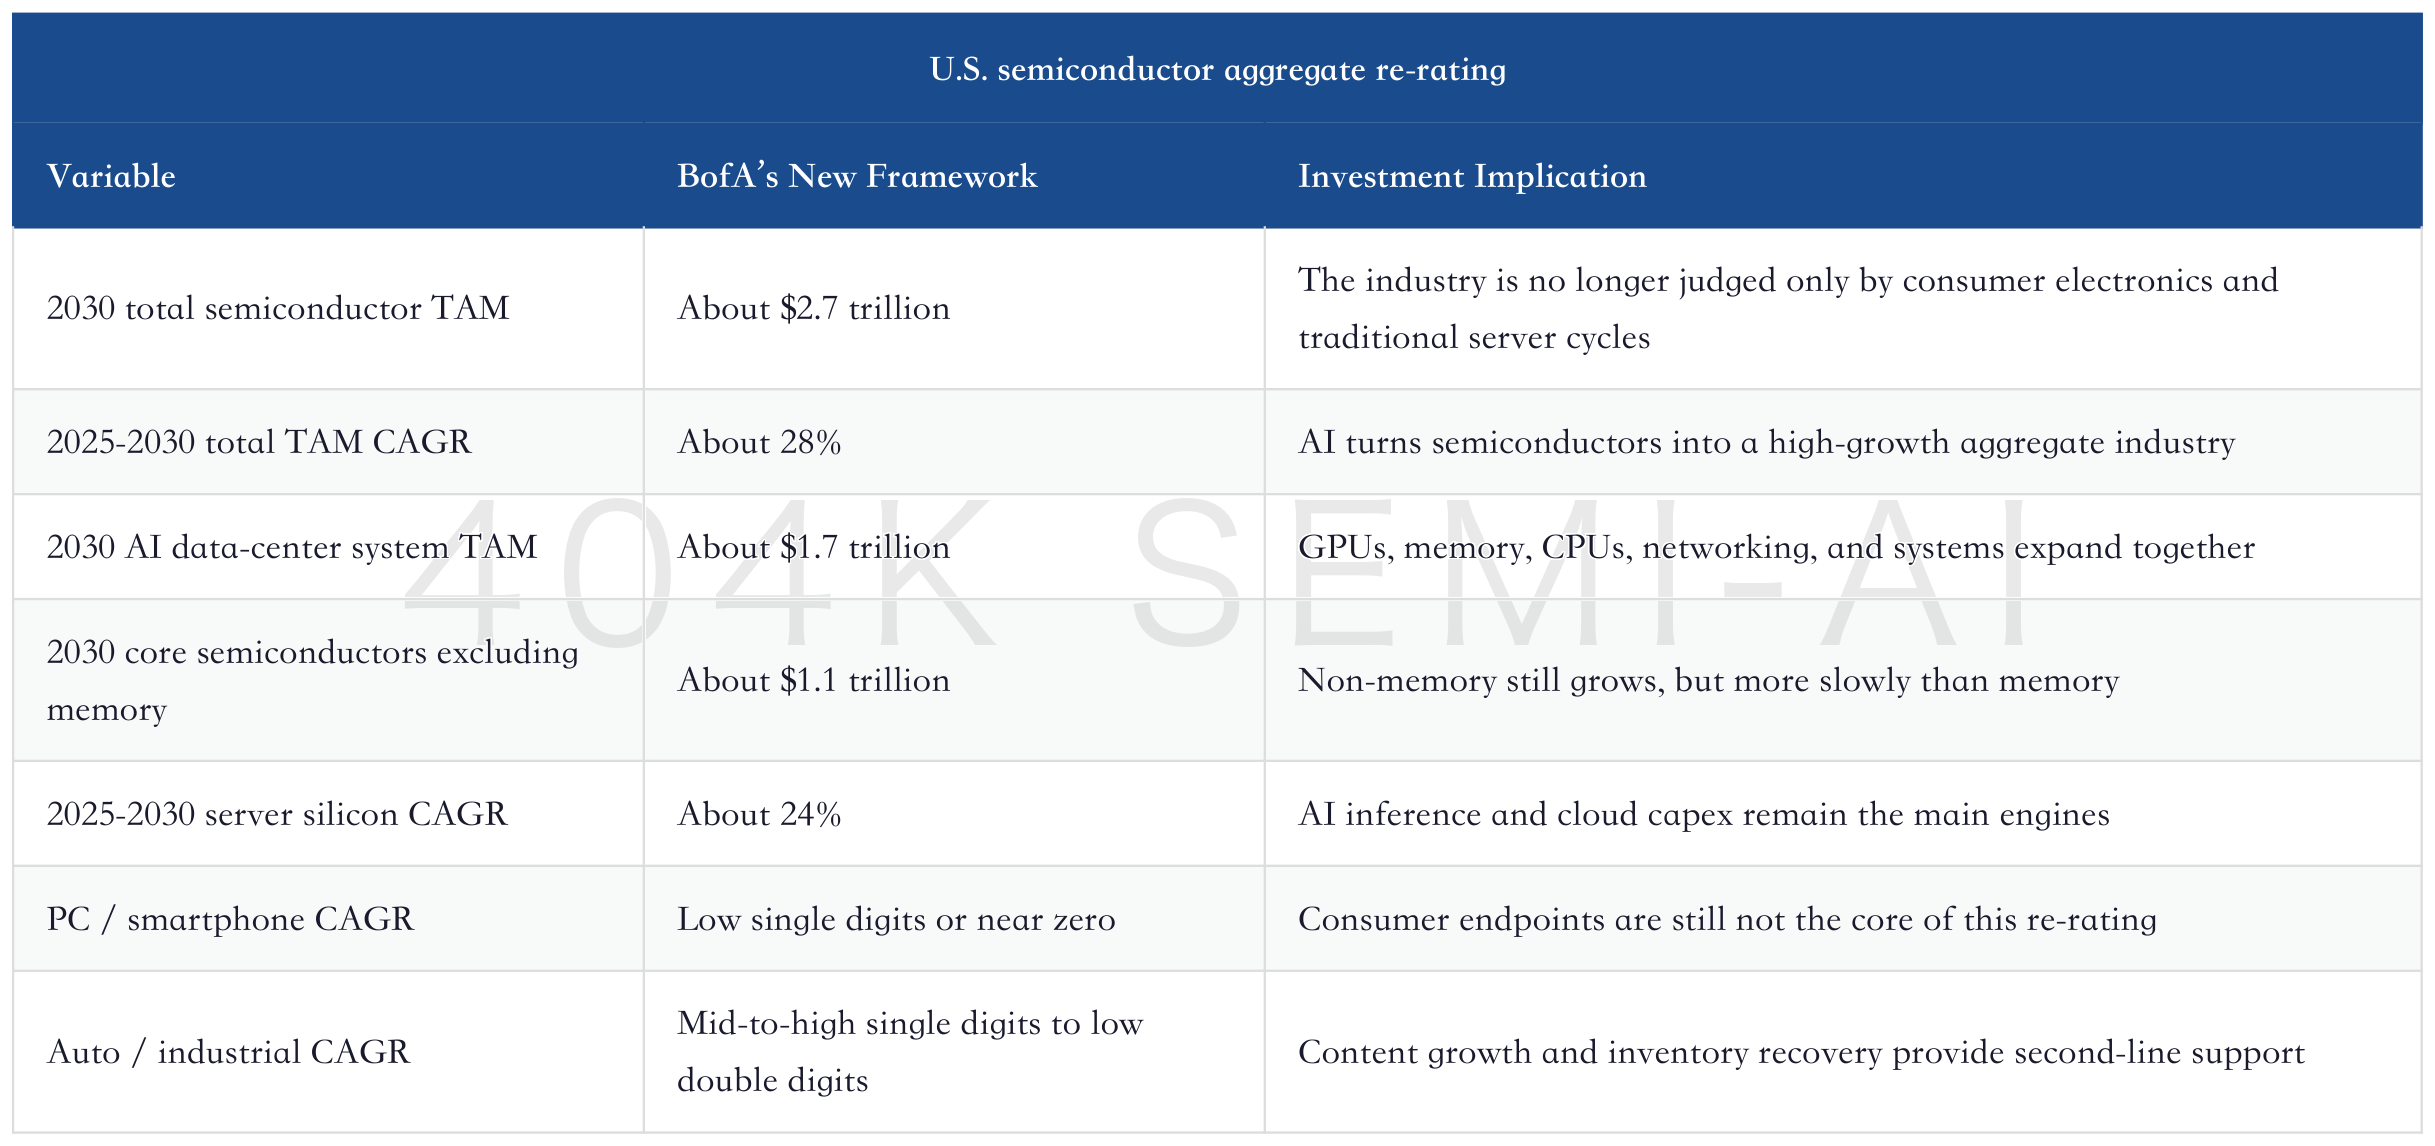
This table explains why BofA is raising estimates for memory, equipment, CPUs, interconnect, and test at the same time. An AI data center is not a chip; it is a system. The larger the system, the more it depends on multiple bottlenecks opening simultaneously. In the past, the market understood “compute” as GPUs. Now compute is closer to a delivery function: GPUs need HBM; HBM needs DRAM wafers and advanced packaging; systems need CPUs and networking; clusters need switching, optical interconnect, and test; capacity needs WFE and cleanrooms.
This is the most important conclusion in the BofA report: AI semiconductors are moving from a demand story to a delivery story. Demand stories focus on orders; delivery stories focus on bottlenecks. Orders can fluctuate across quarters, but bottlenecks can change valuation structure. Companies that control capacity that is hard to replace, customers that are hard to qualify, processes that are hard to substitute, and supply positions that are hard to price down can capture a longer duration of profits.
The aggregate model also needs to be read in reverse. If 2030 semiconductor TAM is revised up to $2.7 trillion, the real driver of stock-price elasticity is not the aggregate multiple, but where incremental profit is retained. GPUs are of course still among the strongest assets, but the GPU supply chain has already been studied extensively by the market. Incremental pricing power will continue to spread toward bottlenecks that have not yet been fully confirmed. BofA putting MU, AMAT, LRCX, KLAC, MRVL, CRDO, TER, INTC, and ARM in the same revision report reflects exactly this profit migration: from a single accelerator toward the full AI infrastructure stack.
Therefore, $2.7 trillion is not simply an optimistic aggregate figure. It is a constraint map. Memory determines how much data each accelerator can consume. Equipment determines wafers and yield over the next two to three years. Interconnect determines whether clusters can scale at low latency. CPUs schedule complex inference workloads. Test makes high-speed, high-current, multi-die systems actually deliverable. If the supply elasticity of any one segment is below the demand slope, value will remain in that layer.
This is also why consumer electronics has not become the main theme. PCs and smartphones may see cyclical recovery, but they mainly affect traditional semiconductor inventory and are not enough to explain why BofA has pulled valuation anchors beyond 2028. If a company only benefits from ordinary endpoint restocking, its valuation will struggle to move beyond next-year EPS. If a company sits directly in the AI data-center delivery chain, the market will be willing to pay in advance for CY28 and CY30 earnings power.
III. Five Themes: Where the Next $1 Trillion Comes From
BofA lays out several vectors that will drive the next $1 trillion of semiconductor growth. They are not a simple parallel list, but different gates in the same AI system: data center systems pull demand, memory determines throughput, equipment determines capacity, analog and power determine power conversion, CPUs determine inference scheduling, and Physical AI extends the opportunity further out to edge devices and robotics.
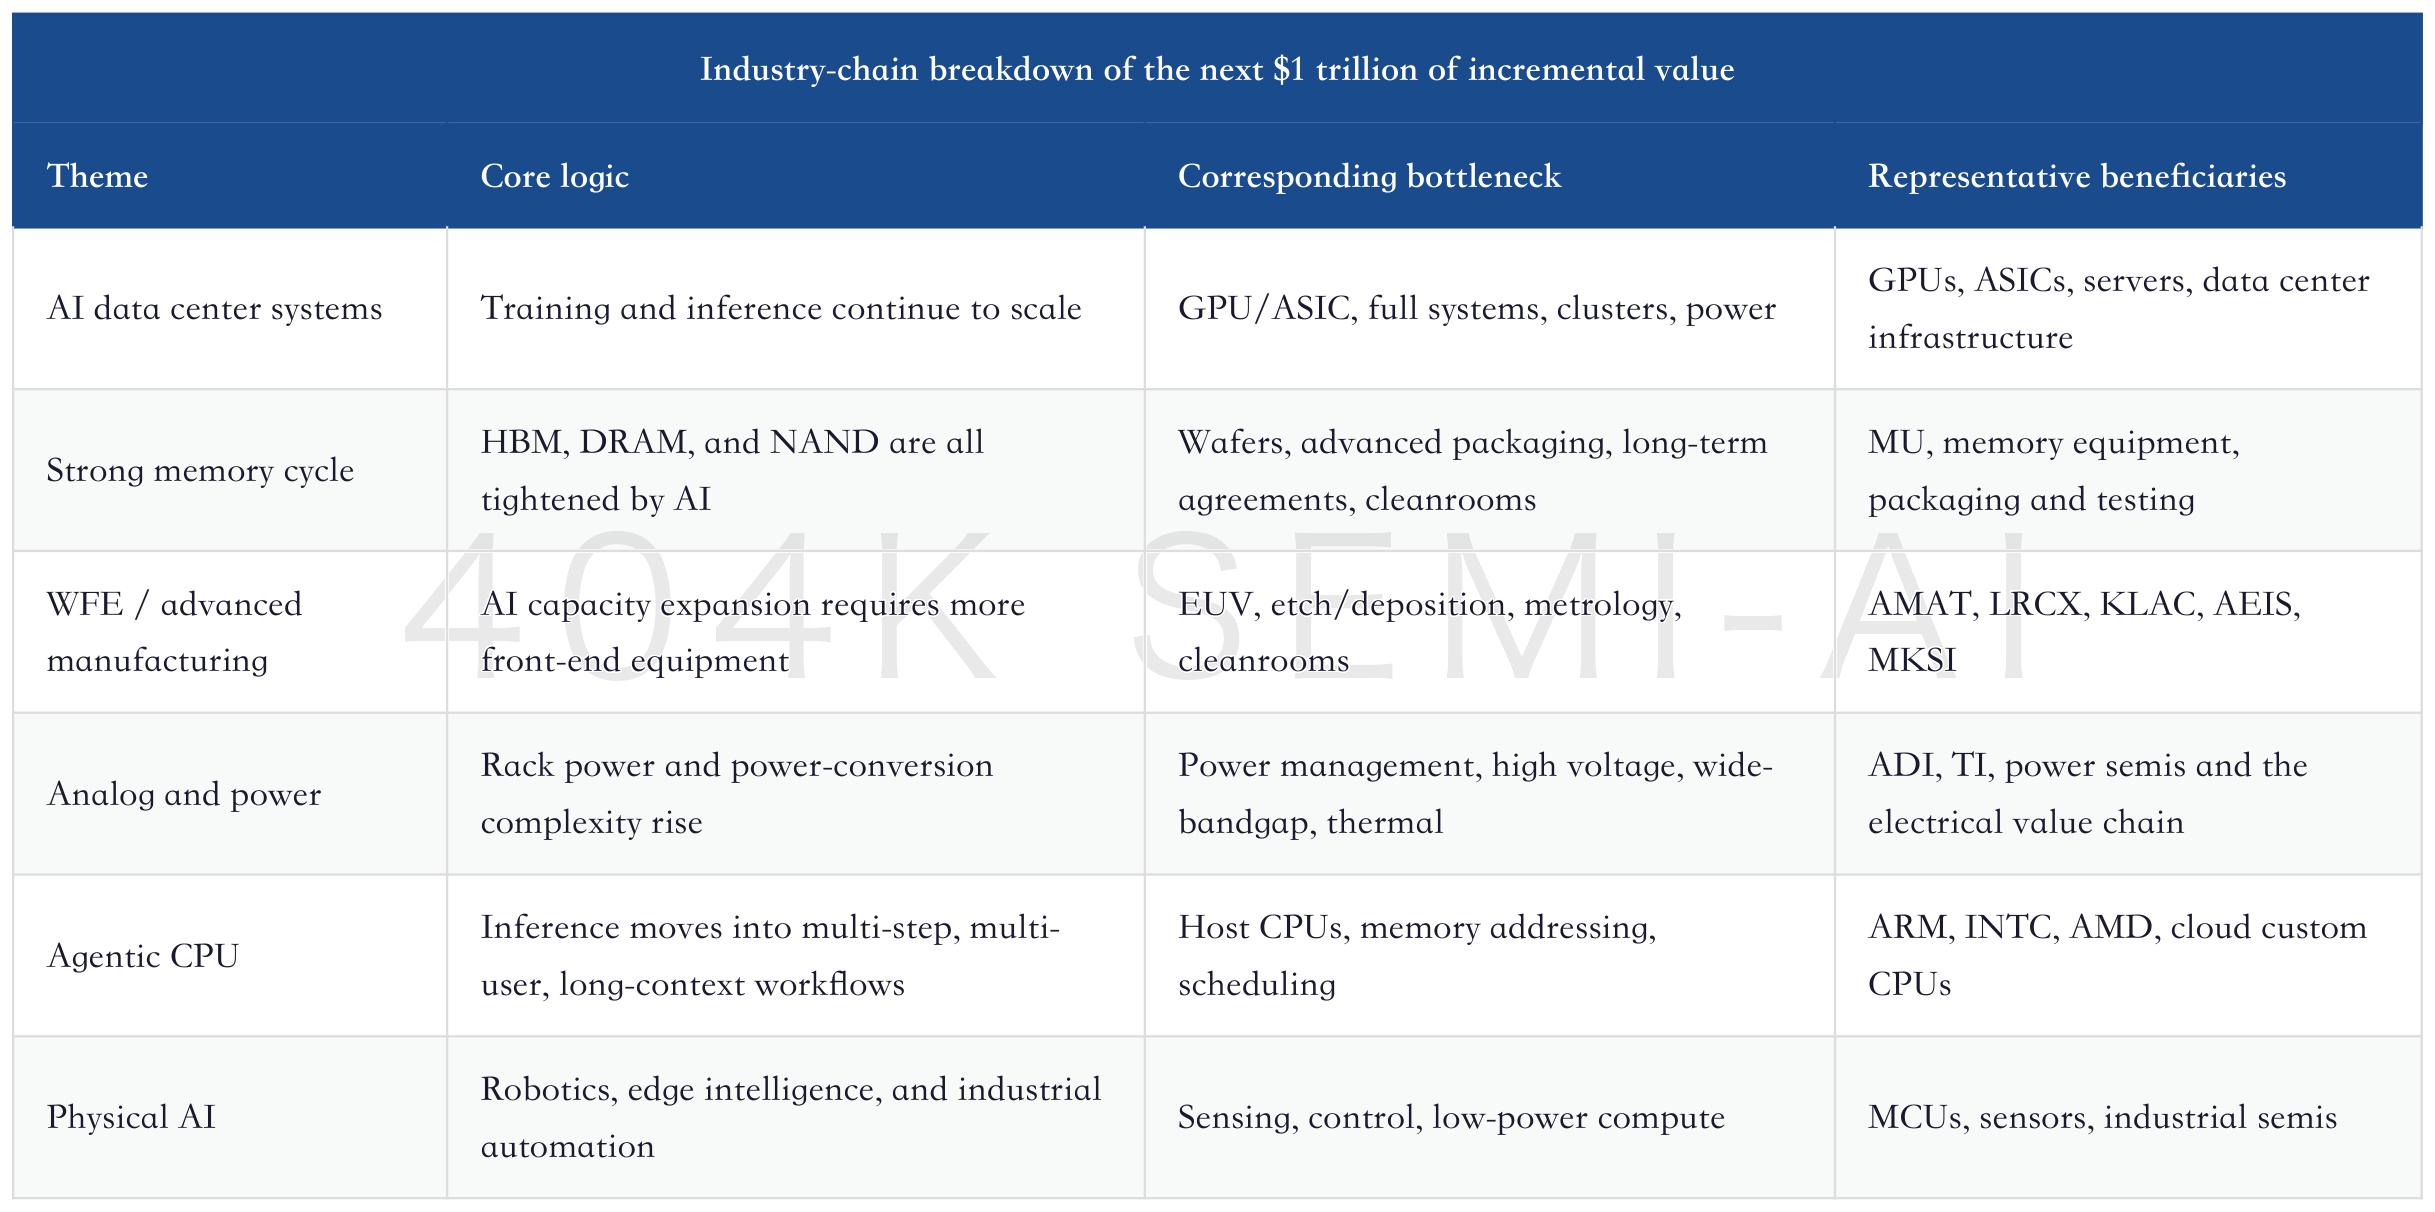
Among these themes, memory and WFE have the highest near-term visibility. The reason is simple: their supply is hardest to replenish immediately, and this is already reflected in pricing, long-term agreements, and equipment orders. CPUs and interconnects have the most medium-term optionality, because Agentic AI will change system architecture from a single-GPU focus toward coordination across CPUs, memory, networking, and accelerators. Further out are analog power and Physical AI. They are not the main driver of current EPS upgrades, but they will extend AI from data centers into power, industrial, and robotics markets.
After NVIDIA, What Else to Buy in AI: Value Migration Across HBM, PCBs, Power, Software, and Agent Entry Points
IV. Memory: The Change in Asset Attributes Behind Micron’s Target-Price Upgrade
Memory is the strongest theme in this report. BofA raised its MU price target from $950 to $1,500. The key is not only earnings upgrades for 2026-2028, but also that BofA is separating Micron from a traditional DRAM/NAND cyclical stock into two assets: a traditional memory business and an HBM business.
This segment valuation matters. Traditional DRAM/NAND is valued using 2028 book value and an upcycle PB multiple, while HBM is valued using AI compute peer PE multiples. In other words, BofA recognizes that HBM is no longer merely a high-margin product inside a memory company, but a profit stream closer to the AI compute supply chain.
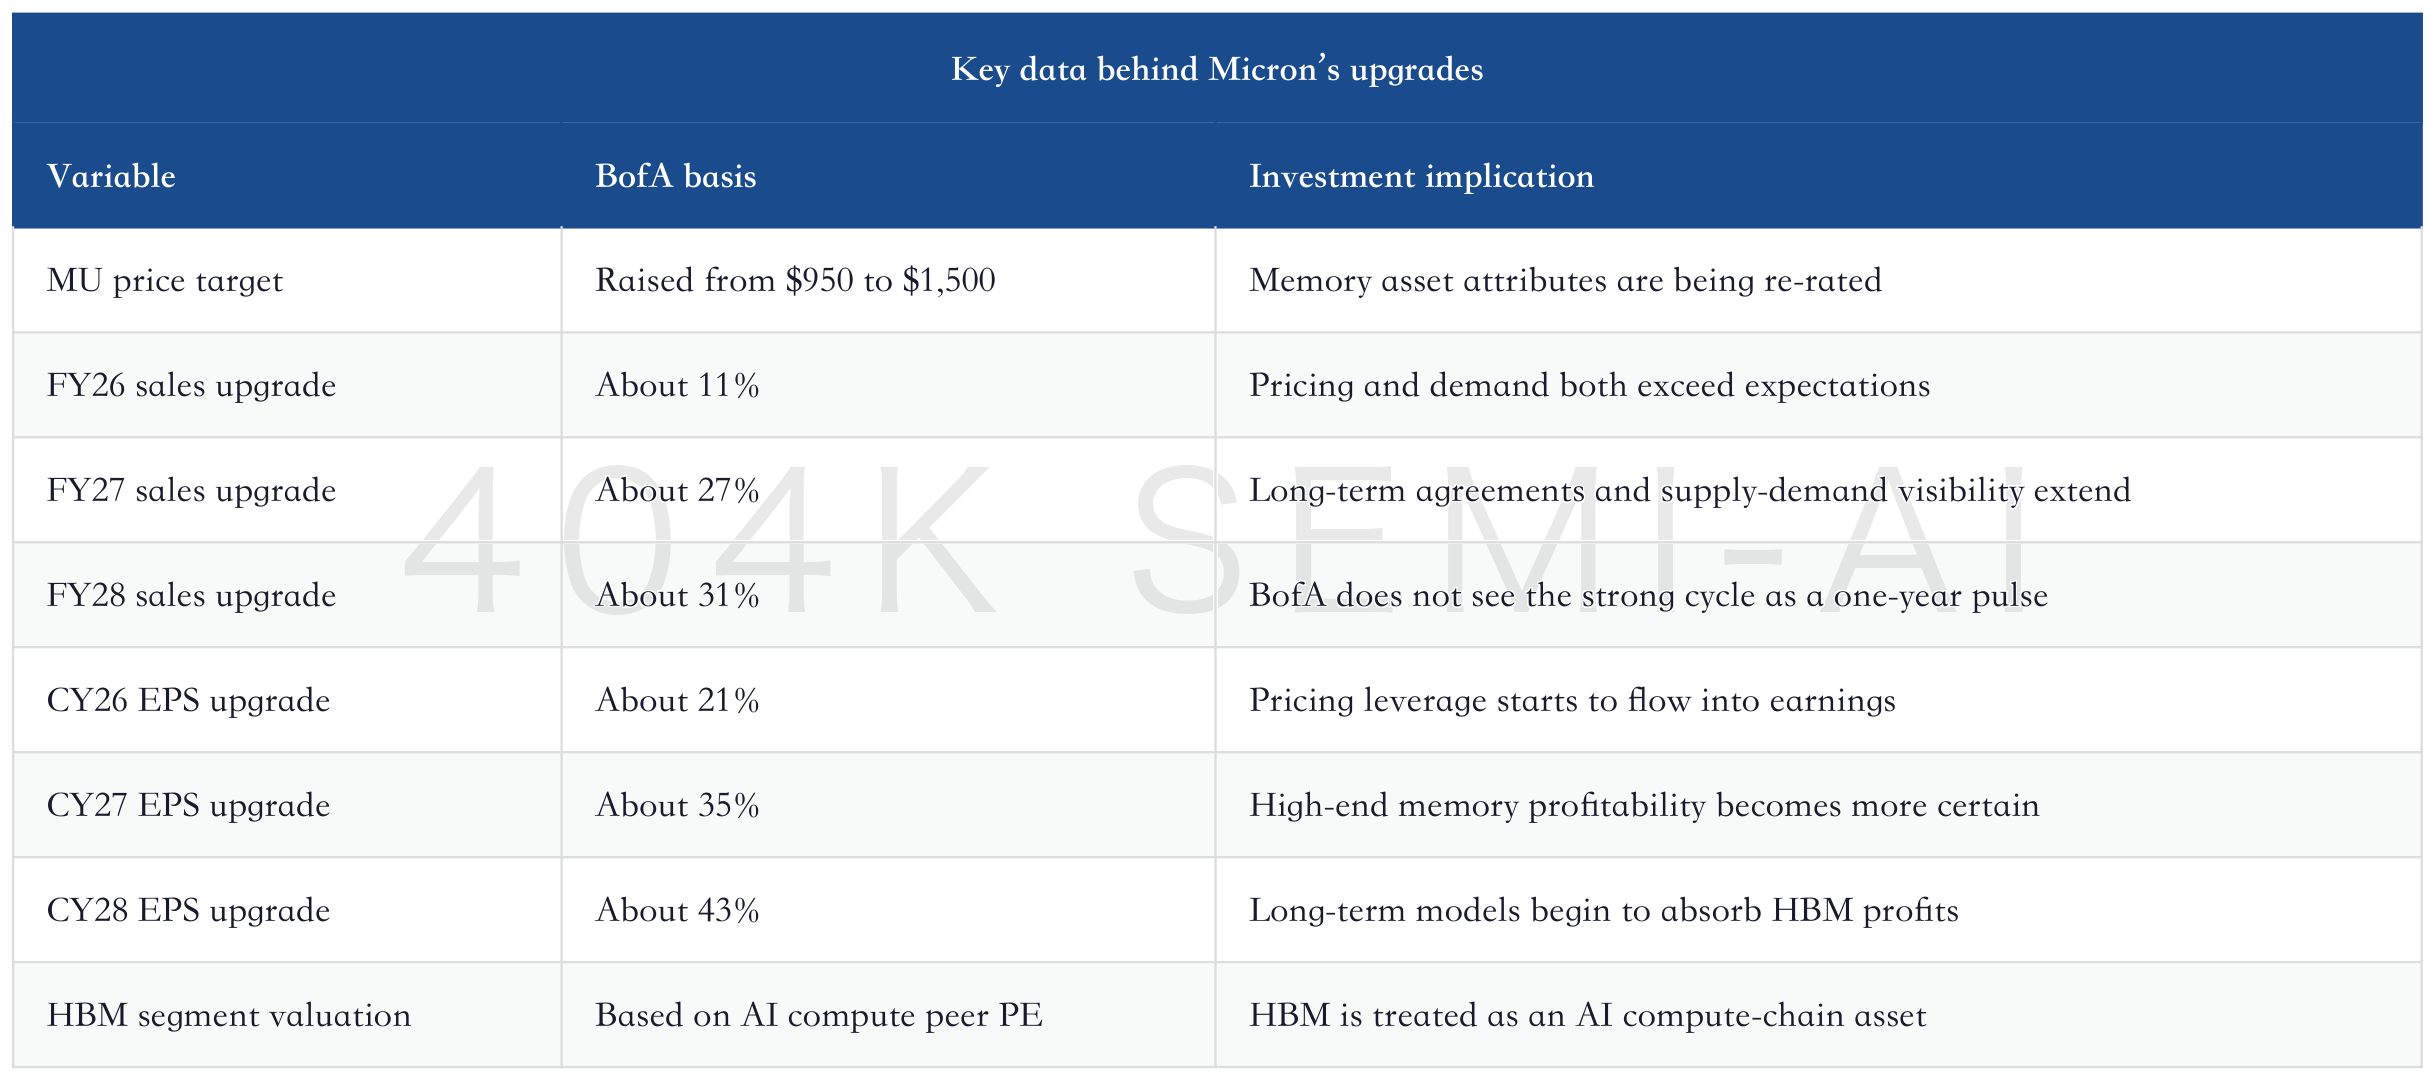
BofA’s memory logic can be summarized in three points. First, AI inference is shifting from a “compute bottleneck” to a “memory bottleneck.” Long context, high concurrency, and multi-step agents repeatedly access model weights and KV cache, so memory bandwidth and capacity are no longer supporting items. Second, memory supply elasticity has declined. Even if vendors raise capex, much of the money first goes into cleanrooms and buildings; real capacity is released only later. Third, HBM and traditional DRAM/NAND reinforce each other. HBM consumes advanced DRAM wafers, ordinary DRAM is also pulled by server and CPU-side inference, and NAND/eSSD benefits from demand in the data layer and cache layer.
The Memory Tax Has Arrived: How AI Is Turning HBM, DRAM, and NAND Into a Global Macro Bottleneck
HBM data is especially important. BofA expects the HBM TAM to grow from about $35 billion in 2025 to about $246 billion in 2030, a CAGR of about 34%. HBM content per accelerator rises from about 187GB to about 464GB. HBM pricing should still have strong support in 2027-2028. The memory configuration of NVIDIA’s Vera Rubin system also shows that future AI systems will not rely only on HBM; LPDDR, SRAM, and CPU-side memory will all expand meaningfully.
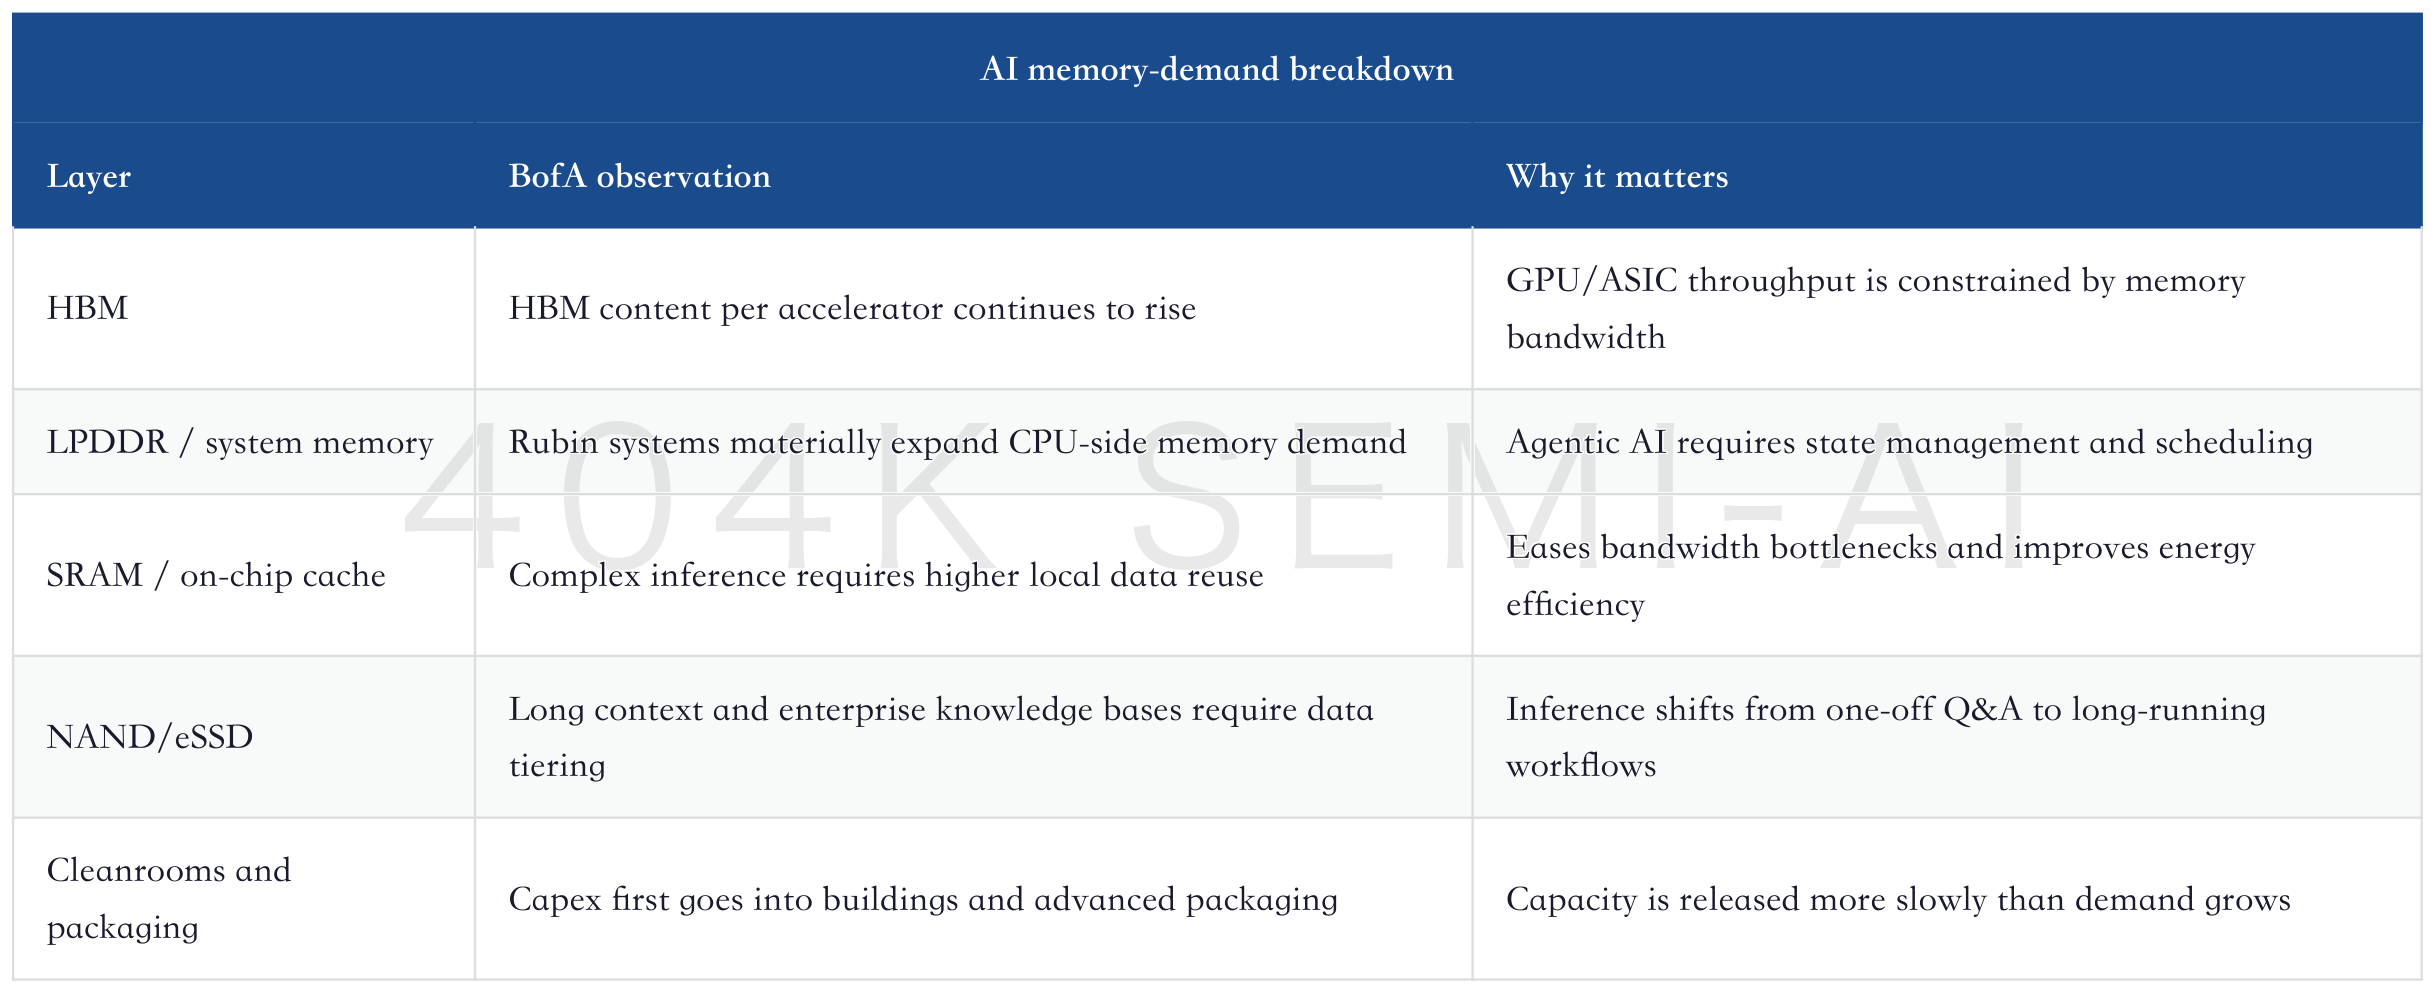
The risks in memory also need to be clear. First, if HBM long-term agreements loosen, pricing leverage will be questioned first. Second, if new capacity from multiple vendors is released in a concentrated way after 2028, the market will again worry about oversupply. Third, if memory price increases lift the total cost of ownership for AI clusters, cloud vendors may delay some deployments or push back on pricing. Fourth, traditional DRAM and NAND are still cyclical products, so HBM’s high-quality profits cannot be extrapolated directly to all of memory.
In the short to medium term, however, memory remains the first toll gate in this semiconductor re-rating cycle. As long as AI systems continue to pursue long context, multiple agents, high concurrency, and greater inference throughput, the logic of memory shifting from a “cost item” to a “throughput gate” will not end easily.
The most important part of Micron’s valuation is that traditional memory and HBM can no longer be handled with the same cyclical multiple. The value of traditional DRAM/NAND depends on supply-demand and book value. A higher PB can be assigned during a strong cycle, but the market will always worry that new capacity eventually drives prices down. HBM is different. It requires customer qualification, packaging capability, advanced DRAM wafers, thermal management, and system-design coordination, and it is deeply tied to GPU/ASIC roadmaps. As long as customers are willing to lock in supply through long-term agreements and prepayments, the duration of HBM profits will be materially longer than that of ordinary memory.
This does not mean HBM can always be valued like an AI compute company. A more precise way to put it is that, during a period of tight constraints, HBM has the “profit attributes of the AI compute chain.” When supply is tight, customers lock in inventory, and product generations switch quickly, HBM looks like a critical ticket to AI compute infrastructure. When capacity catches up with demand and prices begin to loosen, it will still return to the logic of the memory cycle. BofA’s re-rating of Micron is essentially a bet that the first state lasts longer.
For investors, assessing Micron cannot be reduced to HBM shipments alone. Three things matter. First, whether HBM unit pricing and contract duration can hold. Second, whether traditional DRAM/NAND also benefits as HBM crowds out wafer supply. Third, whether capex is mainly allocated to high-return cleanrooms, advanced packaging, and high-end memory, rather than creating ordinary capacity oversupply too early. As long as all three hold, Micron is not simply memory beta, but a pricing asset tied to the AI memory bottleneck.
V. WFE: The Key to a $250 Billion Equipment Cycle Is Not Intensity, but Cost per Wafer
Equipment is the second hard through-line in BofA’s report. BofA raised its 2028 WFE forecast from roughly $203 billion to roughly $250 billion, and laid out a path toward nearly $292 billion by 2030. This upward revision is not simply “semiconductor sales rise, therefore equipment rises.” It is being driven jointly by technical complexity, memory capacity expansion, advanced logic, EUV, non-China capacity additions, and cleanroom unlocks.
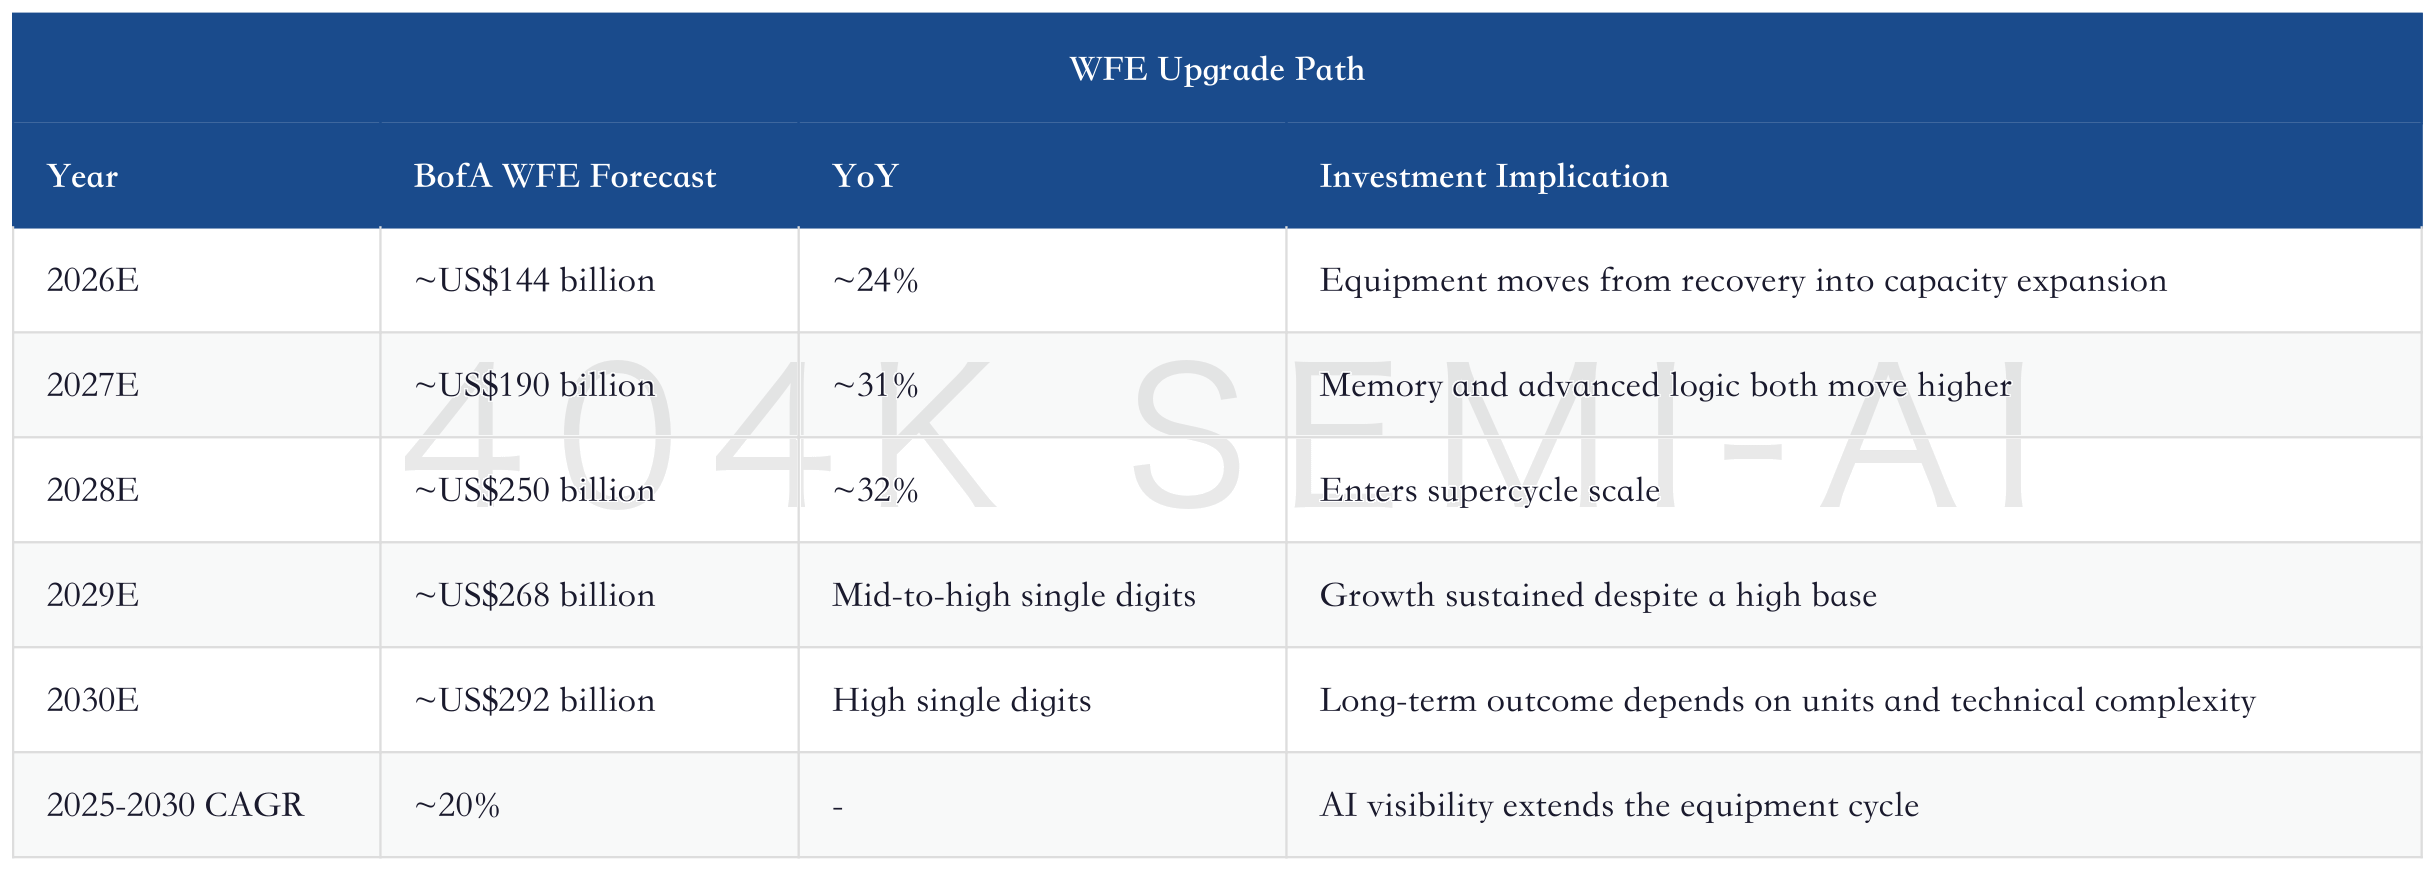
BofA emphasizes that investors cannot look only at WFE intensity. Current semiconductor revenue growth includes a large ASP contribution, especially from rising memory prices, which can make WFE as a percentage of sales appear to decline. Looking only at intensity can therefore lead to the mistaken conclusion that equipment demand is weakening. The more important metric is equipment spending per 12-inch wafer, or WFE per wafer. As advanced processes, HBM, DRAM EUV, NAND layer counts, advanced packaging, and yield requirements all rise, each wafer requires more equipment and more process steps.
This explains why equipment companies can continue to rerate in years when “intensity appears to decline.” Rising memory prices expand the denominator, but memory manufacturers still need to buy more equipment to add real capacity, improve yield, and introduce HBM and advanced DRAM. DRAM and NAND technology migrations in particular are not only about building new capacity, but also about upgrading existing capacity to more complex nodes.
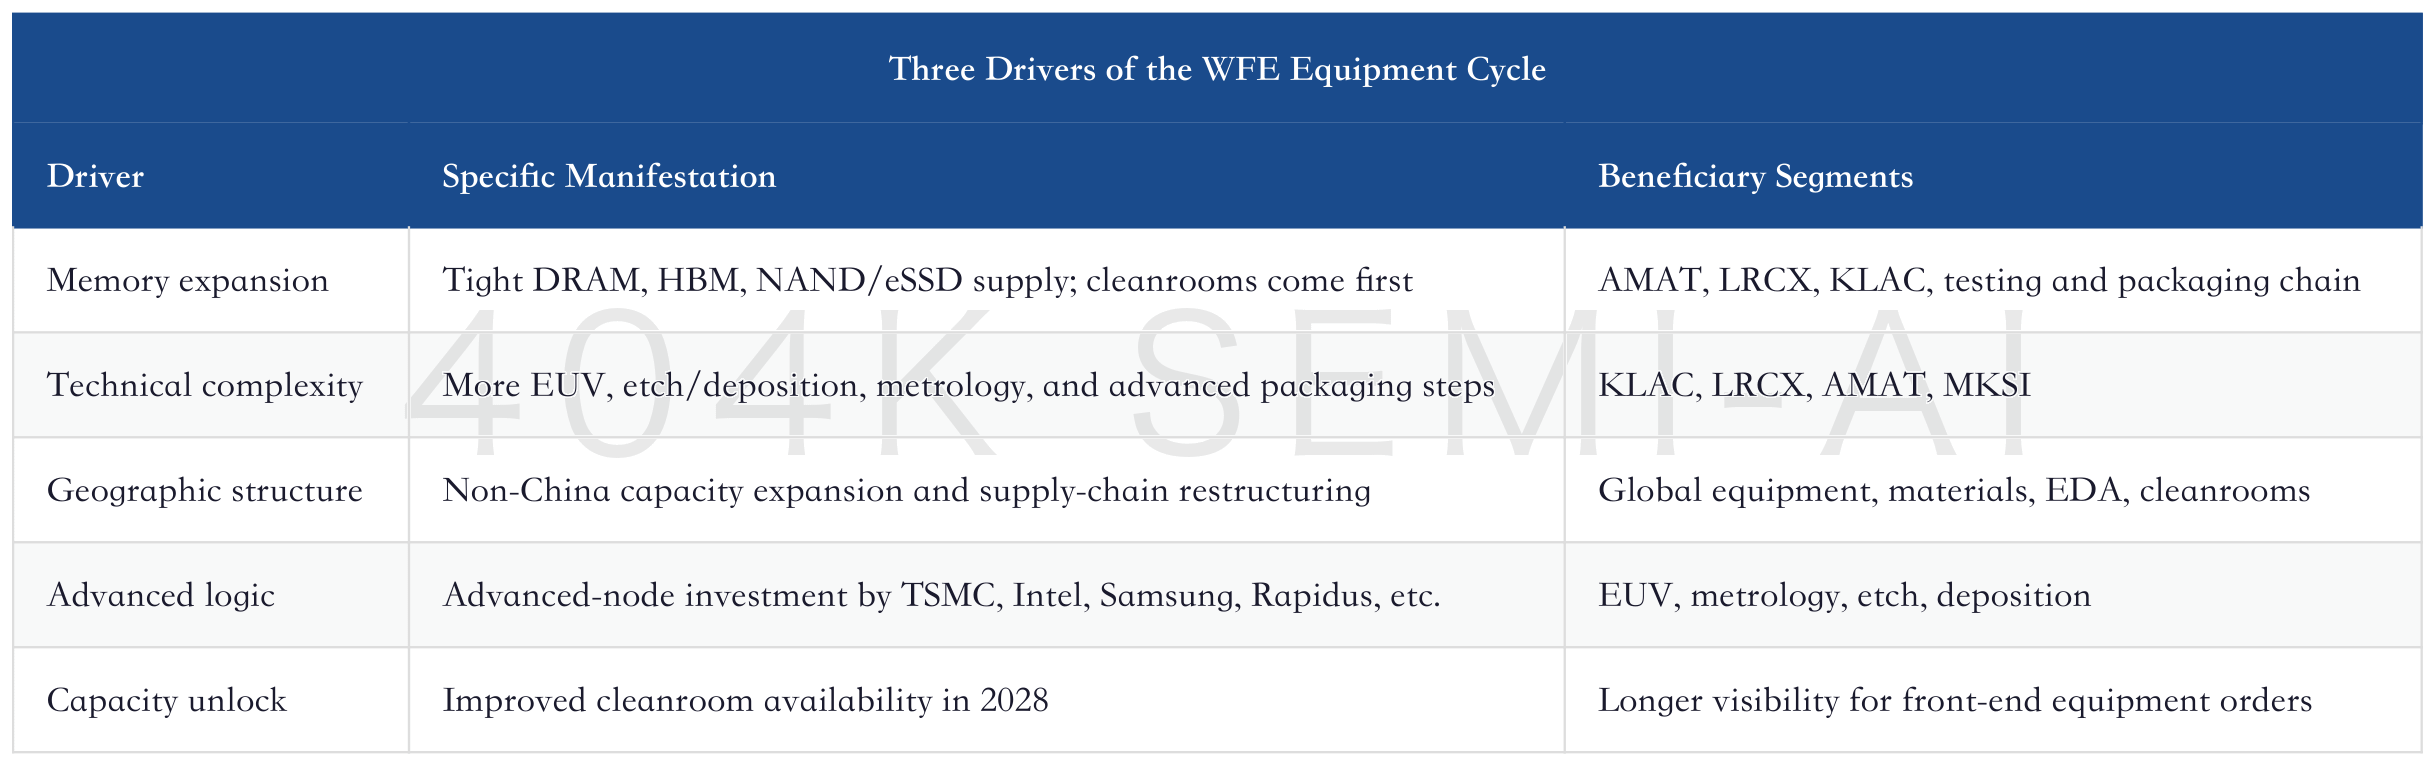
BofA also treats non-China WFE as an important variable. From 2025 to 2030, non-China WFE CAGR is meaningfully higher than China WFE CAGR, driven by supply-chain restructuring, advanced nodes, AI/HPC, and global capacity expansion projects. This shift matters for equipment companies: if incremental demand comes from advanced logic, DRAM, EUV, and non-China advanced capacity, earnings quality is generally better than in mature-node price competition.
The WFE upgrade cannot be judged only by order value; investors also need to assess whether equipment companies can convert the cycle into margins. Leading equipment companies have two embedded business-model levers. One is service and spare-parts revenue from a larger installed base. The other is mix improvement from rising advanced-process complexity. If incremental WFE mainly comes from price competition in mature nodes, equipment-company revenue may rise, but margins may not expand in parallel. If the incremental demand comes from DRAM EUV, advanced logic, advanced packaging, process control, and high-end etch/deposition, earnings quality is usually better.
This explains why KLAC holds a high position in this equipment rerating cycle. Process control does not directly determine the number of incremental wafers, but it determines yield ramp in highly complex production lines. The more complex AI chips become, the more chiplets they use, the higher HBM stacks go, and the denser advanced packaging becomes, the more valuable defect inspection and metrology become. KLAC monetizes the “complexity tax,” not a simple capacity-expansion tax. Its revenue elasticity may be lower than that of broader front-end equipment names, but its earnings quality and valuation stability are often stronger.
AMAT and LRCX are closer to the main beta of the WFE supercycle. AMAT covers deposition, materials engineering, advanced packaging, and services, giving it broader exposure. LRCX is more sensitive to etch, deposition, NAND and DRAM technology migration; if NAND/eSSD again becomes a data-center capacity asset, LRCX’s slope becomes more attractive. MKSI and AEIS represent subsystems and power, where elasticity is more about spillover from equipment complexity and requires monitoring order conversion and cash-flow improvement.
There is also an easily overlooked time lag in the equipment chain. From semiconductor manufacturers announcing capex to cleanrooms becoming available, tools moving in, process tuning, and yield ramp, the process often spans multiple quarters. If the market focuses only on current-quarter orders, it can underestimate the length of the cycle; if it looks only at long-term TAM, it can miss the risk of orders being pulled forward. A more robust framework is to split equipment stocks into three lines: order visibility, margin quality, and continuity of customer capex. Only when all three improve at the same time is the equipment supercycle truly being realized.
VI. How to Rank Equipment Companies: AMAT, LRCX, KLAC, and MKSI Do Not Have the Same Elasticity
Behind BofA’s target-price increases for equipment companies is a clear judgment: if 2028 WFE reaches $250 billion, leading equipment companies still have significant EPS upside. But different equipment companies derive their elasticity from different positions.
AMAT’s core is broad-based equipment exposure and multi-point exposure to DRAM, advanced packaging, and foundry. BofA raised its AMAT price target to $720, arguing that in a higher-WFE environment, its EPS power could be meaningfully above consensus. AMAT’s strength is breadth of coverage; its weakness is that it needs to prove gross margin and service revenue can turn the large cycle into profits.
LRCX’s elasticity comes more from etch, deposition, NAND upgrades, and advanced packaging. BofA raised its LRCX price target to $480, emphasizing share opportunities in NAND greenfield, foundry/logic, DRAM, and advanced packaging. If NAND/eSSD shifts from a weak cycle into a data-center capacity asset, LRCX’s slope becomes stronger.
KLAC’s key is process control. BofA raised its KLAC price target from $210 to $317, with a significant increase in the valuation multiple as well. The reason is that process complexity, design counts, advanced packaging, yield ramp, and defect inspection all increase process-control density in the AI era. KLAC may not be the largest beneficiary of total WFE, but it is more like the collector of the “complexity tax.”
MKSI is more oriented toward components, subsystems, and advanced packaging/PCB complexity. BofA raised its price target to $500, highlighting benefits to its semiconductor, electronics, and packaging businesses from the etch/dep inflection and AI substrate/PCB demand. It is not a pure-play equipment leader, but it has solid operating leverage when complexity rises.
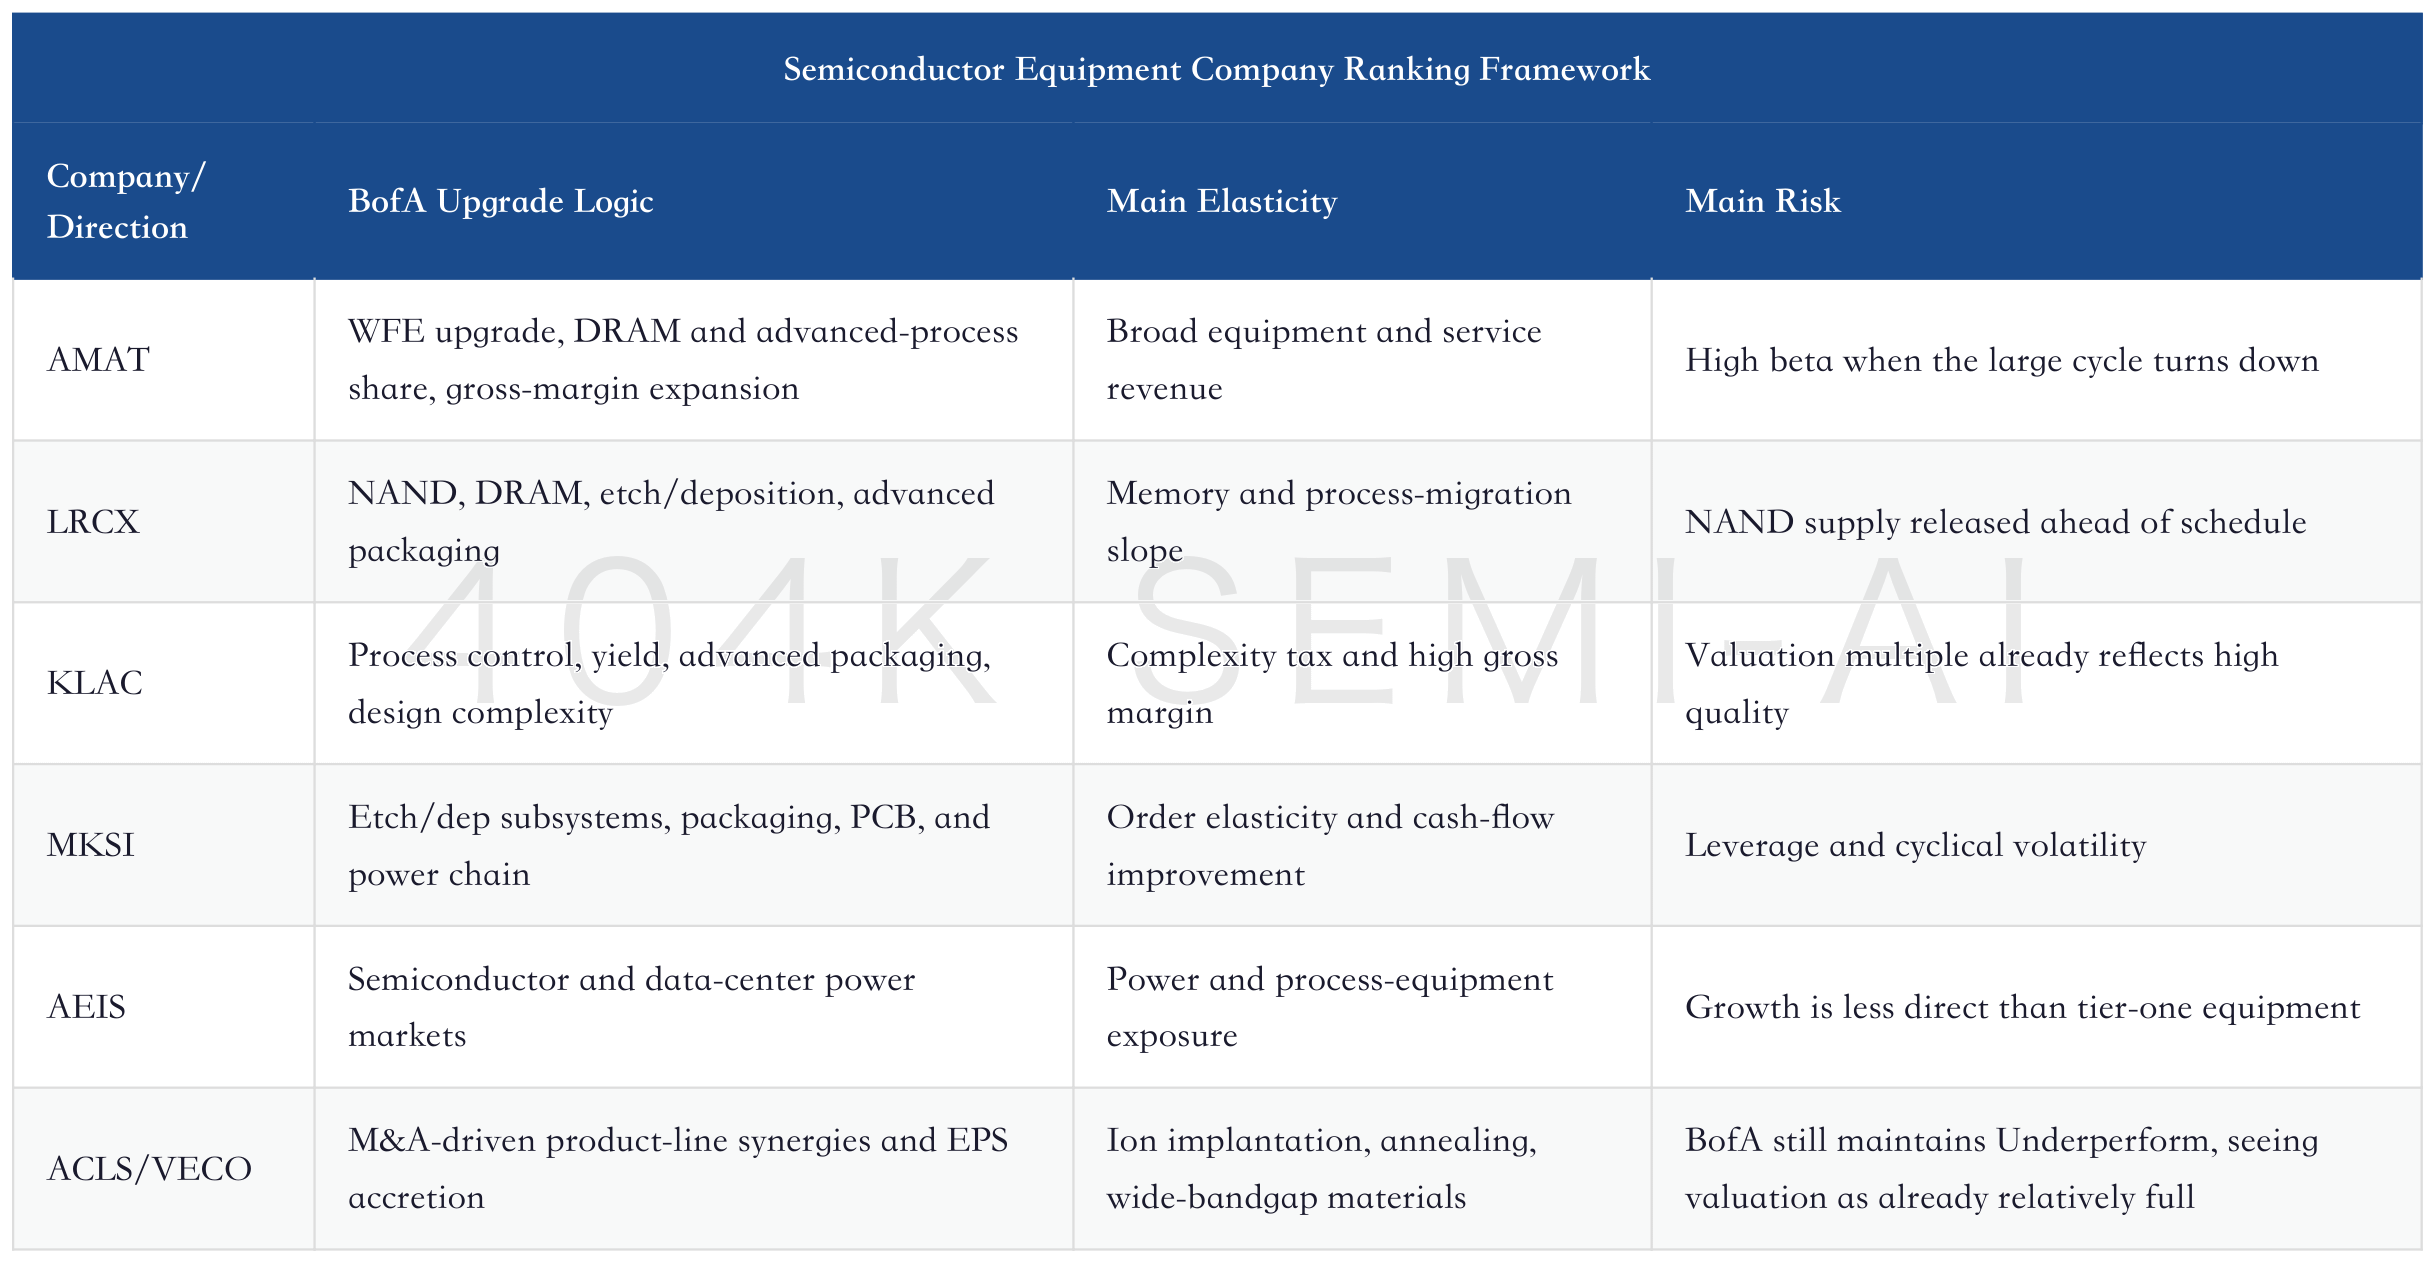
The ways to disprove the equipment-chain thesis are also clear: if cloud capex is revised down, equipment orders will be reassessed; if memory manufacturers release capacity in a concentrated way around 2028, equipment orders could be pulled forward and then fall back; if advanced-node progress is slower than expected, incremental EUV, metrology, and etch demand will be delayed; and if China’s mature-node capacity continues to digest existing capacity, mature-equipment demand will be weaker.
7. CPUs Return to the Main Battlefield: Intel and Arm Make Different Bets
The next phase of AI semiconductors is not just about more GPUs; CPUs are becoming important again. The reason is not that CPUs replace GPUs, but that inference and agentic AI require more scheduling, memory addressing, tool calls, database access, state maintenance, and multi-tenant management. GPUs handle high-throughput matrix computation; CPUs make complex workflows run.
BofA sets the server CPU TAM at roughly $170 billion by 2030 and believes the Arm architecture has a chance to approach half of server CPU value share, with part of that coming from merchant CPUs and part from cloud providers’ in-house CPUs. The core point is not Arm replacing x86, but server CPUs shifting from “losing the narrative to GPUs” to becoming an essential component of AI system coordination.
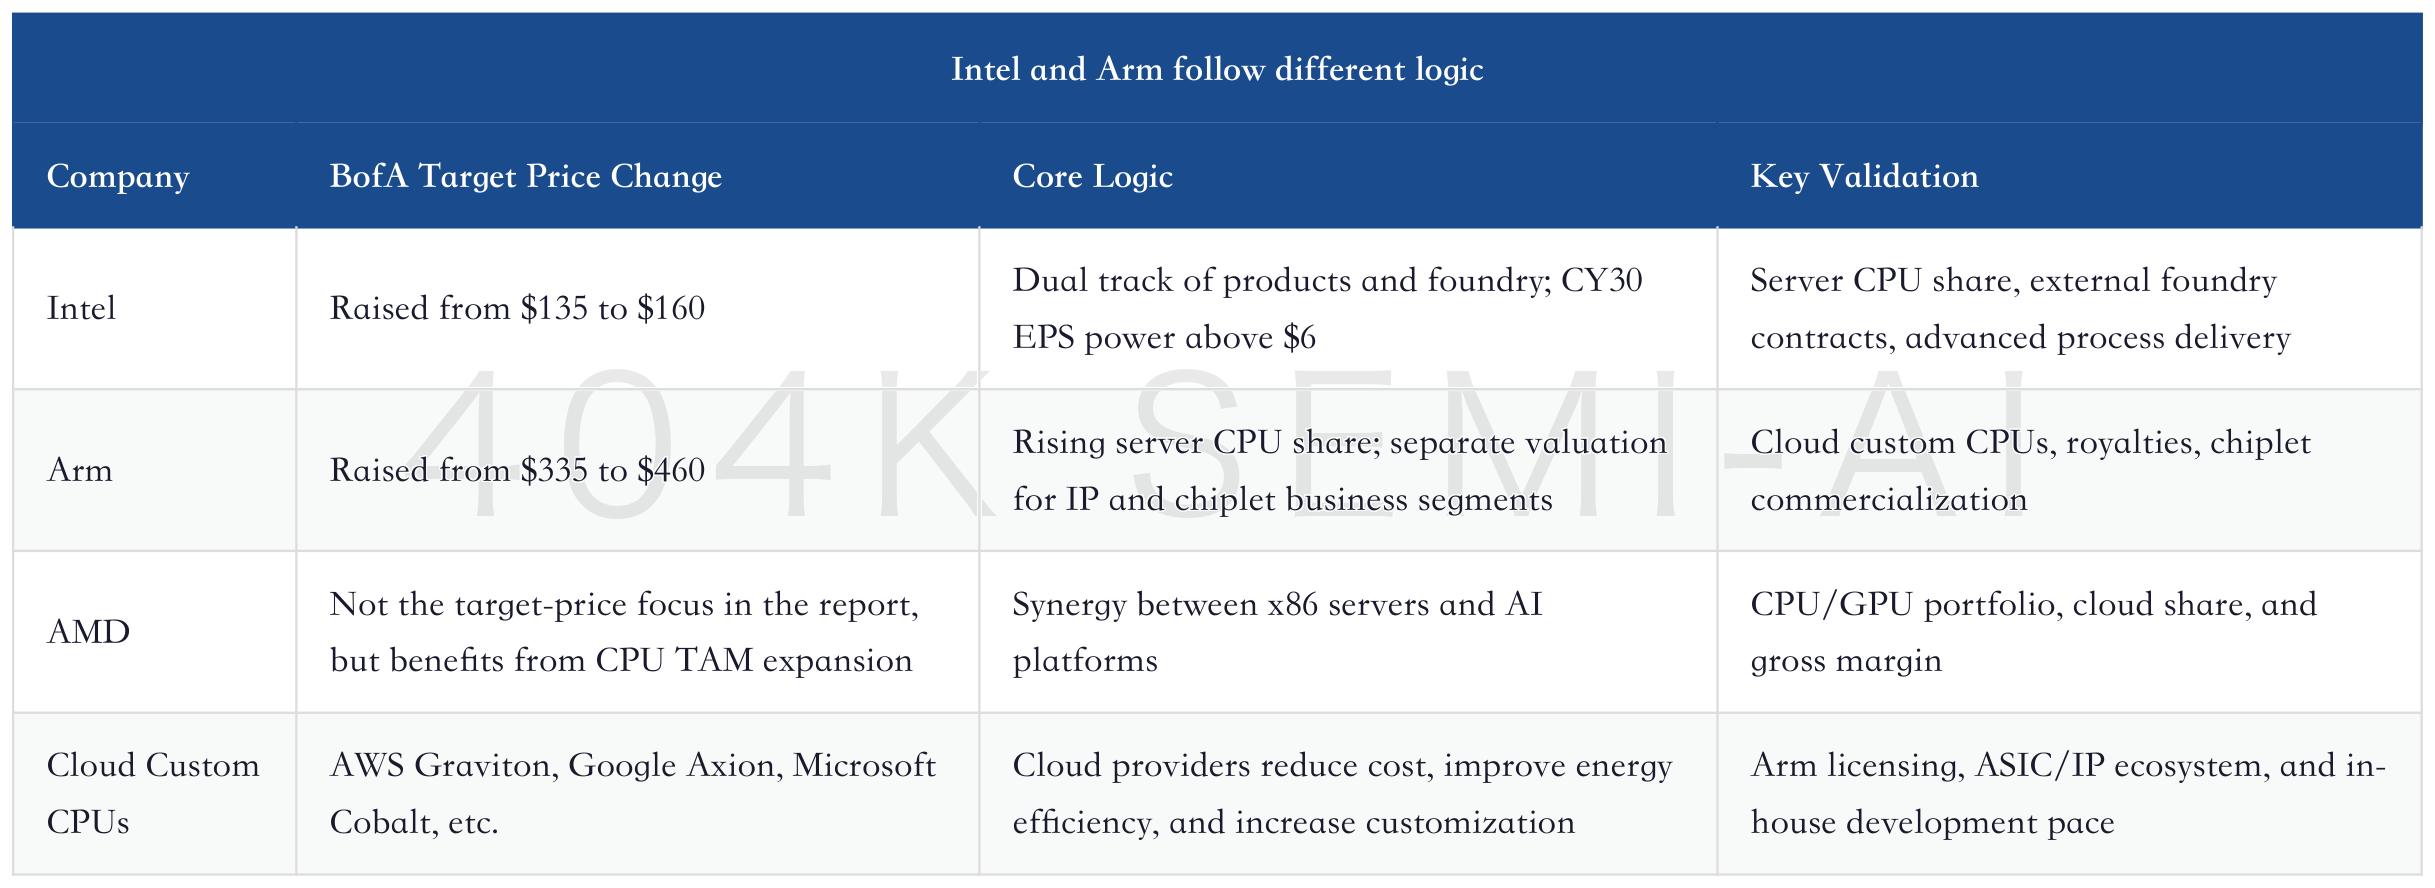
Intel’s logic is more like an “undervalued rebuilding option.” BofA revalues the company using CY30 EPS power and incorporates the product business, foundry, Apple/MediaTek TPU wafers, Terafab, and other HPC products into the model. This model is aggressive, and the implied requirements behind it are also high: Intel must not only restore product competitiveness, but also prove that foundry can absorb external customers and that advanced process and packaging can be delivered on time.
Arm’s logic is more like a “server CPU royalty and chiplet option.” The traditional IP business can be valued like a high-growth IP company, while the new chip business is valued separately using an AI compute P/E. BofA maintains a Neutral rating because the share price already reflects many opportunities, but it acknowledges that Arm is one of the clearest ecosystem beneficiaries of the server CPU tide.
The biggest risk in the CPU theme is that the market writes it too linearly. GPUs and ASICs may continue to retain a large amount of value in the accelerators themselves, and cloud providers’ in-house chips may also compress merchant CPU profits. Intel needs process technology, customers, capex, and organizational execution to all come through at the same time; Arm needs its chiplet business to become genuinely commercial, not merely see licensing revenue rise. CPUs are back at the main table, but they are not risk-free winners yet.
Intel’s upward revision especially needs to be viewed within a scenario framework. In a bullish scenario, server CPU share stabilizes, foundry wins large external customers, and advanced packaging and process nodes progress on schedule, prompting the market to again assign it a manufacturing-platform option. In a neutral scenario, the product business improves but foundry losses narrow slowly, and the stock trades more like a semiconductor recovery story. In a bearish scenario, capex pressure and customer onboarding delays consume EPS power, and the valuation returns to the traditional x86 cycle.
Arm’s debate is different. Its advantage is a lighter ecosystem position, with cloud custom CPUs, server IP, and chiplets all capable of generating high-margin revenue. The problem is that the valuation is already pre-buying rising server share. If Arm merely delivers steadier royalties, the stock’s upside is limited; if chiplets or semi-custom compute commercialize beyond expectations, the market will push it further from an IP company toward an AI compute platform asset. BofA’s Neutral rating shows that a good direction does not mean a cheap price.
The key issue to watch in CPUs is not “who wins, x86 or Arm,” but how much value AI inference architecture returns to the host side. In the training era, GPUs and HBM were the most visible. In the inference and agentic workflow era, task scheduling, memory access, data preprocessing, tool calls, and multi-tenant management will make CPUs part of system efficiency again. As long as inference workloads become increasingly complex, CPU value will not disappear, but the winners will depend on platform share, power efficiency, and the depth of cloud-customer customization.
8. Interconnect and Data Movement: What MRVL, CRDO, and ALAB Have in Common, and How They Differ
The larger AI clusters become, the more expensive data movement gets. If GPU compute cannot be fed by networks, interconnects, retimers, DSPs, AECs, CXL, and switching systems, utilization will fall. This is also the fundamental reason BofA raised MRVL, CRDO, and ALAB: AI needs not only compute, but also stable, low-latency, low-power movement of data to the right place.
Marvell Earnings Deep Dive: AI Custom Chips Enter the Delivery Validation Phase; How Data-Center ASICs and High-Speed Interconnects Are Revalued for FY2027
MRVL has the most comprehensive position. BofA raised its target price for MRVL from $240 to $365, centered on optical DSP, TIA, drivers, CPO, custom XPUs, and XPU attach. BofA continues to see MRVL’s EPS power exceeding $15 by 2030. Its story is not a single-product breakout, but the combined pull from data-center connectivity, custom silicon, and network attach chips.
CRDO is more focused on AECs and high-speed connectivity. BofA raised its target price for CRDO to $340, emphasizing current 100G/lane products, future 200G/lane products, AEC adoption by multiple cloud customers, and new product lines including optical DSP, ZF optics, ALC, and PCIe retimers. CRDO’s advantages are high growth and customer validation; its risks are product concentration, competition, and the pace of cloud-provider procurement.
ALAB’s story is retimers and new product platforms. BofA raised its target price for ALAB from $240 to $450, but kept its rating at Neutral, showing that the opportunity is large while the valuation is not cheap. Scorpio, custom fabrics, NVLink Fusion, UALink, and other directions are taking ALAB from a single retimer business toward a broader data-center connectivity platform, but the market has already assigned high expectations.
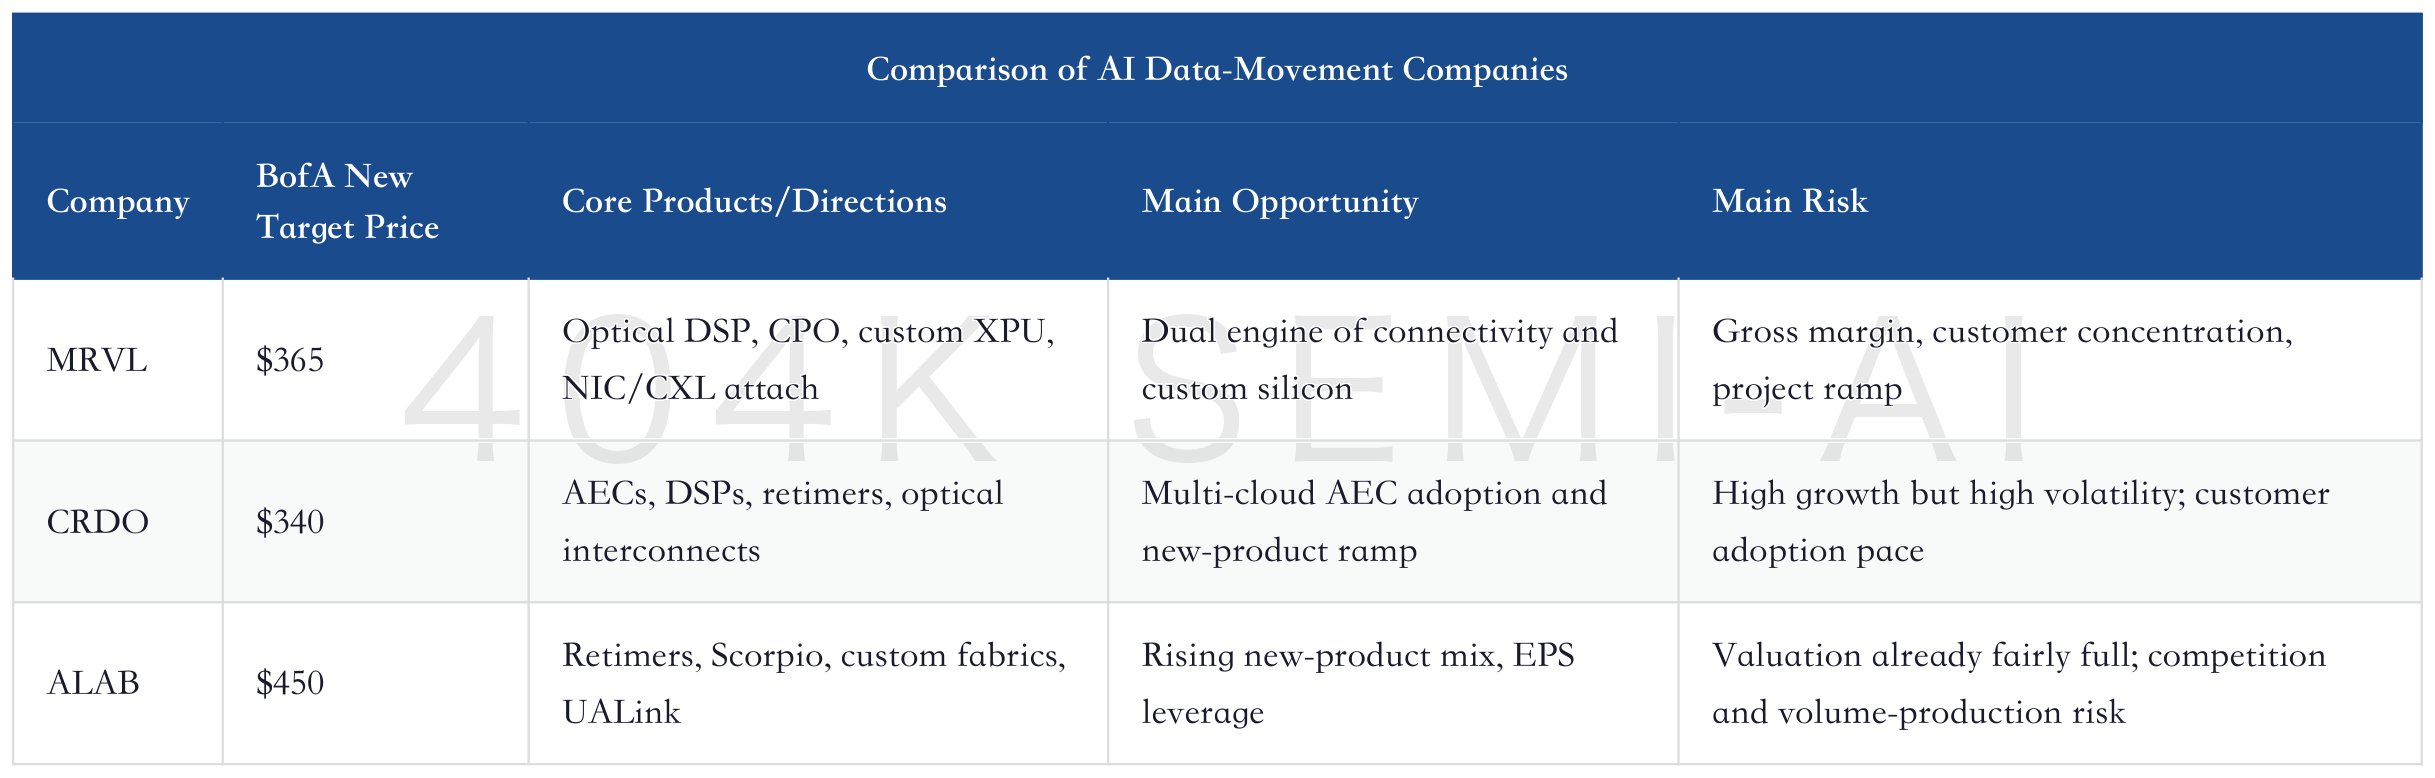
These three companies jointly answer one question: inside AI racks and clusters, besides GPUs, who determines effective compute? MRVL is more like a platform data-movement company, CRDO is a high-speed short-reach connectivity beta asset, and ALAB is a growth company in PCIe/CXL/retimers and future fabrics. They should not be valued with the same yardstick, but tiered by customer lock-in, product substitution risk, gross margin, and shipment cadence.
The core of the data-movement layer is not as simple as “higher bandwidth is better.” Each generation of AI clusters rebalances cost, power consumption, distance, reliability, and latency. Short-reach in-rack connectivity can be handled with AECs, copper cables, and retimers, while inter-rack and cluster-level scaling require optical modules, DSPs, CPO, or new network architectures. Different solutions are not absolute substitutes; they constantly migrate across the trade-offs of power, cost, and distance.
MRVL’s advantage is its broad product span. It has optical DSPs and high-speed analog front ends, as well as custom XPUs and data-center connectivity chips, giving it multiple entry points as customer system architectures change. Its risks also come from that comprehensiveness: slow project ramps, customer concentration, and changes in gross-margin structure can all affect valuation realization. Investors buying MRVL are not buying a single product cycle, but the system-level expansion of AI data centers from compute to connectivity to custom silicon.
CRDO’s advantage is purer high-growth interconnect beta. If AECs continue to expand penetration among multi-cloud customers, the revenue slope will look attractive; but it is also more exposed to a single product cycle and customer shipment timing. ALAB sits at the platformization inflection point of retimers, PCIe/CXL, and future fabrics, with large growth space but a more difficult valuation digestion path. Among the three, MRVL looks more like a core asset, CRDO more like high beta, and ALAB more like a high-valuation option.
The falsification points for this theme are especially concrete: if the migration to 200G/lane is slow, AECs are suppressed by optical solutions, CPO progresses below expectations, or cloud providers’ in-house connectivity chips replace third parties, data-movement company valuations will compress first. Conversely, if cloud customers begin locking in volumes early for next-generation racks, high-speed interconnects will move from “AI infrastructure support” to “compute-utilization assets,” and valuation anchors will continue shifting toward longer-term revenue capacity.
IX. Testing: TER Is the Low-Visibility, High-Elasticity Link in Back-End Validation
Testing is often overlooked in many AI semiconductor discussions, but Bank of America’s decision to raise its TER price target from $365 to $525 shows that testing complexity is entering valuation. The more complex AI chips become, and the more HBM, ASICs, CPO, SiPho, high-speed interfaces, and custom silicon they incorporate, the more important test time, platform complexity, and customer qualification become.
Bank of America cited Teradyne’s comments at the conference: if the WFE environment reaches roughly $250 billion, ATE TAM could easily support a level of about $20 billion. This framing implies that testing as a share of WFE is rising modestly, rather than simply tracking semiconductor shipments. Testing complexity itself is increasing.
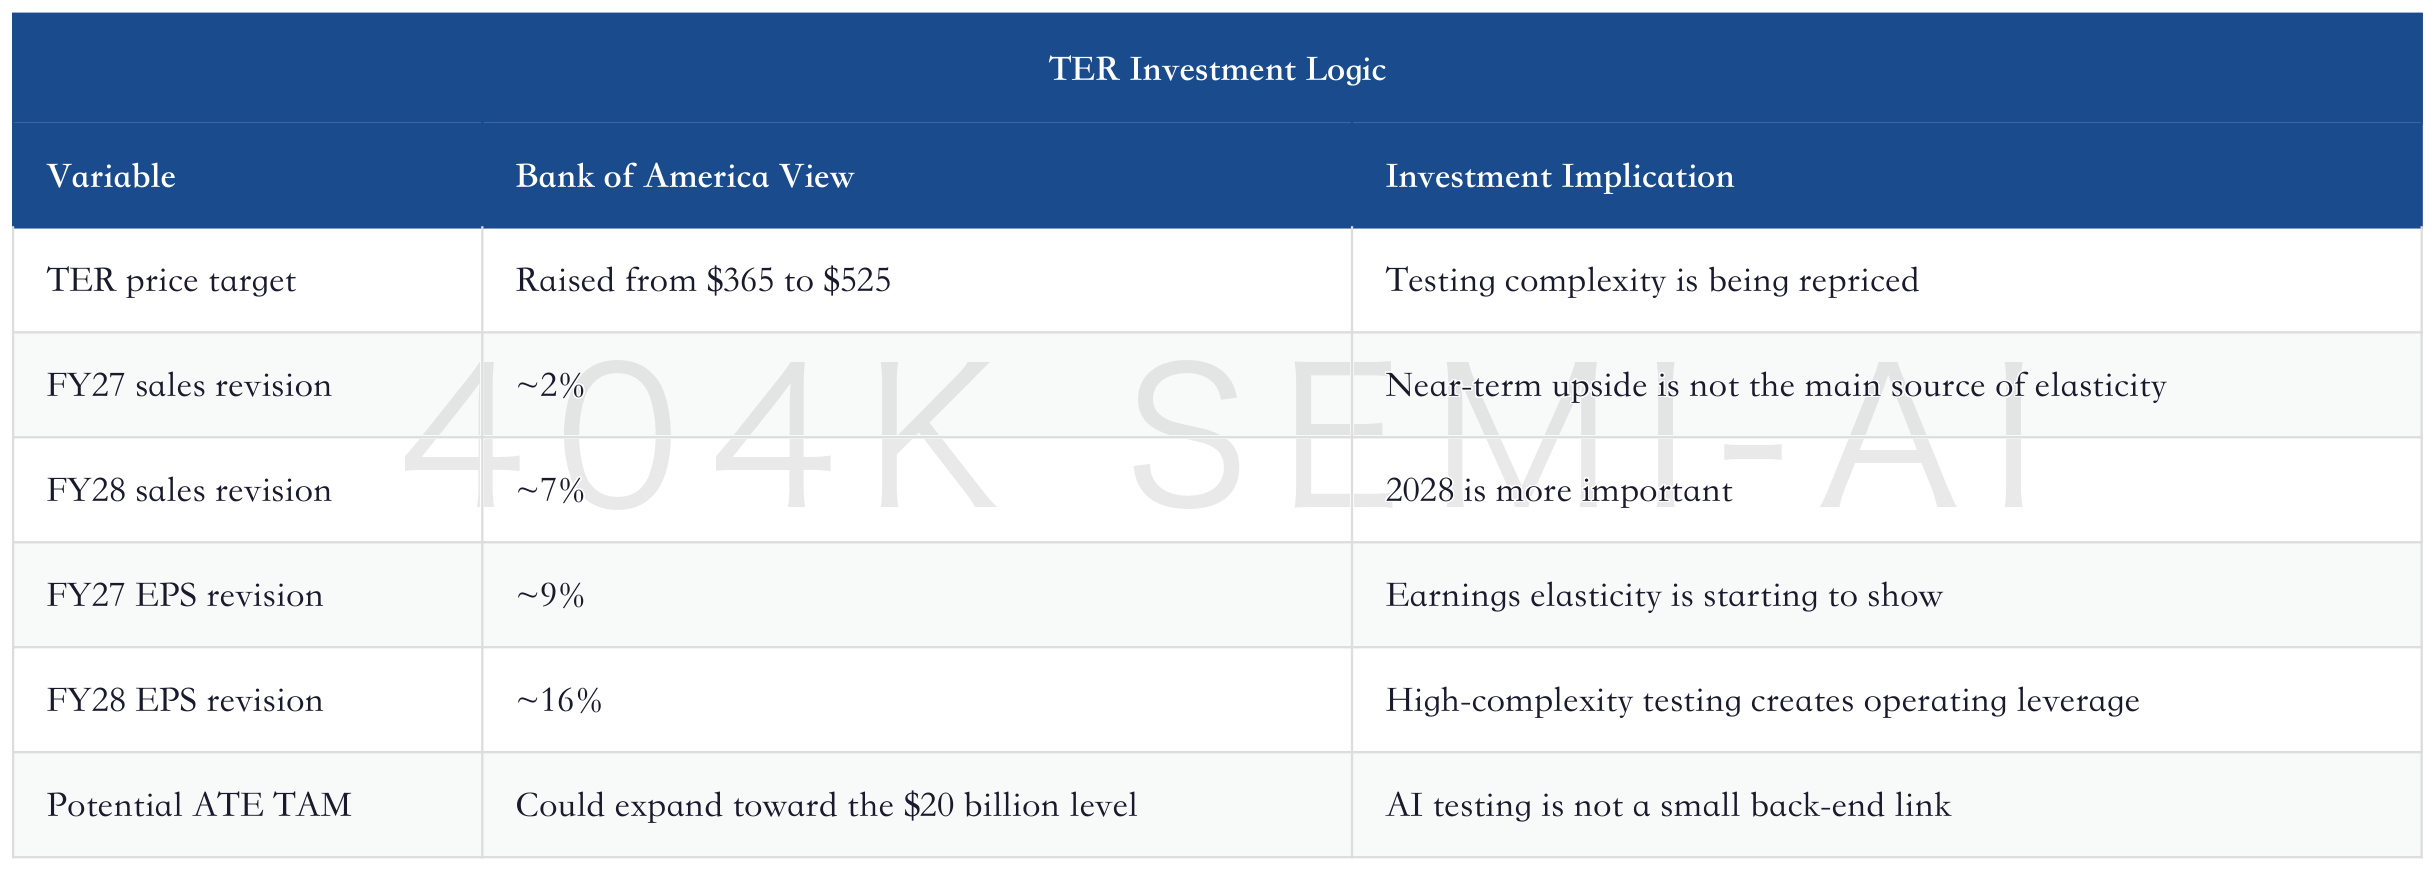
TER’s advantage is its exposure to custom ASICs, HBM/DRAM testing, CPO/silicon photonics, and robotics automation. Its weakness is that back-end testing has lower visibility than front-end WFE, and order cadence is more vulnerable to customer shipment schedules. Bank of America also cautions that 2H could decline due to the timing of custom ASIC tester shipments, so while the long-term view is constructive, the near term still needs 2Q earnings to provide clearer visibility.
Testing is the third layer of elasticity in this AI semiconductor cycle. The first layer is memory and equipment, because the supply bottlenecks are clear. The second layer is interconnect and CPUs, because the system architecture migration is underway. The third layer is testing and advanced packaging, because rising complexity will gradually flow through to the back end. TER may not be the fastest asset to deliver, but it proves that AI semiconductors are moving from “buying chips” to “buying validation capability.”
X. Price Target Revision List: Which Are Major Re-Ratings, and Which Are Merely Following Along
Bank of America’s latest revisions cover multiple companies, but they should not all be grouped into the same category. A more effective approach is to group them by “reason for re-rating”: memory assetization, WFE supercycle, data movement platforms, CPU optionality, testing complexity, and M&A;/synergies. Only then can we see whose revisions are highest quality.
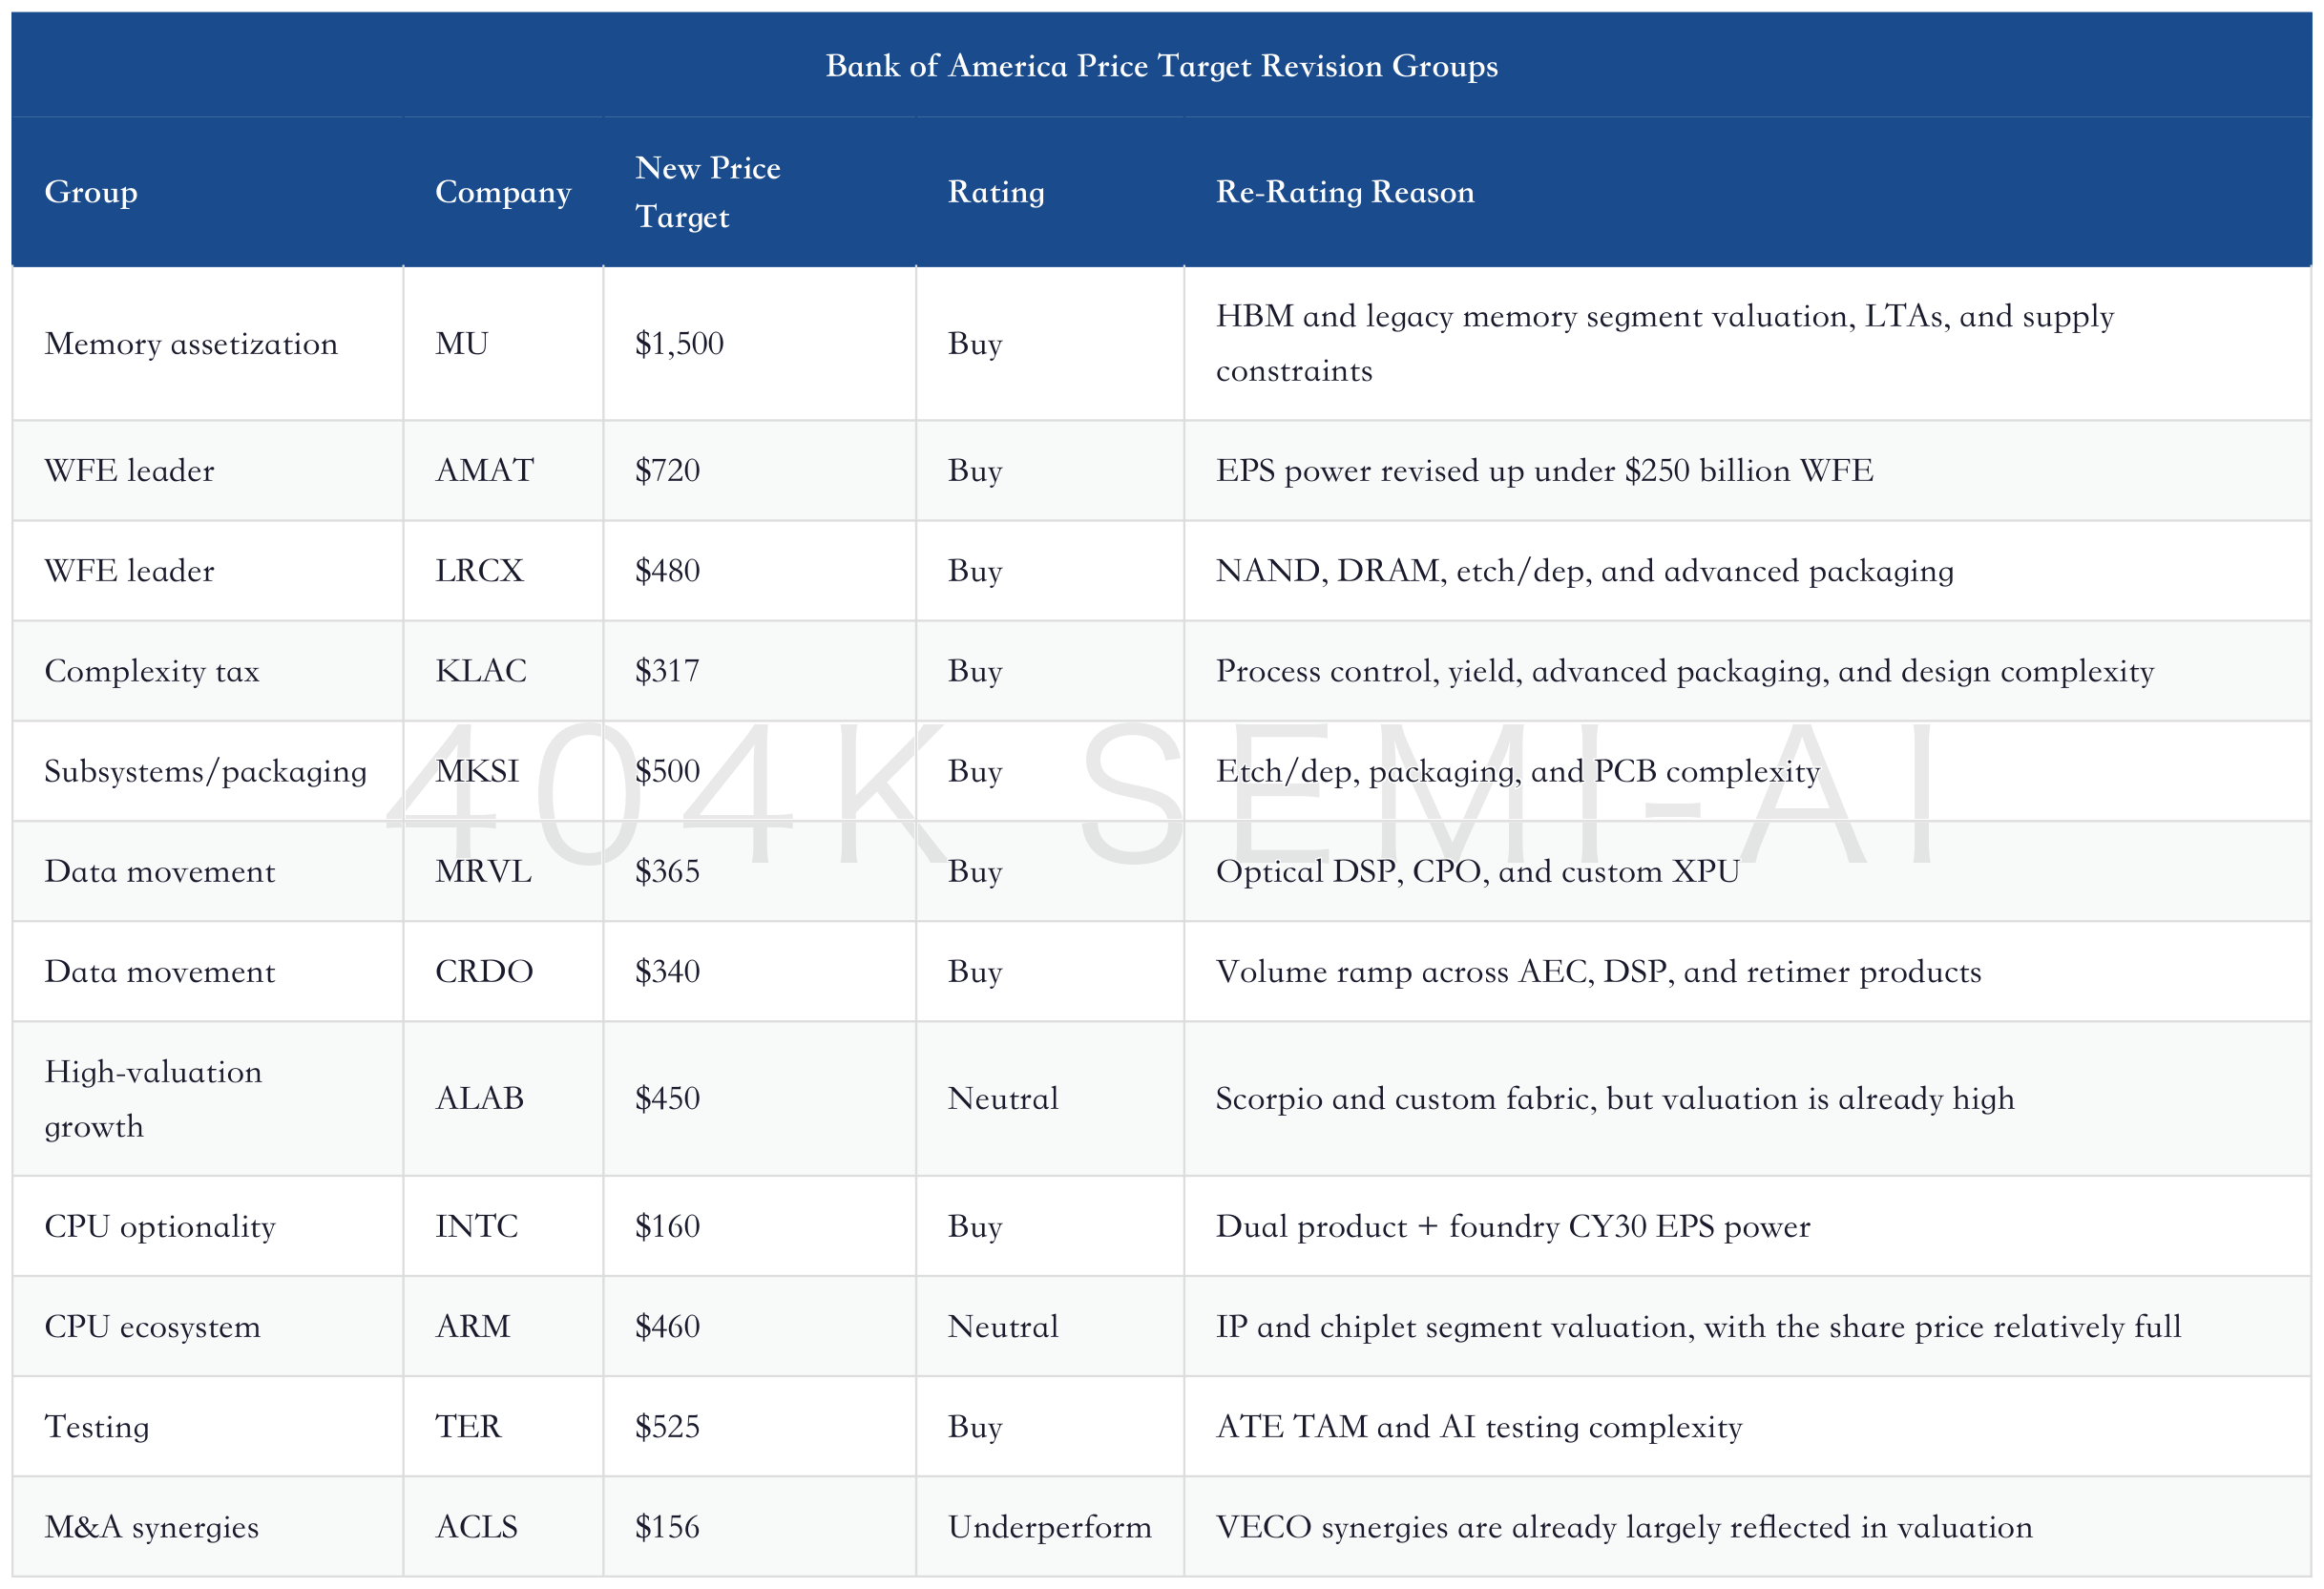
The most important point in this table is rating differentiation. Bank of America is not “blindly buying the whole industry.” ALAB saw a large price target increase but remains Neutral because the market has already assigned it a high valuation; ACLS had its price target raised but remains Underperform because much of the M&A; synergy is already reflected. This stance matters: AI exposure does not mean low risk, and a higher price target does not mean the valuation is cheap.
Major re-ratings have three characteristics. First, the earnings model is raised meaningfully, not merely rolled forward on valuation benchmarks. Second, the company controls a link with supply constraints or customer lock-in. Third, visibility beyond 2028 is not imaginary, but can be validated through LTAs, capacity, equipment orders, product introductions, or customer projects. MU, AMAT/LRCX/KLAC, MRVL/CRDO, and TER each satisfy different parts of this framework.
Follow-on revisions also have three characteristics. First, they are driven mainly by higher industry valuation multiples. Second, the price target is raised but the rating is unchanged or not especially strong. Third, the risk is that valuation has already priced in earnings several years out. The treatment of ALAB, ARM, and ACLS is closer to this category. They do not lack good stories; rather, the market has already bought those stories very fully.
This price target list can be split into three worldviews. The first is “AI demand continues to be revised up, and supply still cannot keep up.” In this case, MU, AMAT, LRCX, KLAC, and some high-end testing, packaging, and interconnect companies benefit the most, because their bottlenecks are the hardest. The second is “AI demand remains strong, but supply gradually catches up.” In this case, the elasticity of high-valuation growth stocks declines, and the market becomes more willing to buy leaders with higher earnings certainty, cash flow, and service revenue contribution. The third is “cloud capex slows.” In this case, almost all AI semiconductors come under pressure, but the first to be hit are companies where long-dated EPS power carries the highest weight in valuation.
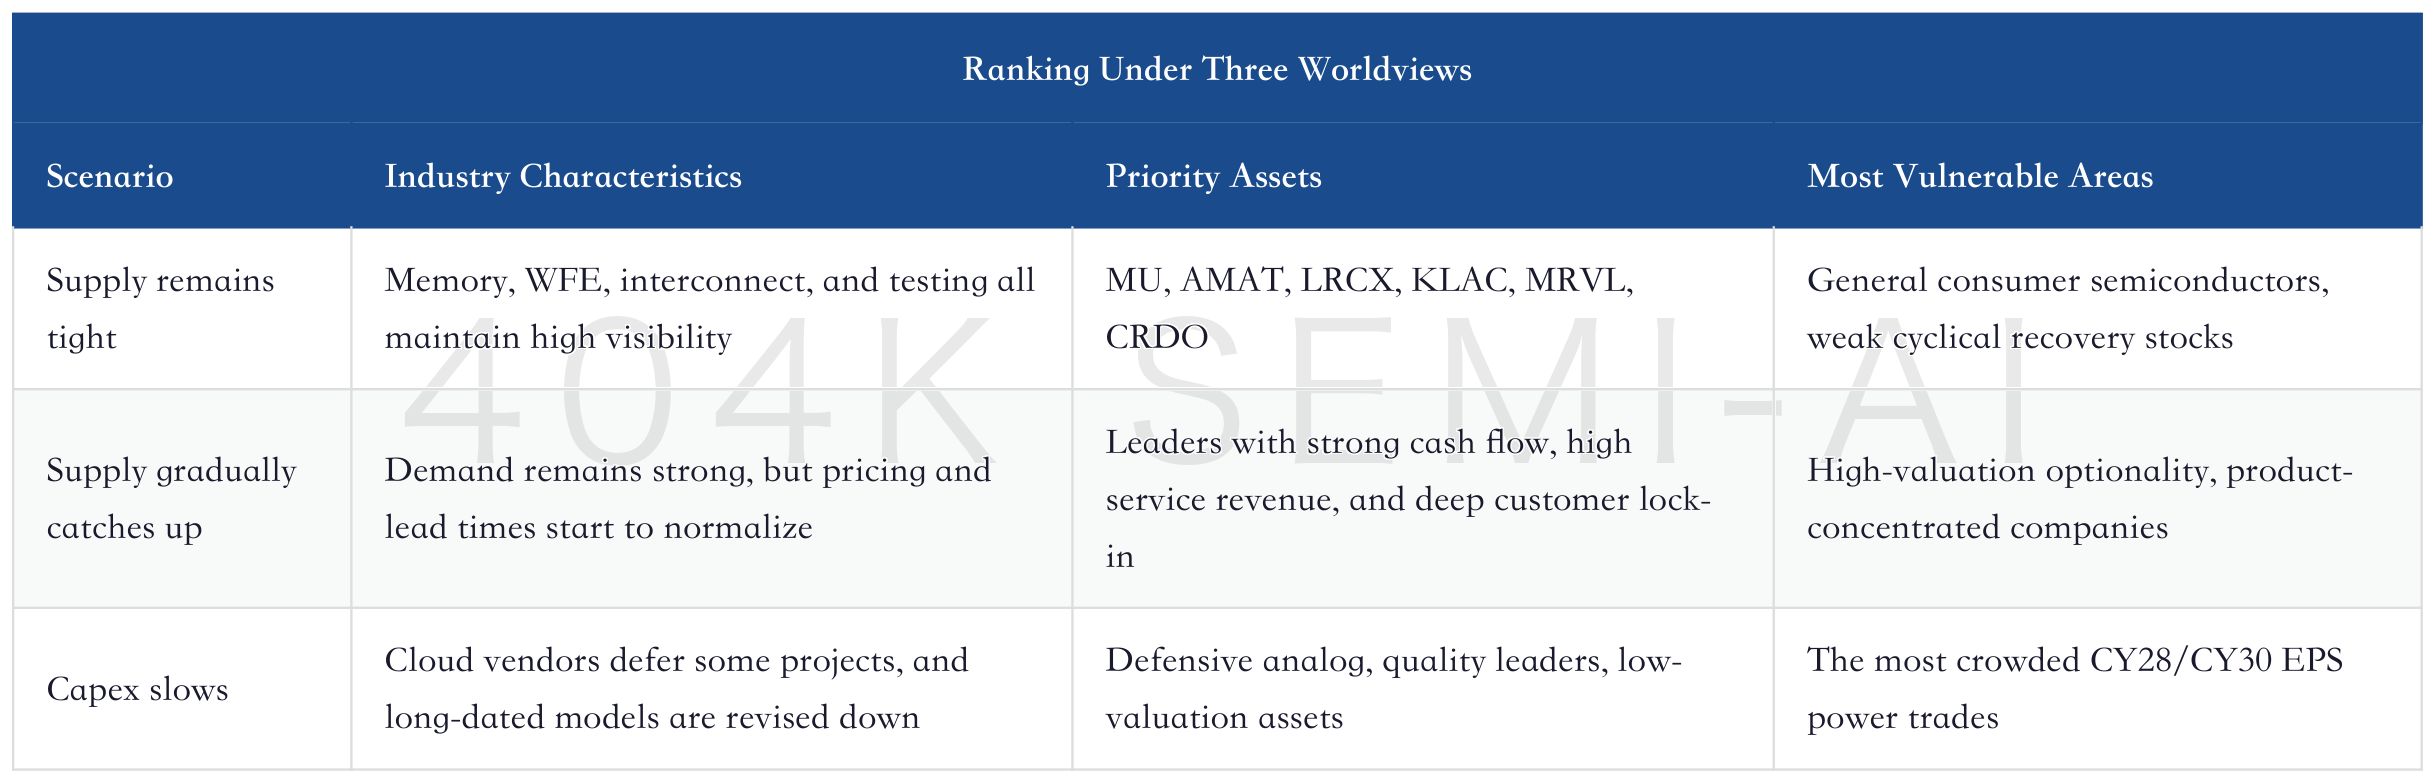
This scenario table is more useful than simply looking at price targets. Most of Bank of America’s price targets are already based on relatively optimistic medium- to long-term assumptions. What will really drive share prices over the next six months is whether these assumptions are revised up further, sustained, or discounted. If cloud capex remains strong over the next few quarters, HBM LTAs stay tight, and equipment orders continue to rise, the market will keep betting on the first worldview. If pricing and orders start to loosen, it will rotate to the second. If cloud budgets are adjusted, the third will quickly take over pricing.
11. How This Cycle Differs From Past Semiconductor Cycles
Traditional semiconductor cycles are typically driven by PCs, smartphones, servers, autos, and industrial inventory. The key variables are end-demand shipments, inventory, and capex. The AI cycle is different in three main ways.
First, demand is not a single end market; it is infrastructure buildout. Cloud providers, large models, inference platforms, enterprise AI, and sovereign AI are all building systems. As long as capex continues, demand is not just the quarterly fluctuation of a consumer end market.
Second, supply is not constrained by a single capacity point, but by multiple links at the same time. HBM requires advanced DRAM wafers and advanced packaging; WFE requires cleanrooms and equipment lead times; interconnect requires reliability qualification; CPUs and ASICs require customer ramps; testing requires new platforms. If any one link is blocked, system delivery slows.
Third, pricing power comes from delivery scarcity. In past cycles, price increases often triggered capacity expansion, eventually creating oversupply. The AI cycle will also follow that path, but the timeline may be longer because expansion requires buildings, equipment, yields, and customer qualification. BofA extending visibility to 2028 essentially reflects the view that supply release in this cycle will be slower than demand realization.
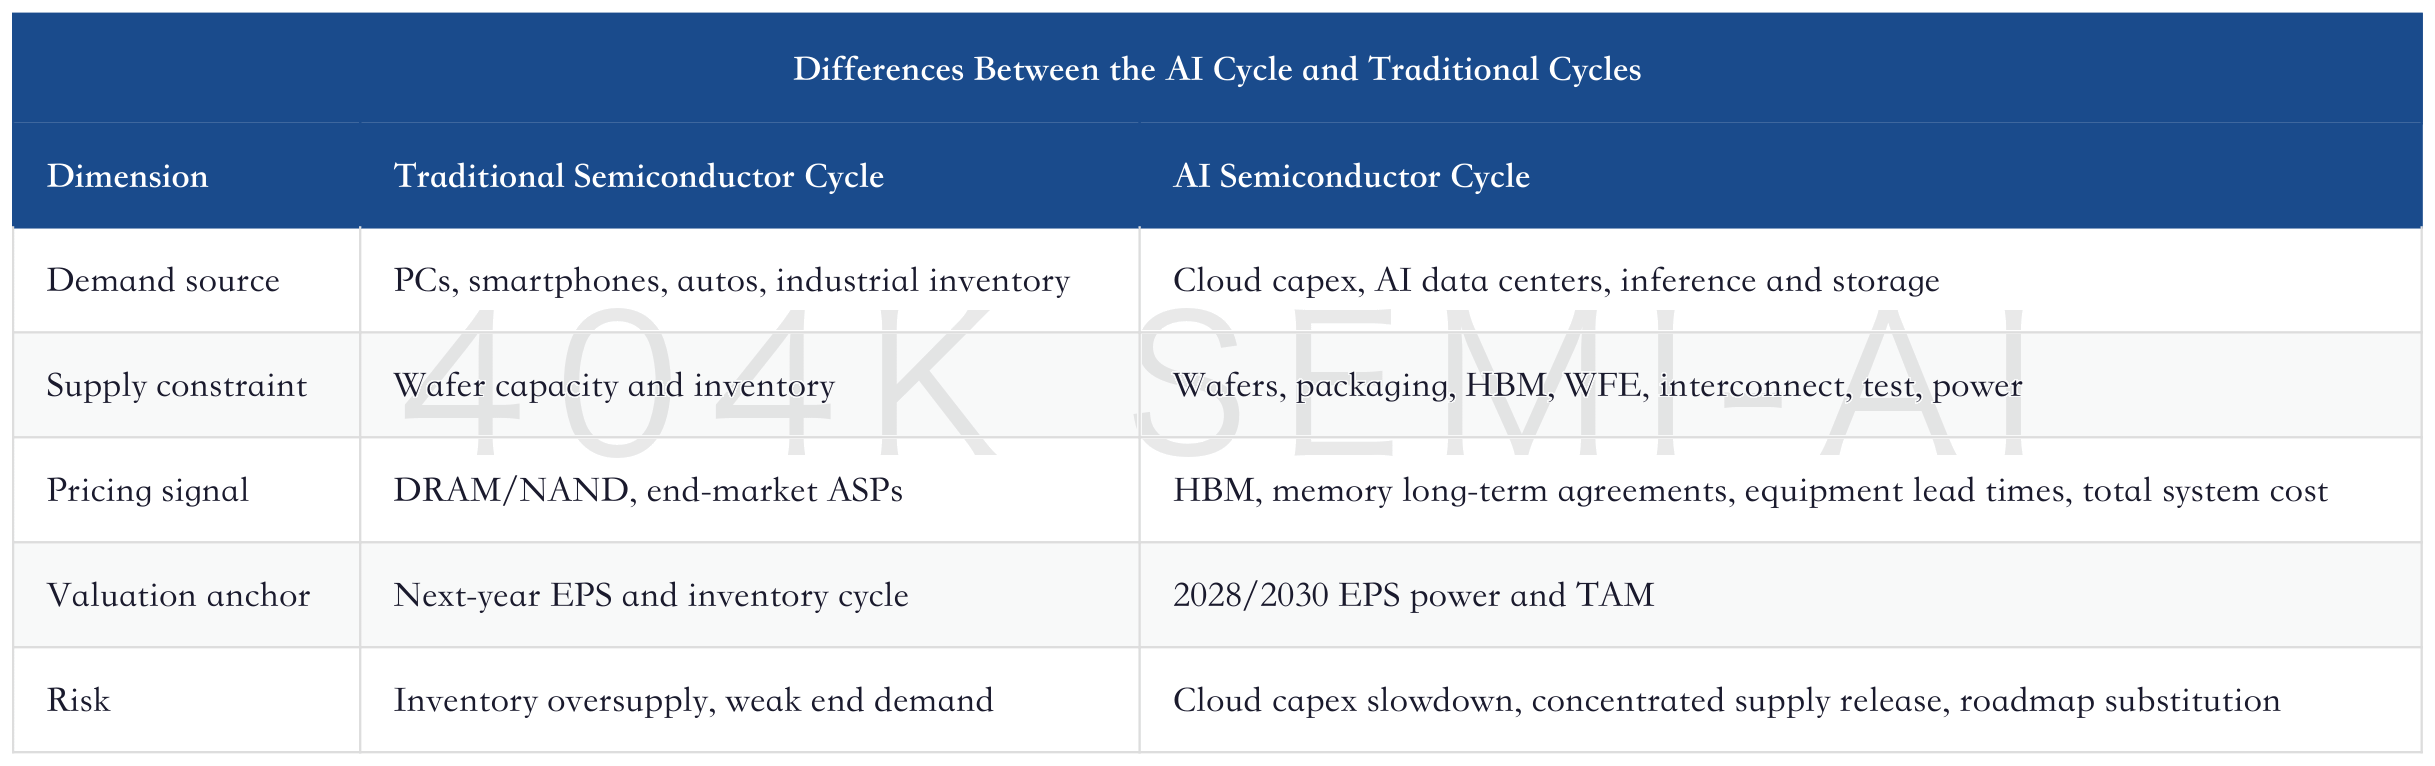
This does not mean AI semiconductors have no cycle. On the contrary, the cycle still exists, but the trough may be lifted by long-term contracts, complexity, and capex plans. The biggest risk is not that “AI demand suddenly disappears,” but that the market extrapolates supply constraints too far. Once customers start pushing on price, long-term agreements loosen, WFE lead times shorten, and memory prices roll over, valuations will adjust quickly.
The reason 2028 visibility has become critical is that many semiconductor investment decisions naturally have long cycles. Memory suppliers cannot build cleanrooms, introduce advanced DRAM, and expand HBM packaging in a single quarter. Equipment companies also need multiple reporting periods from order to installation, debugging, and acceptance. If cloud providers want to deploy larger-scale inference clusters over the next few years, they must lock in power, data centers, servers, networking, and chips in advance. These long chains can turn AI demand from short-term orders into multi-year delivery plans.
But “visibility” is not “certainty.” It is more like an evidence chain: customers are willing to sign long-term agreements, suppliers are willing to expand capacity, equipment orders continue, pricing is not broken by new supply, and end-user AI workloads genuinely absorb the added compute. If any link in the chain breaks, the market will shorten the valuation horizon again. What semiconductor stocks fear most is not a high long-term model, but a long-term model without near-term evidence to keep it alive.
This is also how this cycle differs from the 2021 equipment, memory, and automotive semiconductor cycle. At that time, price increases in many categories came from supply-chain disruption and inventory rebuilding; demand itself did not form a unified long-term infrastructure investment cycle. The stronger aspect of the AI cycle is that cloud capex, model inference, enterprise workflows, and sovereign AI are simultaneously lifting system demand. The more dangerous aspect is that the market is also more likely to misread short-term tightness as long-term scarcity. The boundary between the two is whether long-term agreements, orders, pricing, and customer ramps continue to validate each other.
If one were to define the core falsification condition for this report, it would be this: AI semiconductors revert from a “delivery bottleneck” back to an “ordinary order cycle.” Once memory prices are merely quarterly fluctuations, equipment orders begin to be deferred by customers, interconnect products are just short-term pull-ins from a few customers, CPU share does not materially change, and test complexity does not translate into platform demand, the market will no longer pay for earnings beyond 2028. Conversely, if this evidence continues to reinforce itself over the next four quarters, the valuation anchor will keep migrating toward long-term earnings power.
Therefore, 2028 is not a mechanical valuation year, but a stress-test year. It requires investors to answer whether a company’s products, capacity, customer relationships, and capex today can remain scarce two or three years from now. If the answer is yes, the market can tolerate short-term volatility. If the answer is only “AI-related,” without delivery bottlenecks and customer lock-in, high valuations will look fragile.
This stress test can also be applied to earnings analysis. For memory companies, look not only at revenue growth, but also ASPs, contract structure, days of inventory, and capex allocation. For equipment companies, look not only at order growth, but also non-China advanced capacity, DRAM/NAND technology migration, and service revenue. For interconnect companies, look not only at single-quarter shipments, but also product generations, customer count, and gross margin. For CPU and IP companies, look not only at TAM narratives, but also platform share, ecosystem lock-in, and unit economics. Only by linking these earnings indicators can investors judge whether long-term visibility in AI semiconductors is still improving.
The market often views semiconductors as a high-volatility industry, so every rally invites the question of whether it is a bubble. The better question is not “is there a bubble,” but “how much fundamental evidence remains before bubble conditions take over.” If valuations rise quickly while orders, pricing, customer lock-in, and capex also deepen in parallel, the rally still has fundamental support. If valuations rise quickly while the only evidence left is long-term TAM and target-price upgrades, risk increases. BofA’s report is not an unconditional bullish call; it is a bottleneck-trade framework that must be continuously validated.
12. Investment Ranking: Bottlenecks First, Beta Later
For investment purposes, the most important takeaway from this report is ranking, not simply saying “AI semiconductors remain strong.” Buying a basket purely on AI relevance can easily capture assets whose valuations already reflect the theme but whose profit retention is not strong enough. A better ranking is by bottleneck control.
The first tier is memory and equipment. Memory pricing, long-term agreements, and capacity constraints have already entered earnings reports. Equipment orders and WFE upgrades have clearer supply-chain transmission. This tier includes MU, AMAT, LRCX, KLAC, as well as related advanced packaging and test equipment.
The second tier is data movement and CPUs. The upside for MRVL, CRDO, ALAB, ARM, and INTC comes from system architecture migration. This is not a traditional cyclical recovery, but the shift in AI clusters from GPU-centric systems toward data movement, host scheduling, and custom compute. The risks are technology roadmaps and customer ramps.
The third tier is test, analog power, and Physical AI extensions. TER, AEIS, MKSI, analog power, and the power chain will benefit as system complexity rises, but the realization cadence is more dispersed and requires tracking customer projects and product cycles.
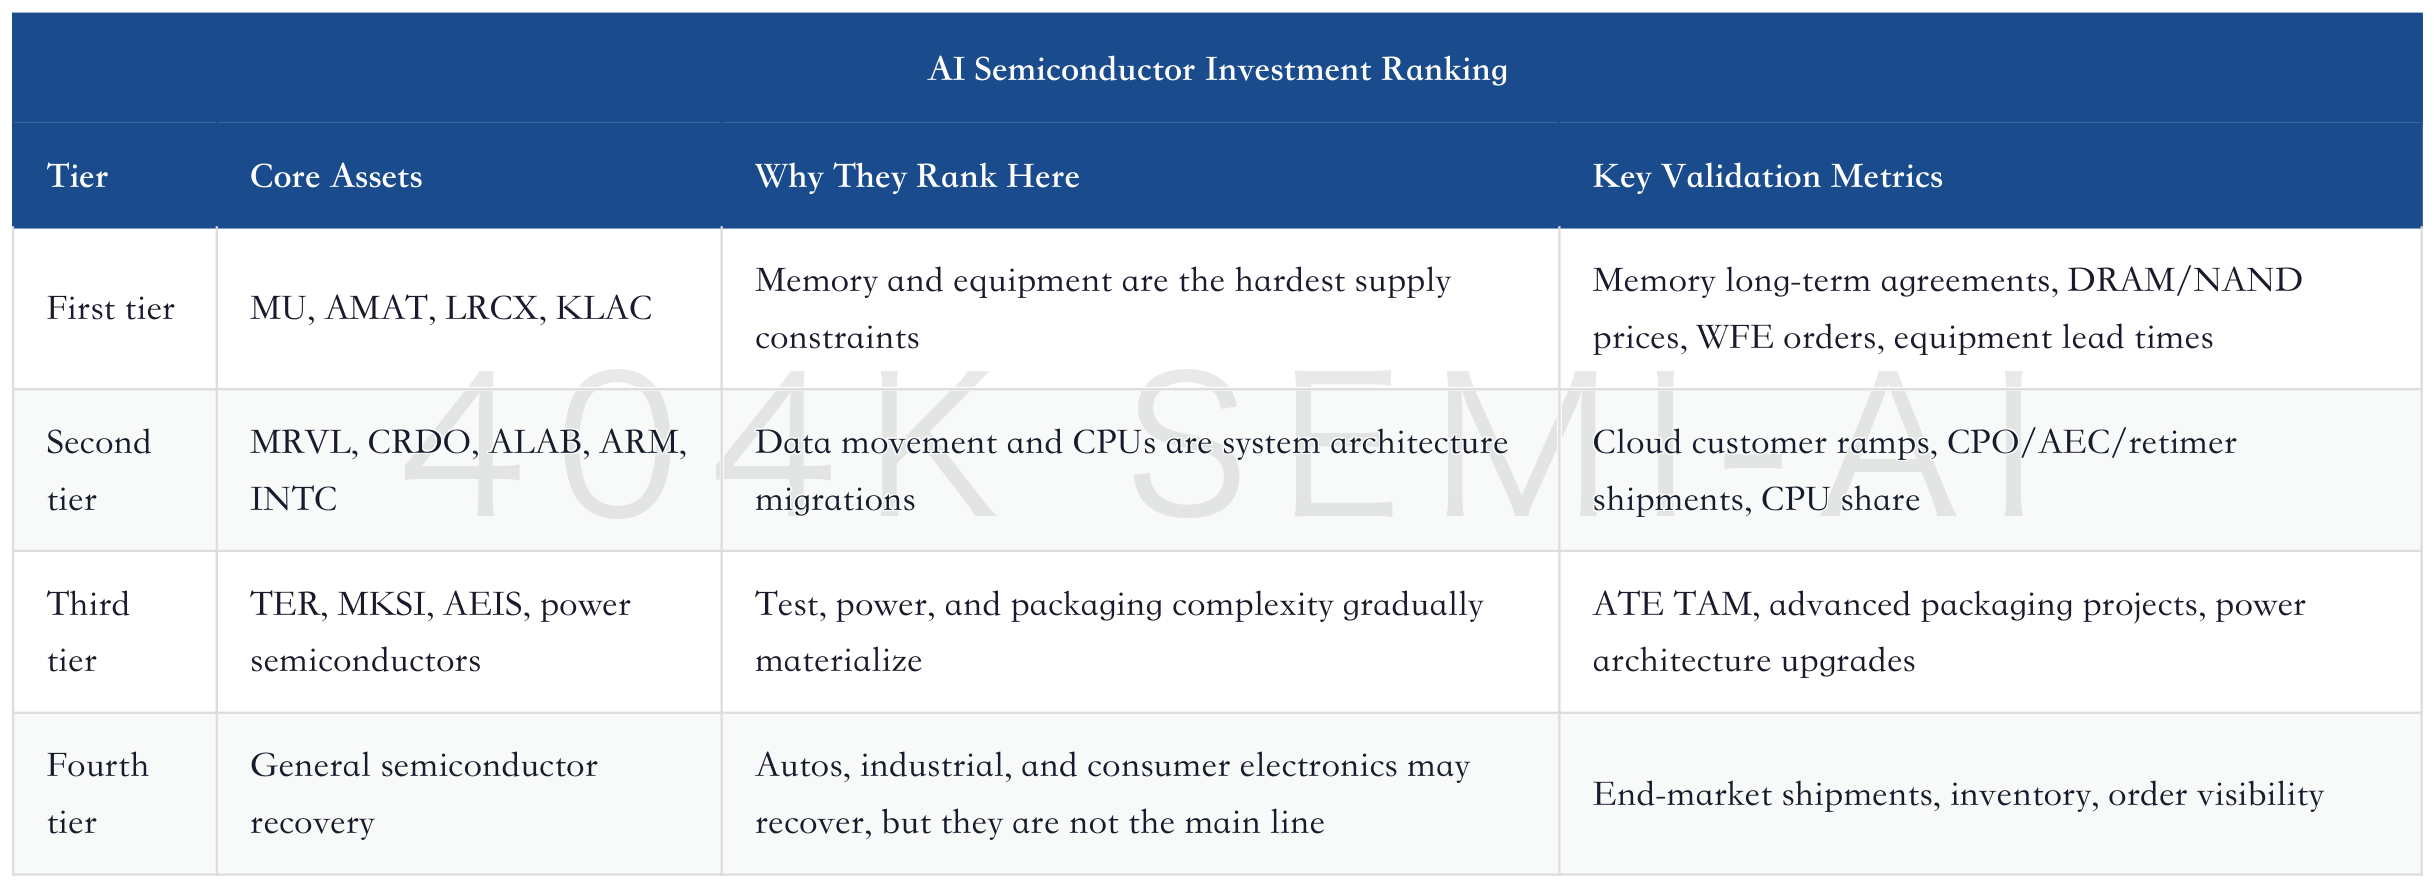
This ranking also explains why consumer semiconductors are still not the main line. In BofA’s model, PC and smartphone growth is weak, and in some years still under pressure. Autos and industrials have content growth and inventory recovery, but they are less certain than AI data centers. A strong total semiconductor ledger does not mean all semiconductors are strong. The truly strong areas are those that enter the AI delivery chain and are hard to replace.
Trading cadence should also be layered by bottleneck, not by share-price gain. Memory and equipment are the assets validated first in earnings because pricing, orders, capex, and lead times quickly show up in company guidance. Interconnect, CPUs, and test are validated in the second stage, as the revenue slope often becomes clearer only after customer projects enter volume production. Power, analog, and Physical AI extensions are more like long-term diffusion, with short-term valuations more sensitive to risk appetite.
This means the judgment criteria differ even within AI semiconductor stocks after a rally. For a memory asset such as MU, the key question is whether pricing and long-term agreements continue to strengthen. For AMAT, LRCX, and KLAC, the key question is whether WFE orders move from expectations into backlog. For MRVL, CRDO, and ALAB, the key question is whether customer projects convert into revenue through generational upgrades. For INTC and ARM, the key question is server CPU share and platform ecosystems. For TER, the key question is whether complex-test TAM is genuinely rising.
Valuation should also be separated. Memory can be assessed using a combination of PB, cyclical earnings, and HBM segment PE. Equipment is better assessed by through-cycle EPS, service revenue, orders, and gross margin. High-growth interconnect companies rely more on revenue CAGR, customer concentration, and product iteration. CPU assets require judging the credibility of long-term EPS power. Test and subsystem companies require assessing order elasticity and free cash flow. Applying the same AI PE multiple to every company obscures the real risks.
In terms of trading action, the best add points are often not when the story is hottest, but when evidence has just spread from a single point to multiple points. For example, memory is not just strong in HBM; traditional DRAM and NAND are also starting to be pulled by AI demand. Equipment is not just strong in advanced logic; DRAM, NAND, advanced packaging, and non-China expansion are also rising together. Interconnect is not just one cloud customer ramp, but multiple cloud customers and multiple product generations being validated simultaneously. The more evidence moves from a single point to a system, the more reason valuations have to move from short-term EPS toward long-term earnings power.
Conversely, trimming signals should not be based only on share price. If prices are still rising but contract duration shortens, memory profit duration is weakening. If equipment orders are still decent but customer capex begins to be pulled forward or lead times shorten, WFE visibility may be peaking. If an interconnect company’s revenue grows quickly but customer concentration keeps rising and gross margin falls, competition and pricing pressure are accumulating. If a CPU company keeps discussing long-term TAM but lacks platform share gains and customer-project execution, long-term EPS power should be discounted.
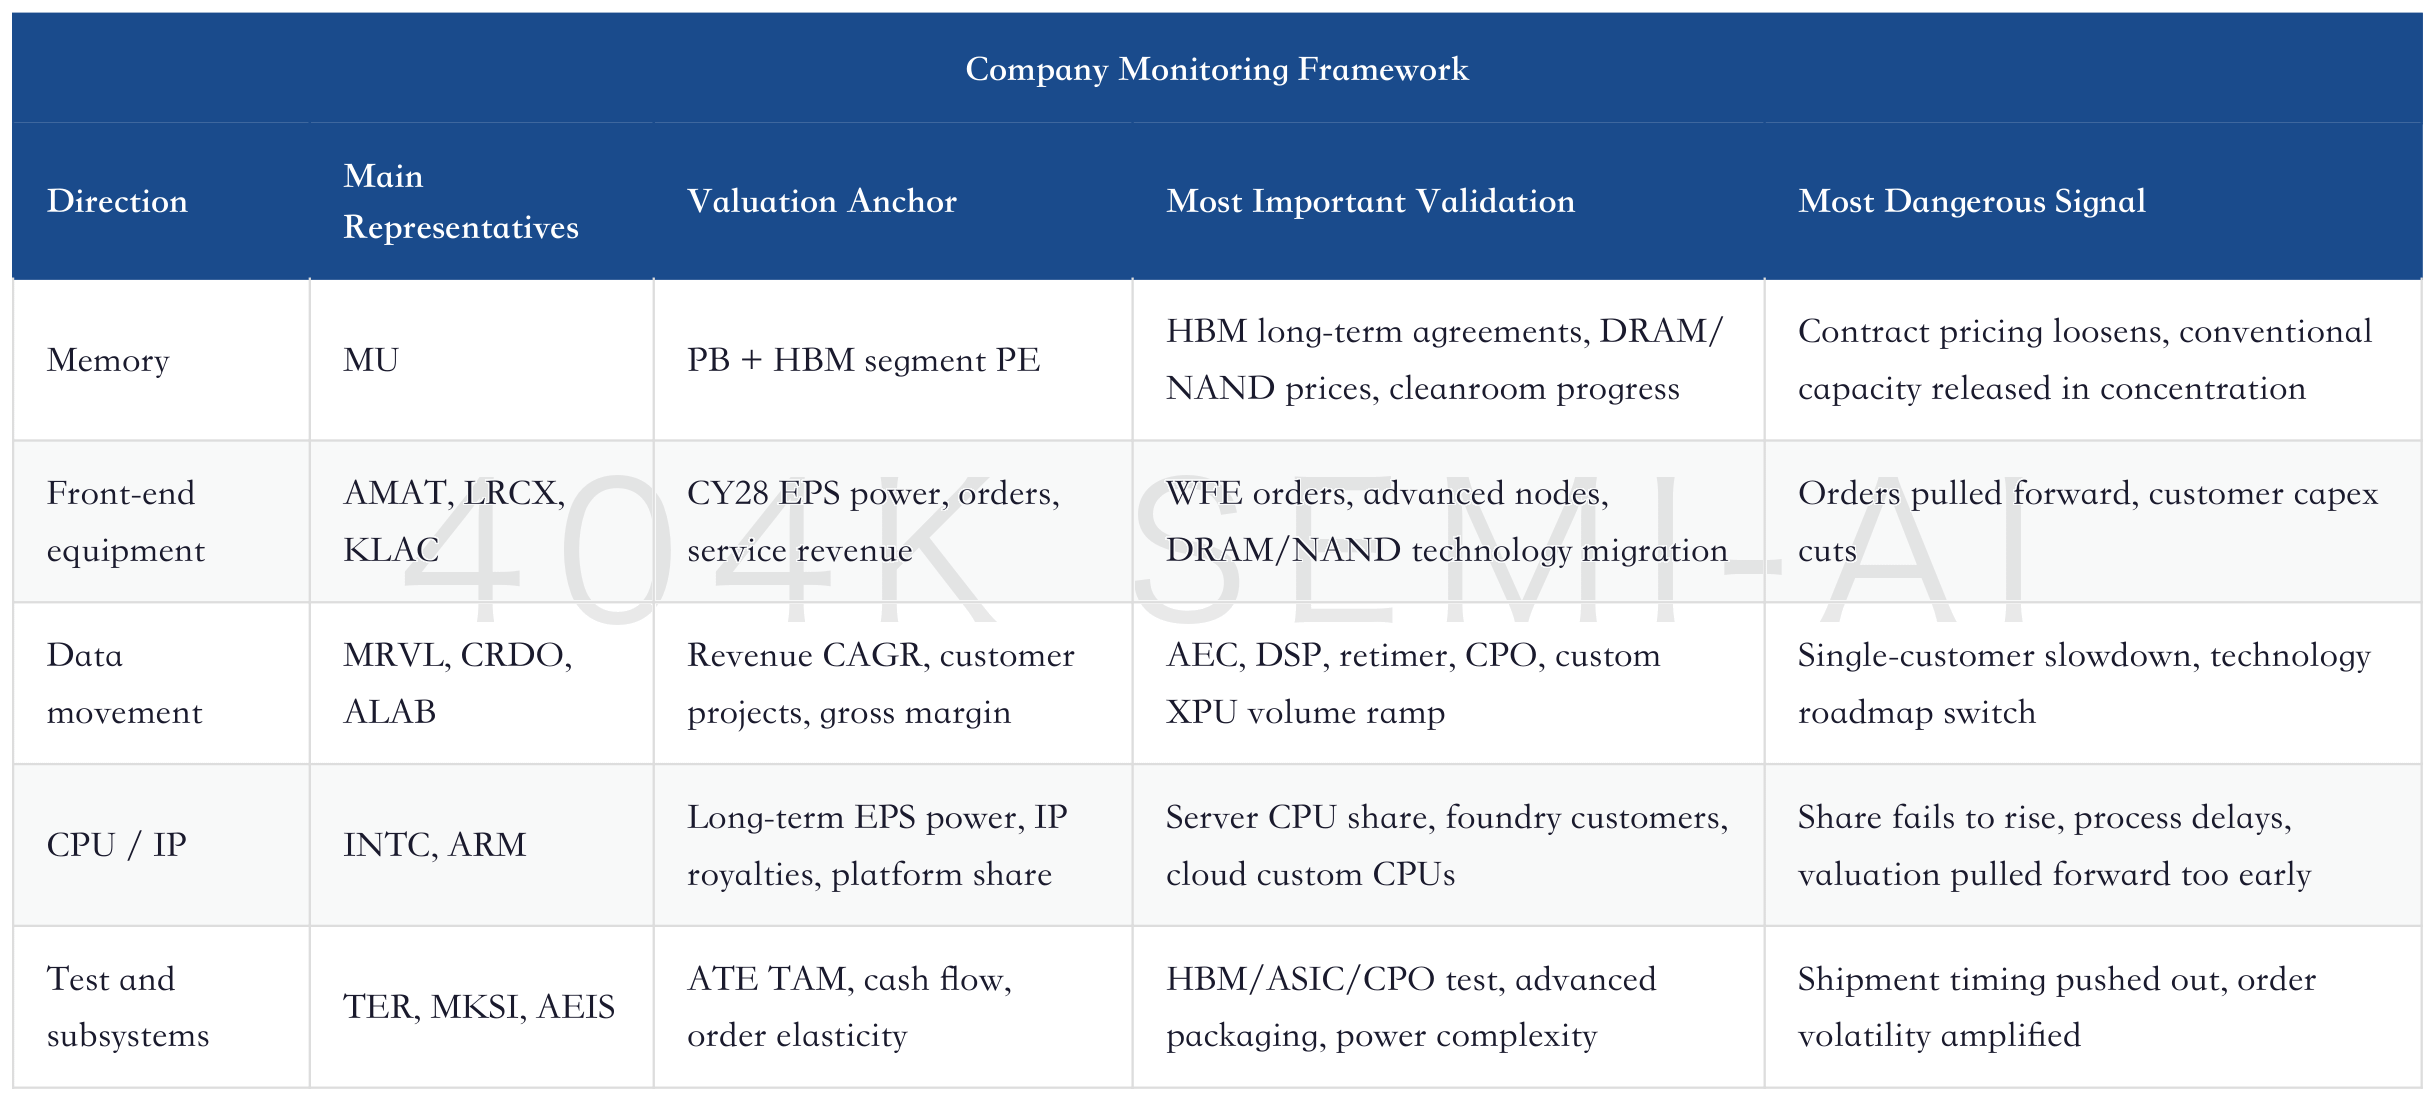
This monitoring table also helps distinguish “expensive but can get more expensive” from “expensive and needs a pullback.” Assets that are expensive but can get more expensive usually continue to provide new evidence at high valuations, such as longer contracts, more customers, more distant orders, and faster product generations. Assets that are expensive and need a pullback usually have evidence that is not spreading, while valuations continue to roll forward. The AI semiconductor rally has entered its second stage. The market will no longer reward stories alone; it must see the evidence chain lengthen.
Cross-validation also shows how this BofA report connects with several earlier industry lines. The memory line shows that HBM, DRAM, and NAND are shifting from cost items into throughput bottlenecks. The equipment line shows that these bottlenecks ultimately become WFE and cleanroom demand. The server line shows that CPUs, motherboards, networks, and power are all being retightened by inference workloads. The interconnect line shows that high bandwidth does not automatically equal effective compute; data movement itself can also become a bottleneck. By putting these lines into one ledger, BofA effectively combines multiple scattered AI trades into one supply-chain revaluation.
This cross-validation reduces the risk of a single narrative. Looking only at GPUs makes it easy to understand the semiconductor rally as one leader’s order cycle. Looking only at memory makes it easy to underestimate the persistence of equipment and interconnect. Looking only at equipment may miss the cloud capex and memory pricing behind orders. Looking only at interconnect can turn high-speed connectivity products into a single new-product cycle. Only by viewing all four lines together can investors judge whether AI semiconductors are a localized upcycle or a migration in the asset characteristics of the supply chain.
There is another important question: why BofA is willing to extend visibility beyond 2028. The answer is not the broad statement that “AI will definitely keep growing fast,” but that multiple links now show longer-term hard commitments. Memory has long-term agreements and prepayments; equipment has customer capex and cleanroom cycles; interconnect has generational product roadmaps; CPUs have cloud-custom platforms; testing has new-chip complexity. These commitments are not all irrevocable, but they are longer than ordinary consumer electronics orders and harder to reverse entirely within a single quarter.
Therefore, future investment judgment should break “good demand” into three layers. The first layer is customers’ willingness to place orders, which is only the starting point. The second layer is customers’ willingness to lock supply, pricing, or capacity in advance, which indicates the bottleneck is starting to enter profits. The third layer is suppliers expanding capex, product roadmaps, and customer qualifications in order to deliver, which indicates the bottleneck is becoming a long-term asset. Only after reaching the second and third layers will the market be willing to pay higher multiples for long-term EPS power.
This framework also explains why not all companies with upgraded target prices should be treated equally. BofA’s more restrained ratings on ALAB and ARM do not reject their long-term opportunities; they acknowledge that prices already reflect a large amount of good news. By contrast, the revaluation of MU and the equipment leaders is more direct because pricing, orders, capex, and supply constraints are easier to validate continuously. In investing, the problem is not that the story is long-dated; the problem is a long-dated story without near-term evidence.
XIII. Risk Checklist: The Biggest Risk Is Not Slightly Lower Demand, but a Break in Visibility
The biggest risk to this report is not a few points of revenue in any given quarter, but a breakdown in the premise that visibility can extend to 2028. A large part of BofA’s upgrade comes from longer-dated earnings power and a forward shift in the valuation benchmark. If the long-term evidence weakens, the high-valuation parts of the chain will come under pressure first.
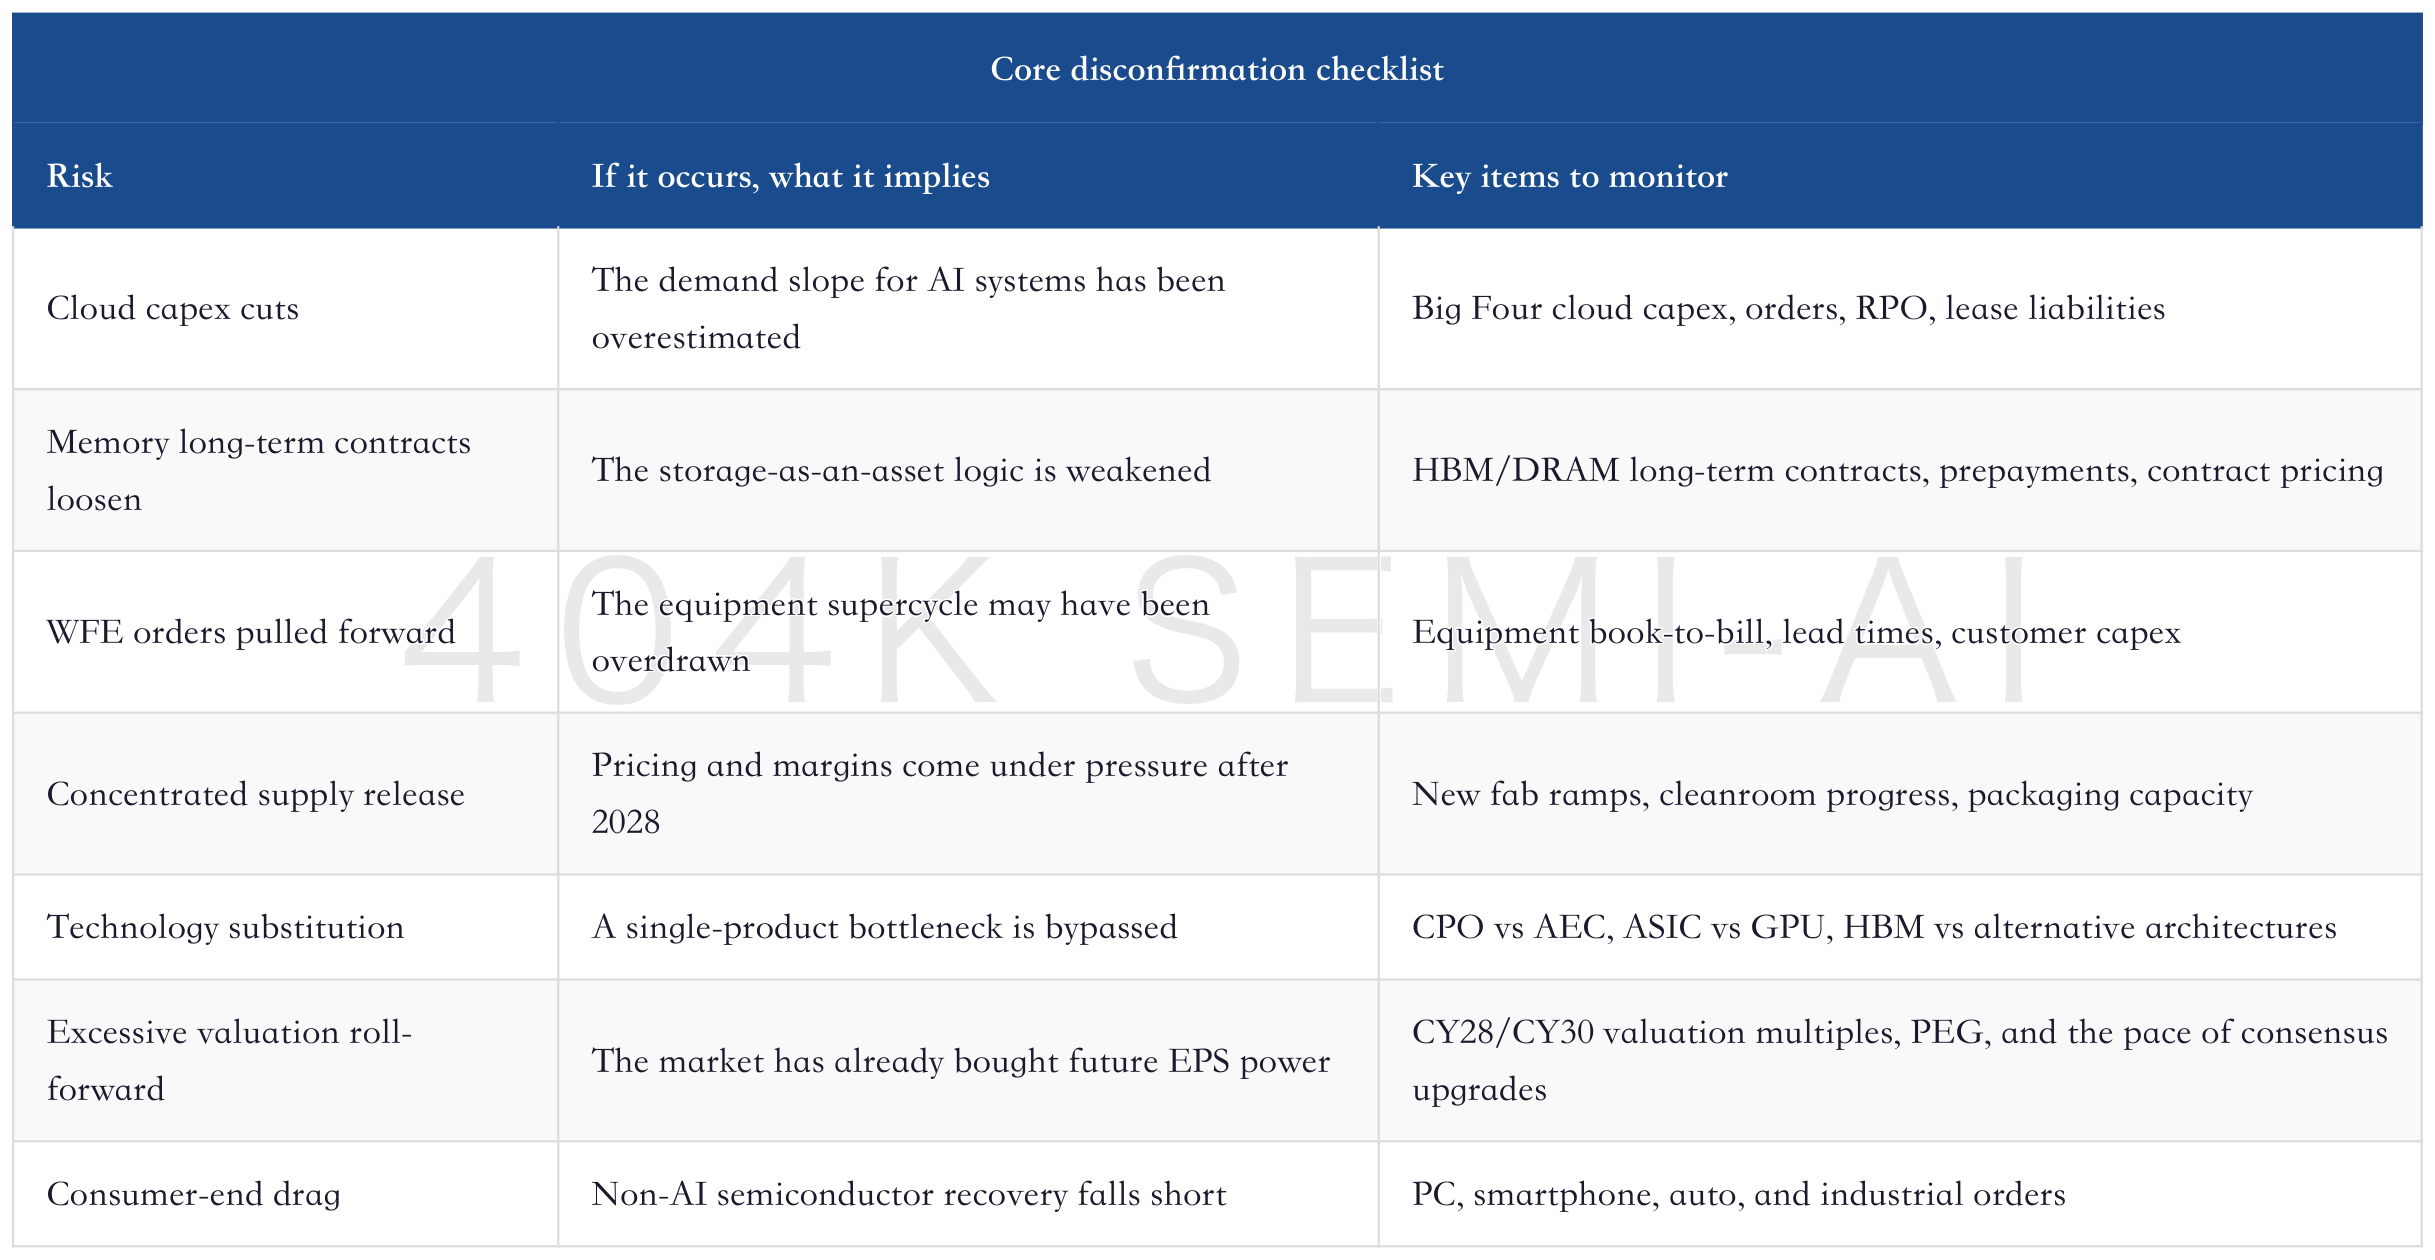
The biggest point to watch is the “future EPS power trade.” When the market is willing to value companies on 2028 or 2030 earnings power, share prices become highly sensitive to long-term assumptions. The upside is that if visibility continues to improve, valuations can keep being revised higher; the downside is that any delivery delay, pricing looseness, or customer pushback on pricing will be amplified.
XIV. What to Watch Over the Next Four Quarters
A report like this cannot stop at the investment view. It has to be tested with data. Over the next four quarters, the most important variables are not moves in the semiconductor index, but six categories of evidence.
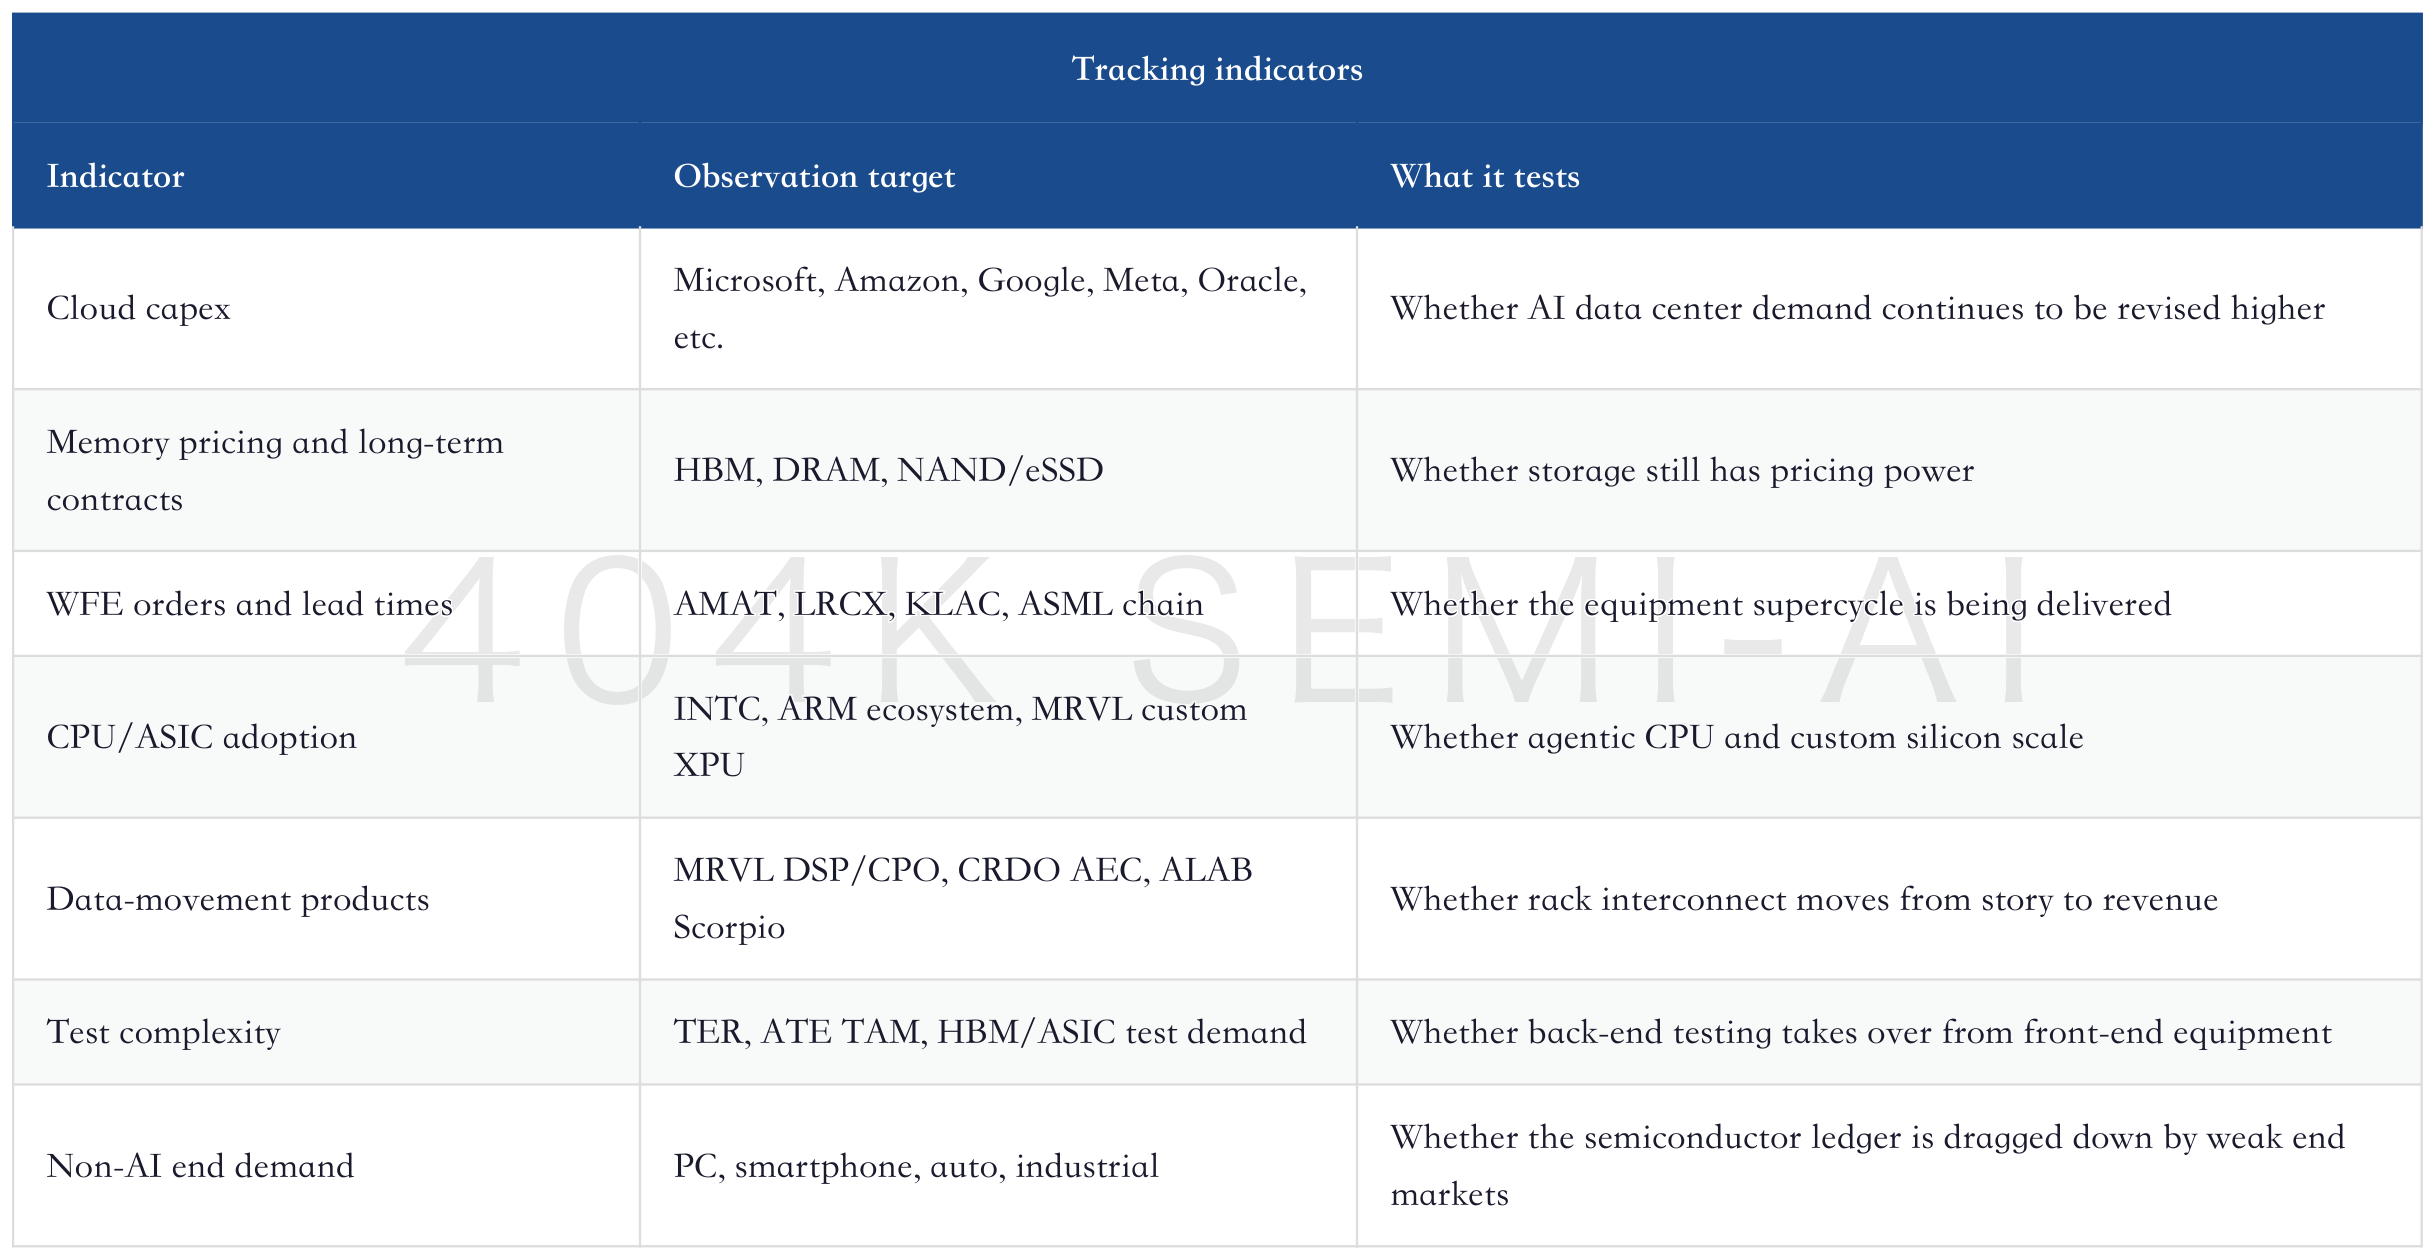
If these indicators improve together, the AI semiconductor trade will continue to spread from GPUs into memory, equipment, interconnect, CPUs, testing, and power. If one or two of them begin to deteriorate, the market will retreat from “full-chain revaluation” back to “only buy the most certain bottlenecks.” That is the core of stock selection over the next year.
XV. Conclusion: U.S. Semiconductors Are Moving from Cyclical Recovery to Bottleneck-Asset Revaluation
The most valuable part of this BofA report is that it pushes U.S. semiconductors from “AI demand is strong” to “can the AI supply chain deliver?” That shift determines why semiconductor investing will no longer be only about who is closest to GPUs, but about who controls bottlenecks, who can lock in customers, and who can convert complexity into profit.
Memory is the first tollgate. HBM, DRAM, and NAND/eSSD are all being tightened by AI demand, while long-term contracts and cleanroom construction extend earnings visibility beyond a traditional cycle. Equipment is the second gate. The WFE supercycle framing out to 2028 reflects rising complexity per wafer, not simply a revenue-share effect. CPUs and interconnect are the third main thread. Agentic AI will push CPUs, memory, networking, and accelerators onto the same main stage. Testing and power are the fourth layer of extension. Monetization may be slower, but the direction is not weak.
The most robust investment framework is to buy hard-to-replace supply first, then system architecture migration, and finally general recovery. MU, AMAT/LRCX/KLAC, MRVL/CRDO, TER, and INTC/ARM represent different layers of AI semiconductor revaluation and should not be placed in the same generic “AI-related” basket.
This U.S. semiconductor cycle still has cyclicality, and it still has valuation risk. What is genuinely different is this: AI has lifted the cyclical bottom across multiple sub-industries, extended long-term visibility, and pushed the hardest-to-deliver parts of the supply chain back to the center of valuation. As long as cloud capex, memory long-term contracts, WFE orders, and data-movement products continue to validate one another, the central question for semiconductors is not whether they have risen enough, but who can still turn bottlenecks into profit.U.S. Semiconductor Deep Dive: AI Extends Visibility to 2028; After BofA’s Estimate Revisions, Who Can Still Re-rate?
目录
Too Long; Didn’t Read
I. What This BofA Report Actually Changed
II. The Aggregate Ledger: A $2.7 Trillion TAM Is Not the End-State Number, But a Constraint Ranking
III. Five Themes: Where the Next $1 Trillion Comes From
IV. Memory: The Change in Asset Attributes Behind Micron’s Target-Price Upgrade
V. WFE: The Key to a $250 Billion Equipment Cycle Is Not Intensity, but Cost per Wafer
VI. How to Rank Equipment Companies: AMAT, LRCX, KLAC, and MKSI Do Not Have the Same Elasticity
7. CPUs Return to the Main Battlefield: Intel and Arm Make Different Bets
8. Interconnect and Data Movement: What MRVL, CRDO, and ALAB Have in Common, and How They Differ
IX. Testing: TER Is the Low-Visibility, High-Elasticity Link in Back-End Validation
X. Price Target Revision List: Which Are Major Re-Ratings, and Which Are Merely Following Along
11. How This Cycle Differs From Past Semiconductor Cycles
12. Investment Ranking: Bottlenecks First, Beta Later
XIII. Risk Checklist: The Biggest Risk Is Not Slightly Lower Demand, but a Break in Visibility
XIV. What to Watch Over the Next Four Quarters
XV. Conclusion: U.S. Semiconductors Are Moving from Cyclical Recovery to Bottleneck-Asset Revaluation
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
This BofA report is not a routine target-price increase. It extends the U.S. semiconductor thesis from GPU strength to a supply-constraint framework spanning memory, equipment, CPUs, interconnect, and test: AI visibility now extends beyond 2028, and the market needs to reassess which companies are merely benefiting from capex beta and which truly control delivery bottlenecks and long-duration profits.
Too Long; Didn’t Read
The semiconductor narrative has changed. BofA extends AI from GPU demand to memory, equipment, CPUs, interconnect, test, and power constraints. The core issue is whether the supply chain can deliver.
Memory is the first gate. HBM, DRAM, and NAND are all tightening at the same time. Long-term agreements and cleanroom construction are shifting Micron from a cyclical stock into an AI compute-chain asset.
Equipment is the second gate. WFE has been revised up into supercycle territory. The variable is not just revenue, but equipment intensity per wafer, yield, and process complexity.
CPUs and interconnect are back at the main table. Agentic AI requires scheduling, memory addressing, and data movement. Intel, Arm, MRVL, CRDO, and ALAB benefit through different mechanisms.
Target-price revisions need to be tiered. MU is about memory assetization; AMAT/LRCX/KLAC are about equipment profits; TER is about test complexity. Investors cannot simply buy the AI label.
The biggest risk is a pullback in visibility. If cloud capex slows, memory LTAs loosen, or supply is released in concentration in 2028, high-valuation segments will be repriced first.
Investment ranking should follow bottlenecks. Start with memory and equipment, then look at CPUs, interconnect, test, and advanced packaging. Track prices, orders, cloud budgets, and customer qualifications; if they weaken together, the bottleneck trade is starting to unwind.
I. What This BofA Report Actually Changed
On the surface, this report is a target-price revision across BofA’s U.S. semiconductor coverage. The real change is a migration in the valuation anchor. BofA moves AI semiconductors from a “GPU demand curve” to a “scarce capacity curve”: the semiconductor industry is no longer just about incremental compute chips, but whether an entire supply chain can deliver at the same time.
Over the past two years, the easiest AI semiconductor story for the market to understand was GPUs. As long as demand for large-model training and inference continued to rise, GPUs, HBM, advanced packaging, and server systems would have orders. But by mid-2026, the issue had become more complex. GPUs remain important, but they no longer determine on their own whether AI clusters can be deployed. Memory bandwidth, standard DRAM, NAND/eSSD, server CPUs, Ethernet interconnect, test equipment, WFE, EUV, cleanrooms, power, and advanced packaging have all been pulled into the same delivery chain.
The core of BofA’s revision is bringing the period beyond 2028 into the valuation foreground. Previously, many semiconductor companies traded on 2026 or 2027 earnings revisions. Now BofA is pushing the valuation basis for multiple companies toward 2028 or even 2030. This is not simply “looking further out.” It means the market believes AI demand is not a one-year order pulse, but a force that will require the supply chain to lock in capacity, equipment, yield, and customers in advance.
This is also why the report should not be written up as a “target-price list.” Target prices are only the result. What is worth unpacking is how BofA redefines the semiconductor cycle. It argues that the chip industry took roughly half a century to reach its first trillion dollars in sales, while AI may add another trillion-dollar-scale increment over the next few years. If that view is correct, semiconductors are not merely returning to the last cyclical peak; they are entering a new cycle in which capex, supply constraints, and product mix all rise together.
II. The Aggregate Ledger: A $2.7 Trillion TAM Is Not the End-State Number, But a Constraint Ranking
BofA raises its 2030 global semiconductor TAM estimate to $2.7 trillion, implying a 2025-2030 CAGR of roughly 28%. That number is large, but the truly important point is not the figure itself. It is the structure: memory, AI data-center systems, server silicon, networking, and equipment all contribute incremental growth, while consumer electronics remains weak.
Under BofA’s model, AI data-center systems could approach $1.7 trillion by 2030, versus only about $273 billion in 2025. Core semiconductors excluding memory are estimated at roughly $1.1 trillion by 2030, with a 2025-2030 CAGR of about 14%. Server silicon has the highest growth rate, while networking also benefits meaningfully. PCs and smartphones remain weak; autos and industrials are more about content growth and inventory normalization.
This table explains why BofA is raising estimates for memory, equipment, CPUs, interconnect, and test at the same time. An AI data center is not a chip; it is a system. The larger the system, the more it depends on multiple bottlenecks opening simultaneously. In the past, the market understood “compute” as GPUs. Now compute is closer to a delivery function: GPUs need HBM; HBM needs DRAM wafers and advanced packaging; systems need CPUs and networking; clusters need switching, optical interconnect, and test; capacity needs WFE and cleanrooms.
This is the most important conclusion in the BofA report: AI semiconductors are moving from a demand story to a delivery story. Demand stories focus on orders; delivery stories focus on bottlenecks. Orders can fluctuate across quarters, but bottlenecks can change valuation structure. Companies that control capacity that is hard to replace, customers that are hard to qualify, processes that are hard to substitute, and supply positions that are hard to price down can capture a longer duration of profits.
The aggregate model also needs to be read in reverse. If 2030 semiconductor TAM is revised up to $2.7 trillion, the real driver of stock-price elasticity is not the aggregate multiple, but where incremental profit is retained. GPUs are of course still among the strongest assets, but the GPU supply chain has already been studied extensively by the market. Incremental pricing power will continue to spread toward bottlenecks that have not yet been fully confirmed. BofA putting MU, AMAT, LRCX, KLAC, MRVL, CRDO, TER, INTC, and ARM in the same revision report reflects exactly this profit migration: from a single accelerator toward the full AI infrastructure stack.
Therefore, $2.7 trillion is not simply an optimistic aggregate figure. It is a constraint map. Memory determines how much data each accelerator can consume. Equipment determines wafers and yield over the next two to three years. Interconnect determines whether clusters can scale at low latency. CPUs schedule complex inference workloads. Test makes high-speed, high-current, multi-die systems actually deliverable. If the supply elasticity of any one segment is below the demand slope, value will remain in that layer.
This is also why consumer electronics has not become the main theme. PCs and smartphones may see cyclical recovery, but they mainly affect traditional semiconductor inventory and are not enough to explain why BofA has pulled valuation anchors beyond 2028. If a company only benefits from ordinary endpoint restocking, its valuation will struggle to move beyond next-year EPS. If a company sits directly in the AI data-center delivery chain, the market will be willing to pay in advance for CY28 and CY30 earnings power.
III. Five Themes: Where the Next $1 Trillion Comes From
BofA lays out several vectors that will drive the next $1 trillion of semiconductor growth. They are not a simple parallel list, but different gates in the same AI system: data center systems pull demand, memory determines throughput, equipment determines capacity, analog and power determine power conversion, CPUs determine inference scheduling, and Physical AI extends the opportunity further out to edge devices and robotics.
Among these themes, memory and WFE have the highest near-term visibility. The reason is simple: their supply is hardest to replenish immediately, and this is already reflected in pricing, long-term agreements, and equipment orders. CPUs and interconnects have the most medium-term optionality, because Agentic AI will change system architecture from a single-GPU focus toward coordination across CPUs, memory, networking, and accelerators. Further out are analog power and Physical AI. They are not the main driver of current EPS upgrades, but they will extend AI from data centers into power, industrial, and robotics markets.
After NVIDIA, What Else to Buy in AI: Value Migration Across HBM, PCBs, Power, Software, and Agent Entry Points
IV. Memory: The Change in Asset Attributes Behind Micron’s Target-Price Upgrade
Memory is the strongest theme in this report. BofA raised its MU price target from $950 to $1,500. The key is not only earnings upgrades for 2026-2028, but also that BofA is separating Micron from a traditional DRAM/NAND cyclical stock into two assets: a traditional memory business and an HBM business.
This segment valuation matters. Traditional DRAM/NAND is valued using 2028 book value and an upcycle PB multiple, while HBM is valued using AI compute peer PE multiples. In other words, BofA recognizes that HBM is no longer merely a high-margin product inside a memory company, but a profit stream closer to the AI compute supply chain.
BofA’s memory logic can be summarized in three points. First, AI inference is shifting from a “compute bottleneck” to a “memory bottleneck.” Long context, high concurrency, and multi-step agents repeatedly access model weights and KV cache, so memory bandwidth and capacity are no longer supporting items. Second, memory supply elasticity has declined. Even if vendors raise capex, much of the money first goes into cleanrooms and buildings; real capacity is released only later. Third, HBM and traditional DRAM/NAND reinforce each other. HBM consumes advanced DRAM wafers, ordinary DRAM is also pulled by server and CPU-side inference, and NAND/eSSD benefits from demand in the data layer and cache layer.
The Memory Tax Has Arrived: How AI Is Turning HBM, DRAM, and NAND Into a Global Macro Bottleneck
HBM data is especially important. BofA expects the HBM TAM to grow from about $35 billion in 2025 to about $246 billion in 2030, a CAGR of about 34%. HBM content per accelerator rises from about 187GB to about 464GB. HBM pricing should still have strong support in 2027-2028. The memory configuration of NVIDIA’s Vera Rubin system also shows that future AI systems will not rely only on HBM; LPDDR, SRAM, and CPU-side memory will all expand meaningfully.
The risks in memory also need to be clear. First, if HBM long-term agreements loosen, pricing leverage will be questioned first. Second, if new capacity from multiple vendors is released in a concentrated way after 2028, the market will again worry about oversupply. Third, if memory price increases lift the total cost of ownership for AI clusters, cloud vendors may delay some deployments or push back on pricing. Fourth, traditional DRAM and NAND are still cyclical products, so HBM’s high-quality profits cannot be extrapolated directly to all of memory.
In the short to medium term, however, memory remains the first toll gate in this semiconductor re-rating cycle. As long as AI systems continue to pursue long context, multiple agents, high concurrency, and greater inference throughput, the logic of memory shifting from a “cost item” to a “throughput gate” will not end easily.
The most important part of Micron’s valuation is that traditional memory and HBM can no longer be handled with the same cyclical multiple. The value of traditional DRAM/NAND depends on supply-demand and book value. A higher PB can be assigned during a strong cycle, but the market will always worry that new capacity eventually drives prices down. HBM is different. It requires customer qualification, packaging capability, advanced DRAM wafers, thermal management, and system-design coordination, and it is deeply tied to GPU/ASIC roadmaps. As long as customers are willing to lock in supply through long-term agreements and prepayments, the duration of HBM profits will be materially longer than that of ordinary memory.
This does not mean HBM can always be valued like an AI compute company. A more precise way to put it is that, during a period of tight constraints, HBM has the “profit attributes of the AI compute chain.” When supply is tight, customers lock in inventory, and product generations switch quickly, HBM looks like a critical ticket to AI compute infrastructure. When capacity catches up with demand and prices begin to loosen, it will still return to the logic of the memory cycle. BofA’s re-rating of Micron is essentially a bet that the first state lasts longer.
For investors, assessing Micron cannot be reduced to HBM shipments alone. Three things matter. First, whether HBM unit pricing and contract duration can hold. Second, whether traditional DRAM/NAND also benefits as HBM crowds out wafer supply. Third, whether capex is mainly allocated to high-return cleanrooms, advanced packaging, and high-end memory, rather than creating ordinary capacity oversupply too early. As long as all three hold, Micron is not simply memory beta, but a pricing asset tied to the AI memory bottleneck.
V. WFE: The Key to a $250 Billion Equipment Cycle Is Not Intensity, but Cost per Wafer
Equipment is the second hard through-line in BofA’s report. BofA raised its 2028 WFE forecast from roughly $203 billion to roughly $250 billion, and laid out a path toward nearly $292 billion by 2030. This upward revision is not simply “semiconductor sales rise, therefore equipment rises.” It is being driven jointly by technical complexity, memory capacity expansion, advanced logic, EUV, non-China capacity additions, and cleanroom unlocks.
BofA emphasizes that investors cannot look only at WFE intensity. Current semiconductor revenue growth includes a large ASP contribution, especially from rising memory prices, which can make WFE as a percentage of sales appear to decline. Looking only at intensity can therefore lead to the mistaken conclusion that equipment demand is weakening. The more important metric is equipment spending per 12-inch wafer, or WFE per wafer. As advanced processes, HBM, DRAM EUV, NAND layer counts, advanced packaging, and yield requirements all rise, each wafer requires more equipment and more process steps.
This explains why equipment companies can continue to rerate in years when “intensity appears to decline.” Rising memory prices expand the denominator, but memory manufacturers still need to buy more equipment to add real capacity, improve yield, and introduce HBM and advanced DRAM. DRAM and NAND technology migrations in particular are not only about building new capacity, but also about upgrading existing capacity to more complex nodes.
BofA also treats non-China WFE as an important variable. From 2025 to 2030, non-China WFE CAGR is meaningfully higher than China WFE CAGR, driven by supply-chain restructuring, advanced nodes, AI/HPC, and global capacity expansion projects. This shift matters for equipment companies: if incremental demand comes from advanced logic, DRAM, EUV, and non-China advanced capacity, earnings quality is generally better than in mature-node price competition.
The WFE upgrade cannot be judged only by order value; investors also need to assess whether equipment companies can convert the cycle into margins. Leading equipment companies have two embedded business-model levers. One is service and spare-parts revenue from a larger installed base. The other is mix improvement from rising advanced-process complexity. If incremental WFE mainly comes from price competition in mature nodes, equipment-company revenue may rise, but margins may not expand in parallel. If the incremental demand comes from DRAM EUV, advanced logic, advanced packaging, process control, and high-end etch/deposition, earnings quality is usually better.
This explains why KLAC holds a high position in this equipment rerating cycle. Process control does not directly determine the number of incremental wafers, but it determines yield ramp in highly complex production lines. The more complex AI chips become, the more chiplets they use, the higher HBM stacks go, and the denser advanced packaging becomes, the more valuable defect inspection and metrology become. KLAC monetizes the “complexity tax,” not a simple capacity-expansion tax. Its revenue elasticity may be lower than that of broader front-end equipment names, but its earnings quality and valuation stability are often stronger.
AMAT and LRCX are closer to the main beta of the WFE supercycle. AMAT covers deposition, materials engineering, advanced packaging, and services, giving it broader exposure. LRCX is more sensitive to etch, deposition, NAND and DRAM technology migration; if NAND/eSSD again becomes a data-center capacity asset, LRCX’s slope becomes more attractive. MKSI and AEIS represent subsystems and power, where elasticity is more about spillover from equipment complexity and requires monitoring order conversion and cash-flow improvement.
There is also an easily overlooked time lag in the equipment chain. From semiconductor manufacturers announcing capex to cleanrooms becoming available, tools moving in, process tuning, and yield ramp, the process often spans multiple quarters. If the market focuses only on current-quarter orders, it can underestimate the length of the cycle; if it looks only at long-term TAM, it can miss the risk of orders being pulled forward. A more robust framework is to split equipment stocks into three lines: order visibility, margin quality, and continuity of customer capex. Only when all three improve at the same time is the equipment supercycle truly being realized.
VI. How to Rank Equipment Companies: AMAT, LRCX, KLAC, and MKSI Do Not Have the Same Elasticity
Behind BofA’s target-price increases for equipment companies is a clear judgment: if 2028 WFE reaches $250 billion, leading equipment companies still have significant EPS upside. But different equipment companies derive their elasticity from different positions.
AMAT’s core is broad-based equipment exposure and multi-point exposure to DRAM, advanced packaging, and foundry. BofA raised its AMAT price target to $720, arguing that in a higher-WFE environment, its EPS power could be meaningfully above consensus. AMAT’s strength is breadth of coverage; its weakness is that it needs to prove gross margin and service revenue can turn the large cycle into profits.
LRCX’s elasticity comes more from etch, deposition, NAND upgrades, and advanced packaging. BofA raised its LRCX price target to $480, emphasizing share opportunities in NAND greenfield, foundry/logic, DRAM, and advanced packaging. If NAND/eSSD shifts from a weak cycle into a data-center capacity asset, LRCX’s slope becomes stronger.
KLAC’s key is process control. BofA raised its KLAC price target from $210 to $317, with a significant increase in the valuation multiple as well. The reason is that process complexity, design counts, advanced packaging, yield ramp, and defect inspection all increase process-control density in the AI era. KLAC may not be the largest beneficiary of total WFE, but it is more like the collector of the “complexity tax.”
MKSI is more oriented toward components, subsystems, and advanced packaging/PCB complexity. BofA raised its price target to $500, highlighting benefits to its semiconductor, electronics, and packaging businesses from the etch/dep inflection and AI substrate/PCB demand. It is not a pure-play equipment leader, but it has solid operating leverage when complexity rises.
The ways to disprove the equipment-chain thesis are also clear: if cloud capex is revised down, equipment orders will be reassessed; if memory manufacturers release capacity in a concentrated way around 2028, equipment orders could be pulled forward and then fall back; if advanced-node progress is slower than expected, incremental EUV, metrology, and etch demand will be delayed; and if China’s mature-node capacity continues to digest existing capacity, mature-equipment demand will be weaker.
7. CPUs Return to the Main Battlefield: Intel and Arm Make Different Bets
The next phase of AI semiconductors is not just about more GPUs; CPUs are becoming important again. The reason is not that CPUs replace GPUs, but that inference and agentic AI require more scheduling, memory addressing, tool calls, database access, state maintenance, and multi-tenant management. GPUs handle high-throughput matrix computation; CPUs make complex workflows run.
BofA sets the server CPU TAM at roughly $170 billion by 2030 and believes the Arm architecture has a chance to approach half of server CPU value share, with part of that coming from merchant CPUs and part from cloud providers’ in-house CPUs. The core point is not Arm replacing x86, but server CPUs shifting from “losing the narrative to GPUs” to becoming an essential component of AI system coordination.
Intel’s logic is more like an “undervalued rebuilding option.” BofA revalues the company using CY30 EPS power and incorporates the product business, foundry, Apple/MediaTek TPU wafers, Terafab, and other HPC products into the model. This model is aggressive, and the implied requirements behind it are also high: Intel must not only restore product competitiveness, but also prove that foundry can absorb external customers and that advanced process and packaging can be delivered on time.
Arm’s logic is more like a “server CPU royalty and chiplet option.” The traditional IP business can be valued like a high-growth IP company, while the new chip business is valued separately using an AI compute P/E. BofA maintains a Neutral rating because the share price already reflects many opportunities, but it acknowledges that Arm is one of the clearest ecosystem beneficiaries of the server CPU tide.
The biggest risk in the CPU theme is that the market writes it too linearly. GPUs and ASICs may continue to retain a large amount of value in the accelerators themselves, and cloud providers’ in-house chips may also compress merchant CPU profits. Intel needs process technology, customers, capex, and organizational execution to all come through at the same time; Arm needs its chiplet business to become genuinely commercial, not merely see licensing revenue rise. CPUs are back at the main table, but they are not risk-free winners yet.
Intel’s upward revision especially needs to be viewed within a scenario framework. In a bullish scenario, server CPU share stabilizes, foundry wins large external customers, and advanced packaging and process nodes progress on schedule, prompting the market to again assign it a manufacturing-platform option. In a neutral scenario, the product business improves but foundry losses narrow slowly, and the stock trades more like a semiconductor recovery story. In a bearish scenario, capex pressure and customer onboarding delays consume EPS power, and the valuation returns to the traditional x86 cycle.
Arm’s debate is different. Its advantage is a lighter ecosystem position, with cloud custom CPUs, server IP, and chiplets all capable of generating high-margin revenue. The problem is that the valuation is already pre-buying rising server share. If Arm merely delivers steadier royalties, the stock’s upside is limited; if chiplets or semi-custom compute commercialize beyond expectations, the market will push it further from an IP company toward an AI compute platform asset. BofA’s Neutral rating shows that a good direction does not mean a cheap price.
The key issue to watch in CPUs is not “who wins, x86 or Arm,” but how much value AI inference architecture returns to the host side. In the training era, GPUs and HBM were the most visible. In the inference and agentic workflow era, task scheduling, memory access, data preprocessing, tool calls, and multi-tenant management will make CPUs part of system efficiency again. As long as inference workloads become increasingly complex, CPU value will not disappear, but the winners will depend on platform share, power efficiency, and the depth of cloud-customer customization.
8. Interconnect and Data Movement: What MRVL, CRDO, and ALAB Have in Common, and How They Differ
The larger AI clusters become, the more expensive data movement gets. If GPU compute cannot be fed by networks, interconnects, retimers, DSPs, AECs, CXL, and switching systems, utilization will fall. This is also the fundamental reason BofA raised MRVL, CRDO, and ALAB: AI needs not only compute, but also stable, low-latency, low-power movement of data to the right place.
Marvell Earnings Deep Dive: AI Custom Chips Enter the Delivery Validation Phase; How Data-Center ASICs and High-Speed Interconnects Are Revalued for FY2027
MRVL has the most comprehensive position. BofA raised its target price for MRVL from $240 to $365, centered on optical DSP, TIA, drivers, CPO, custom XPUs, and XPU attach. BofA continues to see MRVL’s EPS power exceeding $15 by 2030. Its story is not a single-product breakout, but the combined pull from data-center connectivity, custom silicon, and network attach chips.
CRDO is more focused on AECs and high-speed connectivity. BofA raised its target price for CRDO to $340, emphasizing current 100G/lane products, future 200G/lane products, AEC adoption by multiple cloud customers, and new product lines including optical DSP, ZF optics, ALC, and PCIe retimers. CRDO’s advantages are high growth and customer validation; its risks are product concentration, competition, and the pace of cloud-provider procurement.
ALAB’s story is retimers and new product platforms. BofA raised its target price for ALAB from $240 to $450, but kept its rating at Neutral, showing that the opportunity is large while the valuation is not cheap. Scorpio, custom fabrics, NVLink Fusion, UALink, and other directions are taking ALAB from a single retimer business toward a broader data-center connectivity platform, but the market has already assigned high expectations.
These three companies jointly answer one question: inside AI racks and clusters, besides GPUs, who determines effective compute? MRVL is more like a platform data-movement company, CRDO is a high-speed short-reach connectivity beta asset, and ALAB is a growth company in PCIe/CXL/retimers and future fabrics. They should not be valued with the same yardstick, but tiered by customer lock-in, product substitution risk, gross margin, and shipment cadence.
The core of the data-movement layer is not as simple as “higher bandwidth is better.” Each generation of AI clusters rebalances cost, power consumption, distance, reliability, and latency. Short-reach in-rack connectivity can be handled with AECs, copper cables, and retimers, while inter-rack and cluster-level scaling require optical modules, DSPs, CPO, or new network architectures. Different solutions are not absolute substitutes; they constantly migrate across the trade-offs of power, cost, and distance.
MRVL’s advantage is its broad product span. It has optical DSPs and high-speed analog front ends, as well as custom XPUs and data-center connectivity chips, giving it multiple entry points as customer system architectures change. Its risks also come from that comprehensiveness: slow project ramps, customer concentration, and changes in gross-margin structure can all affect valuation realization. Investors buying MRVL are not buying a single product cycle, but the system-level expansion of AI data centers from compute to connectivity to custom silicon.
CRDO’s advantage is purer high-growth interconnect beta. If AECs continue to expand penetration among multi-cloud customers, the revenue slope will look attractive; but it is also more exposed to a single product cycle and customer shipment timing. ALAB sits at the platformization inflection point of retimers, PCIe/CXL, and future fabrics, with large growth space but a more difficult valuation digestion path. Among the three, MRVL looks more like a core asset, CRDO more like high beta, and ALAB more like a high-valuation option.
The falsification points for this theme are especially concrete: if the migration to 200G/lane is slow, AECs are suppressed by optical solutions, CPO progresses below expectations, or cloud providers’ in-house connectivity chips replace third parties, data-movement company valuations will compress first. Conversely, if cloud customers begin locking in volumes early for next-generation racks, high-speed interconnects will move from “AI infrastructure support” to “compute-utilization assets,” and valuation anchors will continue shifting toward longer-term revenue capacity.
IX. Testing: TER Is the Low-Visibility, High-Elasticity Link in Back-End Validation
Testing is often overlooked in many AI semiconductor discussions, but Bank of America’s decision to raise its TER price target from $365 to $525 shows that testing complexity is entering valuation. The more complex AI chips become, and the more HBM, ASICs, CPO, SiPho, high-speed interfaces, and custom silicon they incorporate, the more important test time, platform complexity, and customer qualification become.
Bank of America cited Teradyne’s comments at the conference: if the WFE environment reaches roughly $250 billion, ATE TAM could easily support a level of about $20 billion. This framing implies that testing as a share of WFE is rising modestly, rather than simply tracking semiconductor shipments. Testing complexity itself is increasing.
TER’s advantage is its exposure to custom ASICs, HBM/DRAM testing, CPO/silicon photonics, and robotics automation. Its weakness is that back-end testing has lower visibility than front-end WFE, and order cadence is more vulnerable to customer shipment schedules. Bank of America also cautions that 2H could decline due to the timing of custom ASIC tester shipments, so while the long-term view is constructive, the near term still needs 2Q earnings to provide clearer visibility.
Testing is the third layer of elasticity in this AI semiconductor cycle. The first layer is memory and equipment, because the supply bottlenecks are clear. The second layer is interconnect and CPUs, because the system architecture migration is underway. The third layer is testing and advanced packaging, because rising complexity will gradually flow through to the back end. TER may not be the fastest asset to deliver, but it proves that AI semiconductors are moving from “buying chips” to “buying validation capability.”
X. Price Target Revision List: Which Are Major Re-Ratings, and Which Are Merely Following Along
Bank of America’s latest revisions cover multiple companies, but they should not all be grouped into the same category. A more effective approach is to group them by “reason for re-rating”: memory assetization, WFE supercycle, data movement platforms, CPU optionality, testing complexity, and M&A;/synergies. Only then can we see whose revisions are highest quality.
The most important point in this table is rating differentiation. Bank of America is not “blindly buying the whole industry.” ALAB saw a large price target increase but remains Neutral because the market has already assigned it a high valuation; ACLS had its price target raised but remains Underperform because much of the M&A; synergy is already reflected. This stance matters: AI exposure does not mean low risk, and a higher price target does not mean the valuation is cheap.
Major re-ratings have three characteristics. First, the earnings model is raised meaningfully, not merely rolled forward on valuation benchmarks. Second, the company controls a link with supply constraints or customer lock-in. Third, visibility beyond 2028 is not imaginary, but can be validated through LTAs, capacity, equipment orders, product introductions, or customer projects. MU, AMAT/LRCX/KLAC, MRVL/CRDO, and TER each satisfy different parts of this framework.
Follow-on revisions also have three characteristics. First, they are driven mainly by higher industry valuation multiples. Second, the price target is raised but the rating is unchanged or not especially strong. Third, the risk is that valuation has already priced in earnings several years out. The treatment of ALAB, ARM, and ACLS is closer to this category. They do not lack good stories; rather, the market has already bought those stories very fully.
This price target list can be split into three worldviews. The first is “AI demand continues to be revised up, and supply still cannot keep up.” In this case, MU, AMAT, LRCX, KLAC, and some high-end testing, packaging, and interconnect companies benefit the most, because their bottlenecks are the hardest. The second is “AI demand remains strong, but supply gradually catches up.” In this case, the elasticity of high-valuation growth stocks declines, and the market becomes more willing to buy leaders with higher earnings certainty, cash flow, and service revenue contribution. The third is “cloud capex slows.” In this case, almost all AI semiconductors come under pressure, but the first to be hit are companies where long-dated EPS power carries the highest weight in valuation.
This scenario table is more useful than simply looking at price targets. Most of Bank of America’s price targets are already based on relatively optimistic medium- to long-term assumptions. What will really drive share prices over the next six months is whether these assumptions are revised up further, sustained, or discounted. If cloud capex remains strong over the next few quarters, HBM LTAs stay tight, and equipment orders continue to rise, the market will keep betting on the first worldview. If pricing and orders start to loosen, it will rotate to the second. If cloud budgets are adjusted, the third will quickly take over pricing.
11. How This Cycle Differs From Past Semiconductor Cycles
Traditional semiconductor cycles are typically driven by PCs, smartphones, servers, autos, and industrial inventory. The key variables are end-demand shipments, inventory, and capex. The AI cycle is different in three main ways.
First, demand is not a single end market; it is infrastructure buildout. Cloud providers, large models, inference platforms, enterprise AI, and sovereign AI are all building systems. As long as capex continues, demand is not just the quarterly fluctuation of a consumer end market.
Second, supply is not constrained by a single capacity point, but by multiple links at the same time. HBM requires advanced DRAM wafers and advanced packaging; WFE requires cleanrooms and equipment lead times; interconnect requires reliability qualification; CPUs and ASICs require customer ramps; testing requires new platforms. If any one link is blocked, system delivery slows.
Third, pricing power comes from delivery scarcity. In past cycles, price increases often triggered capacity expansion, eventually creating oversupply. The AI cycle will also follow that path, but the timeline may be longer because expansion requires buildings, equipment, yields, and customer qualification. BofA extending visibility to 2028 essentially reflects the view that supply release in this cycle will be slower than demand realization.
This does not mean AI semiconductors have no cycle. On the contrary, the cycle still exists, but the trough may be lifted by long-term contracts, complexity, and capex plans. The biggest risk is not that “AI demand suddenly disappears,” but that the market extrapolates supply constraints too far. Once customers start pushing on price, long-term agreements loosen, WFE lead times shorten, and memory prices roll over, valuations will adjust quickly.
The reason 2028 visibility has become critical is that many semiconductor investment decisions naturally have long cycles. Memory suppliers cannot build cleanrooms, introduce advanced DRAM, and expand HBM packaging in a single quarter. Equipment companies also need multiple reporting periods from order to installation, debugging, and acceptance. If cloud providers want to deploy larger-scale inference clusters over the next few years, they must lock in power, data centers, servers, networking, and chips in advance. These long chains can turn AI demand from short-term orders into multi-year delivery plans.
But “visibility” is not “certainty.” It is more like an evidence chain: customers are willing to sign long-term agreements, suppliers are willing to expand capacity, equipment orders continue, pricing is not broken by new supply, and end-user AI workloads genuinely absorb the added compute. If any link in the chain breaks, the market will shorten the valuation horizon again. What semiconductor stocks fear most is not a high long-term model, but a long-term model without near-term evidence to keep it alive.
This is also how this cycle differs from the 2021 equipment, memory, and automotive semiconductor cycle. At that time, price increases in many categories came from supply-chain disruption and inventory rebuilding; demand itself did not form a unified long-term infrastructure investment cycle. The stronger aspect of the AI cycle is that cloud capex, model inference, enterprise workflows, and sovereign AI are simultaneously lifting system demand. The more dangerous aspect is that the market is also more likely to misread short-term tightness as long-term scarcity. The boundary between the two is whether long-term agreements, orders, pricing, and customer ramps continue to validate each other.
If one were to define the core falsification condition for this report, it would be this: AI semiconductors revert from a “delivery bottleneck” back to an “ordinary order cycle.” Once memory prices are merely quarterly fluctuations, equipment orders begin to be deferred by customers, interconnect products are just short-term pull-ins from a few customers, CPU share does not materially change, and test complexity does not translate into platform demand, the market will no longer pay for earnings beyond 2028. Conversely, if this evidence continues to reinforce itself over the next four quarters, the valuation anchor will keep migrating toward long-term earnings power.
Therefore, 2028 is not a mechanical valuation year, but a stress-test year. It requires investors to answer whether a company’s products, capacity, customer relationships, and capex today can remain scarce two or three years from now. If the answer is yes, the market can tolerate short-term volatility. If the answer is only “AI-related,” without delivery bottlenecks and customer lock-in, high valuations will look fragile.
This stress test can also be applied to earnings analysis. For memory companies, look not only at revenue growth, but also ASPs, contract structure, days of inventory, and capex allocation. For equipment companies, look not only at order growth, but also non-China advanced capacity, DRAM/NAND technology migration, and service revenue. For interconnect companies, look not only at single-quarter shipments, but also product generations, customer count, and gross margin. For CPU and IP companies, look not only at TAM narratives, but also platform share, ecosystem lock-in, and unit economics. Only by linking these earnings indicators can investors judge whether long-term visibility in AI semiconductors is still improving.
The market often views semiconductors as a high-volatility industry, so every rally invites the question of whether it is a bubble. The better question is not “is there a bubble,” but “how much fundamental evidence remains before bubble conditions take over.” If valuations rise quickly while orders, pricing, customer lock-in, and capex also deepen in parallel, the rally still has fundamental support. If valuations rise quickly while the only evidence left is long-term TAM and target-price upgrades, risk increases. BofA’s report is not an unconditional bullish call; it is a bottleneck-trade framework that must be continuously validated.
12. Investment Ranking: Bottlenecks First, Beta Later
For investment purposes, the most important takeaway from this report is ranking, not simply saying “AI semiconductors remain strong.” Buying a basket purely on AI relevance can easily capture assets whose valuations already reflect the theme but whose profit retention is not strong enough. A better ranking is by bottleneck control.
The first tier is memory and equipment. Memory pricing, long-term agreements, and capacity constraints have already entered earnings reports. Equipment orders and WFE upgrades have clearer supply-chain transmission. This tier includes MU, AMAT, LRCX, KLAC, as well as related advanced packaging and test equipment.
The second tier is data movement and CPUs. The upside for MRVL, CRDO, ALAB, ARM, and INTC comes from system architecture migration. This is not a traditional cyclical recovery, but the shift in AI clusters from GPU-centric systems toward data movement, host scheduling, and custom compute. The risks are technology roadmaps and customer ramps.
The third tier is test, analog power, and Physical AI extensions. TER, AEIS, MKSI, analog power, and the power chain will benefit as system complexity rises, but the realization cadence is more dispersed and requires tracking customer projects and product cycles.
This ranking also explains why consumer semiconductors are still not the main line. In BofA’s model, PC and smartphone growth is weak, and in some years still under pressure. Autos and industrials have content growth and inventory recovery, but they are less certain than AI data centers. A strong total semiconductor ledger does not mean all semiconductors are strong. The truly strong areas are those that enter the AI delivery chain and are hard to replace.
Trading cadence should also be layered by bottleneck, not by share-price gain. Memory and equipment are the assets validated first in earnings because pricing, orders, capex, and lead times quickly show up in company guidance. Interconnect, CPUs, and test are validated in the second stage, as the revenue slope often becomes clearer only after customer projects enter volume production. Power, analog, and Physical AI extensions are more like long-term diffusion, with short-term valuations more sensitive to risk appetite.
This means the judgment criteria differ even within AI semiconductor stocks after a rally. For a memory asset such as MU, the key question is whether pricing and long-term agreements continue to strengthen. For AMAT, LRCX, and KLAC, the key question is whether WFE orders move from expectations into backlog. For MRVL, CRDO, and ALAB, the key question is whether customer projects convert into revenue through generational upgrades. For INTC and ARM, the key question is server CPU share and platform ecosystems. For TER, the key question is whether complex-test TAM is genuinely rising.
Valuation should also be separated. Memory can be assessed using a combination of PB, cyclical earnings, and HBM segment PE. Equipment is better assessed by through-cycle EPS, service revenue, orders, and gross margin. High-growth interconnect companies rely more on revenue CAGR, customer concentration, and product iteration. CPU assets require judging the credibility of long-term EPS power. Test and subsystem companies require assessing order elasticity and free cash flow. Applying the same AI PE multiple to every company obscures the real risks.
In terms of trading action, the best add points are often not when the story is hottest, but when evidence has just spread from a single point to multiple points. For example, memory is not just strong in HBM; traditional DRAM and NAND are also starting to be pulled by AI demand. Equipment is not just strong in advanced logic; DRAM, NAND, advanced packaging, and non-China expansion are also rising together. Interconnect is not just one cloud customer ramp, but multiple cloud customers and multiple product generations being validated simultaneously. The more evidence moves from a single point to a system, the more reason valuations have to move from short-term EPS toward long-term earnings power.
Conversely, trimming signals should not be based only on share price. If prices are still rising but contract duration shortens, memory profit duration is weakening. If equipment orders are still decent but customer capex begins to be pulled forward or lead times shorten, WFE visibility may be peaking. If an interconnect company’s revenue grows quickly but customer concentration keeps rising and gross margin falls, competition and pricing pressure are accumulating. If a CPU company keeps discussing long-term TAM but lacks platform share gains and customer-project execution, long-term EPS power should be discounted.
This monitoring table also helps distinguish “expensive but can get more expensive” from “expensive and needs a pullback.” Assets that are expensive but can get more expensive usually continue to provide new evidence at high valuations, such as longer contracts, more customers, more distant orders, and faster product generations. Assets that are expensive and need a pullback usually have evidence that is not spreading, while valuations continue to roll forward. The AI semiconductor rally has entered its second stage. The market will no longer reward stories alone; it must see the evidence chain lengthen.
Cross-validation also shows how this BofA report connects with several earlier industry lines. The memory line shows that HBM, DRAM, and NAND are shifting from cost items into throughput bottlenecks. The equipment line shows that these bottlenecks ultimately become WFE and cleanroom demand. The server line shows that CPUs, motherboards, networks, and power are all being retightened by inference workloads. The interconnect line shows that high bandwidth does not automatically equal effective compute; data movement itself can also become a bottleneck. By putting these lines into one ledger, BofA effectively combines multiple scattered AI trades into one supply-chain revaluation.
This cross-validation reduces the risk of a single narrative. Looking only at GPUs makes it easy to understand the semiconductor rally as one leader’s order cycle. Looking only at memory makes it easy to underestimate the persistence of equipment and interconnect. Looking only at equipment may miss the cloud capex and memory pricing behind orders. Looking only at interconnect can turn high-speed connectivity products into a single new-product cycle. Only by viewing all four lines together can investors judge whether AI semiconductors are a localized upcycle or a migration in the asset characteristics of the supply chain.
There is another important question: why BofA is willing to extend visibility beyond 2028. The answer is not the broad statement that “AI will definitely keep growing fast,” but that multiple links now show longer-term hard commitments. Memory has long-term agreements and prepayments; equipment has customer capex and cleanroom cycles; interconnect has generational product roadmaps; CPUs have cloud-custom platforms; testing has new-chip complexity. These commitments are not all irrevocable, but they are longer than ordinary consumer electronics orders and harder to reverse entirely within a single quarter.
Therefore, future investment judgment should break “good demand” into three layers. The first layer is customers’ willingness to place orders, which is only the starting point. The second layer is customers’ willingness to lock supply, pricing, or capacity in advance, which indicates the bottleneck is starting to enter profits. The third layer is suppliers expanding capex, product roadmaps, and customer qualifications in order to deliver, which indicates the bottleneck is becoming a long-term asset. Only after reaching the second and third layers will the market be willing to pay higher multiples for long-term EPS power.
This framework also explains why not all companies with upgraded target prices should be treated equally. BofA’s more restrained ratings on ALAB and ARM do not reject their long-term opportunities; they acknowledge that prices already reflect a large amount of good news. By contrast, the revaluation of MU and the equipment leaders is more direct because pricing, orders, capex, and supply constraints are easier to validate continuously. In investing, the problem is not that the story is long-dated; the problem is a long-dated story without near-term evidence.
XIII. Risk Checklist: The Biggest Risk Is Not Slightly Lower Demand, but a Break in Visibility
The biggest risk to this report is not a few points of revenue in any given quarter, but a breakdown in the premise that visibility can extend to 2028. A large part of BofA’s upgrade comes from longer-dated earnings power and a forward shift in the valuation benchmark. If the long-term evidence weakens, the high-valuation parts of the chain will come under pressure first.
The biggest point to watch is the “future EPS power trade.” When the market is willing to value companies on 2028 or 2030 earnings power, share prices become highly sensitive to long-term assumptions. The upside is that if visibility continues to improve, valuations can keep being revised higher; the downside is that any delivery delay, pricing looseness, or customer pushback on pricing will be amplified.
XIV. What to Watch Over the Next Four Quarters
A report like this cannot stop at the investment view. It has to be tested with data. Over the next four quarters, the most important variables are not moves in the semiconductor index, but six categories of evidence.
If these indicators improve together, the AI semiconductor trade will continue to spread from GPUs into memory, equipment, interconnect, CPUs, testing, and power. If one or two of them begin to deteriorate, the market will retreat from “full-chain revaluation” back to “only buy the most certain bottlenecks.” That is the core of stock selection over the next year.
XV. Conclusion: U.S. Semiconductors Are Moving from Cyclical Recovery to Bottleneck-Asset Revaluation
The most valuable part of this BofA report is that it pushes U.S. semiconductors from “AI demand is strong” to “can the AI supply chain deliver?” That shift determines why semiconductor investing will no longer be only about who is closest to GPUs, but about who controls bottlenecks, who can lock in customers, and who can convert complexity into profit.
Memory is the first tollgate. HBM, DRAM, and NAND/eSSD are all being tightened by AI demand, while long-term contracts and cleanroom construction extend earnings visibility beyond a traditional cycle. Equipment is the second gate. The WFE supercycle framing out to 2028 reflects rising complexity per wafer, not simply a revenue-share effect. CPUs and interconnect are the third main thread. Agentic AI will push CPUs, memory, networking, and accelerators onto the same main stage. Testing and power are the fourth layer of extension. Monetization may be slower, but the direction is not weak.
The most robust investment framework is to buy hard-to-replace supply first, then system architecture migration, and finally general recovery. MU, AMAT/LRCX/KLAC, MRVL/CRDO, TER, and INTC/ARM represent different layers of AI semiconductor revaluation and should not be placed in the same generic “AI-related” basket.
This U.S. semiconductor cycle still has cyclicality, and it still has valuation risk. What is genuinely different is this: AI has lifted the cyclical bottom across multiple sub-industries, extended long-term visibility, and pushed the hardest-to-deliver parts of the supply chain back to the center of valuation. As long as cloud capex, memory long-term contracts, WFE orders, and data-movement products continue to validate one another, the central question for semiconductors is not whether they have risen enough, but who can still turn bottlenecks into profit.