
TSMC CoWoS Repricing: How CPU, GPU, ASIC, and Optical Interconnects Are Rewriting AI Semiconductor Profit Distribution
目录
Too Long; Didn’t Read
I. The Core Change in This Update: TSMC Is Moving from Foundry to AI System Capacity Platform
II. The Real Significance of the 2Q26 Preview: 2027 Capex Credibility
III. CoWoS at 200k/Month: The 2027 Delivery Ceiling for AI Chips
IV. SoIC Is the Second Valuation Variable: CPU and ASIC Complexity Will Keep Rising
V. ASIC Expansion Has Not Weakened GPUs; It Has Lifted TSMC and the Test Chain
VI. HBM Demand Shows One Thing: CoWoS Expansion Will Continue to Squeeze Memory Supply
VII. Optical Interconnect and CPO: TSMC’s Long-Term Option Value Lies Not in Modules, but in an Optoelectronic Integration Platform
VIII. Why Test Equipment Suddenly Matters: AI Chip Complexity Turns Test Time into a Profit Pool
IX. Ranking Companies and Segments: TSMC in the First Layer, ASIC/Test/Optical Interconnects in the Second, Domestic China Chain in the Third
X. How to Think About Valuation: TSMC’s P/E Buys a 2027 AI Delivery Option
XI. How to Position the China Chain: AI Inference and Test Complexity Are the Real Validation Points
XII. Risks and Falsification: The Biggest Risk for This AI Semiconductor Cycle Is a Break in “Synchronized Capacity”
XIII. Tracking Indicators for the Next Four Quarters: Do Not Just Watch Share Prices; Watch Capacity, Customers, and Test Orders
XIV. Conclusion: The AI Compute Chain Is Moving From “Whose Chip Is Stronger” to “Who Can Deliver the System”
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
TSMC’s next round of upward revision comes from AI systems tightening the same constraint set: advanced nodes, CoWoS, SoIC, CPUs, ASICs, HBM, and test time. The key signal from Morgan Stanley’s June 30 update is that packaging capacity is shifting from a delivery bottleneck into a rule for profit allocation, and valuation will be repriced accordingly.
Too Long; Didn’t Read
TSMC is collecting a platform fee. Morgan Stanley raised TSMC’s 2026/2027 capex forecasts to US$56bn and US$75bn, and expects leading-edge process pricing to rise another 5%-10% in 2027. The substance of this price increase is that AI customers are willing to hand more system value to TSMC in exchange for access to 2nm/3nm, CoWoS, SoIC, HBM integration, and capacity queue priority.
The CoWoS bottleneck is becoming a valuation anchor. Morgan Stanley lifted TSMC’s year-end monthly CoWoS capacity from 70k in 2025 and 120k in 2026 to 200k in 2027. Non-TSMC supply also rises from 23k in 2025 to 80k in 2027, but TSMC still captures the most critical and most technically demanding GPU/ASIC packaging. In 2027, only those who can secure CoWoS will be able to convert AI chip revenue into server shipments.
CPUs are also entering the AI compute ledger. Vera CPU and Venice CPU are included in the AI wafer consumption table, showing that agentic AI does not only consume GPUs; it also pulls demand for server CPUs, memory control, cache, and advanced packaging. Morgan Stanley’s bull case gives a US$238bn CPU orchestration TAM. What readers should track is not the popularity of the CPU theme, but whether CPUs are actually consuming N3/N2 and SoIC capacity.
ASICs have not weakened GPU pricing. Google TPU, AWS Trainium, Microsoft Maia, Meta MTIA, and Global Unichip customer projects jointly consume CoWoS, HBM, advanced process, and test resources. Their expansion increases TSMC’s platform revenue and the profit pool for MediaTek, Alchip, Global Unichip, King Yuan Electronics, ASE, and related supply-chain names. In the near term, GPU versus ASIC competition looks more like a joint upward revision for TSMC, HBM, and test equipment.
Optical interconnects and test equipment are second-layer elasticity. Morgan Stanley frames CPO, probe cards, handlers, sockets, and photonics automation as part of the semiconductor solution. It expects the handler market to grow from US$436mn in 2023 to US$6.6bn in 2027, MPI’s probe card share to rise from 8% in 2024 to 20% in 2028, and WinWay’s pin capacity to increase from 3.5mn per month in 2025 to 9mn in 2026. The more complex compute chips become, the more back-end test and optoelectronic coupling resemble binding constraints.
The biggest risk is capacity mismatch. If CoWoS really ramps to 200k per month in 2027, but any link in the chain undershoots expectations, whether cloud capex, HBM supply, Rubin/TPU/Trainium delivery cadence, or power deployment, TSMC’s high capex will shift from evidence of pricing power into depreciation pressure. Over the next four quarters, the four numbers to watch most closely are monthly CoWoS output, N2 customer queues, AI revenue share, and advanced-packaging-related test equipment orders.
I. The Core Change in This Update: TSMC Is Moving from Foundry to AI System Capacity Platform
The most important point in Morgan Stanley’s June 30 update is not another confirmation that AI demand is strong. It is the decomposition of “strong demand” into several billable components for TSMC: advanced nodes, CoWoS, SoIC, HBM integration, system-level testing, optical interconnect automation, and customer capacity queuing.
This means TSMC’s asset attributes have moved up another layer. The old TSMC was the leader in advanced process technology; customers paid for the transistor density, yield, and delivery schedule of N5, N3, and N2. The new TSMC looks more like an AI system capacity platform. Customers are paying for the ability to deliver GPU, CPU, ASIC, HBM, optical interconnect, and testing together as deployable compute capacity. Wafers are only the starting point. Advanced packaging and back-end validation determine whether these chips can enter the rack.
This change will affect profit distribution across the AI semiconductor stack. The old GPU versus ASIC debate often fell into the question of whether Nvidia would be replaced by cloud vendors’ in-house chips. This material gives a more specific answer: whether Nvidia Rubin, AMD MI455/MI400, Google TPU v8/v9, AWS Trainium3, Microsoft Maia, or Meta MTIA, all of them must queue for advanced process, CoWoS, HBM, and test resources. As long as this resource set remains tight, GPU and ASIC competition will jointly lift TSMC’s platform value.
GPUs Will Not Lose, but XPUs Will Rewrite Profit Distribution: AI Compute Moves from Chip Wars to Performance-per-Watt Wars
The broader GPU/XPU piece addresses compute form factors and profit distribution. This TSMC update is closer to the manufacturing side. GPUs will not be simply replaced by XPUs, but XPUs will spread profit from a single GPU chip into foundry, packaging, HBM, optical interconnects, testing, and system delivery. TSMC stands at the center of that spread.
A platform fee is not an accounting line item. It is the supply chain repricing scarce links. AI customers are not buying a single wafer or a single packaging service. They are buying a system path that can deliver on time. Advanced process provides compute density, CoWoS connects compute chips with HBM, SoIC pushes CPUs, cache, and specific logic to higher integration, and test equipment screens failures in complex packages earlier. As long as these steps must be scheduled together, TSMC is no longer just “foundry price multiplied by wafer volume”; it is charging a certainty premium for system delivery.
This is also why capex must be analyzed together with customer structure. In traditional semiconductor expansion, the biggest fear is building capacity first and finding orders later; once capacity is excessive, it quickly hits pricing and gross margin. TSMC’s current expansion is closer to reverse modeling: customers first provide AI rack, accelerator card, CPU, ASIC, and HBM roadmaps, and TSMC translates them into investments in advanced process, packaging, testing, and fabs. Capex still carries cyclical risk, but the source of risk has shifted from “is there demand?” to “can customer commitments become deliverable systems on time?”
Another implication of a manufacturing platform is that the more customers there are, the stronger the platform becomes. GPUs, ASICs, and CPUs will compete in end markets, but at TSMC they provide diversification. Nvidia Rubin, AMD MI, Google TPU, AWS Trainium, Microsoft Maia, and Meta MTIA each have their own architecture, software, and total cost of ownership logic, but on the manufacturing side they cannot bypass TSMC’s advanced process and advanced packaging. A delay in a single customer project can create volatility, but multiple customers competing for the same set of critical resources makes TSMC’s queue priority more valuable.
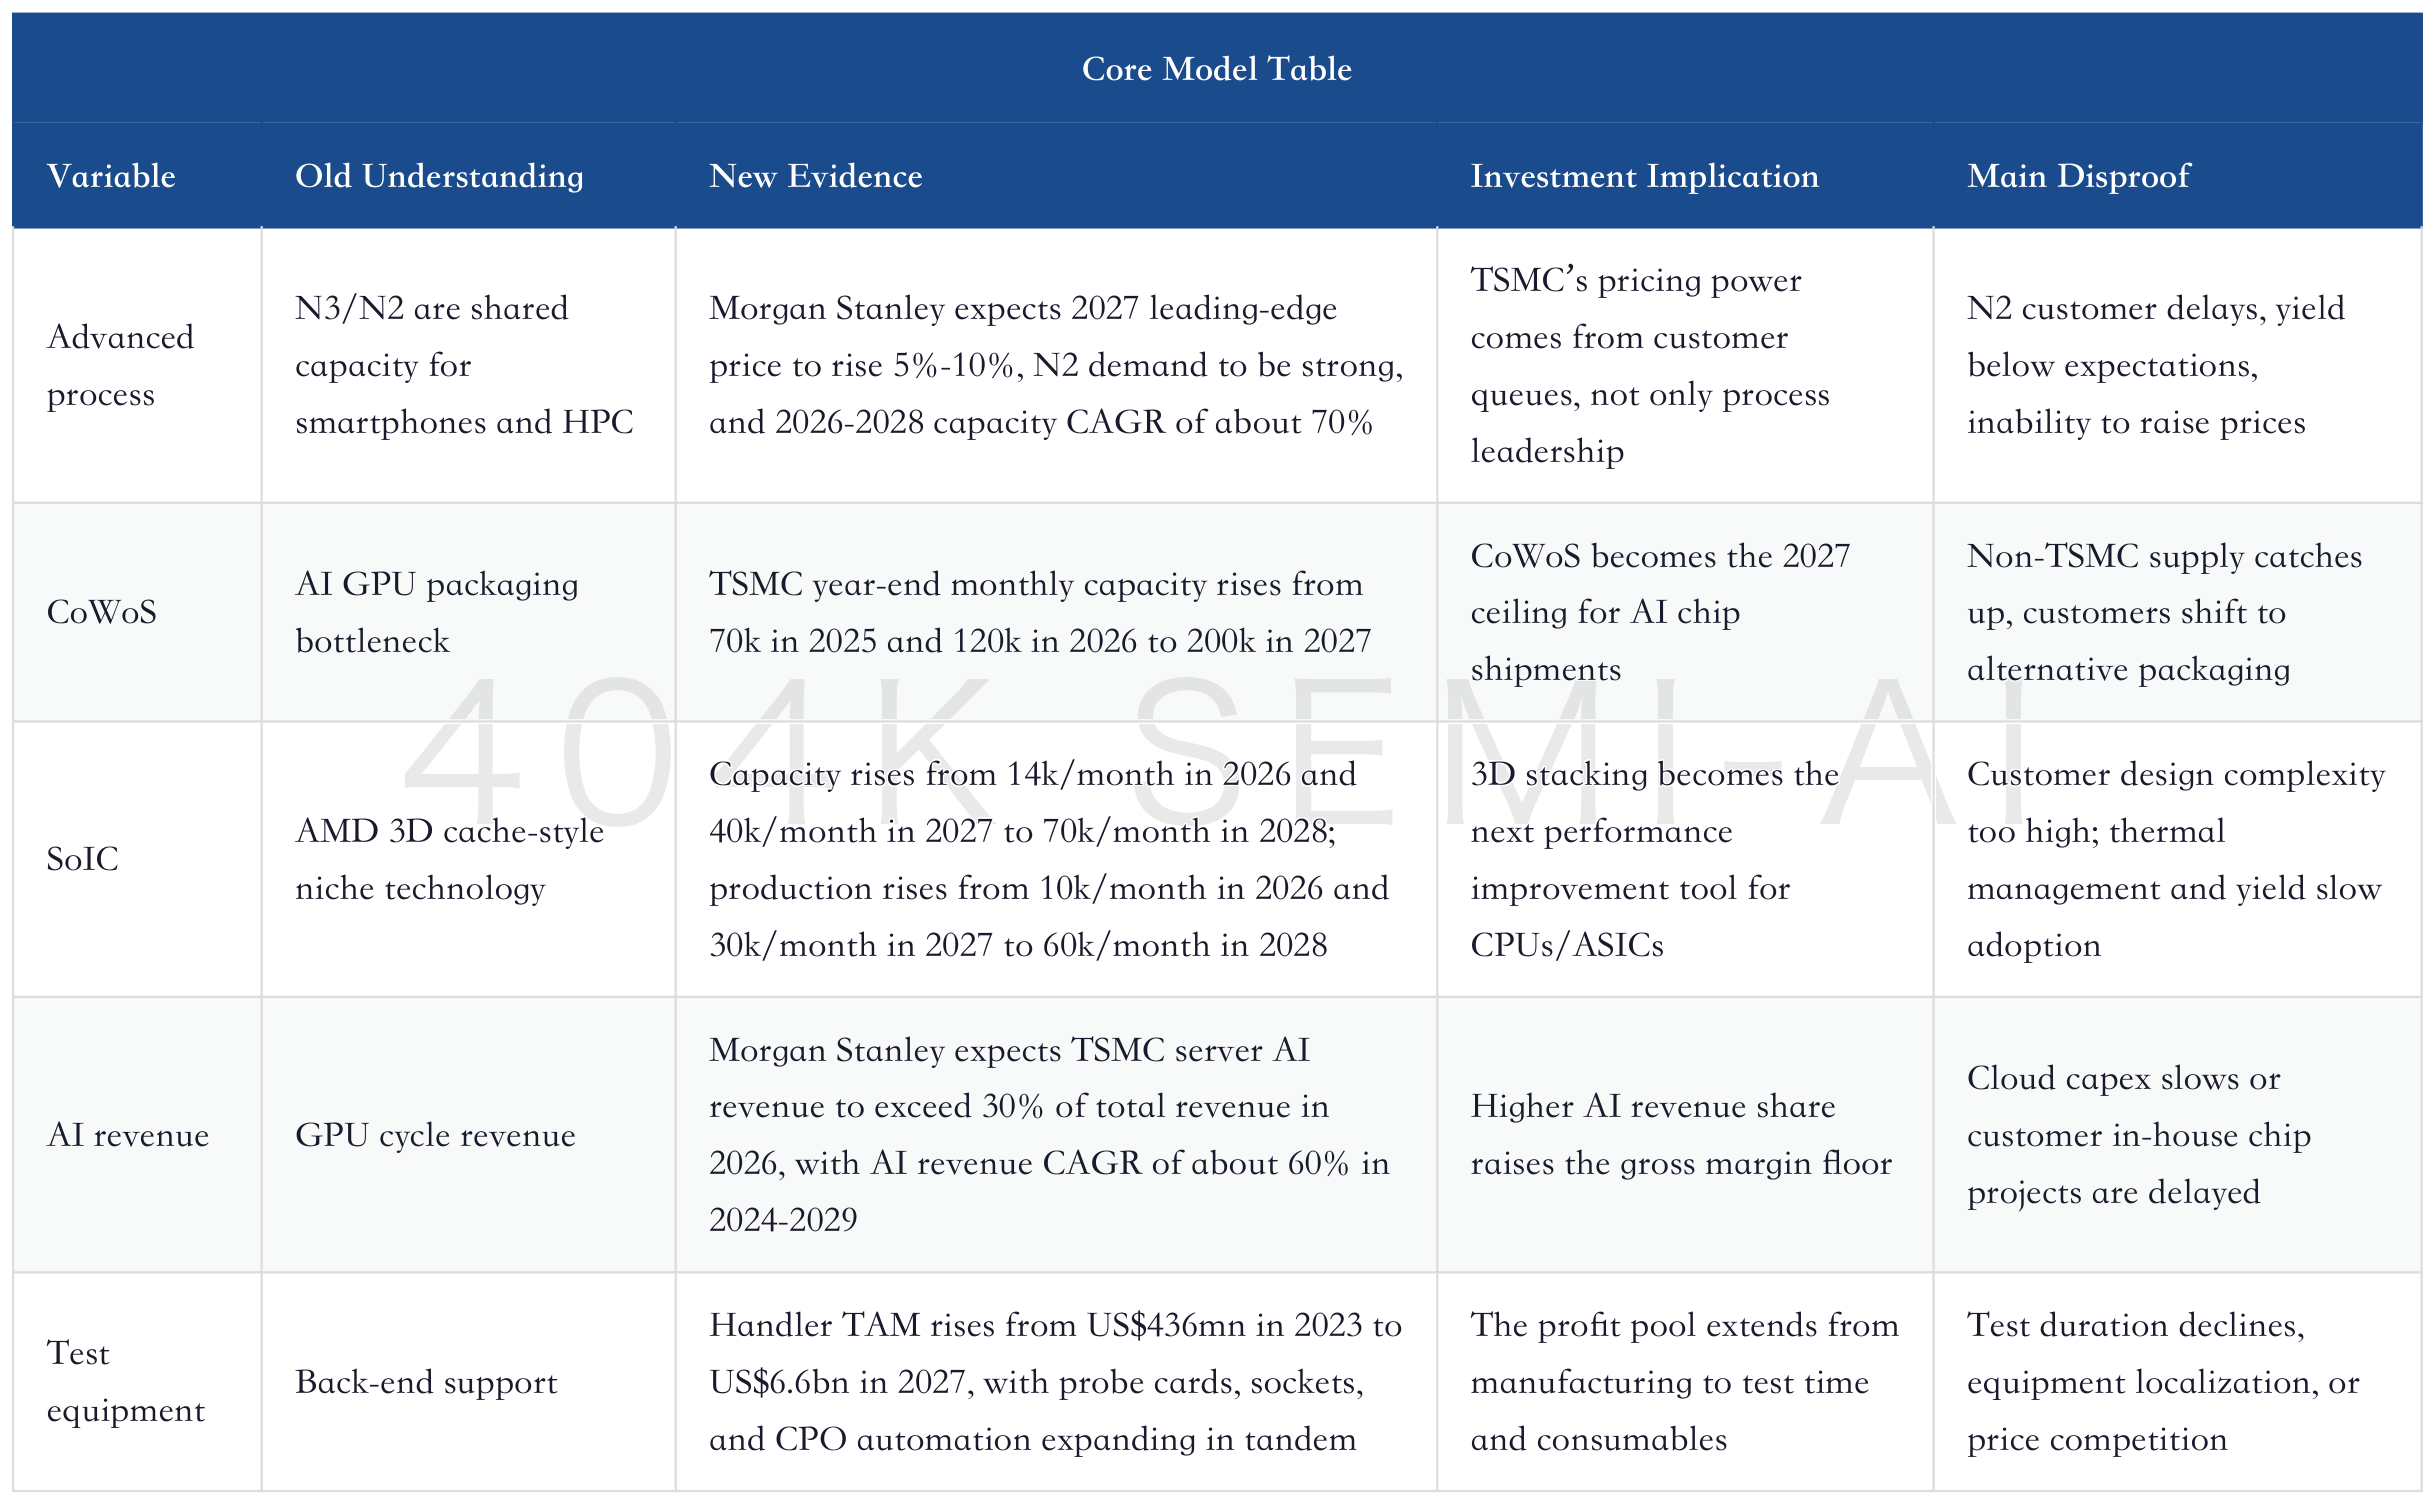
Behind this table is a hard judgment: the reason for upward revision in TSMC’s valuation is expanding from “process leadership” to “irreplaceable system delivery.” Looking only at wafer pricing underestimates the value that CoWoS and SoIC allow TSMC to recapture. Looking only at CoWoS capacity underestimates the secondary constraints that testing, HBM, and optical interconnects impose on delivery.
II. The Real Significance of the 2Q26 Preview: 2027 Capex Credibility
On the surface, this update contains a TSMC 2Q26 earnings preview, but the investment question is no longer whether 2Q26 EPS beats. What the market really wants to see is whether TSMC can raise 2026 and 2027 capex enough to support AI system deliveries without breaking gross margin.
Morgan Stanley raised its 2026/2027 capex forecasts for TSMC to US$56bn and US$75bn. In isolation, these numbers look heavy. In the context of AI demand, they become a leading signal: TSMC has already put 2027 N2, N3, CoWoS, SoIC, and overseas capacity onto the same planning sheet. Capex is not being spent first while waiting for demand; it is being reverse-engineered from customer commitments, rack power, cloud capex, and advanced-packaging schedules.
This is different from prior semiconductor expansion cycles. Memory or mature-node expansions are often vulnerable to oversupply because product differentiation is not strong enough and pricing can be pushed down by new capacity. TSMC’s current expansion looks more like “queue-list-driven dedicated capacity”: Nvidia, AMD, Google, AWS, Microsoft, Meta, Apple, Broadcom, MediaTek, and other customers have different chip roadmaps, but all need TSMC’s scarcest advanced process and packaging platforms.
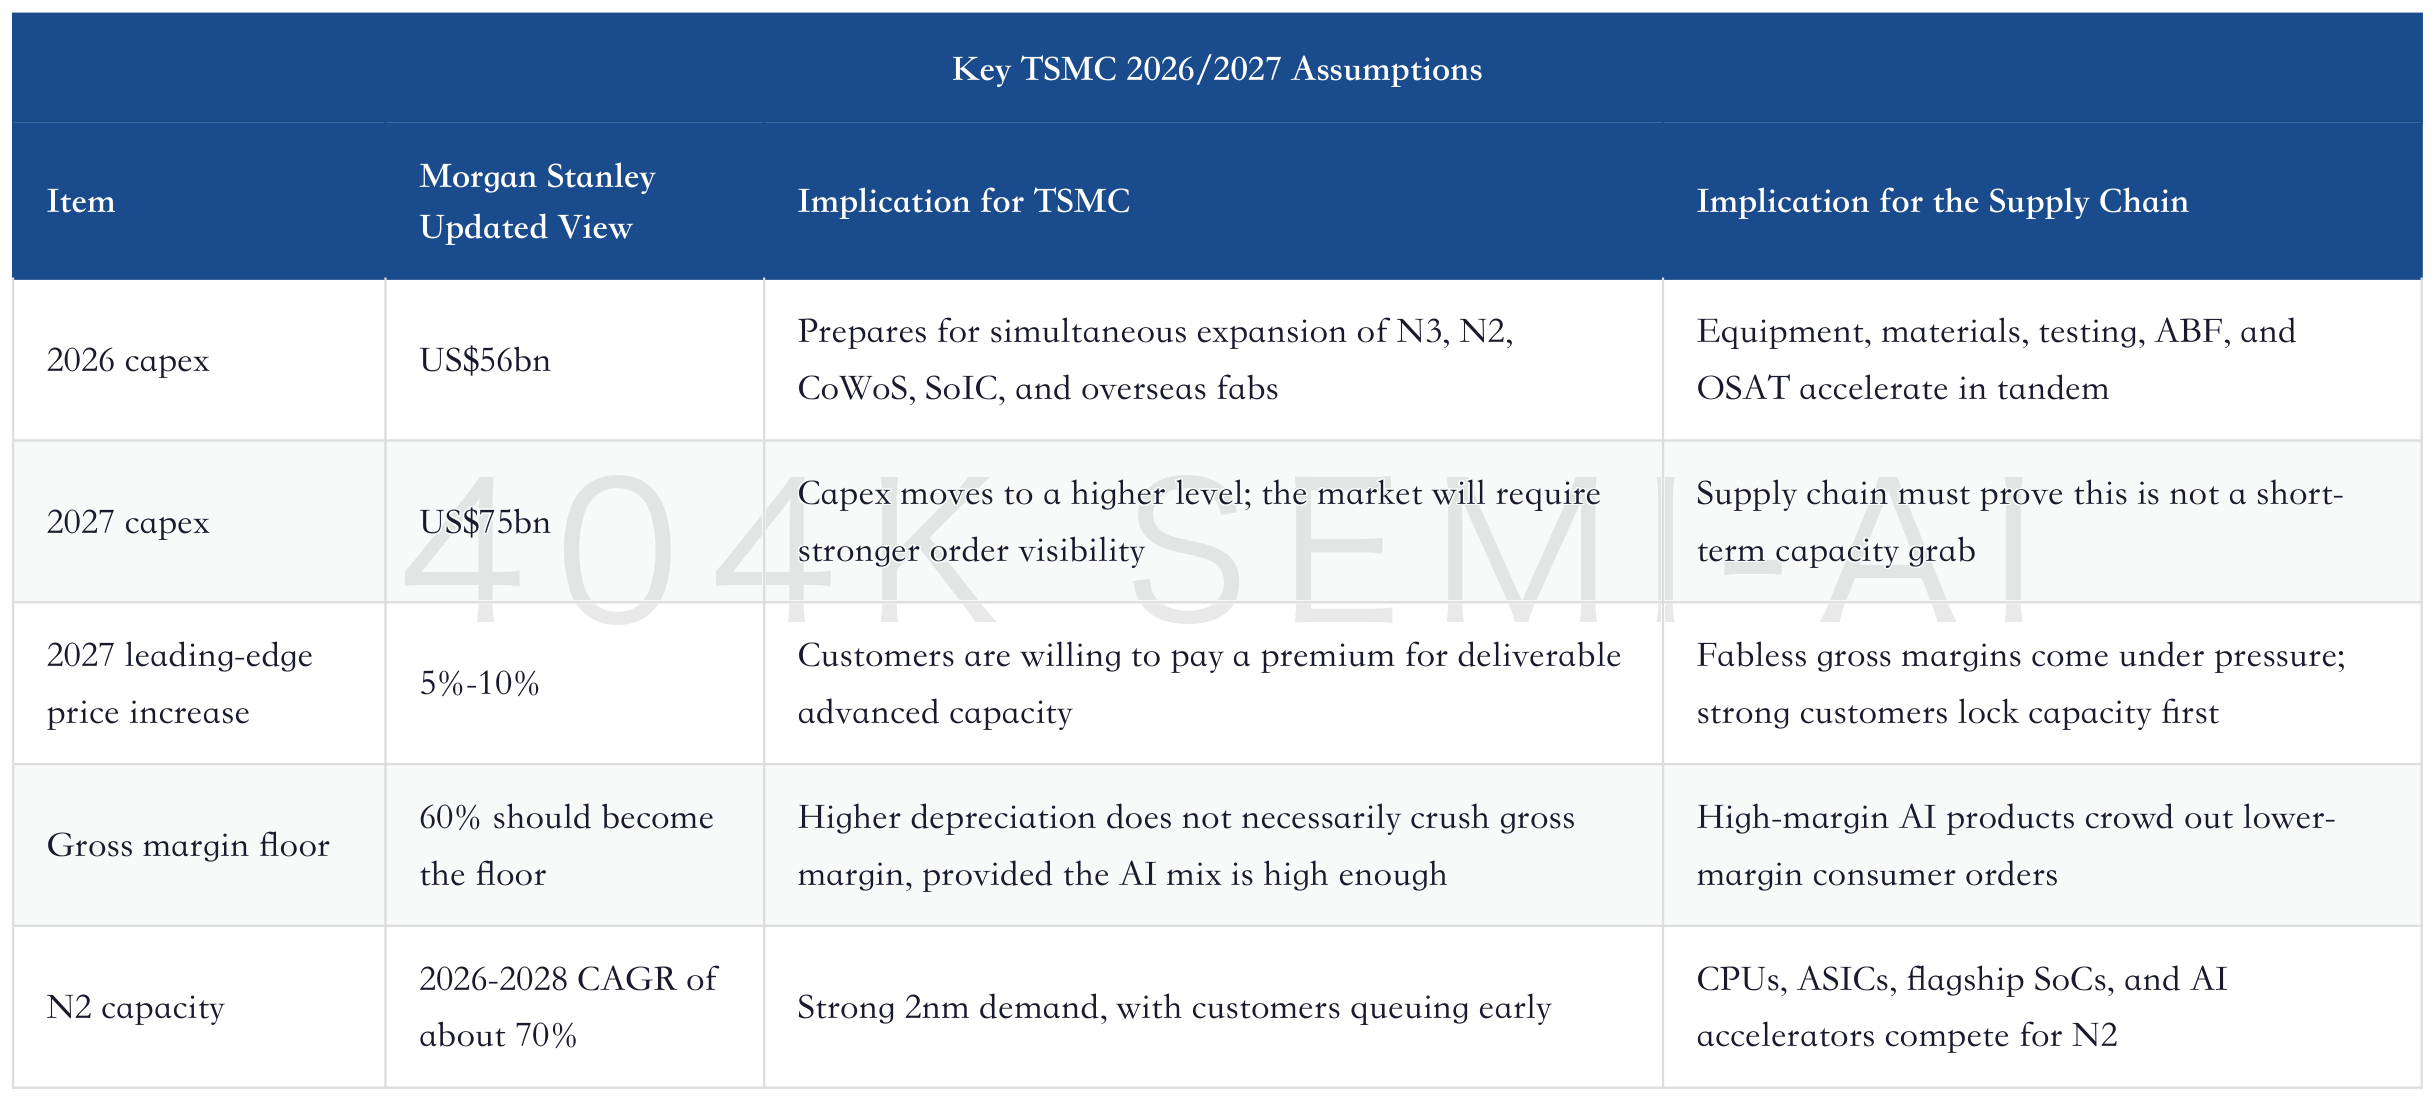
The key to TSMC’s valuation is no longer as simple as “high capex pressures near-term free cash flow.” More importantly, can capex convert the next two years of orders into a capacity moat? If CoWoS, SoIC, and N2 are all pre-booked by customers, depreciation is merely a cost incurred before revenue recognition. If customer demand later softens, US$75bn becomes a reason for a valuation discount.
TSMC’s shareholder-meeting communications have already laid out AI demand, capex, and the global capacity footprint clearly. The incremental value in Morgan Stanley’s latest update is that it maps those management messages into more granular CoWoS, SoIC, CPU/ASIC wafer consumption, and back-end test equipment assumptions. In other words, capex is no longer just a management-level narrative; it is starting to be broken down into product and customer lists.
III. CoWoS at 200k/Month: The 2027 Delivery Ceiling for AI Chips
CoWoS is the core anchor of this update. Morgan Stanley expects TSMC’s year-end monthly CoWoS capacity to rise from 13k in 2023, 32k in 2024, 70k in 2025, and 120k in 2026 to 200k in 2027. Non-TSMC supply is also rising, from 3k in 2023, 6k in 2024, 23k in 2025, and 50k in 2026 to 80k in 2027.
The implication is straightforward. Global CoWoS-like capacity will expand meaningfully in 2027, but TSMC will still capture the largest, most complex, and highest-premium portion of demand. Non-TSMC supply can ease some pressure, but it is unlikely to replace TSMC’s ecosystem position in Nvidia, AMD, Google, AWS, Apple, and high-end ASICs in the near term.
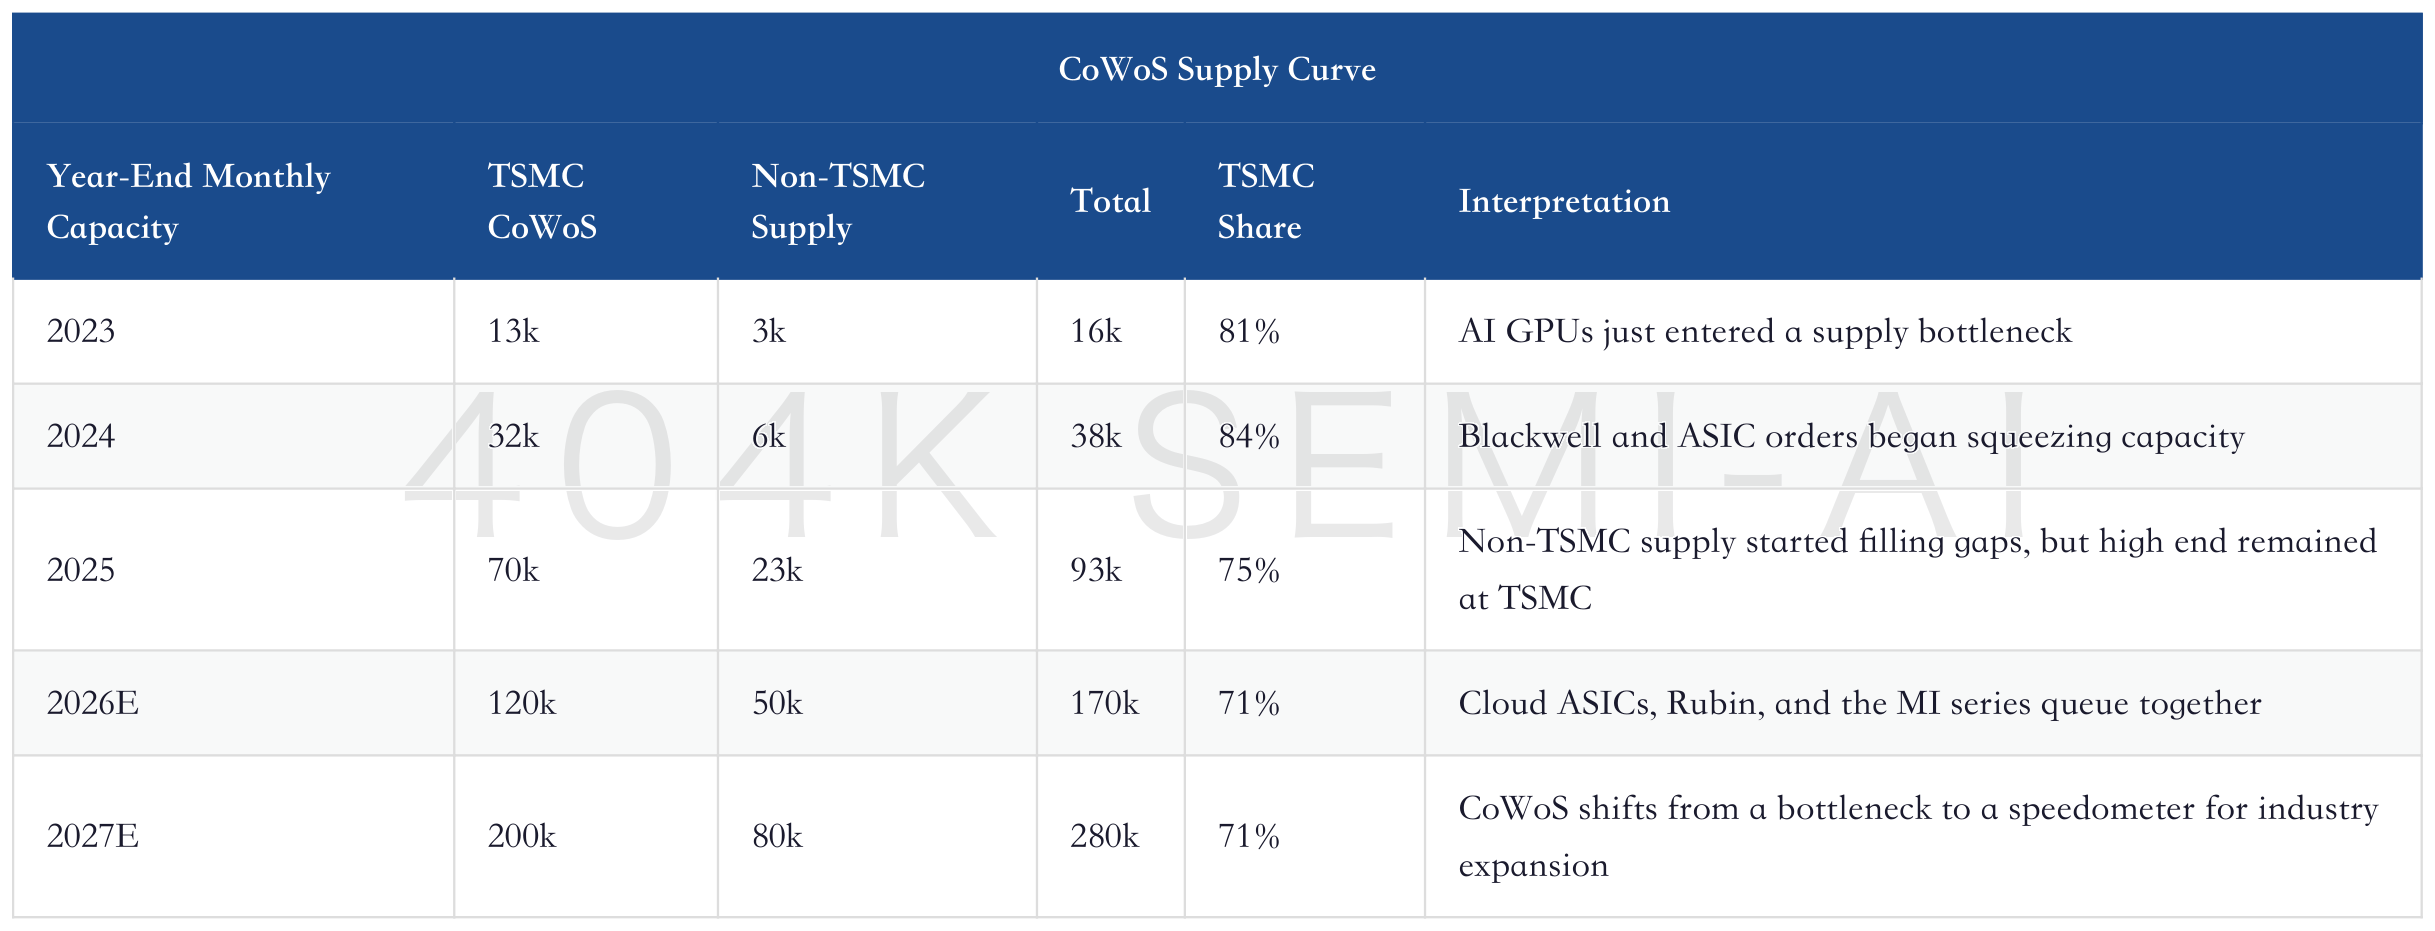
This table should be read together with power deployment. Morgan Stanley reverse-engineers AI chip capacity consumption from disclosed power deployment: Nvidia Vera Rubin NVL144 corresponds to 10GW, 45k racks, 409k lifetime CoWoS wafers, and 136k wafers of annualized CoWoS demand in 2027; AMD Helios corresponds to 6GW, 27k racks, 166k lifetime wafers, and 55k wafers of 2027 demand; Broadcom TPU corresponds to 3.5GW, 56k racks, 260k lifetime wafers, and 52k wafers of 2027 demand; AWS Trainium3 corresponds to 2GW, 14k racks, 118k lifetime wafers, and 15k wafers of 2027 demand.
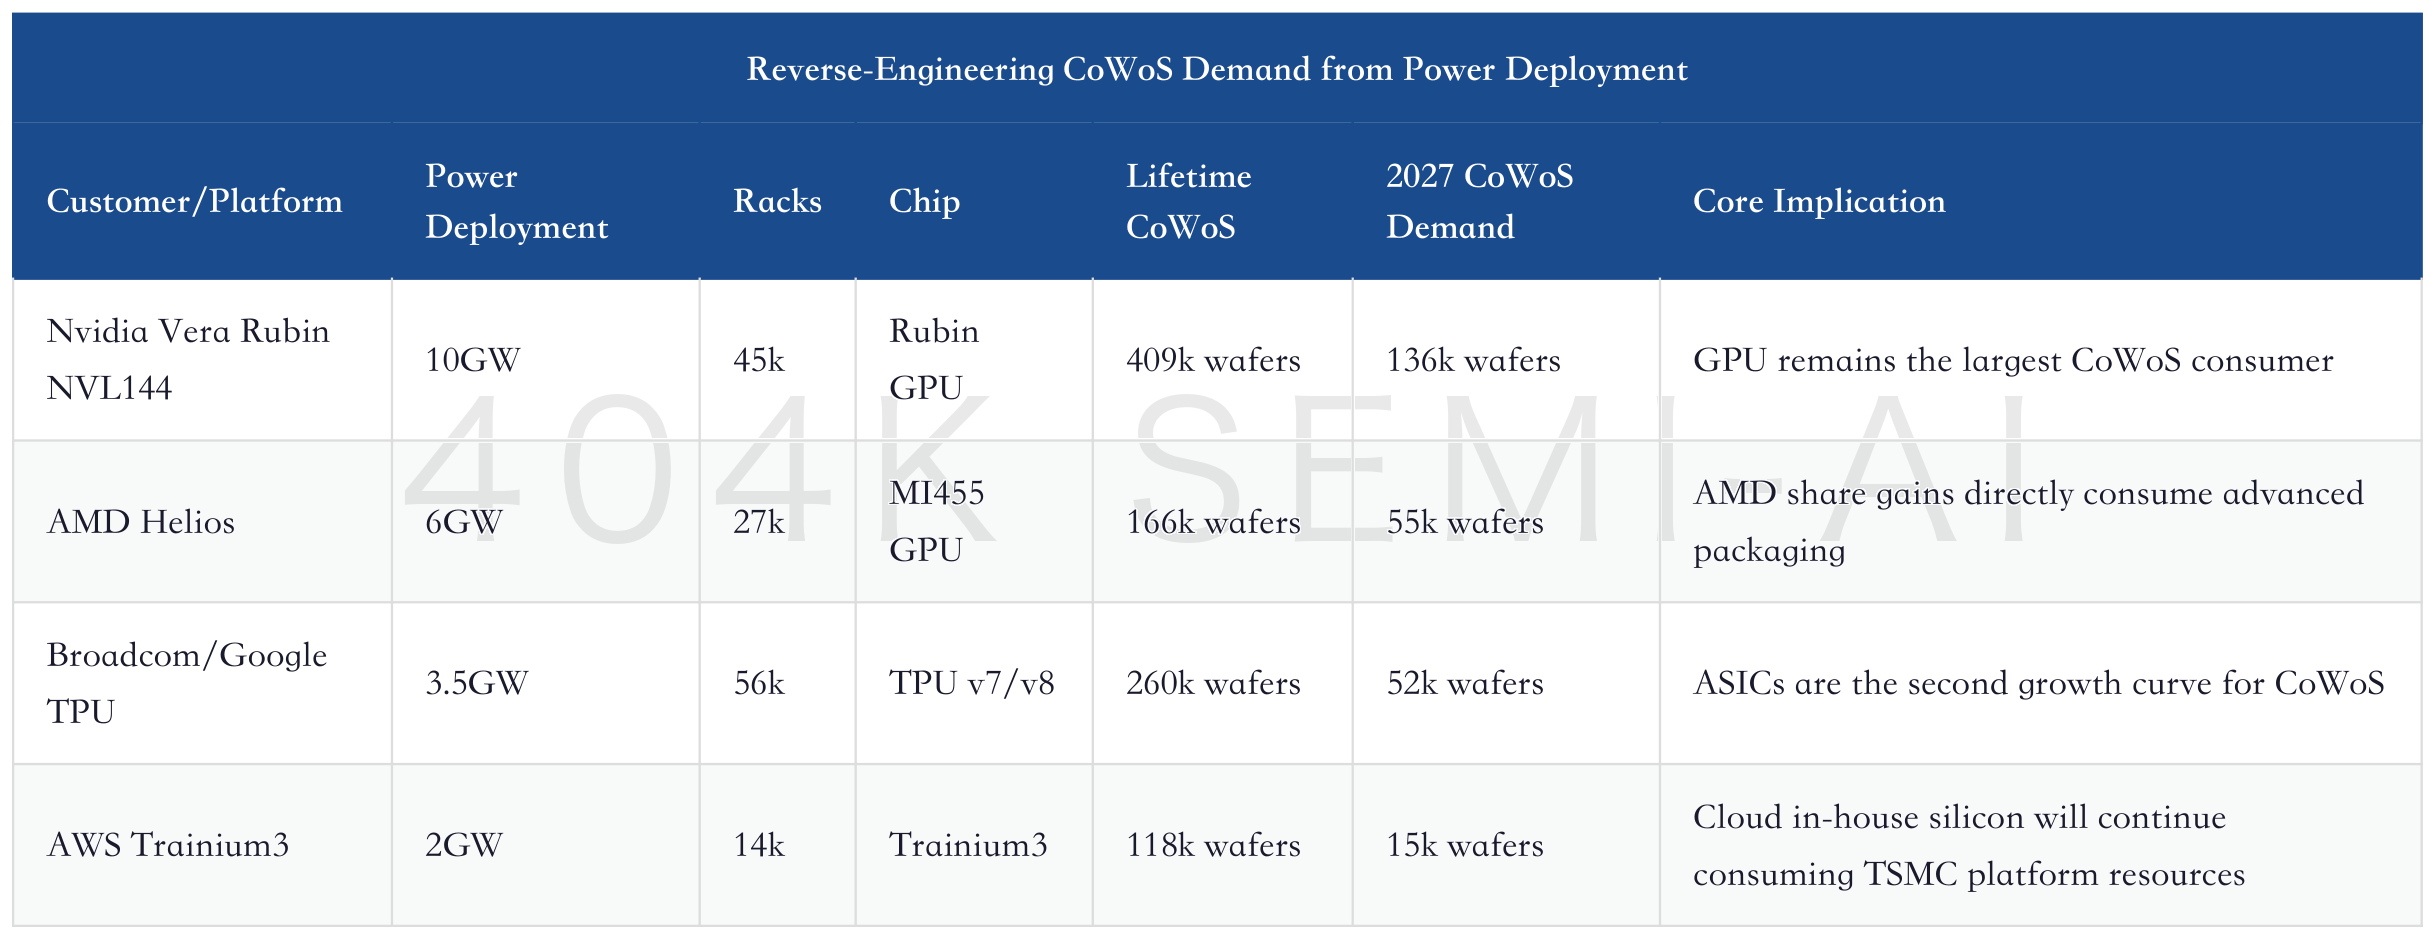
This reverse-engineering is more useful than simply saying “cloud capex is strong.” Cloud capex first becomes power, data centers, and racks, then GPU/ASIC unit volumes, and finally TSMC CoWoS and advanced-node orders. As long as this chain holds, CoWoS is the intermediate valve through which AI capex is converted into semiconductor revenue.
That broad diffusion analysis focused on orders expanding from GPUs into memory, PCBs, interconnects, equipment, and power. Today’s update quantifies the “packaging valve” within that diffusion chain. If 200k/month of CoWoS capacity in 2027 is delivered, AI semiconductors will move from chip shortages to system-delivery competition; if not, GPU, ASIC, HBM, and full-rack shipments will all have to re-queue.
The investment challenge with CoWoS is that it is both a supply constraint and proof of demand. The supply constraint is easy to understand: when packaging capacity is insufficient, GPUs and ASICs cannot be fully delivered even if they are manufactured. The demand proof is easier to overlook: only if customers are willing to lock in CoWoS in advance will TSMC dare to push capex to a higher level, and only then will equipment, substrates, testing, and OSAT follow with expansion. In other words, the CoWoS ramp itself is leading evidence of the quality of cloud AI orders.
Expansion of non-TSMC supply should not be simplistically read as TSMC share loss. Overflow of lower- to mid-complexity packaging can ease supply-chain tightness and give more ASIC projects a path to delivery. But the most difficult, highest-value, and deepest-validated customer programs will still likely stay with TSMC first. For TSMC, spillover supply may actually expand the ecosystem: as more customers adopt advanced packaging, TSMC remains the most natural target supplier when they later upgrade to more complex platforms.
More importantly, CoWoS is not an isolated process step. It ties together HBM supply, substrates, thermal solutions, system integrators, and test equipment. If any supporting link fails to keep up, nominal CoWoS capacity cannot fully translate into revenue. That is why, when assessing the 2027 capacity target, investors should focus on “effective output,” not just “nominal monthly capacity.” What can truly drive a valuation re-rating for TSMC is not the announced capacity number, but customers’ willingness to pay a premium for effective output.
IV. SoIC Is the Second Valuation Variable: CPU and ASIC Complexity Will Keep Rising
CoWoS addresses horizontal integration; SoIC addresses vertical stacking. The market has watched CoWoS for a long time, but this report places SoIC among TSMC’s key capacity-expansion priorities over the next few years. That matters.
Morgan Stanley expects TSMC’s SoIC month-end capacity to rise from 14k/month in 2026, to 40k/month in 2027, and 70k/month in 2028; production is expected to increase from 10k/month in 2026, to 30k/month in 2027, and 60k/month in 2028. On the demand side, SoIC demand from Nvidia, AMD, Apple, and other customers all steps up materially in 2027. Nvidia rises from 6k in 2026 to 120k in 2027, AMD from 42k to 60k, Apple from 36k to 60k, and other customers from 36k to 120k.
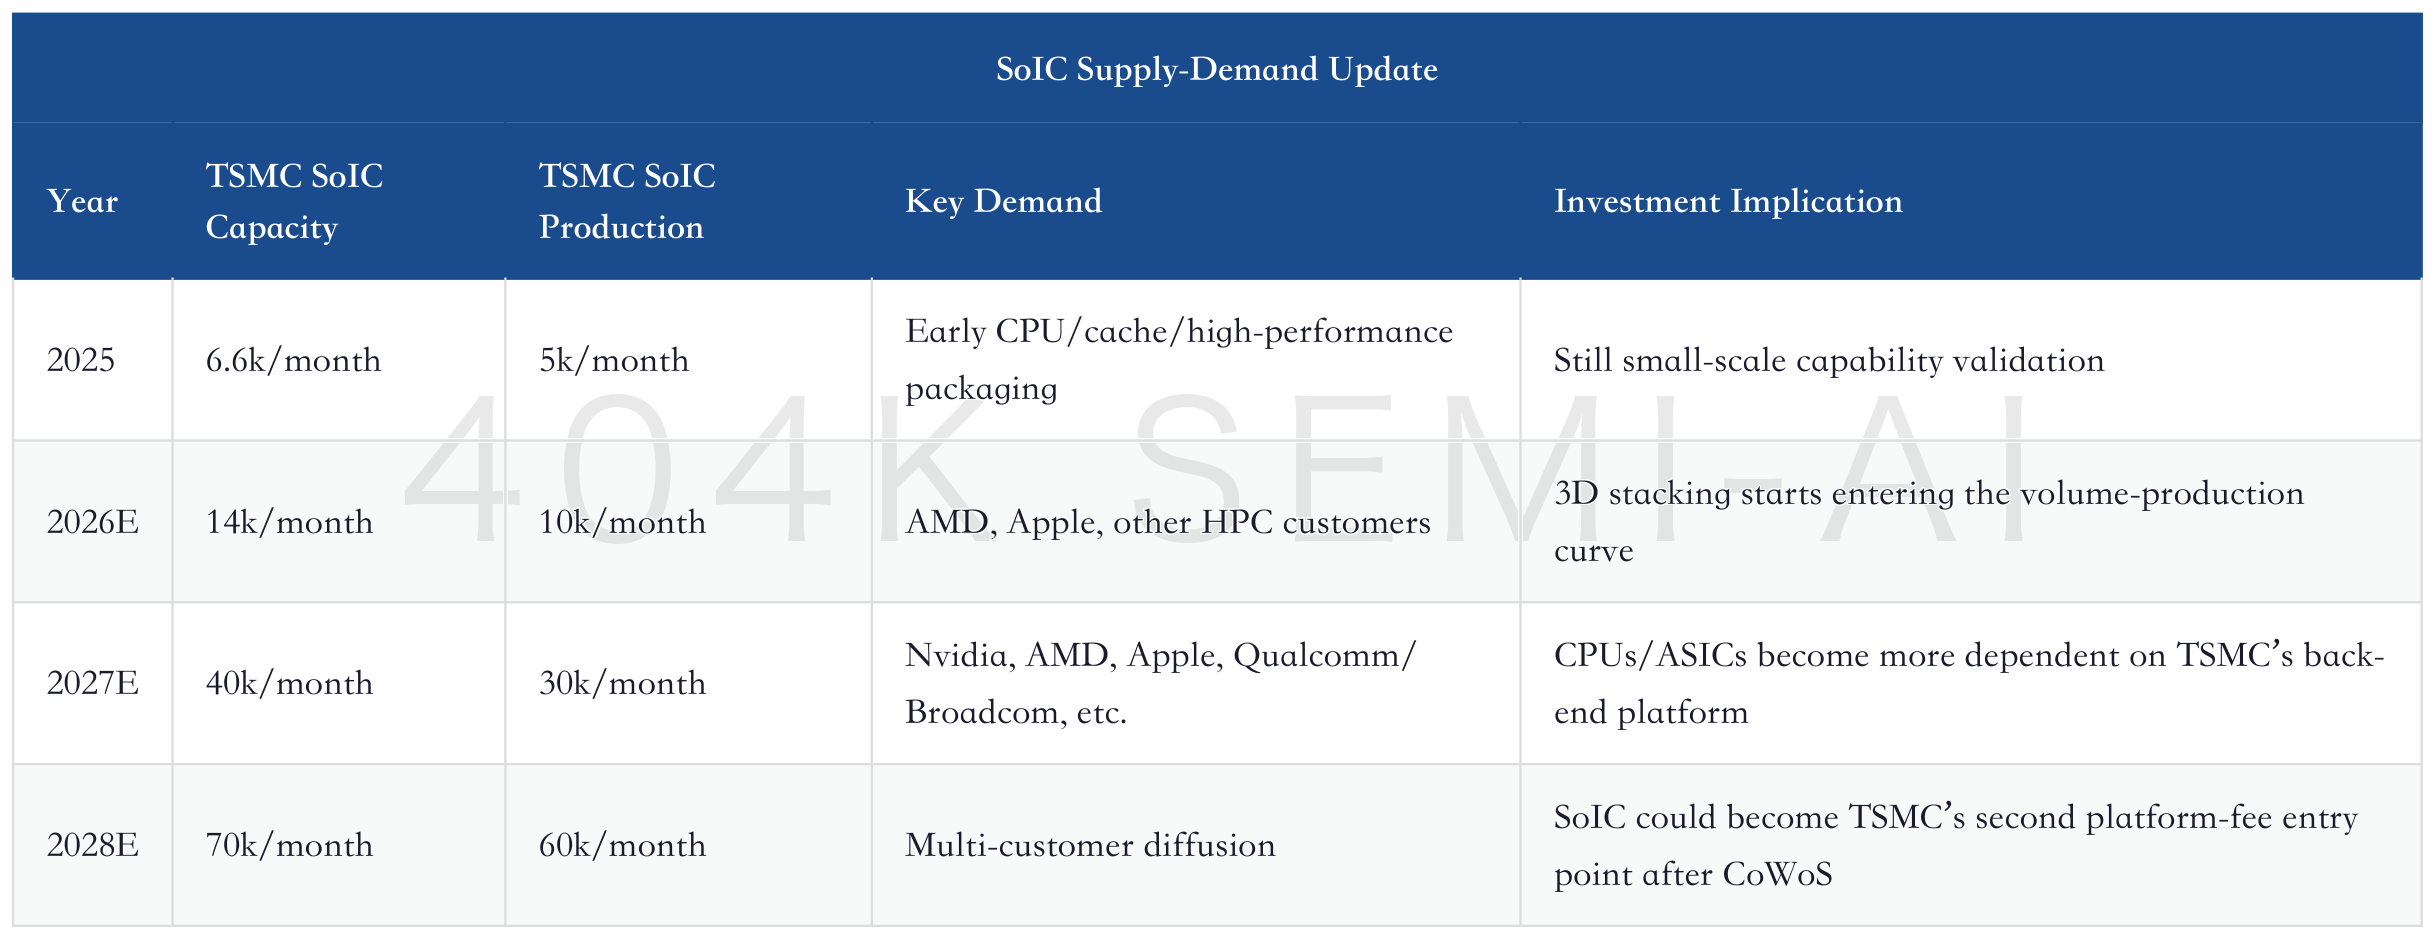
The significance of SoIC is not that it adds another packaging-technology acronym. It changes how CPU and ASIC performance improves. Advanced nodes continue to shrink transistors, but SRAM cache, interconnect distance, power consumption, and thermal density are increasingly hard to solve through process scaling alone. 3D stacking can bring cache, logic, I/O, and certain specialized functions closer together, which matters for CPU orchestration, AI ASICs, and high-performance SoCs.
Vera CPU is the symbol of this shift. Morgan Stanley includes Vera CPU in its AI computing wafer consumption table and emphasizes that Vera performance could reach 1.8x that of the highest-performance x86 CPU, while CPU cores are no longer split across chiplets, enabling faster core-to-core connections. The investment implication is straightforward: as AI inference moves toward agentic workloads, CPUs will not remain traditional server supporting actors. They will again consume advanced-node and packaging resources.
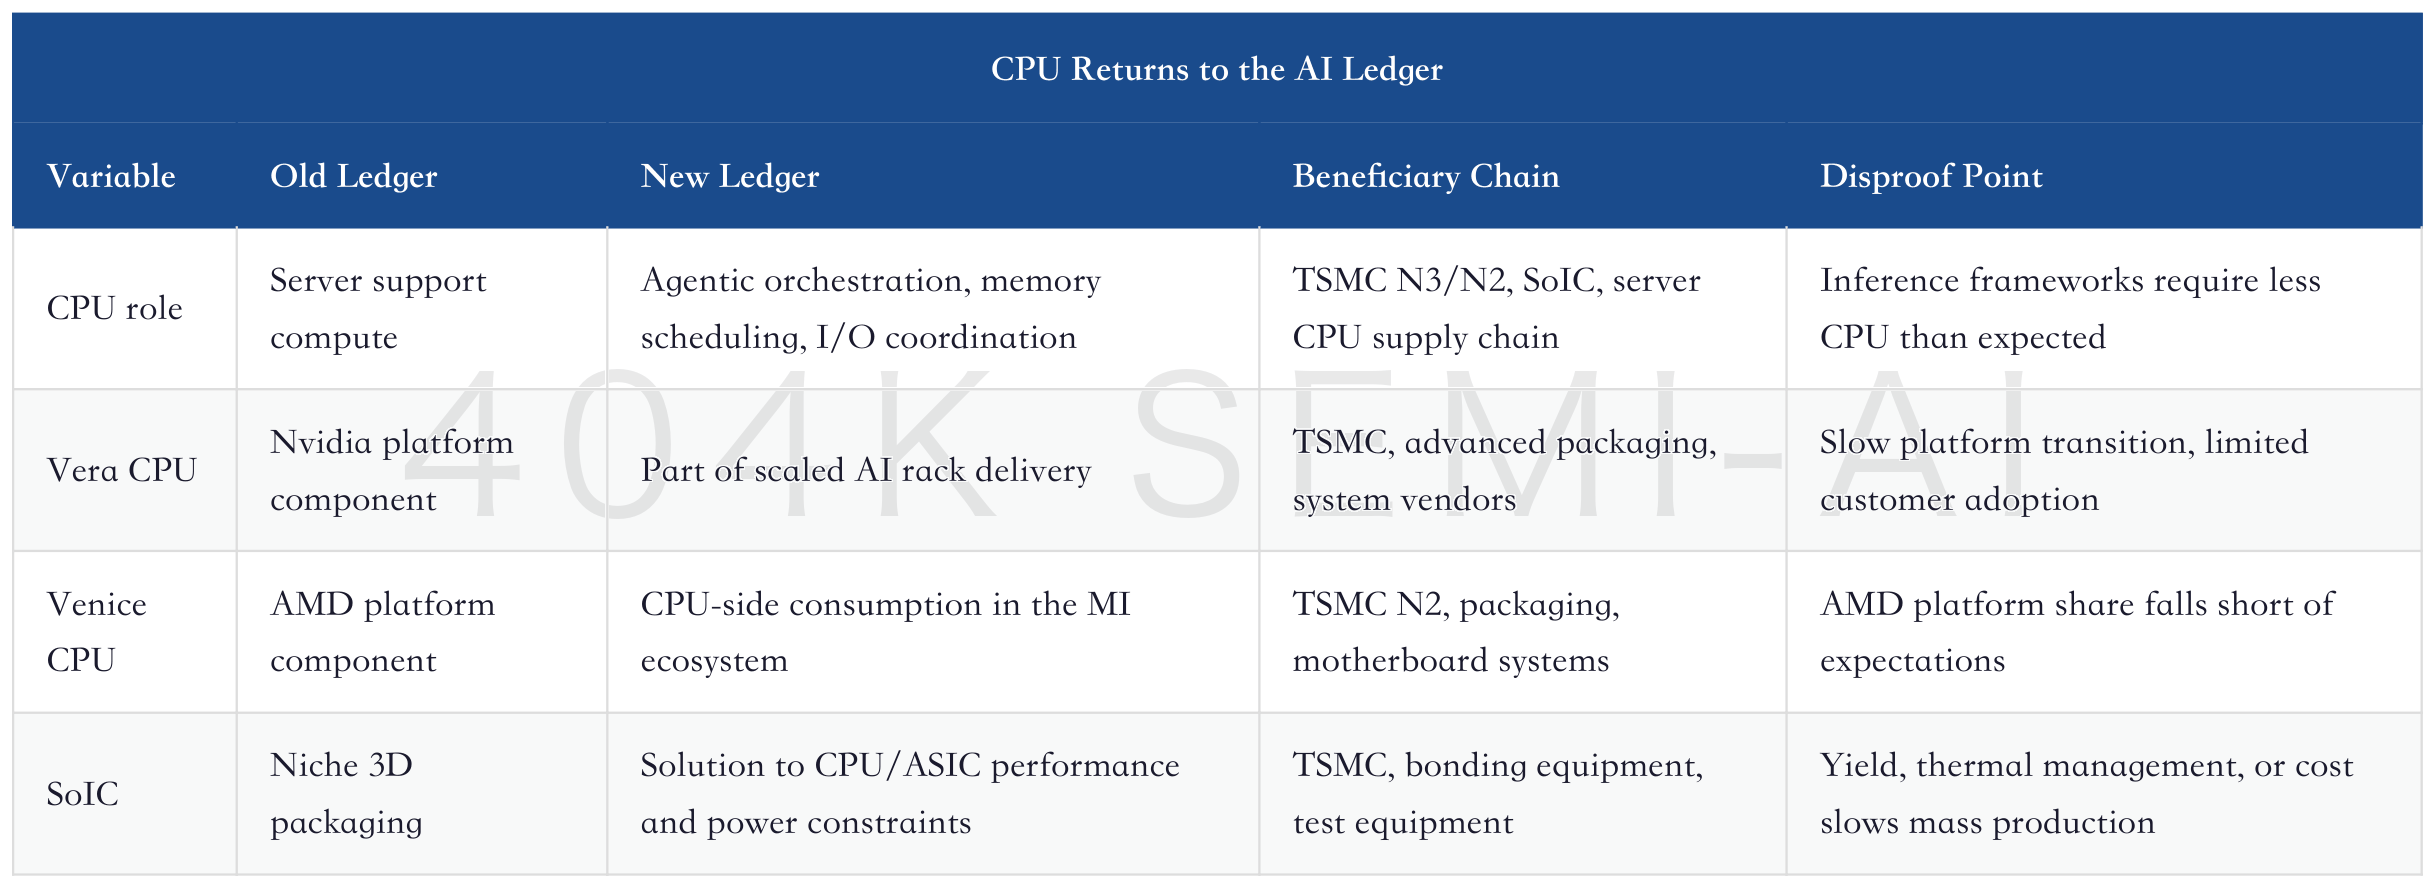
This is also where TSMC’s valuation is most easily underestimated. The market likes to divide AI semiconductors into buckets such as GPU, ASIC, CPU, memory, and networking, but the manufacturing side recombines them into the same problem: who can optimize across power, bandwidth, package area, HBM, testing, and delivery cycle. TSMC’s position in that problem is moving further forward.
SoIC’s upside has not fully entered most valuation models. CoWoS has already been repeatedly discussed by the market, and investors know it is the bottleneck for AI accelerators. SoIC is more like the next layer of complexity. It is not simply stacking chips together; it shortens the distance among CPU, cache, logic, and I/O. As advanced nodes move forward, transistor scaling alone becomes less able to solve bandwidth, power, and latency problems. 3D stacking will shift from a high-end option to a necessary tool for more high-performance chips.
This matters especially for CPUs. After AI inference enters agentic workloads, the system is not only running forward passes on a large model; it must also handle retrieval, tool calls, memory management, multitask scheduling, and security isolation. GPUs handle throughput, while CPUs handle organization and scheduling. Server architecture will again place greater emphasis on coordination between CPUs and accelerators. Vera CPU and Venice CPU are included in AI wafer consumption not because CPUs have suddenly become a hot concept, but because system-level AI makes CPUs consume advanced-node and packaging resources again.
TSMC’s advantage is its ability to synthesize these complex requirements into one manufacturing platform. Customers can choose different architectures at the design layer, but the manufacturing side requires the same capabilities in yield, thermals, interconnects, packaging, and testing. If SoIC adoption expands in CPUs and ASICs, TSMC’s monetization logic will extend from “advanced wafers + CoWoS” to “advanced wafers + horizontal packaging + vertical stacking + test validation.” The longer this chain becomes, the harder it is for latecomers to replicate.
V. ASIC Expansion Has Not Weakened GPUs; It Has Lifted TSMC and the Test Chain
The GPU-versus-ASIC debate is easily framed as a zero-sum war. The June 30 update gives a better lens: ASIC expansion will change profit distribution, but in the near term it will not weaken TSMC, HBM, or the test chain. Whether customers choose Nvidia, AMD, Google TPU, AWS Trainium, Microsoft Maia, or Meta MTIA, they all consume the same set of advanced manufacturing resources.
Morgan Stanley estimates that AI computing wafer consumption could reach $46.4 billion in 2027, with Nvidia still accounting for the largest share. Several figures in the table are highly revealing: Nvidia Rubin R200 corresponds to 740k CoWoS allocation, 5,920k compute die shipments, 470k compute die wafer consumption, and a wafer revenue TAM of $12.827 billion; Google TPU v8i corresponds to 330k CoWoS allocation, 3,960k compute die shipments, 296k wafer consumption, and $8.075 billion; TPU v8t corresponds to 180k CoWoS allocation, 3,600k shipments, 269k wafer consumption, and $7.341 billion; AWS Trainium3 corresponds to 140k CoWoS allocation, 2,380k shipments, 127k wafer consumption, and $3.465 billion.
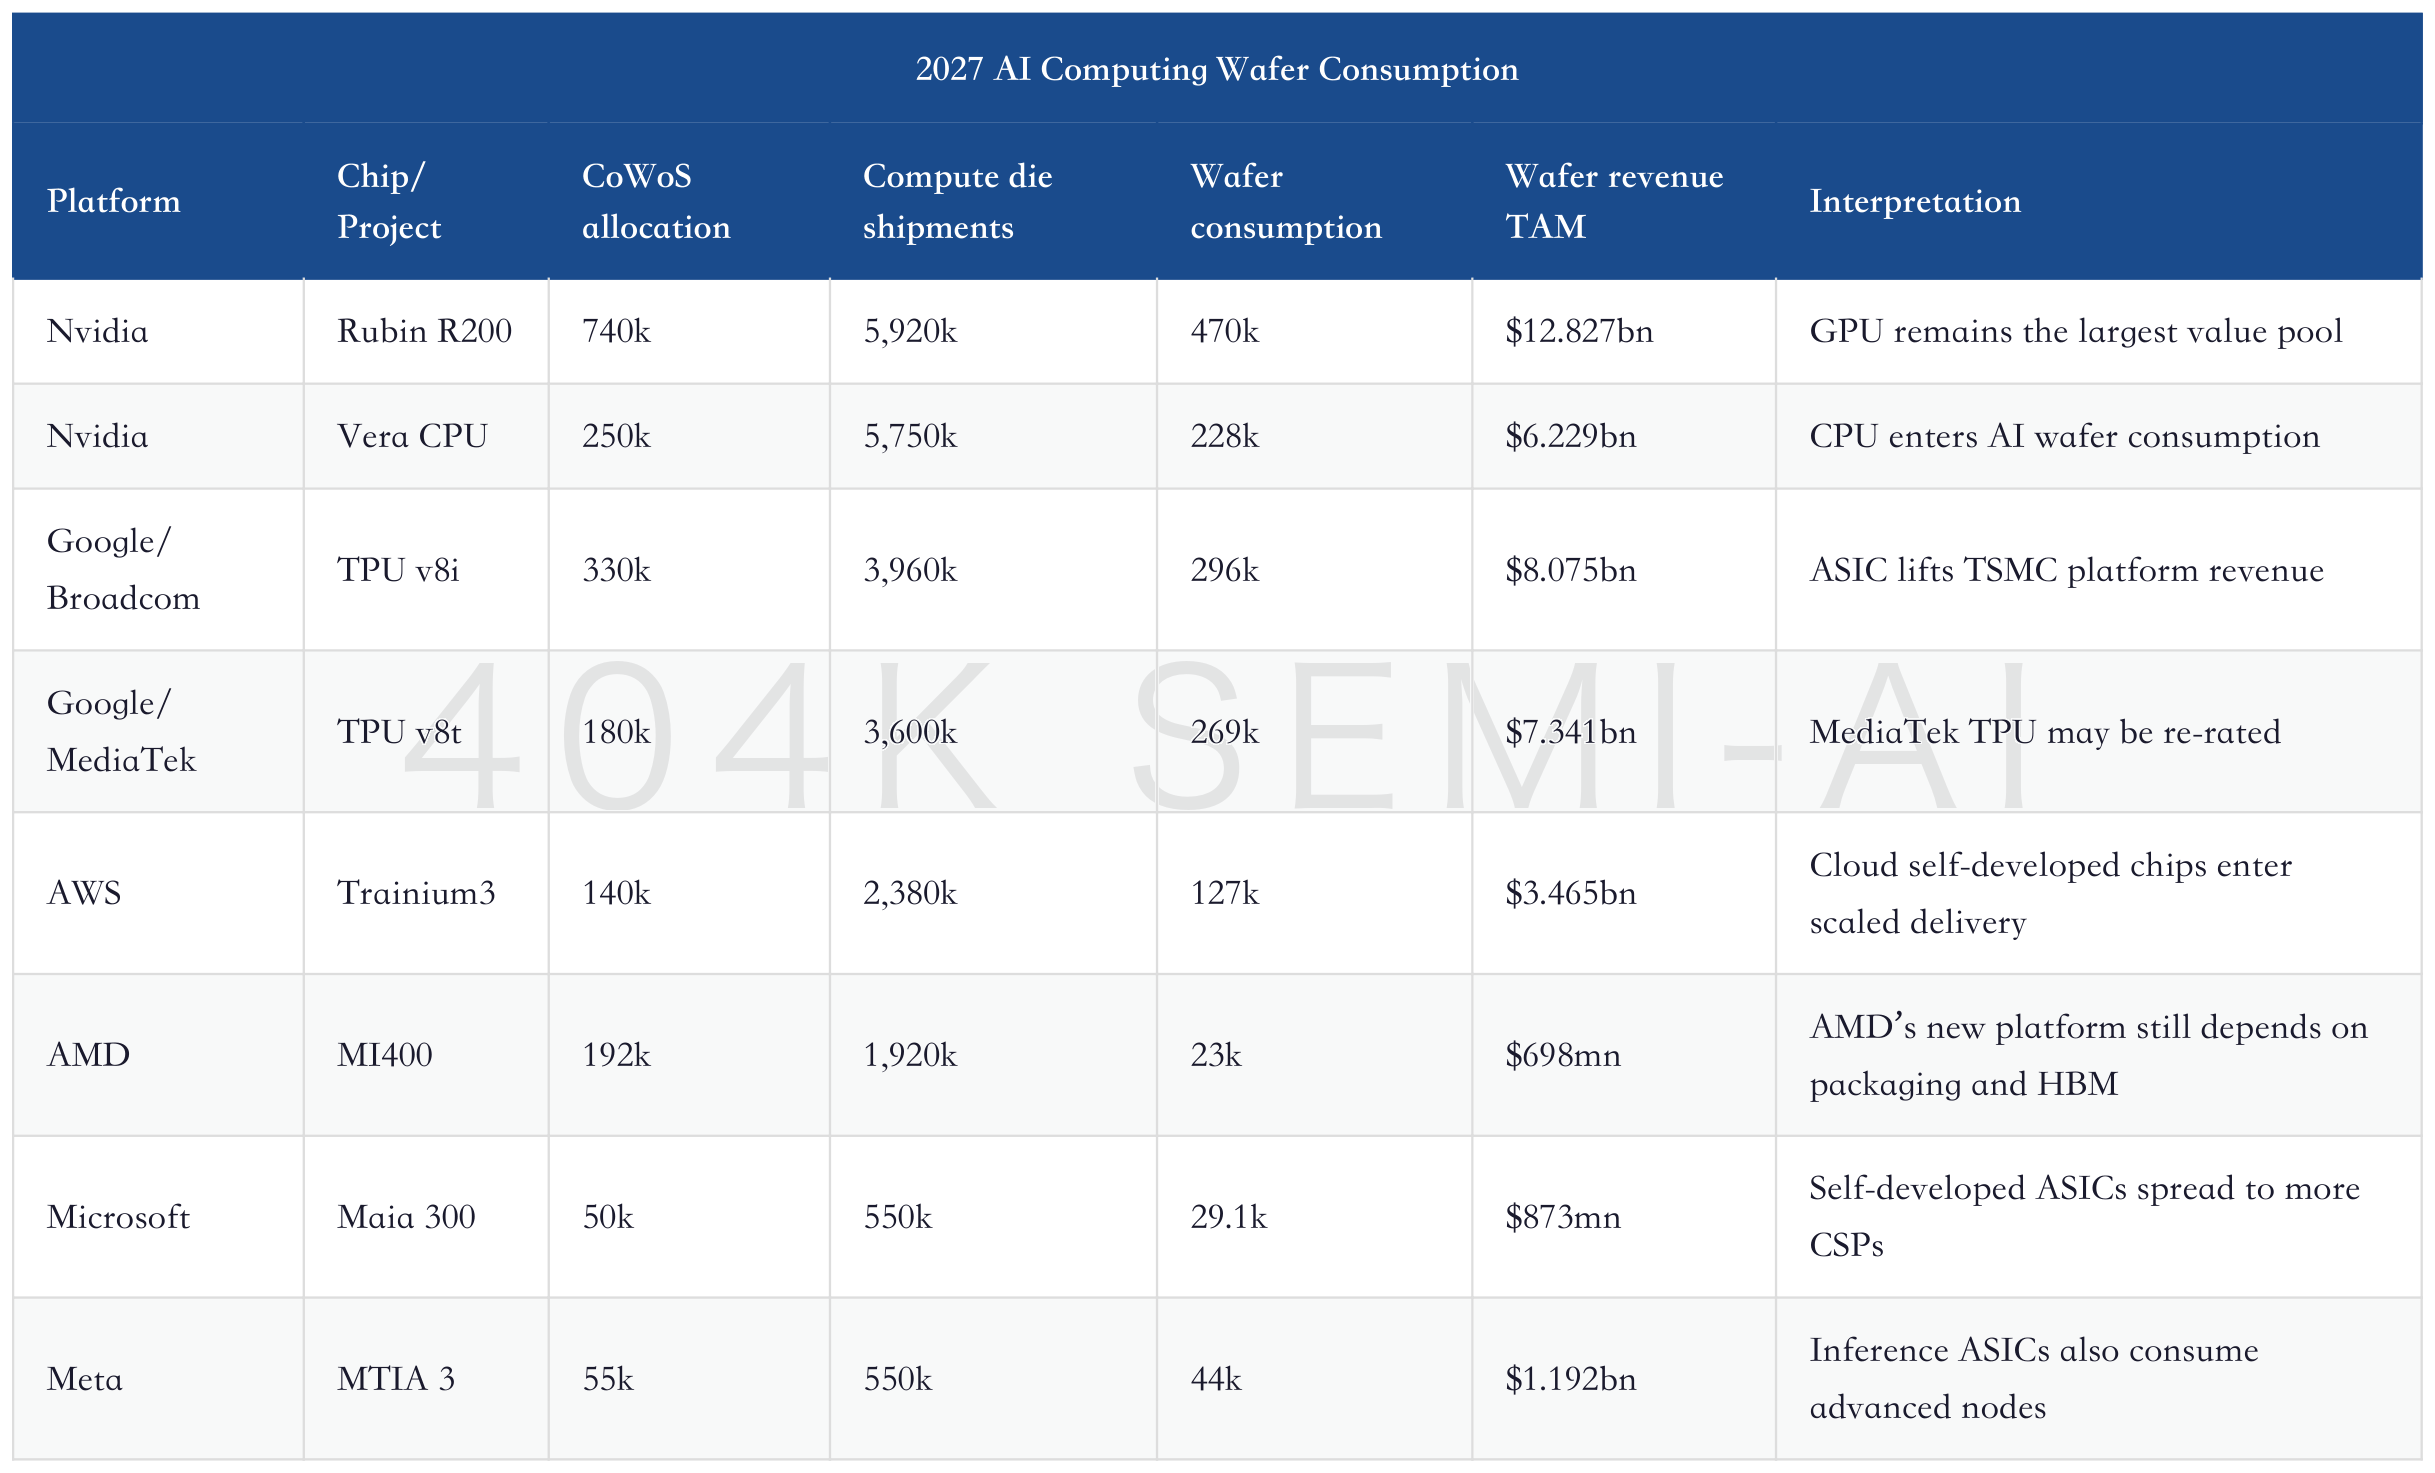
This table leads to three conclusions.
First, Nvidia remains the largest variable. GPUs have not lost. Rubin R200 and Vera CPU together still consume the largest share of advanced-node and packaging resources. TSMC’s AI estimate upgrades cannot be separated from Nvidia.
Second, ASIC scale is already too large to be treated as “scraps.” Google TPU v8i/v8t, AWS Trainium3, Microsoft Maia, and Meta MTIA together are enough to affect the revenue slope of CoWoS, HBM, testing, MediaTek, Alchip, and GUC.
Third, TSMC is the largest common intersection in this non-zero-sum competition. GPUs and ASICs compete in customers and ecosystems, but they queue together on the manufacturing side. As long as the queue exists, TSMC does not need to bet on who wins or loses.
Broadcom’s ASIC logic has already been partially validated: cloud vendors are not developing chips in-house to eliminate all external supply chains, but to regain more system control. For TSMC, this instead creates more customers, more complex projects, and longer queues.
ASIC expansion is most easily misread as a one-way risk to Nvidia. A better understanding is that cloud vendors use ASICs to improve the cost curve for specific workloads, but they have not brought manufacturing, packaging, HBM, or testing capabilities back in-house. The larger Google TPU, AWS Trainium, Microsoft Maia, and Meta MTIA become, the more they push the external supply chain to higher complexity. TSMC captures the manufacturing intersection, HBM vendors capture the memory intersection, and test equipment captures the complexity intersection. The parts truly squeezed are those without differentiation and dependent on a single customer or a single cycle.
Design-service and ASIC companies sit in the second layer of optionality. For assets such as MediaTek, Alchip, and GUC, the core question is not whether they have an “AI concept,” but whether they can win real cloud-vendor projects and deliver engineering outcomes across advanced nodes, packaging constraints, validation cycles, and customer-specific requirements. Once an ASIC project enters mass production, revenue elasticity can be significant. But project delays, customer transitions, or cost overruns can also defer earnings realization. These companies should be tracked through order milestones, not priced only on industry narratives.
The GPU-ASIC relationship will also affect valuation cadence. GPUs still have the strongest software ecosystem and fastest platform iteration, making them suitable for training and general acceleration. ASICs are better suited to clear workloads, clear customers, and clear system architectures. Over the long run, the two will divide labor rather than simply replace each other. For TSMC, the finer the division of labor, the more projects there are, and the more dispersed customers become, the stronger its platform position. For second-layer assets, the finer the division of labor, the harder stock selection becomes, because every company must prove it is standing on real projects.
VI. HBM Demand Shows One Thing: CoWoS Expansion Will Continue to Squeeze Memory Supply
Morgan Stanley estimates 2027 HBM consumption of up to 50bn Gb, with total demand of 50,609mn Gb. NVIDIA Rubin R200 alone has HBM demand of 1,704,960k GB; Google TPU v8i, 1,140,480k GB; AMD MI400, 829,440k GB; Google TPU v8t, 777,600k GB; NVIDIA Rubin Ultra, 399,360k GB; and AWS Trainium3, 342,720k GB.
This figure needs to be viewed in the context of the memory cycle. More AI accelerators mean more HBM; more HBM means more DRAM capacity being squeezed; tighter DRAM means servers, PCs, smartphones, specialty memory, and modules will all feel cost pressure. Morgan Stanley’s opening reference to chip inflation and memory shortage is not just a casual macro backdrop, but evidence that AI semiconductor expansion is transmitting into the cost curve of the entire technology hardware stack.
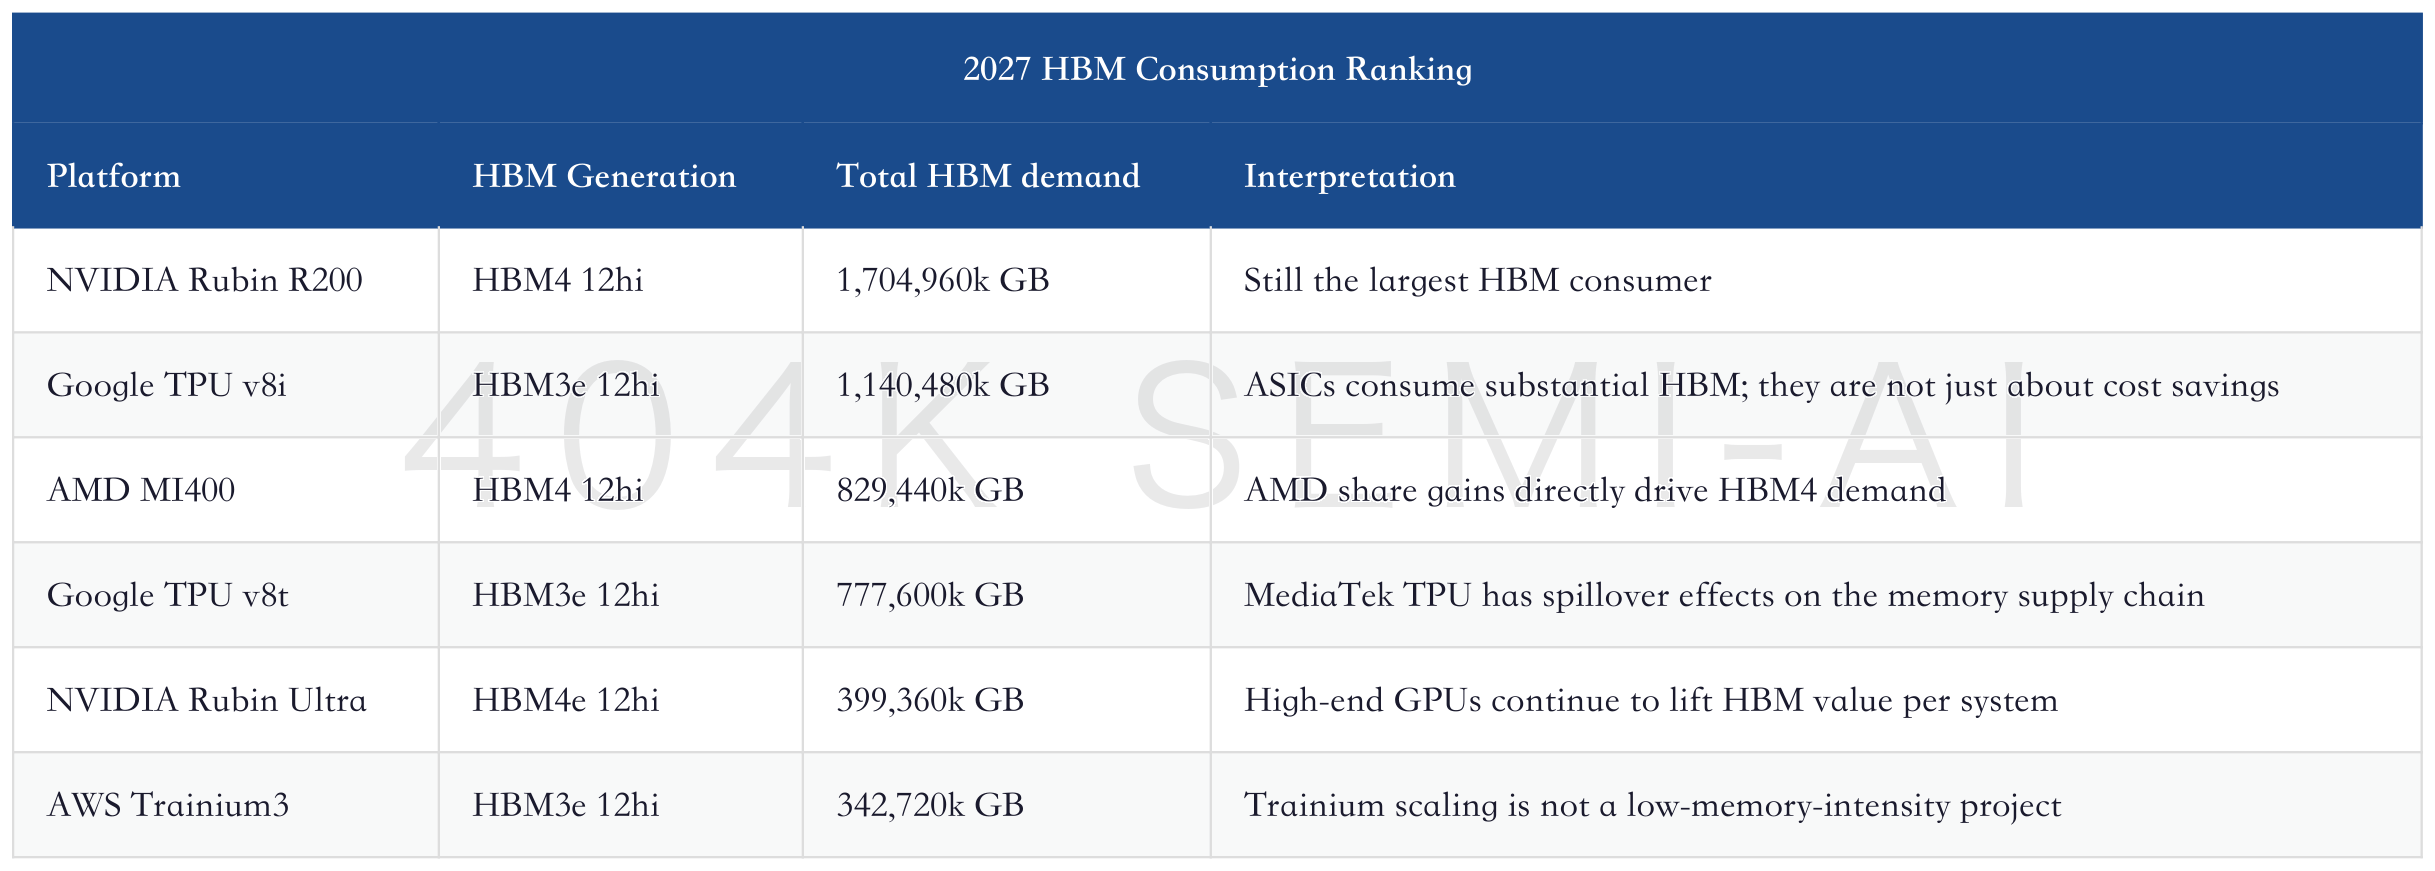
HBM also has reverse significance for TSMC. HBM is not TSMC’s own DRAM product, but it determines the delivery cadence of CoWoS. If CoWoS capacity is available but HBM is insufficient, AI accelerators cannot be delivered; if HBM capacity is available but CoWoS is insufficient, memory makers’ utilization will be constrained. Together, they determine actual GPU and ASIC shipments.
This is also why TSMC, SK hynix, Samsung, Micron, ASE, King Yuan Electronics, test equipment, and packaging materials cannot be viewed separately. An AI chip is not a single foundry order; it is a set of synchronized capacities. The slowest link in that synchronization determines the pace of revenue recognition.
VII. Optical Interconnect and CPO: TSMC’s Long-Term Option Value Lies Not in Modules, but in an Optoelectronic Integration Platform
This update puts Optical in the title, and later discusses CPO, photonics automation, probe cards, handlers, and sockets together. That structure matters. Optical interconnect is not a standalone optical-module cycle; it is entering back-end semiconductor processes and testing flows.
As AI clusters move from 800G to 1.6T and 3.2T, the constraints go far beyond “whether modules are sufficient.” Bandwidth, power consumption, distance, maintainability, yield, coupling precision, test time, and system delivery all become constraints. Traditional pluggable modules will still scale in volume, but if routes such as CPO/NPO/COUPE scale, value will shift toward manufacturing platforms, optical-engine assembly, FAU coupling, test automation, and substrates/interposers.
AI Network Interconnect Hardware Part I: The Value Migration Behind 1.6T/3.2T, and Who Benefits Most Across Switching, Copper Interconnect, Optical Interconnect, and the Physical Layer
AI Optical Module Demand Revised Up Again: How Morgan Stanley’s May Report Pushed 1.6T, InP, and CPO Bottlenecks Out to 2028
The first two pieces already moved the optical interconnect discussion from module demand to physical-layer bottlenecks. Today’s update pushes optical interconnect further toward TSMC and back-end testing. The real long-term question is whether optics will become platform-bound to TSMC in the same way as HBM. If COUPE or CPO-type routes mature, TSMC’s role would not only be foundry manufacturing for GPUs/ASICs; it could also become the manufacturing platform for optoelectronic integration.
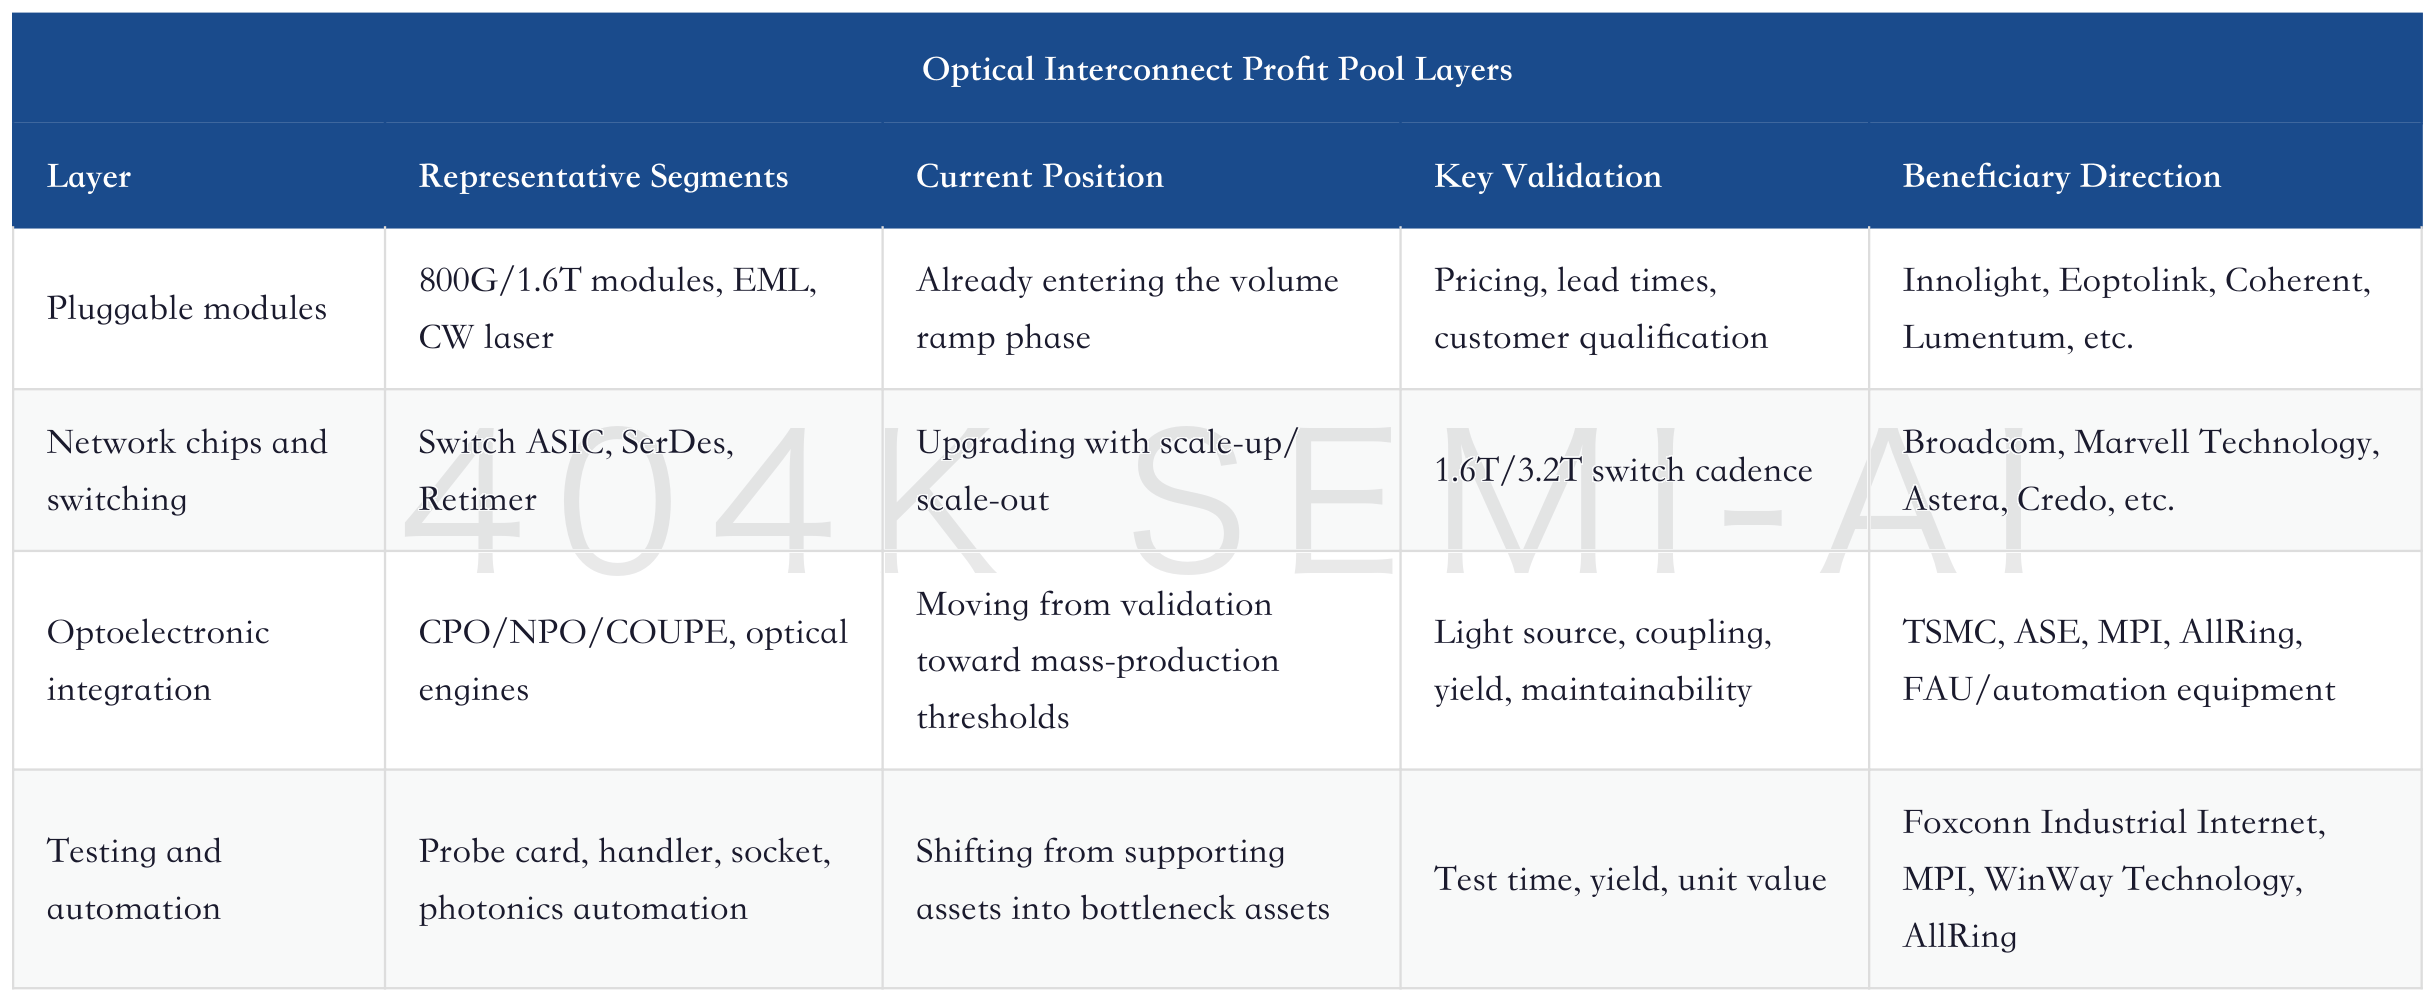
Optical interconnect also carries an easily overlooked risk. CPO is not a linear replacement for pluggables. Its mass-production cadence will be constrained by maintainability, thermals, testing, the supply chain, and customers’ architectural conservatism. Public markets can easily portray CPO as a straight-line story; real investment work needs to assess whether customers are willing, during 2027-2029, to embed optical components more deeply into the packaging platform.
The core tension in optical interconnect is that as bandwidth continues to rise, the distance, power consumption, and signal integrity of electrical connections become increasingly expensive. Pluggable modules can still support the market for a long time, but data movement among switch chips, accelerators, memory, and racks will keep approaching physical limits. As long as AI clusters continue to expand, optics will not stop at the level of “more modules sold”; it will spread into light sources, optical engines, coupling, testing, and packaging automation.
TSMC’s option value in optical interconnect comes from the manufacturing platform, not from a traditional module brand. If CPO or COUPE matures, the difficulty is not only placing optical devices closer to chips, but also managing thermals, yield, optoelectronic coupling, long-term reliability, and mass-production testing. What TSMC excels at is turning complex processes into repeatable flows. If optical components enter advanced packaging, TSMC has an opportunity to extend its CoWoS-accumulated customer relationships and process control into the connectivity layer.
From an investment perspective, optical interconnect should be split into time horizons. In the near term, watch pluggable modules, switch chips, Retimers, and DSPs; in the medium term, watch 1.6T/3.2T mass production, optical engines, and FAU automation; only in the longer term should investors assess whether CPO/NPO/COUPE becomes part of platform-based manufacturing. Discounting all value into CPO at once would overstate the near term; completely ignoring optoelectronic integration would understate the long-term option value for TSMC and test equipment.
