
TSMC CoWoS Deep Dive: 200kwpm Packaging, US$75bn CapEx, and Redistribution Across CPU, GPU, ASIC, and Optical Interconnect
目录
TL;DR
1. Core View of This Report: AI Semis Are Moving From a Demand Story to Bottleneck Pricing
II. TSMC: Pricing Power in Both Advanced Process and Packaging
III. CoWoS: The Real Congestion Point in 2027
IV. CPU Comeback: Agentic AI Makes the “Scheduling Chip” Valuable Again
V. ASIC Proliferation: Cloud Vendors’ In-House Chips Are Not the Opposite of NVIDIA
VI. HBM, ABF, and Testing: The Physical Ledger of AI Systems Thickens
VII. Optical Interconnects: CPO Debate Cannot Stop the Bandwidth Bill
VIII. China AI Compute: Using Systems Engineering to Offset the Single-Chip Gap
IX. Investment Ranking: Buy Bottlenecks, Buy Validation, Buy Fewer Long-Dated Slogans
X. Scenario Framework: Three AI Semiconductor Worldviews
XI. Follow-Up Tracking: Four Tables Will Decide How Far This Trade Can Go
XII. TSMC Profile: What It Sells Is AI Capacity With Delivery Certainty
XIII. CapEx Return Check: $75 Billion Is Not a Capacity-Expansion Slogan
XIV. Advanced Packaging Competition: CoWoS, SoIC, EMIB, and Optical Interconnect Are Not Isolated Technologies
XV. Sell-Side Disagreement: Bulls Buy the Bottleneck; Cautious Investors Watch Returns
XVI. Portfolio Implications: Look for Second-Order Elasticity Along TSMC’s Capacity Map
XVII. Three Common Misreadings: Demand, Substitution, and Expansion
XVIII. Conclusion: What Morgan Stanley Sees Is a Reallocation of the AI Compute Bill
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
The next validation point for the AI semiconductor trade lies in TSMC’s advanced-node and CoWoS capacity. Morgan Stanley’s answer is direct: cloud vendors are still raising CapEx, while the value chain is broadening from a single GPU focus to CPUs, ASICs, HBM, optical interconnect, and China AI compute. This will determine earnings and valuation elasticity in 2026-2027.
TL;DR
TSMC remains the bottleneck asset for AI compute. Morgan Stanley positions TSMC as the “only game in town,” citing simultaneous tightness in advanced nodes, EUV supply, and advanced packaging capacity. CapEx, CoWoS, and advanced-node pricing form the core anchors of this trade. Whether gross margin can stay elevated is the key test of TSMC’s transition from manufacturing expansion to bottleneck pricing.
GPU demand remains, but the trade is broadening. Morgan Stanley expects 2027 CapEx for the top 14 listed global cloud vendors to approach US$1.3tn, with the AI semiconductor TAM potentially rising from US$485bn in 2026E to US$753bn in 2030E. Nvidia still consumes the most CoWoS and HBM, but ASIC and CPU projects from AMD, Broadcom, AWS, Google, Microsoft, and Meta will allocate incremental value across wafers, packaging, HBM, testing, ABF, and optical interconnect.
CPUs are becoming part of the AI system bill again. Agentic AI pushes inference from “answering questions” to “executing tasks,” increasing CPU:GPU intensity in clusters. Morgan Stanley raises its base-case TAM for orchestration CPUs to US$79bn, with a bull case of US$238bn, and highlights the value of Vera CPU performance, memory connectivity, and cluster scheduling. This theme will influence valuation anchors for Arm, Nvidia, AMD, custom CPUs, testing, and advanced packaging.
ASICs and HBM determine the pace of second-stage diffusion. Cloud vendors will not abandon in-house chips just because Nvidia GPUs are powerful. Google TPU, AWS Trainium, Microsoft Maia, and Meta MTIA are all competing for TSMC advanced nodes, CoWoS, HBM, and ABF resources. Morgan Stanley estimates 2027 AI computing wafer consumption at more than US$46bn and HBM demand at about 50,609 mn Gb. The supply-chain bottleneck is not in a single chip, but in simultaneous scheduling constraints across multiple stages.
Optical interconnect becomes mandatory once clusters scale. The report groups CPO, larger package sizes, test equipment, and high-pin-count sockets into the same supply-constraint framework, indicating that AI compute competition has moved from chip level to rack and cluster level. Even if the CPO rollout pace remains uneven, optical modules, silicon photonics, FAU, packaging and testing, and high-end connectors should continue to rise with rack power, bandwidth, and latency requirements.
China AI compute is following an efficiency and domestic-supply path. Morgan Stanley expects China’s AI GPU TAM to grow to US$91bn by 2030E and China’s CPU TAM to reach US$42bn by 2030E, and lists Cambricon, Moore Threads, and Iluvatar CoreX as domestic AI accelerator names to watch. Key variables are inference TCO, cost per token, order execution, domestic wafer and packaging/testing capacity, and cluster-architecture compensation under export-control constraints.
The biggest risk is CapEx return validation. The trade will not stop at “AI is still strong.” Capital will ask whether US$75bn of CapEx can translate into profit, cash flow, and pricing power. Four numbers need to be tracked: TSMC’s CoWoS monthly capacity ramp, 2nm/N3 tool installation and utilization, cloud-vendor CapEx-to-EBITDA, and whether advanced packaging and HBM delivery delays are dragging on customer shipments. If these numbers weaken, AI semis will shift first from valuation expansion to earnings delivery.
1. Core View of This Report: AI Semis Are Moving From a Demand Story to Bottleneck Pricing
Morgan Stanley’s industry call is strong. The title uses “Strong AI Semi Outlook,” and the industry view remains Attractive. The underlying logic is not complicated: cloud vendors continue to spend, AI servers continue to consume chips, and TSMC, advanced packaging, HBM, testing, and China domestic compute still have expansion curves ahead.
More importantly, Morgan Stanley breaks apart the trading framework for AI semiconductors in this report. In the prior phase, the market mainly bought GPU shipments and the Nvidia supply chain. In the new phase, investors need to examine how money is redistributed within AI systems: who can raise wafer prices, who can secure CoWoS, how much budget ASICs and CPUs will take, whether HBM and ABF face physical shortages, when optical interconnect moves from expectation to orders, and whether China domestic compute can use system engineering to offset single-chip gaps.
Morgan Stanley’s stock-selection table also reflects this shift. It divides overweight areas into AI, memory, China AI/semiconductor equipment, test equipment, and mature nodes. The AI group includes MediaTek, TSMC, SMIC, Aspeed, Alchip, King Yuan Electronics, ASE Technology Holding, Global Unichip, ASMPT, AllRing, and GUC; the memory group includes Macronix, AP Memory, Nanya Technology, Winbond, and GigaDevice; China AI and equipment includes Iluvatar CoreX, Cambricon, NAURA Technology, AMEC, and USI.
This shows that Morgan Stanley’s core view is to “buy the full bottleneck stack of AI compute.” If cloud-vendor CapEx continues to be revised upward, profits will first settle in the scarcest areas: advanced nodes, advanced packaging, HBM, testing, materials, and the few companies able to enter China’s domestic compute closed loop. If CapEx return pressure rises, the first segments screened out will be those that only discuss long-term TAM without near-term orders or delivery capability.
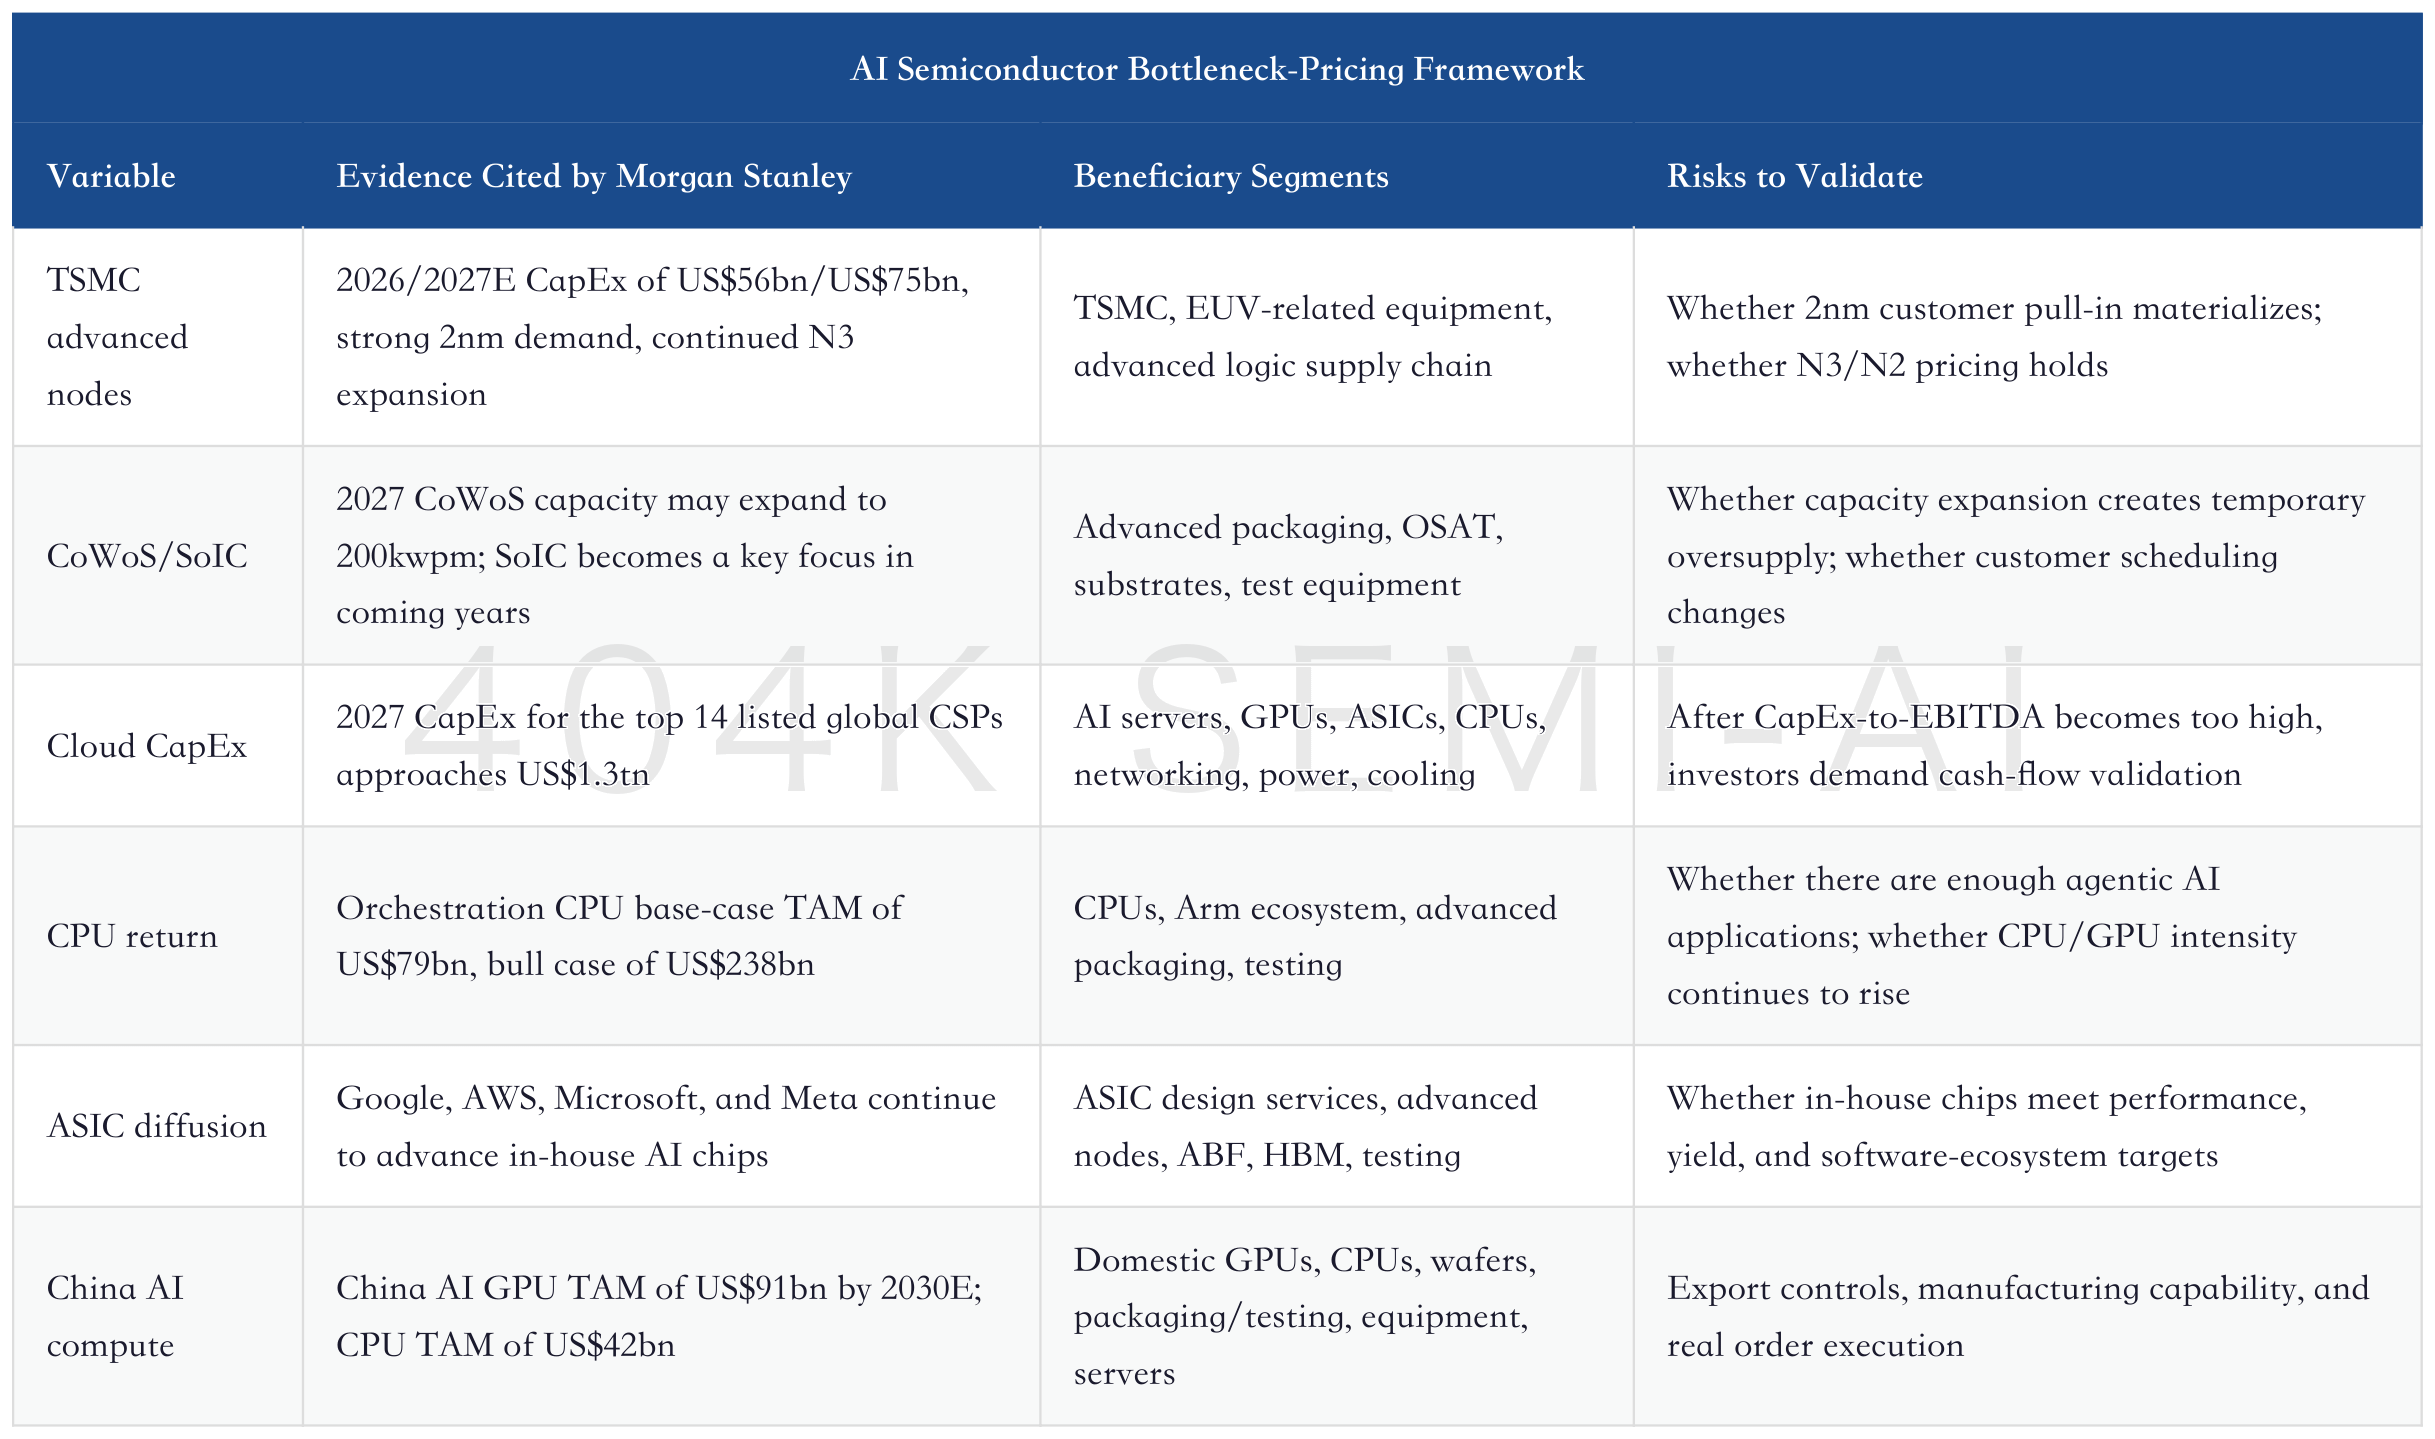
This table summarizes Morgan Stanley’s real message: AI demand is not over, but the trade has shifted from “whether demand exists” to “where the bottlenecks are, whether prices can rise, and how CapEx returns should be calculated.” TSMC sits at the very upstream end, so its valuation should not be based only on next-quarter revenue, but on how much bottleneck rent the full system can retain after 2027.
II. TSMC: Pricing Power in Both Advanced Process and Packaging
TSMC is the axis of this report. Morgan Stanley forecasts TSMC’s 2026/2027E CapEx at US$56 billion and US$75 billion, a systematic step-up around N2/N3, Arizona capacity, CoWoS, and SoIC.
TSMC’s pricing power comes from three places. First, it continues to lead in advanced process nodes, while tight EUV supply leaves customers with few alternatives. Second, 2nm demand is strong; the report notes that N2 capacity could achieve a 70% CAGR over 2026-2028E. Third, advanced packaging is no longer a back-end service, but the entry ticket for whether AI chips can ship.
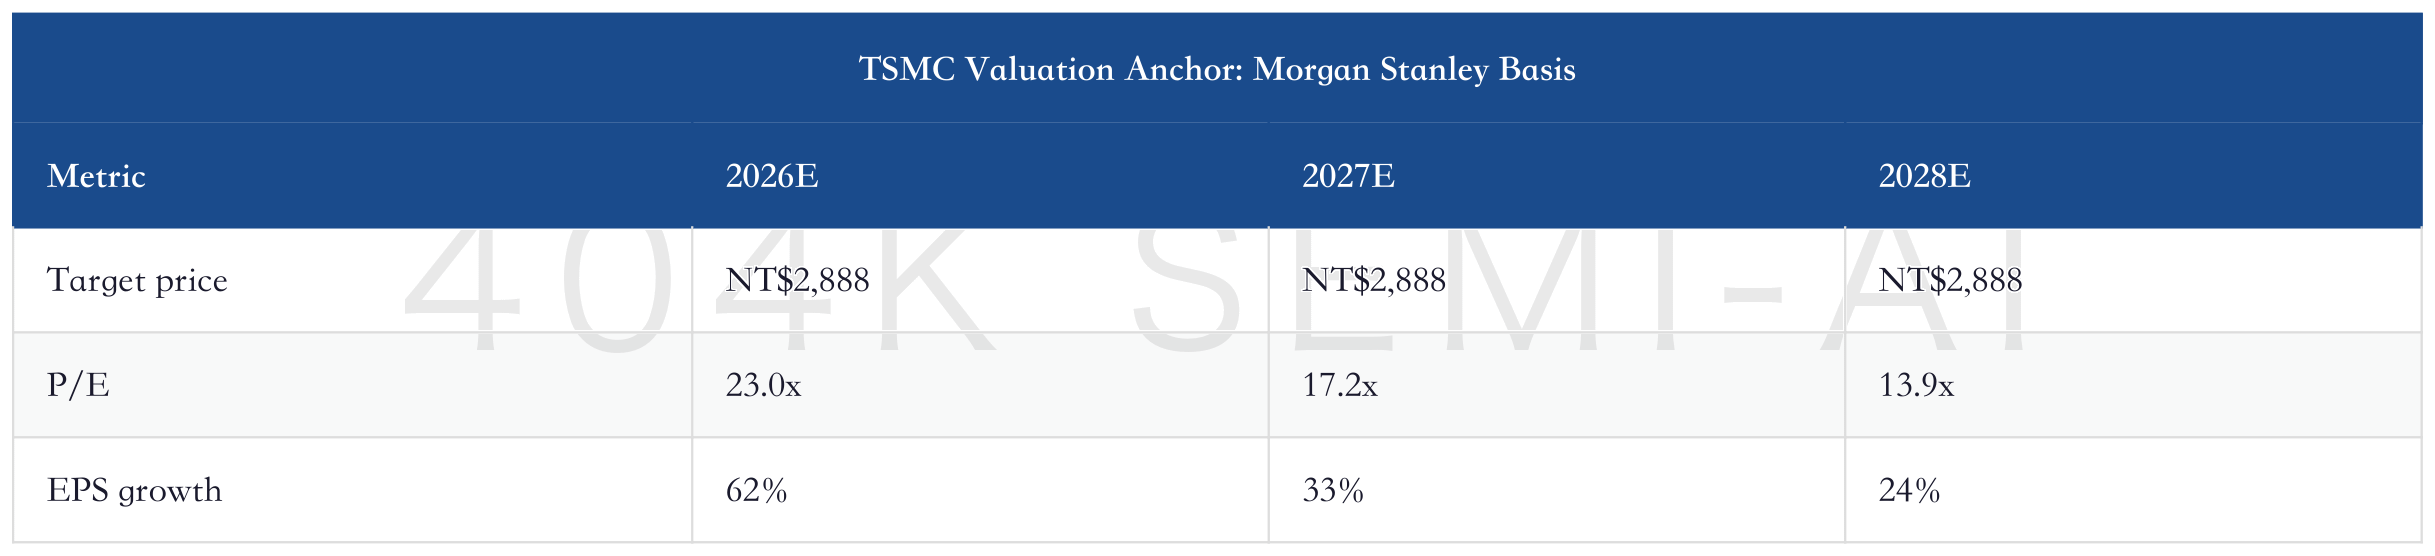
Morgan Stanley’s valuation anchor for TSMC is strong. The target price, P/E, and EPS growth are clearer in table form. The key point is that the market views TSMC as a high-growth bottleneck asset, provided it can deliver advanced-node expansion, packaging expansion, and gross-margin defense at the same time.
Full transcript of TSMC’s 2026 shareholder meeting: AI demand, capital expenditure, advanced process nodes, and global capacity layout
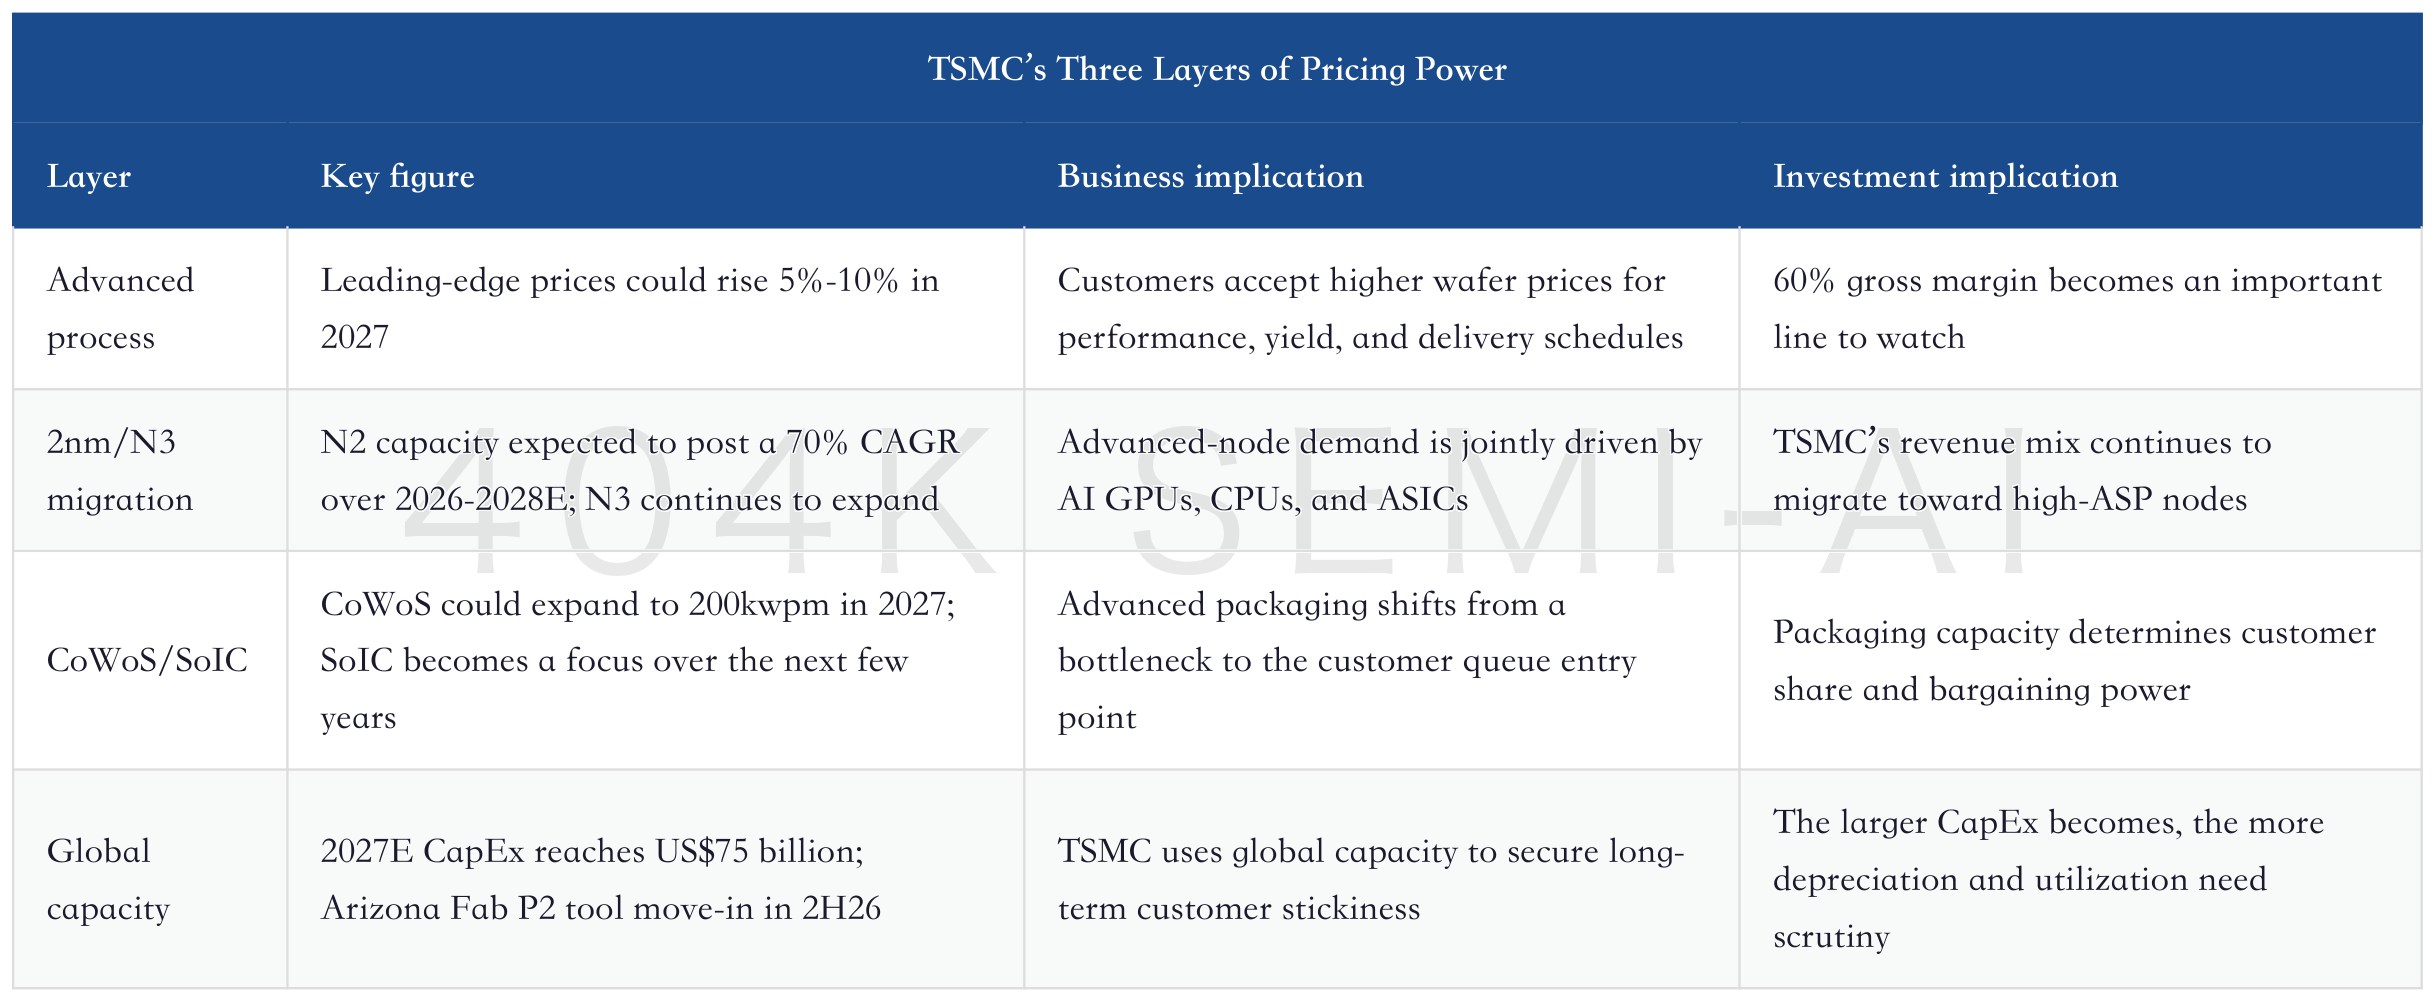
TSMC’s risks are also here. As CapEx jumps from US$56 billion to US$75 billion, depreciation pressure will not disappear. Morgan Stanley believes 60% gross margin should become the floor, implicitly assuming that advanced-node price increases and high utilization can offset depreciation. If cloud vendors begin cutting AI capital expenditure after 2027, or if customers spread orders across different packaging paths, TSMC’s valuation could shift from a “bottleneck premium” back to “high-CapEx manufacturing.”
In the near term, however, Morgan Stanley’s evidence is positive. Logic foundry utilization is expected to reach 80% in 2H26, 2nm demand is strong, N5 declines in 2027 while N3 continues to rise, and AI semiconductor revenue could exceed 30% of total revenue in 2026E, with a chance to approach 60% by 2029E. TSMC is moving from an “advanced foundry” to an “AI system capacity allocation center.”
III. CoWoS: The Real Congestion Point in 2027
CoWoS is the most important trading variable in this report. Morgan Stanley expects sustained AI demand could push TSMC to expand CoWoS capacity to 200kwpm in 2027. That number implies multiple customers competing for the same scarce resource in 2027.
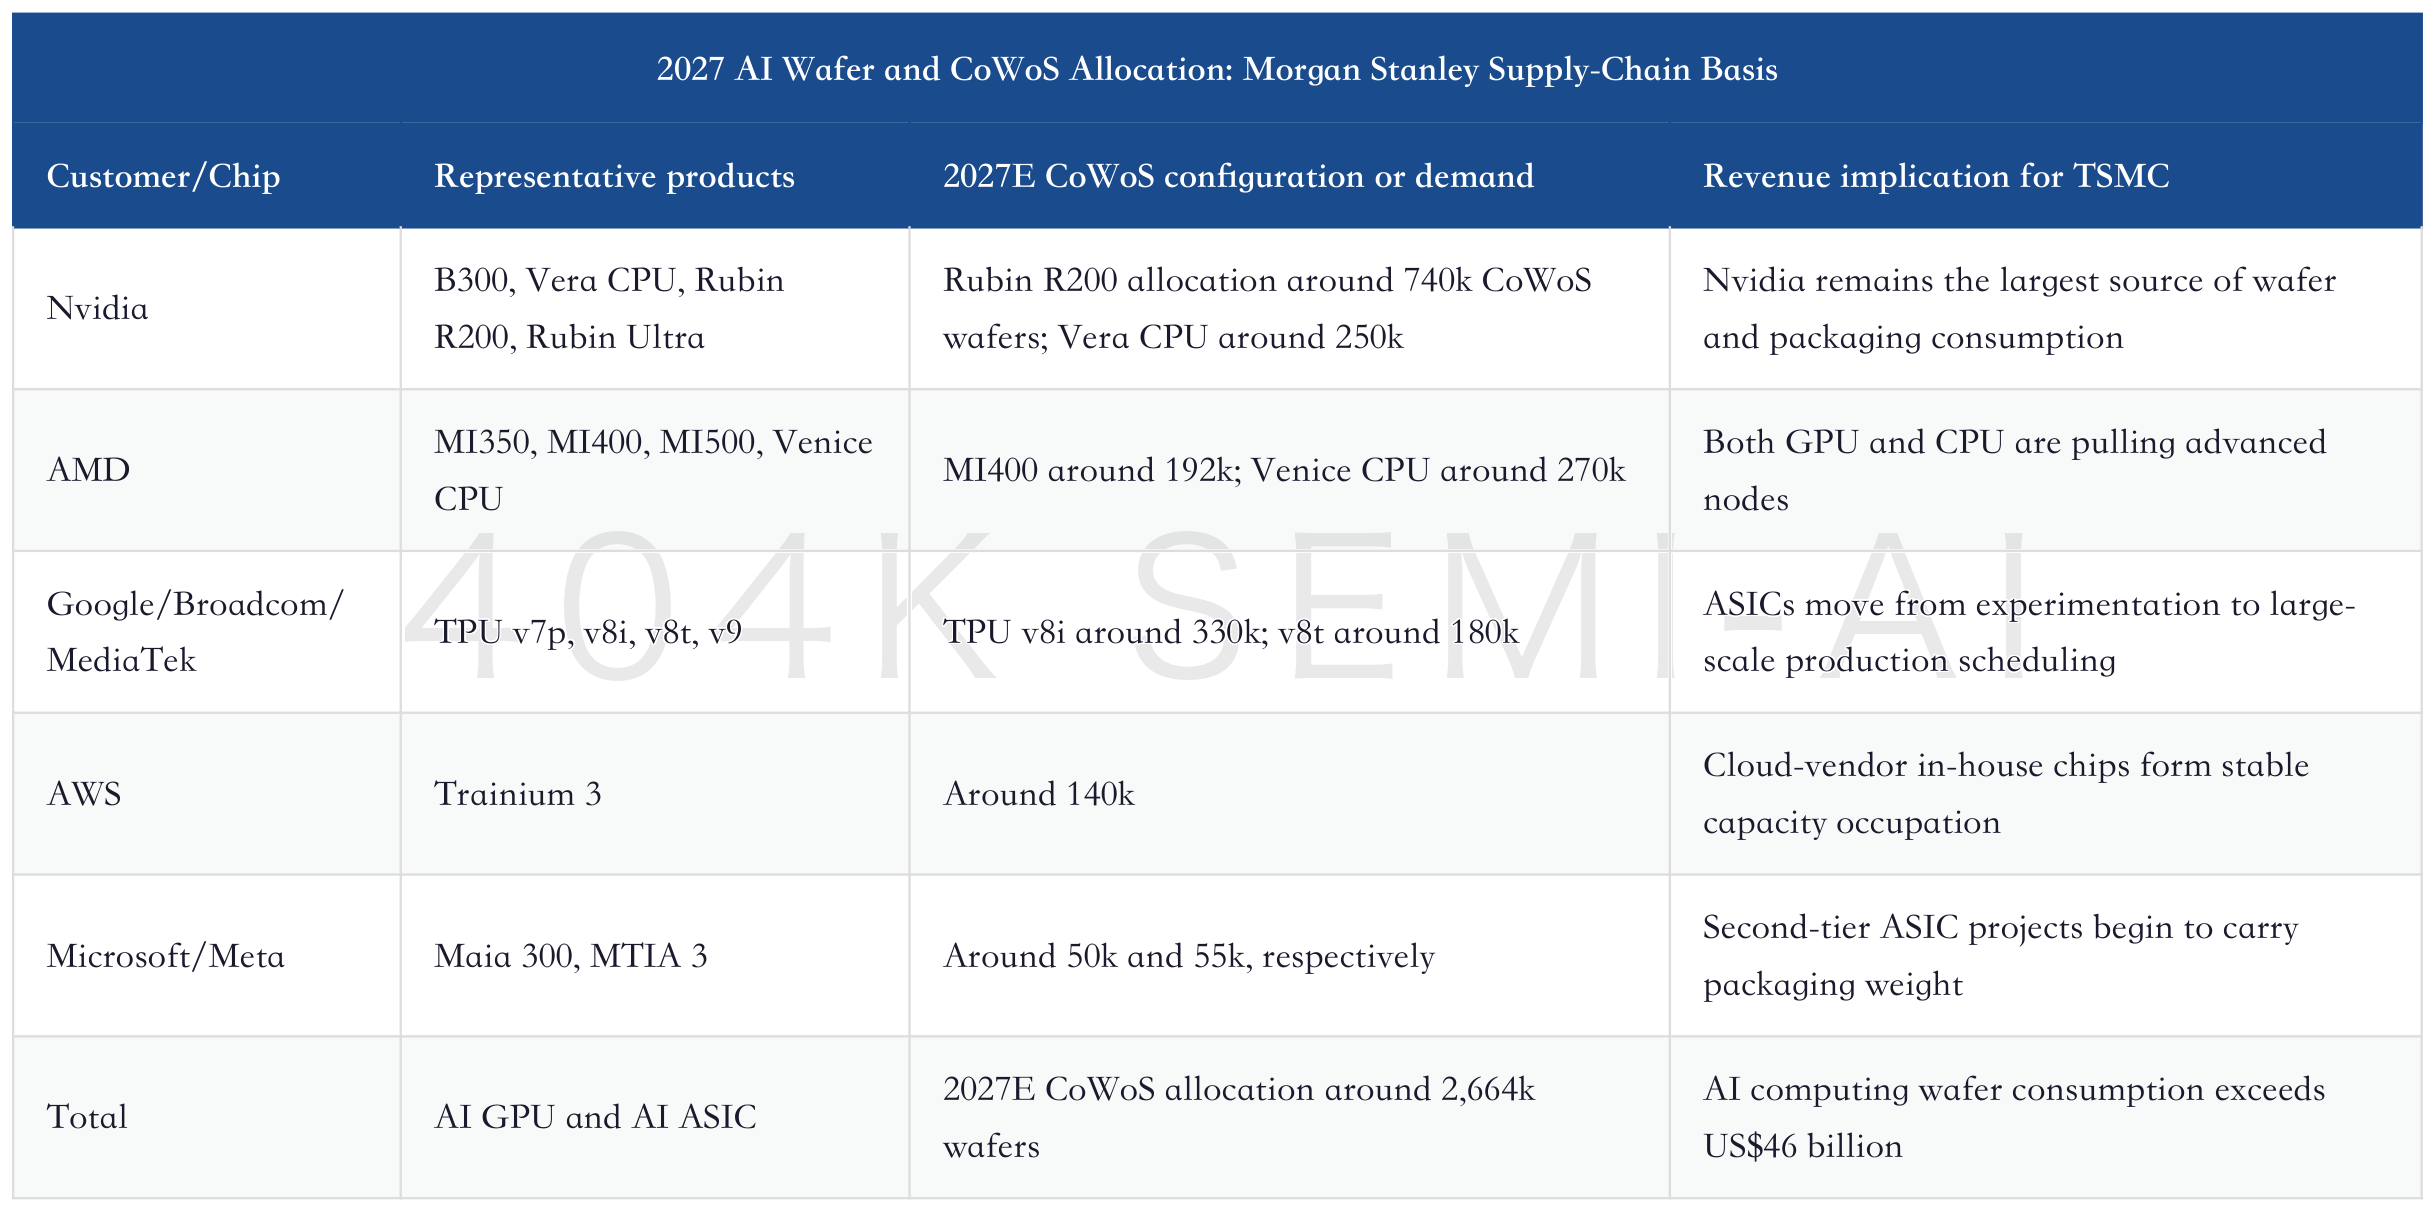
The report infers CoWoS demand from public power deployment data. Nvidia Vera Rubin NVL144, AMD Helios, Broadcom TPU, and AWS Trainium3 UltraServers all require advanced packaging resources. Based on lifecycle CoWoS usage, Nvidia requires around 409k wafers, AMD around 166k wafers, Broadcom around 260k wafers, and AWS around 118k wafers. Converted into 2027 annual CoWoS demand, the figures are around 136k, 55k, 52k, and 15k wafers, respectively.
These figures dismantle a common market misconception. The CoWoS supply-demand table is jointly determined by Nvidia, AMD, Google/Broadcom, AWS, and other CSPs. GPUs are the strongest driver, but ASICs are starting to create real capacity occupation. CPUs do not necessarily use HBM, but they do consume advanced process and some packaging capacity. HBM supply will also feed back into and constrain the shipment cadence of GPUs and ASICs.
CoWoS also has a technology-level competition issue. Morgan Stanley compares TSMC’s CoWoS with Intel’s EMIB: TSMC’s CoWoS-S can support larger silicon interposers and multi-chip packaging, while Intel’s EMIB can theoretically also support a larger reticle count, provided supply-chain execution is strong enough. The investment implication of this comparison is to watch who can deliver at customer mass-production nodes.
If TSMC ramps CoWoS toward 200kwpm, the benefits will not remain only at TSMC. Substrates, wafer testing, packaging equipment, sockets, probe cards, materials, and automation equipment will all become assets that “move with CoWoS expansion.” Morgan Stanley puts King Yuan Electronics, ASE Technology Holding, FOCI, ASMPT, WinWay Technology, MPI, Gudeng, and AllRing in its focus list because rising AI chip complexity will lengthen test time, increase pin counts, and push up demand for burn-in and high-end components.
IV. CPU Comeback: Agentic AI Makes the “Scheduling Chip” Valuable Again
CPU is the most easily underestimated part of this report. The market is used to equating AI compute with GPUs, but Agentic AI moves the system from “model inference” to “task execution.” Large amounts of orchestration, retrieval, tool calling, environment-state management, and concurrent tasks consume CPU resources. Morgan Stanley raised its base-case TAM for orchestration CPUs to US$79bn, while the bull case reaches US$238bn.
The Crazy CPU: From Supporting Role Back to Center Stage — A 40,000-Word Panorama of the New Compute Bottleneck in the AI Agent Era
This line is critical for TSMC. The CPU comeback does not mean GPUs exit the stage; it means the heterogeneous-computing bill inside AI clusters becomes larger. NVIDIA’s Vera CPU, AMD’s Venice CPU, Google CPUs, and various custom CPUs will increase advanced-node demand and extend TSMC from the GPU supply chain into the CPU orchestration layer. Morgan Stanley emphasizes that Vera CPU performance can reach 1.8x that of the highest-performance x86 CPU. This shows NVIDIA is not satisfied with selling GPUs; it is bringing CPUs into the AI system control plane.
The investment implications of CPUs have three layers. First, Arm licensing and ecosystem value rise, because cloud vendors and accelerator vendors need high-efficiency CPUs. Second, advanced-node demand becomes more distributed, because CPUs, GPUs, and ASICs all compete for N3/N2. Third, testing and packaging revenue becomes more stable, because CPUs, GPUs, and ASICs together increase test hours and complexity.
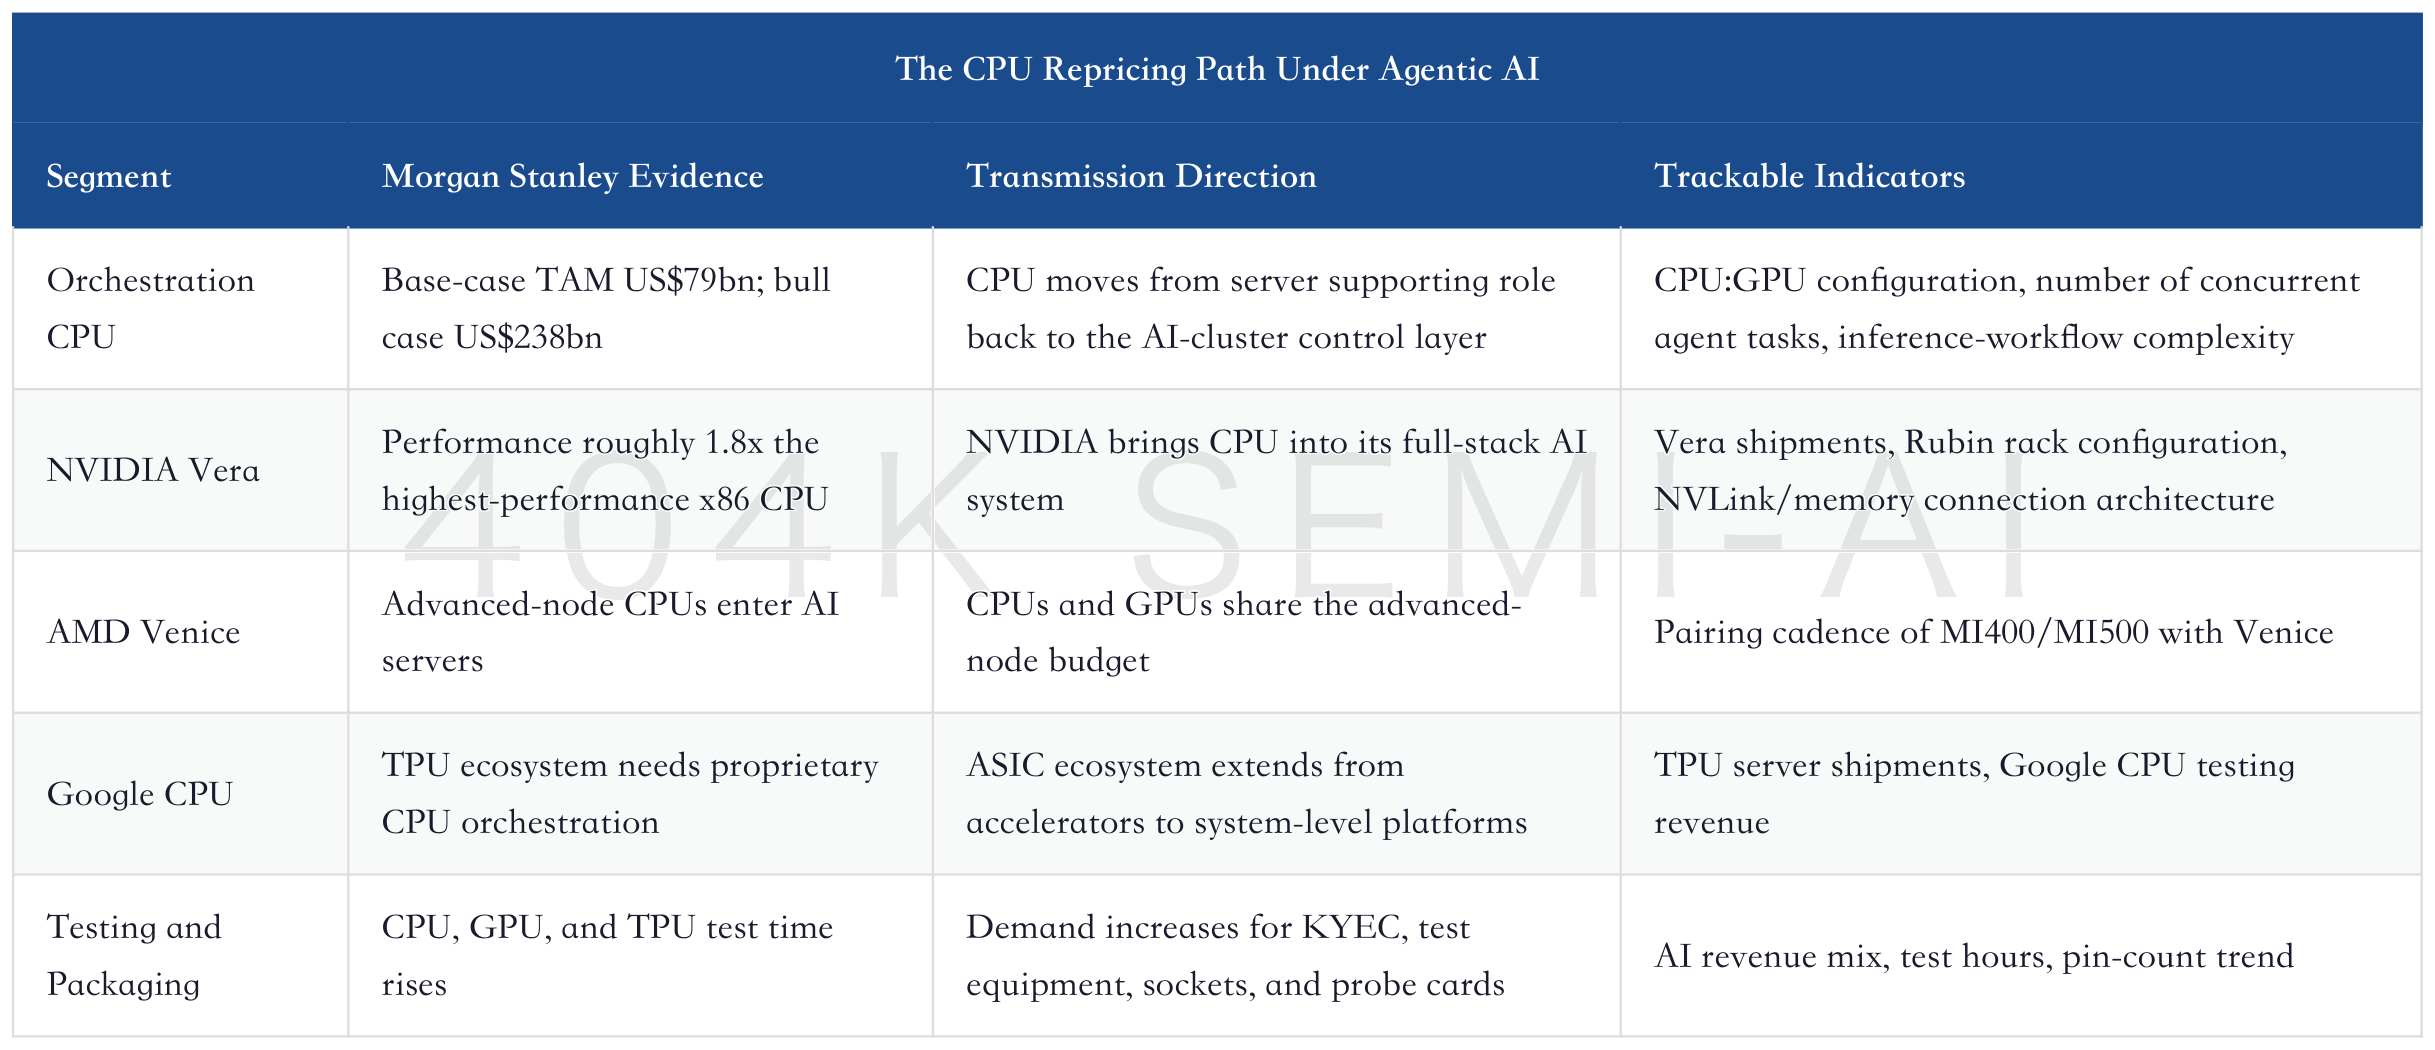
The risk to the CPU line is at the application layer. If Agentic AI remains limited to demos and small-scale workflows, CPU intensity will not rise as in the bull case. Conversely, if enterprises start putting AI agents into customer service, software engineering, data analysis, internal operations, and automation processes, CPUs will shift from “something already inside the server” to “the control cost of the inference economy.” This is why Morgan Stanley separates CPUs out.
V. ASIC Proliferation: Cloud Vendors’ In-House Chips Are Not the Opposite of NVIDIA
The core judgment on ASICs is straightforward: cloud vendors still need in-house chips. The stronger NVIDIA GPUs become, the greater the incentive for cloud vendors to migrate some mature workloads to in-house ASICs, for reasons including cost, supply, energy efficiency, software-stack control, and bargaining power.
Deep Dive Into Broadcom Earnings: AI Custom Chips Enter Delivery-Validation Phase; How Data-Center ASICs and High-Speed Interconnects Should Be Revalued for FY2027
The projects Morgan Stanley lists are no longer concepts. Google TPU v7p, v8i, v8t, and v9, AWS Trainium 3, Microsoft Maia 300, and Meta MTIA 3 all correspond to 2027 CoWoS and advanced-node demand. Google TPU v8i corresponds to roughly 330k CoWoS wafers, TPU v8t to roughly 180k, and AWS Trainium 3 to roughly 140k. Together, they will bring a second growth curve to TSMC, MediaTek, Broadcom, GUC, Alchip, ABF, HBM, and testing.
ASICs have a major impact on the investment framework. GPU trades track NVIDIA production allocation; ASIC trades track CSP project cadence, yield, and software migration. The GPU supply chain is more concentrated, while the ASIC supply chain is more distributed. TSMC’s most comfortable position is this: whether customers buy NVIDIA, AMD, or choose Google TPU, AWS Trainium, Microsoft Maia, or Meta MTIA, as long as advanced nodes and CoWoS remain within the TSMC system, TSMC can collect upstream capacity rent.
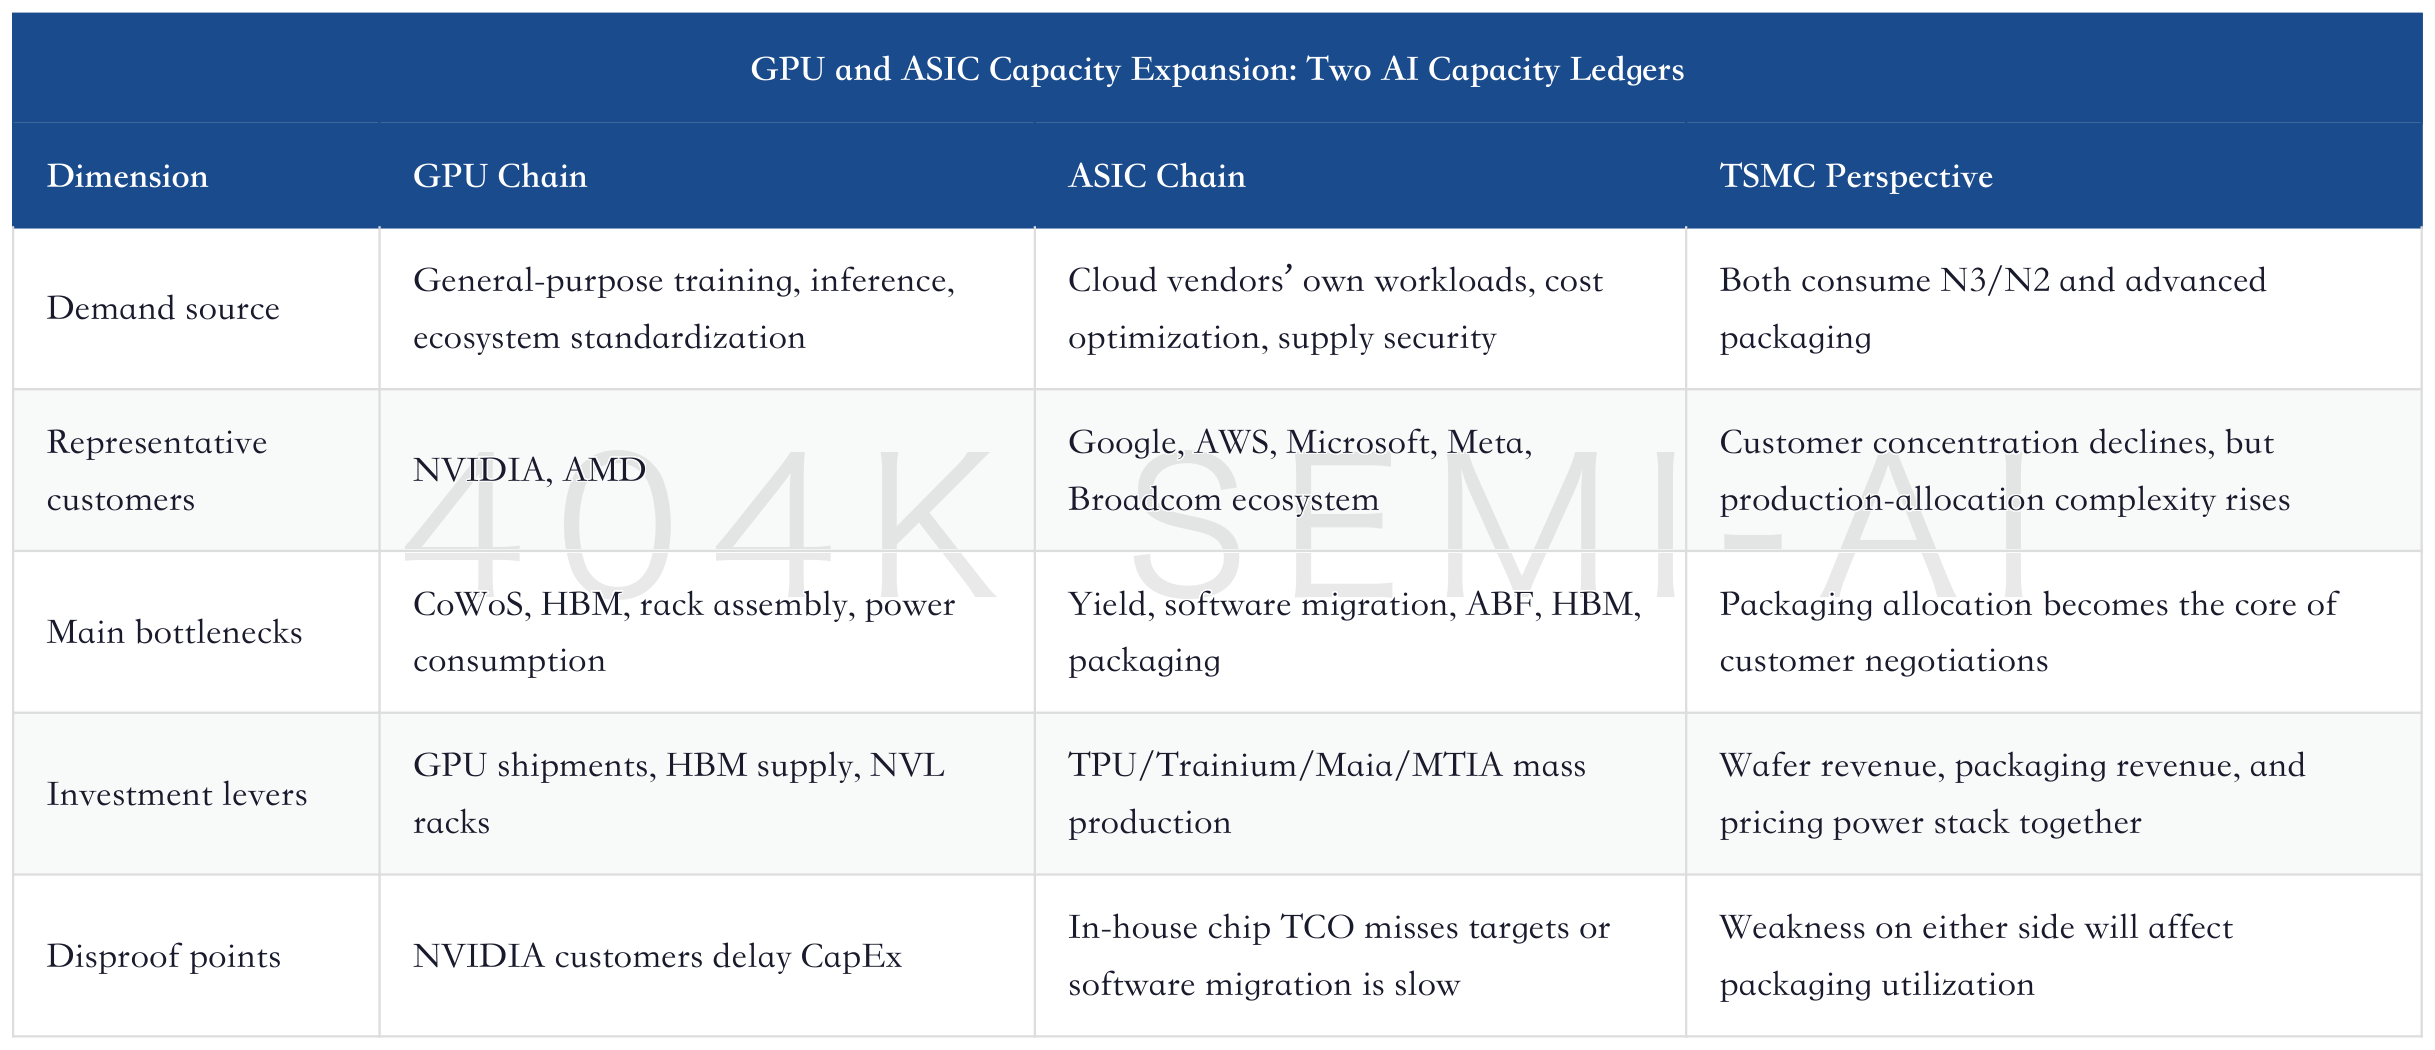
ASIC is not a single-line narrative of “replacing NVIDIA.” A better interpretation is that once AI workloads multiply, cloud vendors will allocate different models, different inference tasks, and different cost targets to different chips. NVIDIA continues to capture high-performance general-purpose demand; in-house ASICs capture scaled and cost-optimized demand; TSMC captures advanced-node and packaging demand on both sides.
VI. HBM, ABF, and Testing: The Physical Ledger of AI Systems Thickens
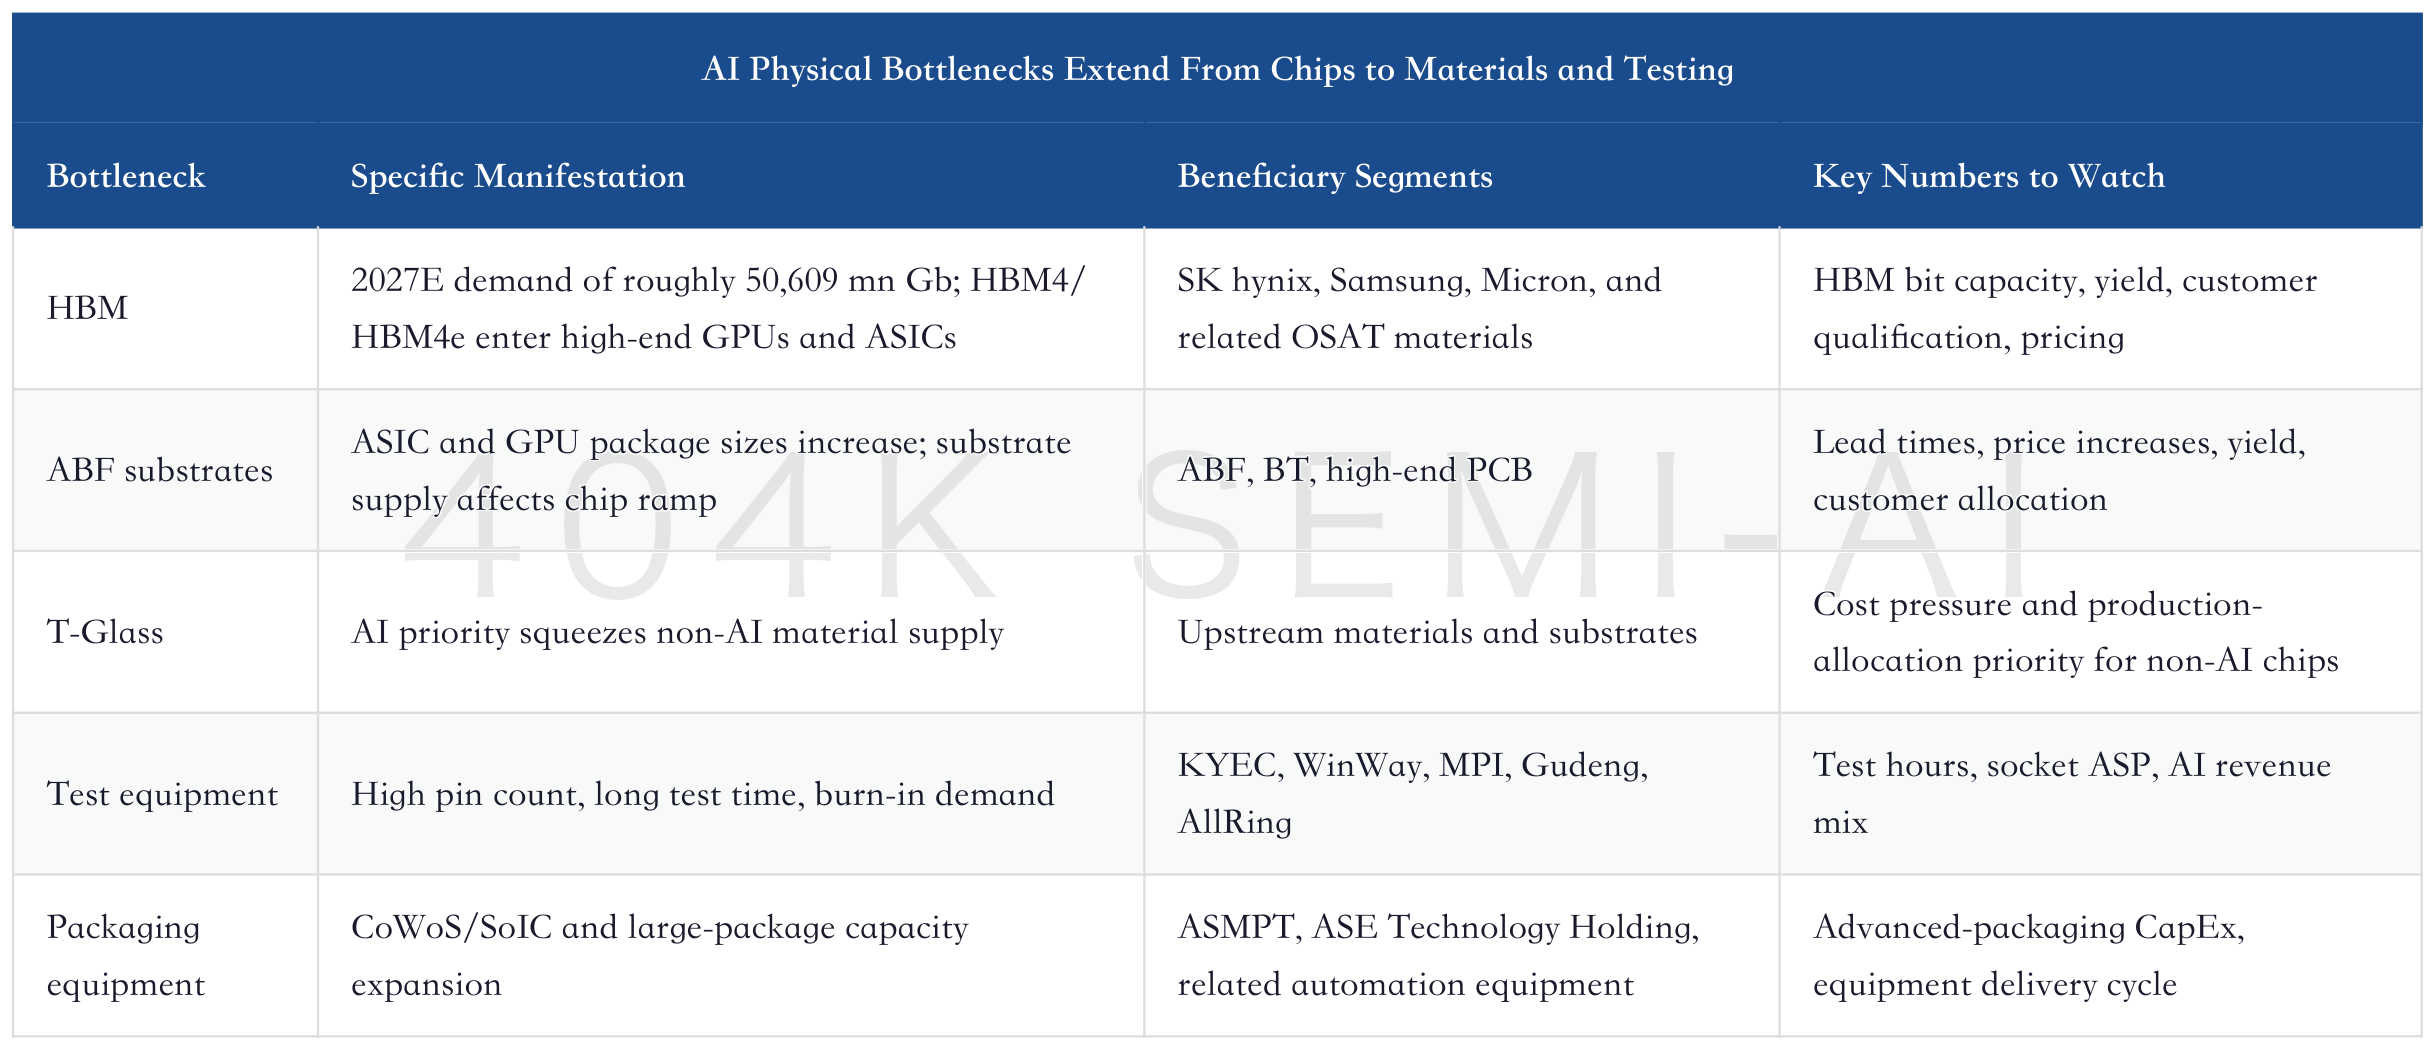
Morgan Stanley estimates 2027 HBM demand at roughly 50,609 mn Gb, with NVIDIA still consuming the largest share of HBM supply. Rubin R200 uses HBM4 12hi, Rubin Ultra uses HBM4e 12hi, and AMD MI400 and MI500 will also drive HBM4/HBM4e. On the ASIC side, TPU, Trainium, Maia, and MTIA also consume HBM. HBM has moved beyond a standalone memory-cycle story and become a hard constraint on whether AI systems can be delivered on time.
The Second Engine of the Memory Supercycle: CPU Comeback, HBM Spillover, and the US$1.7tn TAM Revaluation
ABF and T-Glass are also on the same physical ledger. Morgan Stanley mentions AI’s crowding-out effect on non-AI semiconductors, such as T-Glass and memory shortages. This wording is important because AI semiconductors have expanded from “advanced-chip price increases” into pressure on materials, substrates, memory, packaging, and testing resources. Non-AI semiconductors may face rising costs and lower capacity priority in 2026.
The changes in testing also deserve separate attention. AI/HPC chips require higher pin counts, larger package sizes, and longer test times. Morgan Stanley expects the test-equipment market to post a 2024-2027E CAGR of roughly 35%, and uses KYEC to show how testing demand for AI GPUs, TPUs, and CPUs pushes up the revenue mix. AI revenue from KYEC’s largest customer as a share of KYEC MSe revenue is expected to rise from 23% in 2025 to 34% in 2026E and 40% in 2027E.
ABF Substrate Deep-Dive Update: 25% Shortfall by 2030, BT Price Increases of 20-30%, and AI ASIC Proliferation; Which of Unimicron, Nan Ya PCB, and Zhen Ding Can Deliver Best
The investment conclusion from this section is: the second phase of AI semiconductors will look more like a “systems-engineering supply chain,” not just a question of chip-company revenue. The closer a segment is to the physical bottleneck, and the better it can convert price increases into profit, the more durable its valuation. Segments that rise only with the theme but lack validation from lead times, price increases, revenue mix, and customer orders are more likely to see valuations cut when CapEx return pressure appears.
VII. Optical Interconnects: CPO Debate Cannot Stop the Bandwidth Bill
Morgan Stanley places CPO inside AI semiconductor solutions, alongside Moore's Law, CoWoS/SoIC, HBM, custom chips, and GaN HVDC 800V. That acknowledges one fact: the larger AI clusters become, the thicker the bandwidth bill gets across chips, boards, racks, and data centers.
CPO Bull-Case Expectations Cool: Architecture Debate Cannot Stop Optical Incremental Demand as AI Clusters Enter the Optical Interconnect Era
The trading difficulty in CPO is timing. The market can repeatedly debate "when CPO will be deployed at scale," but Morgan Stanley's framework is better split into three layers. The first layer is traditional pluggable optical modules continuing to upgrade with bandwidth. The second is silicon photonics, FAU, and optical components moving closer inside the rack. The third is CPO and co-packaged optics entering deeper chip-packaging systems.
For TSMC, optical interconnects and CoWoS are not two fully separate tracks. Large-format packaging, SoIC, silicon photonics, test equipment, and high-end connectivity are all solving the same problem: AI cluster constraints in power, latency, and bandwidth. As long as GPUs, ASICs, and CPUs continue raising system-level throughput, optical interconnects will move from "conceptual optionality" to "part of the total bill."
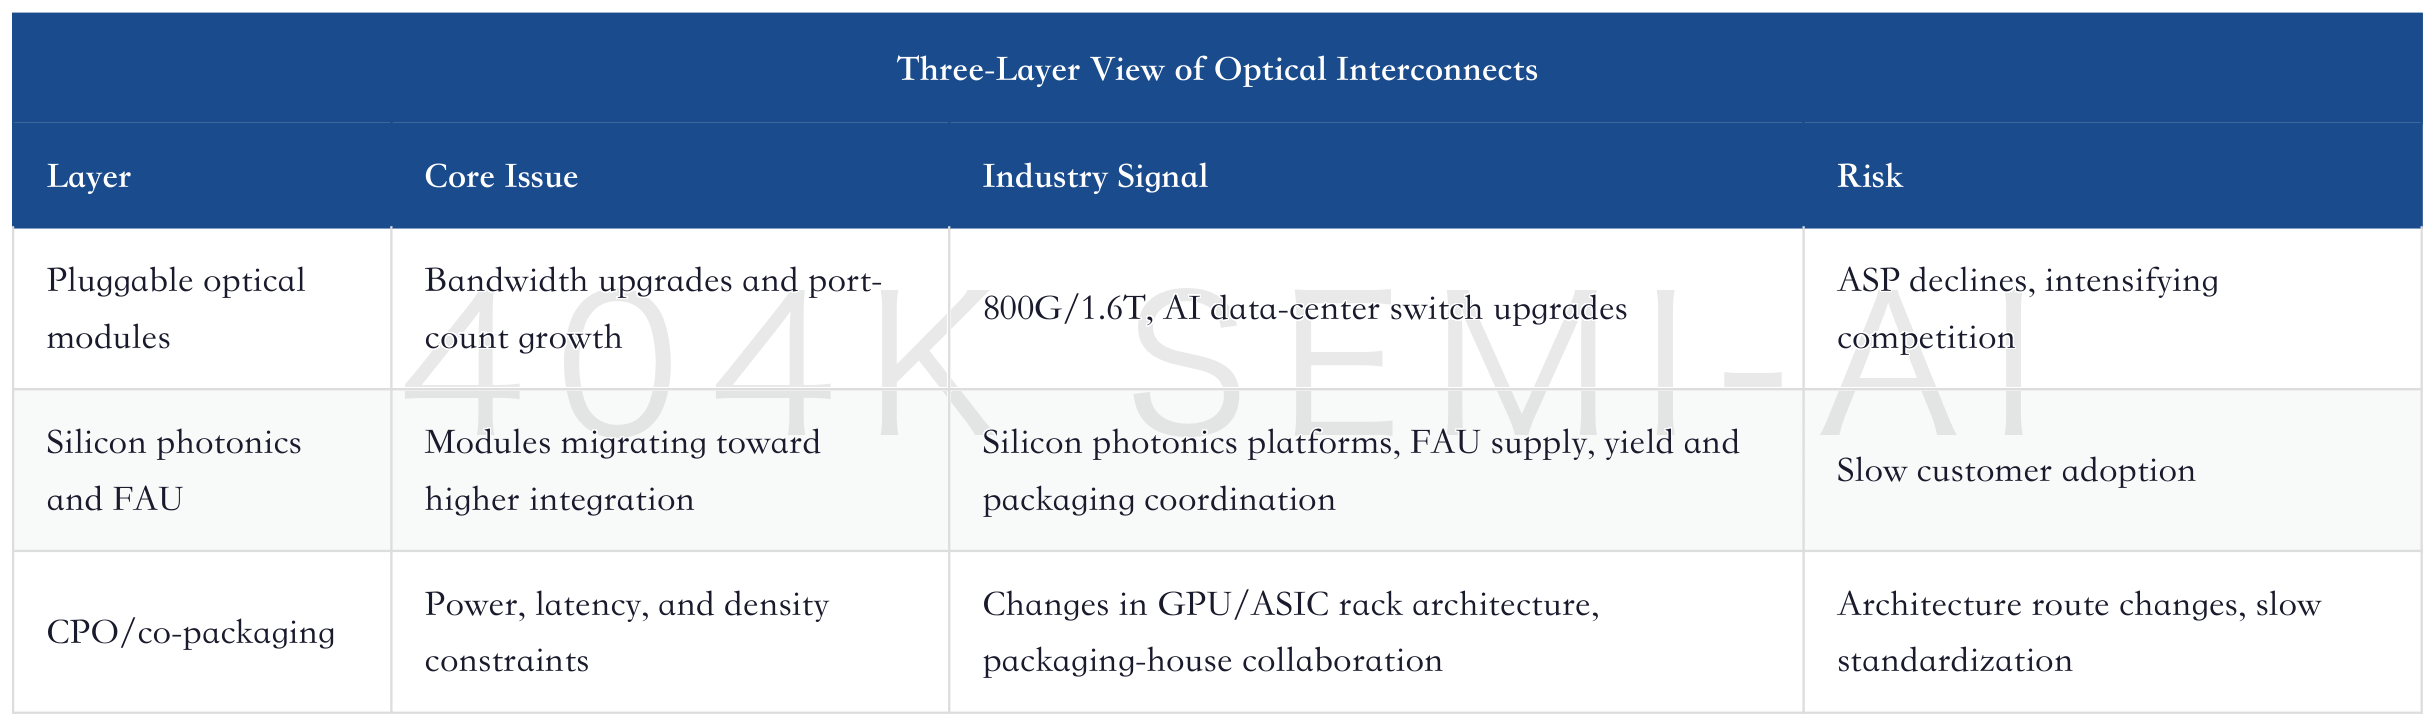
Optical interconnects will move onto the same agenda as CoWoS and rack power consumption. Morgan Stanley putting advanced packaging and optics in the same update itself shows that investors need to assess "can the chip be built" and "can the cluster be connected" together.
VIII. China AI Compute: Using Systems Engineering to Offset the Single-Chip Gap
China AI compute is the second major focus of this report. Morgan Stanley expects China's AI GPU TAM to grow to US$91 billion by 2030E, and China's CPU TAM to rise to US$42 billion by 2030E. This view rests on several realities: rising inference demand, more domestic cloud and model applications, lower prices for onshore AI chips, and system clusters that can use more chips, larger racks, and stronger infrastructure to offset the single-chip gap.
The report's framework is clear: if a single compute die is not strong enough, package more dies into one chip; if a single chip is not strong enough, build larger racks and clusters; if a single foundry's capacity is insufficient, expand manufacturing capability. This is a classic systems-engineering route. Its weaknesses are efficiency, power consumption, and software adaptation. Its strengths are a more controllable supply chain, lower prices, and deployment closer to domestic demand.
Morgan Stanley also compares the TCO and per-token cost of onshore chips in inference scenarios, with a broadly positive conclusion: because domestic chips are significantly cheaper, they can provide competitive unit costs in some China large-model inference scenarios. The key is whether customers can accept the all-in cost, with variables including DeepSeek-type models, specific batch sizes, the number of active MoE experts, and domestic deployment conditions.
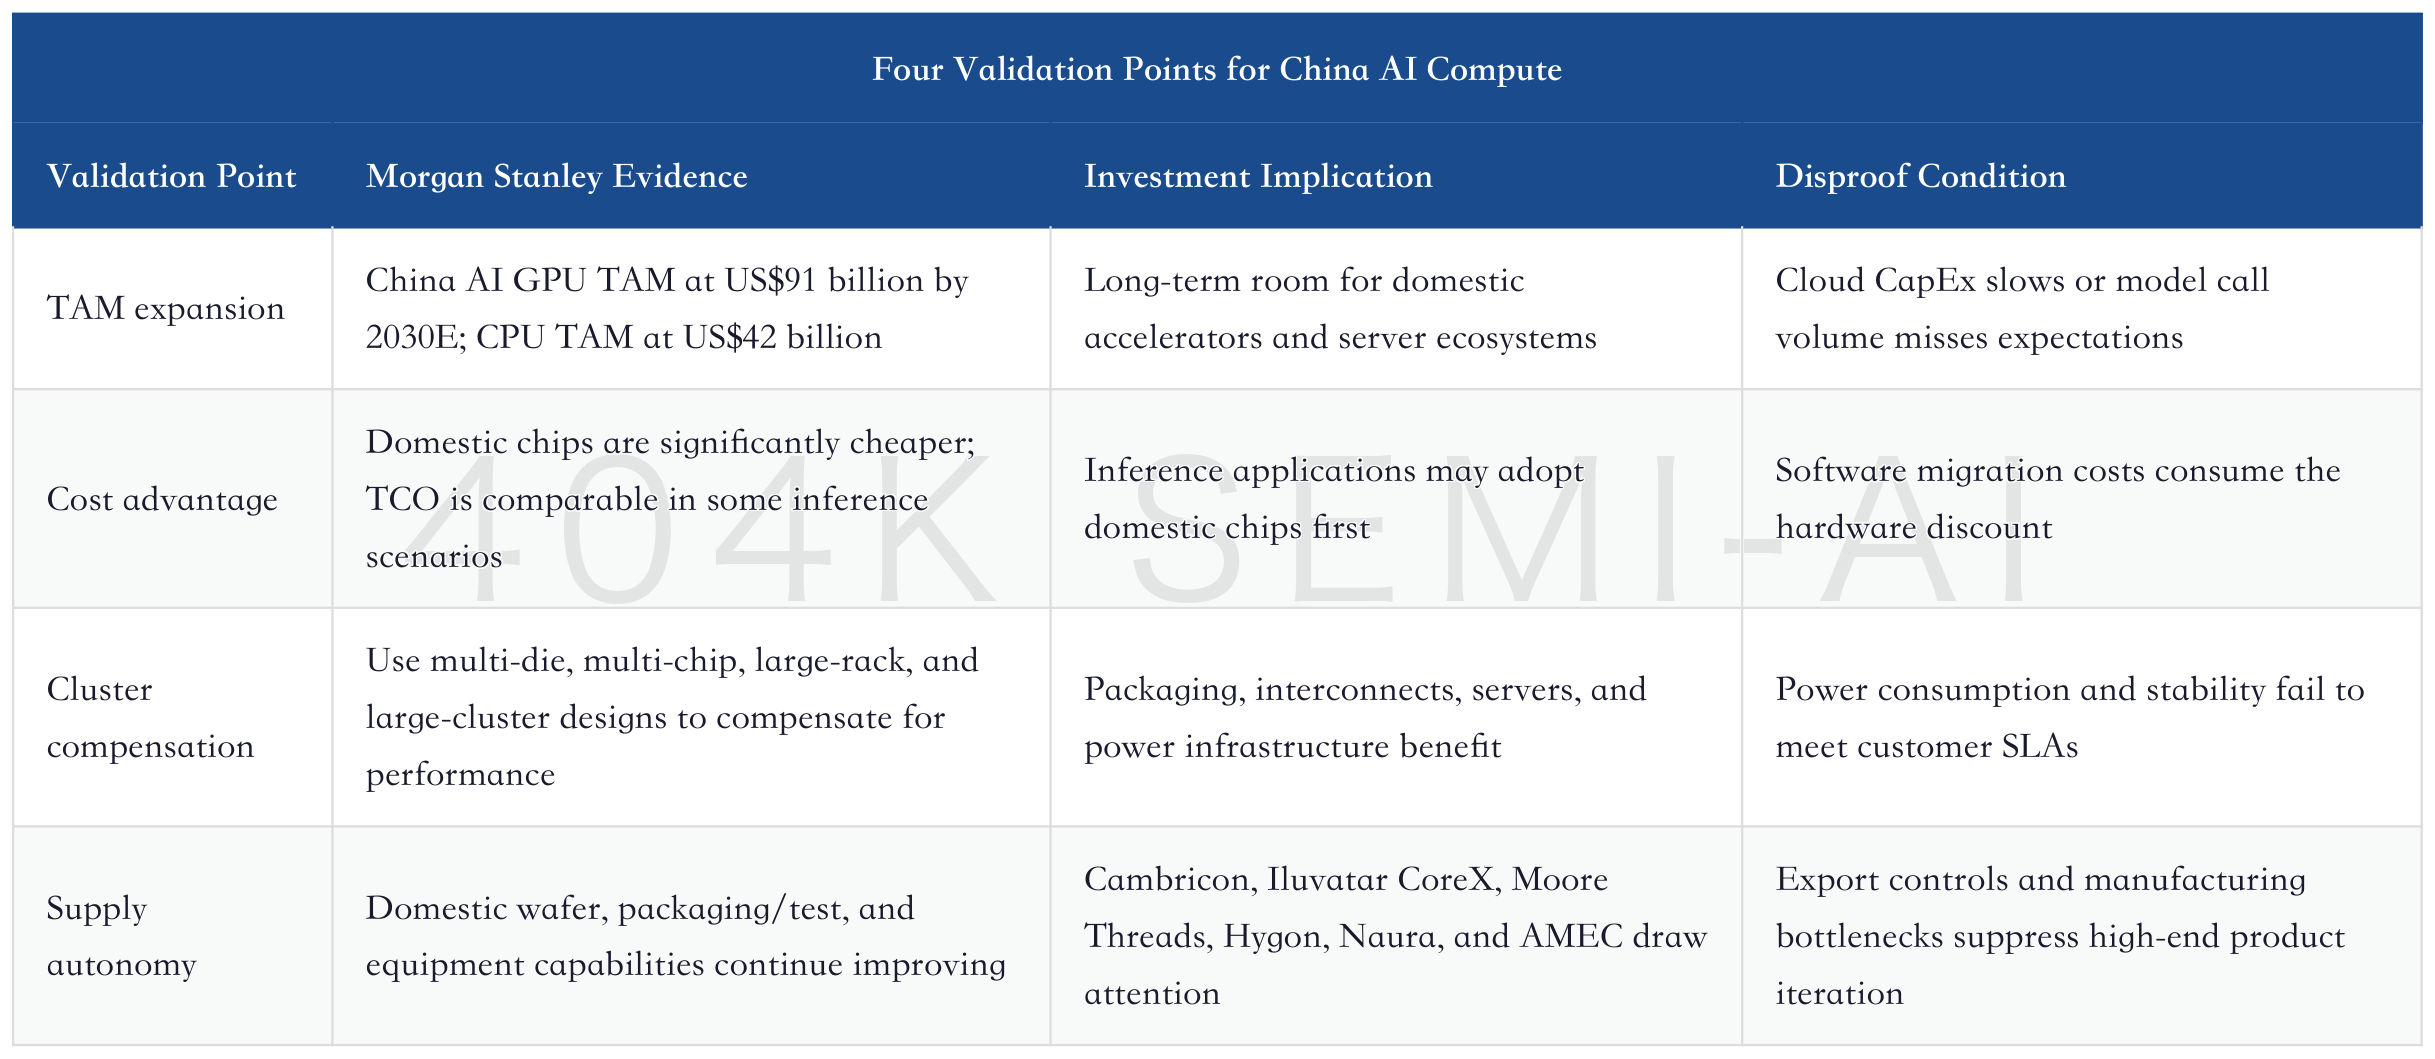
Morgan Stanley mentions "10 Dragons" among China's AI GPGPU vendors, with particular focus on Cambricon, Moore Threads, and Iluvatar CoreX; Hygon is the representative CPU+GPU integrated platform. This line is better validated through orders and TCO than through valuation optionality alone. Only companies that can enter real cloud-vendor orders, deliver stable inference costs, and secure domestic manufacturing and packaging/test resources can move from theme stocks to supply-chain assets.
China AI compute will also feed back into the TSMC narrative. On one hand, the stronger domestic compute becomes, the less certain it is that part of China's demand will fully flow to overseas GPUs. On the other hand, demand for domestic equipment, wafers, packaging/test, servers, and materials will be pushed higher. For global investors, this line offers another set of supply constraints: a compute supply chain under export controls and domestic-substitution frameworks.
IX. Investment Ranking: Buy Bottlenecks, Buy Validation, Buy Fewer Long-Dated Slogans
The best framework in this report is to split AI semiconductors into three types of assets. The first is bottleneck assets, which can directly translate tight supply-demand into pricing and gross margins. The second is validation assets, where orders and revenue mix are being pulled by AI but still need quarterly delivery. The third is long-dated assets, where TAM is large but delivery, yield, customers, and cash flow have not yet been fully proven.
Representative bottleneck assets include TSMC, CoWoS/SoIC, HBM, advanced packaging equipment, high-end test, and some ABF/materials. Their advantage is that they sit closest to capacity constraints. Their risk is that CapEx and expansion cycles can loosen supply-demand at some stage. Validation assets include ASIC design services, cloud-vendor in-house chip supply chains, CPU scheduling chains, optical interconnects, and China's domestic AI chips. They have greater upside, but each line must be tracked against orders, shipments, and customer qualification.
Rubin Rack Revaluation: GPU Share Falls to 51%, AI Hardware Value Is Shifting Toward Memory, PCB, Power, and Liquid Cooling. Who Is Capturing the New AI Hardware Increment?
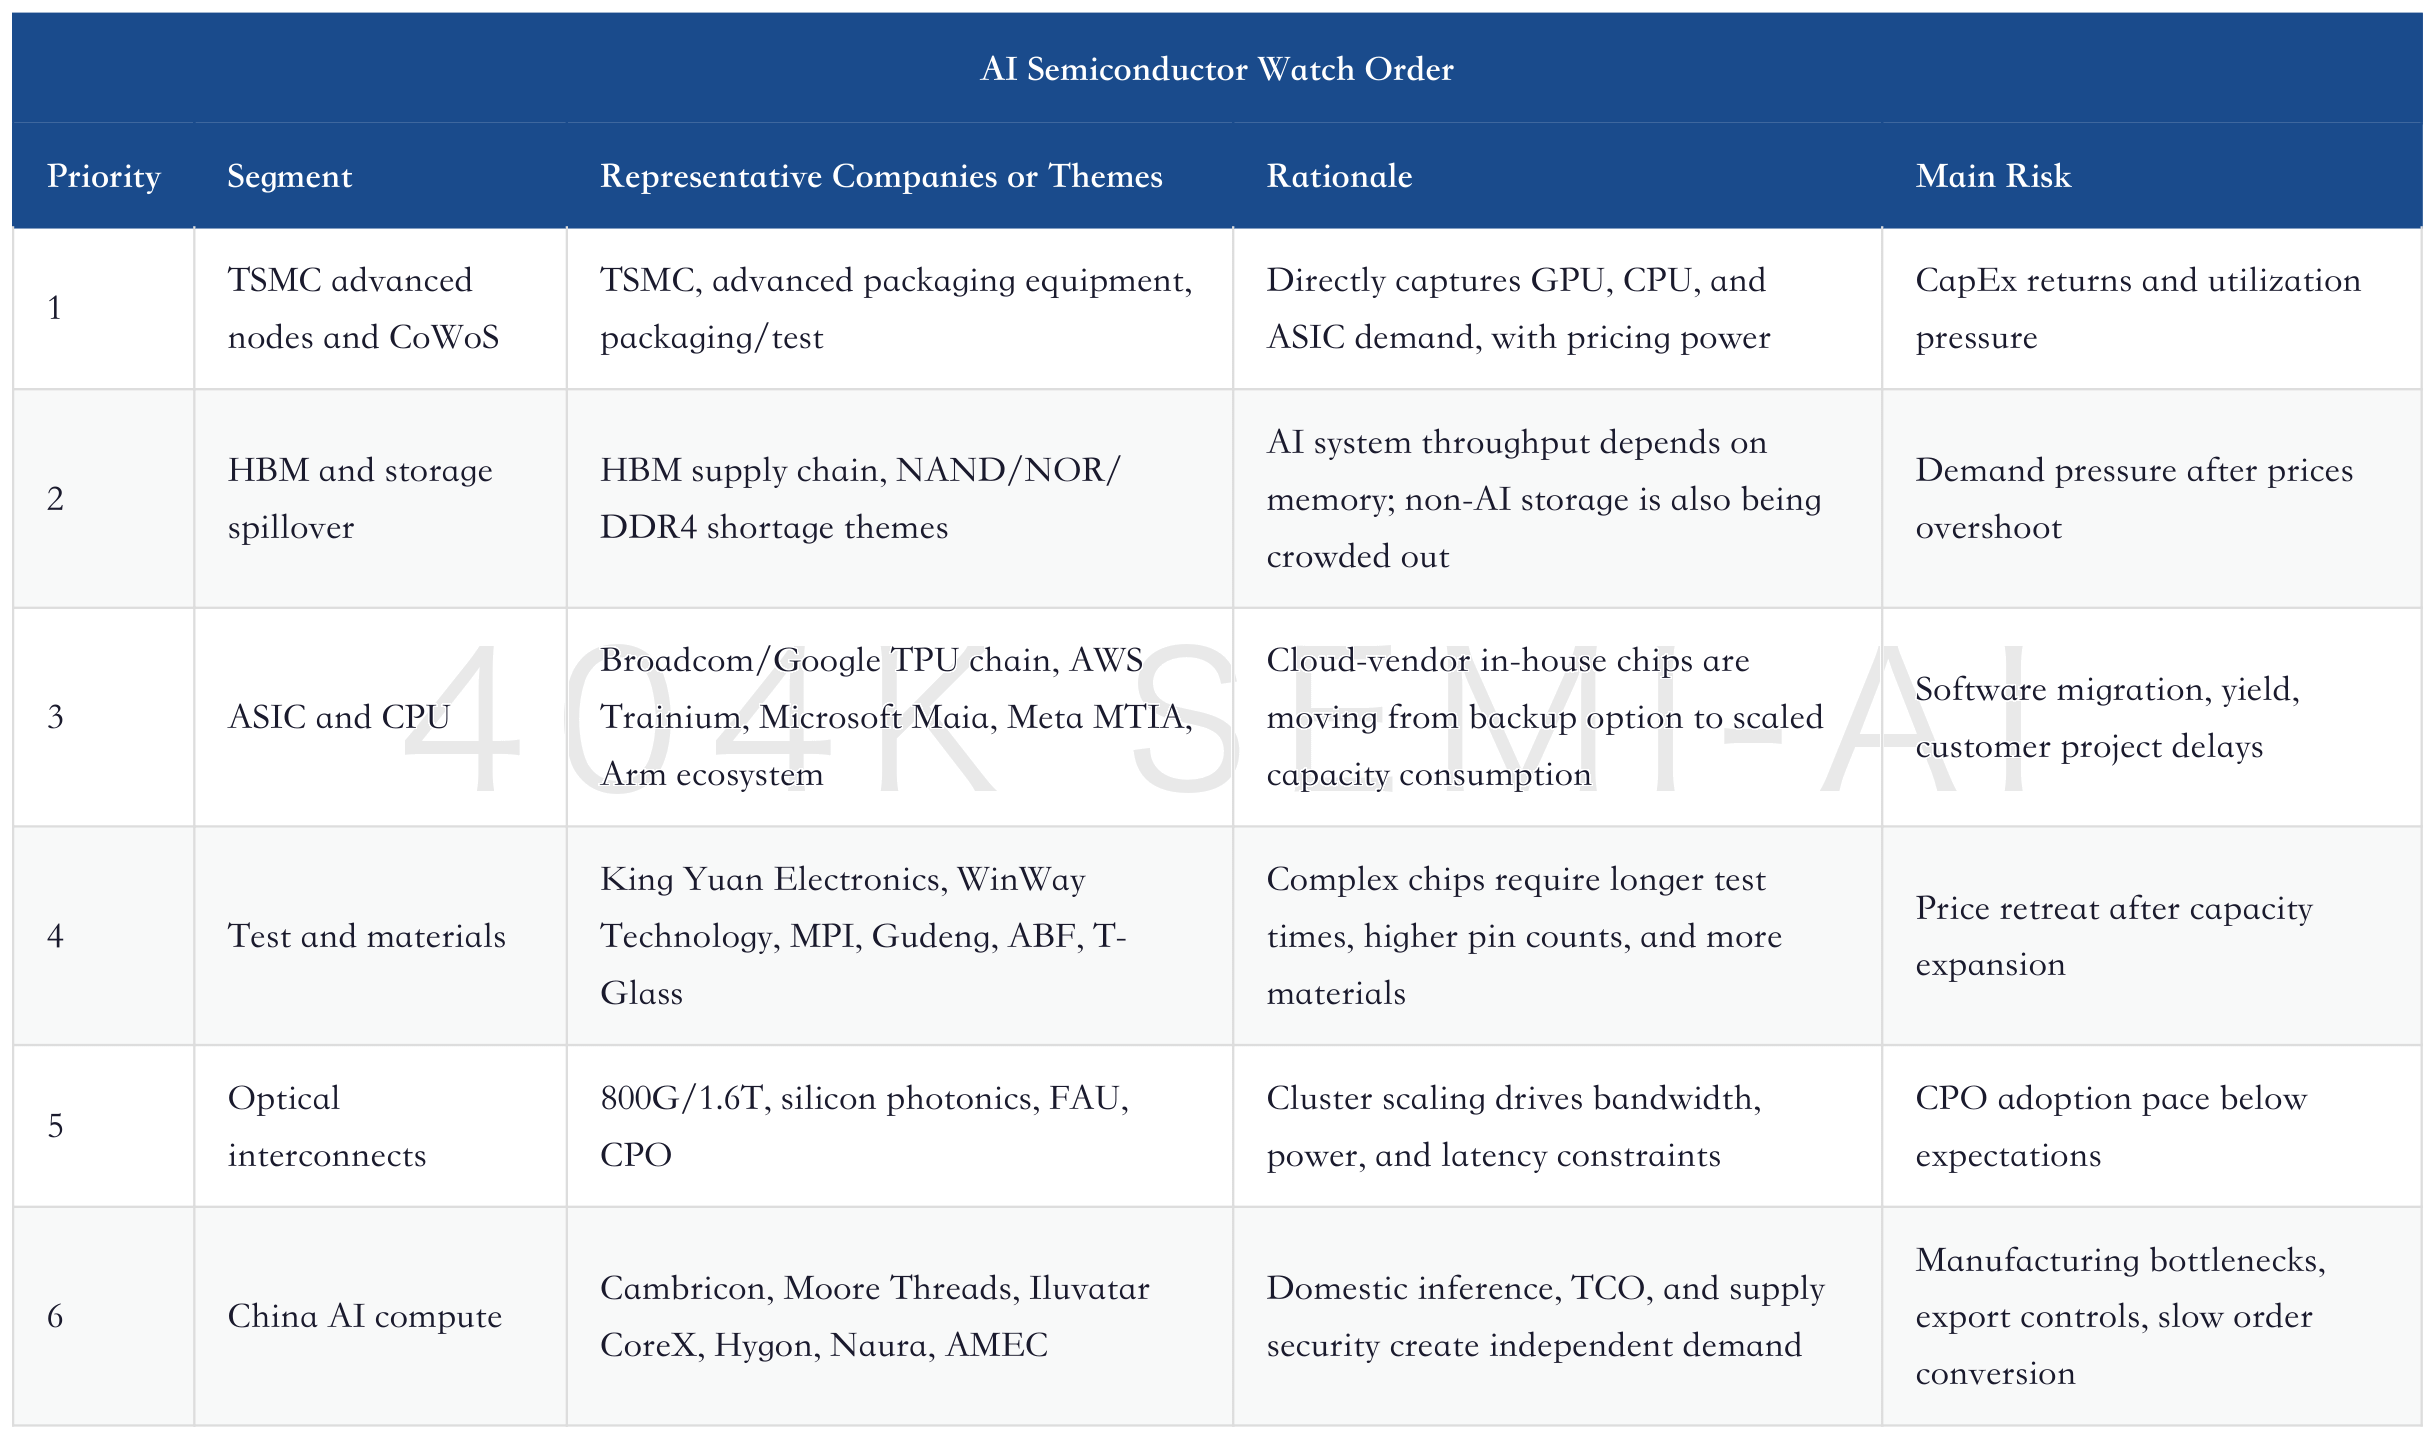
This ranking also explains why semiconductor trading will shift from "momentum upgrades" to "cash-flow reconciliation." When the market only looks at AI demand, every link can rise. When the market starts demanding CapEx returns, valuation will first remain with segments that can prove pricing, margins, and orders. TSMC remains in the first layer because it is closest to the bottleneck, but TSMC itself also has to face the same reconciliation. US$75 billion of CapEx is not a free lunch.
X. Scenario Framework: Three AI Semiconductor Worldviews
In the base case, cloud CapEx continues to grow, but investors begin to demand efficiency. TSMC’s N3/N2, CoWoS, and SoIC remain tight, and 5%-10% price increases for advanced nodes can partly offset depreciation, while AI semiconductor revenue continues to rise as a share of total revenue. GPUs remain the largest source of demand, while ASICs, CPUs, HBM, and optical interconnects take portions of incremental growth. This scenario is most favorable for TSMC, advanced packaging, HBM, testing, and ASIC design services.
In the bull case, agentic AI applications scale rapidly, and although cloud vendors’ CapEx-to-EBITDA remains high, revenue and inference call volume keep pace. The orchestration CPU TAM approaches Morgan Stanley’s bull case, while GPUs, ASICs, and CPUs simultaneously compete for N3/N2 and CoWoS capacity. HBM and ABF remain tight, and optical interconnect adoption accelerates. In this scenario, investment opportunities continue to spread from the Nvidia chain to CPUs, ASICs, testing, packaging equipment, and China’s domestic AI compute.
In the stress case, cloud vendor CapEx materializes ahead of revenue, and the market begins to penalize high depreciation and high capital spending. CoWoS capacity expansion outpaces customer demand, HBM pricing peaks, ASIC projects are delayed, and agentic AI applications fail to generate sufficient CPU intensity. In this scenario, theme stocks come under pressure first, while TSMC also shifts from being valued as a premium manufacturing platform back to a utilization and depreciation model. The only segments that can still withstand pressure are assets with strong customer lock-in, favorable pricing contracts, and visible cash flow.
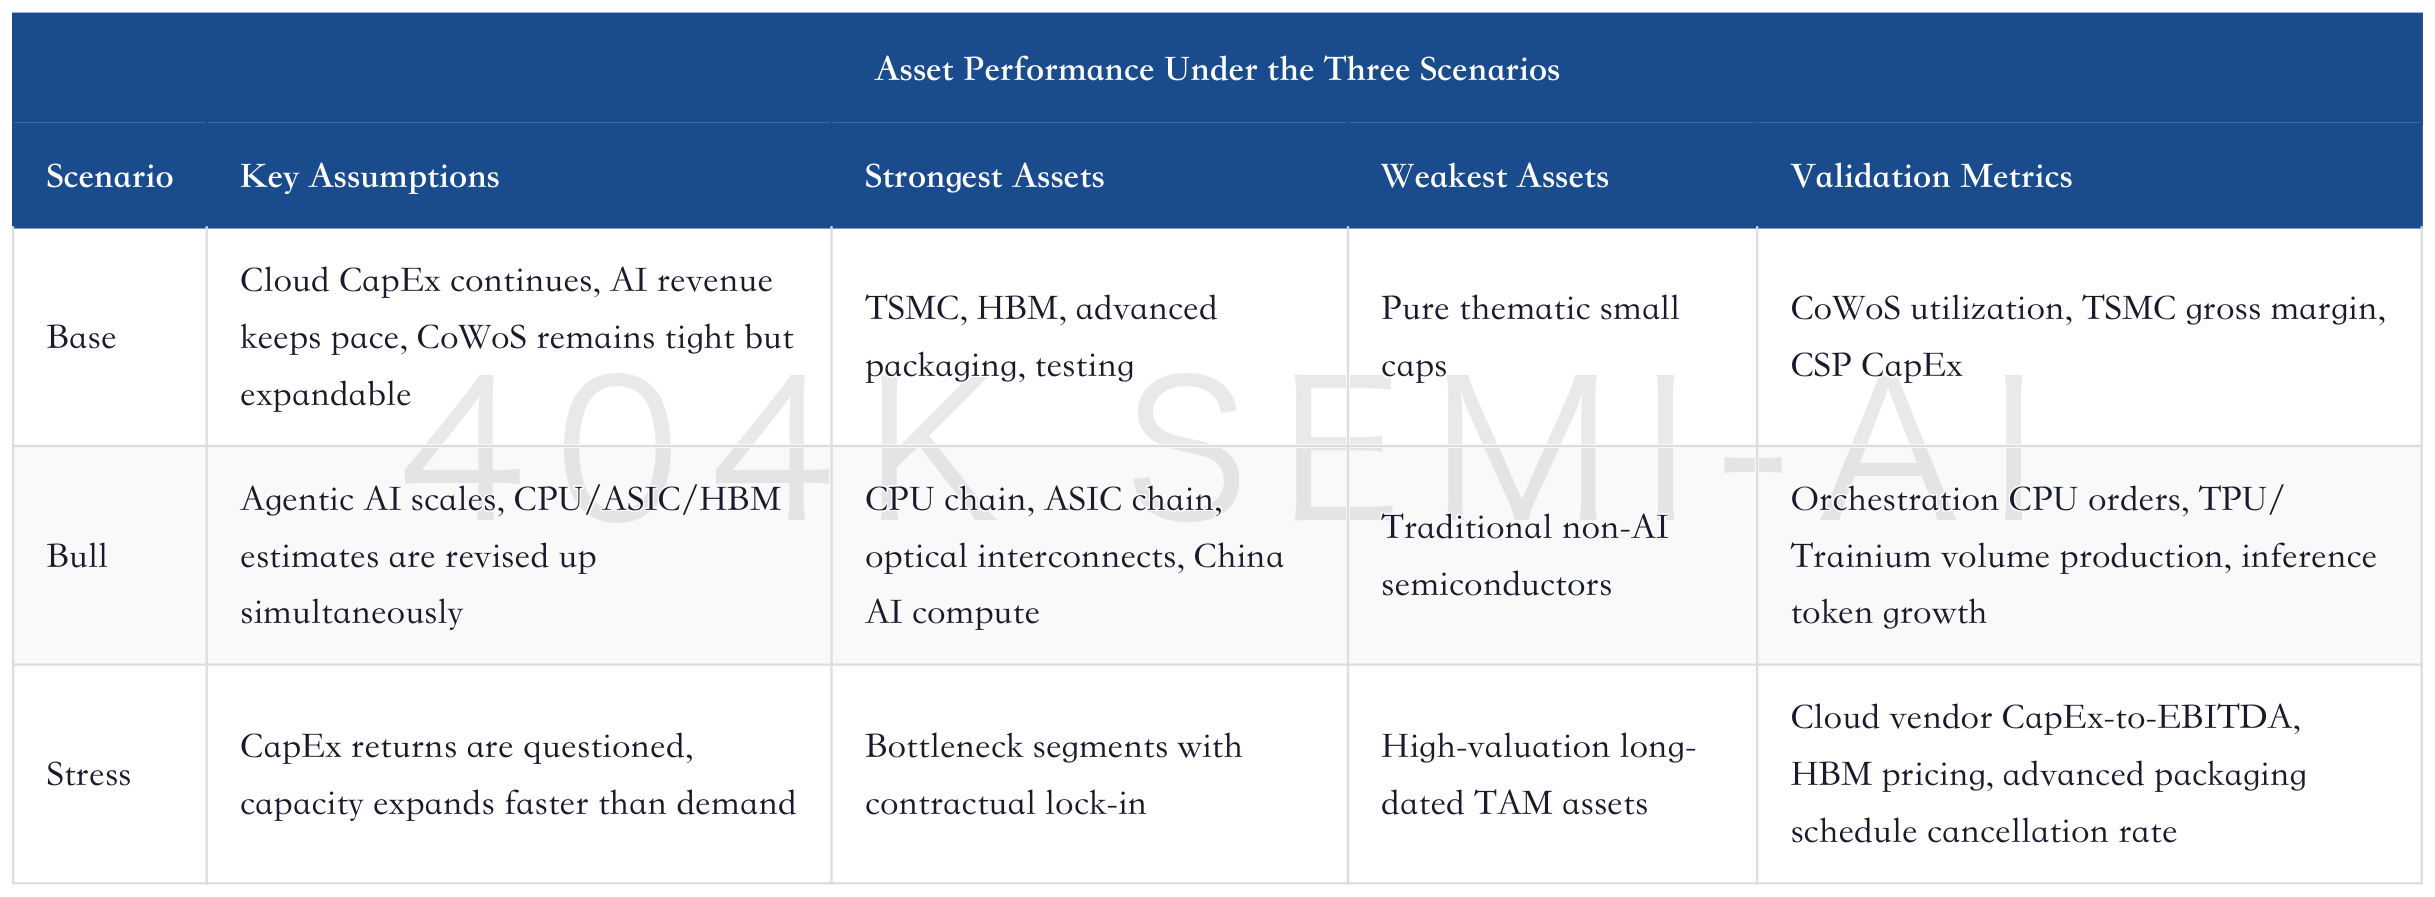
Morgan Stanley’s report leans between the base and bull cases. It does not deny CapEx pressure; instead, it uses larger cloud CapEx, more customer projects, and a broader AI supply chain to explain why AI semiconductors still have upside. My interpretation is that this report is useful for correcting two extreme views: AI is not over, but AI semiconductors can no longer earn valuation support simply from saying “demand is strong.”
XI. Follow-Up Tracking: Four Tables Will Decide How Far This Trade Can Go
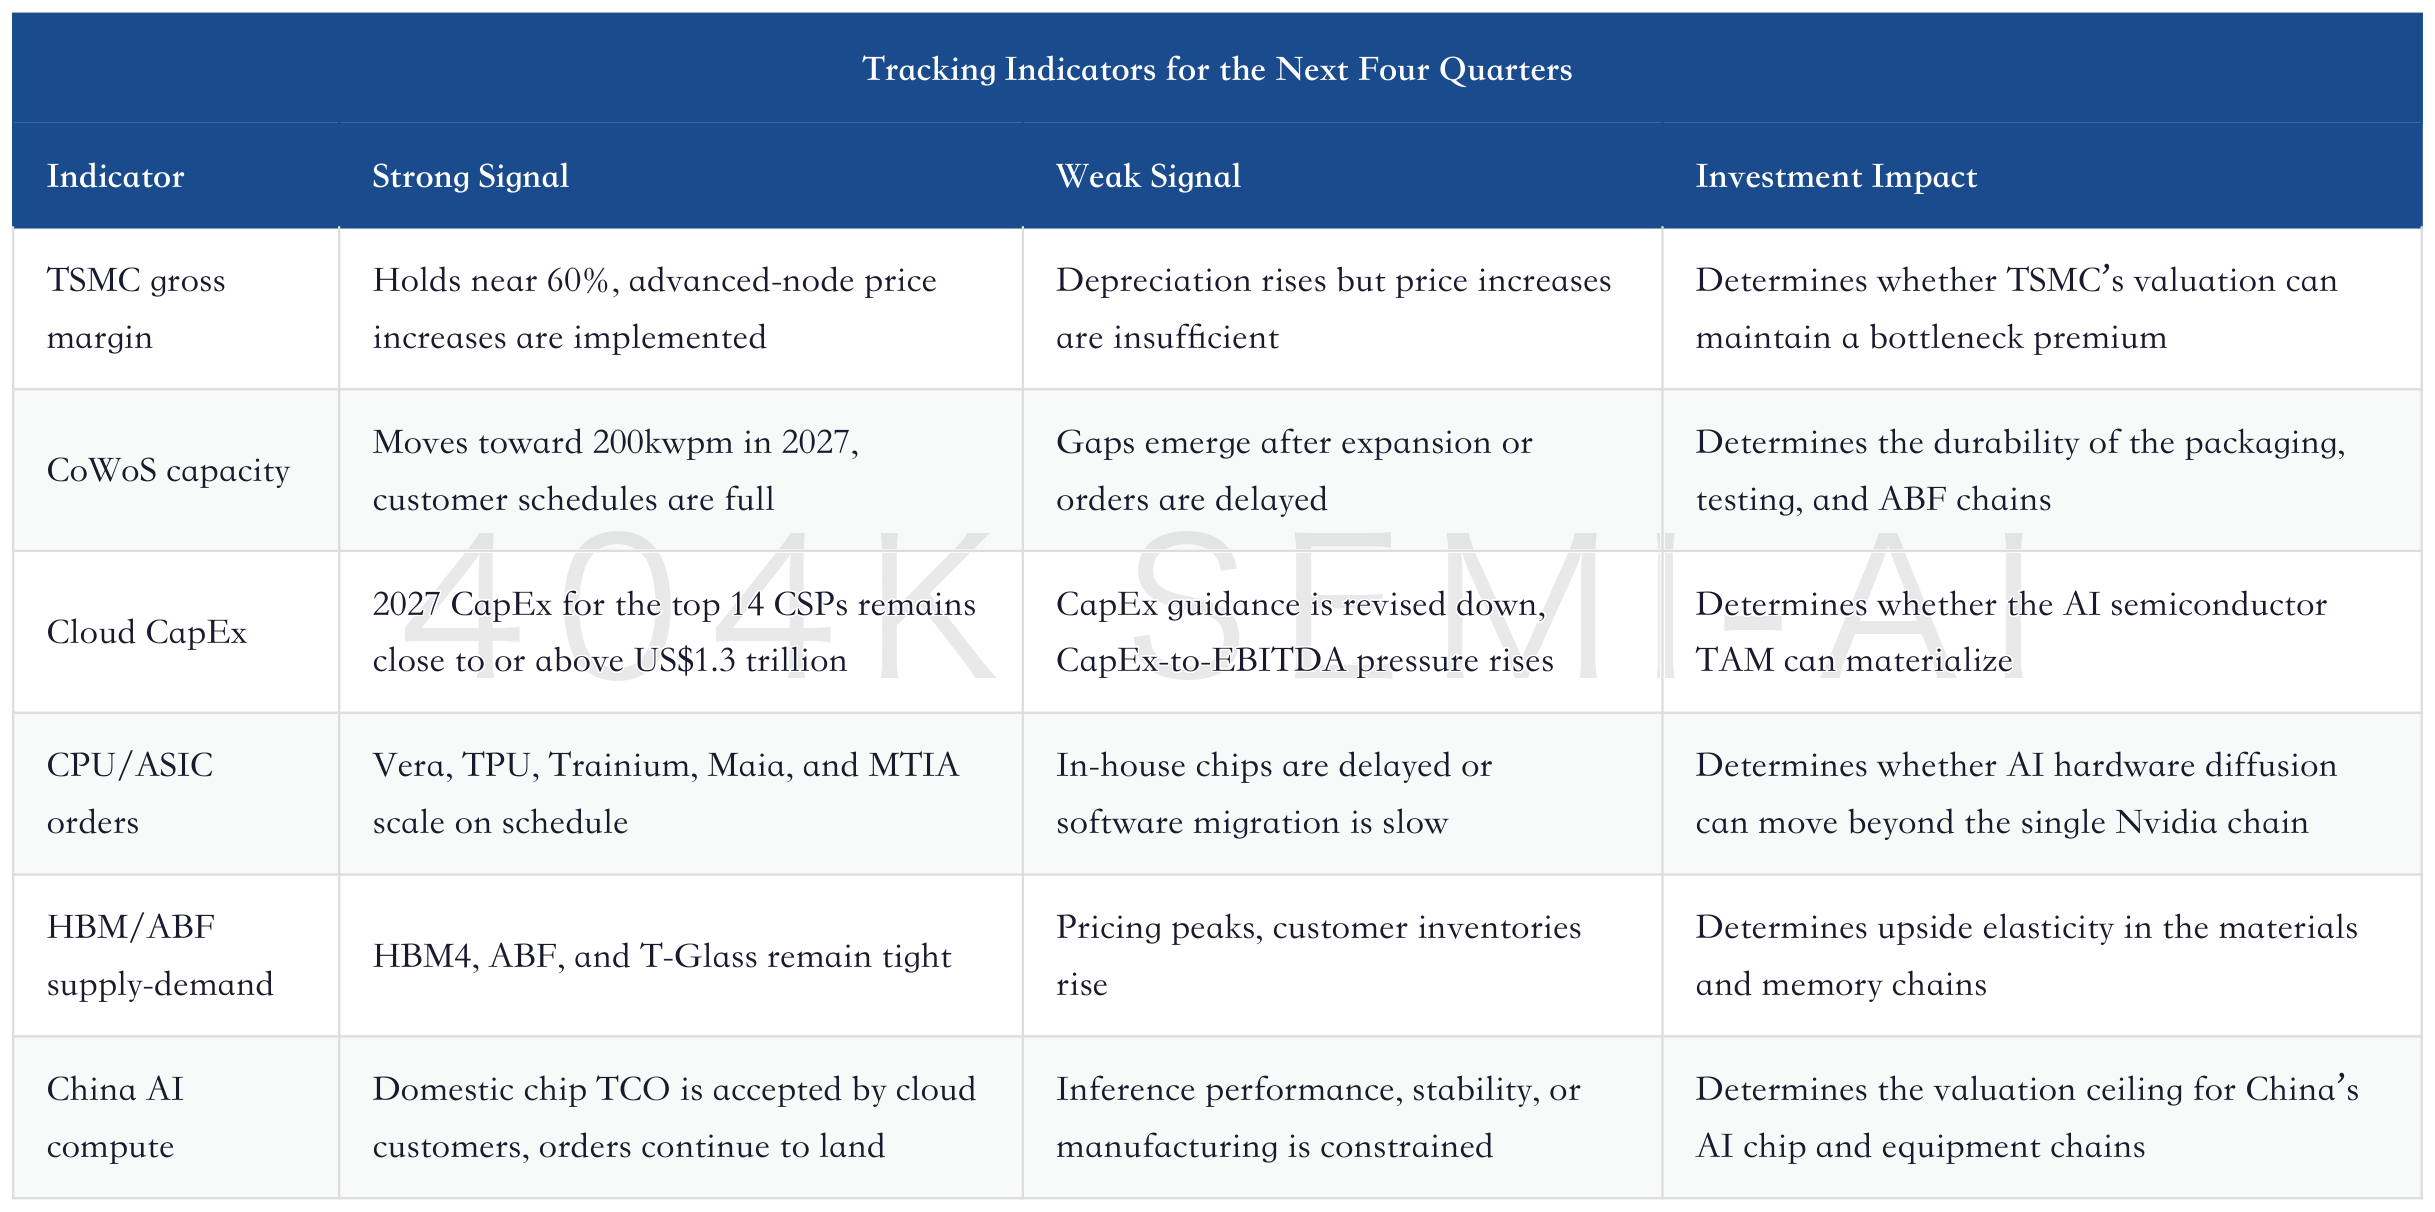
The first table is TSMC CapEx and gross margin. As long as 2027E CapEx of US$75 billion continues to be revised upward, the market will ask about depreciation, utilization, and pricing. TSMC must prove that it can simultaneously deliver advanced-node price increases, high CoWoS utilization, and defend a 60% gross margin line.
The second table is CoWoS monthly capacity and customer allocation. 200kwpm is the key anchor. The denominator is total capacity, and the numerator is production allocation for customers such as Nvidia, AMD, Google/Broadcom, AWS, Microsoft, and Meta. If customer allocation becomes more diversified, TSMC’s pricing power becomes more stable; if a major customer cuts orders, packaging utilization will immediately affect valuation.
The third table is cloud vendor CapEx-to-EBITDA. Morgan Stanley notes that CapEx-to-EBITDA for the top four CSPs has already exceeded 70%, which means the trade has entered a return-on-investment inspection phase. As long as AI revenue, inference call volume, and customer productization keep pace, capital markets will tolerate high CapEx. If revenue proof slows, the semiconductor supply chain will derate first.
The fourth table is order conversion for CPUs, ASICs, and optical interconnects. For CPUs, watch Vera, Venice, and Google CPU; for ASICs, watch TPU, Trainium, Maia, and MTIA; for optical interconnects, watch 800G/1.6T, silicon photonics, and CPO adoption. These determine whether AI hardware value can spread from GPUs into more segments.
XII. TSMC Profile: What It Sells Is AI Capacity With Delivery Certainty
TSMC’s corporate characteristics need to be stated clearly first. On the surface, it sells wafer foundry services; in practice, it sells manufacturing certainty that customers can verify, scale, and receive on time at advanced nodes. The AI cycle has amplified this feature, because GPUs, CPUs, ASICs, and high-bandwidth packaging cannot ship on design blueprints alone. Customers must simultaneously buy yield, process windows, packaging capacity, supply-chain coordination, and global capacity stability.
This is also what distinguishes TSMC from ordinary cyclical manufacturers. Ordinary manufacturers can easily fall into price competition after capacity expansion. For TSMC, expansion in advanced processes and advanced packaging instead reinforces customer dependence in the short term. The more customers there are, the more complex the chips become, the larger the packages get, and the tighter the launch windows are, the more valuable TSMC’s capacity allocation power becomes. Morgan Stanley calls it the “only game in town.” Behind that phrase is customer switching cost, not just process leadership.
TSMC’s revenue structure is also changing. Smartphones remain an important customer group, but high-performance computing and AI semiconductors are lifting the revenue slope. Morgan Stanley expects the revenue weight of AI semiconductors to rise rapidly, while advanced-node pricing still has room to move higher. This change creates two opposing forces: on one side, high-ASP nodes and advanced packaging improve revenue quality; on the other, massive CapEx, depreciation, and globalized capacity bring fixed-cost pressure.
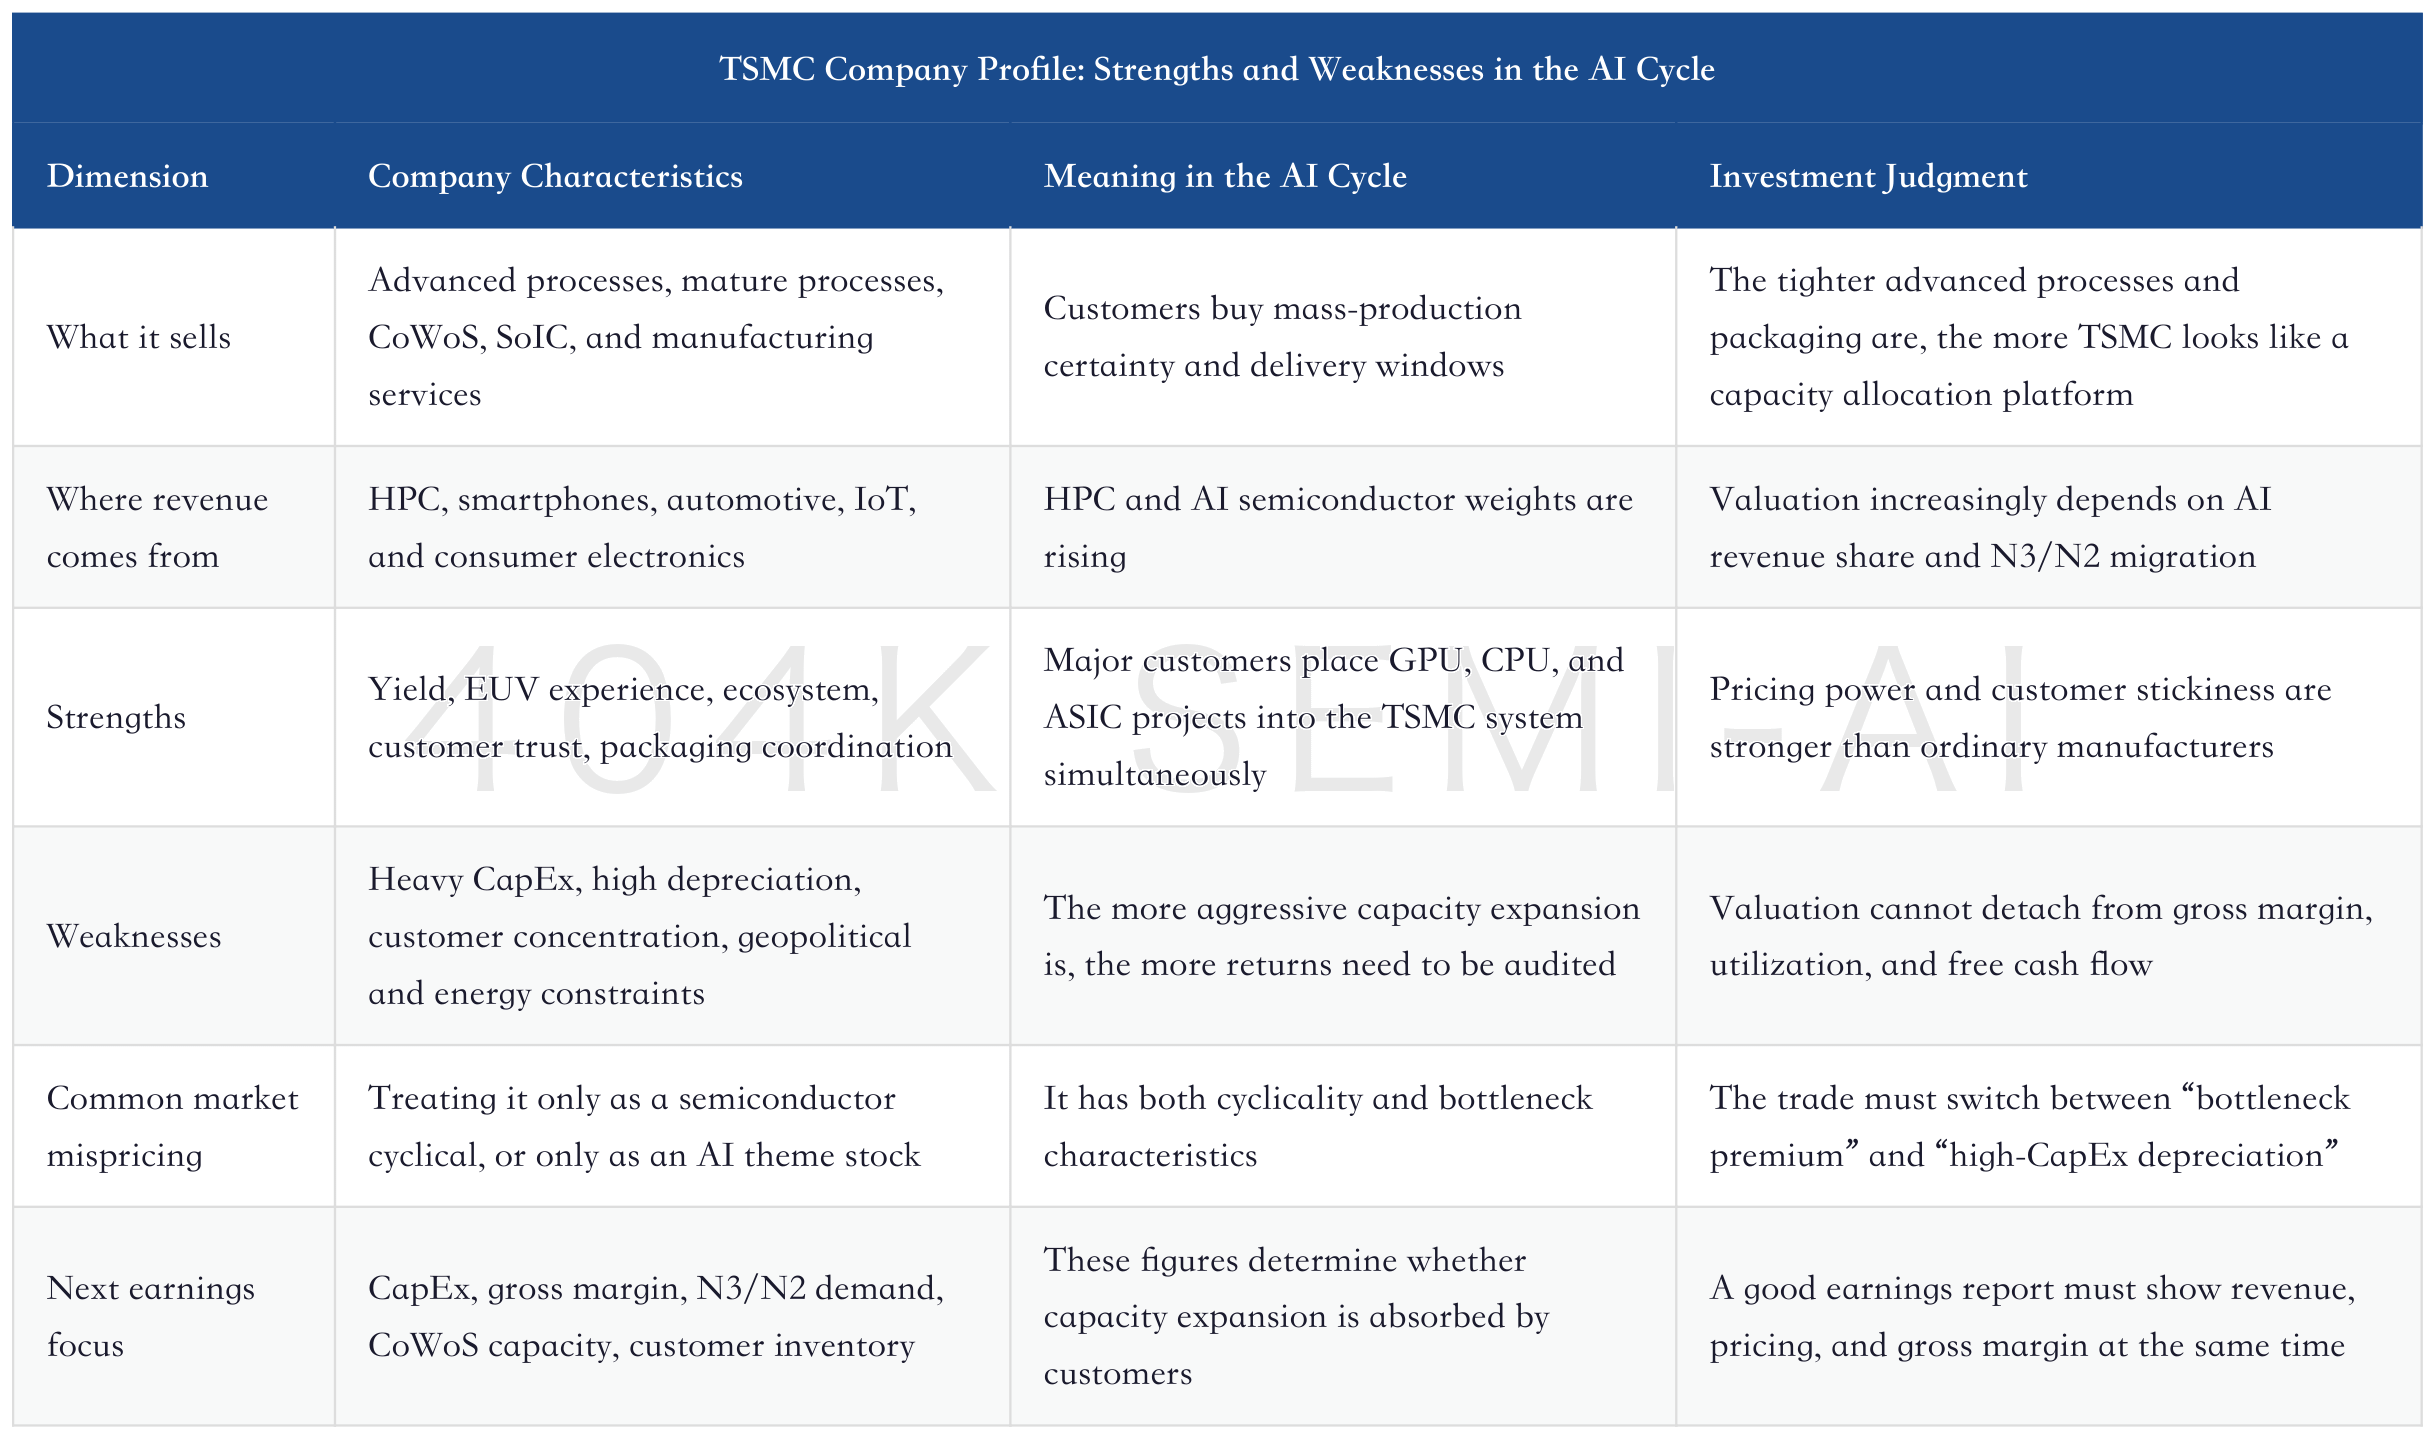
TSMC’s greatest strength is that it concentrates customers’ roadmap choices onto itself. If Nvidia continues to expand GPUs, TSMC benefits; if AMD and Nvidia add CPUs, TSMC benefits; if Google, AWS, Microsoft, and Meta increase ASIC investment, TSMC still benefits; if HBM and advanced packaging become tighter, TSMC remains in a key position through CoWoS and SoIC. Customers may compete with one another, but together they increase TSMC’s manufacturing load.
TSMC’s greatest weakness also comes from the same logic. It must build capacity in advance to retain major customers and maintain node leadership; building capacity in advance means depreciation arrives first, while customer orders and pricing arrive later. If AI demand is revised upward, TSMC enjoys a bottleneck premium; if customer CapEx weakens, the market will first question TSMC’s return on assets. TSMC’s valuation therefore naturally has a dual character: in good times, it looks like a high-certainty AI platform; in bad times, it looks like a high-depreciation manufacturing asset.
Therefore, the TSMC view in this report should not be read simply as “target price raised” or “AI demand is strong.” The more important question is whether TSMC can continue to maintain high gross margins after massive CapEx. This question determines whether it continues to enjoy a bottleneck-platform valuation or is placed back into the foundry cyclical-stock framework.
XIII. CapEx Return Check: $75 Billion Is Not a Capacity-Expansion Slogan
Morgan Stanley’s 2027E CapEx estimate of $75 billion is one of the numbers in the report that most needs repeated cross-checking. It represents TSMC’s willingness to place early bets on AI semiconductors, advanced nodes, advanced packaging, and global capacity deployment. The number itself is not automatically positive. It only becomes earnings leverage when customer orders, pricing, utilization, and gross margin all line up.
The CapEx check can be broken into three layers. The first is the revenue check: whether N3, N2, CoWoS, and SoIC are truly filled by GPU, CPU, and ASIC customers. The second is the pricing check: whether advanced-node price increases can offset depreciation and overseas capacity costs. The third is the cash-flow check: whether AI customer prepayments, long-term orders, and production-schedule commitments can prevent free cash flow from being swallowed by CapEx.
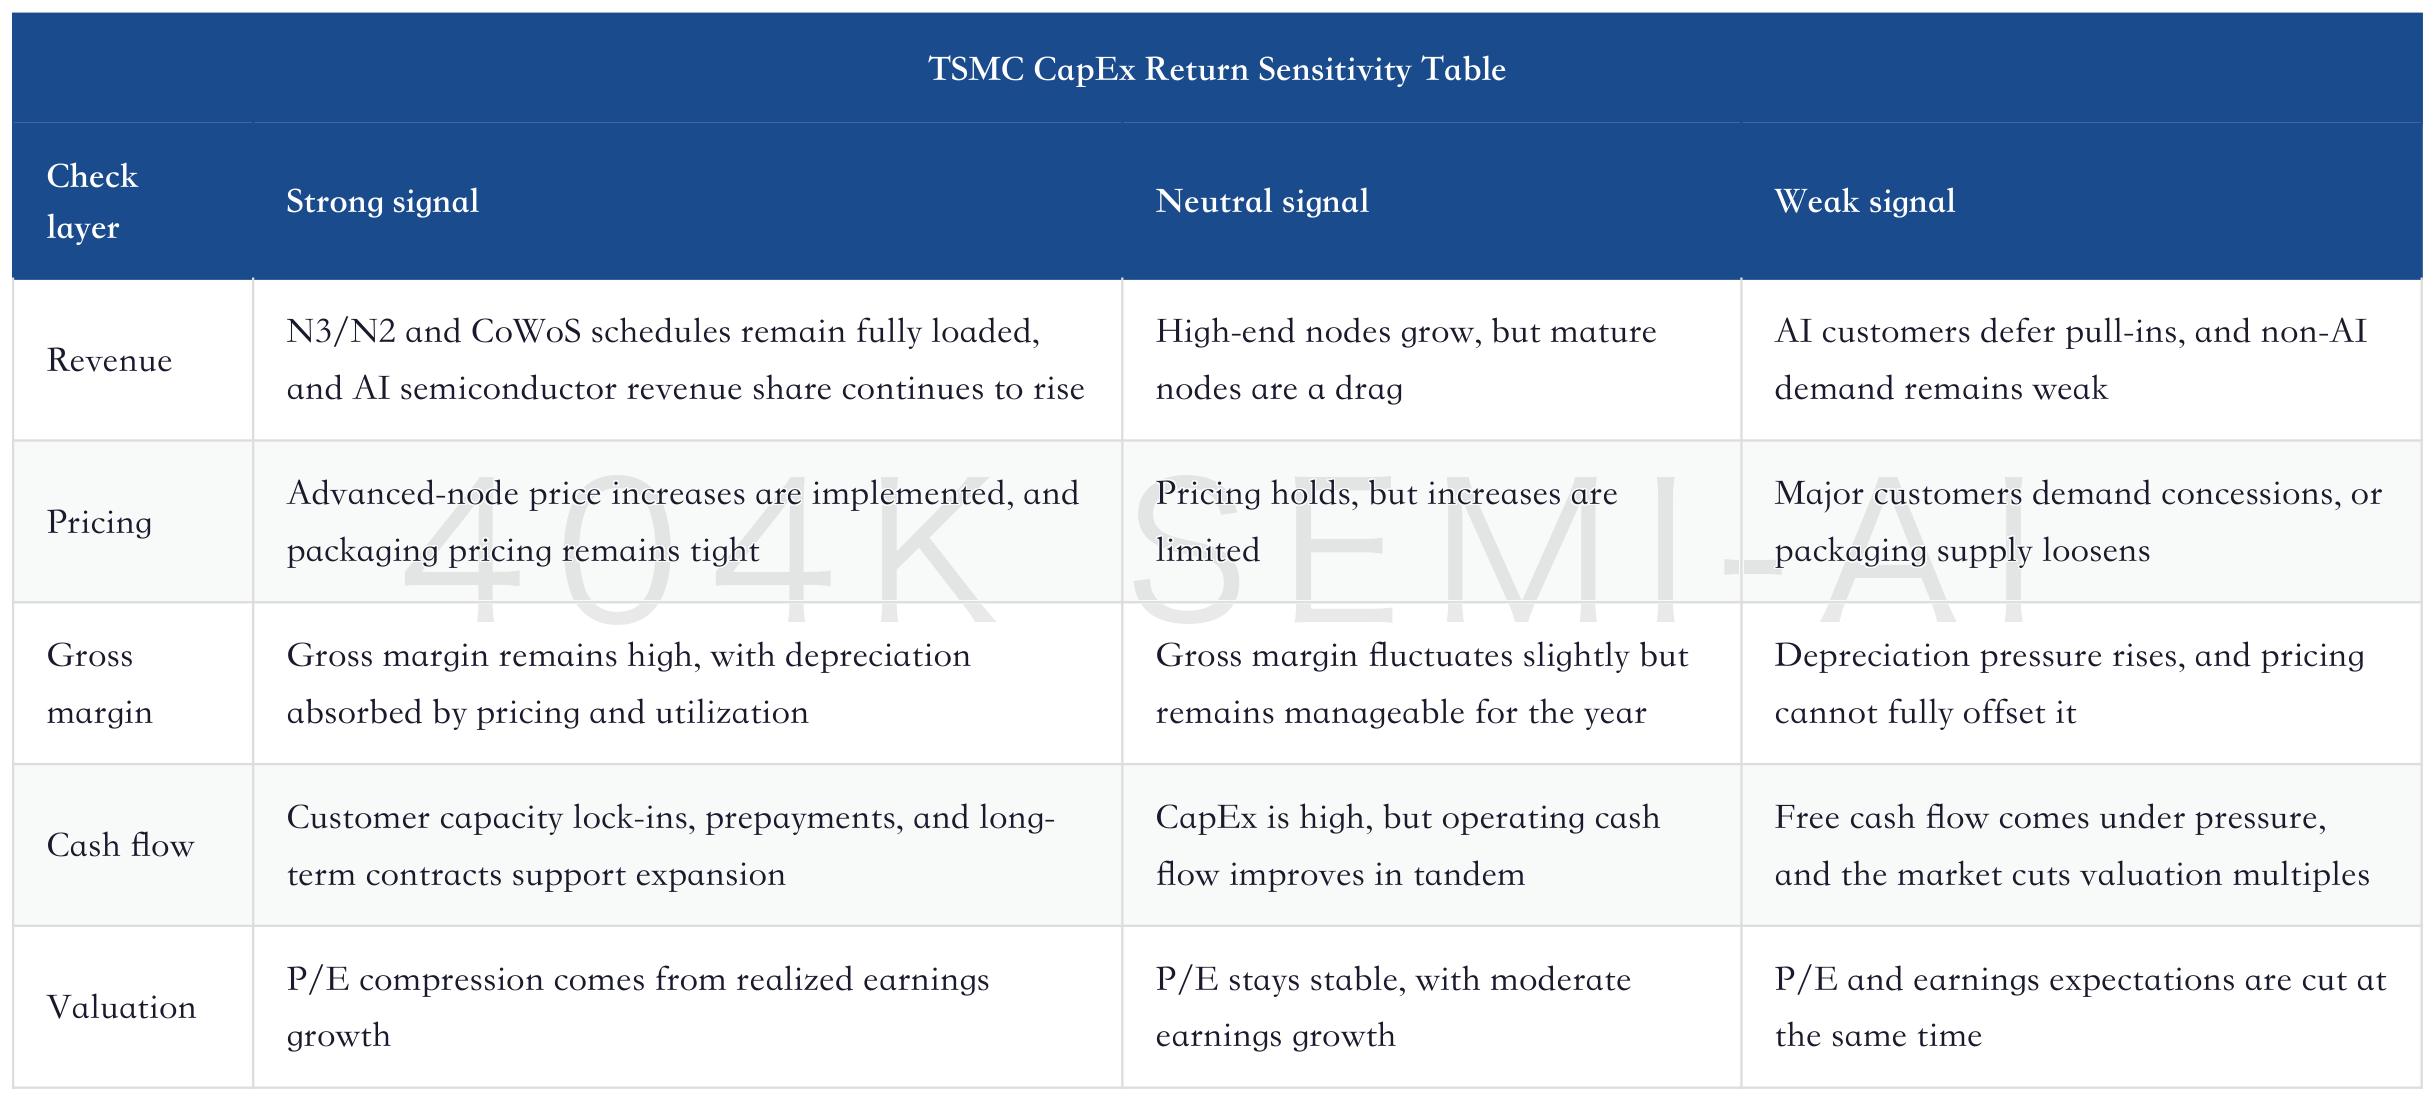
This framework also explains why TSMC’s trading leverage will not come only from revenue. If revenue growth is bought with high depreciation, the market will assign a lower multiple. If revenue growth comes with price increases, packaging shortages, and defended gross margin, the market will treat it as bottleneck rent. The key for TSMC is whether this spending turns into scarce capacity that customers must buy.
2027 will be an even more important year for verification. CoWoS expansion, N2 adoption, continued N3 ramp-up, overseas capacity investment, and AI customer project transitions will all affect TSMC’s income statement at the same time. Any single item can be explained away, but several weakening simultaneously would change the investment narrative. Investors should especially track customer schedule-cancellation rates, advanced-packaging lead times, wafer-price negotiations, and cloud vendor CapEx guidance.
Morgan Stanley’s positive view rests on the premise that customer demand is strong enough. Projects such as Nvidia Rubin, AMD MI400/MI500, Google TPU, AWS Trainium, Microsoft Maia, and Meta MTIA provide TSMC with a multi-customer demand pool. This multi-customer structure helps TSMC maintain pricing power and reduces the risk of a single customer cutting orders. The issue is that all of these customers’ orders depend on continued realization of cloud CapEx.
In other words, TSMC now has greater order depth to hedge CapEx pressure. Investors need to check quarter by quarter whether capacity expansion is being absorbed by real orders.
XIV. Advanced Packaging Competition: CoWoS, SoIC, EMIB, and Optical Interconnect Are Not Isolated Technologies
CoWoS is the most important bottleneck today, but it is not a standalone technology. As AI chip complexity rises, advanced-packaging roadmaps will simultaneously involve silicon interposers, hybrid bonding, chiplet interconnect, HBM stacking, testing, thermal management, and optical interconnect. TSMC’s advantage is that it can place advanced process technology and advanced packaging inside the same customer-service system, rather than forcing customers to assemble multiple supply-chain segments themselves.
The importance of SoIC is rising. CoWoS solves the packaging problem for multi-chip designs and HBM, while SoIC pushes further toward vertical integration and high-density interconnect. As connection requirements rise across GPUs, CPUs, ASICs, and HBM, SoIC may become a core tool for TSMC to maintain technology leadership over the next few years. It will move TSMC from “packaging chips” toward “participating in system architecture definition.”
Intel’s EMIB offers another competitive path. Morgan Stanley notes that EMIB can, in theory, support larger chips and more reticles, but supply-chain execution is the key. The investment implication here is clear: advanced packaging is a competition over customer mass-production windows. Whoever can deliver stable volume production at customers’ delivery nodes will win subsequent projects.
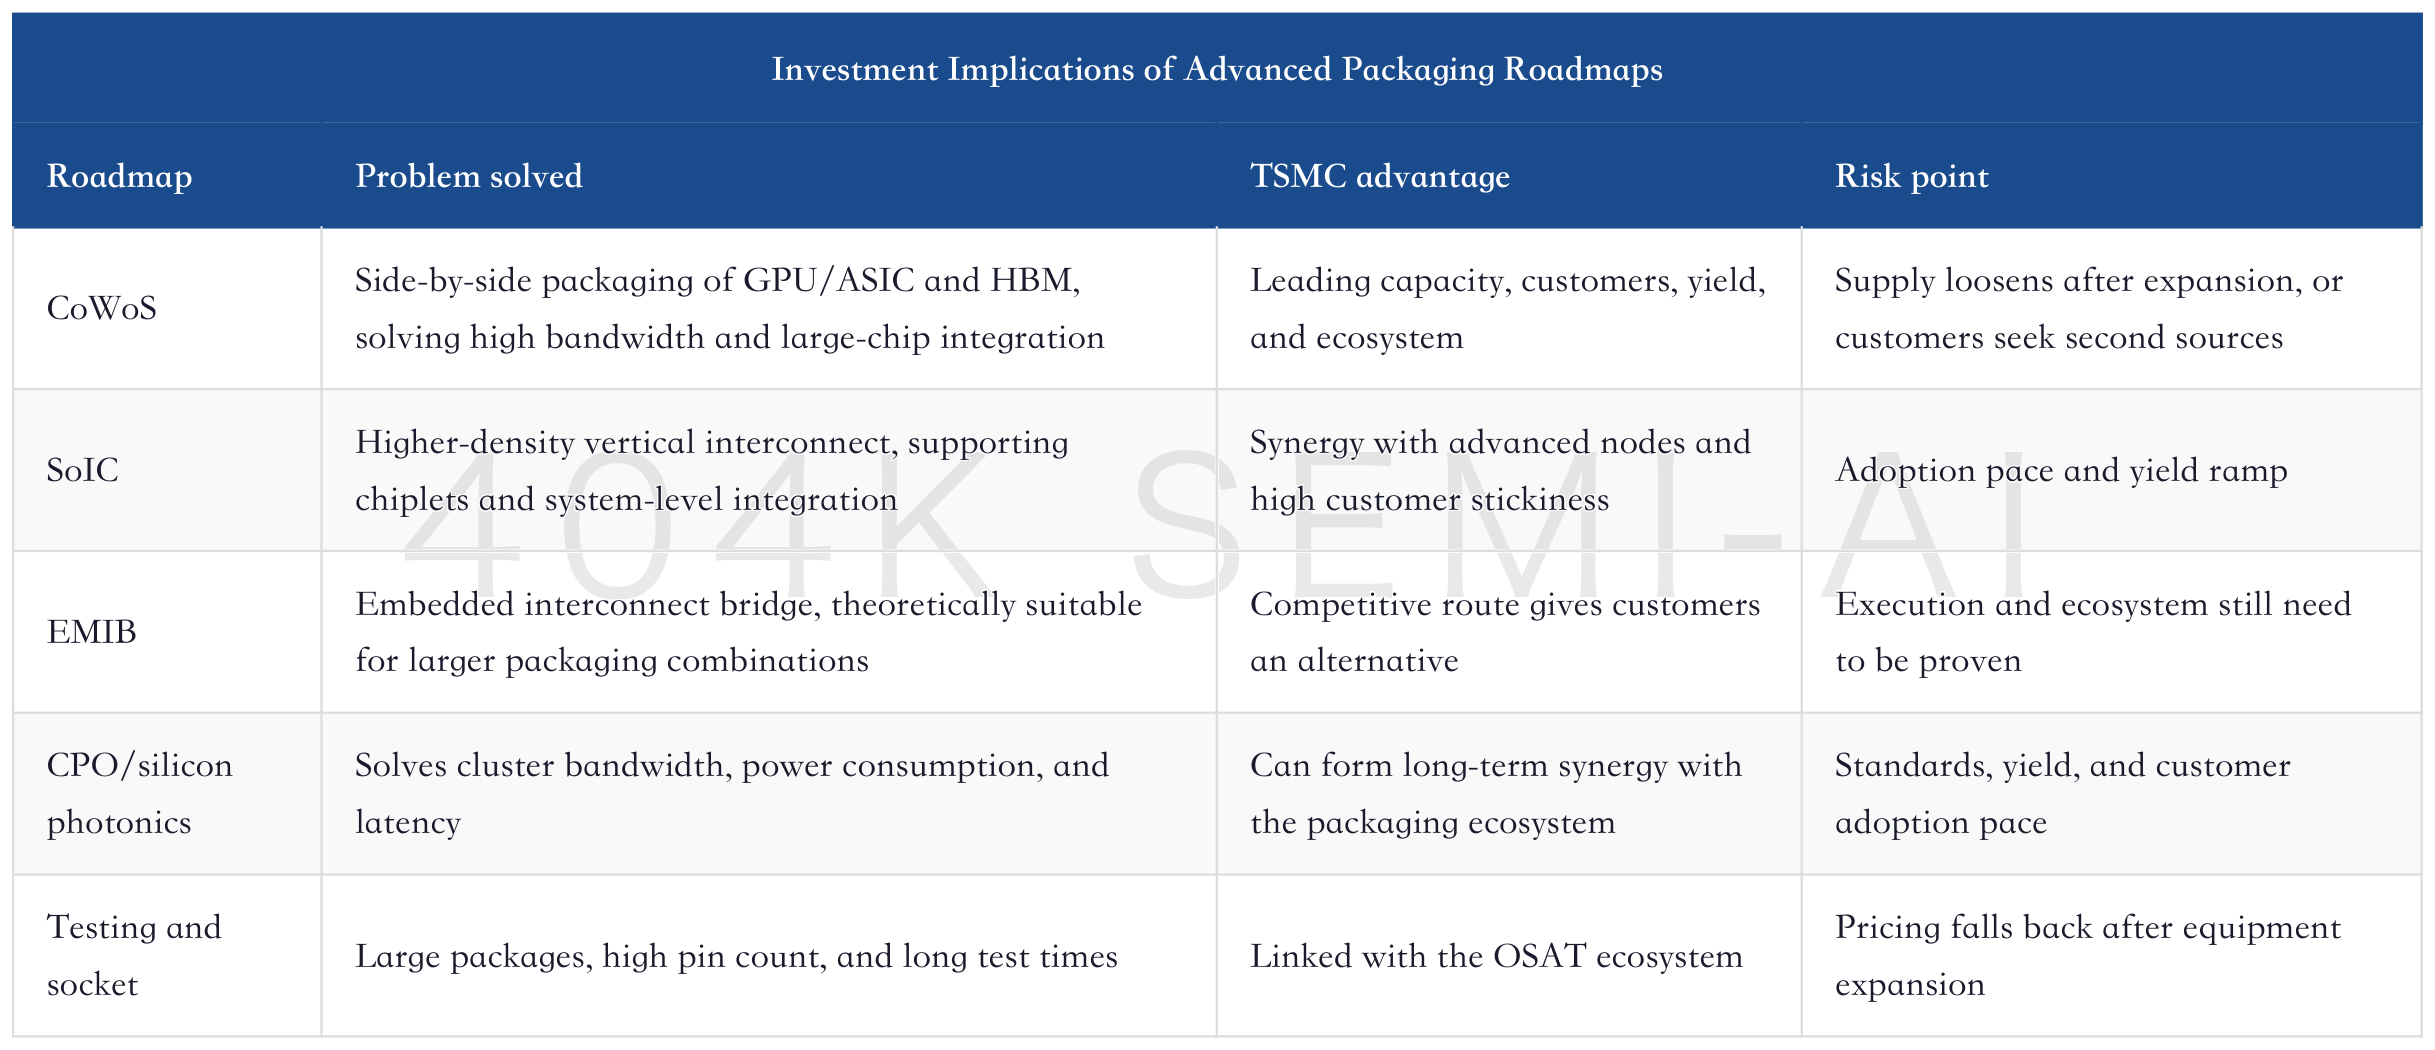
There is another easily overlooked aspect of advanced-packaging competition: it will change profit distribution. In the past, advanced nodes were mainly charged by wafer pricing, while customers earned higher profits in design and systems. After entering CoWoS and SoIC, TSMC is participating in solutions to more system constraints, and its charging base is expanding from individual wafers to system-level capacity. The tighter packaging is, the easier it is for TSMC to turn customers’ launch windows into pricing power.
This is also why CPO and optical interconnect should be placed in the same framework. There is still disagreement over whether CPO will quickly enter large-scale volume production, but the bandwidth and power pressures of AI clusters are already clear. Optical interconnect, silicon photonics, FAU, packaging testing, and high-end materials will gradually move closer to the chip-packaging layer. TSMC may not earn the most money directly in every optical segment, but it will strengthen its platform position as system complexity rises.
XV. Sell-Side Disagreement: Bulls Buy the Bottleneck; Cautious Investors Watch Returns
This Morgan Stanley report is optimistic, but optimism does not mean there is no disagreement. The core debate in AI semiconductors today can be broken into four layers: demand, supply, margin, and valuation. Bulls believe cloud CapEx is still being revised upward and bottleneck links will continue to gain pricing power. Cautious investors worry that CapEx-to-EBITDA is too high and that customers will eventually pass budget pressure down to the supply chain.
The demand debate comes from cloud-vendor returns. As long as AI application revenue, inference call volume, and enterprise deployment speed can keep up, cloud vendors will continue increasing investment in GPUs, ASICs, and CPUs. If AI revenue is realized slowly, capital markets will demand that cloud vendors reduce CapEx. TSMC benefits from multi-customer production schedules when demand is strong, but when demand is weak, the same group of customers will also pressure pricing in sync.
The supply debate comes from advanced packaging. CoWoS is tight today, but expansion is moving quickly. If 200kwpm of capacity is fully absorbed by Nvidia, AMD, Google, AWS, and other customers, the packaging chain will continue to raise prices. If ASIC projects are delayed, GPU transition timing slows, or customer inventory rises, the packaging chain will move from the strongest bottleneck to the biggest expectation gap.
The margin debate comes from depreciation. Advanced nodes and overseas capacity construction will keep pushing depreciation higher. Bulls believe price increases, yield, and high utilization can offset depreciation. Cautious investors will watch whether high gross margins begin to loosen. Once the gross-margin defense line moves down, TSMC’s valuation will shift back from a growth bottleneck asset to a manufacturing asset.
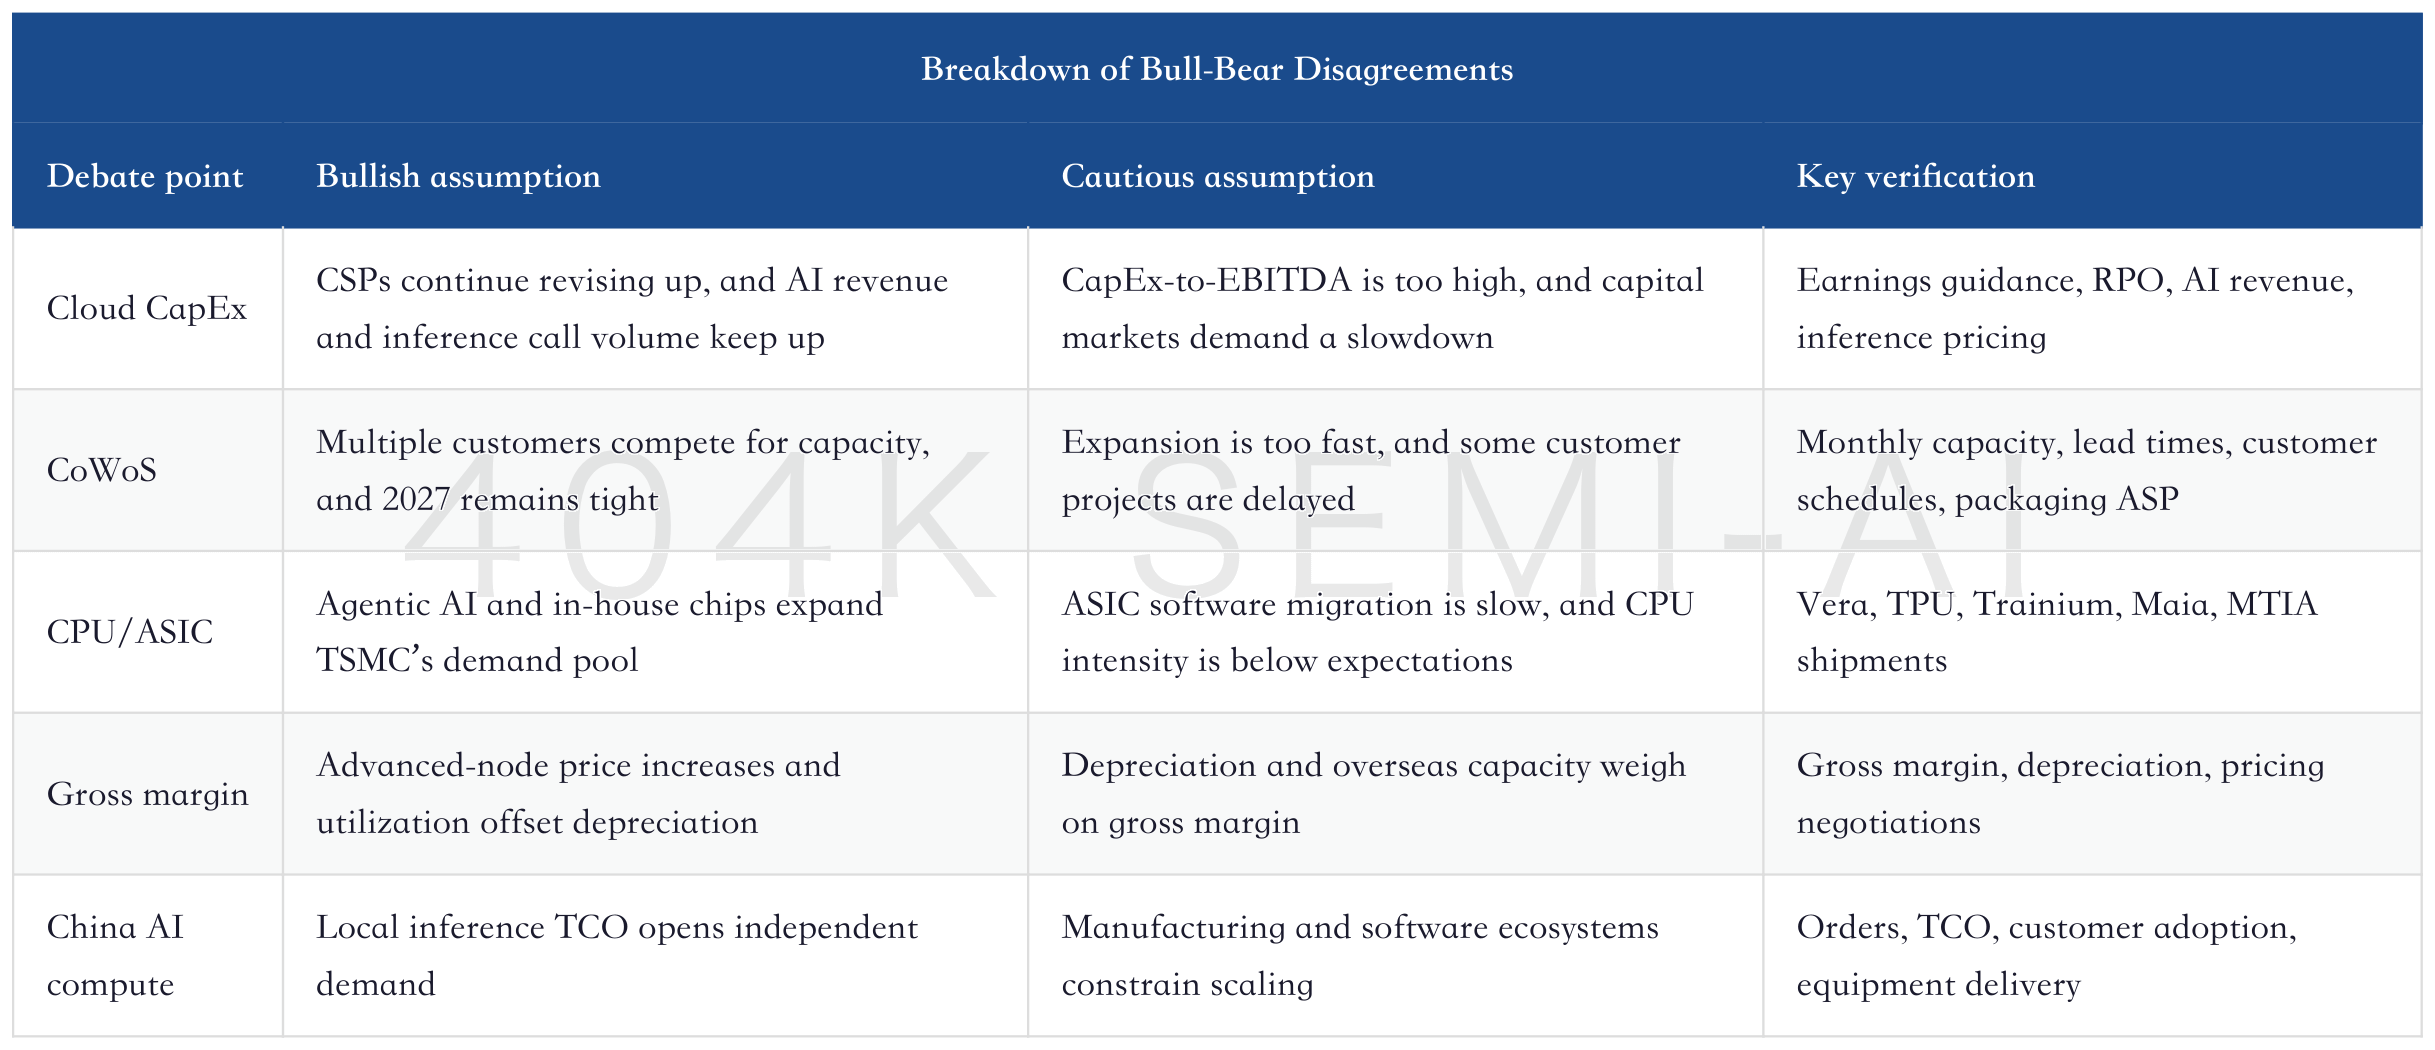
My view is moderately optimistic, leaning toward the middle. AI semiconductor demand remains resilient, especially as cloud vendors have already incorporated GPUs, CPUs, ASICs, networking, power, and storage into one infrastructure buildout. TSMC remains the clearest upstream bottleneck asset. But from a trading-rhythm perspective, the market will increasingly reward pure forward TAM less, and reward orders, pricing, and cash flow more. TSMC can remain in the first tier because it has the ability to deliver these metrics simultaneously.
XVI. Portfolio Implications: Look for Second-Order Elasticity Along TSMC’s Capacity Map
If this report is converted into portfolio thinking, the first step is to look for second-order elasticity along TSMC’s capacity map, rather than placing equal bets across all AI semiconductor companies. TSMC determines the supply cadence for advanced nodes and advanced packaging; customers determine who gets capacity first. The most valuable second-order assets often sit at the intersection of confirmed customer orders, still-tight capacity, and pricing that can be passed through.
The first source of second-order elasticity is packaging and testing. CoWoS expansion requires supporting capacity in packaging equipment, testing, sockets, probe cards, burn-in, and high-end materials. AI chips are becoming larger, test times are becoming longer, and packaging yield and test efficiency will affect actual customer deliveries. The elasticity in names such as King Yuan Electronics, ASE Technology Holding, WinWay Technology, MPI, Gudeng, and ASMPT comes from rising complexity, not merely beta to the AI theme.
The second source of second-order elasticity is ASIC design and production services. The Google TPU, AWS Trainium, Microsoft Maia, and Meta MTIA projects listed by Morgan Stanley all require design services, IP, packaging coordination, and TSMC advanced-node scheduling behind the scenes. Whether companies such as Broadcom, MediaTek, Global Unichip, and Alchip can continue to benefit depends on whether CSP in-house chips enter continuous generations, rather than remaining one-off projects.
The third source of second-order elasticity is memory and materials. HBM is the most visible constraint, but NAND, NOR, DDR4, ABF, T-Glass, and high-end CCL will also be affected by AI prioritization. Morgan Stanley mentions AI’s crowding-out effect on non-AI semiconductors. This matters for materials and memory companies: when AI customers receive priority access to resources, non-AI customers face rising costs and longer lead times, and price increases may spill over into more subsegments.
The fourth source of second-order elasticity is optical interconnect. The timing of CPO remains debated, but bandwidth constraints in AI clusters are already very clear. In the near term, 800G/1.6T, silicon photonics, FAU, and high-end connectivity are easier to monetize; in the medium term, the key question is whether CPO and co-packaged optics enter mainstream rack architectures. Trading the optical-interconnect chain should focus less on concepts and more on customer qualification, yield, delivery, and gross margin.
The fifth source of second-order elasticity is China AI compute. The advantage of domestic Chinese chips is not single-card performance, but TCO, supply security, and local deployment in specific inference scenarios. For Cambricon, Moore Threads, Iluvatar CoreX, Hygon, and the domestic equipment chain, investment validation should begin with orders, then move to customer utilization, inference cost, software adaptation, and manufacturing capability. As long as these indicators do not improve together, valuations can easily remain stuck in thematic trading.
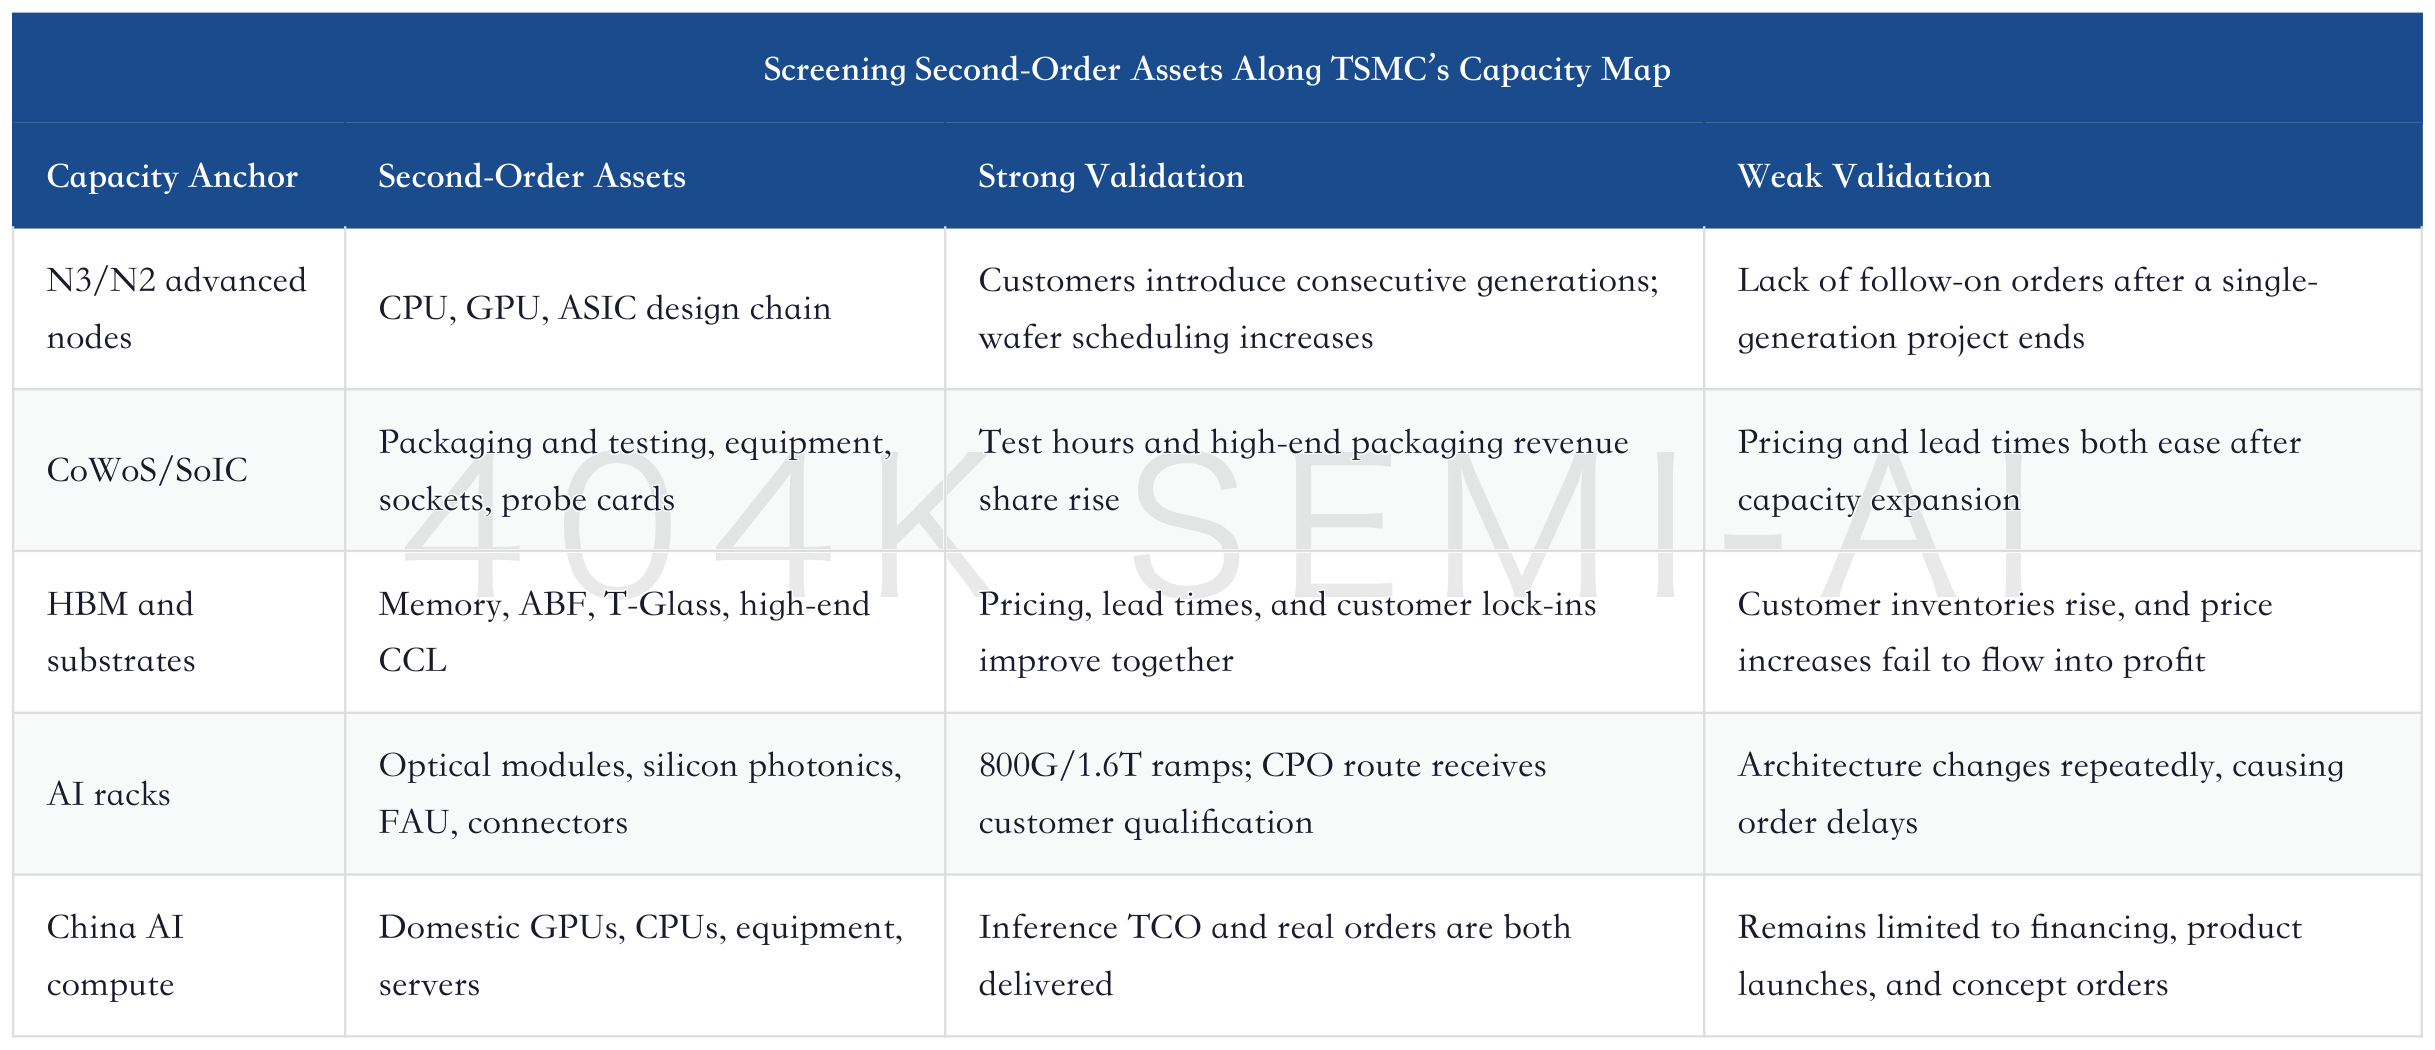
In terms of portfolio cadence, TSMC can be treated as the “core anchor,” while packaging and testing, ASICs, HBM materials, optical interconnect, and China AI compute can be treated as the “elasticity layer.” The core anchor confirms that the AI semiconductor cycle has not broken; the elasticity layer captures profit redistribution. If TSMC’s gross margin, CoWoS capacity, and cloud CapEx are all strong at the same time, the elasticity layer will continue to broaden. If TSMC itself starts to be pressured by depreciation and utilization, the elasticity layer will come under pressure first.
This framework has another benefit: it helps avoid simply chasing the hottest segment. From time to time, the market shifts its focus from GPUs to HBM, then to PCBs, optical modules, CPO, CPUs, or ASICs. The truly sustainable opportunities are not in the hottest label of the day, but in the resources that are becoming increasingly difficult to secure on TSMC’s capacity map. Those who can secure resources, and convert them into revenue and gross margin, are the ones worth continuing to track.
XVII. Three Common Misreadings: Demand, Substitution, and Expansion
When reading this report, three misreadings are most likely. The first is to interpret Morgan Stanley’s optimism as “infinite AI demand.” What the report is really saying is that demand remains strong, but each layer of demand must ultimately land against resource constraints. Cloud CapEx is still being revised upward, AI servers are still shipping, and GPUs, CPUs, ASICs, and HBM are all consuming capacity. But these demands ultimately have to pass through power, wafers, packaging, memory, substrates, testing, and customer budgets. Morgan Stanley is optimistic about the pricing power of bottleneck segments, not about all AI assets rising indiscriminately.
The second misreading is to view ASICs as a replacement trade for Nvidia. ASICs are better understood as proprietary tools for cloud vendors to control costs and supply chains. Nvidia continues to address demand for the most general-purpose, strongest-ecosystem, highest-performance accelerators; ASICs address specific workloads, scaled inference, and cloud vendors’ internal optimization. For TSMC, it is better for both lines to run in parallel, because the more customers there are, the more dispersed N3/N2 and CoWoS scheduling becomes, and the more stable TSMC’s negotiating position with customers becomes.
The third misreading is to view capacity expansion directly as profit. Capacity expansion only solves supply; profit depends on pricing, utilization, yield, and depreciation. CoWoS moving from bottleneck to expansion and then potentially to periodic easing is a process seen in any semiconductor capex cycle. What investors need to verify is whether customer orders during the expansion window are long enough, whether pricing is strong enough, and whether TSMC can turn advanced packaging into a long-term service rather than a one-time capacity shortage.
Behind these three misreadings is actually the same issue: AI semiconductors have moved from thematic trading into return-on-assets trading. Thematic trading asks whether the story can continue. Return-on-assets trading asks whether every dollar of CapEx, every wafer, every CoWoS wafer, and every hour of testing can turn into revenue and gross margin. TSMC remains the best entry point because it touches almost every AI compute route at the same time, but a clear entry point does not mean valuation has no constraints.
Another misreading to guard against is viewing China AI compute only as sanction substitution. Morgan Stanley’s analysis of China AI compute is closer to a systems-engineering perspective: weaker single-chip performance can be offset with more dies, larger racks, and stronger infrastructure; lower prices can be used to compete for inference scenarios through TCO and cost per token; manufacturing constraints can be gradually addressed through domestic wafers, packaging and testing, and equipment. The investment opportunity here must return to whether customers are willing to deploy at real scale, rather than betting only on the phrase “domestic substitution.”
Once these misreadings are removed, the remaining investment questions become clearer. Whether TSMC can continue to hold pricing power depends on whether multi-customer scheduling remains tight. Whether CPUs and ASICs can unlock second-order elasticity depends on whether agentic AI and cloud in-house chips form continuous generations. Whether HBM, ABF, and testing can continue to raise prices depends on whether physical bottlenecks have been locked in by customers in advance. Whether China AI compute can be re-rated depends on inference cost and order delivery. Each line can be tracked; there is no need to rely only on sentiment.
XVIII. Conclusion: What Morgan Stanley Sees Is a Reallocation of the AI Compute Bill
The most valuable part of this Morgan Stanley report is that it breaks AI semiconductors down from one demand story into multiple bills. TSMC captures the advanced-node and packaging bill; Nvidia continues to capture the GPU bill; cloud vendors’ in-house ASICs capture the cost-optimization bill; CPUs capture the agentic AI scheduling bill; HBM, ABF, testing, and optical interconnect capture the physical-bottleneck bill; and China AI compute captures the local-supply and inference-TCO bill.
In trading terms, the clearest direction remains TSMC. It sits at the intersection of N3/N2, CoWoS, SoIC, AI GPUs, CPUs, ASICs, and global cloud CapEx. Morgan Stanley’s US$75 billion CapEx estimate and 200kwpm CoWoS capacity indicate that TSMC is preparing for a larger AI system bill after 2027.
Risks must also be placed in the same table. More CapEx is not always better, and CoWoS will not remain in shortage forever. In the second half of 2026 and in 2027, the market will audit the numbers through gross margin, pricing, customer scheduling, HBM supply, cloud CapEx returns, and China AI orders. Segments that can deliver orders, pricing, and cash flow will continue to benefit from AI hardware diffusion; segments left only with long-term TAM will be filtered out first by valuation compression.
The AI trade has not ebbed; what has ebbed is the phase of buying single-factor momentum. The next phase looks more like a hard ledger: who controls advanced nodes, who gets CoWoS, who gets HBM, who shortens testing and delivery, and who brings down inference cost. TSMC is the first line of this ledger, but not the only line. The real opportunity lies in following TSMC’s capacity allocation to find the bottleneck assets that can keep collecting revenue from the rising complexity of AI systems.TSMC CoWoS Deep Dive: 200kwpm Packaging, US$75bn CapEx, and Redistribution Across CPU, GPU, ASIC, and Optical Interconnect
目录
TL;DR
1. Core View of This Report: AI Semis Are Moving From a Demand Story to Bottleneck Pricing
II. TSMC: Pricing Power in Both Advanced Process and Packaging
III. CoWoS: The Real Congestion Point in 2027
IV. CPU Comeback: Agentic AI Makes the “Scheduling Chip” Valuable Again
V. ASIC Proliferation: Cloud Vendors’ In-House Chips Are Not the Opposite of NVIDIA
VI. HBM, ABF, and Testing: The Physical Ledger of AI Systems Thickens
VII. Optical Interconnects: CPO Debate Cannot Stop the Bandwidth Bill
VIII. China AI Compute: Using Systems Engineering to Offset the Single-Chip Gap
IX. Investment Ranking: Buy Bottlenecks, Buy Validation, Buy Fewer Long-Dated Slogans
X. Scenario Framework: Three AI Semiconductor Worldviews
XI. Follow-Up Tracking: Four Tables Will Decide How Far This Trade Can Go
XII. TSMC Profile: What It Sells Is AI Capacity With Delivery Certainty
XIII. CapEx Return Check: $75 Billion Is Not a Capacity-Expansion Slogan
XIV. Advanced Packaging Competition: CoWoS, SoIC, EMIB, and Optical Interconnect Are Not Isolated Technologies
XV. Sell-Side Disagreement: Bulls Buy the Bottleneck; Cautious Investors Watch Returns
XVI. Portfolio Implications: Look for Second-Order Elasticity Along TSMC’s Capacity Map
XVII. Three Common Misreadings: Demand, Substitution, and Expansion
XVIII. Conclusion: What Morgan Stanley Sees Is a Reallocation of the AI Compute Bill
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
The next validation point for the AI semiconductor trade lies in TSMC’s advanced-node and CoWoS capacity. Morgan Stanley’s answer is direct: cloud vendors are still raising CapEx, while the value chain is broadening from a single GPU focus to CPUs, ASICs, HBM, optical interconnect, and China AI compute. This will determine earnings and valuation elasticity in 2026-2027.
TL;DR
TSMC remains the bottleneck asset for AI compute. Morgan Stanley positions TSMC as the “only game in town,” citing simultaneous tightness in advanced nodes, EUV supply, and advanced packaging capacity. CapEx, CoWoS, and advanced-node pricing form the core anchors of this trade. Whether gross margin can stay elevated is the key test of TSMC’s transition from manufacturing expansion to bottleneck pricing.
GPU demand remains, but the trade is broadening. Morgan Stanley expects 2027 CapEx for the top 14 listed global cloud vendors to approach US$1.3tn, with the AI semiconductor TAM potentially rising from US$485bn in 2026E to US$753bn in 2030E. Nvidia still consumes the most CoWoS and HBM, but ASIC and CPU projects from AMD, Broadcom, AWS, Google, Microsoft, and Meta will allocate incremental value across wafers, packaging, HBM, testing, ABF, and optical interconnect.
CPUs are becoming part of the AI system bill again. Agentic AI pushes inference from “answering questions” to “executing tasks,” increasing CPU:GPU intensity in clusters. Morgan Stanley raises its base-case TAM for orchestration CPUs to US$79bn, with a bull case of US$238bn, and highlights the value of Vera CPU performance, memory connectivity, and cluster scheduling. This theme will influence valuation anchors for Arm, Nvidia, AMD, custom CPUs, testing, and advanced packaging.
ASICs and HBM determine the pace of second-stage diffusion. Cloud vendors will not abandon in-house chips just because Nvidia GPUs are powerful. Google TPU, AWS Trainium, Microsoft Maia, and Meta MTIA are all competing for TSMC advanced nodes, CoWoS, HBM, and ABF resources. Morgan Stanley estimates 2027 AI computing wafer consumption at more than US$46bn and HBM demand at about 50,609 mn Gb. The supply-chain bottleneck is not in a single chip, but in simultaneous scheduling constraints across multiple stages.
Optical interconnect becomes mandatory once clusters scale. The report groups CPO, larger package sizes, test equipment, and high-pin-count sockets into the same supply-constraint framework, indicating that AI compute competition has moved from chip level to rack and cluster level. Even if the CPO rollout pace remains uneven, optical modules, silicon photonics, FAU, packaging and testing, and high-end connectors should continue to rise with rack power, bandwidth, and latency requirements.
China AI compute is following an efficiency and domestic-supply path. Morgan Stanley expects China’s AI GPU TAM to grow to US$91bn by 2030E and China’s CPU TAM to reach US$42bn by 2030E, and lists Cambricon, Moore Threads, and Iluvatar CoreX as domestic AI accelerator names to watch. Key variables are inference TCO, cost per token, order execution, domestic wafer and packaging/testing capacity, and cluster-architecture compensation under export-control constraints.
The biggest risk is CapEx return validation. The trade will not stop at “AI is still strong.” Capital will ask whether US$75bn of CapEx can translate into profit, cash flow, and pricing power. Four numbers need to be tracked: TSMC’s CoWoS monthly capacity ramp, 2nm/N3 tool installation and utilization, cloud-vendor CapEx-to-EBITDA, and whether advanced packaging and HBM delivery delays are dragging on customer shipments. If these numbers weaken, AI semis will shift first from valuation expansion to earnings delivery.
1. Core View of This Report: AI Semis Are Moving From a Demand Story to Bottleneck Pricing
Morgan Stanley’s industry call is strong. The title uses “Strong AI Semi Outlook,” and the industry view remains Attractive. The underlying logic is not complicated: cloud vendors continue to spend, AI servers continue to consume chips, and TSMC, advanced packaging, HBM, testing, and China domestic compute still have expansion curves ahead.
More importantly, Morgan Stanley breaks apart the trading framework for AI semiconductors in this report. In the prior phase, the market mainly bought GPU shipments and the Nvidia supply chain. In the new phase, investors need to examine how money is redistributed within AI systems: who can raise wafer prices, who can secure CoWoS, how much budget ASICs and CPUs will take, whether HBM and ABF face physical shortages, when optical interconnect moves from expectation to orders, and whether China domestic compute can use system engineering to offset single-chip gaps.
Morgan Stanley’s stock-selection table also reflects this shift. It divides overweight areas into AI, memory, China AI/semiconductor equipment, test equipment, and mature nodes. The AI group includes MediaTek, TSMC, SMIC, Aspeed, Alchip, King Yuan Electronics, ASE Technology Holding, Global Unichip, ASMPT, AllRing, and GUC; the memory group includes Macronix, AP Memory, Nanya Technology, Winbond, and GigaDevice; China AI and equipment includes Iluvatar CoreX, Cambricon, NAURA Technology, AMEC, and USI.
This shows that Morgan Stanley’s core view is to “buy the full bottleneck stack of AI compute.” If cloud-vendor CapEx continues to be revised upward, profits will first settle in the scarcest areas: advanced nodes, advanced packaging, HBM, testing, materials, and the few companies able to enter China’s domestic compute closed loop. If CapEx return pressure rises, the first segments screened out will be those that only discuss long-term TAM without near-term orders or delivery capability.
This table summarizes Morgan Stanley’s real message: AI demand is not over, but the trade has shifted from “whether demand exists” to “where the bottlenecks are, whether prices can rise, and how CapEx returns should be calculated.” TSMC sits at the very upstream end, so its valuation should not be based only on next-quarter revenue, but on how much bottleneck rent the full system can retain after 2027.
II. TSMC: Pricing Power in Both Advanced Process and Packaging
TSMC is the axis of this report. Morgan Stanley forecasts TSMC’s 2026/2027E CapEx at US$56 billion and US$75 billion, a systematic step-up around N2/N3, Arizona capacity, CoWoS, and SoIC.
TSMC’s pricing power comes from three places. First, it continues to lead in advanced process nodes, while tight EUV supply leaves customers with few alternatives. Second, 2nm demand is strong; the report notes that N2 capacity could achieve a 70% CAGR over 2026-2028E. Third, advanced packaging is no longer a back-end service, but the entry ticket for whether AI chips can ship.
Morgan Stanley’s valuation anchor for TSMC is strong. The target price, P/E, and EPS growth are clearer in table form. The key point is that the market views TSMC as a high-growth bottleneck asset, provided it can deliver advanced-node expansion, packaging expansion, and gross-margin defense at the same time.
Full transcript of TSMC’s 2026 shareholder meeting: AI demand, capital expenditure, advanced process nodes, and global capacity layout
TSMC’s risks are also here. As CapEx jumps from US$56 billion to US$75 billion, depreciation pressure will not disappear. Morgan Stanley believes 60% gross margin should become the floor, implicitly assuming that advanced-node price increases and high utilization can offset depreciation. If cloud vendors begin cutting AI capital expenditure after 2027, or if customers spread orders across different packaging paths, TSMC’s valuation could shift from a “bottleneck premium” back to “high-CapEx manufacturing.”
In the near term, however, Morgan Stanley’s evidence is positive. Logic foundry utilization is expected to reach 80% in 2H26, 2nm demand is strong, N5 declines in 2027 while N3 continues to rise, and AI semiconductor revenue could exceed 30% of total revenue in 2026E, with a chance to approach 60% by 2029E. TSMC is moving from an “advanced foundry” to an “AI system capacity allocation center.”
III. CoWoS: The Real Congestion Point in 2027
CoWoS is the most important trading variable in this report. Morgan Stanley expects sustained AI demand could push TSMC to expand CoWoS capacity to 200kwpm in 2027. That number implies multiple customers competing for the same scarce resource in 2027.
The report infers CoWoS demand from public power deployment data. Nvidia Vera Rubin NVL144, AMD Helios, Broadcom TPU, and AWS Trainium3 UltraServers all require advanced packaging resources. Based on lifecycle CoWoS usage, Nvidia requires around 409k wafers, AMD around 166k wafers, Broadcom around 260k wafers, and AWS around 118k wafers. Converted into 2027 annual CoWoS demand, the figures are around 136k, 55k, 52k, and 15k wafers, respectively.
These figures dismantle a common market misconception. The CoWoS supply-demand table is jointly determined by Nvidia, AMD, Google/Broadcom, AWS, and other CSPs. GPUs are the strongest driver, but ASICs are starting to create real capacity occupation. CPUs do not necessarily use HBM, but they do consume advanced process and some packaging capacity. HBM supply will also feed back into and constrain the shipment cadence of GPUs and ASICs.
CoWoS also has a technology-level competition issue. Morgan Stanley compares TSMC’s CoWoS with Intel’s EMIB: TSMC’s CoWoS-S can support larger silicon interposers and multi-chip packaging, while Intel’s EMIB can theoretically also support a larger reticle count, provided supply-chain execution is strong enough. The investment implication of this comparison is to watch who can deliver at customer mass-production nodes.
If TSMC ramps CoWoS toward 200kwpm, the benefits will not remain only at TSMC. Substrates, wafer testing, packaging equipment, sockets, probe cards, materials, and automation equipment will all become assets that “move with CoWoS expansion.” Morgan Stanley puts King Yuan Electronics, ASE Technology Holding, FOCI, ASMPT, WinWay Technology, MPI, Gudeng, and AllRing in its focus list because rising AI chip complexity will lengthen test time, increase pin counts, and push up demand for burn-in and high-end components.
IV. CPU Comeback: Agentic AI Makes the “Scheduling Chip” Valuable Again
CPU is the most easily underestimated part of this report. The market is used to equating AI compute with GPUs, but Agentic AI moves the system from “model inference” to “task execution.” Large amounts of orchestration, retrieval, tool calling, environment-state management, and concurrent tasks consume CPU resources. Morgan Stanley raised its base-case TAM for orchestration CPUs to US$79bn, while the bull case reaches US$238bn.
The Crazy CPU: From Supporting Role Back to Center Stage — A 40,000-Word Panorama of the New Compute Bottleneck in the AI Agent Era
This line is critical for TSMC. The CPU comeback does not mean GPUs exit the stage; it means the heterogeneous-computing bill inside AI clusters becomes larger. NVIDIA’s Vera CPU, AMD’s Venice CPU, Google CPUs, and various custom CPUs will increase advanced-node demand and extend TSMC from the GPU supply chain into the CPU orchestration layer. Morgan Stanley emphasizes that Vera CPU performance can reach 1.8x that of the highest-performance x86 CPU. This shows NVIDIA is not satisfied with selling GPUs; it is bringing CPUs into the AI system control plane.
The investment implications of CPUs have three layers. First, Arm licensing and ecosystem value rise, because cloud vendors and accelerator vendors need high-efficiency CPUs. Second, advanced-node demand becomes more distributed, because CPUs, GPUs, and ASICs all compete for N3/N2. Third, testing and packaging revenue becomes more stable, because CPUs, GPUs, and ASICs together increase test hours and complexity.
The risk to the CPU line is at the application layer. If Agentic AI remains limited to demos and small-scale workflows, CPU intensity will not rise as in the bull case. Conversely, if enterprises start putting AI agents into customer service, software engineering, data analysis, internal operations, and automation processes, CPUs will shift from “something already inside the server” to “the control cost of the inference economy.” This is why Morgan Stanley separates CPUs out.
V. ASIC Proliferation: Cloud Vendors’ In-House Chips Are Not the Opposite of NVIDIA
The core judgment on ASICs is straightforward: cloud vendors still need in-house chips. The stronger NVIDIA GPUs become, the greater the incentive for cloud vendors to migrate some mature workloads to in-house ASICs, for reasons including cost, supply, energy efficiency, software-stack control, and bargaining power.
Deep Dive Into Broadcom Earnings: AI Custom Chips Enter Delivery-Validation Phase; How Data-Center ASICs and High-Speed Interconnects Should Be Revalued for FY2027
The projects Morgan Stanley lists are no longer concepts. Google TPU v7p, v8i, v8t, and v9, AWS Trainium 3, Microsoft Maia 300, and Meta MTIA 3 all correspond to 2027 CoWoS and advanced-node demand. Google TPU v8i corresponds to roughly 330k CoWoS wafers, TPU v8t to roughly 180k, and AWS Trainium 3 to roughly 140k. Together, they will bring a second growth curve to TSMC, MediaTek, Broadcom, GUC, Alchip, ABF, HBM, and testing.
ASICs have a major impact on the investment framework. GPU trades track NVIDIA production allocation; ASIC trades track CSP project cadence, yield, and software migration. The GPU supply chain is more concentrated, while the ASIC supply chain is more distributed. TSMC’s most comfortable position is this: whether customers buy NVIDIA, AMD, or choose Google TPU, AWS Trainium, Microsoft Maia, or Meta MTIA, as long as advanced nodes and CoWoS remain within the TSMC system, TSMC can collect upstream capacity rent.
ASIC is not a single-line narrative of “replacing NVIDIA.” A better interpretation is that once AI workloads multiply, cloud vendors will allocate different models, different inference tasks, and different cost targets to different chips. NVIDIA continues to capture high-performance general-purpose demand; in-house ASICs capture scaled and cost-optimized demand; TSMC captures advanced-node and packaging demand on both sides.
VI. HBM, ABF, and Testing: The Physical Ledger of AI Systems Thickens
Morgan Stanley estimates 2027 HBM demand at roughly 50,609 mn Gb, with NVIDIA still consuming the largest share of HBM supply. Rubin R200 uses HBM4 12hi, Rubin Ultra uses HBM4e 12hi, and AMD MI400 and MI500 will also drive HBM4/HBM4e. On the ASIC side, TPU, Trainium, Maia, and MTIA also consume HBM. HBM has moved beyond a standalone memory-cycle story and become a hard constraint on whether AI systems can be delivered on time.
The Second Engine of the Memory Supercycle: CPU Comeback, HBM Spillover, and the US$1.7tn TAM Revaluation
ABF and T-Glass are also on the same physical ledger. Morgan Stanley mentions AI’s crowding-out effect on non-AI semiconductors, such as T-Glass and memory shortages. This wording is important because AI semiconductors have expanded from “advanced-chip price increases” into pressure on materials, substrates, memory, packaging, and testing resources. Non-AI semiconductors may face rising costs and lower capacity priority in 2026.
The changes in testing also deserve separate attention. AI/HPC chips require higher pin counts, larger package sizes, and longer test times. Morgan Stanley expects the test-equipment market to post a 2024-2027E CAGR of roughly 35%, and uses KYEC to show how testing demand for AI GPUs, TPUs, and CPUs pushes up the revenue mix. AI revenue from KYEC’s largest customer as a share of KYEC MSe revenue is expected to rise from 23% in 2025 to 34% in 2026E and 40% in 2027E.
ABF Substrate Deep-Dive Update: 25% Shortfall by 2030, BT Price Increases of 20-30%, and AI ASIC Proliferation; Which of Unimicron, Nan Ya PCB, and Zhen Ding Can Deliver Best
The investment conclusion from this section is: the second phase of AI semiconductors will look more like a “systems-engineering supply chain,” not just a question of chip-company revenue. The closer a segment is to the physical bottleneck, and the better it can convert price increases into profit, the more durable its valuation. Segments that rise only with the theme but lack validation from lead times, price increases, revenue mix, and customer orders are more likely to see valuations cut when CapEx return pressure appears.
VII. Optical Interconnects: CPO Debate Cannot Stop the Bandwidth Bill
Morgan Stanley places CPO inside AI semiconductor solutions, alongside Moore’s Law, CoWoS/SoIC, HBM, custom chips, and GaN HVDC 800V. That acknowledges one fact: the larger AI clusters become, the thicker the bandwidth bill gets across chips, boards, racks, and data centers.
CPO Bull-Case Expectations Cool: Architecture Debate Cannot Stop Optical Incremental Demand as AI Clusters Enter the Optical Interconnect Era
The trading difficulty in CPO is timing. The market can repeatedly debate “when CPO will be deployed at scale,” but Morgan Stanley’s framework is better split into three layers. The first layer is traditional pluggable optical modules continuing to upgrade with bandwidth. The second is silicon photonics, FAU, and optical components moving closer inside the rack. The third is CPO and co-packaged optics entering deeper chip-packaging systems.
For TSMC, optical interconnects and CoWoS are not two fully separate tracks. Large-format packaging, SoIC, silicon photonics, test equipment, and high-end connectivity are all solving the same problem: AI cluster constraints in power, latency, and bandwidth. As long as GPUs, ASICs, and CPUs continue raising system-level throughput, optical interconnects will move from “conceptual optionality” to “part of the total bill.”
Optical interconnects will move onto the same agenda as CoWoS and rack power consumption. Morgan Stanley putting advanced packaging and optics in the same update itself shows that investors need to assess “can the chip be built” and “can the cluster be connected” together.
VIII. China AI Compute: Using Systems Engineering to Offset the Single-Chip Gap
China AI compute is the second major focus of this report. Morgan Stanley expects China’s AI GPU TAM to grow to US$91 billion by 2030E, and China’s CPU TAM to rise to US$42 billion by 2030E. This view rests on several realities: rising inference demand, more domestic cloud and model applications, lower prices for onshore AI chips, and system clusters that can use more chips, larger racks, and stronger infrastructure to offset the single-chip gap.
The report’s framework is clear: if a single compute die is not strong enough, package more dies into one chip; if a single chip is not strong enough, build larger racks and clusters; if a single foundry’s capacity is insufficient, expand manufacturing capability. This is a classic systems-engineering route. Its weaknesses are efficiency, power consumption, and software adaptation. Its strengths are a more controllable supply chain, lower prices, and deployment closer to domestic demand.
Morgan Stanley also compares the TCO and per-token cost of onshore chips in inference scenarios, with a broadly positive conclusion: because domestic chips are significantly cheaper, they can provide competitive unit costs in some China large-model inference scenarios. The key is whether customers can accept the all-in cost, with variables including DeepSeek-type models, specific batch sizes, the number of active MoE experts, and domestic deployment conditions.
Morgan Stanley mentions “10 Dragons” among China’s AI GPGPU vendors, with particular focus on Cambricon, Moore Threads, and Iluvatar CoreX; Hygon is the representative CPU+GPU integrated platform. This line is better validated through orders and TCO than through valuation optionality alone. Only companies that can enter real cloud-vendor orders, deliver stable inference costs, and secure domestic manufacturing and packaging/test resources can move from theme stocks to supply-chain assets.
China AI compute will also feed back into the TSMC narrative. On one hand, the stronger domestic compute becomes, the less certain it is that part of China’s demand will fully flow to overseas GPUs. On the other hand, demand for domestic equipment, wafers, packaging/test, servers, and materials will be pushed higher. For global investors, this line offers another set of supply constraints: a compute supply chain under export controls and domestic-substitution frameworks.
IX. Investment Ranking: Buy Bottlenecks, Buy Validation, Buy Fewer Long-Dated Slogans
The best framework in this report is to split AI semiconductors into three types of assets. The first is bottleneck assets, which can directly translate tight supply-demand into pricing and gross margins. The second is validation assets, where orders and revenue mix are being pulled by AI but still need quarterly delivery. The third is long-dated assets, where TAM is large but delivery, yield, customers, and cash flow have not yet been fully proven.
Representative bottleneck assets include TSMC, CoWoS/SoIC, HBM, advanced packaging equipment, high-end test, and some ABF/materials. Their advantage is that they sit closest to capacity constraints. Their risk is that CapEx and expansion cycles can loosen supply-demand at some stage. Validation assets include ASIC design services, cloud-vendor in-house chip supply chains, CPU scheduling chains, optical interconnects, and China’s domestic AI chips. They have greater upside, but each line must be tracked against orders, shipments, and customer qualification.
Rubin Rack Revaluation: GPU Share Falls to 51%, AI Hardware Value Is Shifting Toward Memory, PCB, Power, and Liquid Cooling. Who Is Capturing the New AI Hardware Increment?
This ranking also explains why semiconductor trading will shift from “momentum upgrades” to “cash-flow reconciliation.” When the market only looks at AI demand, every link can rise. When the market starts demanding CapEx returns, valuation will first remain with segments that can prove pricing, margins, and orders. TSMC remains in the first layer because it is closest to the bottleneck, but TSMC itself also has to face the same reconciliation. US$75 billion of CapEx is not a free lunch.
X. Scenario Framework: Three AI Semiconductor Worldviews
In the base case, cloud CapEx continues to grow, but investors begin to demand efficiency. TSMC’s N3/N2, CoWoS, and SoIC remain tight, and 5%-10% price increases for advanced nodes can partly offset depreciation, while AI semiconductor revenue continues to rise as a share of total revenue. GPUs remain the largest source of demand, while ASICs, CPUs, HBM, and optical interconnects take portions of incremental growth. This scenario is most favorable for TSMC, advanced packaging, HBM, testing, and ASIC design services.
In the bull case, agentic AI applications scale rapidly, and although cloud vendors’ CapEx-to-EBITDA remains high, revenue and inference call volume keep pace. The orchestration CPU TAM approaches Morgan Stanley’s bull case, while GPUs, ASICs, and CPUs simultaneously compete for N3/N2 and CoWoS capacity. HBM and ABF remain tight, and optical interconnect adoption accelerates. In this scenario, investment opportunities continue to spread from the Nvidia chain to CPUs, ASICs, testing, packaging equipment, and China’s domestic AI compute.
In the stress case, cloud vendor CapEx materializes ahead of revenue, and the market begins to penalize high depreciation and high capital spending. CoWoS capacity expansion outpaces customer demand, HBM pricing peaks, ASIC projects are delayed, and agentic AI applications fail to generate sufficient CPU intensity. In this scenario, theme stocks come under pressure first, while TSMC also shifts from being valued as a premium manufacturing platform back to a utilization and depreciation model. The only segments that can still withstand pressure are assets with strong customer lock-in, favorable pricing contracts, and visible cash flow.
Morgan Stanley’s report leans between the base and bull cases. It does not deny CapEx pressure; instead, it uses larger cloud CapEx, more customer projects, and a broader AI supply chain to explain why AI semiconductors still have upside. My interpretation is that this report is useful for correcting two extreme views: AI is not over, but AI semiconductors can no longer earn valuation support simply from saying “demand is strong.”
XI. Follow-Up Tracking: Four Tables Will Decide How Far This Trade Can Go
The first table is TSMC CapEx and gross margin. As long as 2027E CapEx of US$75 billion continues to be revised upward, the market will ask about depreciation, utilization, and pricing. TSMC must prove that it can simultaneously deliver advanced-node price increases, high CoWoS utilization, and defend a 60% gross margin line.
The second table is CoWoS monthly capacity and customer allocation. 200kwpm is the key anchor. The denominator is total capacity, and the numerator is production allocation for customers such as Nvidia, AMD, Google/Broadcom, AWS, Microsoft, and Meta. If customer allocation becomes more diversified, TSMC’s pricing power becomes more stable; if a major customer cuts orders, packaging utilization will immediately affect valuation.
The third table is cloud vendor CapEx-to-EBITDA. Morgan Stanley notes that CapEx-to-EBITDA for the top four CSPs has already exceeded 70%, which means the trade has entered a return-on-investment inspection phase. As long as AI revenue, inference call volume, and customer productization keep pace, capital markets will tolerate high CapEx. If revenue proof slows, the semiconductor supply chain will derate first.
The fourth table is order conversion for CPUs, ASICs, and optical interconnects. For CPUs, watch Vera, Venice, and Google CPU; for ASICs, watch TPU, Trainium, Maia, and MTIA; for optical interconnects, watch 800G/1.6T, silicon photonics, and CPO adoption. These determine whether AI hardware value can spread from GPUs into more segments.
XII. TSMC Profile: What It Sells Is AI Capacity With Delivery Certainty
TSMC’s corporate characteristics need to be stated clearly first. On the surface, it sells wafer foundry services; in practice, it sells manufacturing certainty that customers can verify, scale, and receive on time at advanced nodes. The AI cycle has amplified this feature, because GPUs, CPUs, ASICs, and high-bandwidth packaging cannot ship on design blueprints alone. Customers must simultaneously buy yield, process windows, packaging capacity, supply-chain coordination, and global capacity stability.
This is also what distinguishes TSMC from ordinary cyclical manufacturers. Ordinary manufacturers can easily fall into price competition after capacity expansion. For TSMC, expansion in advanced processes and advanced packaging instead reinforces customer dependence in the short term. The more customers there are, the more complex the chips become, the larger the packages get, and the tighter the launch windows are, the more valuable TSMC’s capacity allocation power becomes. Morgan Stanley calls it the “only game in town.” Behind that phrase is customer switching cost, not just process leadership.
TSMC’s revenue structure is also changing. Smartphones remain an important customer group, but high-performance computing and AI semiconductors are lifting the revenue slope. Morgan Stanley expects the revenue weight of AI semiconductors to rise rapidly, while advanced-node pricing still has room to move higher. This change creates two opposing forces: on one side, high-ASP nodes and advanced packaging improve revenue quality; on the other, massive CapEx, depreciation, and globalized capacity bring fixed-cost pressure.
TSMC’s greatest strength is that it concentrates customers’ roadmap choices onto itself. If Nvidia continues to expand GPUs, TSMC benefits; if AMD and Nvidia add CPUs, TSMC benefits; if Google, AWS, Microsoft, and Meta increase ASIC investment, TSMC still benefits; if HBM and advanced packaging become tighter, TSMC remains in a key position through CoWoS and SoIC. Customers may compete with one another, but together they increase TSMC’s manufacturing load.
TSMC’s greatest weakness also comes from the same logic. It must build capacity in advance to retain major customers and maintain node leadership; building capacity in advance means depreciation arrives first, while customer orders and pricing arrive later. If AI demand is revised upward, TSMC enjoys a bottleneck premium; if customer CapEx weakens, the market will first question TSMC’s return on assets. TSMC’s valuation therefore naturally has a dual character: in good times, it looks like a high-certainty AI platform; in bad times, it looks like a high-depreciation manufacturing asset.
Therefore, the TSMC view in this report should not be read simply as “target price raised” or “AI demand is strong.” The more important question is whether TSMC can continue to maintain high gross margins after massive CapEx. This question determines whether it continues to enjoy a bottleneck-platform valuation or is placed back into the foundry cyclical-stock framework.
XIII. CapEx Return Check: $75 Billion Is Not a Capacity-Expansion Slogan
Morgan Stanley’s 2027E CapEx estimate of $75 billion is one of the numbers in the report that most needs repeated cross-checking. It represents TSMC’s willingness to place early bets on AI semiconductors, advanced nodes, advanced packaging, and global capacity deployment. The number itself is not automatically positive. It only becomes earnings leverage when customer orders, pricing, utilization, and gross margin all line up.
The CapEx check can be broken into three layers. The first is the revenue check: whether N3, N2, CoWoS, and SoIC are truly filled by GPU, CPU, and ASIC customers. The second is the pricing check: whether advanced-node price increases can offset depreciation and overseas capacity costs. The third is the cash-flow check: whether AI customer prepayments, long-term orders, and production-schedule commitments can prevent free cash flow from being swallowed by CapEx.
This framework also explains why TSMC’s trading leverage will not come only from revenue. If revenue growth is bought with high depreciation, the market will assign a lower multiple. If revenue growth comes with price increases, packaging shortages, and defended gross margin, the market will treat it as bottleneck rent. The key for TSMC is whether this spending turns into scarce capacity that customers must buy.
2027 will be an even more important year for verification. CoWoS expansion, N2 adoption, continued N3 ramp-up, overseas capacity investment, and AI customer project transitions will all affect TSMC’s income statement at the same time. Any single item can be explained away, but several weakening simultaneously would change the investment narrative. Investors should especially track customer schedule-cancellation rates, advanced-packaging lead times, wafer-price negotiations, and cloud vendor CapEx guidance.
Morgan Stanley’s positive view rests on the premise that customer demand is strong enough. Projects such as Nvidia Rubin, AMD MI400/MI500, Google TPU, AWS Trainium, Microsoft Maia, and Meta MTIA provide TSMC with a multi-customer demand pool. This multi-customer structure helps TSMC maintain pricing power and reduces the risk of a single customer cutting orders. The issue is that all of these customers’ orders depend on continued realization of cloud CapEx.
In other words, TSMC now has greater order depth to hedge CapEx pressure. Investors need to check quarter by quarter whether capacity expansion is being absorbed by real orders.
XIV. Advanced Packaging Competition: CoWoS, SoIC, EMIB, and Optical Interconnect Are Not Isolated Technologies
CoWoS is the most important bottleneck today, but it is not a standalone technology. As AI chip complexity rises, advanced-packaging roadmaps will simultaneously involve silicon interposers, hybrid bonding, chiplet interconnect, HBM stacking, testing, thermal management, and optical interconnect. TSMC’s advantage is that it can place advanced process technology and advanced packaging inside the same customer-service system, rather than forcing customers to assemble multiple supply-chain segments themselves.
The importance of SoIC is rising. CoWoS solves the packaging problem for multi-chip designs and HBM, while SoIC pushes further toward vertical integration and high-density interconnect. As connection requirements rise across GPUs, CPUs, ASICs, and HBM, SoIC may become a core tool for TSMC to maintain technology leadership over the next few years. It will move TSMC from “packaging chips” toward “participating in system architecture definition.”
Intel’s EMIB offers another competitive path. Morgan Stanley notes that EMIB can, in theory, support larger chips and more reticles, but supply-chain execution is the key. The investment implication here is clear: advanced packaging is a competition over customer mass-production windows. Whoever can deliver stable volume production at customers’ delivery nodes will win subsequent projects.
There is another easily overlooked aspect of advanced-packaging competition: it will change profit distribution. In the past, advanced nodes were mainly charged by wafer pricing, while customers earned higher profits in design and systems. After entering CoWoS and SoIC, TSMC is participating in solutions to more system constraints, and its charging base is expanding from individual wafers to system-level capacity. The tighter packaging is, the easier it is for TSMC to turn customers’ launch windows into pricing power.
This is also why CPO and optical interconnect should be placed in the same framework. There is still disagreement over whether CPO will quickly enter large-scale volume production, but the bandwidth and power pressures of AI clusters are already clear. Optical interconnect, silicon photonics, FAU, packaging testing, and high-end materials will gradually move closer to the chip-packaging layer. TSMC may not earn the most money directly in every optical segment, but it will strengthen its platform position as system complexity rises.
XV. Sell-Side Disagreement: Bulls Buy the Bottleneck; Cautious Investors Watch Returns
This Morgan Stanley report is optimistic, but optimism does not mean there is no disagreement. The core debate in AI semiconductors today can be broken into four layers: demand, supply, margin, and valuation. Bulls believe cloud CapEx is still being revised upward and bottleneck links will continue to gain pricing power. Cautious investors worry that CapEx-to-EBITDA is too high and that customers will eventually pass budget pressure down to the supply chain.
The demand debate comes from cloud-vendor returns. As long as AI application revenue, inference call volume, and enterprise deployment speed can keep up, cloud vendors will continue increasing investment in GPUs, ASICs, and CPUs. If AI revenue is realized slowly, capital markets will demand that cloud vendors reduce CapEx. TSMC benefits from multi-customer production schedules when demand is strong, but when demand is weak, the same group of customers will also pressure pricing in sync.
The supply debate comes from advanced packaging. CoWoS is tight today, but expansion is moving quickly. If 200kwpm of capacity is fully absorbed by Nvidia, AMD, Google, AWS, and other customers, the packaging chain will continue to raise prices. If ASIC projects are delayed, GPU transition timing slows, or customer inventory rises, the packaging chain will move from the strongest bottleneck to the biggest expectation gap.
The margin debate comes from depreciation. Advanced nodes and overseas capacity construction will keep pushing depreciation higher. Bulls believe price increases, yield, and high utilization can offset depreciation. Cautious investors will watch whether high gross margins begin to loosen. Once the gross-margin defense line moves down, TSMC’s valuation will shift back from a growth bottleneck asset to a manufacturing asset.
My view is moderately optimistic, leaning toward the middle. AI semiconductor demand remains resilient, especially as cloud vendors have already incorporated GPUs, CPUs, ASICs, networking, power, and storage into one infrastructure buildout. TSMC remains the clearest upstream bottleneck asset. But from a trading-rhythm perspective, the market will increasingly reward pure forward TAM less, and reward orders, pricing, and cash flow more. TSMC can remain in the first tier because it has the ability to deliver these metrics simultaneously.
XVI. Portfolio Implications: Look for Second-Order Elasticity Along TSMC’s Capacity Map
If this report is converted into portfolio thinking, the first step is to look for second-order elasticity along TSMC’s capacity map, rather than placing equal bets across all AI semiconductor companies. TSMC determines the supply cadence for advanced nodes and advanced packaging; customers determine who gets capacity first. The most valuable second-order assets often sit at the intersection of confirmed customer orders, still-tight capacity, and pricing that can be passed through.
The first source of second-order elasticity is packaging and testing. CoWoS expansion requires supporting capacity in packaging equipment, testing, sockets, probe cards, burn-in, and high-end materials. AI chips are becoming larger, test times are becoming longer, and packaging yield and test efficiency will affect actual customer deliveries. The elasticity in names such as King Yuan Electronics, ASE Technology Holding, WinWay Technology, MPI, Gudeng, and ASMPT comes from rising complexity, not merely beta to the AI theme.
The second source of second-order elasticity is ASIC design and production services. The Google TPU, AWS Trainium, Microsoft Maia, and Meta MTIA projects listed by Morgan Stanley all require design services, IP, packaging coordination, and TSMC advanced-node scheduling behind the scenes. Whether companies such as Broadcom, MediaTek, Global Unichip, and Alchip can continue to benefit depends on whether CSP in-house chips enter continuous generations, rather than remaining one-off projects.
The third source of second-order elasticity is memory and materials. HBM is the most visible constraint, but NAND, NOR, DDR4, ABF, T-Glass, and high-end CCL will also be affected by AI prioritization. Morgan Stanley mentions AI’s crowding-out effect on non-AI semiconductors. This matters for materials and memory companies: when AI customers receive priority access to resources, non-AI customers face rising costs and longer lead times, and price increases may spill over into more subsegments.
The fourth source of second-order elasticity is optical interconnect. The timing of CPO remains debated, but bandwidth constraints in AI clusters are already very clear. In the near term, 800G/1.6T, silicon photonics, FAU, and high-end connectivity are easier to monetize; in the medium term, the key question is whether CPO and co-packaged optics enter mainstream rack architectures. Trading the optical-interconnect chain should focus less on concepts and more on customer qualification, yield, delivery, and gross margin.
The fifth source of second-order elasticity is China AI compute. The advantage of domestic Chinese chips is not single-card performance, but TCO, supply security, and local deployment in specific inference scenarios. For Cambricon, Moore Threads, Iluvatar CoreX, Hygon, and the domestic equipment chain, investment validation should begin with orders, then move to customer utilization, inference cost, software adaptation, and manufacturing capability. As long as these indicators do not improve together, valuations can easily remain stuck in thematic trading.
In terms of portfolio cadence, TSMC can be treated as the “core anchor,” while packaging and testing, ASICs, HBM materials, optical interconnect, and China AI compute can be treated as the “elasticity layer.” The core anchor confirms that the AI semiconductor cycle has not broken; the elasticity layer captures profit redistribution. If TSMC’s gross margin, CoWoS capacity, and cloud CapEx are all strong at the same time, the elasticity layer will continue to broaden. If TSMC itself starts to be pressured by depreciation and utilization, the elasticity layer will come under pressure first.
This framework has another benefit: it helps avoid simply chasing the hottest segment. From time to time, the market shifts its focus from GPUs to HBM, then to PCBs, optical modules, CPO, CPUs, or ASICs. The truly sustainable opportunities are not in the hottest label of the day, but in the resources that are becoming increasingly difficult to secure on TSMC’s capacity map. Those who can secure resources, and convert them into revenue and gross margin, are the ones worth continuing to track.
XVII. Three Common Misreadings: Demand, Substitution, and Expansion
When reading this report, three misreadings are most likely. The first is to interpret Morgan Stanley’s optimism as “infinite AI demand.” What the report is really saying is that demand remains strong, but each layer of demand must ultimately land against resource constraints. Cloud CapEx is still being revised upward, AI servers are still shipping, and GPUs, CPUs, ASICs, and HBM are all consuming capacity. But these demands ultimately have to pass through power, wafers, packaging, memory, substrates, testing, and customer budgets. Morgan Stanley is optimistic about the pricing power of bottleneck segments, not about all AI assets rising indiscriminately.
The second misreading is to view ASICs as a replacement trade for Nvidia. ASICs are better understood as proprietary tools for cloud vendors to control costs and supply chains. Nvidia continues to address demand for the most general-purpose, strongest-ecosystem, highest-performance accelerators; ASICs address specific workloads, scaled inference, and cloud vendors’ internal optimization. For TSMC, it is better for both lines to run in parallel, because the more customers there are, the more dispersed N3/N2 and CoWoS scheduling becomes, and the more stable TSMC’s negotiating position with customers becomes.
The third misreading is to view capacity expansion directly as profit. Capacity expansion only solves supply; profit depends on pricing, utilization, yield, and depreciation. CoWoS moving from bottleneck to expansion and then potentially to periodic easing is a process seen in any semiconductor capex cycle. What investors need to verify is whether customer orders during the expansion window are long enough, whether pricing is strong enough, and whether TSMC can turn advanced packaging into a long-term service rather than a one-time capacity shortage.
Behind these three misreadings is actually the same issue: AI semiconductors have moved from thematic trading into return-on-assets trading. Thematic trading asks whether the story can continue. Return-on-assets trading asks whether every dollar of CapEx, every wafer, every CoWoS wafer, and every hour of testing can turn into revenue and gross margin. TSMC remains the best entry point because it touches almost every AI compute route at the same time, but a clear entry point does not mean valuation has no constraints.
Another misreading to guard against is viewing China AI compute only as sanction substitution. Morgan Stanley’s analysis of China AI compute is closer to a systems-engineering perspective: weaker single-chip performance can be offset with more dies, larger racks, and stronger infrastructure; lower prices can be used to compete for inference scenarios through TCO and cost per token; manufacturing constraints can be gradually addressed through domestic wafers, packaging and testing, and equipment. The investment opportunity here must return to whether customers are willing to deploy at real scale, rather than betting only on the phrase “domestic substitution.”
Once these misreadings are removed, the remaining investment questions become clearer. Whether TSMC can continue to hold pricing power depends on whether multi-customer scheduling remains tight. Whether CPUs and ASICs can unlock second-order elasticity depends on whether agentic AI and cloud in-house chips form continuous generations. Whether HBM, ABF, and testing can continue to raise prices depends on whether physical bottlenecks have been locked in by customers in advance. Whether China AI compute can be re-rated depends on inference cost and order delivery. Each line can be tracked; there is no need to rely only on sentiment.
XVIII. Conclusion: What Morgan Stanley Sees Is a Reallocation of the AI Compute Bill
The most valuable part of this Morgan Stanley report is that it breaks AI semiconductors down from one demand story into multiple bills. TSMC captures the advanced-node and packaging bill; Nvidia continues to capture the GPU bill; cloud vendors’ in-house ASICs capture the cost-optimization bill; CPUs capture the agentic AI scheduling bill; HBM, ABF, testing, and optical interconnect capture the physical-bottleneck bill; and China AI compute captures the local-supply and inference-TCO bill.
In trading terms, the clearest direction remains TSMC. It sits at the intersection of N3/N2, CoWoS, SoIC, AI GPUs, CPUs, ASICs, and global cloud CapEx. Morgan Stanley’s US$75 billion CapEx estimate and 200kwpm CoWoS capacity indicate that TSMC is preparing for a larger AI system bill after 2027.
Risks must also be placed in the same table. More CapEx is not always better, and CoWoS will not remain in shortage forever. In the second half of 2026 and in 2027, the market will audit the numbers through gross margin, pricing, customer scheduling, HBM supply, cloud CapEx returns, and China AI orders. Segments that can deliver orders, pricing, and cash flow will continue to benefit from AI hardware diffusion; segments left only with long-term TAM will be filtered out first by valuation compression.
The AI trade has not ebbed; what has ebbed is the phase of buying single-factor momentum. The next phase looks more like a hard ledger: who controls advanced nodes, who gets CoWoS, who gets HBM, who shortens testing and delivery, and who brings down inference cost. TSMC is the first line of this ledger, but not the only line. The real opportunity lies in following TSMC’s capacity allocation to find the bottleneck assets that can keep collecting revenue from the rising complexity of AI systems.