
The AI Memory Wall: A Deep Dive into the $23 Billion Market Beyond HBM—HBF, CXL, and Six Technology Pathways
目录
TL;DR
The Memory Wall’s Four Constraints: Capacity, Bandwidth, Latency, and Cost
Clarifying the Market Definitions: $23 Billion and $276 Billion Are Not the Same
The Essence of the Six Pathways: No Longer Relying Solely on Shrinking Transistors
Packaging and Interfaces Are Closer to Cash Flow: HBM, HBF, MRDIMM, and CXL
If Software Uses Less Memory, Why Might Total Demand Still Rise?
Company Value Map: Manufacturers Capture the Cycle; Interface and Equipment Vendors Capture Complexity
Montage Technology Case Study: Higher Product Content Is a Real Driver, but So Is Valuation Risk
A Three-Layer Validation Framework: Separate the Roadmap, Revenue, and Valuation
The Final Numbers to Watch
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
The next constraint on artificial intelligence (AI) is not just chip compute, but whether data can be stored, moved, and delivered to compute units in time and at sufficiently low cost.
TL;DR
The memory wall has evolved from a “chip performance issue” into a “data-center economics issue.” Morgan Stanley estimates that Google Cloud’s monthly token volume increased from 10 trillion in April 2024 to 3.2 quadrillion in June 2026, more than 320-fold. Over the same period, DDR5 single-channel bandwidth rose only 14%, from 44.8GB/s to 51.2GB/s. Faster processors are starved of data, while higher model parameter counts require greater capacity. Capacity, bandwidth, latency, and cost are now simultaneously constraining AI expansion.
The $23 billion figure does not represent the entire market for new memory technologies. It is only the 2030 base-case market for emerging technologies excluding conventional high-bandwidth memory. The bull- and bear-case estimates are $41.4 billion and $16.9 billion, respectively. Including high-bandwidth memory (HBM), the base, bull, and bear cases are $276 billion, $342 billion, and $160 billion, respectively. The former is useful for assessing incremental opportunities in new interfaces, packaging, and materials; the latter more closely approximates the entire AI high-performance memory value pool.
The five areas most worth tracking over the next three years have already entered customer platforms. 1c dynamic random-access memory (DRAM), HBM4/4E, 300-plus-layer 3D NAND, multiplexed rank dual in-line memory modules (MRDIMMs), and Compute Express Link (CXL) all have clear roadmaps for mass production, sampling, or server deployment. 4F² vertical transistors, high-bandwidth flash (HBF), and DDR6 face critical validation windows in 2027–2028. Fully stacked 3D DRAM, five-bits-per-cell NAND, and certain compute-in-memory technologies remain longer-dated options.
Value will broaden from memory wafers into packaging, interfaces, controllers, and materials, but will not bypass incumbent memory manufacturers. Samsung Electronics, SK hynix, Micron Technology, Kioxia, and SanDisk will continue to capture the most significant manufacturing, supply, and pricing benefits. Connectivity-chip vendors such as Montage Technology, Renesas Electronics, and Marvell Technology will benefit from higher interface content per server. Advanced etching, hybrid bonding, thermal management, and new conductor materials will share in the gains from rising process complexity.
Software optimization is a critical counterindicator for demand and must be monitored continuously. DeepSeek Engram offloads static knowledge to conventional DRAM or CXL memory, while TurboQuant claims to accelerate inference eightfold and reduce memory usage sixfold. These approaches could reduce the high-performance memory required per task. However, if the resulting savings are reinvested in longer context windows, more agents, and higher concurrency, total system memory demand could still rise. The key question is whether the decline in memory usage per inference can outpace growth in total inference volume.
Investors should distinguish between technology delivery and valuation realization. Montage Technology is the report’s clearest example of interface value creation: Morgan Stanley expects its revenue to rise from RMB5.28 billion in 2025 to RMB19.506 billion in 2028, with net profit increasing from RMB2.158 billion to RMB10.752 billion, and has raised its A-share price target from RMB274 to RMB377. However, the valuation assumes sustained cloud capital expenditure, product penetration, and high margins all materialize simultaneously. New memory technologies may offer long-term structural growth, while related stocks can still experience substantial volatility due to pricing cycles, slower capital spending, and excessive expectations.
The Memory Wall’s Four Constraints: Capacity, Bandwidth, Latency, and Cost
Historically, discussions of AI infrastructure focused primarily on graphics processing unit counts and compute capacity. The question now is whether systems can deliver the required data in time, even as processors continue to become faster. Training repeatedly reads parameters and data, while inference must process longer contexts, more user requests, and increasingly complex agentic workflows. Processor performance, model size, and token volumes are growing rapidly, while memory capacity and bandwidth remain constrained by wafer area, packaging space, power consumption, thermal management, and cost. The result is a memory wall in which processors are left waiting for data.
Morgan Stanley’s order-of-magnitude comparison is striking: floating-point compute performance has increased by approximately 7.5 million times over the past 28 years, while interconnect speeds have risen only 25-fold over roughly 20 years. Even allowing for differences in time frames and measurement methodologies, a gap of approximately 20,000 times remains between compute capacity and data-delivery capability. This is not a precise forecast, but it captures the central tension: compute units are being added far faster than the memory hierarchy can be restructured.
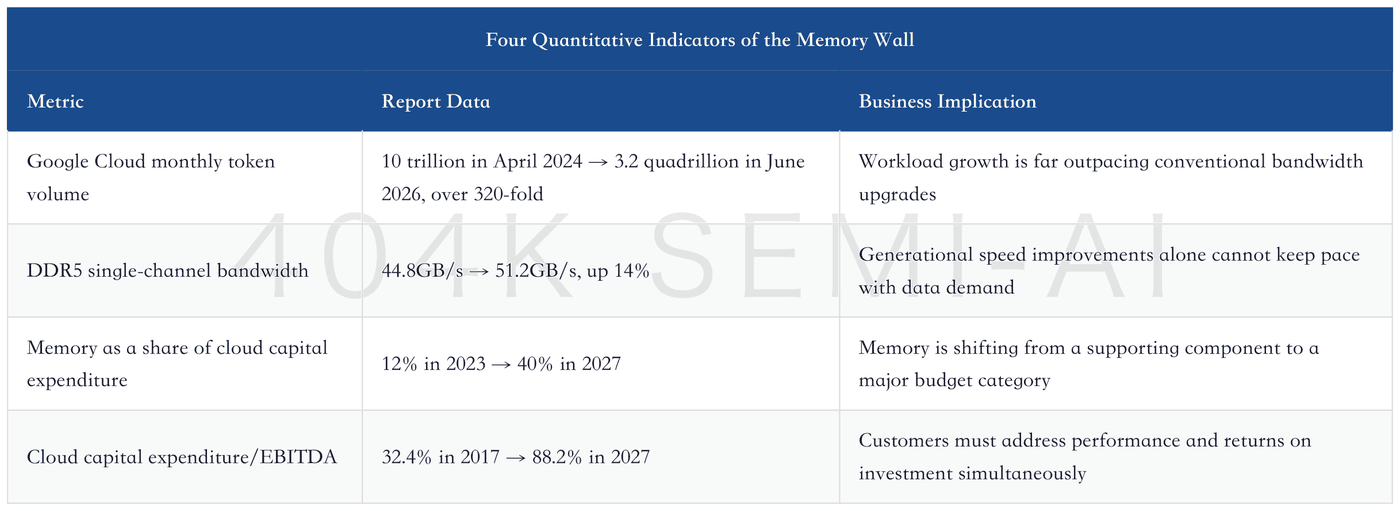
Cost pressures have already reached the system level. Based on prices at the time of the report, memory in a central processing unit server costs approximately $14,000, versus roughly $5,300 for other components, making memory 73% of the bill of materials. The corresponding shares for laptops and smartphones are approximately 41% and 39%. When DRAM and NAND flash prices rise, cloud providers face higher server investment requirements, while device manufacturers must reassess the trade-offs among pricing, capacity, and margins. Next-generation memory is therefore not merely about “selling more bits”; it must enable customers to continue expanding AI deployments through higher bandwidth, better tiering, and lower total cost of ownership.
Clarifying the Market Definitions: $23 Billion and $276 Billion Are Not the Same
The most easily misinterpreted figure in the report is the projected $23 billion addressable market in 2030. It excludes conventional HBM and covers only emerging opportunities in design, packaging, peripherals, integration, and materials beyond process-node migration. It is intended to answer one question: beyond the already well-understood HBM market, how much incremental value could be created?
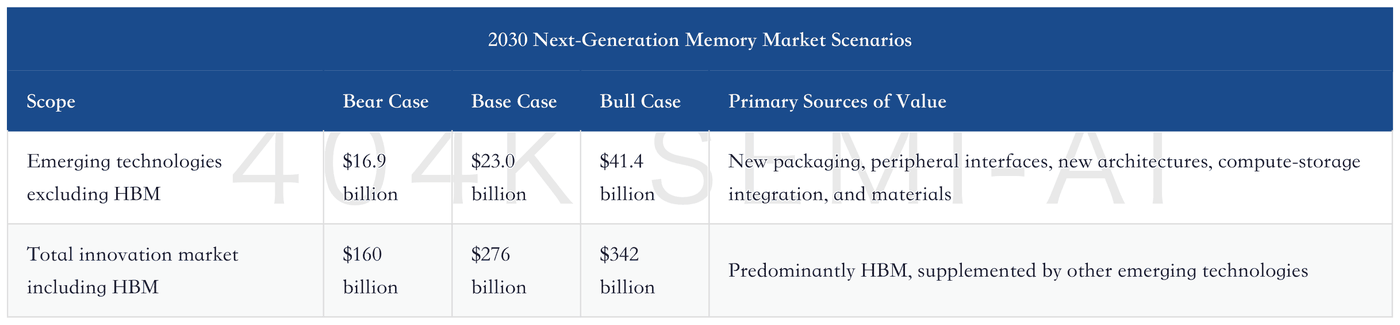
The $23 billion market excluding HBM may appear modest, but it could generate greater earnings leverage for individual companies. Conventional DRAM and NAND are large markets, but they have few participants, high capital intensity, and pronounced pricing cycles. Interface chips, controllers, bonding equipment, and specialty materials address smaller markets, but revenue growth could significantly outpace the overall memory market if content per system doubles or technologies progress from validation to mass production. Conversely, smaller markets are also more susceptible to overestimation: if a technology’s commercialization is delayed by two years or it applies to only a limited set of workloads, valuation realization will be more fragile than the headline total-addressable-market forecast suggests.
The report also contains an internal inconsistency regarding the 2030 market opportunity for wafer-on-wafer (WoW) stacking: the main text cites $9.8 billion, while the chart shows a base case of $13.4 billion; $9.8 billion is closer to the chart’s bear case. The appropriate response is not to select the higher figure, but to retain only the directional conclusion that the market could reach approximately $10 billion, pending further confirmation from product shipments, customers, and a consistent market definition.
The Essence of the Six Pathways: No Longer Relying Solely on Shrinking Transistors
Historically, storage cost reductions primarily relied on process scaling. Today, each scaling pathway faces a different physical limit. DRAM capacitors must retain sufficient charge within ever-smaller areas. As NAND stacks grow taller, aspect ratios, filling, resistance, and yield become increasingly difficult to control. More HBM layers also introduce hotspots, warpage, and hybrid bonding into mass production. Consequently, the industry is simultaneously redesigning structures, packaging, interfaces, compute placement, and materials.
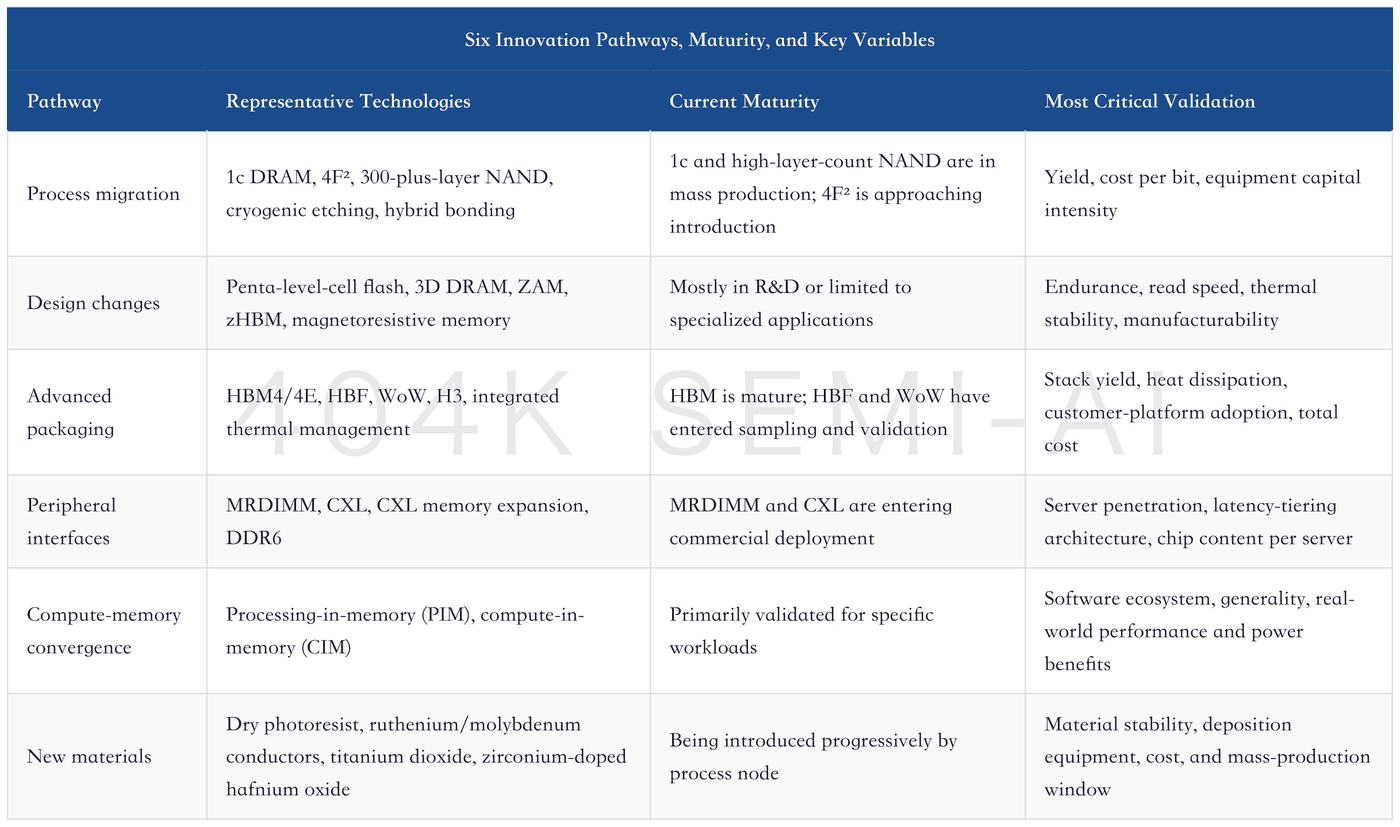
Near-term changes along the process pathway offer the greatest visibility. Samsung Electronics, SK hynix, and Micron Technology are mass-producing or ramping 1γ DRAM, but geometric scaling from 1β to 1γ is already below 10%, and conventional planar architectures are increasingly unable to deliver historical density gains. The next step, the 4F² vertical-channel transistor, further reduces cell area from approximately 6F². The report sees potential for mass production in 2027–2028. If successful, its significance will extend beyond a change in node nomenclature: it would extend the DRAM density and cost curves. If yields fall short, the industry will rely more heavily on stacking and packaging to increase bandwidth.
The NAND roadmap is better characterized as “building higher vertically, shrinking horizontally, and storing more bits per cell.” Mass-production milestones cited in the report include Samsung Electronics at 286 layers, SK hynix at 321 layers, and Yangtze Memory Technologies at 232 layers, with 1,000 layers presented as a longer-term target around 2030. As layer counts rise, each etch must penetrate deeper structures, while the resistance and filling challenges of conventional tungsten conductors become more pronounced. This creates value for cryogenic etching, separate fabrication of memory arrays and peripheral logic, copper-to-copper hybrid bonding, and molybdenum conductors. Opportunities for equipment and materials companies arise because each layer becomes more difficult to manufacture, not merely from fab-capacity expansion.
Within the design pathway, penta-level-cell (PLC) flash stores five bits per cell, providing 25% more capacity than quad-level cells but requiring the detection of 32 voltage states. The report’s long-term performance ranges are only above 20–60MB/s for reads and 1–5MB/s for writes, while endurance could fall below 100 program/erase cycles. This suggests PLC is more suitable for cold data and archival storage. Controllers, error correction, signal processing, and wear leveling will become more important, but PLC is unlikely to directly replace high-performance storage. Fully monolithic 3D DRAM is further away: it requires multiple active DRAM-array layers to be constructed on a single wafer, making thermal budgets, interlayer connections, yield, and cost more complex than packaged stacking. It should not be modeled as a clearly identifiable revenue stream in the near term.
Packaging and Interfaces Are Closer to Cash Flow: HBM, HBF, MRDIMM, and CXL
Among the six pathways, packaging and interfaces are the most likely to convert technological progress into revenue first. They do not require fundamental changes to memory-cell materials, instead rearranging the distance, parallelism, and division of labor among existing DRAM, NAND, and logic chips.
HBM4/4E remains the most direct high-bandwidth solution. The report expects HBM average selling prices to increase by 15% annually from 2026 to 2028 and discusses memory-die capacity rising from 24Gb to 32Gb in the transition from HBM4 to HBM4E. The challenge is that larger dies, more stacked layers, and customized base dies reduce the number of usable dies per wafer while increasing bonding and thermal-management complexity. High prices may reflect both product value and yield or supply constraints. If the market focuses only on revenue while overlooking unit costs, it may overestimate the sustainability of profits.
HBF seeks to address HBM’s trade-off of “high bandwidth but expensive capacity.” It stacks NAND similarly to HBM and connects it through through-silicon vias and a base die near the GPU, enabling large volumes of static parameters to avoid repeated transfers from remote solid-state drives. The report states that first-generation HBF could target 8–16 times the capacity of HBM and discusses the possibility of providing nearly 4TB of accessible storage per GPU. This is highly attractive for large-model inference, but NAND latency, endurance, and power consumption will not disappear automatically. HBF’s success will depend on whether systems can consistently place static, latency-tolerant data in this tier, rather than attempting to push every workload into HBF.
MRDIMM addresses server main-memory bandwidth. It adds a multiplexed rank clock driver and data buffers to the module, allowing two DRAM ranks to output 64 bytes of data simultaneously before combining them into a 128-byte high-speed transfer. With underlying DRAM operating at 6,400MT/s, the module can deliver an effective transfer rate of 12,800MT/s. For interface-chip vendors, the opportunity extends beyond growth in module volumes: one MRDIMM requires one multiplexed rank clock driver and approximately ten data buffers. The report estimates that its interface-chip content is approximately three times that of a standard DDR5 RDIMM.
CXL addresses capacity utilization. It enables processors to access expanded memory or shared memory pools over a coherent interconnect, reserving local DDR5 for hot data while placing colder pages in a slower, less expensive expansion tier. Meta’s Vistara case study shows that CXL-expanded memory has approximately 60% higher latency than local memory and is therefore unsuitable for hot data. However, in distributed machine-learning inference, it can reduce the required server count by as much as 25% and lower out-of-memory events for certain workloads. This is precisely the commercial value of next-generation storage: not maximizing every performance metric, but reducing the number of expensive servers while maintaining acceptable latency.
DDR6 could further increase interface-chip content. Using a dual-socket server as an example, the report notes that a current DDR5 platform with 12 memory channels per processor and one RDIMM per channel requires approximately 24 register clock drivers per server. If future DDR6 platforms increase to 24 channels per processor and each module requires two associated chips, the total could rise to 96, approximately four times the current level. This “fourfold” increase is an architectural assumption, not secured orders. Channel counts, modules per channel, and the final standard will all affect the outcome. Investment conclusions should await confirmation across processor platforms, memory modules, and customer configurations.
If Software Uses Less Memory, Why Might Total Demand Still Rise?
Software optimization is the most important counterargument to the next-generation storage thesis, but it may also become a second demand-growth curve. DeepSeek Engram moves static knowledge bases from expensive HBM into conventional DRAM or CXL memory, leaving dynamic computation on the GPU. TurboQuant reduces inference-memory requirements through quantization and data processing; the report cites an eightfold increase in inference speed and a sixfold reduction in memory usage. If the same model and request volume remain unchanged, these technologies would clearly reduce demand for high-performance memory.
