
目录
I. The Bottom Line: AI Memory Is an Ever-Expanding Pyramid
II. Training Demand: HBM Sets the Ceiling; DRAM and SSDs Keep the System Running
III. Inference Has Two Distinct Stages: Prefill Is Compute-Bound; Decode Is Memory-Bound
IV. Multi-Agent Systems and Long Context: KV Cache Becomes a Commercial Bottleneck
V. HBM Still Captures the Most Value, but Profit Allocation Is Becoming More Complex
VI. Conventional DRAM Is the Underappreciated Second Pillar
VII. NAND’s Re-Rating Comes from Tiering, Not Wholesale DRAM Replacement
8. HBF Offers Enormous Potential—and Equally Formidable Technical Barriers
9. Two Hierarchies Matter: Architectural Position and Physical Media Are Not One-to-One
10. Industry Profit Pools: DRAM Dominates Revenue, While High-Performance SSDs Pursue Incremental Upside
11. Emerging Technology Pathways: Every “Breakthrough” Introduces a New Cost
12. The Ten Most Important Indicators to Track
13. Risk Framework: Mass Production, Cost, and Cyclicality Still Separate Strong Demand from High Valuations
14. Final View: Upgrade the Thesis from “Buy HBM” to “Buy Data-Tiering Efficiency”
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
AI servers are developing a storage architecture far more complex than “GPU plus HBM.” The real opportunity lies in precisely matching each workload to the right storage tier.
I. The Bottom Line: AI Memory Is an Ever-Expanding Pyramid
The greatest value of Bernstein’s Global Memory: An AI Memory Primer is that it breaks the familiar “AI drives storage” narrative into a verifiable technical chain. Training, inference, retrieval-augmented generation (RAG), and multi-agent workflows have different requirements for capacity, bandwidth, latency, power, endurance, and cost. All support HBM growth, but HBM will not capture the entire incremental opportunity.
An AI system can be viewed as a pyramid in which data becomes progressively colder and capacity progressively larger toward the base. At the top is on-chip XPU SRAM—the smallest and fastest tier. Next to the XPU is HBM, which holds the hottest model weights, activations, and KV cache. Below that are CPU-side system DRAM and CXL-expanded memory, followed by Storage Next, local SSDs, and CMX data nodes. Shared SSDs, HDDs, and even tape form the bottom tier. The hotter the data, the closer it must reside to the compute chip; the colder the data, the more it should migrate to high-capacity media with a lower cost per unit of storage.
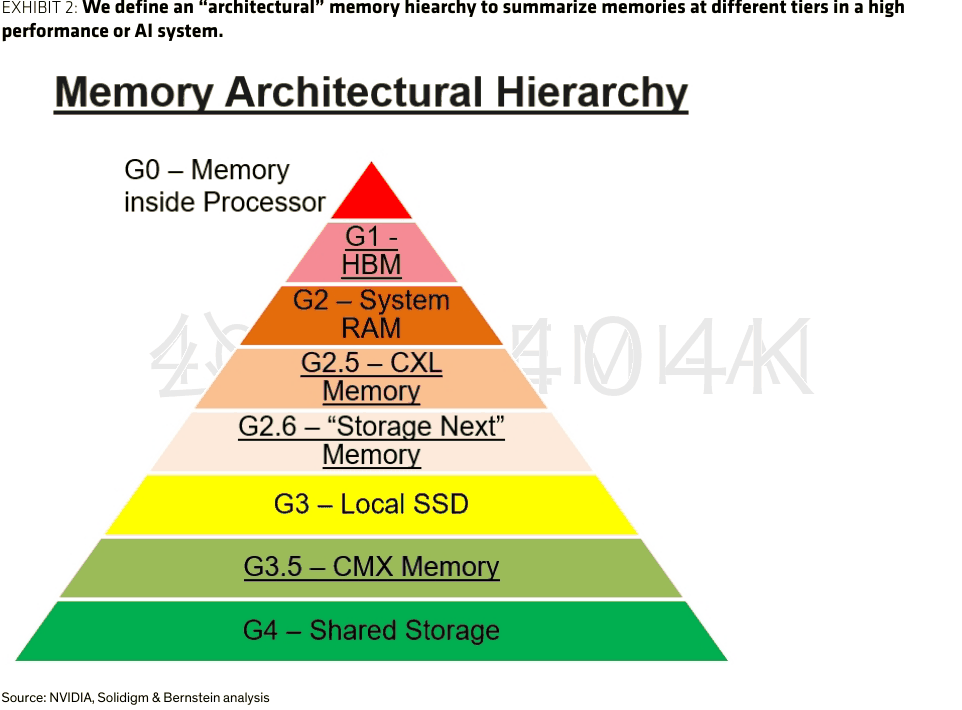
Figure 1: Bernstein’s AI architecture storage hierarchy. The closer data resides to the XPU, the faster the access and the higher the cost per unit of capacity. Sources: NVIDIA, Solidigm, Bernstein analysis; Bernstein, August 28, 2026, p. 7.
This hierarchy means the central challenge in AI storage has shifted from “is there enough capacity?” to “which processor must access which data, and when?” Putting everything in HBM would make system costs and packaging area unmanageable; relying too heavily on inexpensive NAND would allow latency and IOPS to bottleneck costly GPUs. The industry is therefore moving toward retaining hot data in high-bandwidth media while offloading colder data to the next tier more quickly and transparently.
This creates three investment themes. First, HBM remains the highest-value incremental opportunity because it directly determines available bandwidth for large-model training and the decode stage. Second, conventional DRAM is assuming a larger role in training-data pipelines, RAG indexes, CPU tool calls, and KV cache offloading. Third, NAND will benefit from more than capacity growth: high IOPS, low latency, direct GPU connectivity, and networked data nodes are segmenting enterprise SSDs into multiple profit pools.
This also highlights a common misconception: a strong HBM cycle does not automatically translate into simultaneous earnings growth for every memory company. Wafer allocation, advanced packaging, control of base dies, media type, controller capabilities, and software integration determine how much value each company can capture. AI is creating a longer and more complex value chain, but also greater execution risk.
II. Training Demand: HBM Sets the Ceiling; DRAM and SSDs Keep the System Running
Training most readily creates the impression that “HBM is everything,” because model parameters, activations, and frequently accessed compute data must move rapidly near the XPU. Bernstein argues that memory bandwidth may set the absolute ceiling for model scale and compute speed. Regardless of GPU performance, if weights and intermediate results cannot reach the compute units in time, expensive processing capacity will sit idle waiting for data.
But a training system involves far more than HBM. Raw training data is typically stored in lower-cost shared storage. Before training, it must be cleaned, sharded, shuffled, and prefetched, then pipelined through local SSDs and system DRAM before reaching HBM. The longer training runs, the more important fault recovery becomes. Systems must periodically write model state, optimizer state, and training progress to checkpoints. These checkpoints pass through system DRAM and local SSDs before entering networked shared storage, preventing a single hardware failure from wiping out days or even weeks of computation.
Training therefore drives storage demand in sequence: larger models raise HBM capacity and bandwidth requirements; larger datasets expand local SSD and shared-storage capacity; greater training parallelism increases system DRAM caching and network throughput; and more expensive training workloads demand more frequent and reliable checkpointing. Focusing only on HBM bit demand misses three other equally indispensable sources of growth.
Training workloads also explain why memory supply cannot be assessed solely by total bit output. HBM and conventional DRAM share front-end wafer capacity, while HBM requires more dies, more complex TSVs, stacking, and advanced packaging. As manufacturers allocate more wafers and capital to HBM, conventional server DRAM supply may become less elastic. Even when AI demand is concentrated in premium products, capacity displacement can affect pricing across the entire DRAM market.
The NAND implications are more differentiated. Training datasets and checkpoints both require high-capacity SSDs, but their latency, write-endurance, and throughput needs differ. Dataset reads emphasize sequential throughput and capacity; checkpoint writes require burst bandwidth and reliability; and local caches must withstand frequent reads and writes. Enterprise SSD controllers, firmware, parallel channels, and endurance configurations therefore matter more than NAND layer count alone.
III. Inference Has Two Distinct Stages: Prefill Is Compute-Bound; Decode Is Memory-Bound
After a user request enters a large model, it passes first through prefill and then through decode. Both stages use the same model but face entirely different bottlenecks.
Prefill processes the full input prompt and performs large volumes of parallelizable matrix operations. The report describes it as a generally compute-bound stage. Time to first token, or TTFT, includes scheduling and network time as well as prefill computation. Research cited by Bernstein suggests that chatbot TTFT below 0.5 seconds is ideal, 1 second remains acceptable, and more than 2 seconds may cause frustration; complex research or large tasks can tolerate longer waits. The key variables are XPU compute capacity, input length, batching efficiency, and HBM bandwidth—not all first-token latency should be attributed to memory capacity.
Decode is the autoregressive process of generating tokens one at a time. For every new token, the system must read the model weights and access the Keys and Values associated with prior tokens. Model weights are static and can be shared across users; the KV cache updates as the sequence grows and is unique to each user. Decode is therefore more likely to be constrained by memory capacity and bandwidth.
In simplified terms, KV cache size grows with the number of model layers, hidden dimension, numerical precision, context-token count, and concurrent sequences. Bernstein highlights two direct relationships: the KV cache for an individual sequence expands linearly with token count, and KV caches cannot be directly shared across users. Long contexts and high concurrency therefore create a multiplicative effect. A model’s ability to accept longer documents does not mean a provider can serve more users simultaneously on the same hardware.
The user-experience metric also shifts from TTFT to TPOT—the time between consecutive output tokens. Standard text chat may tolerate around 50 milliseconds, equivalent to 20 tokens per second, while real-time voice, coding, and multi-agent applications may require less than 10 milliseconds. The tighter the TPOT requirement, the smaller the time budget for retrieving cold KV cache after offloading it from HBM, increasing the need for high-speed DRAM, low-latency SSDs, and efficient interconnects.
This chain reveals the core economics of inference: revenue depends on the number of users served, tokens per user, and service quality, while costs are shaped by XPU utilization, HBM occupancy, and cache hierarchy. If large volumes of cold KV cache remain in expensive HBM, providers sacrifice concurrency; if data is offloaded too deeply, latency degrades the user experience. Much of the future competition in inference infrastructure will center on cache scheduling, data tiering, and interconnect efficiency.
IV. Multi-Agent Systems and Long Context: KV Cache Becomes a Commercial Bottleneck
Multi-agent systems further amplify these challenges. One agent’s output often becomes the next agent’s input, while downstream nodes may invoke search, code, databases, or enterprise systems. Each handoff can lengthen the prompt, trigger another prefill, and create a new KV cache for the ensuing generation. As the chain grows, so does the coordination overhead across CPU tool calls, system DRAM staging, network access, and GPU inference.
What distinguishes these workloads is that a single user-visible task may involve multiple model calls behind the scenes. Average tokens per request, peak context length, the number of parallel branches, and retry counts all increase. Providers that continue to plan capacity around single-turn chat can easily underestimate peak HBM usage and cache-migration traffic.
Multi-agent workflows also redefine what counts as “hot” or “cold.” Newly generated intermediate results that are consumed immediately by the next step are short-lived hot data. When a task pauses for an external tool, the associated KV cache may temporarily cool; once the task resumes, it must be retrieved quickly. An ideal system would determine in real time which caches remain in HBM, which spill into system DRAM, and which can move to SSD, then prefetch them before execution resumes. This is precisely the gap that CXL, Storage Next, and CMX aim to fill.
Commercially, long context is not merely a model-feature upgrade. It increases memory consumption per active session and may reduce concurrent users per GPU. If service pricing does not cover the additional memory and interconnect costs, stronger model capabilities can actually worsen unit economics. Assessing AI inference providers’ margins will therefore require tracking not only chip acquisition costs, but also context length, average output tokens, KV-cache hit rates, offload ratios, and service-level requirements.
V. HBM Still Captures the Most Value, but Profit Allocation Is Becoming More Complex
HBM sits alongside the XPU, using wide buses and advanced packaging to deliver extremely high bandwidth. Using a Rubin GPU package as an example, the report illustrates eight HBM stacks arranged around a single package. Adding stacks increases capacity and bandwidth, but consumes more package area and raises the complexity of TSVs, base dies, interconnects, and thermal design.
HBM derives its value from three layers of scarcity. The first is DRAM dies and yield; the second is stacking, bonding, and testing; and the third is the capacity and design expertise required to co-package HBM with the XPU. The market often treats all three layers as part of memory vendors’ competitive moat, but emerging architectures could alter how that value is distributed.
Bernstein focuses on zHBM and NVHBM. zHBM seeks to move the HBM stacks from beside the XPU to above it, shortening interconnects and increasing bandwidth. However, the upper DRAM must withstand heat from the XPU beneath it, while hybrid-bonding yield and cost remain unresolved. NVHBM, meanwhile, would move controller and related functions into a custom base die designed by NVIDIA and potentially manufactured by TSMC. If adopted, memory vendors would continue supplying DRAM stacks but could cede some of the value associated with base-die IP, foundry production, and system differentiation.
This does not mean incumbent HBM suppliers will immediately lose pricing power. High-yield DRAM stacking, TSV processes, thermal management, and customer qualification still present formidable barriers, while HBM also competes with conventional DRAM for wafer capacity. A more balanced conclusion is that the HBM profit pool will continue to expand, but incremental value will be redistributed among memory vendors, XPU designers, foundries, advanced-packaging providers, and the interconnect ecosystem.
HBC offers another approach. It uses LPDDR and conventional packaging, avoiding costly CoWoS and reducing power consumption, at the expense of fewer interconnects and lower performance than HBM. The corporate roadmap cited in the report indicates that Qualcomm plans to ship first-generation HBC in fiscal 2027 and launch a second generation in fiscal 2028. This timeline should be treated only as a product-roadmap milestone, not as evidence of validated mass production. HBC is more likely to serve cost- and energy-sensitive applications with less demanding peak-bandwidth requirements than to replace HBM without performance trade-offs.
VI. Conventional DRAM Is the Underappreciated Second Pillar
System DRAM in AI servers performs four functions. First, it supports preprocessing and pipeline buffering before training data enters HBM. Second, it enables RAG vector-database creation and online index retrieval. Third, it supports CPU-based tool execution, scheduling, and control. Fourth, it acts as a front-end cache for NAND, masking SSDs’ relatively high access latency.
RAG particularly illustrates DRAM’s independent value. During database construction, large volumes of unstructured data are stored on SSDs, while the system uses DRAM to generate vectors and indexes. This is generally a pre-deployment, offline cost that does not recur with every online query. During online retrieval, vector indexes reside primarily in system DRAM. Only after matching results are added to the prompt do they re-enter prefill and decode, driving demand for XPUs, HBM, and KV cache. Attributing all RAG-related demand to HBM would simultaneously overstate HBM demand and understate the importance of system DRAM.
Module form factors are also evolving. SOCAMM2 uses LPDDR, lower voltage, and a lower-profile design, while expanding the data bus from 64 bits on a conventional DIMM to 128 bits. This increases bandwidth per module, reduces power consumption, and improves airflow. The report’s Vera CPU example assigns 8 SOCAMM2 modules to each CPU, or 16 modules across two CPUs. The investment implication extends beyond simply installing more memory per server: it also includes higher value per module and upgrades to power delivery, cooling, and board-level layout.
CXL enables memory expansion and pooling over PCIe, reducing the waste created when each server reserves large amounts of idle DRAM for peak demand. Its value depends on whether software can distinguish latency across memory tiers and place data appropriately. For a CXL-connected NAND SSD to perform a “DRAM-like” role, it will generally also require DRAM caching, controller optimization, and greater parallelism.
The risks to conventional DRAM should not be overlooked. HBM’s consumption of wafer capacity can tighten supply, but supply elasticity may also recover quickly when manufacturers expand capacity, migrate process nodes, or encounter weaker-than-expected AI demand. Server DRAM remains cyclical; structural capacity growth will not automatically eliminate inventory and pricing volatility.
VII. NAND’s Re-Rating Comes from Tiering, Not Wholesale DRAM Replacement
NAND and DRAM differ by several orders of magnitude in access latency. The typical parameters summarized by Bernstein on page 23 show SRAM below 10 nanoseconds, DRAM at approximately 35 nanoseconds, MRAM at approximately 10–50 nanoseconds, PCM above 100 nanoseconds, and RRAM at approximately 100 nanoseconds. NAND is approximately 25–100 microseconds, while HDD is approximately 3 milliseconds. This gap means that inexpensive capacity cannot directly become high-performance memory.
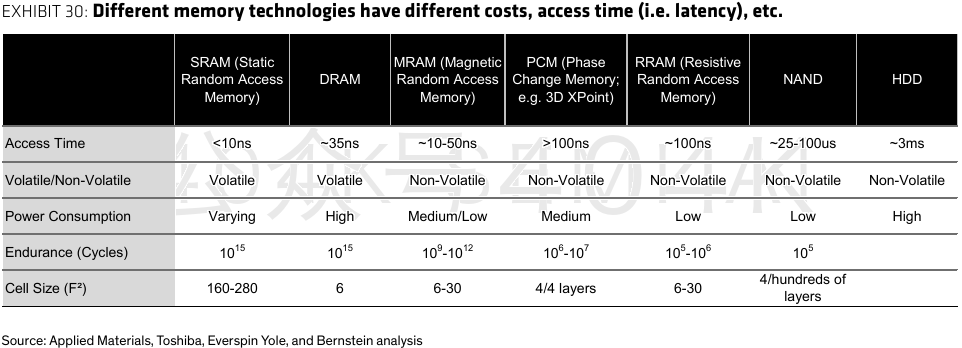
Figure 2: Comparison of the physical characteristics of major storage technologies. NAND’s cost and density advantages come with microsecond-scale access latency and lower write endurance. Sources: Applied Materials, Toshiba, Everspin, Yole, Bernstein analysis; Bernstein, August 28, 2026, page 23.
Endurance and cell area also define the boundaries. The report lists endurance of approximately 10^15 cycles for SRAM and DRAM, 10^9–10^12 for MRAM, 10^6–10^7 for PCM, 10^5–10^6 for RRAM, and 10^5 for NAND. SRAM cell area is approximately 160–280F², versus approximately 6F² for DRAM, while 3D NAND can amortize unit area through hundreds of stacked layers. NAND leads in capacity density and cost; DRAM leads in latency, write endurance, and fine-grained access.
AI is therefore driving further segmentation within NAND. XL-FLASH and Z-NAND use SLC- or MLC-based approaches, sacrificing capacity density for higher IOPS and lower latency, making them suitable for tiers closer to compute, such as Storage Next. TLC offers a more balanced trade-off among performance, endurance, and cost and can be used in CMX. QLC targets lower cost per bit and greater capacity, making it better suited to shared storage and competition with HDDs. No medium is universally superior; workload fit is what matters.
Kioxia Holdings claims that its GP-series SSDs can reach 10 million IOPS in the report year and has set a target of more than 100 million IOPS for 2027. These figures reflect the company’s ambition to move NAND closer to the DRAM tier, but they remain corporate targets and should not be interpreted as capabilities already available across all products. Actual performance will also depend on the read/write mix, queue depth, access granularity, controller, thermal management, and software stack.
Storage Next sits between DDR DRAM and local Compute SSDs, aiming to deliver lower latency and greater parallelism than conventional SSDs. CMX instead deploys capacity in dedicated data nodes connected to compute nodes through the BlueField-4 DPU, Spectrum-X, and Ethernet, allowing GPUs to bypass the CPU and access that capacity directly under suitable software and network conditions. Both address the same problem: enabling GPUs to retrieve data that does not merit permanent residency in HBM with sufficient speed.
8. HBF Offers Enormous Potential—and Equally Formidable Technical Barriers
HBF seeks to stack NAND in much the same way that HBM stacks DRAM, placing HBF alongside HBM around the XPU package. Citing a SanDisk concept, the report compares a pure-HBM configuration with 192GB of total memory against hybrid HBF configurations with 3,120GB and 4,096GB. The capacity advantage is compelling, but these figures illustrate a vendor proposal and should not be treated as generally available production specifications.
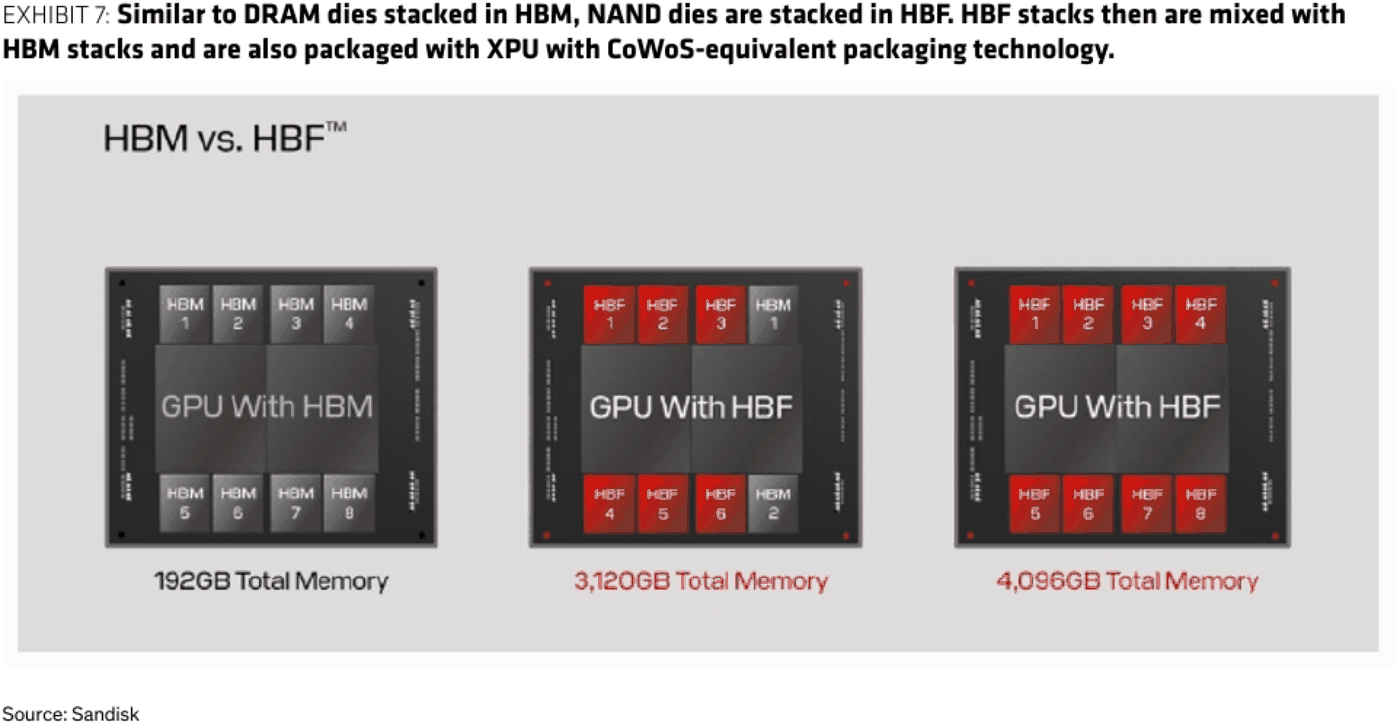
Figure 3: SanDisk’s HBF concept. The 3,120GB and 4,096GB figures are vendor target configurations, not generally available production specifications. Sources: SanDisk; Bernstein, August 28, 2026, p. 9.
The commercial rationale for HBF is straightforward: use NAND’s cost and capacity advantages for colder data while keeping that data as close to the XPU as possible, reducing retrieval across servers and networks. However, HBF must bridge multiple performance gaps—from NAND to DRAM and then to HBM. Bernstein explicitly assesses the technical barriers as high.
There are at least five specific challenges. First, NAND read latency is far higher than DRAM latency. Second, write endurance is weaker. Third, the access granularity may not match GPU workloads. Fourth, thermal management becomes more complex after stacking and packaging. Fifth, controllers and software must make data migration as transparent as possible. Failure on any front could leave HBF as an expensive component with enormous capacity that GPUs cannot afford to wait for.
HBF is therefore better understood as a complementary tier to HBM. If successful, it would expand XPU-adjacent capacity, reduce some data movement between networks and remote SSDs, and increase concurrency for ultra-long-context workloads or large-model inference. In the near term, however, it is unlikely to replace the HBM bandwidth required by the hottest weights and active KV cache.
For NAND vendors, HBF opens a high-value market spanning advanced packaging and XPU integration. For HBM vendors, it could ease the cost and area pressures associated with stacking ever more DRAM. For system vendors, it adds another layer of scheduling complexity. Value capture will depend on who controls the media, controllers, packaging, interconnects, and caching software.
9. Two Hierarchies Matter: Architectural Position and Physical Media Are Not One-to-One
Bernstein presents both an “architectural hierarchy” and a “hardware hierarchy,” a critical distinction for understanding emerging product categories. The architectural hierarchy addresses how far data resides from the XPU, who accesses it, and through which interconnect. The hardware hierarchy addresses the underlying storage medium, its latency and cost, whether it is volatile, and its endurance.
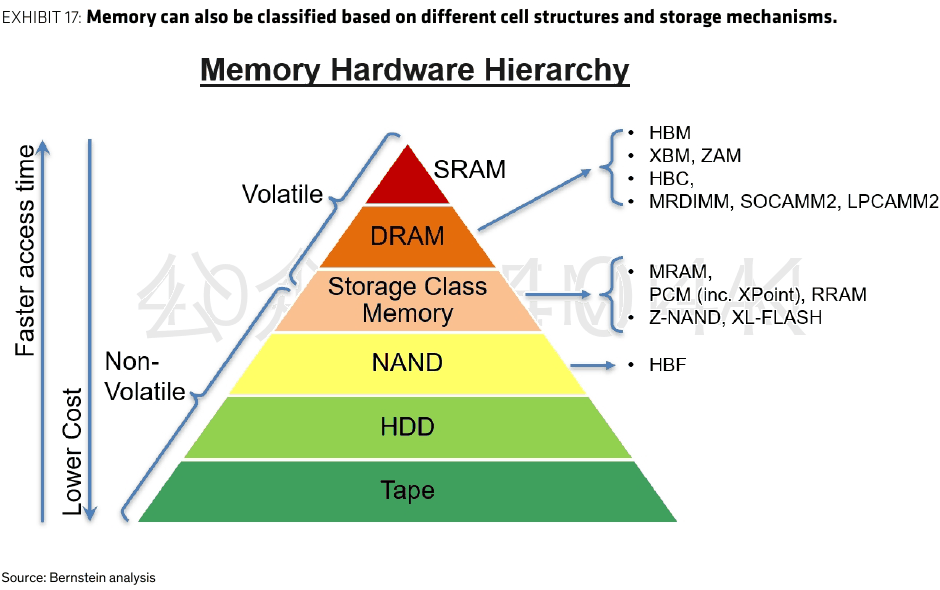
Figure 4: Bernstein’s storage hardware hierarchy. Moving down the hierarchy lowers capacity cost but increases access latency; volatile and non-volatile media serve different roles. Sources: Bernstein analysis; Bernstein, August 28, 2026, p. 18.
The same physical medium can appear at multiple architectural tiers. DRAM can serve as HBM, system memory, CXL-expanded memory, or SSD cache. NAND can support local SSDs, CMX, and shared storage, while XL-FLASH, Z-NAND, and HBF seek to move it into higher-performance tiers. Conversely, a single architectural tier may combine multiple media, using caches and controllers to mask differences in the underlying technologies.
This will make product naming increasingly complex. CXL, Storage Next, CMX, HBF, and HBC are not simple substitutes; they address different bottlenecks and occupy different positions in the architecture. Investors should look beyond the labels and answer at least four questions: What is the underlying medium? How far is it from the XPU? How do the CPU or GPU access it? Relative to the tier above, how much cost is saved and how much latency is added?
If a product does not clearly answer these four questions, the purported “new AI storage product” may simply be an old medium under a new label. The genuinely informative metrics are sustained IOPS, tail latency, bandwidth, power consumption, endurance, the share of GPU-direct access, software compatibility, and customer qualification—not a single peak specification.
10. Industry Profit Pools: DRAM Dominates Revenue, While High-Performance SSDs Pursue Incremental Upside
The report’s long-term revenue mix shows that DRAM accounts for most global memory and storage revenue. This is unsurprising: DRAM commands a higher price per bit than NAND, while HBM adds further value through stacking and packaging. AI growth therefore expands the DRAM revenue pool first, with HBM increasing value per unit.
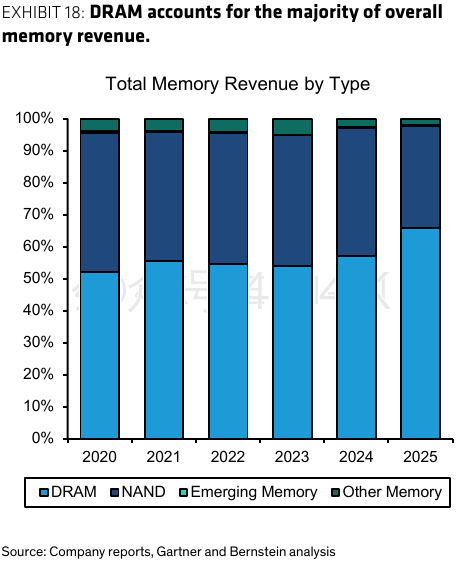
Figure 5: Global memory and storage revenue mix, 2020–2025. The original chart does not label decimal values for each segment, so precise shares should not be inferred from bar heights. Sources: Company reports, Gartner, Bernstein analysis; Bernstein, August 28, 2026, p. 19.
The first group of beneficiaries comprises memory vendors with HBM mass-production capabilities, advanced DRAM processes, and qualification from major customers. Key variables include HBM generation transitions, yields, wafer allocation, advanced-packaging supply, customer share, and conventional DRAM pricing. In strong markets, HBM and conventional DRAM may benefit from simultaneous volume and pricing gains. In periods of stress, failed generation qualifications or lagging yields can rapidly widen the gap between vendors.
The second group consists of the advanced-packaging, base-die, and interconnect ecosystems. zHBM, NVHBM, and taller stacks all require stronger bonding, testing, thermal-management, and foundry capabilities. If XPU vendors control customized base dies, foundries and packaging companies could capture more value, leaving traditional memory vendors increasingly positioned as suppliers of high-performance DRAM.
The third group comprises enterprise NAND and SSD vendors. Commodity capacity growth offers limited earnings leverage. The segments that merit genuine re-rating are low-latency SLC/MLC products, enterprise TLC, controllers, DRAM cache, GPU-direct connectivity, and data-node solutions. A vendor’s ability to enter the Storage Next or CMX ecosystem and consistently deliver low tail latency and high endurance may matter more than peak sequential read/write speeds.
The fourth group comprises HDDs and cold storage. AI-generated and training data will continue to accumulate, while KV cache and checkpoints may also migrate to lower tiers. HDDs and tape remain suitable for high-capacity cold data outside the critical path. They will not achieve HBM-like value per unit, but could benefit from growth in total data volumes and nearline-storage demand.
The supply-chain landscape should be assessed by capability rather than label. Samsung Electronics, SK hynix, and Micron participate in DRAM/HBM; Samsung, SK hynix/Solidigm, Micron, Kioxia Holdings, and SanDisk participate in NAND and enterprise SSDs; Seagate Technology and Western Digital are positioned in HDDs and high-capacity storage; and NVIDIA, Dell, and the DPU and networking ecosystems are advancing CMX and GPU-direct connectivity. This analysis uses only the report’s technical and industry evidence and excludes the point-in-time ratings and price targets on page 2.
11. Emerging Technology Pathways: Every “Breakthrough” Introduces a New Cost
4F² DRAM reduces cell area by changing the cell layout, but Bernstein views this as a one-time structural gain, after which further progress will again depend on lateral scaling. 3D DRAM may offer a genuinely sustainable path, but commercialization remains years away. Process upgrades can alleviate capacity constraints but are unlikely to eliminate the supply cycle entirely.
PIM moves some computation into memory, theoretically reducing data movement between logic and memory and thereby easing bandwidth and power constraints. The challenge is that it departs from the existing von Neumann architecture, requiring processors, software, networks, and manufacturing supply chains to adapt. The report notes that real-world adoption remains extremely limited. PIM is a long-term technology option, but current adoption evidence is insufficient to support assumptions of large-scale revenue.
XBM seeks to build DRAM cells in the back-end interconnect layers of logic chips, while ZAM rotates DRAM dies by 90 degrees to improve cooling. These approaches target bandwidth, stacking, and thermal design, but remain at the patent or proof-of-concept stage. Laboratory peaks demonstrate only technical potential; commercial outcomes will depend on production yields, cost, thermal-cycle reliability, customer software adaptation, and supply-chain replicability.
Edge AI is also producing approaches such as zNAND-O, which stacks NAND using TSVs and places it close to the processor package to provide greater capacity for local models. Edge applications are more sensitive to power, form factor, and cost, while requiring less extreme bandwidth than data centers, and may therefore follow a distinct development path. The report focuses on Transformers and AI systems, and its conclusions should not be extrapolated unconditionally to all edge devices.
12. The Ten Most Important Indicators to Track
To determine whether the AI storage boom is translating from a thematic narrative into earnings, investors should monitor ten indicators.
First, HBM generation qualification and mass-production yields. Customer qualification determines market share; yields determine actual profitability. Second, wafer allocation between HBM and conventional DRAM. If HBM expansion materially crowds out conventional DRAM, pricing elasticity will strengthen; simultaneous supply growth would weaken this effect. Third, CoWoS and hybrid-bonding capacity. Advanced-packaging shortages will defer demand rather than eliminate it.
Fourth, the average context length and number of concurrent sequences in AI inference, which jointly determine KV cache capacity. Fifth, KV cache offload ratios and hit rates across HBM, system DRAM, and SSDs—the core operating metrics for inference unit economics. Sixth, TTFT and TPOT service-level requirements. More demanding real-time applications require higher-end memory and lower-latency interconnects.
Seventh, server penetration of SOCAMM2, MRDIMM, and CXL memory, which will determine whether conventional DRAM can secure structural growth independent of HBM. Eighth, actual customer deployments, sustained IOPS, and tail latency for Storage Next and CMX; peak-performance demonstrations are no substitute for production workloads. Ninth, the media mix in enterprise SSDs. Shifts among SLC/MLC, TLC, and QLC will affect value per unit and gross margins.
Tenth, control of the supply chain. Who designs and manufactures custom base dies, and who supplies the software and networking for direct GPU connectivity, will determine whether incremental profits accrue to memory vendors, XPU vendors, foundry and packaging providers, or systems-equipment companies.
13. Risk Framework: Mass Production, Cost, and Cyclicality Still Separate Strong Demand from High Valuations
The first risk is demand extrapolation. Long-context models, multi-agent systems, and RAG clearly increase memory requirements, but model compression, quantization, sparsity, paged attention, cache reuse, and scheduling optimization can also reduce memory consumption per token. If efficiency improves faster than usage grows, hardware demand will fall short of linear extrapolations.
The second risk is technological maturity. HBF must bridge the latency gap between NAND and DRAM; zHBM faces thermal constraints and hybrid-bonding yield challenges; HBC trades performance for cost; PIM requires an ecosystem overhaul; and 3D DRAM remains far from large-scale commercialization. Supplier roadmaps indicate direction but cannot substitute for evidence of mass production.
The third risk is the pricing and inventory cycle. Structural HBM growth will absorb capital and wafer capacity, but the memory industry remains exposed to delayed capacity additions, inventory corrections, and price elasticity. If several manufacturers expand simultaneously or AI customers slow capital spending, even high-end products could face order adjustments.
The fourth risk is value migration. Custom architectures such as NVHBM could shift the value of base-die and system design to Nvidia and semiconductor foundries; CMX could direct more spending toward DPUs, networking, and data nodes. Growth in the overall market does not guarantee that every traditional memory vendor will achieve corresponding gains in market share and gross margins.
The fifth risk is power consumption and thermal management. Greater capacity and bandwidth increase data-movement requirements and package heat density. SOCAMM2, HBC, and PIM all address energy efficiency, but the report does not provide a complete system-level energy-per-token model and therefore cannot quantify total data-center power consumption or cooling costs.
The sixth risk concerns the scope of the research. This is a technical primer; it does not provide AI server shipments, HBM/DRAM/NAND bit demand, TAM, gross-margin sensitivity, or free-cash-flow sensitivity. The technology roadmap helps identify where value may accrue across the supply chain, but it cannot independently support price targets or earnings forecasts.
14. Final View: Upgrade the Thesis from “Buy HBM” to “Buy Data-Tiering Efficiency”
The investment thesis for memory in the AI era is expanding along two dimensions. The first extends from GPUs to HBM, because compute requires high-bandwidth data delivery. The second extends from HBM to the entire data hierarchy, because long contexts, high concurrency, RAG, and multi-agent systems make capacity, latency, and cost simultaneous constraints.
HBM remains the most direct beneficiary and offers the highest value density. It determines whether the hottest data can keep pace with XPUs and also affects conventional DRAM supply through shared wafer capacity. The value of system DRAM is underappreciated: it supports training pipelines, RAG indexes, CPU workloads, and KV cache offloading. NAND’s opportunity lies in product segmentation. High-performance media can enter Storage Next and CMX; high-capacity QLC and HDDs can absorb colder data; and HBF seeks to move part of the NAND layer closer to the XPU.
Sustainable competitive advantage will depend on combining four capabilities: media performance, advanced packaging, interconnect architecture, and cache software. Any one capability alone is unlikely to convert capacity into low-latency data that GPUs can use. Coordinating all four could increase XPU utilization, support greater concurrency, extend context length, and improve cost per token.
Accordingly, the central question when evaluating AI storage companies is no longer simply, “How many GB can they sell?” A more useful framework asks: Which workload does the company serve? At which tier? How much expensive HBM capacity or GPU waiting time does it save customers? And who captures the resulting value? Viewed through this lens, opportunities in HBM, conventional DRAM, enterprise SSDs, data nodes, interconnects, and cold storage can all coexist—but their realization timelines, margins, and risks differ materially.
Bernstein’s primer does not provide a plug-and-play earnings model, but it offers a more durable analytical framework. The end state of AI memory will not be determined by a single winning medium. It will be shaped by a tiered system capable of continuously placing data in the right location and delivering it to the right processor at the right time.