
目录
TL;DR
A Speed Gap More Urgent Than the Next Chip
Beyond HBM, the Bottleneck Spreads Along the Data Path
CPO First Moves the Optical Engine Next to the Processor
Extending Optical Links to the Memory Interface Could Reshape Capacity Allocation
Why Google and Marvell Validate the Same Thesis
Memory Vendors Move Upstream into Front-End Design
Commercialization Will Unfold Across Three Time Horizons
Four Gates Stand Between the Roadmap and Revenue
Five Public Indicators to Track
Conclusion
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
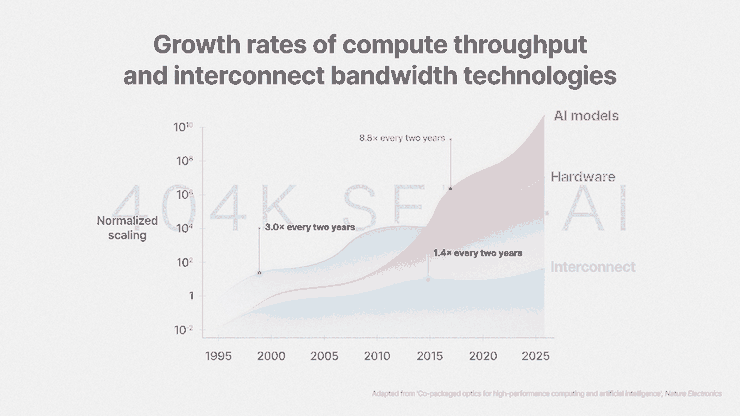
Compute throughput roughly triples every two years, while interconnect bandwidth rises only 1.4x over the same period. The constraint on AI infrastructure is expanding from individual chips to the entire data path.
TL;DR
SK hynix’s published CPO roadmap extends the long-term reach of optical interconnects beyond processors, racks, and clusters to memory interfaces. It targets the growing mismatch between compute throughput and data-movement speed.
The roadmap targets more than 100 Tb/s of bandwidth per node, energy consumption below 1 pJ/bit, and chip-to-chip latency below 10 nanoseconds. These are technical targets, not yet production-product specifications.
Google and Marvell’s disclosed collaboration spans inference accelerators, storage controllers, network interface controllers, memory interface controllers, and near-memory computing. Cloud providers are organizing custom-silicon programs around the entire data path.
Memory vendors are consequently moving upstream. SK hynix has discussed integrating HBM, packaging, and interfaces with Broadcom early in the AI-chip design process, bringing supplier relationships into architecture definition and engineering validation sooner.
Near-term value is more likely to accrue to HBM, advanced packaging, controllers, and custom silicon; CPO sits in the middle, while optical memory pooling is further out. Yield, cost, thermal management, protocols, and reliability will determine when the roadmap translates into financial results.
A Speed Gap More Urgent Than the Next Chip
The CPO roadmap published by SK hynix and research teams at several universities highlights a stark divergence: compute throughput typically triples every two years, while interconnect bandwidth increases by only about 1.4x over the same period.
These figures do not indicate how much product revenue any company will generate next quarter, but they explain why AI systems keep encountering new bottlenecks. If data exchange between nodes fails to keep pace as individual accelerators become faster, adding compute units merely increases waiting, data-movement, and synchronization costs.
HBM has already eased memory-bandwidth pressure within the package. Once thousands of GPUs and large numbers of HBM stacks are assembled into clusters, however, the constraint shifts outward—to links between chips, servers, racks, and larger cluster domains.
This is another layer of the same value chain discussed previously in relation to memory supply-demand and pricing pressure. Supply tightness determines memory pricing; data-movement efficiency determines whether that expensive capacity can be fully utilized.
When GPUs are waiting for data, theoretical peak compute cannot translate into effective throughput. Cloud providers still incur power, networking, and equipment costs, making it difficult to reduce the unit cost of each training and inference workload.
Beyond HBM, the Bottleneck Spreads Along the Data Path
The AI-compute data path can be simplified into five stages: data moves from storage into a controller, passes through the memory interface to HBM, is processed by the accelerator, and then travels through network interfaces to exchange results across additional chips and nodes.
A shortfall at any stage reduces overall system utilization. Faster accelerators address the compute stage; HBM provides high-bandwidth memory access close to the accelerator; networking and optical interconnects handle data exchange over longer distances; and controllers coordinate different capacities, protocols, and devices.
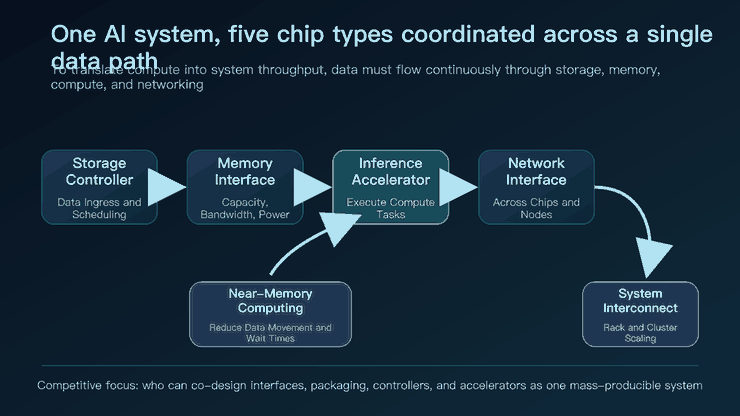
This architecture is redefining the scope of chip programs. Customers care not only about how many operations a chip can perform per second, but also where the data originates, how many protocol conversions it undergoes, how much energy each bit consumes, and whether comparable efficiency can be maintained as the system scales.
Copper interconnects remain inexpensive and mature over short distances. As transmission rates and distances increase, signal loss worsens, requiring more sophisticated compensation circuitry and raising both power consumption and latency. Optical interconnects offer advantages in bandwidth density and energy efficiency over longer distances; they are not poised to replace copper immediately at every reach.
CPO First Moves the Optical Engine Next to the Processor
CPO places the optical engine inside the processor package, minimizing the distance traveled by high-speed electrical signals before shifting the remaining path to optical transmission. This reduces the burden on high-speed board-level electrical connections and supports bandwidth scaling across chips, racks, and clusters.
