
目录
TL;DR
I. What This Paper Actually Advances
II. Why the Bottleneck Keeps Moving Outward After HBM
III. How CPO Redraws the Boundary Between Electrical and Optical Links
IV. What 2D, 2.5D, and 3D Integration Each Address
V. What Changes When Optical Connectivity Reaches the Memory Interface
VI. Why SK hynix Wants to Help Define CPO
VII. The Five Most Difficult Gates to Commercialization
VIII. Why Pluggable Optics, NPO, and CPO Will Coexist
IX. Public Evidence to Watch Next
X. Distinguishing the Three Adoption Scenarios
Conclusion: The Roadmap Is Clear, but the Commercial Clocks Are Not Yet Synchronized
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
This paper extends SK hynix’s technology frontier from bandwidth within HBM packages to data movement across racks and clusters. The direction of CPO is now clear, but the pace of mass production will still depend on thermal performance, yield, standards, and cost.
TL;DR
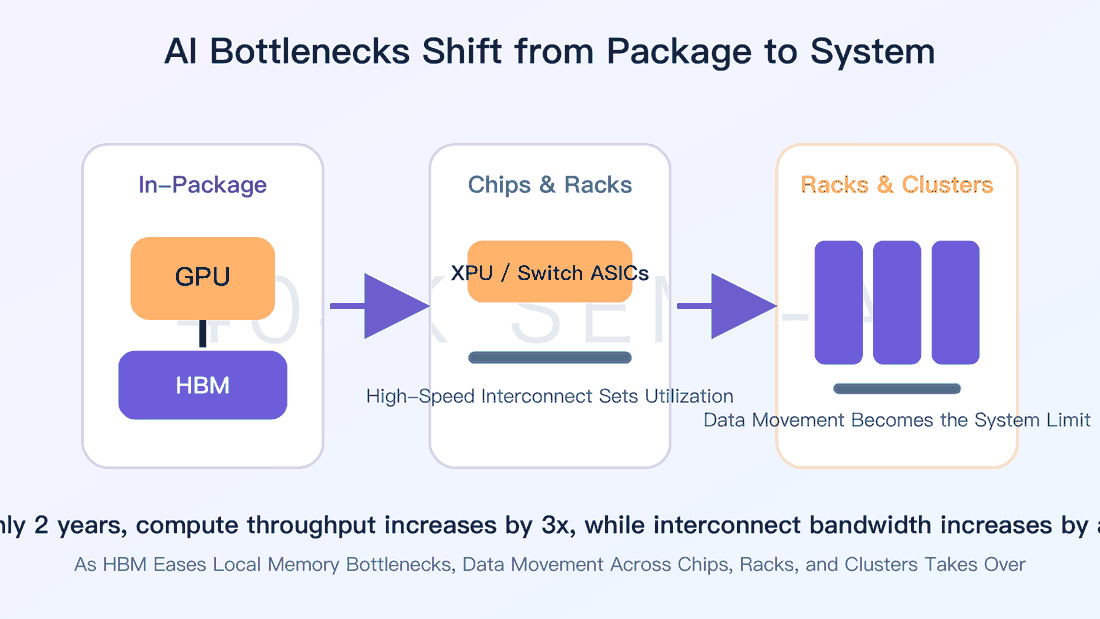
The bottleneck in AI systems is shifting toward interconnects. According to an assessment cited by SK hynix, compute throughput increases 3-fold approximately every 2 years, while interconnect bandwidth rises only 1.4-fold over the same period. Faster GPUs and wider HBM do not automatically translate into proportionate gains in effective cluster throughput, because data must still move across chips, boards, and racks.
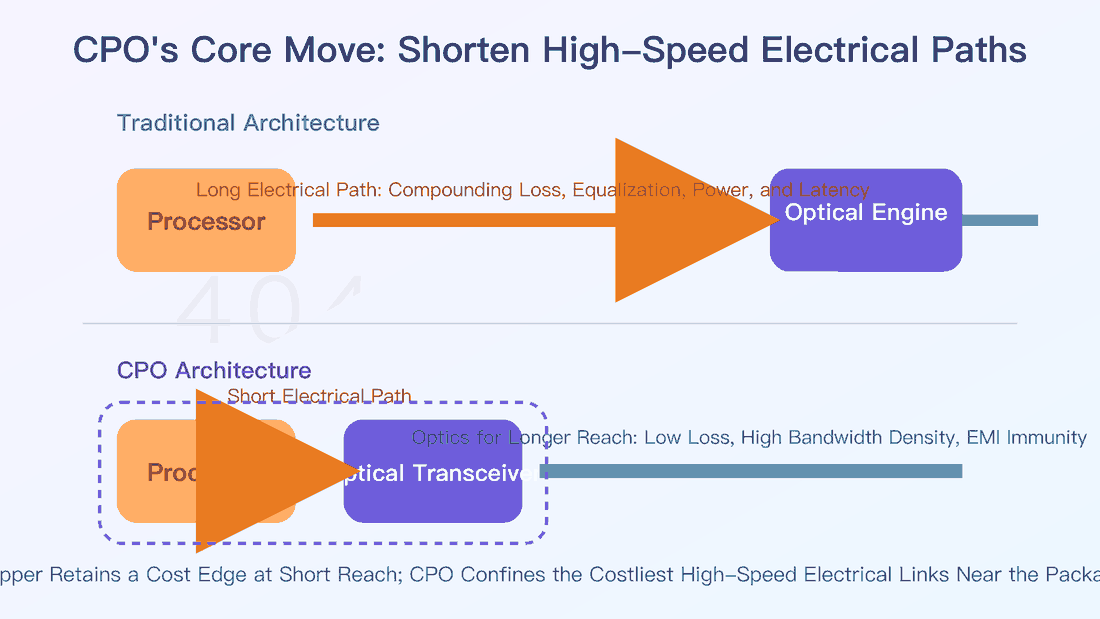
CPO’s core innovation is to place optical transceivers within the same package as the processor or immediately adjacent to it. High-speed electrical signals travel only a very short distance, while longer-distance transmission is handled optically. In a Nature Electronics paper co-authored with several universities, SK hynix sets next-generation targets of more than 100 Tb/s of bandwidth per node, energy efficiency below 1 pJ/bit, and chip-to-chip latency below 10 ns.
The paper’s 2D, 2.5D, and 3D roadmaps represent progressively closer integration of optical components with compute chips. Deeper integration offers greater potential for bandwidth density and energy efficiency, but also makes thermal management, packaging yield, testing, repair, and supply-chain coordination more difficult. The roadmap establishes the direction of travel but provides no mass-production timeline, customer orders, or revenue forecasts.
SK hynix’s strategic intent merits attention. HBM addresses high-bandwidth memory access near the accelerator; CPO goes further by tackling data movement between chips and across systems. If optical interfaces continue to extend toward the memory side, SK hynix could evolve from an HBM supplier into a systems partner involved in the co-design of compute, interconnects, and memory pools.
Nature’s public webpage currently provides only the abstract, while the full paper remains behind a subscription paywall. Verifiable conclusions are therefore limited to the paper’s abstract, SK hynix’s official commentary, and interviews with the authors. Assessments concerning device architecture, commercial cost, mass-production yield, and the pace of customer adoption still require confirmation from the full paper, prototypes, standards, and order evidence.
I. What This Paper Actually Advances
The paper, titled “Co-packaged optics for high-performance computing and artificial intelligence,” was published in Nature Electronics on August 19, 2026. Its authors are affiliated with SK hynix, the University of Virginia, the University of Illinois Urbana-Champaign, Nanyang Technological University, the Massachusetts Institute of Technology, and Yonsei University. It is a review article focused on a system-level roadmap rather than the performance of any single device.
The public abstract covers three layers. First, it reviews the physical constraints of high-speed electrical interconnects, including resistive loss, capacitive loading, and frequency-dependent distortion. Second, it breaks down the electrical subsystems, electro-optic and optoelectronic interfaces, and optical transmission paths within a CPO system. Third, it presents 2D, 2.5D, and 3D heterogeneous-integration roadmaps and identifies challenges in thermal management, manufacturability, and standardization.
The significance of this framework is that it shifts the research question from “how fast can an individual optical device operate?” to “how should an entire compute node move data?” Once GPUs, XPUs, and HBM are considered within the same system architecture, interconnects can no longer be treated as ordinary peripherals outside the processor. Interface placement, packaging architecture, protocols, cooling, and testing collectively determine usable system bandwidth.
The paper’s direct contribution can be summarized as a cross-layer roadmap: retain mature, cost-effective electrical connections over short distances; introduce optical links as distance increases to reduce losses; and progressively raise bandwidth density by moving optical components closer to the chip through 2D, 2.5D, and 3D integration. This gives the industry a common framework for discussion while also exposing the engineering gap between laboratory performance and deployment at scale.
II. Why the Bottleneck Keeps Moving Outward After HBM
HBM stacks multiple DRAM dies using through-silicon vias and places them close to the GPU or AI accelerator through a wide interface. This substantially increases memory bandwidth near the package and alleviates local data-supply constraints in model training and inference. SK hynix has been one of the principal beneficiaries of the current expansion in AI infrastructure.
As systems continue to scale, however, data paths extend beyond a single accelerator package. Training workloads must synchronize large volumes of parameters, gradients, and intermediate results, while inference clusters must route caches and requests among different compute nodes. Bandwidth within nodes is rising rapidly, but communication between nodes remains constrained by electrical-link losses, SerDes power consumption, port density, and switching hierarchies.
SK hynix’s official commentary offers a clear comparison: compute throughput increases 3-fold approximately every 2 years, while interconnect bandwidth rises only about 1.4-fold over the same period. If these curves continue to diverge, more compute resources will sit idle waiting for data. Adding GPUs increases theoretical computing power, but if collective communications and remote access cannot keep pace, the marginal utilization of each additional GPU will decline.
This explains why the “bandwidth wall” keeps moving. The first stage centered on processor-to-memory access, with HBM improving data delivery within the package. The second shifts toward data movement between accelerators, boards, and racks. Beyond that, the bottleneck may emerge between compute pools and shared memory pools. Each outward step increases distance, protocol complexity, and the failure domain, while making power consumption harder to control.
CPO and HBM therefore provide capabilities at two complementary layers. HBM accelerates data delivery close to compute, while CPO seeks to extend that high throughput across larger systems. Improving only one layer merely shifts the bottleneck to the next link. Competition in future AI systems will increasingly hinge on the joint optimization of compute, memory, interconnects, switching, power delivery, and cooling.
III. How CPO Redraws the Boundary Between Electrical and Optical Links
Traditional pluggable optical modules sit on the front panel of a switch or server. High-speed electrical signals generated by the switch chip must travel through the package, printed-circuit-board traces, and connectors before reaching the optical module for electro-optic conversion. As data rates rise, electrical-channel insertion loss, equalization complexity, and SerDes power become increasingly burdensome, while panel space constrains port density.
CPO places the optical engine in the same package as the switch chip, GPU, or other XPU, or positions it very close to the chip. Electrical signals cover only millimeter-to-centimeter-scale paths before optical fiber takes over for longer-distance transmission. This architecture combines the maturity of short-reach electrical connectivity with the energy efficiency and signal integrity of optical links as distance increases.
The electro-optic interface discussed in the paper is the critical conversion point. Drivers, modulators, light sources, detectors, transimpedance amplifiers, and control circuits must collectively meet requirements for bandwidth, power consumption, and thermal stability. Inefficiency in any component raises system-level pJ/bit. Link budgets, clock recovery, error correction, and protocol overhead also affect the throughput ultimately available to applications.
