
目录
Executive Summary
I. 2 Compute Dies and 8 HBM Stacks Can Coexist
II. Why Bandwidth Can Be Maintained Despite Lower Capacity
III. NVL576 Provides System-Level Compensation—and Creates New Bottlenecks
IV. From 10+9+8 to 9+18+9: Rack Space Is Reallocated for Copper Signaling
V. Portia Is the Hardware Demarcation Between NVL72 and NVL576
VI. Per-System Value Is Being Reallocated Across the Supply Chain
VII. Five Validation Points to Monitor
Rubin Ultra reduces per-GPU HBM capacity to 192GB while maintaining 21TB/s of bandwidth; NVL576 scales the system through additional switching, backplanes, and optical interconnects.
Executive Summary
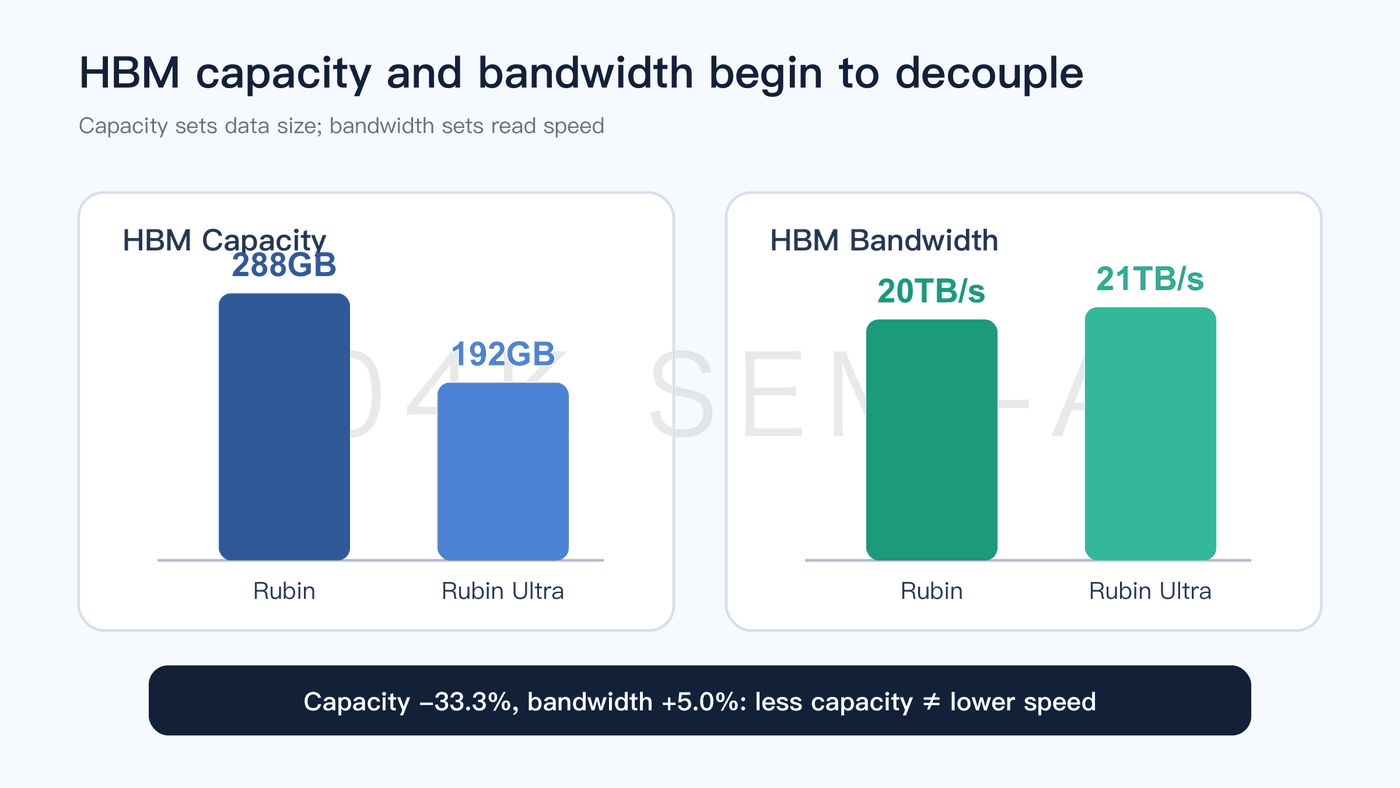
SemiAnalysis’ preliminary supply-chain scenario published on August 10 specifies 8 HBM stacks, 192GB of HBM4, and 21TB/s. Compared with Rubin’s 288GB and 20TB/s, Rubin Ultra reduces per-GPU capacity without lowering per-GPU transfer bandwidth.
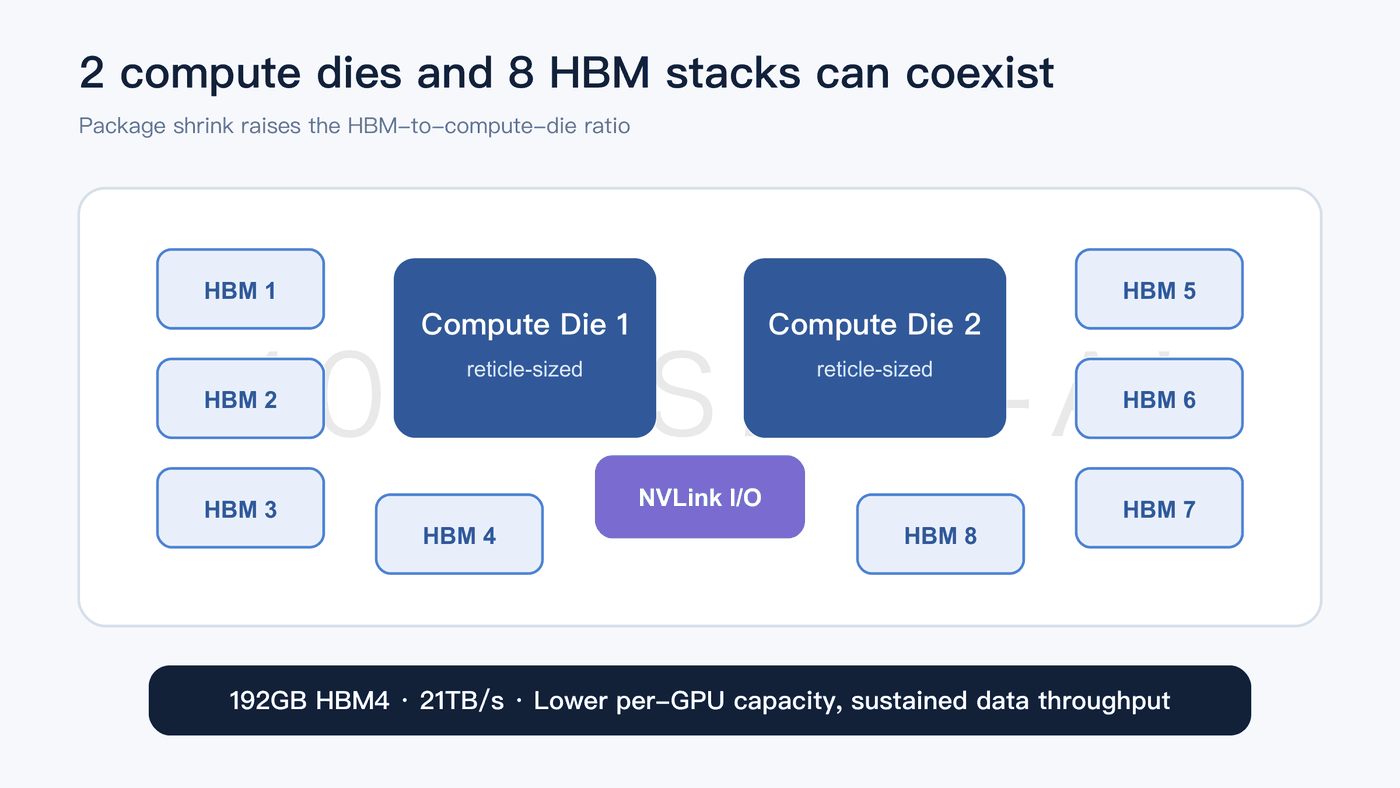
The current Rubin Ultra design combines 2 compute dies with 8 HBM stacks, replacing the earlier configuration of 4 dies, high-capacity HBM4E, and an oversized package. With fewer compute dies, 8 HBM stacks can support 192GB of capacity and 21TB/s of bandwidth. The trade-off is less resident data per GPU and pressure on the high-capacity HBM product mix.
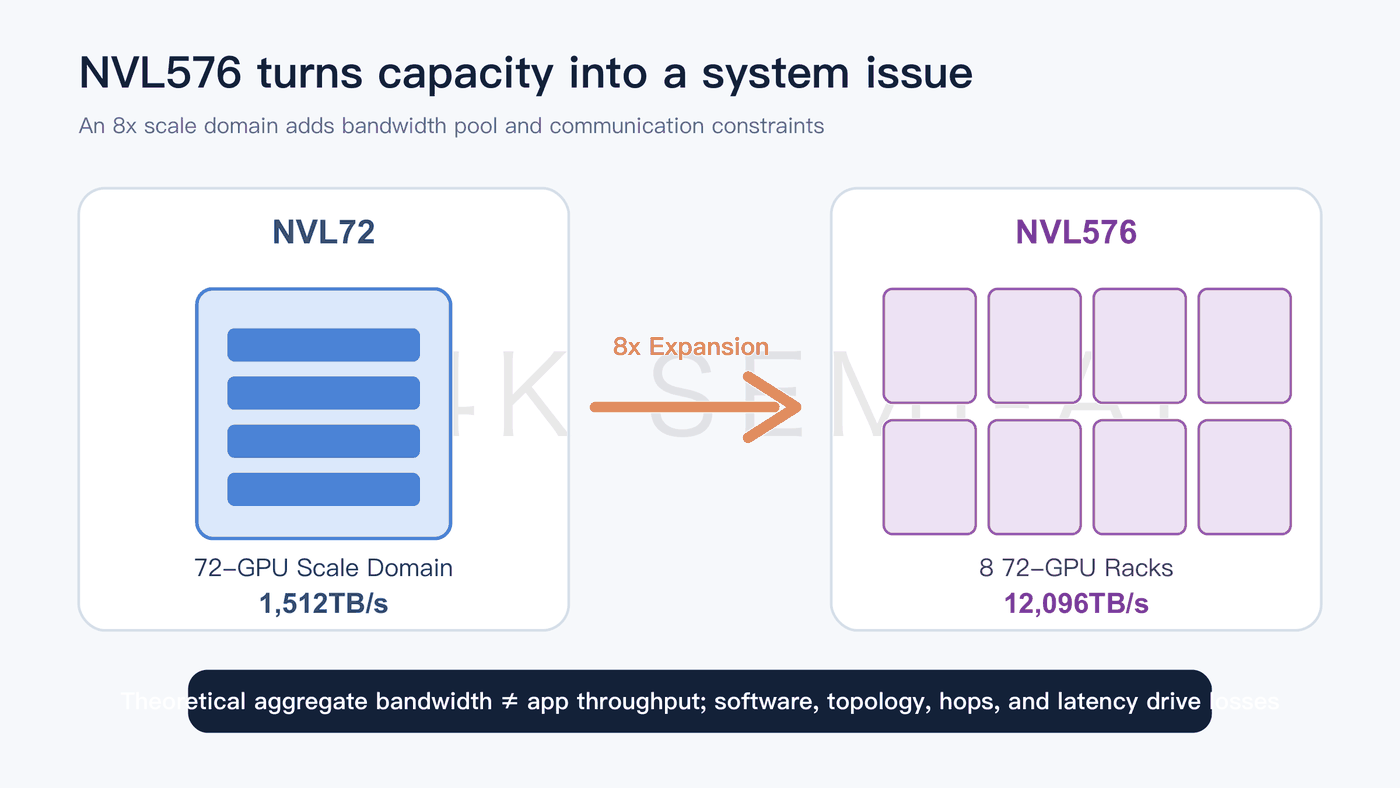
NVL576 is Nvidia’s system-level response to the capacity reduction, but it is not a cost-free upgrade. The scale-up domain expands from 72 to 576 GPUs. Mechanically aggregating 21TB/s per GPU raises theoretical aggregate bandwidth from 1,512TB/s to 12,096TB/s. The trade-offs are twice as many switch trays per rack, twice as many scalable switch ASICs, and the introduction of inter-rack optical interconnects into the core system.
Incremental supply-chain value therefore shifts: HBM vendors face product-mix pressure as per-GPU capacity falls from 288GB to 192GB, while per-rack content rises for switch trays, Portia ASICs, NPO modules, PHD3 backplane connectors, 30-layer HPM PCBs, chassis, and rail components.
Nvidia is reallocating scarce resources through system architecture; this does not mean the memory shortage is over. The actual supply-chain impact will depend on HBM capacity per GPU, the number of deployed systems, SKU mix, switching hardware, and the choice between NPO and CPO.
I. 2 Compute Dies and 8 HBM Stacks Can Coexist
Nvidia is no longer pursuing the initial roadmap’s combination of 4 dies and an ultra-high-capacity HBM4E package. The current design has been streamlined to 2 compute dies and 8 HBM stacks, providing a more manufacturable balance among HBM supply, GPU power consumption, packaging yield, and system deployment volumes.
Combining 4 compute dies with 8 HBM stacks creates simultaneous pressure on capacity, bandwidth, and die-level allocation, making 12 or more HBM stacks a more practical requirement. By moving Rubin Ultra to 2 reticle-sized compute dies, Nvidia doubles the ratio of HBM stacks to compute dies. SemiAnalysis’ current comparison table therefore specifies 2 compute dies, 8 HBM stacks, 192GB, and 21TB/s.
Ultra’s per-GPU HBM capacity is 33.3% below Rubin’s, constraining ultra-large-model residency, long-context KV Cache, and the high-capacity HBM product mix. At the same time, 21TB/s of per-GPU bandwidth means the data path has not contracted in line with capacity. Capacity constraints and bandwidth capability must therefore be assessed separately.
II. Why Bandwidth Can Be Maintained Despite Lower Capacity
Capacity and bandwidth are distinct variables. Capacity determines how many weights, activations, and KV Cache a GPU can retain locally; bandwidth determines how quickly compute units can access data already stored in HBM. Reducing HBM from 288GB to 192GB does not inherently require a proportional reduction in interface speed.
SemiAnalysis’ current table lists Rubin at 20TB/s and Rubin Ultra at 21TB/s. Indexing Rubin’s bandwidth-to-capacity ratio at 100 puts Ultra at approximately 157.5. This does not mean Ultra is 57.5% faster across all workloads: once capacity is exceeded, models must still be partitioned, communications scheduled, or data moved across more GPUs. Communication latency and topology efficiency cannot be offset by a single bandwidth metric.
The 192GB design therefore indicates that Nvidia would rather distribute less local HBM across more GPUs than reduce per-GPU data-path bandwidth in parallel. Capacity remains important, but ranks below transfer speed and deployable volume. This is resource allocation under HBM supply constraints, not a rejection of bandwidth demand.
III. NVL576 Provides System-Level Compensation—and Creates New Bottlenecks
NVL576 expands the scale-up domain from 72 to 576, effectively organizing 8 72-GPU racks into a single, larger NVLink fabric. Mechanically aggregating 21TB/s per GPU increases theoretical aggregate bandwidth from 1,512TB/s for NVL72 to 12,096TB/s for NVL576. This 8-fold figure reflects a larger system-wide bandwidth pool; it does not imply that an individual model will achieve an 8-fold linear performance gain.
As the system expands, the engineering challenge shifts from placing more HBM beside each GPU to enabling stable data exchange across hundreds of GPUs. Copper backplanes remain in use within each rack, while inter-rack connectivity requires NPO or CPO optical interconnects. When local HBM is insufficient, model partitioning, communication frequency, switch-hop count, and software parallelization efficiency will directly determine how much theoretical bandwidth can be realized.
The latest material also contains a definitional discrepancy: the body text refers to “576 Rubin Ultra packages,” while the comparison table uses “576 logical GPUs.” Until Nvidia provides a consistent definition, multiplying 576 directly by 192GB should not be treated as a confirmed total system HBM capacity. What can be confirmed is the 8-fold expansion of the scale-up domain and the corresponding increase in switching and optical-interconnect hardware.
IV. From 10+9+8 to 9+18+9: Rack Space Is Reallocated for Copper Signaling
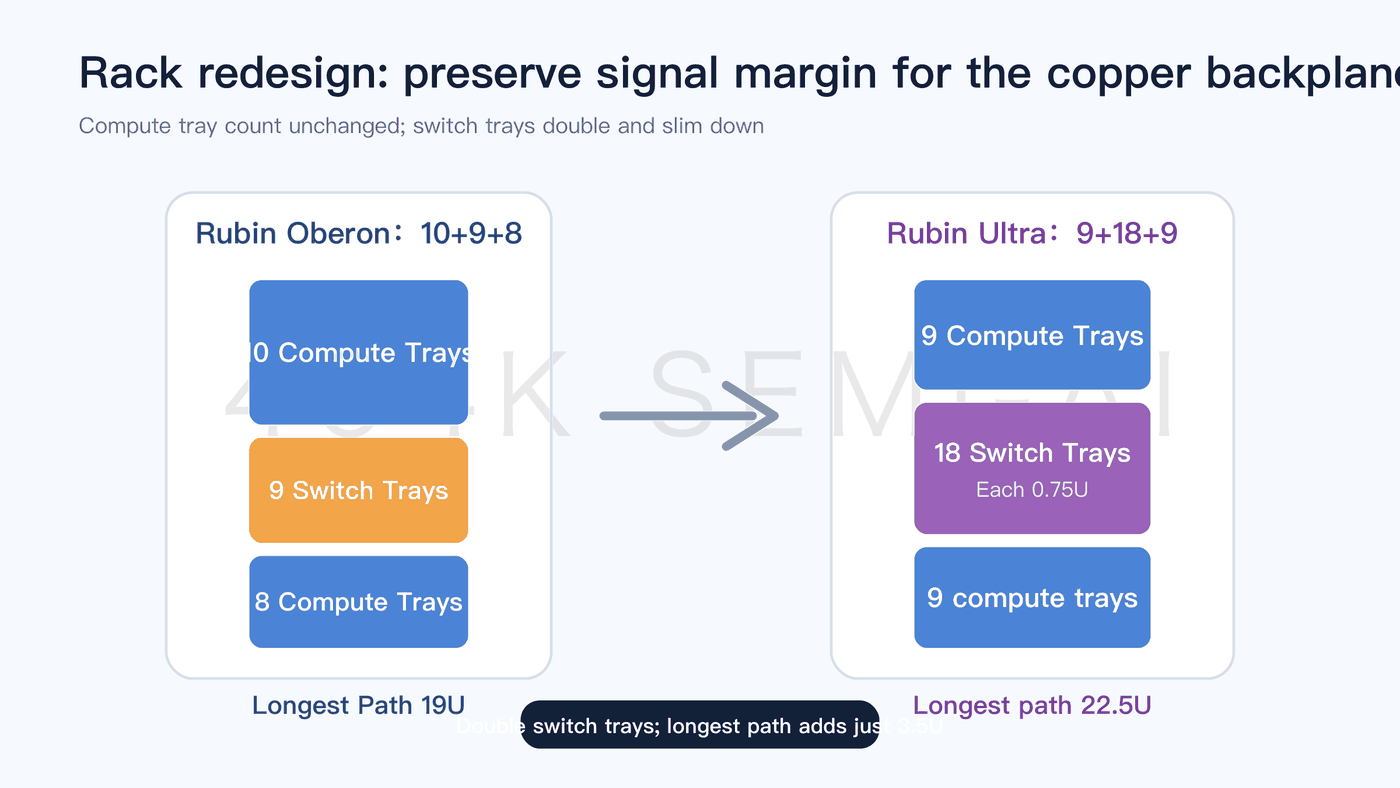
The current Rubin Oberon rack uses a 10+9+8 layout: 10 compute trays at the top, 9 NVLink switch trays in the middle, and 8 compute trays at the bottom, with each tray occupying 1U. Rubin Ultra shifts to 9+18+9: the total number of compute trays remains 18, while the number of switch trays rises from 9 to 18 and each tray’s height is reduced to 0.75U.
This layout directly addresses signal integrity. NVLink continues to run over copper backplanes within the rack. After doubling the number of switch trays, retaining the prior arrangement would make the path between the most distant compute and switch trays excessively long. Placing 9 compute trays at both the top and bottom, with 18 thinner switch trays in the middle, limits the increase in the longest path from 19U to 22.5U.
As Rubin Ultra scales the system, it simultaneously redesigns tray height, rack segmentation, backplane distance, connectors, and cooling. The new architecture allows NVL72 and NVL576 to share the same rack height and backplane foundation, with their principal differences concentrated inside the Portia switch trays.
V. Portia Is the Hardware Demarcation Between NVL72 and NVL576
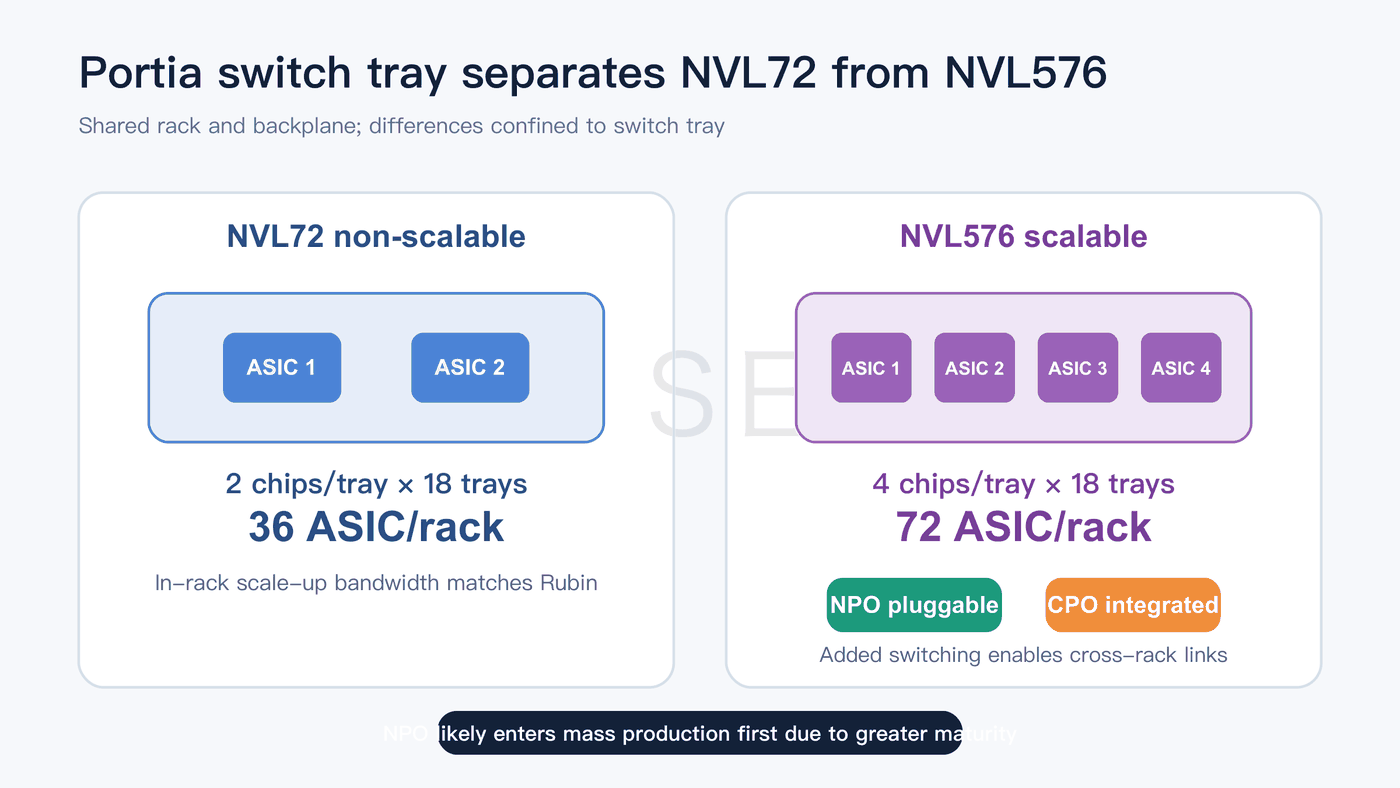
The NVL72 Portia is the non-scalable version, with only 2 NVLink switch ASICs per switch tray. Across 18 trays, the rack contains 36 ASICs—the same ASIC count and in-rack scale-up bandwidth as the current Rubin Oberon rack. This also explains why doubling the number of switch trays does not double the total switch ASIC count in the non-scalable configuration: the number of ASICs per tray is halved.
The scalable NVL576 version places 4 ASICs on each tray, for a total of 72 ASICs per rack; the additional bandwidth supports inter-rack connectivity. Two development paths are underway, NPO and CPO. NPO places pluggable optical modules close to the switch ASICs, while CPO integrates 4 non-replaceable optical engines on each ASIC. SemiAnalysis expects NPO to reach the market first because its form factor is more mature.
The commercial trade-offs are clear. NPO’s pluggability supports maintenance, replacement, and yield isolation, although some distance remains between the optical and electrical interfaces. CPO moves optics closer to the ASIC, further shortening high-speed electrical signal paths, but more tightly couples optical-engine serviceability with board-level risk. During the initial production ramp, maturity and maintainability may matter more than maximum integration.
VI. Per-System Value Is Being Reallocated Across the Supply Chain
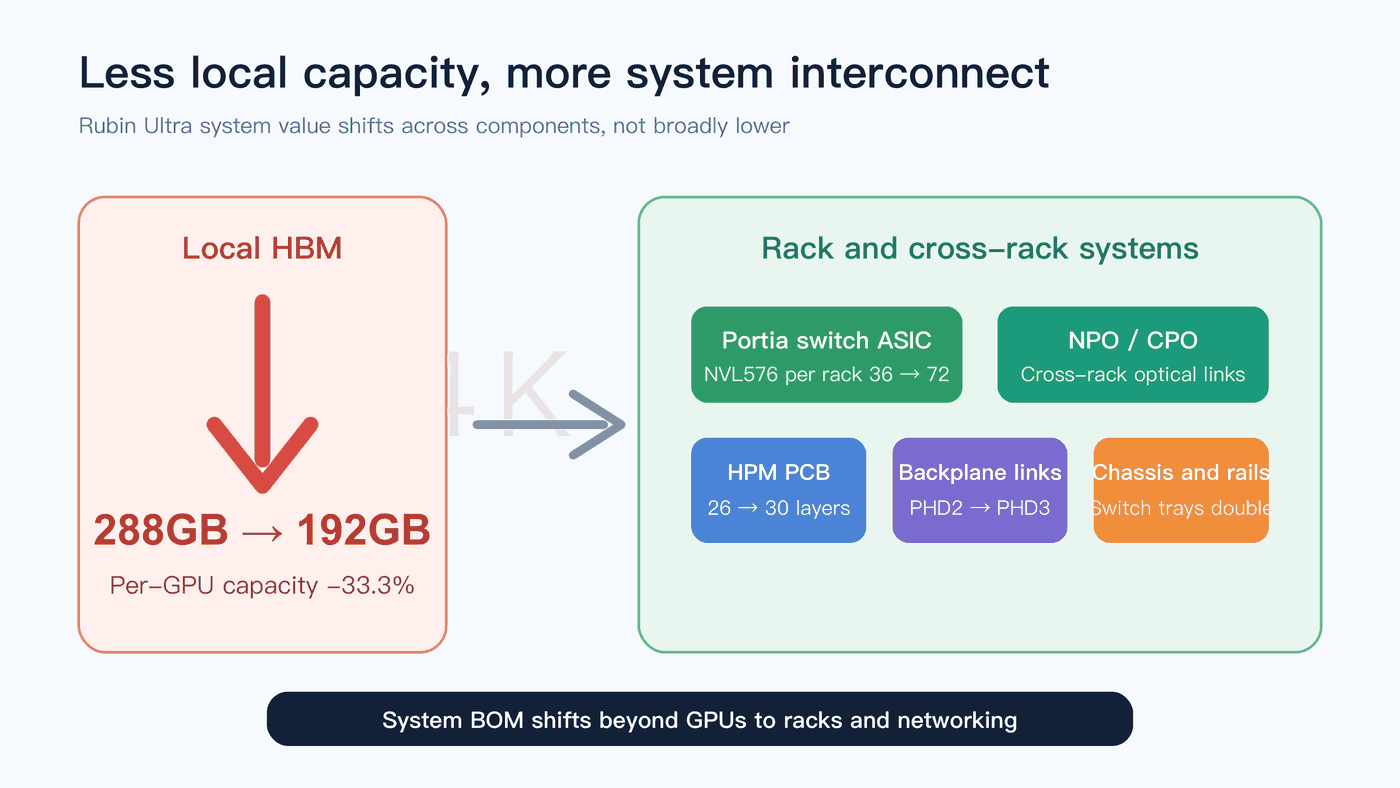
For HBM, the most direct change is the reduction in capacity per GPU from 288GB to 192GB, a 33.3% decline. If mainstream Ultra SKUs also revert from the earlier high-capacity HBM4E concept to HBM4, both the mix of higher-stack products and value per GB would be affected. However, deployment volumes, the Max-Q/Max-P SKU mix, and actual shipments of 576-scale domains will determine the volume offset; lower capacity per GPU does not necessarily imply a reversal in industry-wide HBM demand.
The implications for system hardware are clearer. The number of switch trays rises from 9 to 18, while switch ASICs per rack double from 36 to 72 in the scalable NVL576 configuration. Backplane connectors are upgraded from PHD2 to PHD3, with DP count per rack unchanged. Tachyon HPM PCBs increase from 26 layers to 30 layers, with no change in the material system. Additional switch trays also increase chassis and rail requirements. Portia’s NPO-version PCB is the most complex, while PCB area in the non-scalable version is approximately half that of the scalable version.
Rubin Ultra therefore cannot be characterized simply as “lower specifications equal lower system cost.” BOM pressure from local HBM is easing, while content per rack is increasing across switching, optical-electrical conversion, PCBs, backplanes, and mechanical components. The system’s cost and value centers are shifting away from the immediate GPU vicinity toward rack-level and inter-rack networking.
VII. Five Validation Points to Monitor
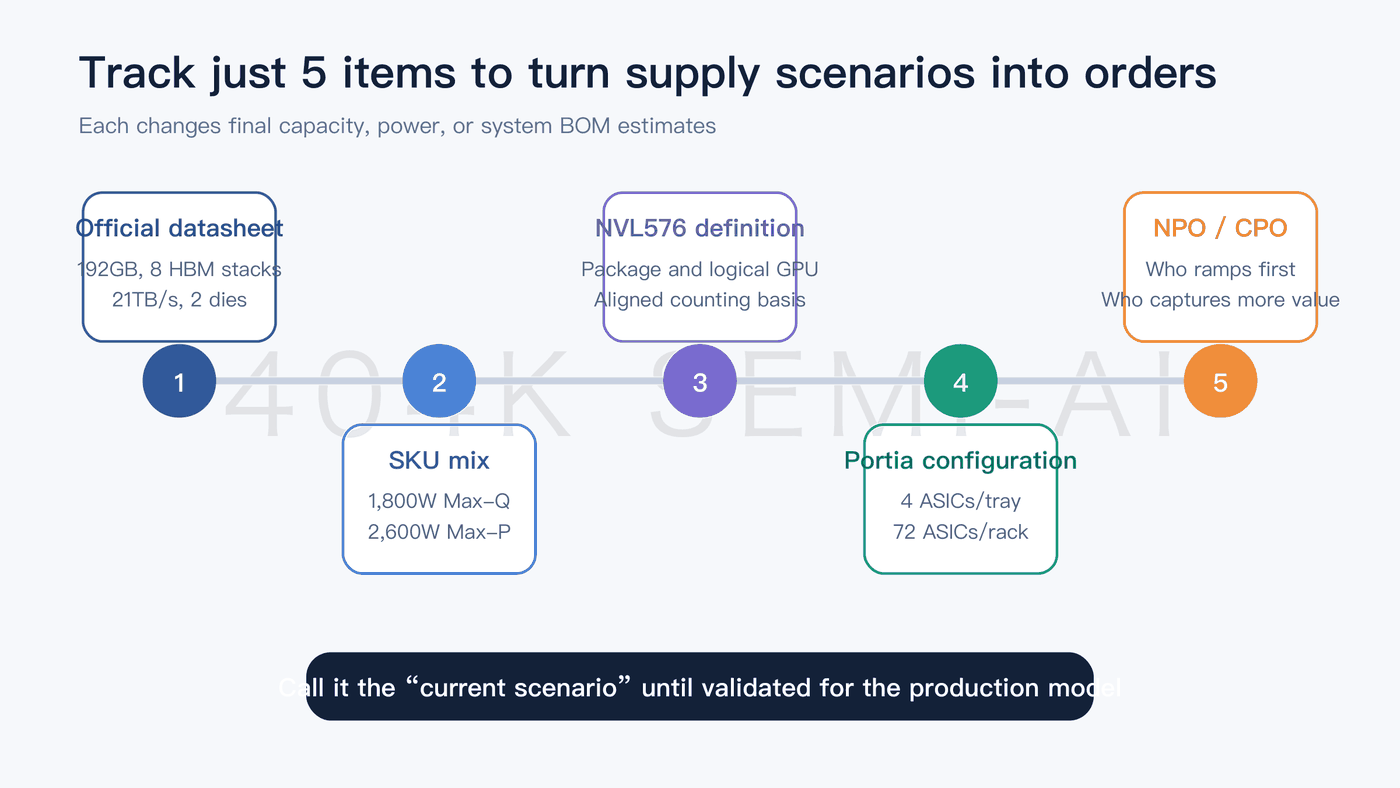
First, the official Ultra datasheet must confirm whether 192GB, 8 HBM stacks, 21TB/s, and 2 compute dies define the mainstream production configuration. Second, the SKU mix—the shipment split between the 1,800W Max-Q and 2,600W Max-P—will determine the actual trade-off among power consumption, power-delivery BOM, and per-system performance.
Third, the definition of NVL576 must reconcile “576 packages” with “576 logical GPUs” before total system HBM capacity and physical package count can be calculated rigorously. Fourth, Portia’s actual configuration must be confirmed: whether the scalable version uses 4 ASICs/tray and 72 ASICs/rack will determine switch-chip and PCB content. Fifth, the production sequence for NPO and CPO matters. If NPO leads, incremental value will skew toward pluggable modules and complex PCBs; if CPO accelerates, more value will migrate to switch ASIC and optical-engine integration.
These 5 validation points will determine whether the current supply-chain scenario translates into actual orders. Rubin Ultra reduces HBM capacity per GPU while redesigning the overall system around a larger scale-up domain, more switching hardware, and inter-rack optical interconnects. Scarcity and per-system value are migrating from local HBM capacity toward system interconnects.
Related Reading
Rubin Ultra HBM Capacity Cut to 192GB: Supply and Power Constraints Drive Roadmap Downgrade