
Nvidia Roadshow Deep Dive: GB300 Tokens per Watt, ACIE at Nearly Half of Revenue, and $1 Trillion of Blackwell and Rubin Visibility
目录
Too Long; Didn’t Read
I. The Valuation Question This Roadshow Really Rewrites
II. Company Profile: Nvidia Sells the Operating System of the AI Factory
III. The Core Roadshow Model: The AI Factory Income Statement
IV. GB300 NVL72: From Compute Performance to Throughput per Megawatt
V. ACIE: Half of Data Center Revenue Is No Longer Cloud Giants
VI. $1 Trillion Visibility: The Order Anchor for Blackwell and Rubin
7. Network Control: NVLink, Spectrum-X, and System Boundaries
8. Cash Flow and Buybacks: Platform Narratives Need Real Money
9. Physical AI: A Long-Term Option, Not the Near-Term Valuation Anchor
10. Three Worldviews: Where NVIDIA’s Valuation Debate Lies
11. Risks and Falsification: Four Variables Matter More Than Slogans
12. Tracking Checklist for the Next Four Quarters
XIII. Investment View: Still Strong, but the Market Will Demand Harder ROI Evidence
XIV. Competitive Landscape: Customer In-House Chips Will Pressure the Profit Pool, but It Is Hard to Dismantle System Control
XV. Supply-Chain Mapping: Rubin Expands the Investment Opportunity from GPUs to the Entire Rack
XVI. Valuation Back-Solving: What Results Justify a Platform-Company Valuation
XVII. How to Use This Roadshow
18. Key Data Definitions
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
This July roadshow shifts Nvidia’s investment narrative from tight GPU supply to AI factory ROI: GB300 tokens per watt, ACIE customer diffusion, and Blackwell/Rubin revenue visibility will determine whether the next leg of valuation revisions can continue, and whether the supply chain should focus on chip counts or system returns.
Too Long; Didn’t Read
The valuation anchor has shifted to tokens per watt. The most important change in this roadshow is the reframing of Nvidia from a “GPU seller” into an “AI factory system supplier.” When power, data centers, and capital become customers’ real constraints, the market should no longer look only at single-GPU ASP, but at how GB300 NVL72, NVLink, Spectrum-X, CUDA, and model software together convert 1 megawatt of power into billable tokens.
ACIE is already close to half of the data center business. FY2027 Q1 data center revenue was $75.246 billion, of which Hyperscale was $37.869 billion, while AI Clouds, Industrial, and Enterprise totaled $37.377 billion. The latter already accounted for about 49.7% of data center revenue. This means growth no longer depends only on the CapEx of a handful of cloud giants; sovereign cloud, AI cloud, industrial, and enterprise data centers are beginning to absorb the second layer of demand.
Rubin is not a distant story. The roadshow’s main thread is a one-year, one-generation system cadence across Blackwell, Blackwell Ultra, Rubin, Rubin Ultra, and Feynman, while lifting CY2025-CY2027 cumulative Blackwell and Rubin revenue visibility to more than $1.0 trillion. This framework will shift the market debate from “whether H100/H200 supply is enough this year” to whether the 2027 Rubin supply chain, HBM4, NVLink, and CPO networking can scale on schedule.
Cash flow is forming a second layer of downside protection. Nvidia’s FY2026 operating cash flow was $102.718 billion, and FY2027 Q1 operating cash flow was $50.344 billion. Under the roadshow framework, FY2026 free cash flow was $96.575 billion, and Q1 FY2027 free cash flow was $48.554 billion. Management plans to return more than 50% of free cash flow, making shareholder returns part of the valuation floor rather than merely upside optionality.
The bear-case triggers are more specific than before. The risk in this roadshow is not that AI demand disappears in one sentence, but that four numbers go wrong: whether ACIE can remain close to 50% of revenue; whether H100/H200/A100 cloud rental prices stay firm; whether GB300/Rubin truly deliver a step-change in throughput per watt; and whether China data center export restrictions, customer concentration, supply chain constraints, and power constraints slow the pace of revenue realization.
I. The Valuation Question This Roadshow Really Rewrites
The core of Nvidia’s July 2026 roadshow is not another retelling of Blackwell, but a redefinition of “AI compute” as a factory whose revenue, costs, depreciation, and cash returns can be measured. In the past, the market usually viewed Nvidia through three questions: whether GPU supply was sufficient, whether the Hopper-to-Blackwell transition was smooth, and whether cloud vendor CapEx would slow. These questions remain important, but they are no longer enough to explain the valuation logic this roadshow is trying to convey.
The main thread after the first page of the roadshow is clear: Nvidia wants investors to accept a new accounting unit. Data, power, and capital are invested into AI factories, which produce billable tokens; the higher the token output, the higher customers’ cloud revenue and AI application revenue; the faster customers recover cash, the stronger their ability to continue expanding AI factories; and the supplier best able to increase tokens per watt and reduce cost per token gains system-level pricing power.
“AI factories”
This short phrase is closer to the roadshow’s real intent than “GPU demand.” Nvidia is not merely selling a stack of accelerator cards. It is packaging GPU, CPU, DPU, NVLink, InfiniBand, Spectrum-X, CUDA, NIM, NeMo, model execution, and the developer ecosystem into the operating system of the AI factory. Chips are only the entry point of this system; what ultimately makes customers pay is the output efficiency jointly determined by racks, clusters, networking, software, and energy consumption.
This also explains why the roadshow does not center on a single chip specification. The importance of GB300 NVL72 lies not only in throughput improvements for training, inference, long context, and agentic workloads, but also in turning a higher-priced rack system into an asset that customers are willing to finance, depreciate over the long term, and keep expanding. Nvidia wants the market to believe that as long as AI applications can continue converting tokens into revenue, Nvidia can translate hardware generational upgrades into improved customer ROI, rather than a simple semiconductor replacement cycle.
The investment implication is direct: Nvidia’s valuation cannot be viewed only through the semiconductor cycle, nor only through the margin profile of traditional server components. It is more like a company that simultaneously controls the engine, transmission system, operating system, ecosystem standards, and financing credibility of the AI factory. As long as customers believe Nvidia systems can shorten payback periods, Nvidia will capture higher system share in each platform transition.
II. Company Profile: Nvidia Sells the Operating System of the AI Factory
What Nvidia is really selling today is a complete system that converts power and capital into AI output. In the company’s own official disclosures, Compute & Networking includes data center accelerated computing and networking platforms, AI solutions and software, and automotive platforms; Graphics still includes GeForce, RTX workstation, and related businesses. But the revenue structure already gives the answer: FY2026 Data Center revenue was $193.737 billion, 4.08x FY2024; FY2027 Q1 Data Center revenue was $75.246 billion, up 92% year over year and 21% quarter over quarter.
This is not an ordinary GPU product ramp. The roadshow emphasizes Nvidia as a platform layer because it controls several critical layers at once: GPUs handle parallel computing, CPUs handle general-purpose control and data orchestration, DPUs offload networking and security, NVLink and switch chips handle intra-rack and inter-rack connectivity, InfiniBand and Spectrum-X enable scale-out, CUDA and the AI software stack create developer switching costs, and all of this is packaged into AI factories that customers can deploy, finance, and operate.
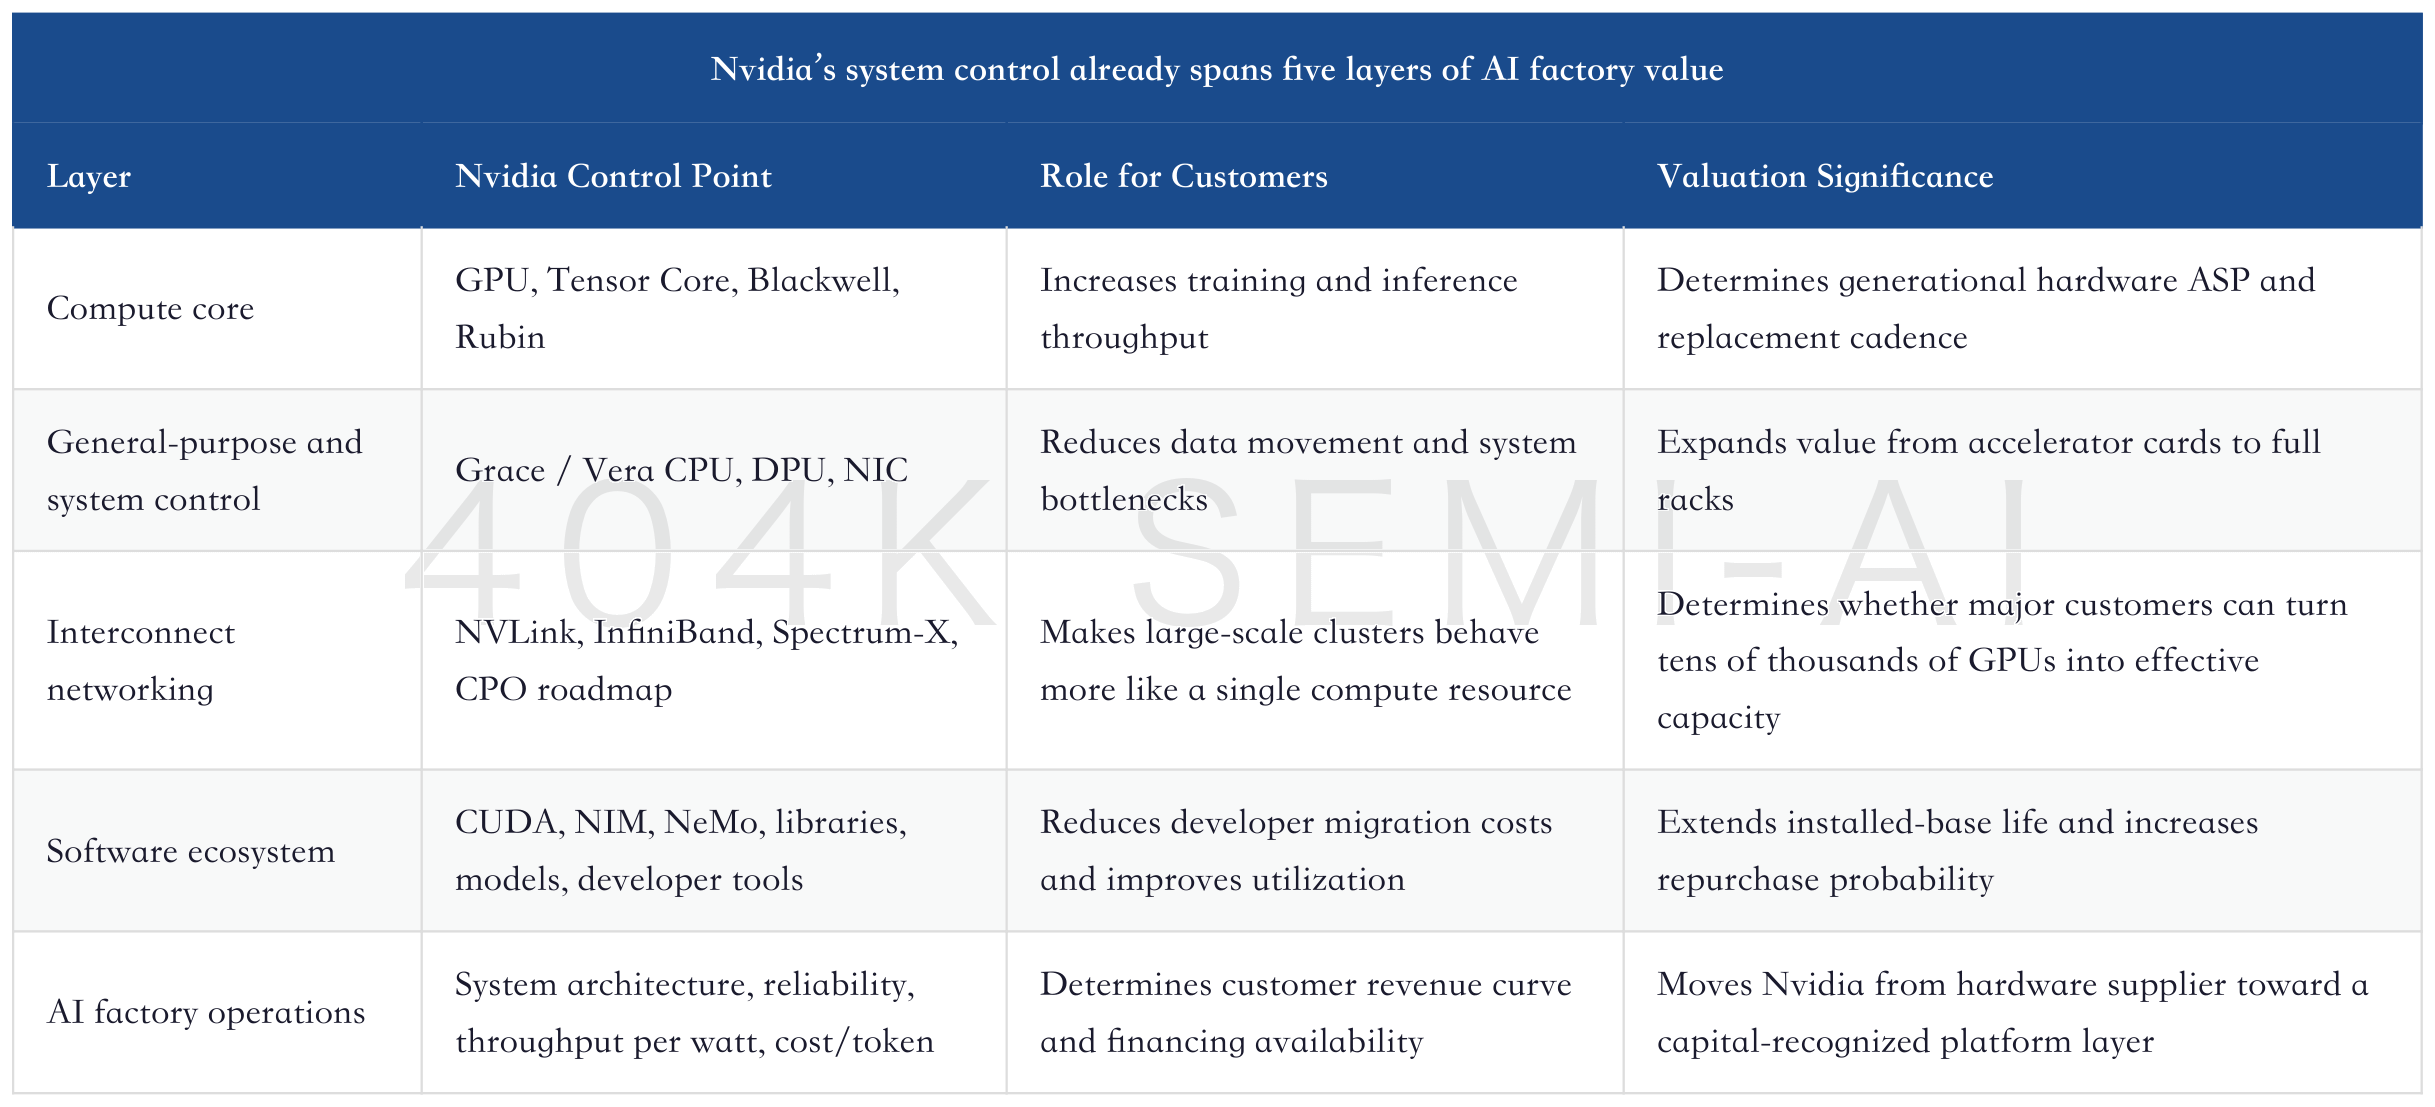
One easily overlooked detail in the roadshow is that Nvidia explicitly mentions ecosystem participants, including developers, CSPs, AI Clouds, OEMs, and enterprises, all forming different benefits around the Nvidia platform. Developers want CUDA and model libraries; cloud providers want high utilization and rentability; AI clouds want systems that can be financed, deployed quickly, and retain residual value; enterprises want AI Enterprise, NIM, and industry application templates. Together, these roles form the underlying source of Nvidia’s pricing power.
“monetizable tokens”
The “monetizable tokens” framework is critical. It links Nvidia’s revenue to customer revenue, rather than only to customer CapEx. If customers buy GPUs merely to stockpile compute, the market will quickly worry about a CapEx bubble. If customers buy systems to produce tokens that can be sold to users, the valuation debate shifts to tokens per watt, token cost, cluster utilization, and depreciation cycles.
III. The Core Roadshow Model: The AI Factory Income Statement
What NVIDIA really handed the market this time was an AI factory income statement. On the revenue side of this income statement are token output and token pricing; on the cost side are electricity, racks, depreciation, networking, operations and maintenance, and cost of capital. The key variables NVIDIA can influence are tokens produced per unit of power, the hardware and energy cost per token, and utilization over the system’s useful life.
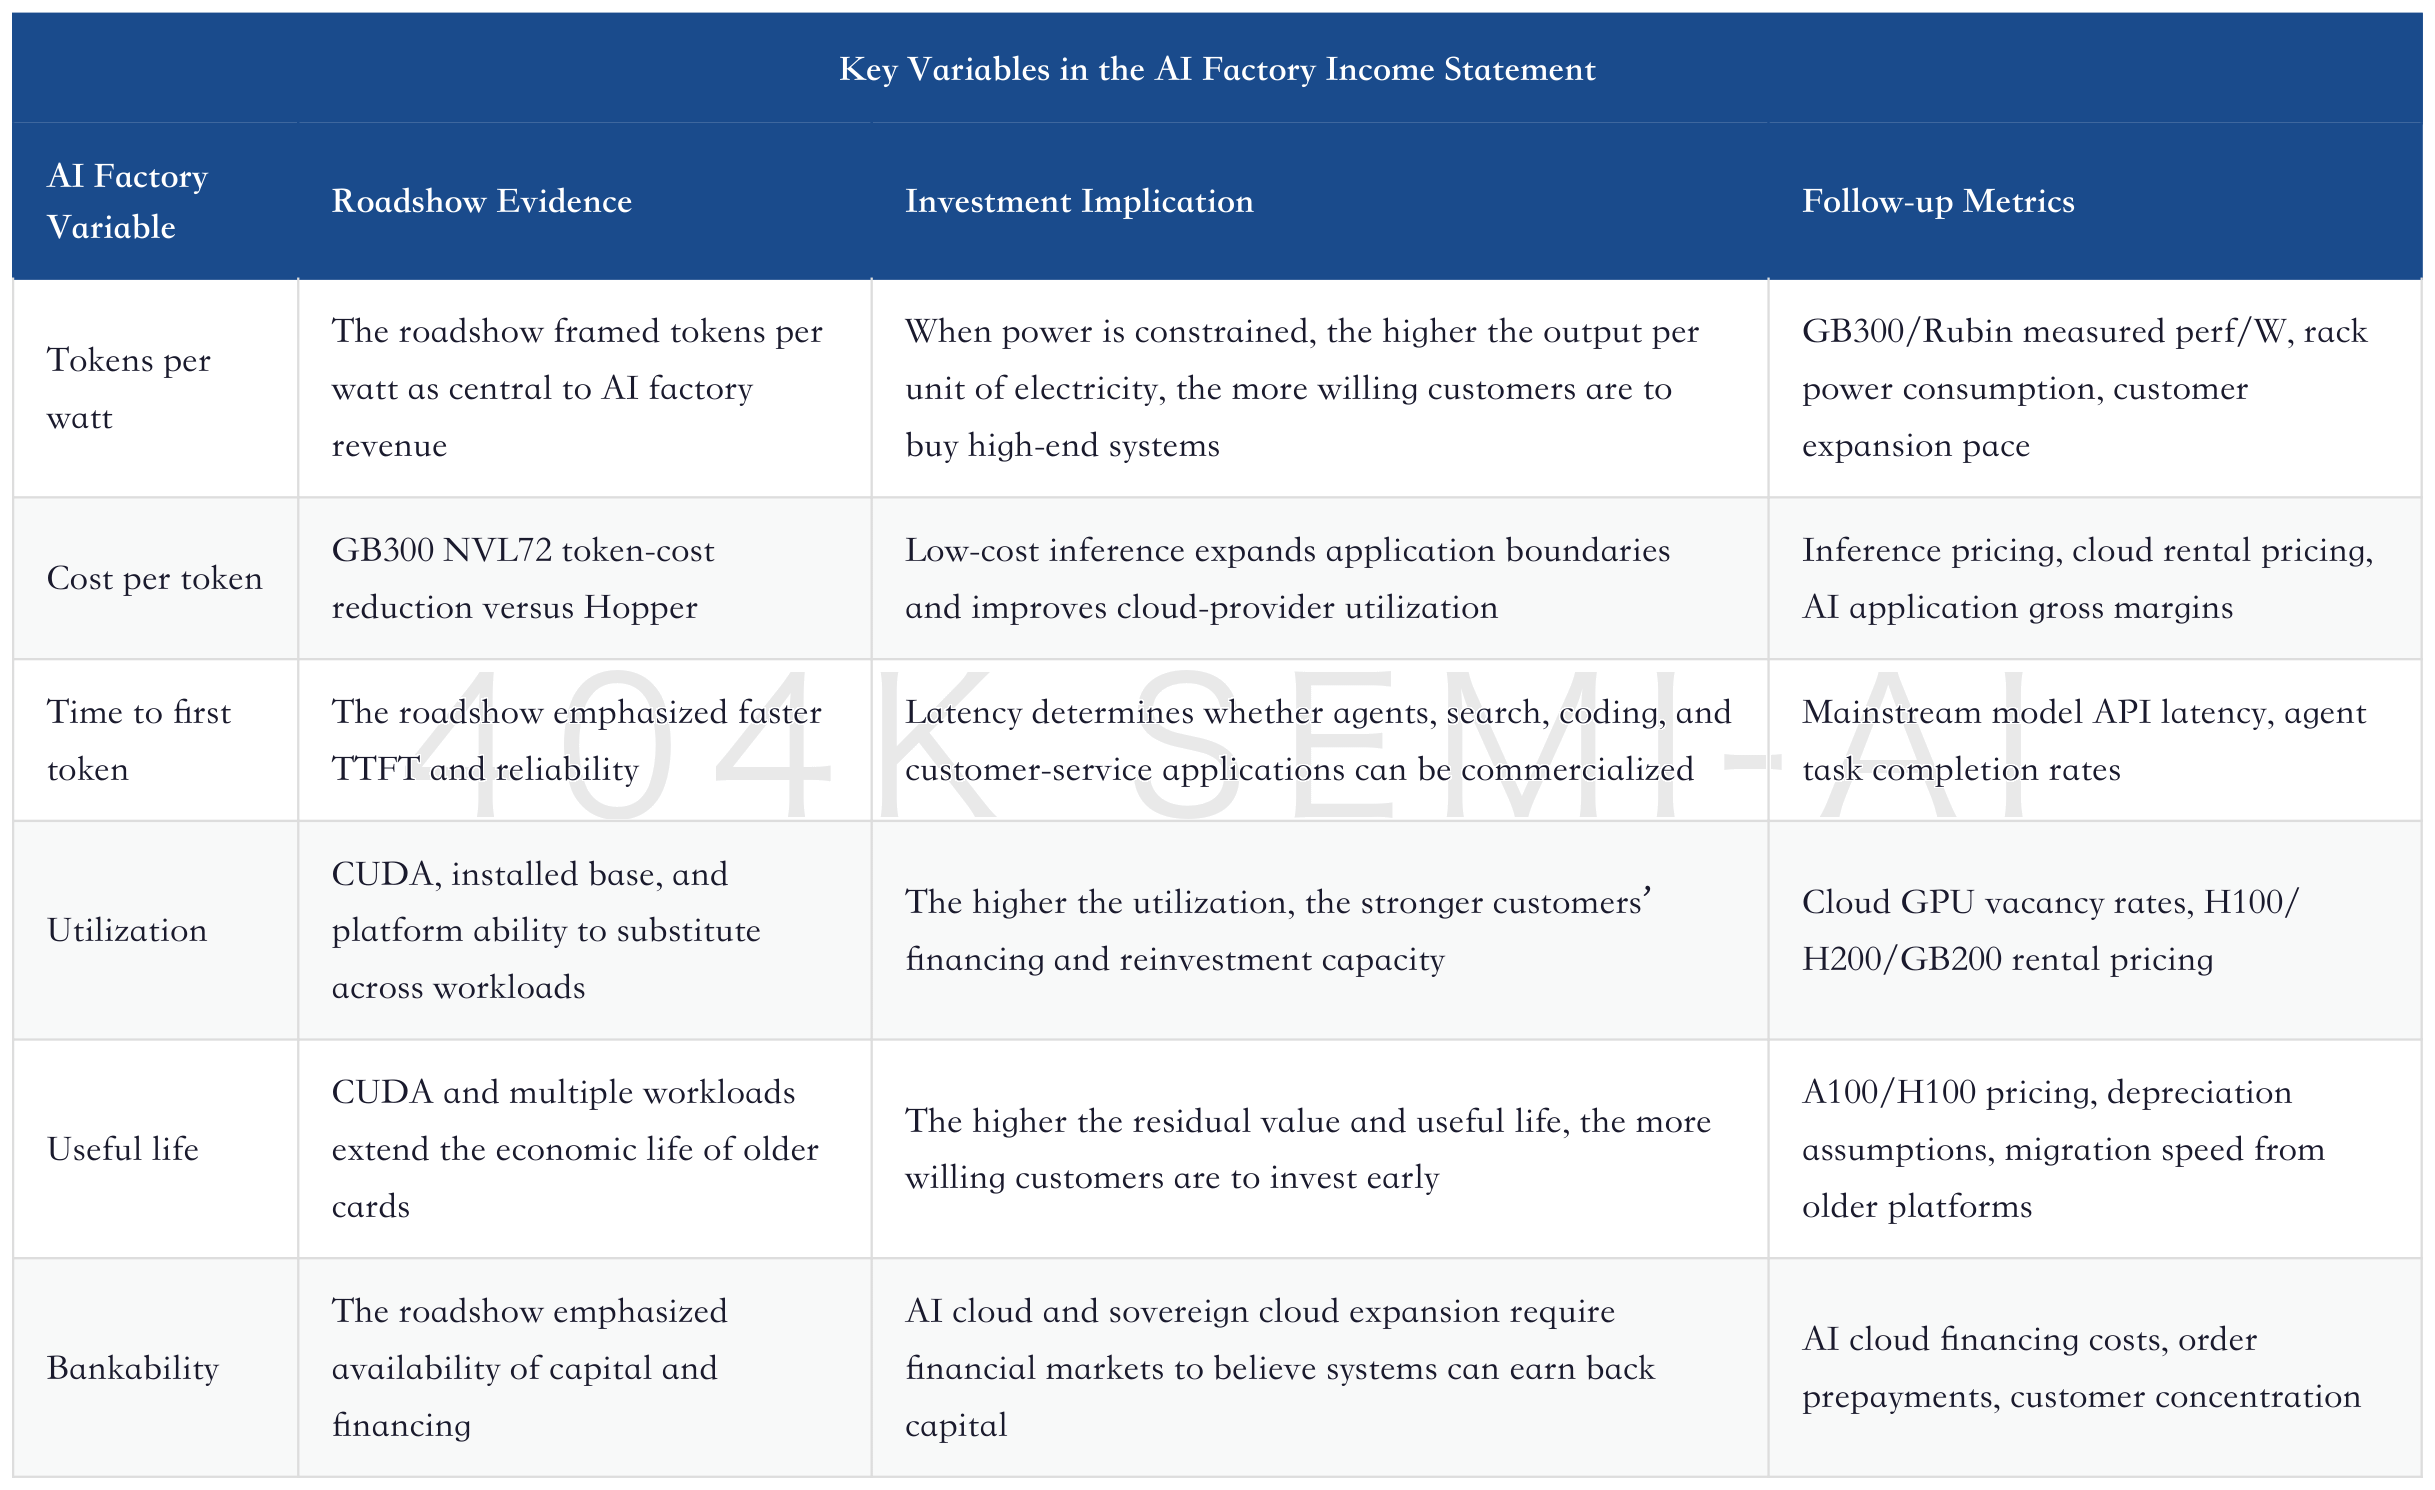
This model explains why the roadshow cited cloud GPU rental pricing. Based on the SemiAnalysis methodology used in the roadshow, A100 pricing rose 7% over the past three months and 5% over the past six months; H100 pricing rose 13% over the past three months and 21% over the past six months. If rental prices for prior-generation GPUs have not collapsed quickly, it shows the market does not view Hopper and A100 as inventory that is about to become obsolete. This matters for NVIDIA because it gives customers confidence that, after buying Blackwell/Rubin, the system will not lose its economic value within 12 months.
This judgment should be distinguished from the normal semiconductor cycle. Traditional chip companies often see inventory discounts during product transitions, as customers wait for the new platform and demand for the old platform is hollowed out. NVIDIA’s roadshow aimed to prove that CUDA, model compatibility, substitutability between AI and non-AI workloads, and the explosion in inference demand can allow older platforms to continue generating cash flow. This turns the product-generation transition from “cutting prices to clear old goods” into “the new platform expands the total market while the old platform continues to absorb long-tail workloads.”
The real risk is also here. If cloud rental prices for H100, H200, or A100 start falling continuously, or if older-platform utilization declines materially after GB200/GB300 availability improves, the market will re-discount NVIDIA’s AI factory income statement. Conversely, if older-platform prices remain firm while GB300’s throughput per watt continues to step up, the market will be willing to view NVIDIA as a platform company with the ability to manage asset residual value.
IV. GB300 NVL72: From Compute Performance to Throughput per Megawatt
GB300 NVL72 is the most important product anchor in this roadshow because it translates the performance story into a power story. Improvements in training and inference performance are not new in themselves. The real new variable is that the bottleneck in AI data centers is shifting from “whether there are GPUs” to “how many billable tasks can be run under the same power and data-center conditions.” The significance of GB300 is that it lifts the revenue curve of the same AI factory.
The performance metrics given in the roadshow all point in the same direction: GB300 is not only a faster training card, but a system that raises inference and agentic workload output per megawatt. The key numbers are shown in the table below. The core judgment in the text is that when customers are constrained by power and racks, throughput per unit of power explains the purchase rationale better than peak performance.
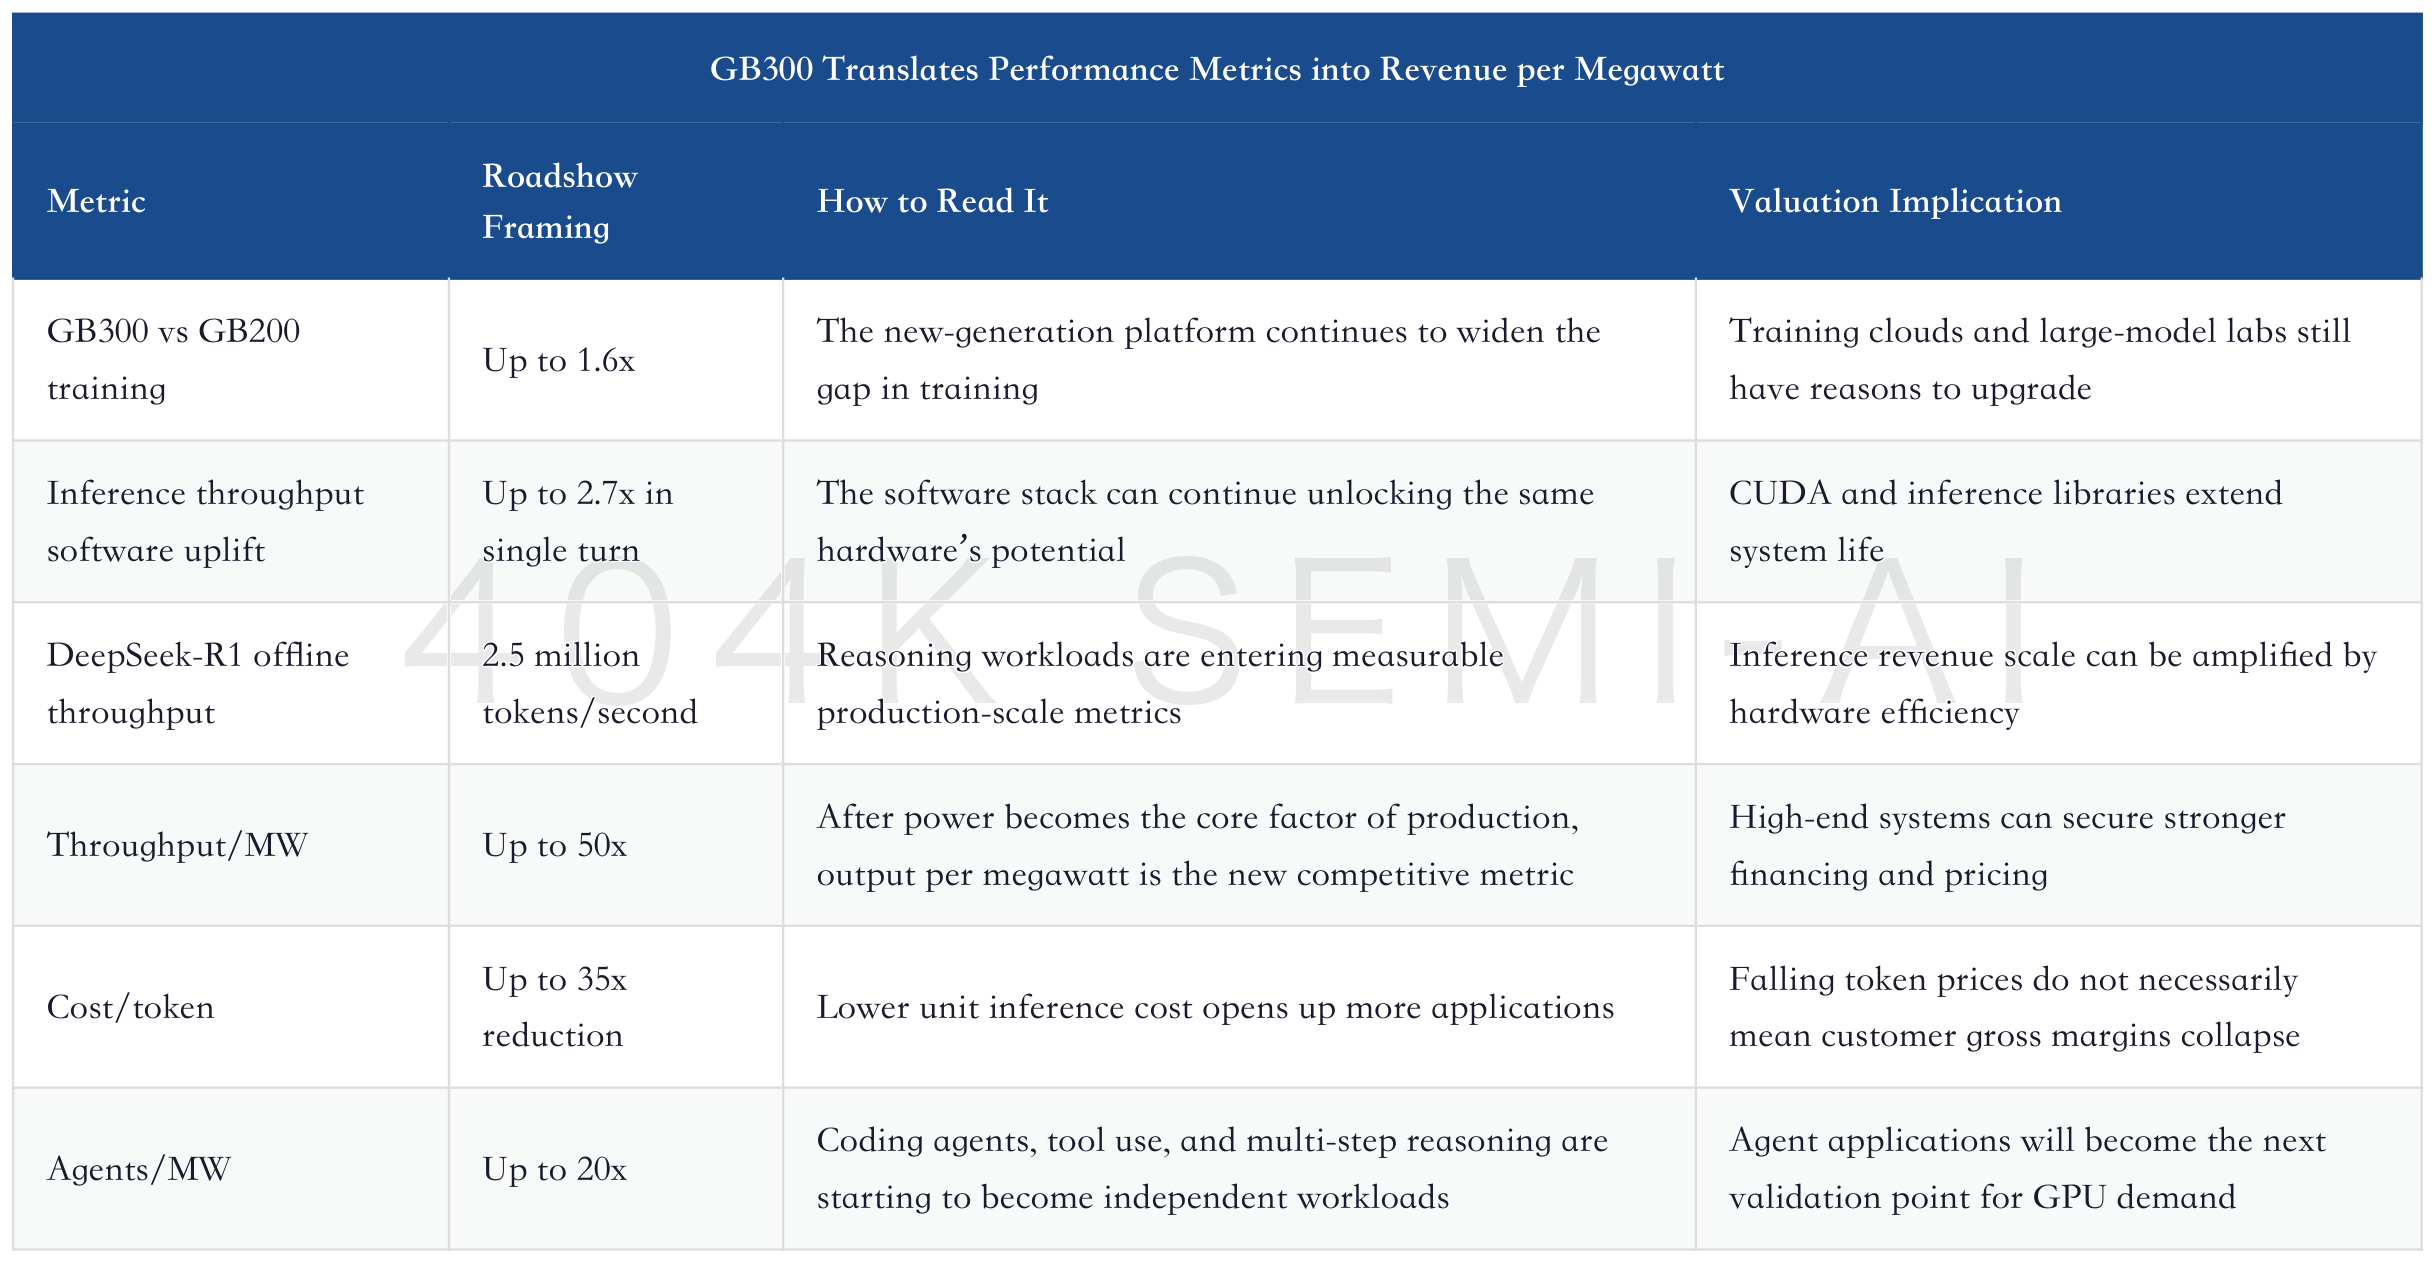
These figures need to be interpreted carefully. The roadshow uses specific benchmarks, specific models, and specific latency constraints; that does not mean every customer will immediately achieve the same benefits. More importantly, what customers ultimately calculate is not the peak benchmark, but the amount of billable workload in production per watt of power, per rack, and per dollar of capital expenditure. NVIDIA’s strength lies in translating the benchmark narrative into system-level optimization: software libraries, networking, CPUs, GPUs, memory, and model execution are tuned together, and what customers see is a decline in total cost.
NVIDIA also placed the Vera CPU along this same line. The roadshow said Vera CPU delivers 1.5x overall performance versus the latest 128-core x86, 1.6x versus the prior-generation Grace, can reach 90% of peak memory bandwidth, and has single-core memory bandwidth roughly 4x that of x86. Vera’s investment significance is not that NVIDIA wants to sell traditional CPUs, but that bottlenecks in GPU clusters are increasingly emerging in data movement, scheduling, memory bandwidth, and system coordination. Vera turns the CPU from a “server component” into part of AI factory efficiency.
If investors still value NVIDIA only by counting GPUs, they will underestimate this kind of system control. Single-card pricing can be targeted by competitors; rack- and cluster-level efficiency is much harder to replace. NVIDIA is iterating CPUs, GPUs, DPUs, NVLink, Spectrum, software, and model services as one integrated system precisely so that when customers evaluate AI factory ROI, it becomes very difficult to replace any single layer in isolation.
V. ACIE: Half of Data Center Revenue Is No Longer Cloud Giants
ACIE is the structural datapoint in this roadshow that is most easily underestimated. The market has long worried that NVIDIA’s revenue is overly dependent on a small number of cloud giants. In particular, when the CapEx cadence of Microsoft, Amazon, Google, Meta, or Oracle is questioned by the market, NVIDIA’s valuation tends to be compressed as well. The July roadshow and the FY2027 Q1 10-Q provide a counterpoint at the same time: Hyperscale remains large, but non-Hyperscale customers across AI Clouds, Industrial, Enterprise, and Sovereign are already approaching half of Data Center revenue.
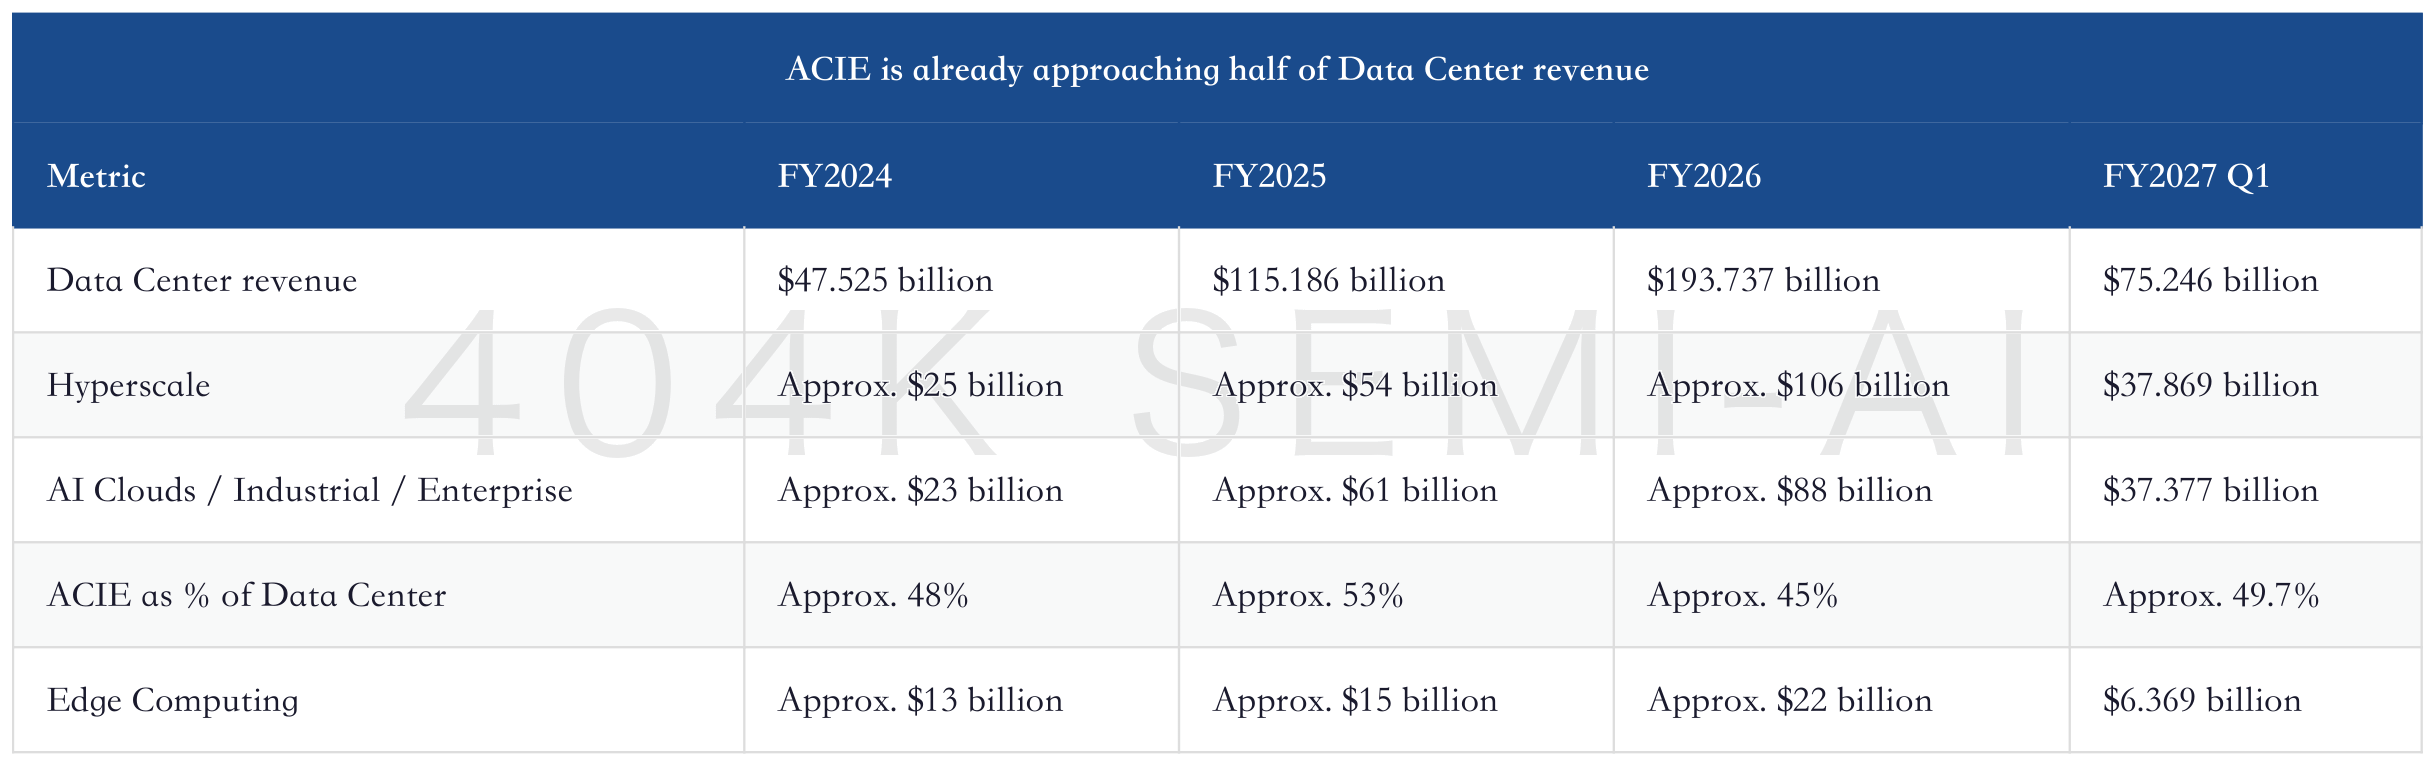
The official FY2027 Q1 disclosure states it more directly: Hyperscaler revenue sequentially increased and remained at approximately 50% of Data Center revenue; the remaining 50% came from AI Clouds, industrial, enterprise, and sovereign customers. This is not a one-off change in reporting definition. NVIDIA is actively splitting revenue into Data Center and Edge Computing, and further splitting Data Center into Hyperscale and ACIE. In other words, the company wants the market to track growth by customer type going forward, rather than extrapolating crudely from “aggregate cloud vendor CapEx.”
ACIE growth matters for valuation in three ways. First, it shows that demand is not coming only from consumer internet and public cloud. AI clouds, sovereign clouds, industrial customers, and enterprise use cases are beginning to build their own AI factories. Second, it increases NVIDIA’s pricing power, because non-cloud-giant customers are often more dependent on NVIDIA’s full reference architecture and ecosystem, and are less likely than the largest cloud vendors to deeply in-source the entire stack. Third, it makes revenue growth more diversified, but also introduces more complex financing, delivery, and credit risks.
This does not mean customer concentration risk has disappeared. The FY2027 Q1 10-Q disclosed that three direct customers accounted for 21%, 17%, and 16% of total revenue, respectively, all primarily from Compute & Networking. In FY2026 annual disclosures, one direct customer accounted for 22% and another for 14%. NVIDIA’s wording also distinguishes between direct customers and indirect customers: some AI model companies, AI clouds, and end enterprises purchase through system integrators, ODMs, distributors, or cloud services. Therefore, direct-customer concentration is not the same as end-demand concentration, but it does affect collections, order cadence, and supply-chain planning.
From an investment perspective, ACIE should be viewed as “growth becoming less cloud-giant-centric,” not as “risk disappearing completely.” If ACIE remains at 45%-55%, it would show that sovereign clouds, AI clouds, and enterprise AI factories have indeed absorbed the second layer of demand. If the ratio falls below 35% while hyperscaler CapEx slows, the market will again discount NVIDIA’s revenue visibility. Conversely, if ACIE continues to grow rapidly while hyperscale remains around 50%, NVIDIA will have a thicker revenue curve than one driven by a single cloud CapEx cycle.
VI. $1 Trillion Visibility: The Order Anchor for Blackwell and Rubin
“More than $1 trillion of cumulative Blackwell and Rubin revenue visibility” is the heaviest valuation anchor in the roadshow. This figure covers CY2025-CY2027. It should not be simplistically interpreted as fully signed, non-cancellable orders, nor should it be equated with accounting revenue. It is more like the company’s integrated assessment of serviceable demand for the next two platform generations, customer deployment plans, supply-chain capacity, and system pricing. The real question for the market is which demand layers support this visibility, and which variables could convert it into revenue or force a discount.
The roadshow’s answer includes four layers. The first is continued buildout by existing hyperscalers, especially for training, inference, and internal AI services. The second is AI Clouds and NCPs, customers that operate GPU/AI factories as cloud rental assets and care most about financing capacity, utilization, and residual value. The third is enterprise, industrial, and sovereign AI. Demand may be less concentrated than among cloud giants, but it will be more dependent on NVIDIA reference architectures. The fourth is physical AI, including robotics, autonomous driving, manufacturing, simulation, and edge deployment.
Rubin Will Consume Smartphone Memory in 2027: Why NVIDIA Is Taking Smartphone Memory — How Vera Rubin Rewrites DRAM Capacity Priorities
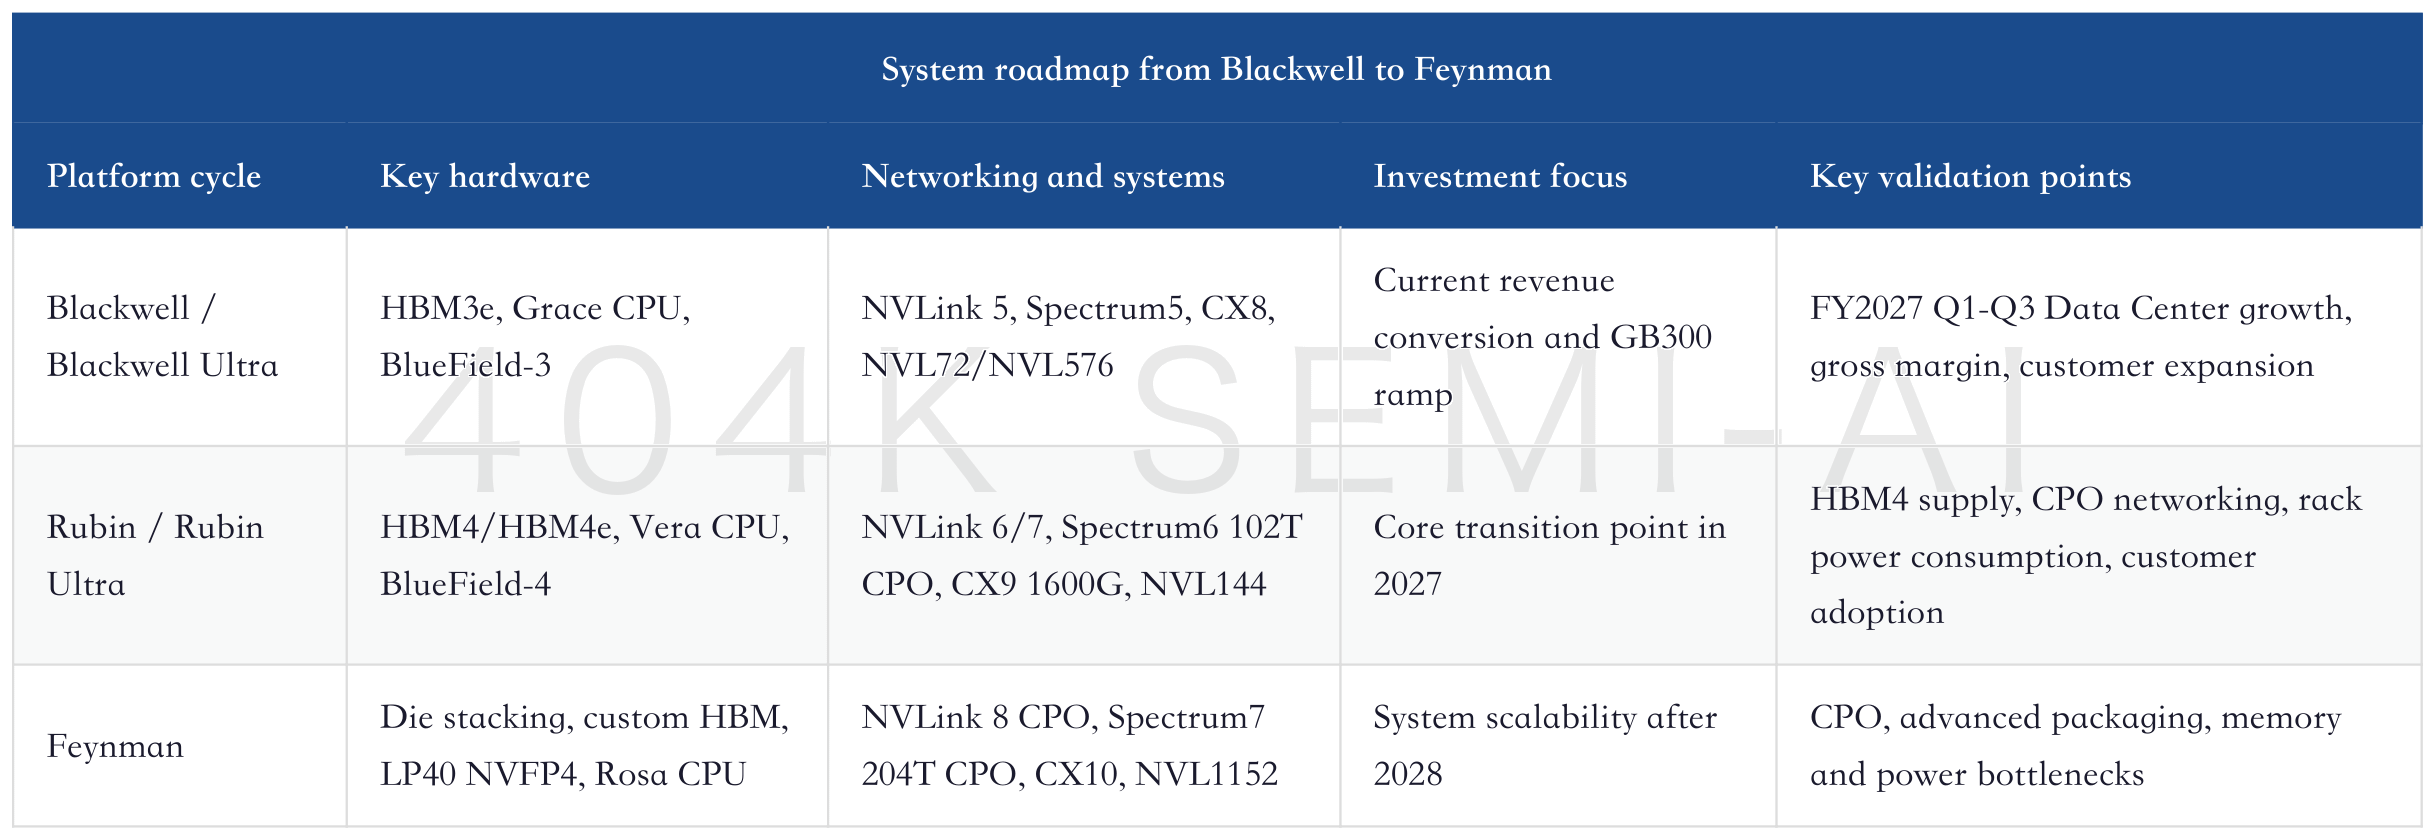
Rubin is not just a new GPU. It will simultaneously drive HBM4, Vera CPU, NVLink 6/7, CPO, Spectrum6, CX9, and higher-density racks. In other words, Rubin is a system-level supply-chain repricing. If NVIDIA can transition smoothly from Blackwell to Rubin on the roadshow timeline, it will convince customers that an annual architecture cadence is not a risk, but a normal upgrade path that improves AI factory ROI. If Rubin is delayed in HBM4, CPO, rack power consumption, or reliability, the market will discount the $1 trillion visibility for execution risk.
Rubin Rack Revaluation: GPU Share Falls to 51%, AI Hardware Value Is Migrating Toward Memory, PCB, Power, and Liquid Cooling. Who Is Absorbing the Incremental AI Hardware Spend?
This also explains why NVIDIA’s investment spillover is not limited to GPU foundry. HBM, advanced packaging, PCB, power, liquid cooling, optical interconnect, CPO, connectors, and high-end server ODMs will all see value reallocated as AI factory architectures change. The stronger NVIDIA’s system-level control, the easier it is for the upstream supply chain to reorganize production around its rack specifications. But similarly, if any part of the supply chain fails to keep up, it will in turn constrain NVIDIA’s revenue cadence.
Deep Update on AI Hardware: How PCB, CPO, and MLCC Become the Three Physical Gates for Rubin Racks
7. Network Control: NVLink, Spectrum-X, and System Boundaries
Nvidia’s moat is expanding from GPU cores to the network edge. An AI factory is not simply a stack of many GPUs. The real difficulty is connecting thousands, tens of thousands, or even hundreds of thousands of accelerators into a schedulable, fault-tolerant, high-utilization system. In this system, network latency, bandwidth, congestion control, communication libraries, and model-parallel strategies directly determine how much training and inference throughput customers actually receive.
The roadshow roadmap places NVLink, Spectrum, ConnectX, and CPO in positions as important as the GPU. The Blackwell phase includes NVLink 5, Spectrum5 51T, and CX8 800G; the Rubin phase advances to NVLink 6/7, Spectrum6 102T CPO, and CX9 1600G; the Feynman phase moves further to NVLink 8 CPO, Spectrum7 204T CPO, and CX10. This cadence shows that Nvidia wants to control not only in-rack interconnects, but also cluster scaling and the network-chip upgrade path.
AI Network Control Among Nvidia, Broadcom, and Marvell Technology — Nvidia’s 2026 Closed Loop and the Battle Against Broadcom’s Open Networking
There is an important set of divergences here. The advantages of Nvidia’s closed-loop networking are performance, tuning, software compatibility, and end-to-end accountability; the advantages of the open-networking route are customer choice, cost transparency, and avoiding single-vendor lock-in. Cloud giants will continue to push down the closed-loop premium, while ASICs, XPUs, and the open Ethernet camp will also compete for network value. But in the most complex training, long-context, and low-latency agentic inference workloads, system-tuning costs are high, and Nvidia’s closed-loop solution remains more likely to deliver stable returns first.
Network control will determine whether Nvidia can preserve system-level gross margin. If customers only buy GPUs and split networking, switches, CPUs, and the software stack among other suppliers, Nvidia’s profit pool will be compressed back to accelerator cards. If customers continue to accept the closed-loop combination of NVLink/Spectrum/CUDA for performance and delivery stability, Nvidia can incorporate network revenue, system revenue, and the software ecosystem into the same AI factory ROI framework.
8. Cash Flow and Buybacks: Platform Narratives Need Real Money
This roadshow holds up not only because the technology roadmap is compelling, but also because cash flow already supports its capital narrative. Nvidia’s current cash-generation pace is already sufficient to serve supply-chain capacity lock-ins, platform R&D;, and large-scale buybacks at the same time. The specific cash-flow and free-cash-flow metrics are shown below. What matters is not how high any single quarter is, but whether this cash conversion can continue through the Rubin transition.
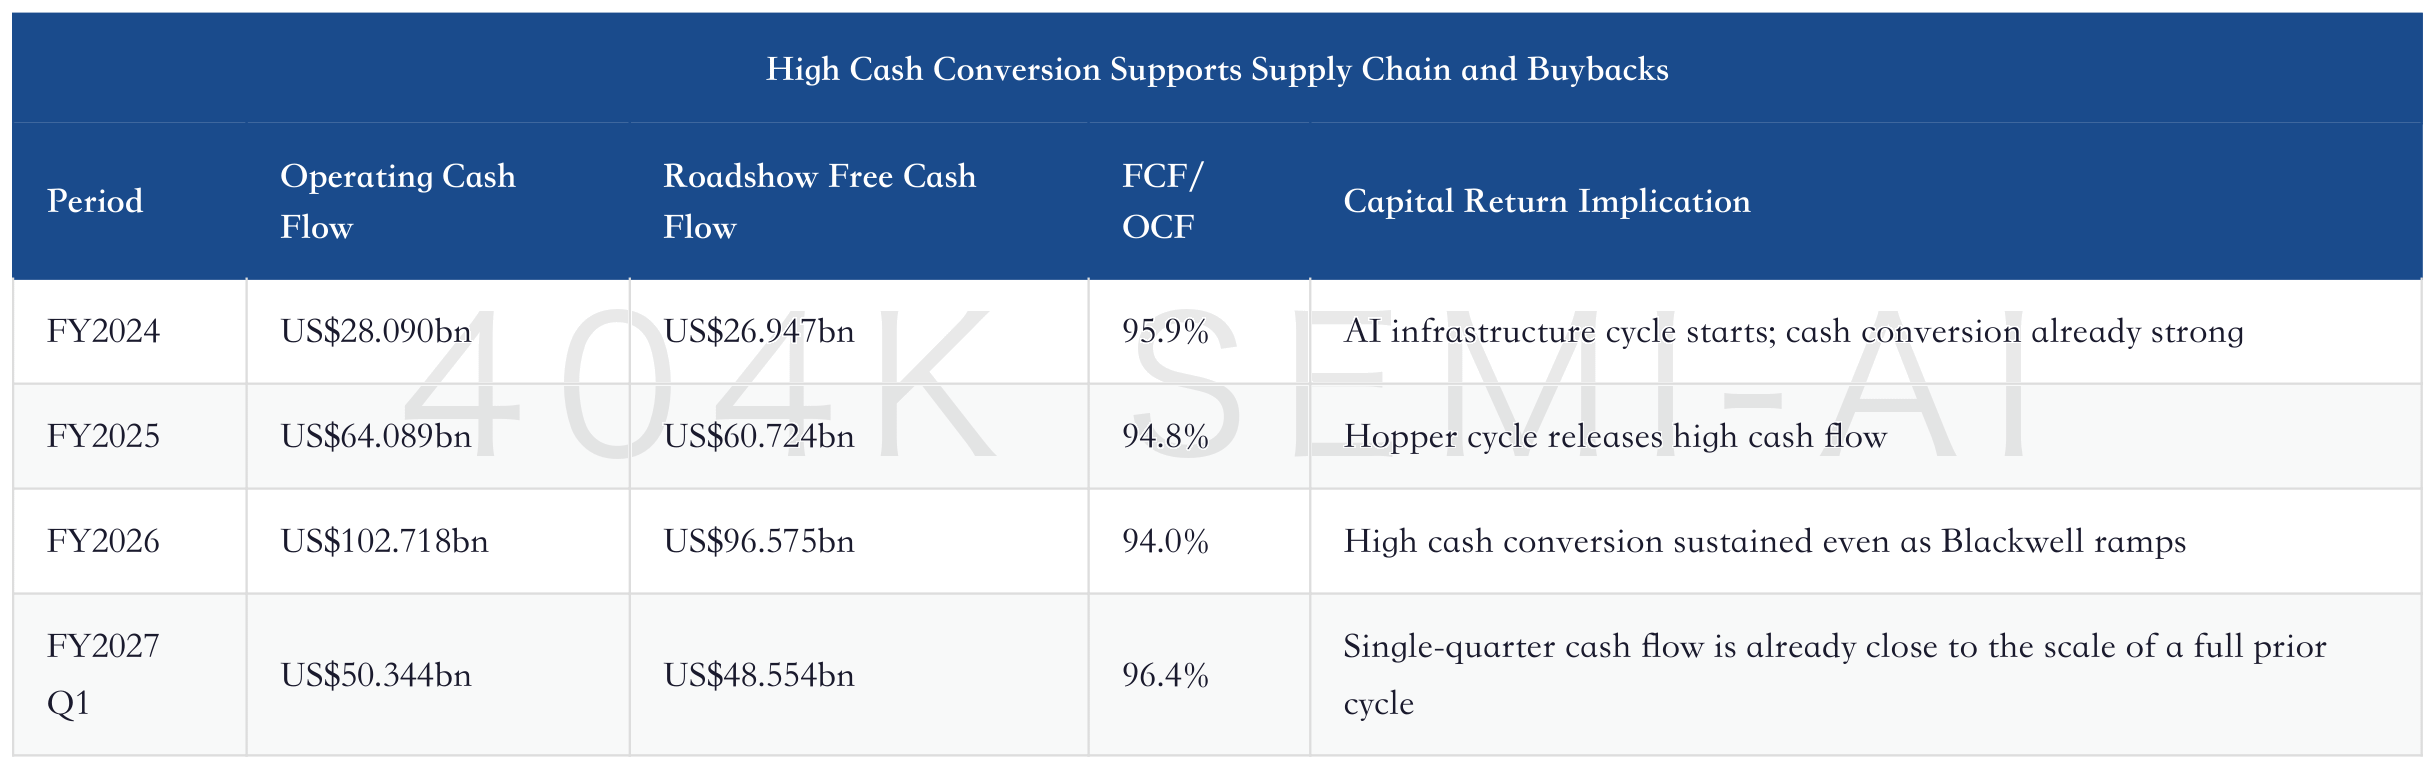
This cash-flow structure gives Nvidia two options. The first is a supply-chain option: high free cash flow allows the company to lock in HBM, advanced packaging, wafers, substrates, networking chips, and manufacturing capacity in advance, reducing the risk that customer demand is strong but supply cannot keep up. The second is a shareholder-return option: management’s proposal to return more than 50% of free cash flow means that, as long as AI factory revenue continues to materialize, buybacks will become part of the support for EPS and valuation.
In-Depth Analysis of Nvidia Earnings: Blackwell Delivery, AI Factory Acceleration, Surging Network Revenue, Continued AI Infrastructure Pricing Power, and Accelerated Share Buybacks to Reward Shareholders
It is important to note that strong cash flow does not mean capex risk has disappeared. Nvidia’s FY2026 10-K disclosed an inventory balance of US$21.4bn and outstanding inventory purchase, long-term supply, and capacity obligations of US$95.2bn, a substantial portion of which relates to inventory purchases. To serve Blackwell/Rubin demand, Nvidia must lock in the supply chain in advance, which magnifies the financial consequences of any demand-forecasting error. The US$4.5bn charge related to H20 inventory and purchase obligations in FY2026 Q1 is a clear reminder.
So the roadshow’s “US$1tn visibility” and “returning more than 50% of free cash flow” should be read together. The former indicates that the company believes demand is sufficient to support its supply-chain commitments; the latter indicates that the company has the capacity to return cash to shareholders. If demand continues to materialize, the two will reinforce each other. If policy, customer capex, or product transitions lead to order cancellations, supply-chain commitments will first weigh on gross margin and cash flow, then reduce buyback capacity.
9. Physical AI: A Long-Term Option, Not the Near-Term Valuation Anchor
Physical AI is a long-term opportunity, but the near-term valuation anchor in this roadshow remains the data center. Nvidia groups manufacturing, robotics, autonomous driving, and heavy industry under physical AI, and describes a US$50tn market and a long-term multi-trillion-dollar opportunity. The market has significant imaginative scope because it pushes AI from text, images, and code on screens into factories, vehicles, warehouses, and robots.
The product chain in the roadshow is Train, Simulate, Run: DGX on the training side, Omniverse and Cosmos on the simulation side, and Jetson Thor on the run side, supported by models and development frameworks such as Isaac GR00T and Alpamayo. Nvidia’s message is that it is not only training large models in the cloud, but also using the same GPU, simulation, and software ecosystem to enter robotics and industrial AI.
This line needs to be viewed in layers. In the near term, physical AI’s revenue contribution is still difficult to compare with Data Center; it is more like a new growth option for Edge Computing, industrial enterprises, and the automotive business. In the medium term, it will elevate the strategic meaning of ACIE, because industrial, enterprise, sovereign-cloud, and edge deployments will form a demand curve different from hyperscale. In the long term, if robotics and autonomous-driving models begin large-scale training, simulation, and inference, physical AI will bring Nvidia another round of data-center and edge-system demand.
From an investment perspective, physical AI should not be treated as an income-statement item that will materialize immediately. It is better placed in a scenario framework: in the base case, it supports continued ACIE expansion; in the upside case, it turns industrial and robotics customers into new buyers of AI factories; in the cautious case, it remains in the developer ecosystem and industry pilots, with limited ability to offset cloud capex volatility in the short term.
10. Three Worldviews: Where NVIDIA’s Valuation Debate Lies
The debate over NVIDIA is not whether it is the strongest company in the AI industry, but how much revenue visibility, how high a system-level margin, and how strong a capital-return discount the market should assign to it. The July roadshow gave the bulls plenty of ammunition, but it also made the counterevidence clearer. A better reading is not a one-sided bull or bear view, but to place NVIDIA within three worldviews.
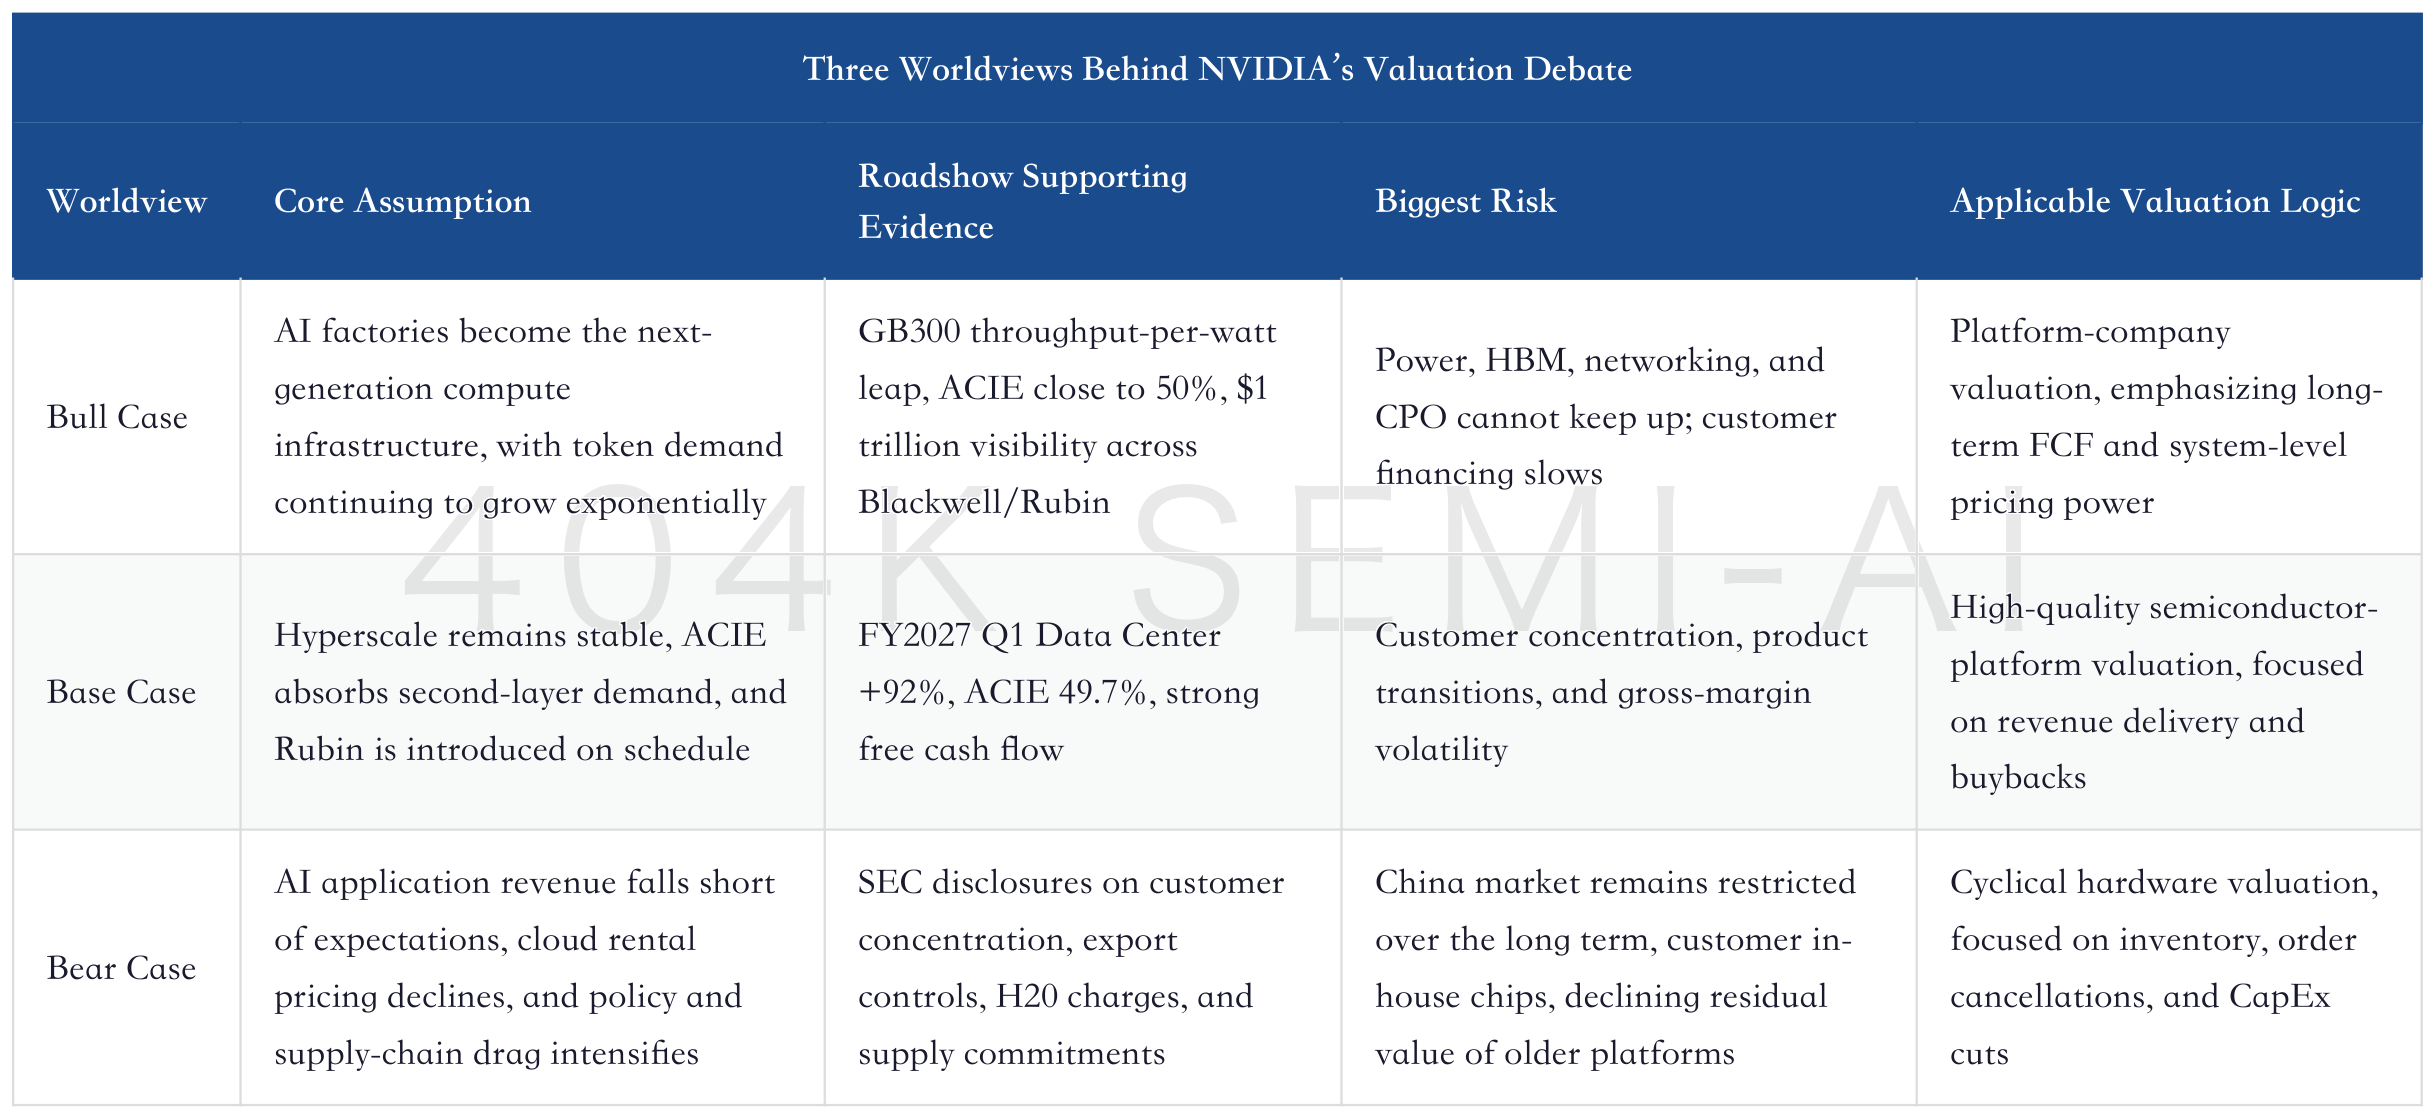
In the bull case, NVIDIA’s value comes from its standard-setting power in AI factories. It is not merely a supplier, but the core reference architecture for customer financing, facility buildout, operations, and application monetization. In the base case, NVIDIA remains an exceptionally strong system-level semiconductor company; revenue growth and cash flow are sufficient to support a higher valuation, but the market will continue to demand proof that the transition from Blackwell to Rubin is not interrupted. In the bear case, the economics of AI factories come under question, and NVIDIA is pulled back into a hardware-cycle framework, with inventory, customer concentration, and export controls amplifying valuation drawdown.
This roadshow was clearly designed to reinforce the overlap between the bull case and the base case. It did not try to prove that AI applications are already broadly profitable. Instead, it repeatedly emphasized tokens per watt, cloud GPU pricing, customer diversification, and cash flow. In other words, NVIDIA wants the market to believe that even if the application layer is still in rapid trial-and-error mode, the economics of the underlying AI factory are already strong enough to support continued customer expansion.
11. Risks and Falsification: Four Variables Matter More Than Slogans
NVIDIA’s biggest risk is not an abstract “AI bubble,” but several measurable variables weakening at the same time. If these variables remain strong, the platform narrative in the roadshow will continue to reinforce itself; if they start to weaken, the market will quickly shift from AI factory ROI back to the hardware cycle and customer CapEx.
First, cloud GPU rental pricing. The roadshow cited rising A100 and H100 prices to prove that installed assets remain scarce, rentable, and monetizable. If A100/H100/H200 rental prices continue to fall, it would indicate that the residual value and utilization of older platforms are starting to weaken, and customers’ financing assumptions for new platforms would also be discounted.
Second, ACIE share. In FY2027 Q1, ACIE accounted for about 49.7% of Data Center, the most important data point for customer diffusion. If ACIE remains close to 50%, it suggests AI cloud, industrial, enterprise, and sovereign customers are genuinely taking over demand; if it falls below 35%, it would suggest growth remains primarily tied to a handful of hyperscalers.
Third, the Rubin supply chain. Rubin involves HBM4, Vera CPU, NVLink, CPO, advanced packaging, rack power delivery, and liquid cooling at the same time. Any delay in one link would affect CY2027 revenue visibility. NVIDIA’s official 10-Q also acknowledges that the Rubin platform is expected to begin shipping in the second half of FY2027, and that the complex architecture and system configurations could result in production delays, quality issues, inventory provisions, lower yields, and higher material costs.
Fourth, policy and China’s data center market. NVIDIA disclosed in its 10-Q that as of the end of FY2027 Q1, although it can sell non-controlled products into China, such as gaming and workstation GPUs, it is effectively excluded from China’s data center compute market. H20 export restrictions have already resulted in a $4.5 billion charge in FY2026 Q1, and H200 licenses have still generated no revenue. This risk affects not only China revenue, but also global customers’ confidence in purchasing advanced U.S. semiconductors.
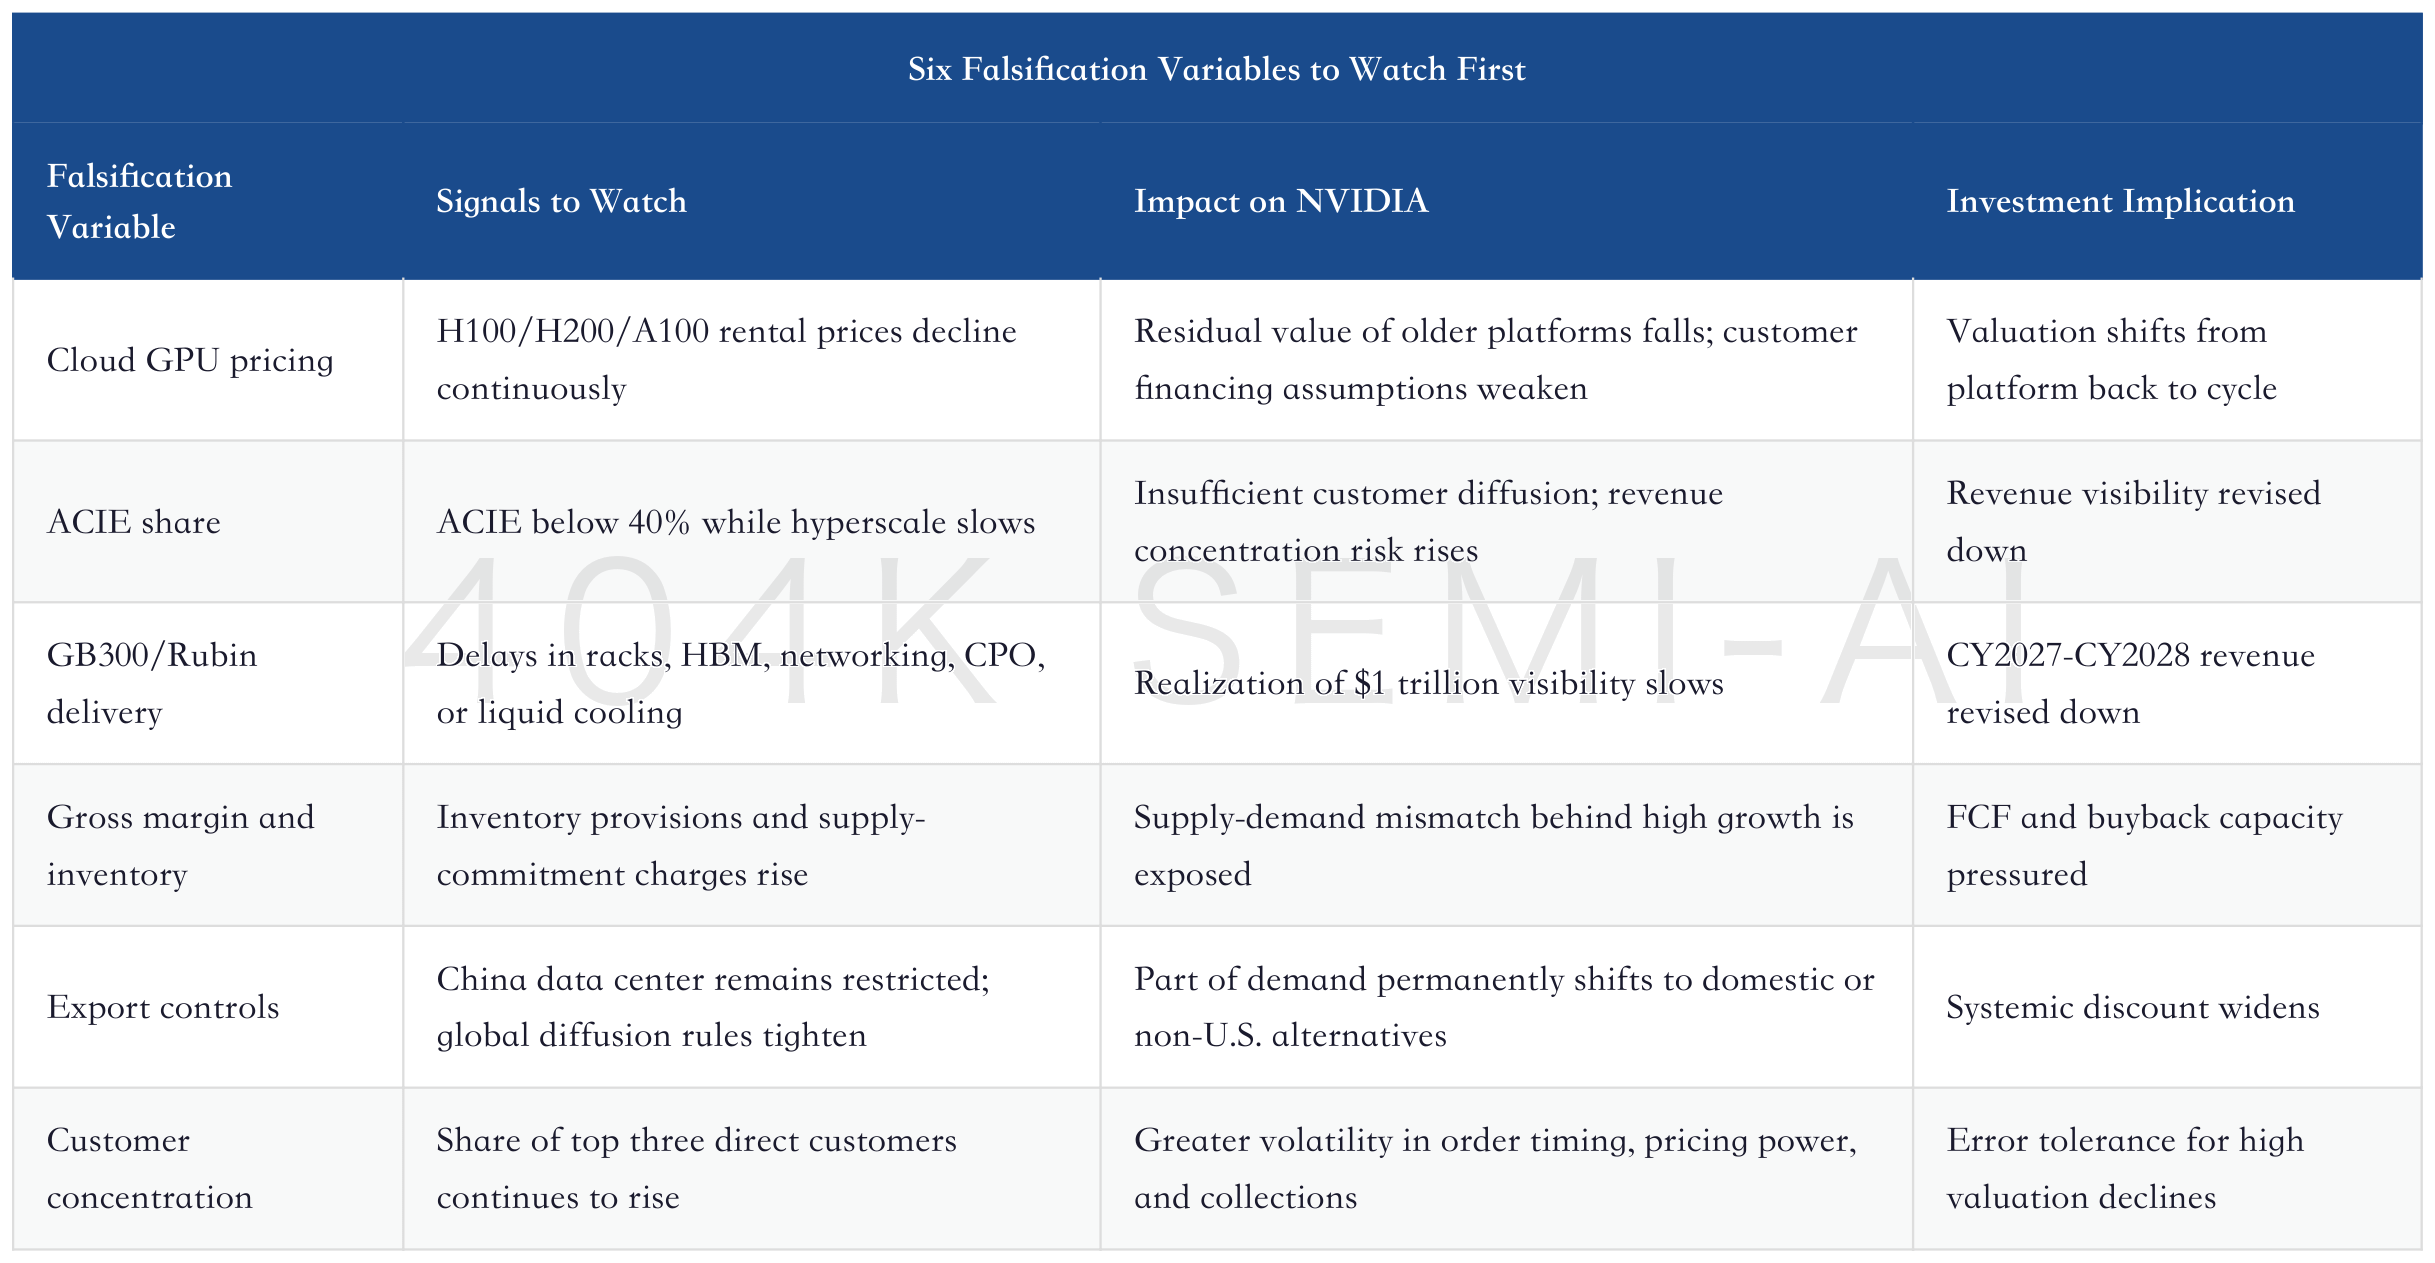
Among these variables, cloud GPU pricing and ACIE share deserve the most attention. The former tells us whether AI factory assets still have residual value; the latter tells us whether demand is truly diffusing. As long as these two metrics do not weaken at the same time, NVIDIA’s platform narrative still has strong support.
12. Tracking Checklist for the Next Four Quarters
Over the next four quarters, the key focus for tracking NVIDIA should move from “whether revenue beats expectations” to “whether AI factory economics continue to improve.” A single-quarter revenue beat is no longer enough. The market will increasingly care about revenue quality, customer mix, system delivery, cash flow, and policy risk. The table below is a more useful framework for tracking upcoming earnings reports and roadshows.
