
目录
Executive Summary
I. What the AI Memory Wall Means: GPUs Are Getting Faster, but Data Cannot Keep Up
II. How HBM Delivers Bandwidth: Parallelism, Wide Interfaces, and Short Distances
III. DDR vs. HBM: An Order-of-Magnitude Bandwidth Gain at the Expense of Capacity and Cost
IV. What HBM4 Changes: Memory Begins to Resemble a Customized System Chip
V. Why Reliability Is More Difficult: Error Protection Extends from the Die to the System
6. Thermal Management Becomes the Performance Ceiling: More Layers Mean Longer Heat Paths
7. How the Supply Chain Benefits: Value Accrues to Execution and Delivery Capabilities
8. What This Means for Micron Technology: Architectural Expertise Is the Entry Ticket; Mass-Production Execution Determines the Outcome
IX. What to Watch Over the Next 12–24 Months: Eight Indicators of Whether the Bottleneck Is Truly Shifting
Micron Technology’s presentation on AI memory architecture reveals both HBM’s true value and the more difficult manufacturing constraints that emerge as bandwidth rises.
Executive Summary
AI-chip competition has entered a stage where compute supply must be matched by data supply. Micron Technology projects that compute performance will increase approximately 3× every 2 years, while HBM bandwidth will grow by less than 2× every 2 years. More GPU compute units do not guarantee a proportional increase in application performance. When a model is constrained by memory bandwidth, incremental compute capacity translates largely into more time spent waiting for data.
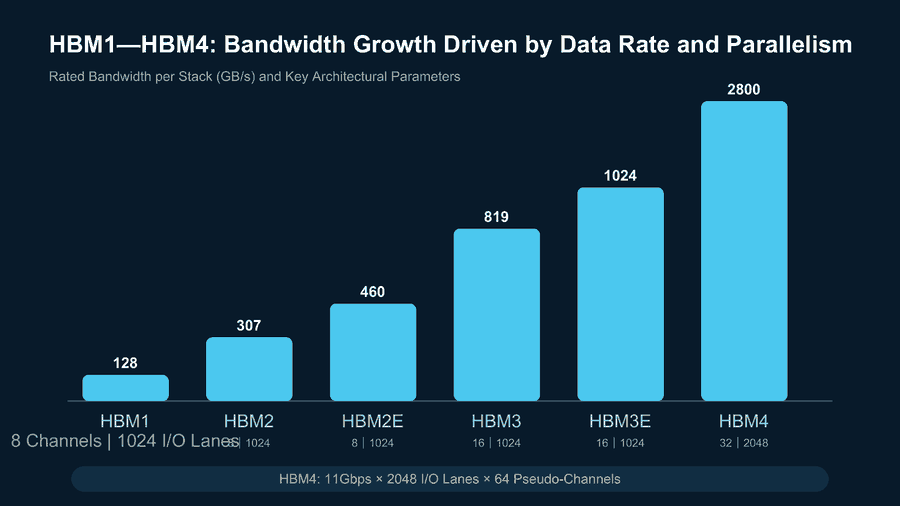
HBM raises the bandwidth ceiling through an extremely wide interface, greater parallelism, and shorter physical distances. From HBM1 to HBM4, rated bandwidth rises from 128GB/s to 2800GB/s. HBM4 increases data I/O from 1024 lines to 2048, channels from 8 to 32, and pseudo-channels from 16 to 64. It is a system-level architecture in which memory dies, a base die, an interposer, and the GPU operate together.
HBM trades silicon area, process complexity, and packaging complexity for bandwidth. Micron Technology estimates that HBM3E consumes approximately 3× as much silicon as DDR5 at equivalent capacity. An AI package configured with 8 HBM4 stacks, each 12 layers high, contains 12,344 square millimeters of memory-related silicon—more than 8× the area of a typical GPU die. HBM scarcity therefore encompasses wafers, advanced packaging, yield, and testing resources.
Beyond HBM4, the bottleneck shifts from the individual DRAM die to the entire package. High-speed D2D links, more complex base dies, greater DRAM activity, and taller stacks all increase thermal density. Differences in material coefficients of thermal expansion create additional warpage, stress, and interconnect-reliability risks. Liquid cooling, hybrid bonding, substrates, interposers, and power-delivery networks therefore become part of the same performance chain.
Micron Technology’s technical logic is clear, but commercial execution must be assessed separately. The material demonstrates that the company understands HBM4’s architectural direction and manufacturing challenges; it does not establish market share, yield, pricing, or customer qualification. Investors must continue to monitor the timing of HBM4 sampling and mass production, custom base-die capabilities, advanced-packaging supply, unit yield, and system power consumption.
Value across the supply chain will concentrate in segments that resolve system-level constraints. Memory vendors capture greater silicon value per system; foundries manufacture base dies; advanced-packaging providers handle interposers and bonding; equipment and materials suppliers address the challenges of TSVs, microbumps, and hybrid bonding; and liquid-cooling and high-speed-interconnect vendors address power and distance constraints. Any 1 segment falling behind could limit delivery of the entire AI compute package.
I. What the AI Memory Wall Means: GPUs Are Getting Faster, but Data Cannot Keep Up
Scaling large models rests on a simple premise: model size, training data, and compute investment must grow in tandem. In practice, compute chips are scaling fastest, while data-movement systems are improving more slowly. Micron Technology illustrates this divergence with two curves: compute performance increases approximately 3× every 2 years, while HBM bandwidth grows by less than 2× every 2 years. As the gap compounds, memory increasingly determines system performance.
The memory wall is not simply a capacity shortage. It encompasses bandwidth, latency, power consumption, reliability, and physical-packaging constraints. Training continuously reads weights, activations, and optimizer states; inference loads model parameters, reads the KV Cache, and serves more concurrent requests. If a GPU can execute more operations per clock cycle but cannot obtain enough data, theoretical peak performance diverges from actual throughput.
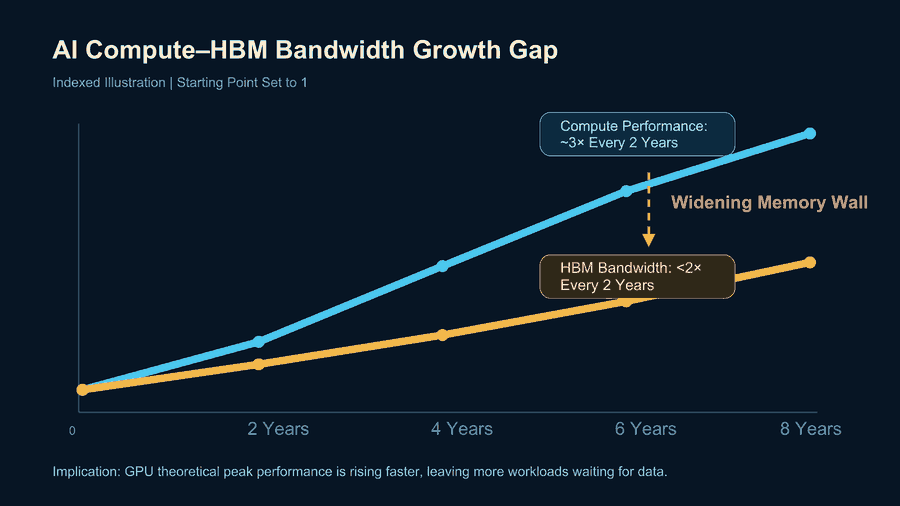
This is also a common source of error when assessing AI-hardware demand. Looking only at a GPU’s floating-point performance overstates the performance available to workloads, while looking only at HBM capacity ignores how much data can be delivered per second. The real determinant of efficiency is arithmetic intensity: how many operations an application can perform for every 1 byte of data moved. Workloads with lower arithmetic intensity are more likely to be bandwidth-constrained, reducing the marginal benefit of additional GPU compute units.
The Roofline model expresses this relationship intuitively. The horizontal axis represents the number of operations performed per byte of data, while the vertical axis represents achievable performance. The sloped segment is determined by memory bandwidth, and the horizontal segment by peak compute performance. HBM raises the sloped line, allowing more workloads to achieve higher performance before hitting the “memory ceiling.” It does not eliminate the bottleneck; it expands the operating range in which GPUs can be used efficiently.
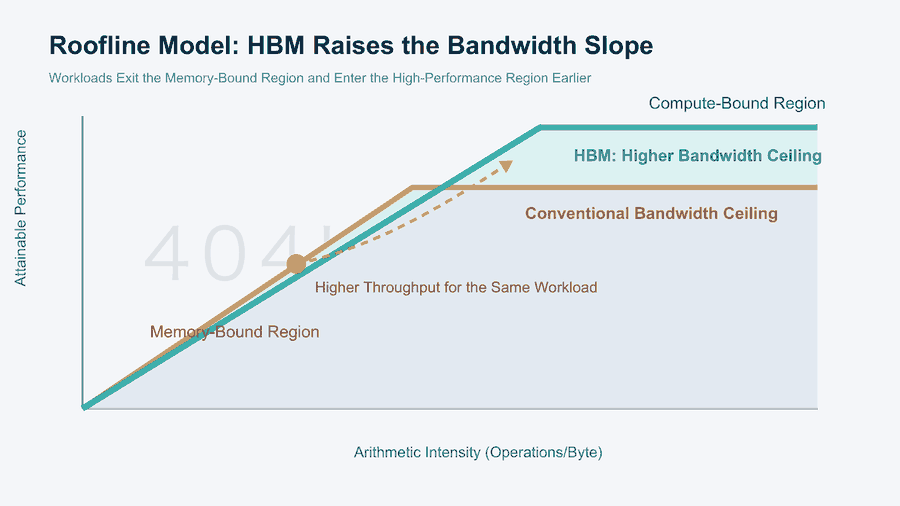
Different AI workloads occupy different positions on this chart. Matrix-multiplication-intensive training kernels with high data reuse are more likely to approach the compute-bound region. Attention, embedding lookups, sparse models, and small-batch inference typically require frequent data access and have lower arithmetic intensity. Changes in model architecture, batch size, context length, and cache-hit rate can place the same GPU in entirely different efficiency regimes.
Training and inference also impose different memory pressures. Training must retain intermediate activations, gradients, and optimizer states, while communication and recomputation strategies alter peak capacity requirements. Inference no longer retains training state, but it must maintain the KV Cache while serving more users concurrently. The longer the context and the higher the concurrency, the greater the KV Cache footprint. Customer demand for HBM therefore cannot be explained by model parameter count alone; precision, batch size, concurrency, and service-latency targets also matter.
Software optimization can reduce memory requirements per task without necessarily lowering aggregate system demand. Quantization, sparsification, operator fusion, and cache reuse can reduce data movement, but the resulting savings may be reinvested in longer contexts, more agents, and lower service prices. Assessing HBM demand therefore requires tracking both “how much memory each task uses” and “how quickly total task volume grows.” Focusing on only 1 variable risks understating demand elasticity or overstating hardware rigidity.
HBM demand is therefore not simply a function of “more AI servers.” The stronger causal chain is that larger models and greater concurrency increase data-movement pressure; continued gains in GPU compute make the memory wall more pronounced; system vendors become willing to pay for more expensive silicon and packaging to secure bandwidth; and HBM consequently accounts for a larger share of system materials and power consumption. As long as the growth-rate gap between compute and bandwidth persists, HBM will retain structural value.
II. How HBM Delivers Bandwidth: Parallelism, Wide Interfaces, and Short Distances
HBM’s core design principle is to use a large number of lines simultaneously, avoiding the need to concentrate all traffic on a few links running at extreme speeds. Conventional DDR memory connects processors and memory modules through motherboard traces, offering longer distances and narrower interfaces suited to larger capacities and flexible expansion. HBM stacks multiple DRAM layers on a base die and places them alongside the GPU in the same system-level package through an interposer, shortening signal paths and sharply increasing the number of I/O connections.
From HBM1 to HBM4, the architecture advances across three dimensions. First, the rated data rate increases from 1Gbps to 11Gbps. Second, parallelism rises, with the channel count increasing from 8 to 32 and the pseudo-channel count reaching 64. Third, interface width expands, with HBM4 increasing data I/O from the previous 1024 lines to 2048. Together, these changes raise rated bandwidth per device from 128GB/s to 2800GB/s.
Pseudo-channels improve access granularity and concurrency. Each channel is divided into two pseudo-channels that share command and address buses but use independent data buses. The system can schedule requests more granularly, reducing the probability that most of a wide channel sits idle during localized accesses. Each HBM3E DRAM die contains 128 banks, increasing to 256 banks in HBM4, further expanding the number of memory units that can operate in parallel.
The base die provides the interface between the host and the DRAM stack. On the host side, a microbump physical layer connects to the base die; within the stack, TSVs connect the DRAM layers. HBM3E has approximately 1000 I/O connections, while HBM4 increases this to approximately 2000. Point-to-point connectivity at this density cannot rely on conventional motherboard traces and instead requires silicon interposers, redistribution layers, or other high-density packaging technologies.
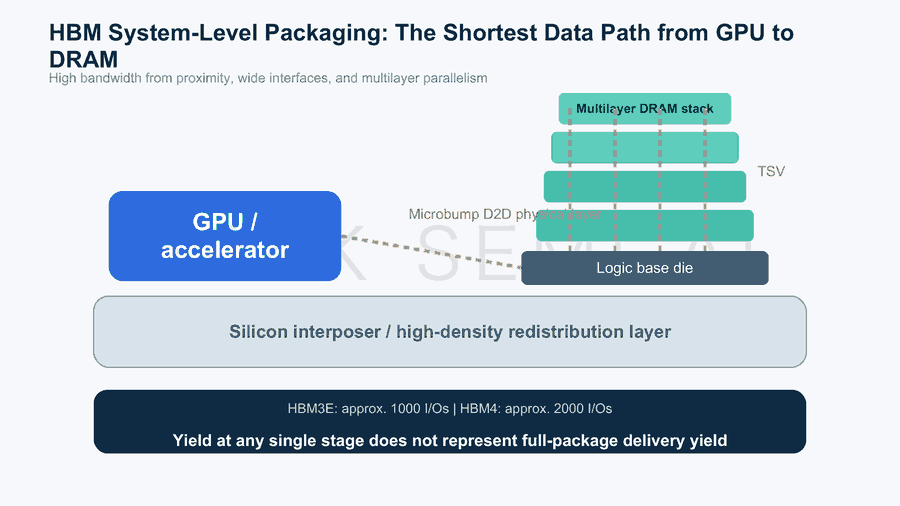
This architecture explains why HBM cannot be understood as merely “a faster DRAM.” It encompasses the DRAM process, logic base die, TSVs, bonding, interposer, substrate, power-delivery network, and host interface. Performance depends on coordination across every segment, while supply depends on the combined capacity of the entire manufacturing chain. High yield at an individual DRAM layer does not guarantee equally high yield for the completed stack or full package.
Generational specifications also reveal an important shift: HBM performance scaling is moving from “increasing the speed of each line” toward “increasing speed and parallelism together.” From HBM3E to HBM4, the rated data rate rises from 8Gbps to 11Gbps, an increase of approximately 38%, while rated bandwidth rises from 1024GB/s to 2800GB/s, an increase of approximately 173%. Most of the difference comes from doubling both the I/O count and the channel count. Greater parallelism is the key driver of HBM4’s step-change improvement.
Expanding parallelism also makes scheduling more difficult. More channels, pseudo-channels, and banks can serve more requests simultaneously, but only if the controller distributes those requests evenly. When accesses cluster in a small number of banks, the theoretical parallelism cannot be fully utilized. GPU memory controllers, compilers, and runtimes must coordinate data placement so that different compute units access different banks wherever possible. Hardware specifications and software efficiency are therefore becoming more tightly coupled.
