
Meta Selling Compute: The Last Straw That Overwhelms the Semiconductor Euphoria?
目录
TL;DR
I. Clarifying the Event: Meta Is Not Selling “Cloud,” but Scarce Compute That Can Be Turned Over
II. The Three Sell-Side Differences: Citi Looks at Cash Flow, Morgan Stanley at the EPS Bridge, JPMorgan at Internal Demand
III. How to Use Morgan Stanley’s 250MW Model: It Is a Sensitivity Ruler, Not an Event Fact
IV. Why Meta Has Capacity to Sell: Not “Idle” Capacity, but a Mismatch Between Buildout Cadence and Product Cadence
V. For Neocloud, This Is Both Validation and a Pricing Stress Test
VI. For Cloud Providers, This Is Not Simple Competition but a Stratification of the AI Cloud Business Model
VII. Impact on the AI Hardware Chain: Orders Remain Strong, but Valuation Starts Looking at “Post-Deployment Revenue”
8. What Is Being Suppressed in the Semiconductor Euphoria Is Not Demand, but the Valuation Narrative
9. Which Segments Are Most Likely to Be Revalued: Not All Semiconductors Face the Same Risk
10. Three Scenarios for This Event: The Same Action Can Be Interpreted by the Market as Three Completely Different Stories
XI. Why This Is Not Yet a Demand Collapse: Four Counterpoints Cannot Be Ignored
XII. Translating the Event into an Investment Framework: Going Forward, Watch Four Operating Variables, Not Just CapEx
XIII. Meta’s Own Long-Term Value Still Depends on Proprietary AI Products
XIV. Why This Changes How the Market Debates AI CapEx
XV. Follow-Up Checklist: Four Sets of Numbers Will Define the Event
XVI. Conclusion: Meta Sells Compute; What the Market Is Buying Is Proof of AI CapEx Recovery
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
Meta selling compute is not hard proof that semiconductor demand has peaked, but it exposes the weakest link in the AI capex boom: it is no longer enough to see cloud providers keep spending. The market is starting to ask whether compute, once brought online, can be sold at the right price, utilization rate, and cash flow. That is the turning point where the semiconductor chain shifts from an order narrative to return verification.
TL;DR
Start with cash flow. Citi puts Meta Compute into the free-cash-flow ledger because Meta’s AI capex is moving from an off-income-statement “future dream” into a daily cash drain that investors must underwrite. Citi estimates Meta’s 2026 and 2027 capex at $139B and $171B, with free cash flow falling to $14.6B and $8.5B, respectively. If part of its externally leased compute can be monetized at high prices, it will first improve the market’s patience with AI investment returns, rather than immediately rewriting the core business.
Morgan Stanley provides the clearest sensitivity analysis. 250MW is not an already-realized leasing scale, but the unit assumption Morgan Stanley uses to decompose EPS sensitivity: if Meta leases out 250MW of self-owned compute for one year at $40/Watt, it could add about $3 to 2028 EPS, or roughly 8% accretion. The value of this model is not in predicting exactly how much compute Meta will sell, but in showing the market that “AI compute assets” can be re-discounted by MW, price, and utilization.
JPMorgan’s reminder defines the risk boundary. JPMorgan acknowledges that external compute leasing can generate revenue and returns, but would rather see Meta’s own AI products, ads, Business Agents, subscriptions, glasses, and other applications absorb the capacity. The more Meta leases out, the more the market will ask two questions: is this active asset turnover, or insufficient demand from its own products; and is this high-return leasing, or loss mitigation after excess high capex?
Neocloud faces validation, not a simple negative shock. If Meta temporarily leases out self-owned compute, it will increase supply and compress some scarcity premium, but it also proves that enterprise AI compute demand remains strong enough that even hyperscalers are willing to break capacity into external products. The real pressure is on low-quality edge compute assets that lack power, customer lock-in, and depend on financing to survive. Platforms that can bundle power, GPUs, networking, customers, and contract duration will become more valuable.
The semiconductor chain will be re-audited. Previously, the market watched “how much more capex cloud providers added.” Now it needs to watch “how much revenue, gross profit, and free cash flow each new 1GW can generate.” GPUs, ASICs, optical modules, power, and data centers still benefit from upward capex revisions, but valuation is shifting from order visibility alone to utilization, price, contract length, and customer usage intensity after compute comes online. What overwhelms the euphoria is not Meta selling compute itself, but the market starting to require every $1 of AI capex to submit its homework.
Watch four hard indicators next. First, whether Meta formally confirms Meta Compute’s product form and pricing. Second, whether the actual externally leasable capacity is at the 10MW, 100MW, or GW level. Third, whether 2027/2028 capex guidance keeps moving higher because of cloud ambitions. Fourth, whether Meta’s own AI products can generate higher ad conversion, Business Agents revenue, and subscription revenue. Until these four numbers come out, the event looks more like a cash-flow option and should not be valued in advance as a second AWS.
I. Clarifying the Event: Meta Is Not Selling “Cloud,” but Scarce Compute That Can Be Turned Over
Meta selling compute can easily be misread as “Meta wants to replicate AWS.” That interpretation is too broad and too early. Based on Citi’s and Morgan Stanley’s breakdowns, the more accurate current framing is this: Meta may open parts of its AI infrastructure to external customers in two product forms. One is model access, similar to AWS Bedrock’s “call models through APIs” format. The other is raw compute, similar to Neocloud selling GPU capacity or usage rights to GPU clusters.
These two product types have completely different levels of difficulty. Model access requires model capability, a developer ecosystem, enterprise sales, billing systems, customer success, and security compliance. Meta has user traffic and open-source model mindshare, but it does not naturally have the enterprise cloud muscles of AWS, Azure, or Google Cloud. Raw compute leasing is much simpler: as long as capacity is available, networking and power are stable, and contract pricing is appropriate, short-term excess or temporarily unused self-owned compute can be converted into revenue.
Morgan Stanley therefore places “Neocloud-style leasing” on the higher-probability path, and a “full hyperscaler-style software cloud” on the higher-execution-risk path. This judgment matters. What is most verifiable for Meta today is not whether it can build a complete cloud platform, but whether it can turn AI compute that is already under construction, about to come online, and not yet fully absorbed internally in the short term into an asset with price, duration, and cash flow.
The value of Meta Compute lies here as well. It is not simply a “new business name,” but a way to put internal compute procurement, data-center construction, model access, and external leasing onto one operating ledger. As long as compute can be dynamically allocated among internal training, internal inference, and external leasing, AI capex no longer has to be justified only by long-term ad efficiency or a superintelligence story. It can also prove asset utilization through near-term cash recovery.
This is also why the market reaction is significant. Over the past year, investors have accepted AI infrastructure spending, but they have become increasingly unwilling to hear only that “products will come in the future.” If Meta can prove that part of its compute can be leased to external customers before its own AI applications mature, the capex narrative will shift from “burning money to buy the future” to “buy scarce assets first, then recover capital through both leasing and self-use.”
II. The Three Sell-Side Differences: Citi Looks at Cash Flow, Morgan Stanley at the EPS Bridge, JPMorgan at Internal Demand
Citi, Morgan Stanley, and JPMorgan do not view the same event in exactly the same way. Their common ground is that AI compute remains scarce and Meta has an opportunity to monetize part of its capacity. Their disagreement is whether the money should be treated as a new growth business, a short-term EPS bridge, or contrary evidence of insufficient product pull.
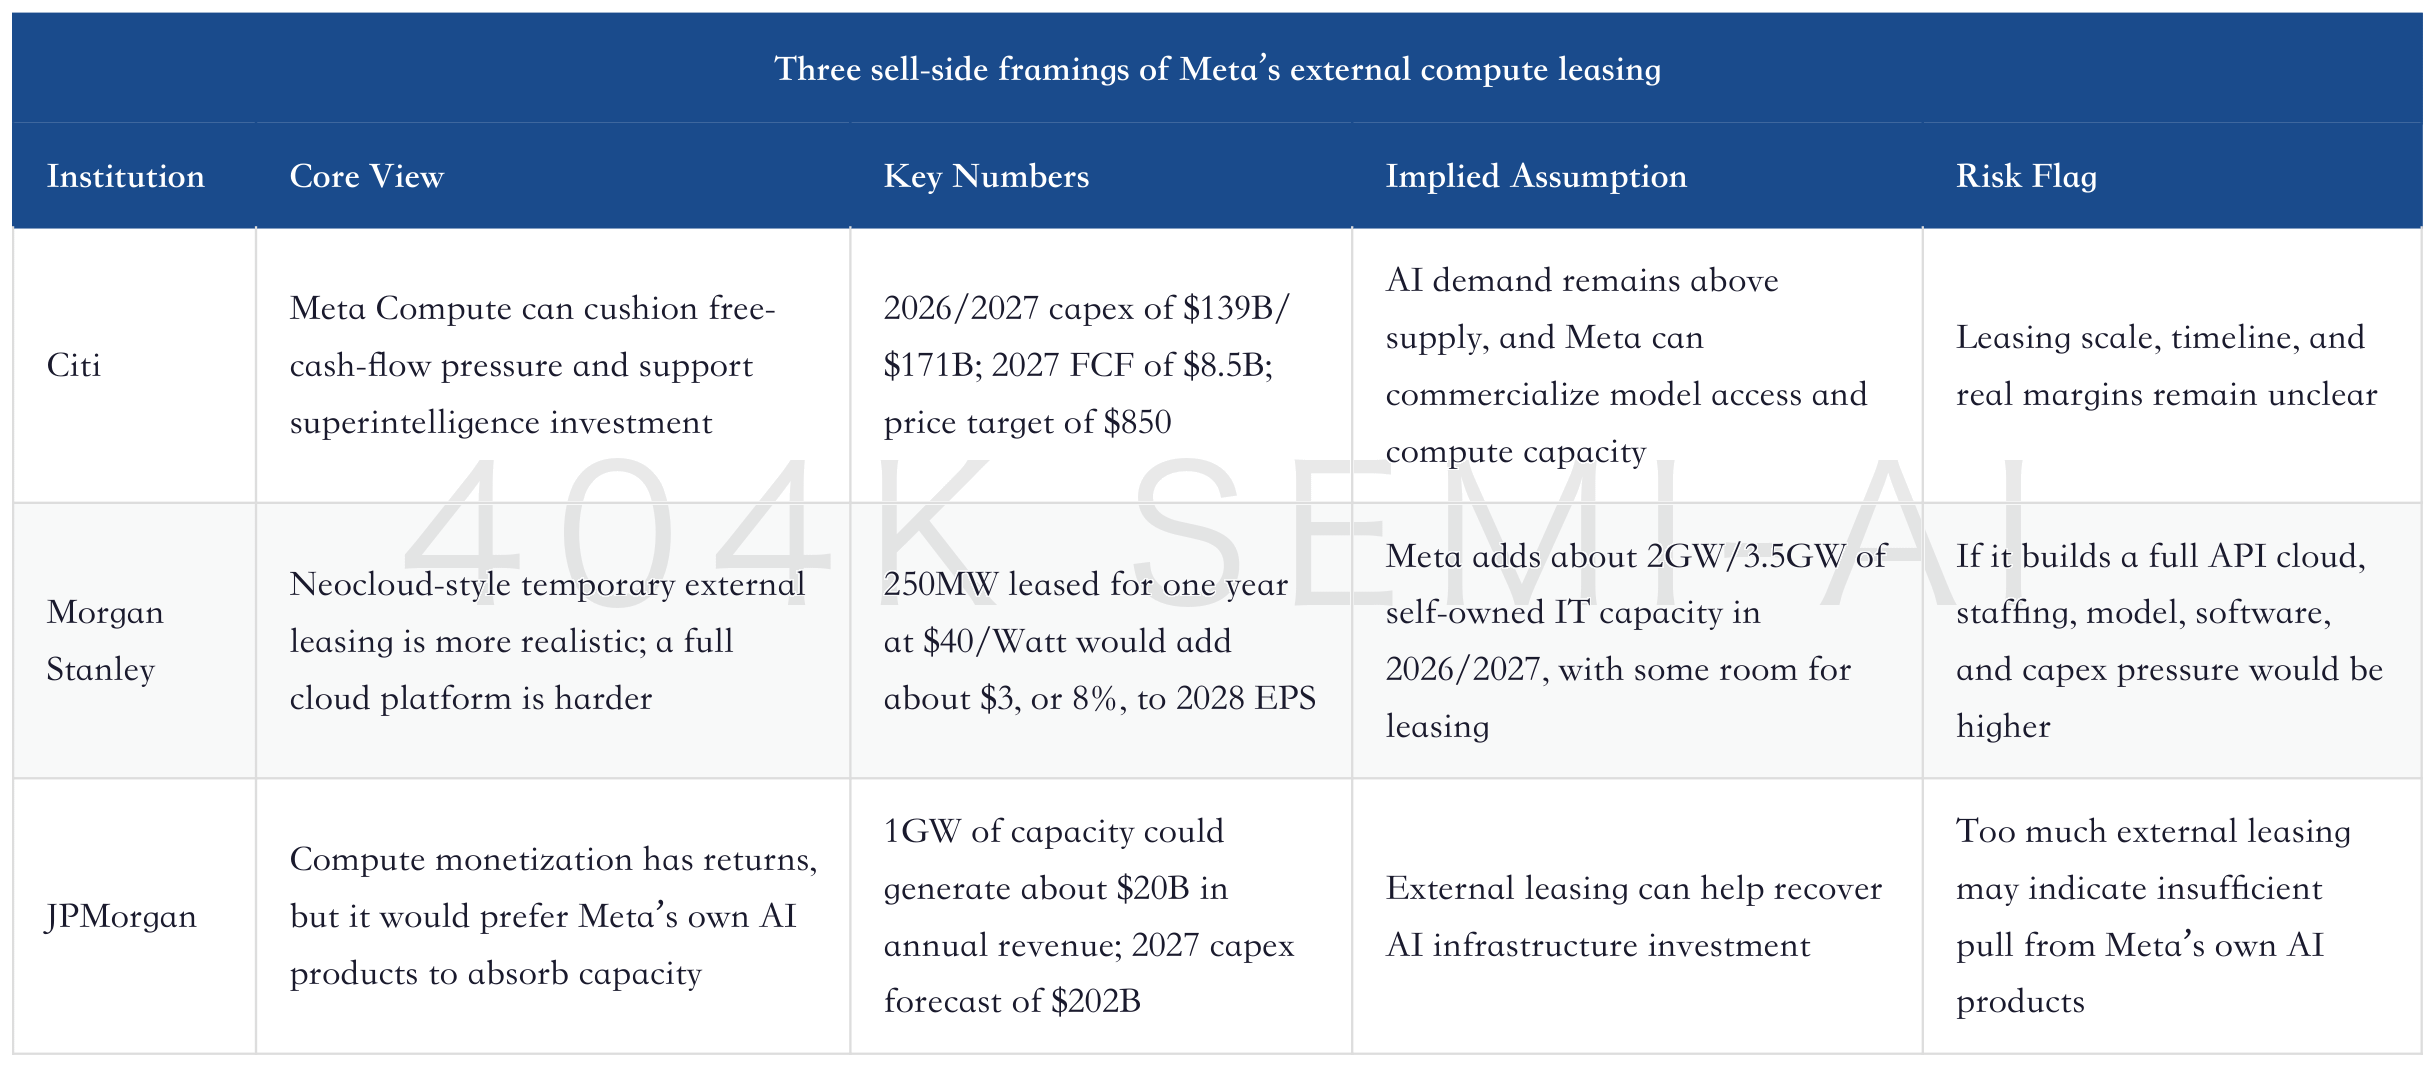
Citi’s logic looks most like cash-flow protection. Meta’s traditional core business remains strong, and ads, Reels, AI ad tools, and messaging monetization can continue contributing profit. But after a steep rise in capex, free cash flow will be compressed. Citi views Meta Compute as a new business unit that can “recognize revenue and free cash flow earlier.” The core point is not that Meta immediately adds a trillion-dollar cloud platform, but that compute leasing can reduce the cash-flow erosion from AI infrastructure buildout.
Morgan Stanley’s logic looks most like a valuation bridge. It does not treat Meta’s external compute leasing as the main reason for its investment rating, but as an EPS cushion while waiting for AI products to mature. Morgan Stanley is explicit that its bullish view on Meta is not based on Meta becoming a Neocloud, but on Meta generating more durable product and revenue growth on its own platforms. Compute leasing is a bridge, not the destination.
JPMorgan’s logic looks most like a checklist of contrary evidence. It acknowledges that 1GW of compute can generate considerable annual revenue, and that this helps AI infrastructure returns. But it would rather see Meta use the compute for its own AI products. This reminder cannot be ignored. If a social advertising giant sells large amounts of its most expensive compute to others, the market will ask: do its own AI ads, agents, glasses, subscriptions, and personal superintelligence roadmap really have enough throughput demand?
Taken together, these three framings are the full meaning of the event. It is neither bearish nor blindly bullish. It is the natural result of AI capex entering its second phase: in the first phase, the market rewarded whoever dared to build; in the second phase, it starts rewarding whoever can put the built assets to work; in the third phase, it will reward whoever can generate the highest return across self-use and external leasing.
III. How to Use Morgan Stanley’s 250MW Model: It Is a Sensitivity Ruler, Not an Event Fact
The most useful part of Morgan Stanley’s work is that it decomposes the event into three variables: 250MW, one year, and $40/Watt. The framing must be clear: 250MW is not a leasing scale Meta has confirmed, nor is it a fact of the event itself. It is the unit Morgan Stanley selected for EPS sensitivity analysis for investors.
According to Morgan Stanley’s estimates, if Meta leases out part of its self-owned compute, EPS would be highly sensitive to capacity and price. The key is not the single 250MW point, but the slope of price and capacity: the larger the capacity and the closer the price is to the high-end Neocloud range, the more external compute leasing looks like a profit bridge. If pricing falls or capacity is constrained, it looks more like a free-cash-flow cushion.
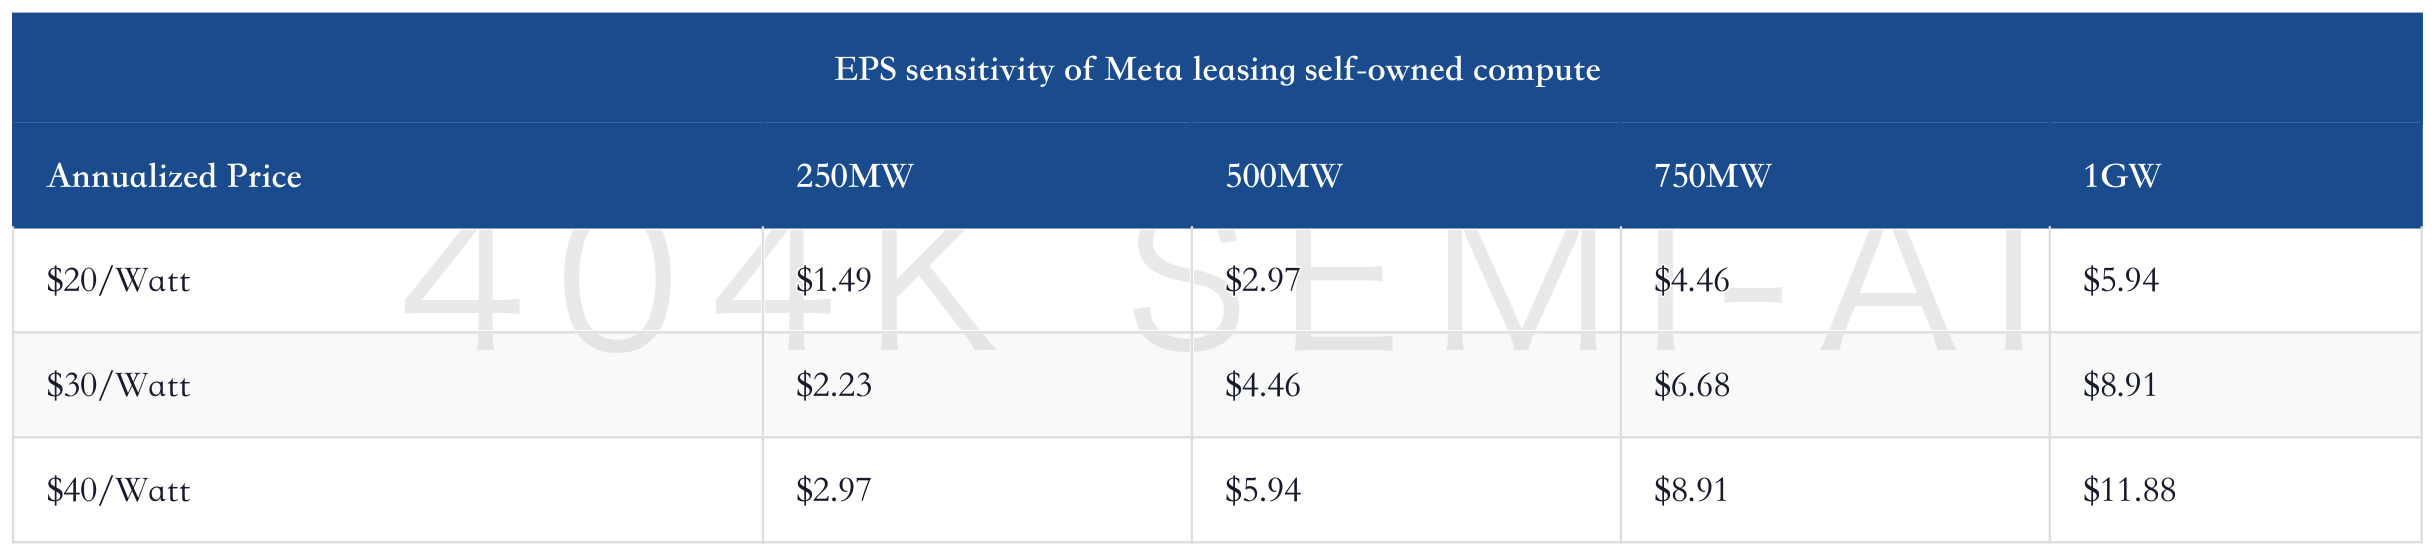
The real value of this table is not precise EPS prediction, but giving the market a ruler for “AI compute assetization.” In the past, the market looked at AI capex by using total amount, year-over-year growth, and supplier orders. Now there is an approach closer to operating assets: leasable capacity multiplied by price, less depreciation, energy, operations, maintenance, and related costs, with net income and free cash flow considered at the end.
JPMorgan’s assumption of about $20B in annual revenue from 1GW effectively corresponds to the more conservative $20/Watt range. Morgan Stanley’s 1GW at $40/Watt corresponds to about $40B in annualized revenue. The difference is large, but the direction is consistent: when GPU compute remains tight and customers are willing to pay a premium for near-term capacity, 1GW is not an abstract power unit, but a potential asset line capable of generating tens of billions of dollars in annualized revenue.
This will change how investors look at Meta’s capex. Estimates for Meta’s 2026 capex differ across institutions: Citi is at $139B, while Morgan Stanley is at $145B. For 2027, the numbers are higher: Citi at $171B, Morgan Stanley at $175B, and JPMorgan even sees $202B. The disagreement is not about direction; all point to continued upward revisions. The real debate is whether this spending will be recovered only through ads and AI products, or whether part of it can first be recovered through external compute leasing.
From an event-interpretation perspective, the 250MW figure should only be used as an anchor for “how much EPS sensitivity would arise if a standard block of capacity were leased.” Meta does not need to lease 1GW in the first step, nor does it need to formally announce an entry into the cloud market. What needs to be verified is whether it can put forward part of its self-owned capacity and let the market see the price, customers, duration, and gross margin. If those numbers hold up, the valuation discount on capex may begin to narrow.
IV. Why Meta Has Capacity to Sell: Not “Idle” Capacity, but a Mismatch Between Buildout Cadence and Product Cadence
Interpreting Meta’s external compute leasing as “idle compute” misses the point. AI infrastructure buildout is inherently batch-based. Data centers, power, networking, GPUs, liquid cooling, and software stacks cannot be scaled up or down precisely against weekly demand. When a 1GW-scale cluster comes online, internal product demand may still be ramping, while training and inference workloads are also cyclical. Short-term external leasing does not necessarily indicate insufficient demand. It may simply reflect a timing gap between asset commissioning and product absorption.
The Prometheus and Hyperion projects cited by Citi are the context for this issue. Prometheus is a 1GW-plus cluster scheduled to come online in 2026. Hyperion targets more than 5GW by 2030, with initial deployment in 2028. Meta is also advancing its in-house MTIA chip roadmap and building long-term procurement and capacity partnerships with ecosystem partners including Google Cloud, CoreWeave, Nvidia, and AMD. This is not a small-scale experiment, but a multi-year infrastructure plan spanning chips, data centers, and model products.
Morgan Stanley estimates that Meta will add roughly 2GW and 3.5GW of self-operated IT capacity in 2026 and 2027, respectively. It is also leasing around 2.5GW of third-party capacity through channels including CoreWeave, Nebius, Google Cloud, and Oracle. Morgan Stanley believes Meta is unlikely to sublease that third-party capacity to others, but this external capacity gives Meta greater flexibility, allowing it to make its own first-party capacity available for temporary external leasing.
The key here is “owned capacity.” If Meta is leasing capacity that it built, controls, and dispatches itself, it earns asset-turnover revenue. If Meta is merely subleasing third-party capacity, the commercial significance is much weaker and more likely to be constrained by contract terms. Morgan Stanley therefore treats first-party owned capacity as the core variable behind the external leasing opportunity.
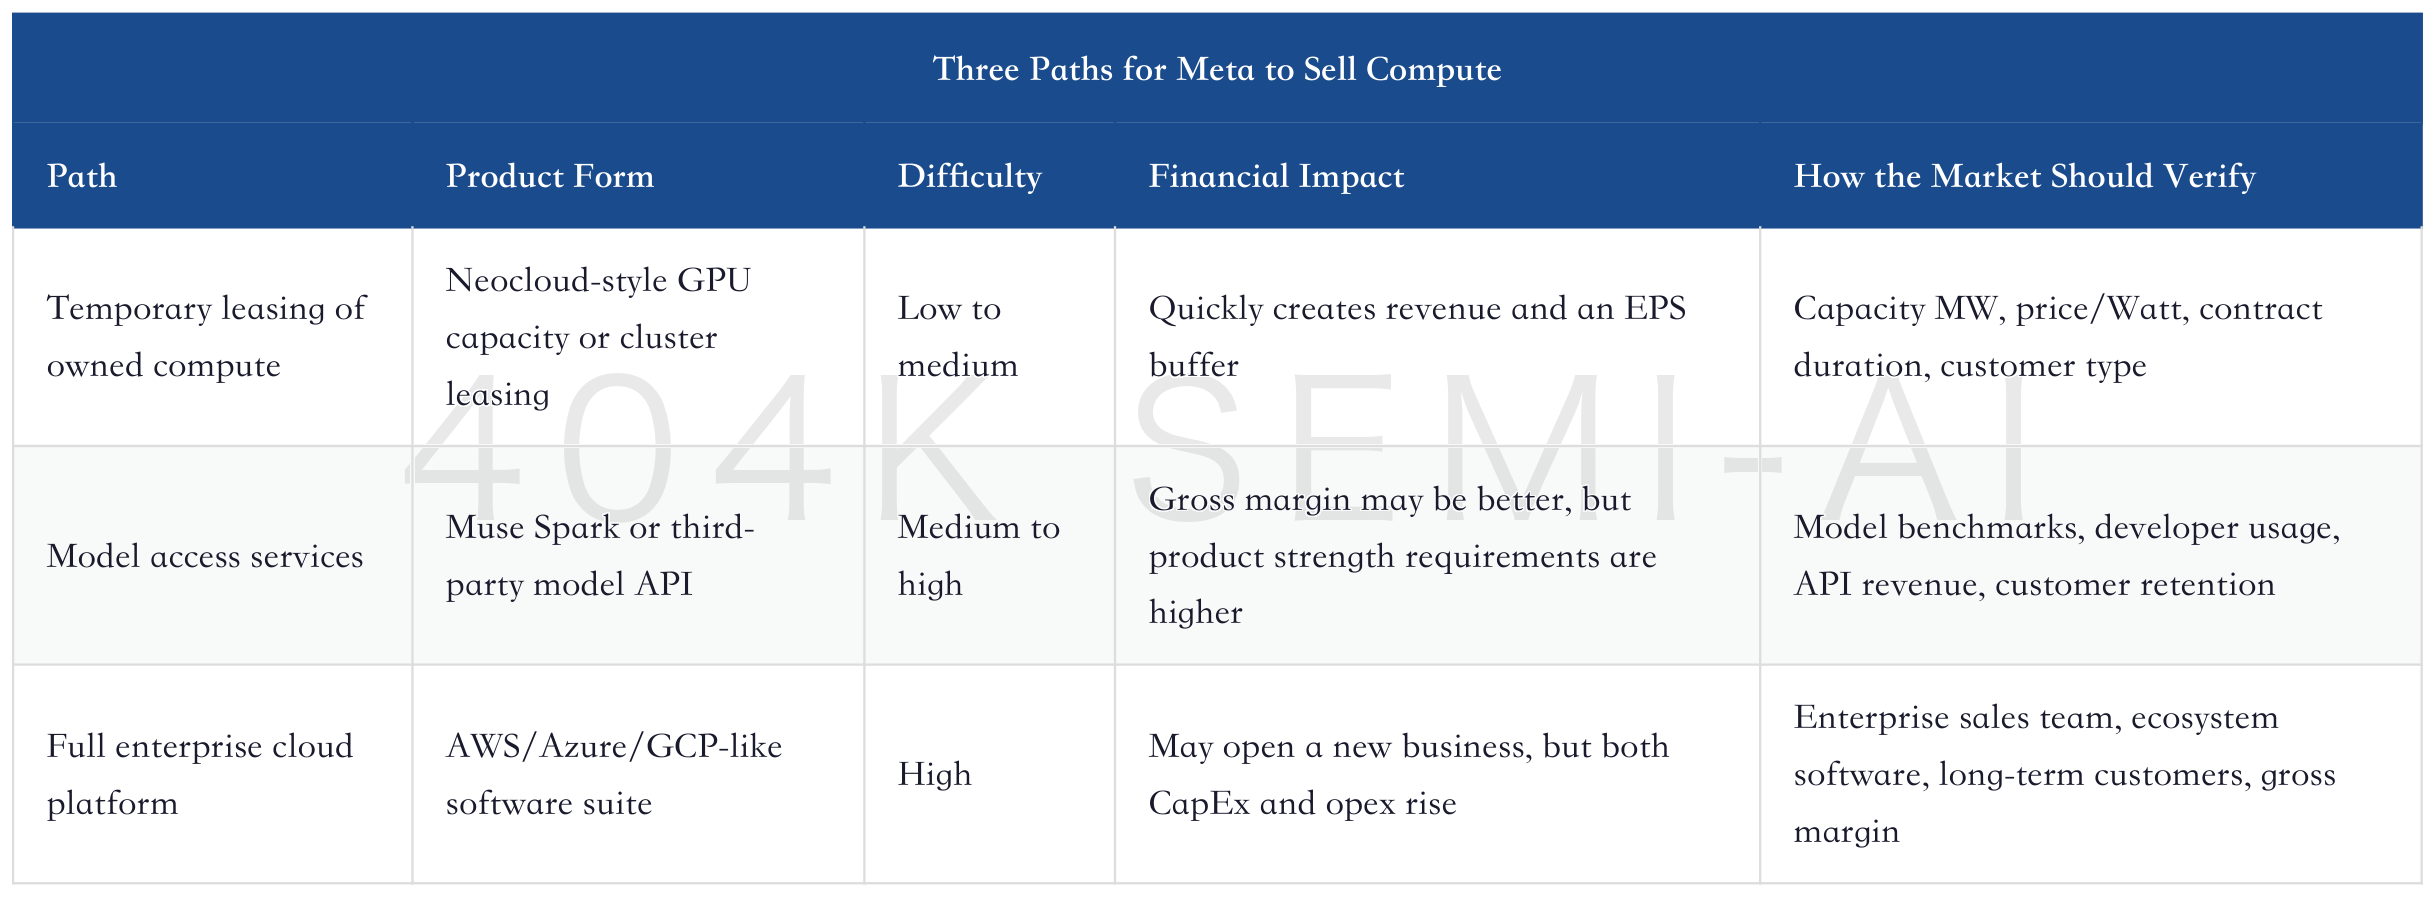
This table explains why the event should be understood in layers. The first layer is the most realistic short-term compute leasing opportunity, addressing cash-flow pressure and CapEx concerns. The second layer is model access, which can improve gross margin but requires proving that the Muse model family and Meta ecosystem can attract developers. The third layer is a full cloud platform, where evidence is currently the thinnest and where the market is most likely to overinterpret too early.
V. For Neocloud, This Is Both Validation and a Pricing Stress Test
Meta entering compute leasing will naturally lead the market to think of CoreWeave, Nebius, Oracle, and the broader Neocloud category. The first reaction may be: “More supply means pressure on Neocloud.” That judgment is only half right.
In the short term, if Meta releases high-quality near-term capacity for lease, it will indeed create a pricing benchmark for Neocloud. Suppliers that have mainly captured premium pricing because of “near-term GPU scarcity,” but lack long-term customer lock-in, will be forced to answer a simple question: why should customers not lease capacity directly from Meta, Google, Oracle, or other hyperscalers?
In the medium term, Meta’s willingness to lease externally also proves that compute demand is strong enough to absorb new supply. Citi’s software and telecom teams both emphasize that AI/HPC demand still exceeds supply, and data center leasing has already begun focusing on 2028-2030 delivery. In other words, Meta’s move will reignite the supply-demand debate, but it does not mean the industry immediately enters oversupply.
The real Neocloud beneficiaries will be those with three attributes: first, near-term deliverable capacity; second, the ability to bind power, GPUs, networking, and customer contracts together; third, sufficient financing capacity to turn contracts into buildable, deployable, operable assets. Assets that rely only on slides claiming future power, GPUs, and customers will see their premium compressed by the external leasing option offered by a giant like Meta.
Behind the 138GW Data Center Expansion Plan: AI CapEx Keeps Being Revised Up, and How Cloud Providers, Bond Markets, ABS, and Power Infrastructure Can Absorb This Buildout Cycle
This event will also affect CoreWeave. Citi notes that Meta has roughly $35.2 billion of contracted capacity with CoreWeave. Meta buying from CoreWeave while potentially selling its own compute may look contradictory, but these are two sides of the same issue: AI compute demand is large enough that a single buildout path is insufficient. Meta both needs external capacity to supplement peaks and wants its owned capacity to generate returns during idle windows.
If Meta’s future external leasing prices are below Neocloud market prices, margins for marginal suppliers will be compressed. If Meta’s prices are above market, it indicates that high-quality, near-term deliverable compute with ecosystem credibility remains scarce, which would instead support Neocloud valuations. Price itself will become the industry thermometer.
VI. For Cloud Providers, This Is Not Simple Competition but a Stratification of the AI Cloud Business Model
What AWS, Azure, and Google Cloud should fear most is not Meta leasing out a few hundred MW of compute, but AI cloud customers starting to procure “full cloud platforms” and “pure compute capacity” separately. In the past, enterprise cloud migration focused on compute, storage, databases, security, developer tools, and ecosystem integration. AI training and inference introduce a new purchasing logic: customers first ask where GPUs are available, where they can go online fastest, and where costs are lowest, then consider cloud-platform stickiness.
If Meta only leases raw compute, the direct impact on the big three clouds is limited. It is more like putting high-end GPU capacity into the market to address shortages for some enterprises and model companies. Customers still need to manage data, model deployment, application development, security, and compliance within AWS, Azure, and Google Cloud.
If Meta moves further into model access, the competition becomes clearer. AWS has Bedrock, Google has Vertex AI, and Microsoft has deeply tied OpenAI to Azure. Only if Meta sells Muse Spark, the Llama ecosystem, or third-party models through Meta Compute would it touch the model platform and developer entry point. But Morgan Stanley’s caution is precisely here: the Muse models still need to prove themselves, and Meta also needs enterprise sales and software product capabilities.
The more likely structure is a three-layer AI cloud market. The bottom layer is power, data centers, GPUs, networking, and storage. The middle layer is training/inference compute orchestration and leasing. The top layer is models, tools, applications, and business processes. Meta is most likely to monetize the middle layer first, while the top layer is the hardest. The big three clouds are strongest in the top layer and enterprise systems. Neocloud is strongest in the middle layer and near-term capacity. Meta’s special position is that it has massive internal demand while also potentially selling short-term excess capacity in the middle layer.
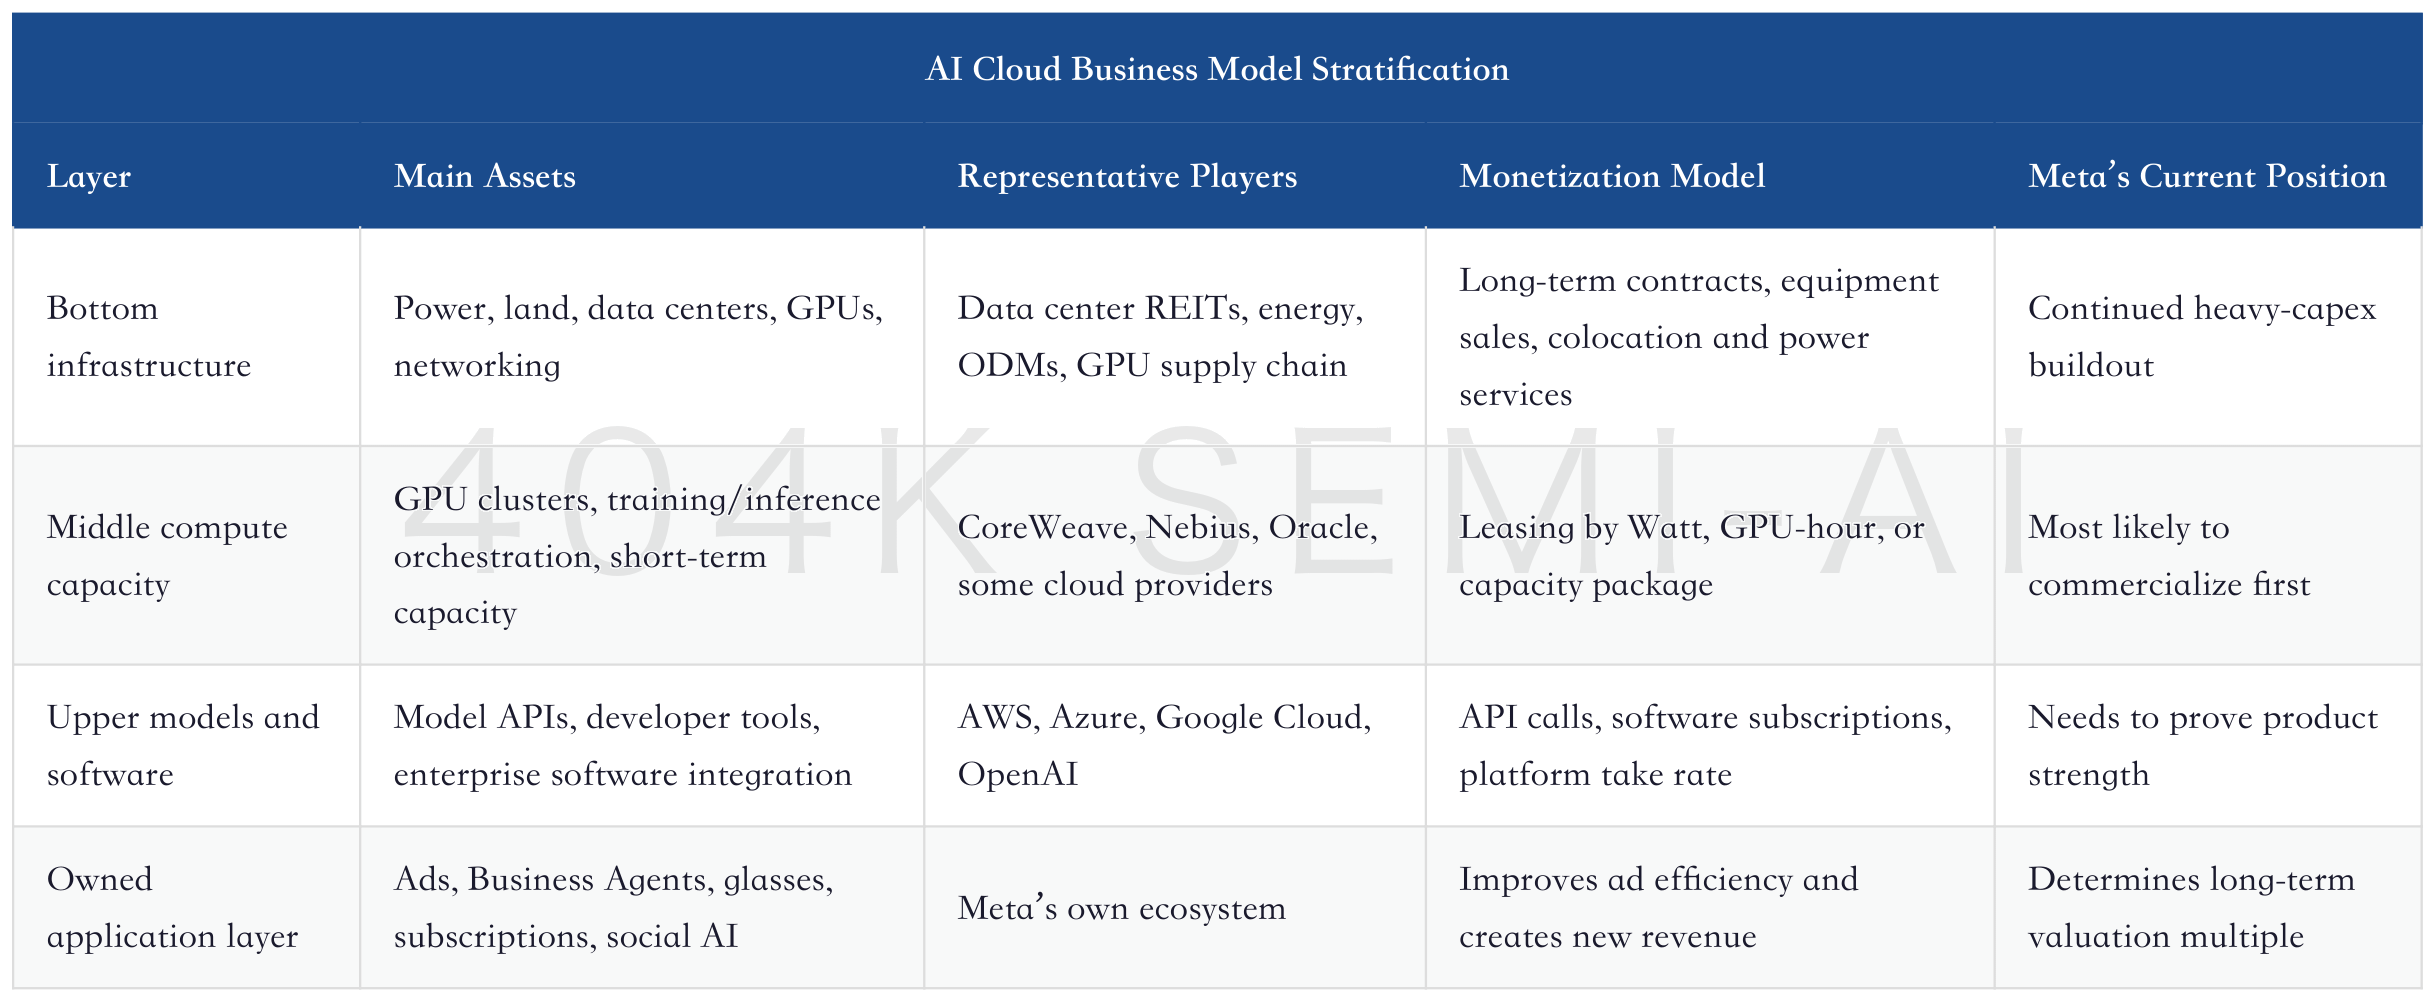
This is also why interpreting the Meta event as an “escalation in the cloud war” is insufficient. It looks more like the emergence of an asset-turnover market in the AI infrastructure value chain. Whoever has capacity can sell capacity. Whoever has models can sell model access. Whoever has applications can turn compute into high-margin revenue. Meta’s advantage is that it holds all three cards at once; its weakness is that the latter two have not yet been fully proven.
VII. Impact on the AI Hardware Chain: Orders Remain Strong, but Valuation Starts Looking at “Post-Deployment Revenue”
For the AI hardware chain, Meta selling compute is not a signal that demand has peaked. Quite the opposite: if hyperscalers believe compute can be leased externally, they have more reason to lock in GPUs, ASICs, power, data centers, and networking resources in advance. Capacity no longer has only one use case: if internal products can absorb it, it goes to ads, agents, and inference; if not, it can be leased to external customers; if future model training needs it, it can be recalled or redispatched.
This will strengthen the “option value” of AI hardware demand. GPUs, HBM, networking, switch chips, optical modules, liquid cooling, power supplies, and data center engineering will continue to benefit from hyperscaler buildout. Meta’s MTIA roadmap shows that cloud providers will not only buy external GPUs, but will also develop in-house training and inference chips. Yet in-house chips will not make the external supply chain disappear. They will simply redistribute value among GPUs, ASICs, memory, networking, and system integration.
GPUs Will Not Lose, but XPUs Will Rewrite Profit Allocation: AI Compute Moves from a Chip War to a Compute-per-Watt War
The hardware chain must also accept stricter valuation validation. In the past, once cloud providers raised CapEx, the market could infer upward revisions to demand for GPUs, servers, optical modules, and power equipment. The next step now becomes: once these assets go online, do they have customers, utilization, premium pricing, long-term contracts, and sufficient gross margin? The valuation anchor of the buildout cycle is gradually moving from “order visibility” to “revenue GW” and “cash-flow GW.”
This is equally important for the data center and power chain. Citi notes that industry leasing has begun focusing on 2028-2030 delivery, indicating that near-term high-quality power and data center capacity remain tight. Continued CapEx revisions from buyers such as Meta, Google, Microsoft, and Amazon will keep demand strong for grid interconnection, front-of-the-meter and behind-the-meter power supply, liquid cooling, and interconnect resources. But if future external leasing prices fall, or if 1GW assets struggle to maintain high utilization, the market will turn around and compress valuations for low-quality buildout projects.
Follow the Power: AI Data Centers Move from GPU Shortage to a Revaluation of Grids, 800V, and Power Semiconductors
Therefore, the hardware chain should not treat the Meta event simply as “one more buyer” or “one more seller.” It marks AI infrastructure’s transition from a procurement race to an operations race. What upstream suppliers need to prove in the future is not only that they can deliver equipment, but that this equipment will enter high-utilization, high-price, high-cash-flow compute asset pools.
8. What Is Being Suppressed in the Semiconductor Euphoria Is Not Demand, but the Valuation Narrative
The "last straw" in the title should not be interpreted as AI semiconductor demand collapsing imminently. A more accurate reading is this: Meta selling compute makes the market, for the first time, pull hyperscaler AI capex back from "strategic investment" into the category of an "operating asset." Once investors start asking whether each GW that comes online can be leased out, at what price, to which customers, under what contract duration, and at what gross margin, valuations across the semiconductor chain that rely only on orders and upward capex revisions will be capped.
Over the past two years, the AI hardware trade has followed a very smooth chain of logic: large models keep getting bigger; both training and inference require more GPUs; hyperscalers keep revising capex upward; the semiconductor supply chain keeps receiving orders; and share prices keep receiving higher multiples. This logic works very well when demand is strong, but it contains an implicit assumption: as long as cloud providers spend, capital markets will believe that this spending can ultimately turn into high-return revenue. The Meta event shakes precisely that assumption.
If Meta takes part of its self-owned compute and sells it externally, it means compute is both scarce and needs to be operated. Scarcity supports semiconductor demand; the need to operate the asset suppresses unconditional euphoria. The market will ask: you can buy more GPUs, more servers, and more optical modules, and you can sign longer data center contracts, but after this equipment comes online, will it be consumed by your own AI products, or will it need external leasing to recover cash? If the answer is unclear, larger orders may instead trigger more questions about returns.
This shifts semiconductor-chain valuations from "capex beta" to "asset-return beta." In the past, the market liked to directly translate cloud-provider capex upgrades into supply-chain revenue upgrades. Now it needs to ask one more question: can the compute assets formed by this capex maintain high utilization and high pricing? If not, semiconductor suppliers' near-term revenue may still be very strong, but valuation multiples will compress first, because investors will worry about downstream capex cuts in the next round.
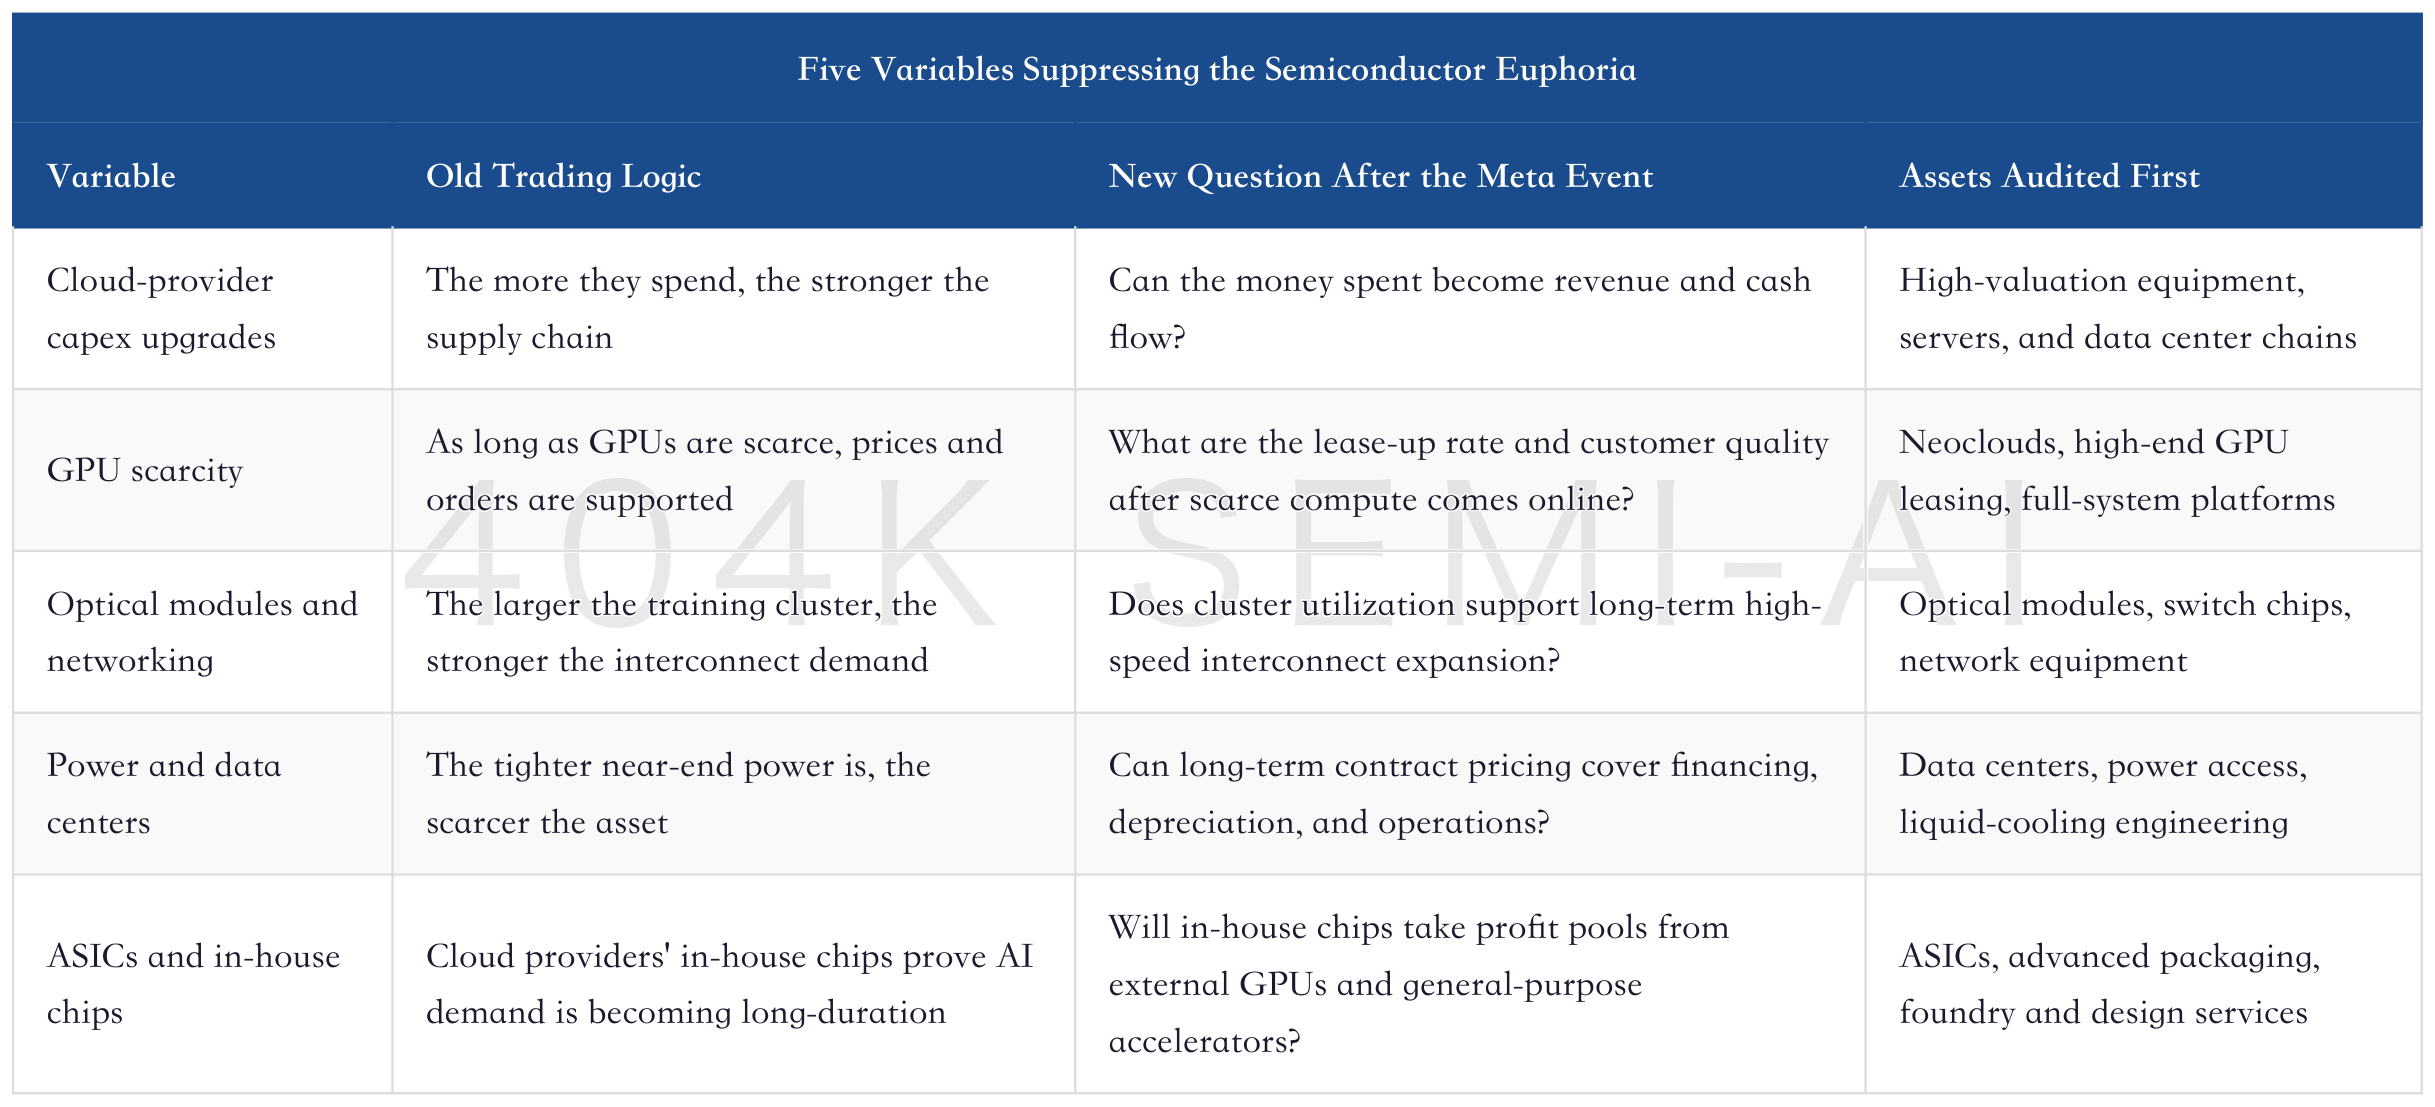
The point of this table is not that the semiconductor chain is ending. Quite the opposite: the segments that can truly prove asset returns will become stronger. Companies that can secure long-term customers, deliver high-utilization clusters, and create bottlenecks in power and networking will still benefit from demand expansion. What gets suppressed is another type of asset: one whose valuation is built entirely on the assumption that "cloud providers will spend endlessly," but that cannot prove high downstream returns after deployment.
The reason the Meta event is so striking is that it happened at the hottest moment of AI capex. The market had been willing to believe that every dollar invested by hyperscalers was aimed at future superintelligence and AI product revenue. But once the act of "selling compute" appears, capital markets gain one more counter-question: if a company's own AI products are strong enough, why does it need to sell compute externally? This question may not be fair, because construction cadence and product absorption cadence can naturally be misaligned, but it is enough to change pricing.
So the biggest risk for the semiconductor chain is not short-term orders, but a slower narrative. Orders remain, deliveries remain, and capex may still continue to be revised upward; but share prices no longer reward only "who got the order." They reward "whose orders correspond to higher-quality downstream cash flow." This is the meaning of the last straw: it does not crush real demand, but it does crush the valuation inertia that ignored returns.
9. Which Segments Are Most Likely to Be Revalued: Not All Semiconductors Face the Same Risk
It would also be wrong to simplify this into "bad for semiconductors." The AI semiconductor chain is too long, spanning GPUs, HBM, switch chips, optical modules, servers, liquid cooling, power supplies, advanced packaging, foundries, equipment, and data center engineering. Different segments face completely different verification pressure. Meta selling compute is more like a sieve, separating the segments that are "definitely beneficiaries of construction" from those that "need to prove downstream cash recovery."
The segments least deserving of indiscriminate selling are those that are genuinely scarce, have long delivery cycles, and are tied to high-utilization clusters. High-end GPUs, HBM, high-speed interconnects, advanced packaging, critical power supplies, and liquid-cooling capabilities still benefit from AI cluster construction in the near term. As long as training and inference demand continues to expand, hyperscalers will not stop procurement just because Meta is exploring external leasing. If external compute leasing can improve asset returns, cloud providers may even have more reason to lock in these scarce resources in advance.
The segments that require more revaluation are those that "only sell construction and do not care about usage." Examples include server systems, some general-purpose equipment, ordinary data center capacity, financing-driven Neocloud assets, and GPU leasing platforms without locked-in customers. They benefited from the construction boom in the past, but the market will now ask: after these assets come online, can they secure high-priced contracts? Are the contract terms long enough? Is customer credit strong enough? Will depreciation speed and financing costs consume profits?
The assets most vulnerable to compression are those whose valuations already imply "AI capex will always be revised upward." If a company's share price assumes higher capex, higher orders, and higher prices every year, but does not explain how downstream customers can earn back that money, then the Meta event becomes a reason for a higher valuation discount rate. Not because it directly takes away orders, but because it reminds the market that AI hardware does not end at delivery; it ultimately has to land in asset returns.
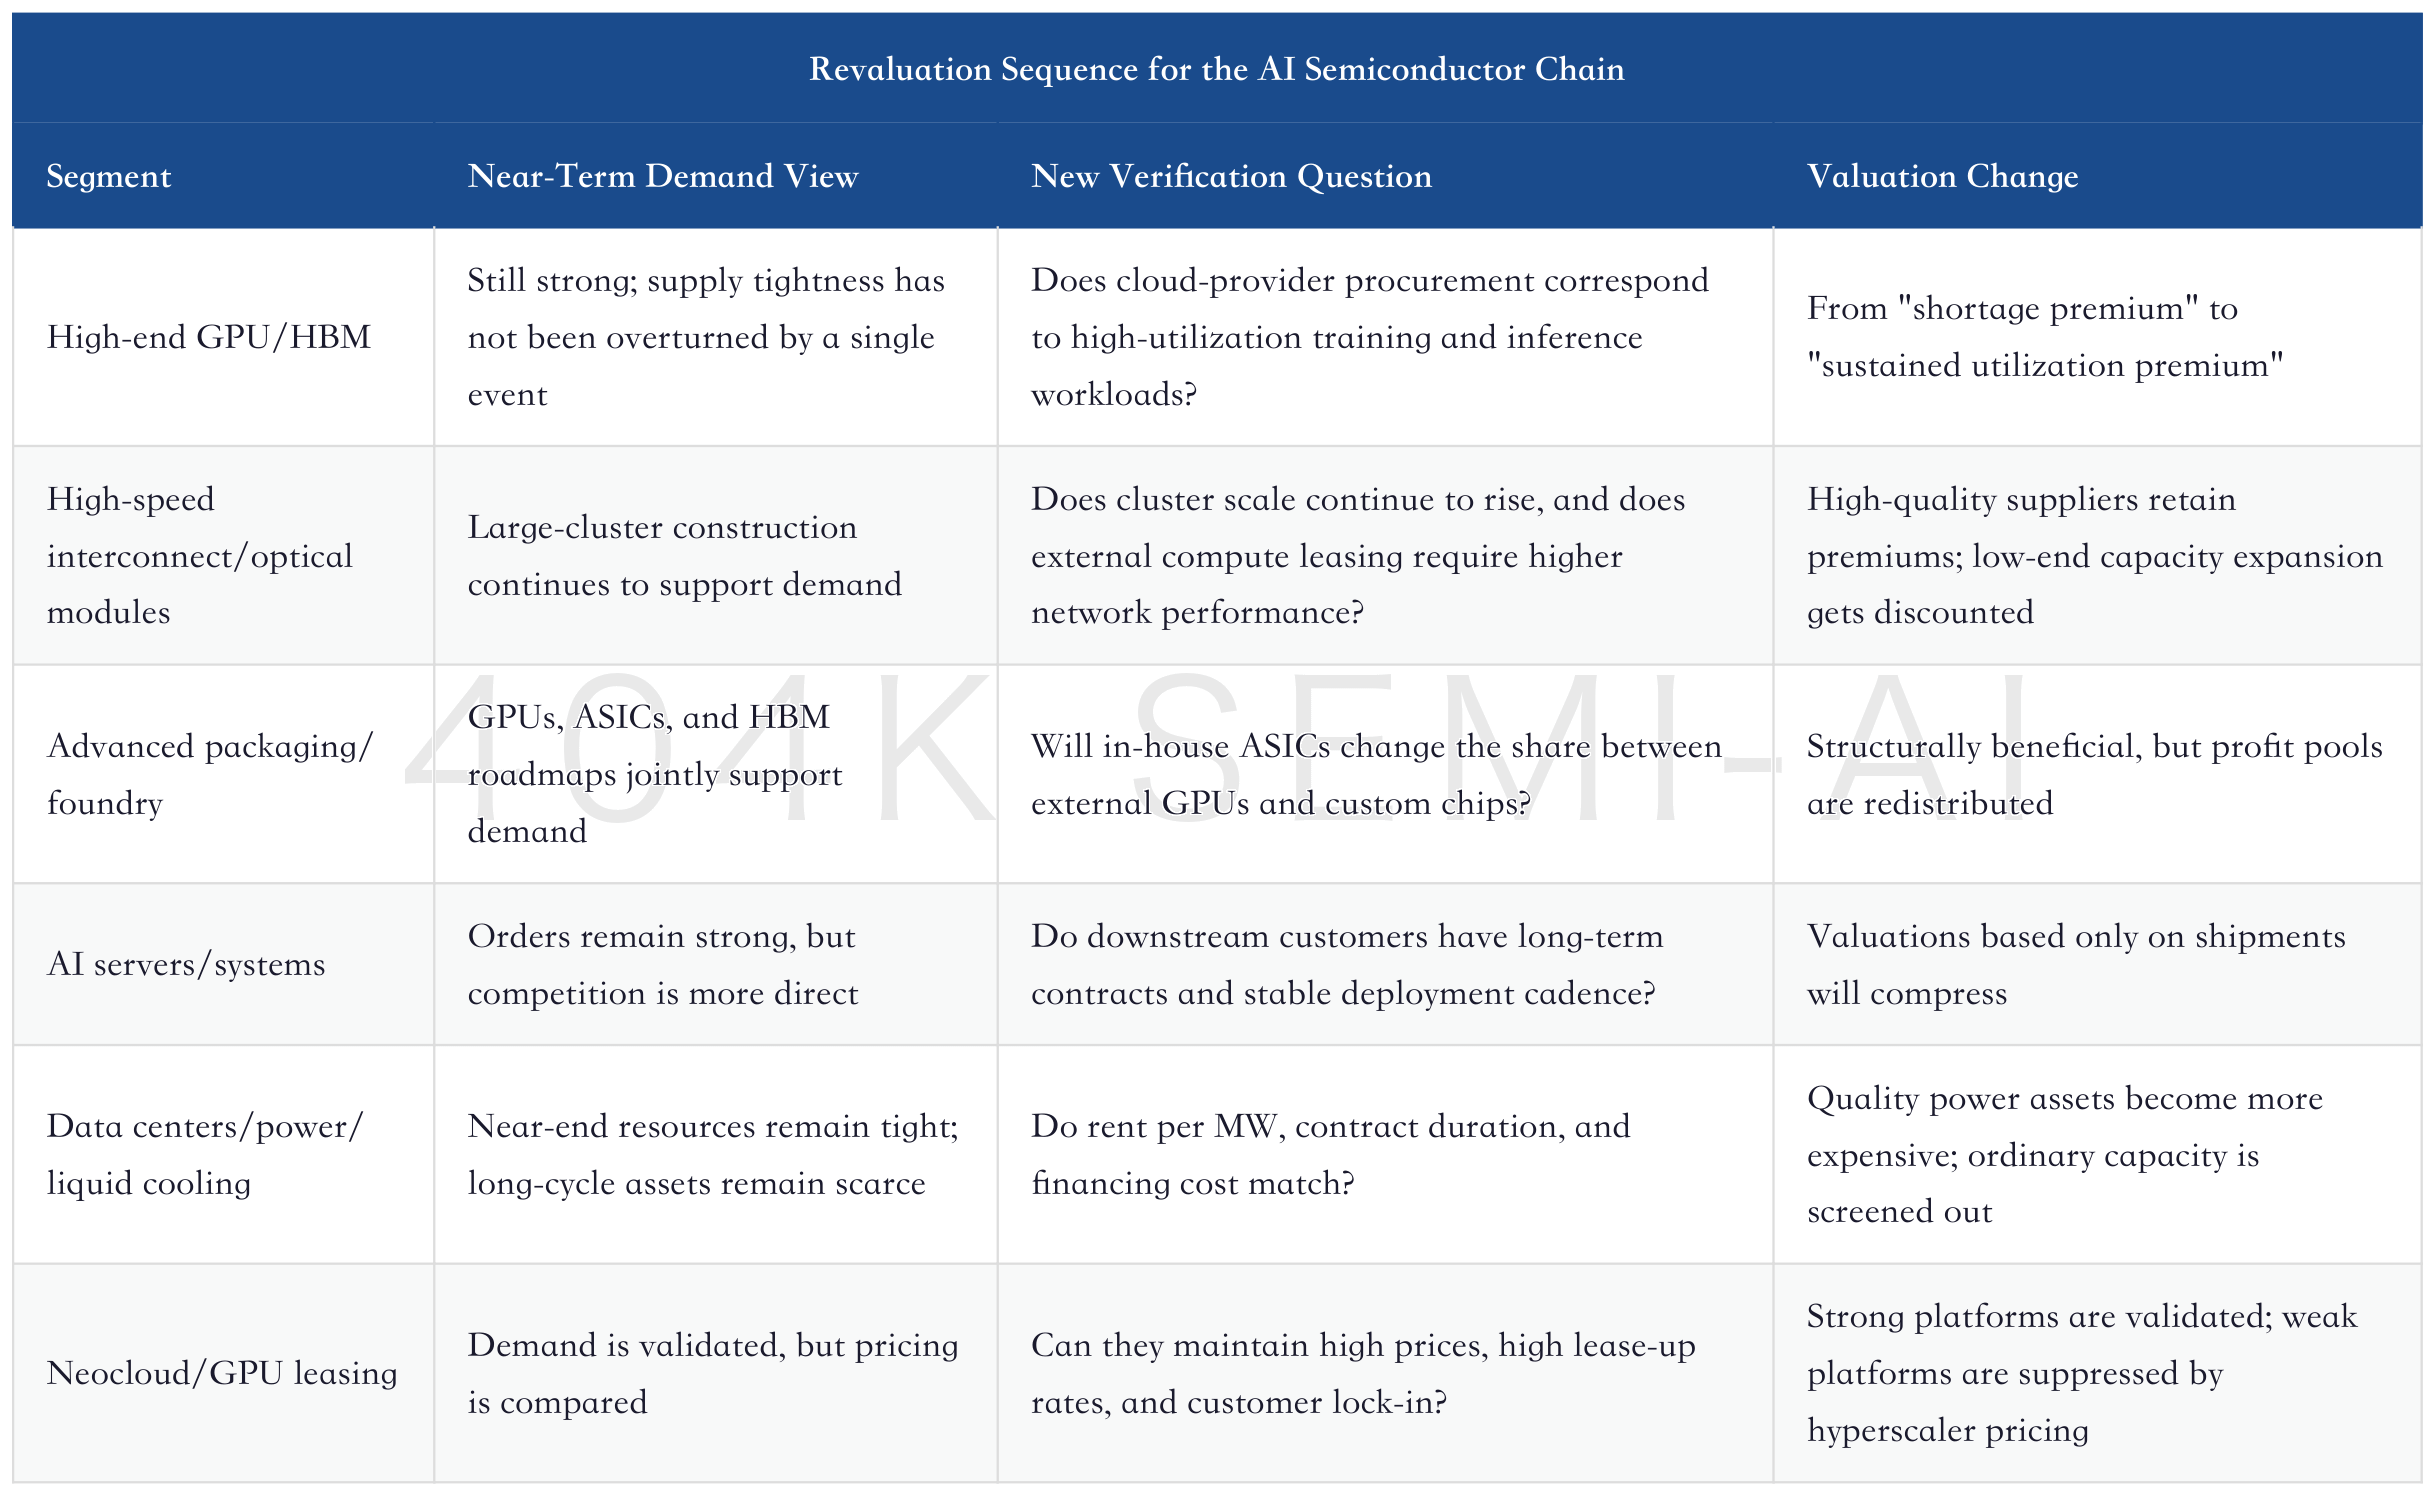
The core of this table is distinguishing between "demand is gone" and "the valuation anchor has changed." If demand is gone, every segment sells off together. If the valuation anchor changes, the market begins to stratify segments. Companies that can prove they connect to high-quality compute assets will still be bought; companies that rely only on AI buzzwords, order announcements, and short-term capacity expansion stories will be sold first.
For the GPU chain, Meta selling compute is not a direct negative. The real issue is that if cloud providers start operating compute as an asset, they will compare the unit economics of GPUs, ASICs, and in-house chips more precisely. Whichever chip can generate higher revenue under given power, networking, utilization, and software-stack conditions will receive more budget. GPUs remain the strongest general-purpose compute foundation, but XPUs and ASICs will continue to reshape profit distribution.
For the optical-module and networking chain, the key issue is not whether Meta sells compute, but whether utilization and east-west traffic in large clusters can keep growing. If external customers lease complete training clusters, network demand will be stronger. If external leasing is only fragmented inference capacity, network intensity may be lower than in training clusters. The market will begin to split "compute capacity" into training, inference, model services, and ordinary GPU leasing, rather than pricing all interconnect demand at the same multiple.
For power and data centers, the Meta event looks more like long-term validation. If compute can be leased out, then power and data centers are not just cost items, but underlying assets capable of generating cash flow. The issue is that only power and data centers that are near-end, stable, quickly deployable, and backed by customer contracts are valuable. Remote projects that lack network access, customers, or cheap financing will be re-discounted within the same AI construction cycle.
For equipment and foundries, near-term orders may not be hurt, but the cycle debate will arrive earlier. As long as hyperscalers are still expanding, advanced processes, packaging, testing, and key equipment will remain in demand. But if the market begins to worry about returns on downstream compute assets, investors will start asking in advance whether the next round of orders can continue. The biggest risk for equipment stocks and the foundry chain is not weak orders this quarter, but a slower pace of new projects after capital spending shifts from rapid expansion to return assessment.
Therefore, this piece is not arguing that the semiconductor euphoria should be killed outright. The more reasonable conclusion is that the AI hardware chain is entering a phase of differentiation. The first category of companies will continue to benefit from scarce resources and high-utilization assets. The second category will still see revenue growth, but valuations will have to give up part of the "infinite capex" premium. The third category, if supported only by financing, concepts, and order expectations, will be suppressed early by events such as a hyperscaler leasing out compute.
10. Three Scenarios for This Event: The Same Action Can Be Interpreted by the Market as Three Completely Different Stories
The most difficult part of Meta selling compute is that the same action can correspond to three completely different interpretations. It can be high-quality asset turnover, the germination of a new cloud business, or passive loss mitigation after insufficient absorption by internal AI products. In the short term, the market will first trade on the most optimistic story, because "selling idle or temporarily surplus compute" sounds like it can address both capex pressure and free-cash-flow pressure at the same time. But medium-term valuations will return to evidence.
The first scenario is high-quality asset turnover. Meta still believes its own AI products will consume most of the compute, but infrastructure is coming online before product revenue is realized, so it sells temporarily available capacity to external customers. In this case, the external leasing scale should be limited, pricing should be high, contracts should preserve flexibility, and Meta should not continue to materially raise long-term capex for external customers. This is the most positive scenario, because it turns AI capex from a pure cost into a revolving asset.
The second scenario is new-business incubation. Meta does not merely sell raw compute; it also builds model access, developer tools, enterprise customer services, and billing systems, creating a Meta Compute platform. This story has a higher ceiling, but also higher execution risk. Meta needs to prove that the Muse model series, the Llama ecosystem, enterprise sales teams, data security capabilities, and customer-success systems can all function. Otherwise, it can easily end up in the awkward position of "having compute but no software."
The third scenario is excess-capacity loss mitigation. If external leasing scale grows larger, pricing is weaker than expected, contracts are very long, and Meta's own AI product revenue fails to keep up, then the market will interpret this as insufficient internal demand. This is the least friendly scenario for the semiconductor chain, because it implies cloud providers built too quickly in the earlier phase and may shift from continuing to add orders toward digesting inventory. Orders will not disappear immediately, but valuations will reflect the next round of capex slowdown in advance.
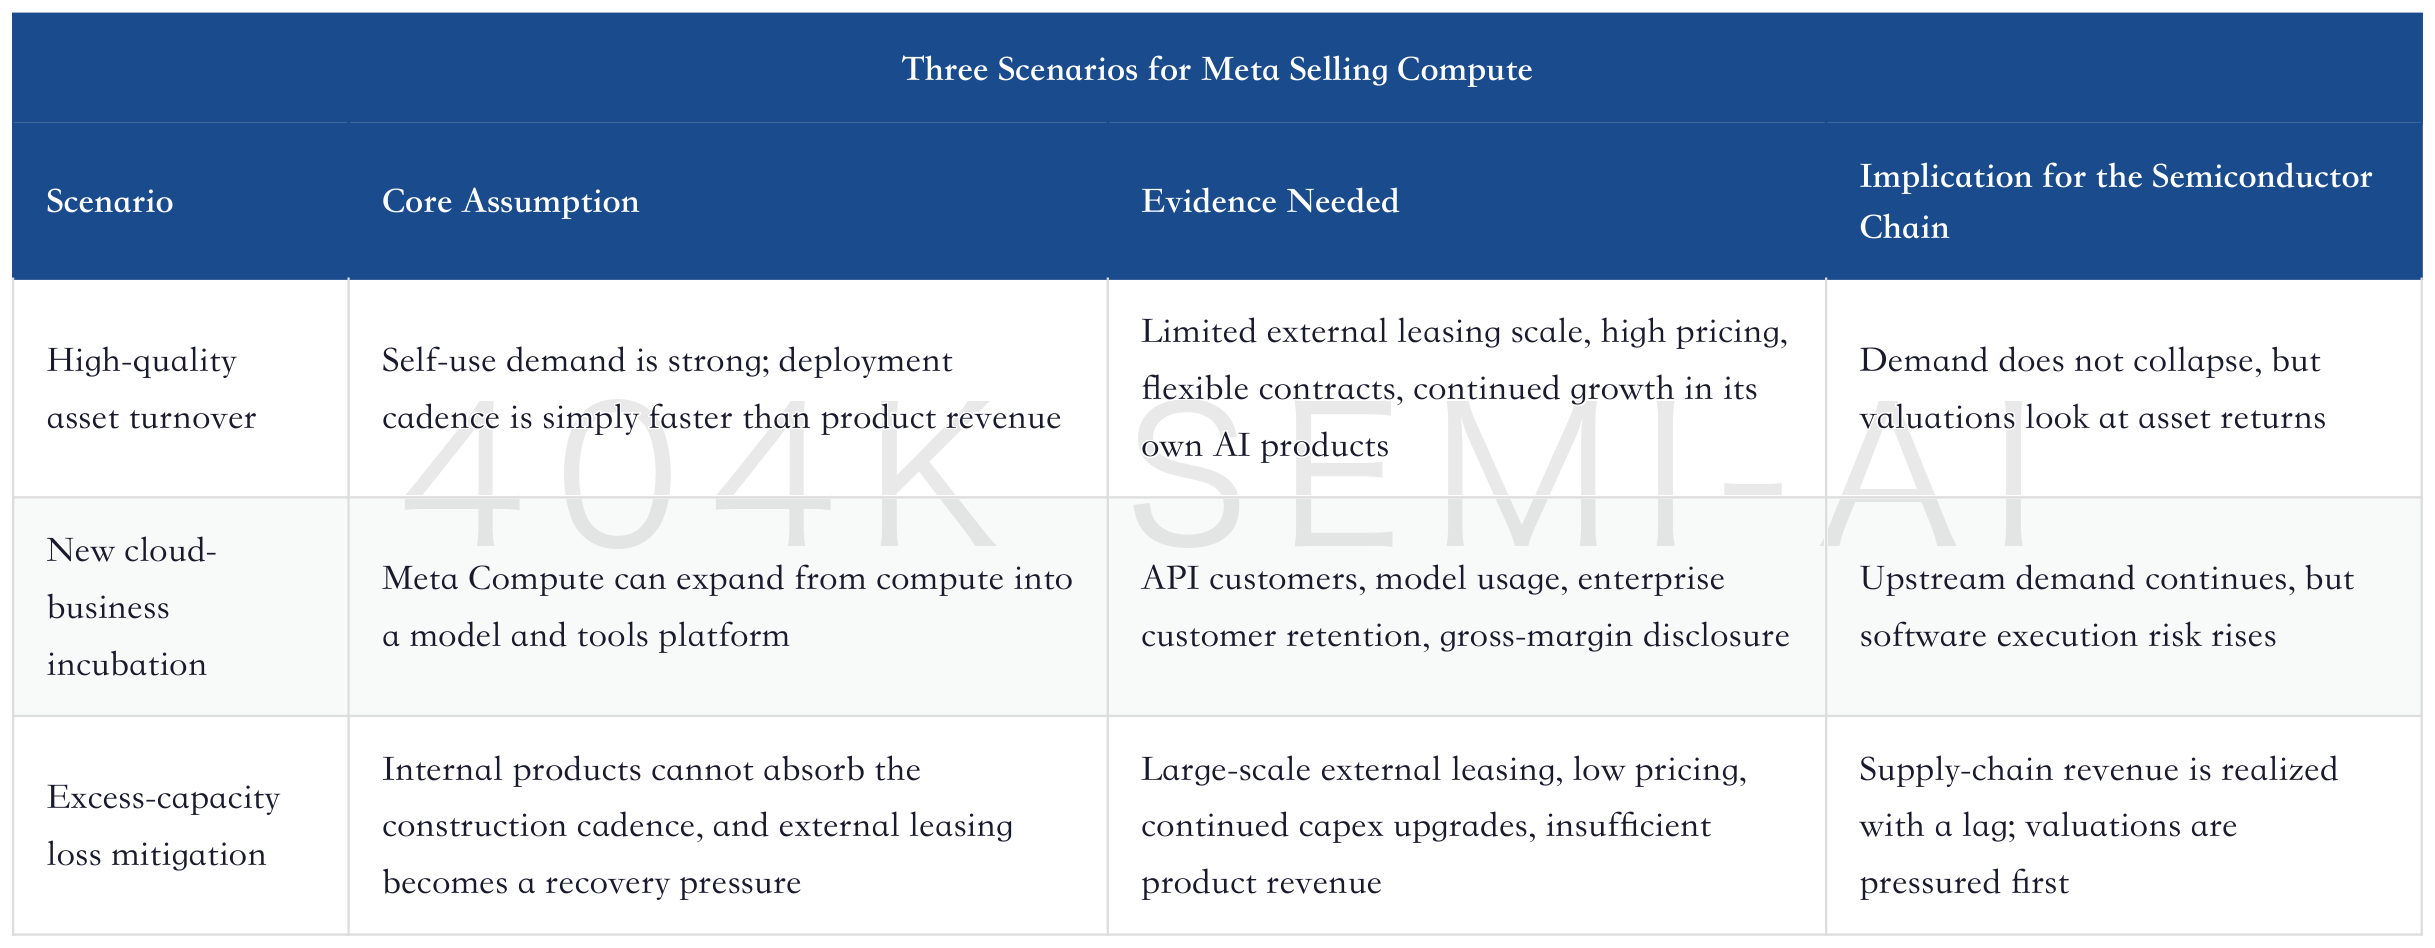
The difference among these three scenarios is not whether Meta sells compute, but why it sells compute. Active turnover and passive loss mitigation both look like "external leasing," but they are completely different for valuation. Active turnover temporarily monetizes scarce assets; passive loss mitigation admits that internal demand is insufficient. Active turnover increases tolerance for capex; passive loss mitigation reduces tolerance for capex.
This is also why the title can say "suppresses the semiconductor euphoria," but the body cannot be written as "semiconductor demand collapses." What is truly suppressed is unconditional optimism. In the past, the market could simply ask, "Can Nvidia ship more GPUs?", "Will cloud providers keep buying servers?", and "Will optical modules keep moving to higher speeds?" Now it also has to ask, "Can customers make money after deployment?", "What is the price of compute leased out by cloud providers?", and "Can AI product revenue keep up with depreciation?" This turns the trade from a single line into a multivariable equation.
If Meta later discloses high external-leasing prices, strong customer quality, flexible contract terms, and continued scaling in ad AI and Business Agents revenue, the semiconductor chain will not be crushed. Instead, it will gain more stable proof of downstream returns. Conversely, if external-leasing prices are low, scale is large, contracts are long, and there is still no revenue evidence from its own AI products, the market will view it as a signal that AI infrastructure has been built too quickly, and high valuations across the semiconductor chain will be repriced.
XI. Why This Is Not Yet a Demand Collapse: Four Counterpoints Cannot Be Ignored
Even though the headline used “the last straw,” four counterpoints cannot be ignored. First, compute remains in short supply. The common premise behind Citi and Morgan Stanley is that AI/HPC demand still exceeds supply, and near-term deliverable capacity remains scarce. If the industry were already oversupplied, Meta would not frame external compute leasing as a cash-flow opportunity, and customers would not be willing to discuss capacity at high prices.
Second, hyperscaler buildout cycles are not linear. For a large data center or GW-scale cluster, from planning, power, civil construction, GPU delivery, network debugging, and software-stack launch, there is naturally a timing gap between capacity arriving first and products arriving later. Equating temporary external leasing directly with “insufficient internal AI demand” underestimates the batch nature of infrastructure construction. Cloud providers cannot precisely buy power, GPUs, and optical modules every week according to model demand.
Third, external compute leasing could increase, rather than reduce, procurement appetite. If cloud vendors discover that part of their capacity can generate cash flow before internal use, their tolerance for locking in GPUs, power, and data-center space ahead of time will be higher. In the past, early construction meant cash flow was consumed; now, early construction may add another recovery path. This logic actually supports long-term AI infrastructure investment, but requires more disciplined investment.
Fourth, AI demand is spreading from training to inference and applications. What Meta truly needs to validate over the long term is advertising tools, Business Agents, messaging monetization, glasses, and personal AI. If these applications continue to grow, training clusters, inference clusters, low-latency networks, and edge/cloud collaboration will continue to consume compute. External leasing is only temporary asset management; it does not mean end applications have no demand.
These four counterpoints show that the Meta event is not a mechanically tradable negative. It is more like a watershed: the market is starting to distinguish between “AI CapEx is still growing” and “AI CapEx deserves a high multiple.” The former is a revenue question; the latter is a valuation question. The semiconductor chain may still see revenue upgrades, but valuation multiples may not continue to expand unconditionally.
The easiest mistake here is to conflate revenue and valuation. Supply-chain companies may still receive higher orders in the short term, and performance over the next few quarters may remain strong. But if downstream cloud providers begin to be asked to prove compute returns, the market will first become more cautious about the supply chain’s forward multiples. This is why share prices sometimes move before fundamentals deteriorate. It is not that orders suddenly disappear, but that discount rates and terminal margins are being repriced.
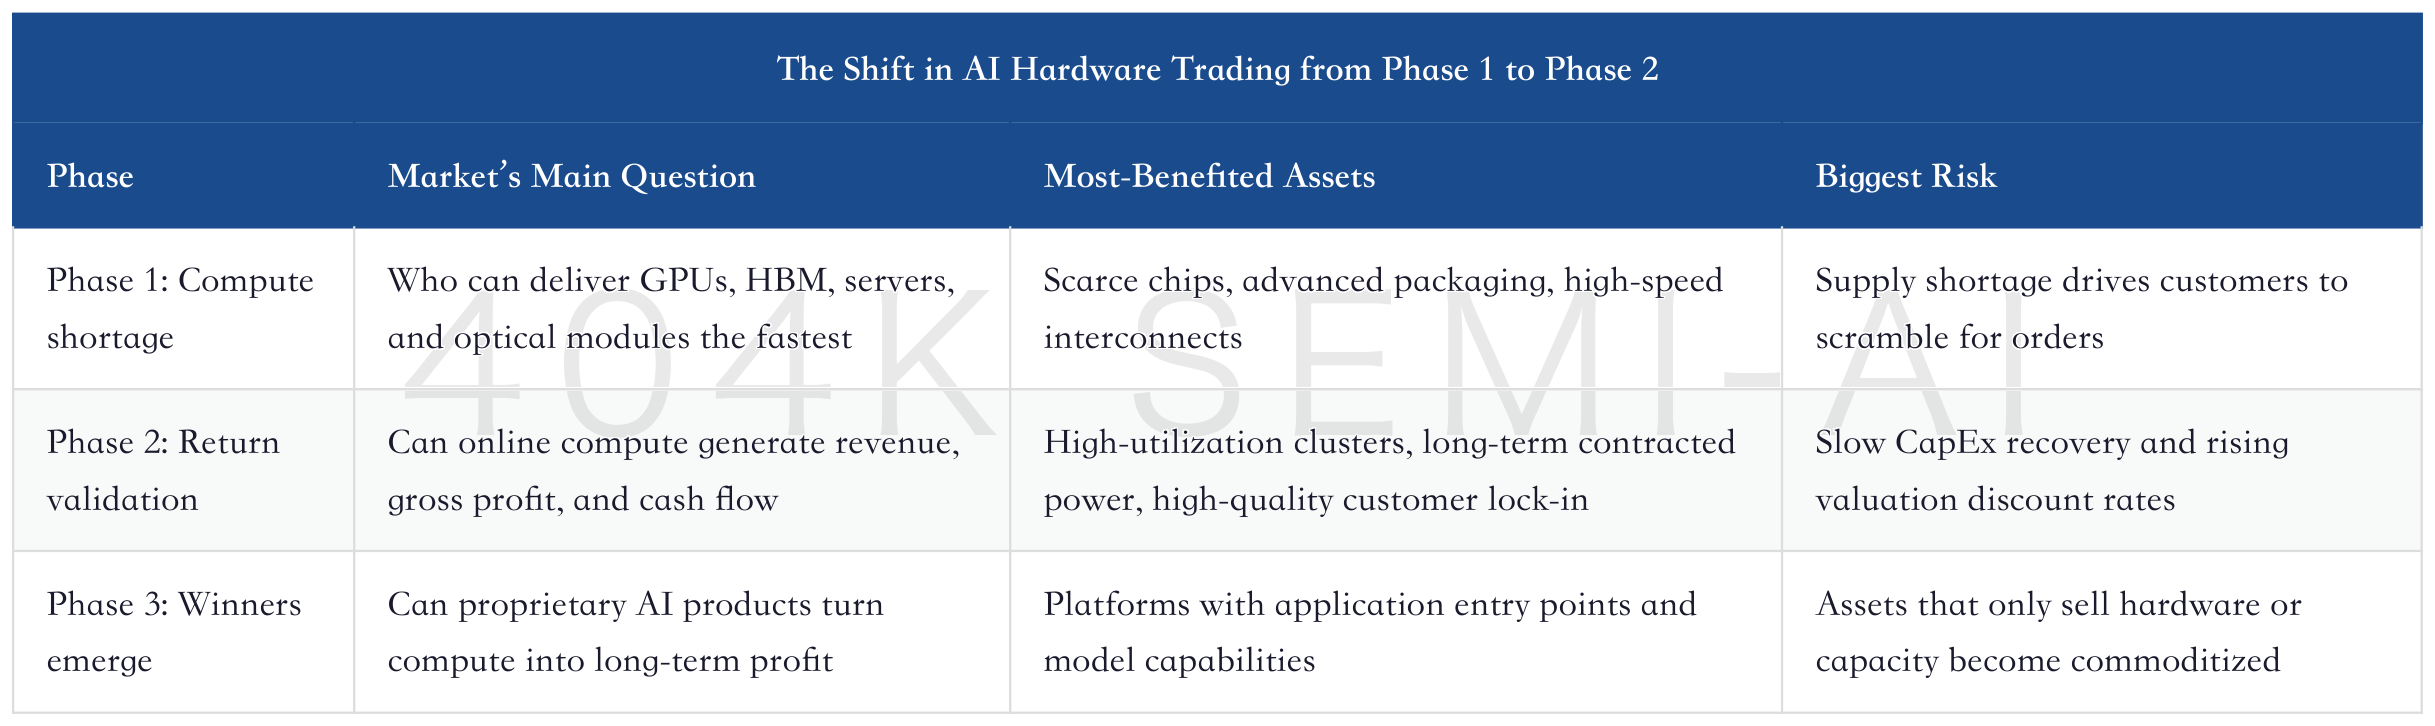
The Meta event pushed the market one step from Phase 1 toward Phase 2. In Phase 1, investors did not care much about how downstream players made money; it was enough to know that demand was large enough, supply was tight enough, and pricing was strong enough. In Phase 2, investors begin to require every link in the chain to answer: who pays, how much they pay, how long they pay, and at what margin. This is not the end of the semiconductor story; it is AI hardware moving from thematic investing into operational validation.
Therefore, the real trading conclusion should be written separately. For segments with scarce supply, long customer relationships, and strong delivery capability, Meta selling compute is not the endpoint; it may only be the beginning of a new round of asset pricing. For segments where valuations have already pulled forward long-term CapEx upgrades but lack proof of downstream returns, the Meta event will become a reason to compress multiples. This distinction is more important than simply calling it bullish or bearish.
XII. Translating the Event into an Investment Framework: Going Forward, Watch Four Operating Variables, Not Just CapEx
This event ultimately needs to be translated into an investment framework; it cannot stop at the headline shock. Going forward, when looking at the AI hardware chain, the first layer is still CapEx, but the second layer must be operating variables. CapEx tells you the scale of construction; operating variables tell you the quality of construction. After Meta sells compute, the market will become increasingly unsatisfied with “cloud providers spent more money again” and will instead demand to see pricing, utilization, contract duration, and customer quality.
The first variable is price. Price is the thermometer for all AI compute assets. High prices indicate that near-term capacity is scarce and customers are willing to pay for delivery certainty; low prices indicate that supply is starting to catch up with demand, or that compute quality, location, network conditions, and service capability are not good enough. Morgan Stanley’s $40/Watt and JPMorgan’s implied $20/Watt are essentially drawing two valuation ranges for the market: the high-end range supports the EPS bridge, while the low-end range is more about cash recovery.
The second variable is utilization. AI clusters are not bought to sit on the balance sheet; they must be used for training, inference, model services, or external customers. The higher the utilization, the easier it is for revenue to cover depreciation pressure; the lower the utilization, the more CapEx looks like demand pulled forward from the future. For the semiconductor chain, utilization is more important than shipments alone, because it determines whether customers will continue to place additional orders in the next cycle.
The third variable is contract duration. Short-term contracts and long-term contracts mean different things. Short-term contracts show that Meta preserves future flexibility for internal use, and also that it treats external leasing as temporary asset turnover. Long-term contracts show strong external customer lock-in, but may also squeeze future capacity for Meta’s own AI products. For investors, the best combination is high pricing, moderate duration, renewability, and no constraint on Meta reclaiming capacity for internal use.
The fourth variable is customer quality. Who rents the compute is more important than how much is rented. If customers are large model companies, enterprise AI platforms, or cloud service providers with cash flow, contract quality is higher. If customers are mainly financing-driven startups, even high prices need to be discounted, because ultimate collections and renewals are unstable. The AI hardware chain will increasingly resemble data-center and infrastructure investment, with customer credit entering valuation models.
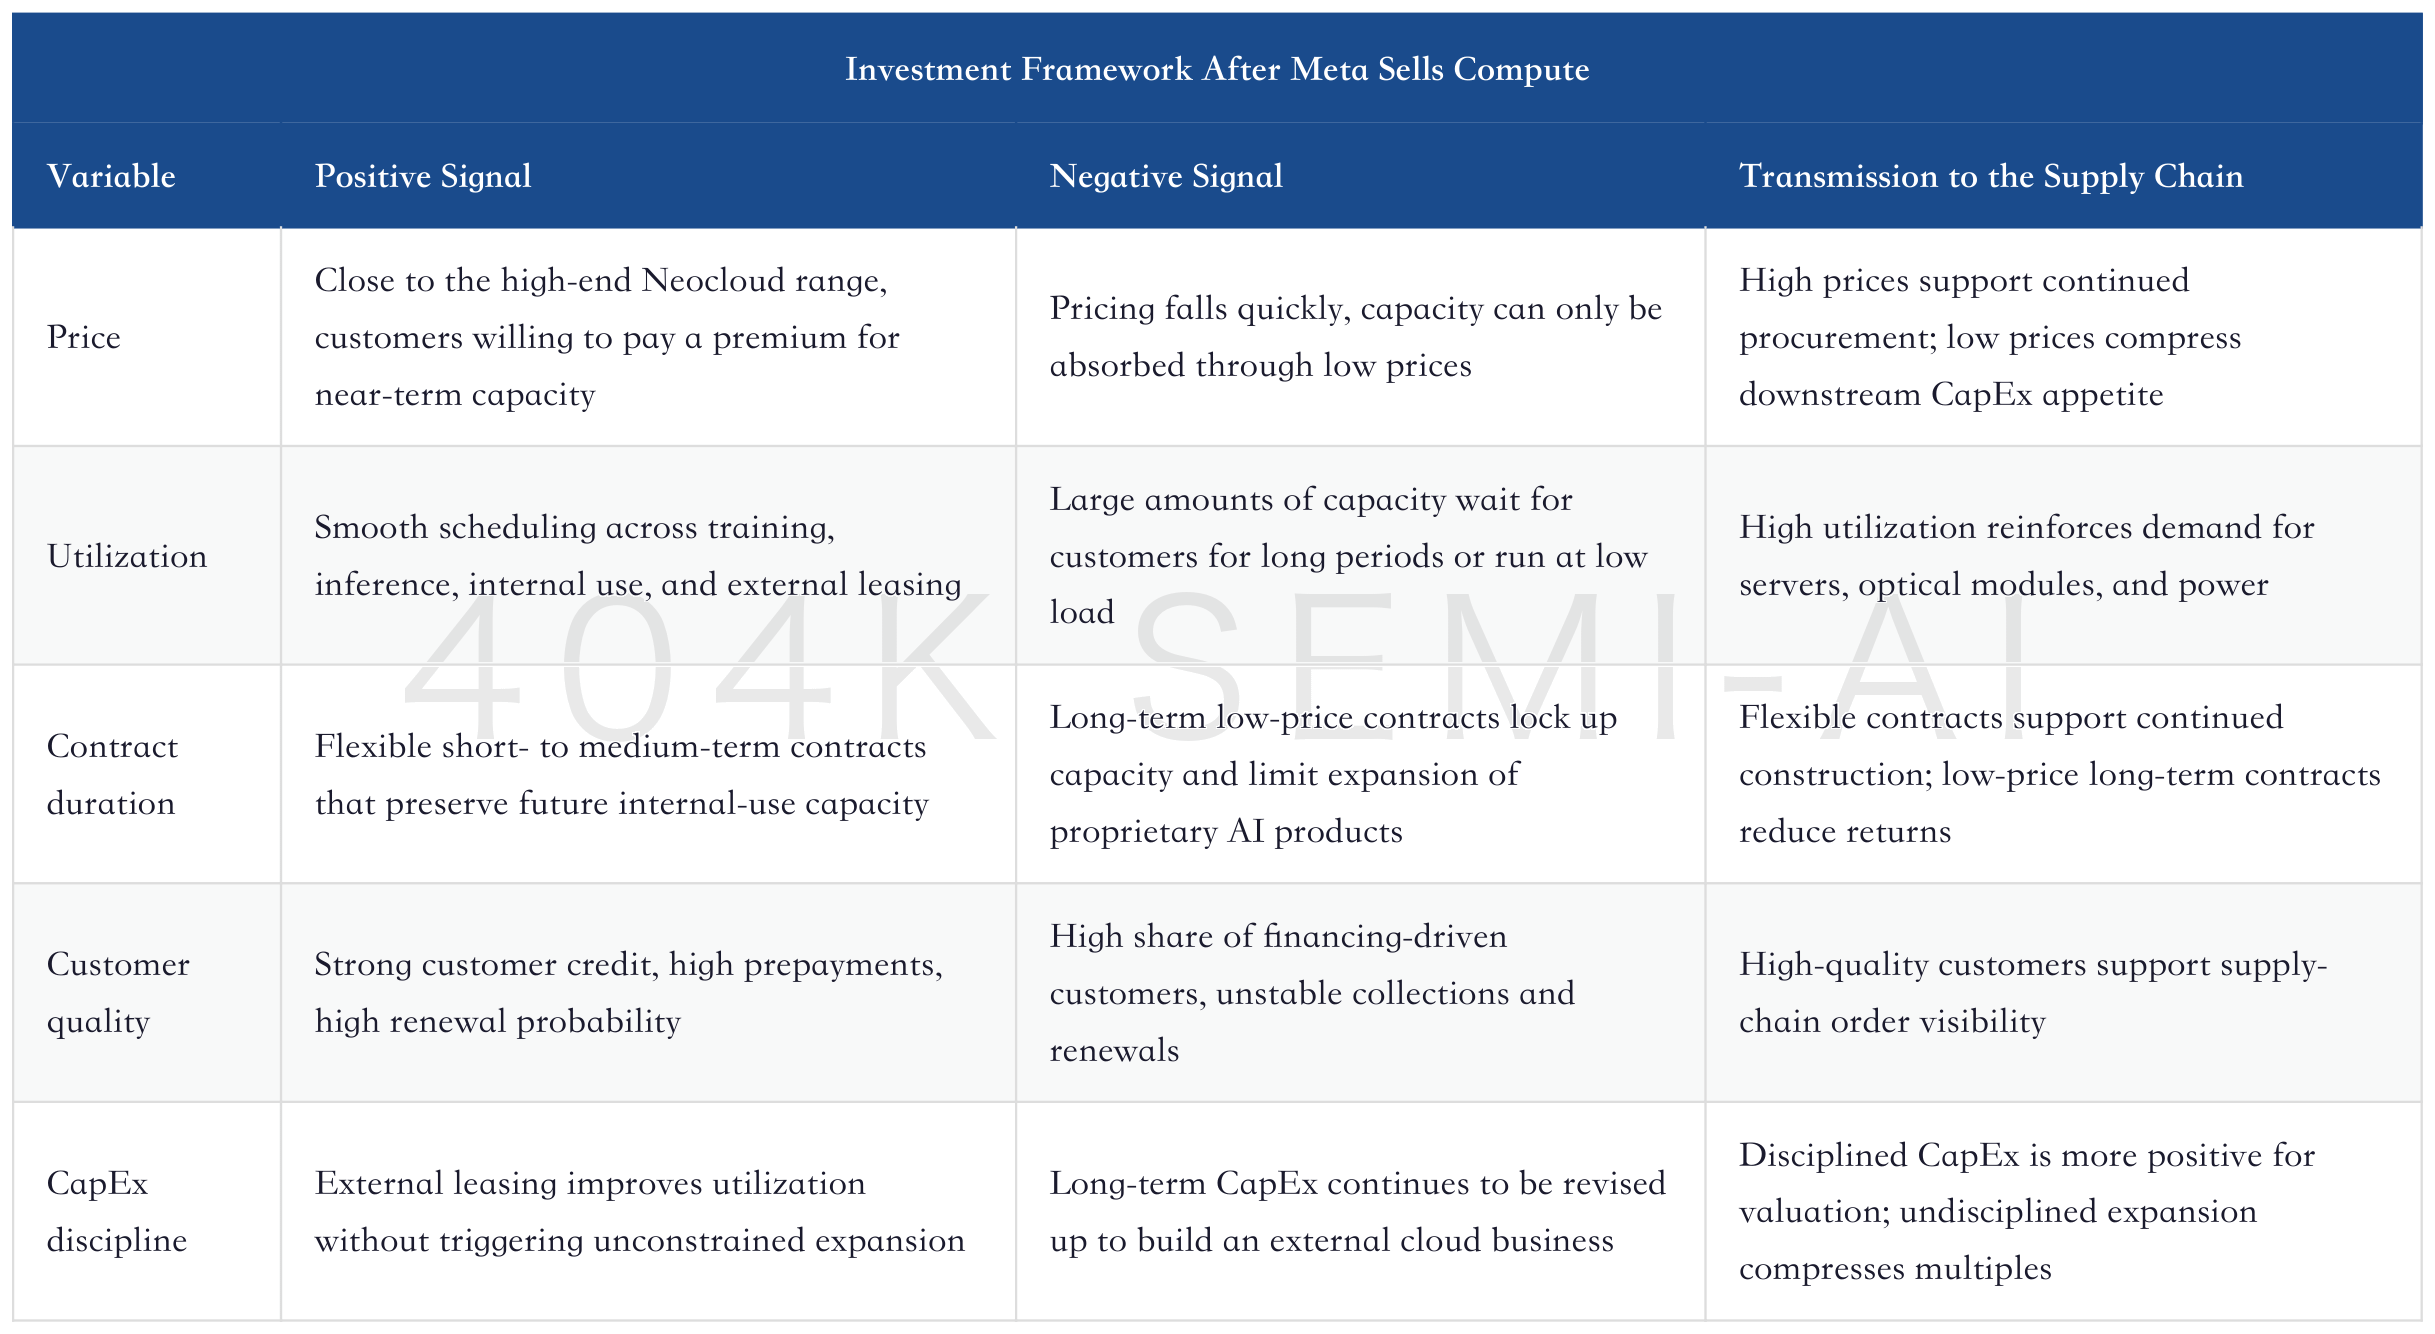
This framework also explains why the semiconductor chain will enter a period of dispersion. Previously, as long as cloud providers said they would build more, all upstream segments could rise together. Going forward, the market will ask how each upstream segment relates to these four operating variables. High-end GPUs, HBM, and high-speed interconnects can continue to command premiums if they are tied to high-utilization clusters. Ordinary servers, low-differentiation components, and financing-driven capacity will face multiple compression if high-quality customers are not visible.
The same applies to cloud providers. If Meta can prove high pricing, high utilization, strong customer quality, and flexible contracts, the market will see it as an improvement in “AI infrastructure operating capability.” If it can only prove that it has a lot of compute to sell, but at low prices, to weak customers, and under long contracts, the market will see it as “remediation after building too quickly.” These two interpretations have completely different implications for the stock price and supply chain.
Most importantly, investors will split AI CapEx into two layers going forward. The first is the build layer, answering whether there are enough chips, data centers, power, and networks. The second is the return layer, answering how much revenue and cash flow these assets generate after going online. The semiconductor rally in the past was mainly in the first layer; the Meta event has pushed the second layer to the foreground. The first layer remains important, but it can no longer determine valuation on its own.
Therefore, any future CapEx upgrade by a cloud provider must be evaluated alongside whether it discloses or implies asset returns. If CapEx is upgraded without a disclosed revenue path, the market will become more selective. If CapEx is upgraded while verifiable utilization, pricing, and customer contracts are provided, the semiconductor chain may receive healthier support. This is the real significance of Meta selling compute: it moves AI hardware from the stage of “the more you build, the better” to “you must build a lot and also use it well.”
XIII. Meta’s Own Long-Term Value Still Depends on Proprietary AI Products
The short-term positive comes from cash flow and the EPS bridge; long-term valuation still comes back to Meta’s own AI products. Morgan Stanley put it directly: the bullish case for Meta is not that it becomes a Neocloud, but that it launches new products on its own platforms that can increase engagement, revenue, and multi-year growth.
This main thread includes several directions. First is advertising efficiency: AI recommendations, creative generation, ad automation, and measurement improvements continue to raise monetization efficiency for Reels, Instagram, Facebook, and WhatsApp. Second is Business Agents and messaging monetization, moving enterprise customer service, sales, and conversion into the private domains of Messenger, WhatsApp, and Instagram. Third is subscriptions and AI tools, turning user scale into non-advertising revenue. Fourth is glasses and personal AI, connecting device entry points with social scenarios.
If these products can absorb Meta’s incremental compute, external compute leasing is only temporary asset turnover, and valuation will be healthier. The market will believe that Meta first uses leasing to cover construction pressure, then reclaims capacity once its own products mature, forming a path of “lease first, use internally later.”
If these products fail to generate large-scale revenue for a long time, external compute leasing will be reinterpreted. Investors will worry that Meta originally built capacity for superintelligence and proprietary AI products, but ultimately had to sell compute to others. At that point, Meta Compute will no longer be a high-quality option; it will become “remediation after excess capital expenditure.”
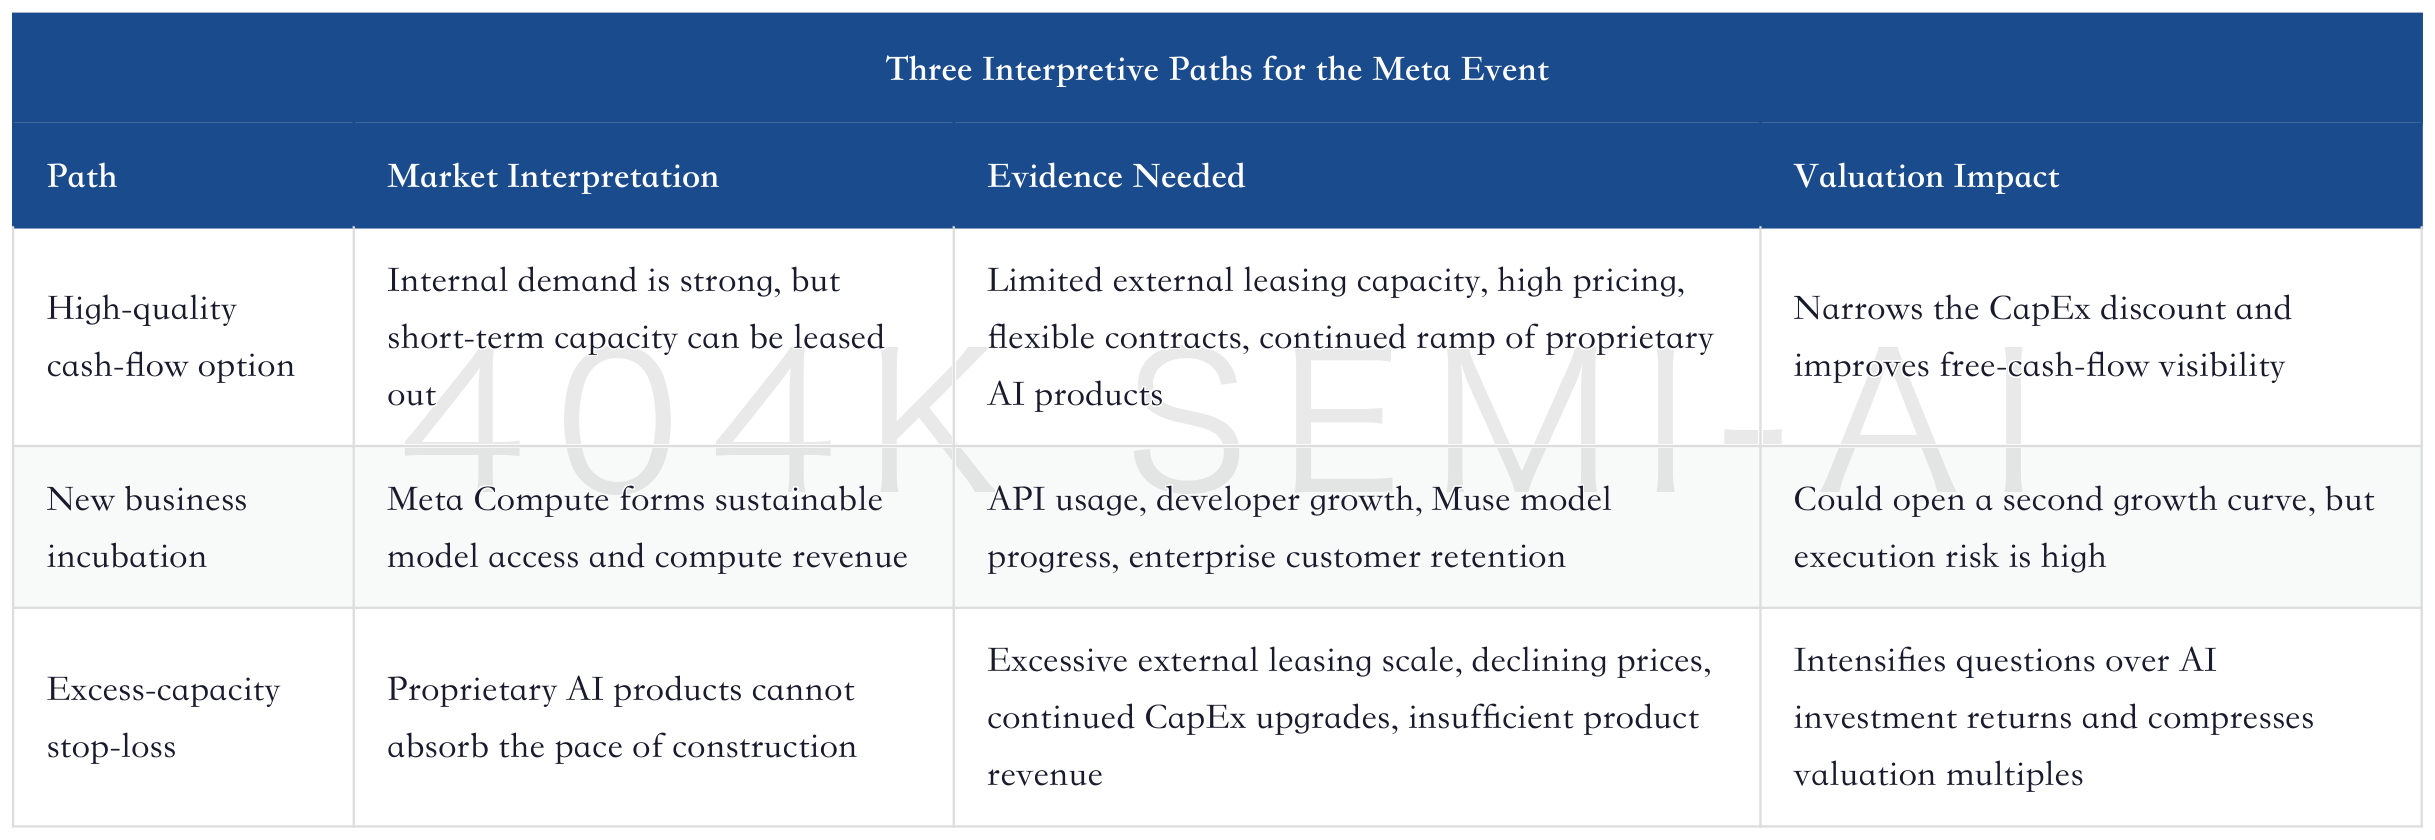
The easiest mistake in trading the event is to look only at the first path. Meta’s strong stock-price reaction to the news shows that the market is willing to price the cash-flow option. But what truly determines sustainability is that external leasing scale cannot be too large, pricing cannot be too low, CapEx cannot lose control, and proprietary AI products cannot remain at the concept stage. If any one of these becomes imbalanced, the market will switch from “cash-flow option” back to “overbuild risk.”
XIV. Why This Changes How the Market Debates AI CapEx
In the past, market discussions around AI CapEx often centered on two questions: who is spending the most, and who is getting the supply-chain orders. After the Meta event, the debate will look more like real estate, shipping, or data-center REITs: where are the assets, when do they come online, what is the occupancy rate, what is the rent, how long are the contracts, what is the customer credit quality, and how high are depreciation and financing costs?
This does not mean AI compute will become a fully traditional asset. GPUs depreciate faster, technology iterations are more aggressive, improvements in model efficiency will compress the unit value of compute, and customer demand may shift from training to inference, or from GPUs to ASICs. But as long as high-quality near-term compute remains scarce, the market will value it through the lens of asset turnover.
This shift will affect every AI infrastructure company. Cloud vendors need to prove CapEx can turn into revenue. Neoclouds need to prove high-priced contracts can cover financing costs and equipment depreciation. Data centers need to prove power and site locations are sufficiently scarce. Hardware suppliers need to prove orders are not one-off inventory replenishment, but long-term demand for capacity coming online. Model companies need to prove rented compute can generate sufficiently high product revenue.
The AI Trade Has Moved Ahead of Macro: Recalibrating Compute CapEx, Earnings Expectations, and Market Pricing
The Meta event brought this question to the forefront. A company with an ecosystem of roughly 4 billion users, advertising cash flow, AI product ambitions, and hyperscale infrastructure plans still needs to explain to the market how its compute investment will be recovered. If it chooses to rent out part of its capacity, that means capital markets have already begun requiring AI infrastructure to move from “strategic investment” toward “operating asset.”
This is also why the event is not simply a Meta story. It will affect how the market discounts the entire AI CapEx chain. Companies focused only on construction will be asked about revenue. Companies focused only on revenue will be asked about gross margin. Companies focused only on gross margin will be asked about depreciation and the supply cycle. Companies focused only on the supply cycle will be asked whether end AI products have real demand. The second stage of the AI trade places more emphasis on cash recovery than the first stage did.
XV. Follow-Up Checklist: Four Sets of Numbers Will Define the Event
This event does not need to be validated by slogans. It only requires tracking four sets of numbers.
The first set is product form. Whether Meta formally confirms Meta Compute, whether it offers both model access and raw compute rental, and whether it discloses the commercialization model for Muse Spark or other models. If it only rents out raw compute, this is asset turnover. Only if model access is also launched can it enter the discussion as a platform business.
The second set is capacity and pricing. 250MW is only the unit used in Morgan Stanley’s model. The key is whether actual externally rented capacity is tens of MW, hundreds of MW, or GW-scale. Pricing needs to be assessed by dollars per watt, GPU-hour pricing, contract duration, and whether power, networking, storage, operations, and model services are included. The closer pricing is to $40/Watt, the clearer the EPS bridge; the closer it is to $20/Watt, the more the significance lies in cash recovery and utilization optimization.
The third set is CapEx guidance. Morgan Stanley’s model assumes Meta’s 2027/2028 CapEx reaches $175 billion/$205 billion, and that this model is primarily used for Meta’s own products rather than a full cloud business. If Meta continues to raise long-term CapEx for an external cloud business, the market will raise the discount rate. External compute rental was originally meant to buffer cash flow; if it instead triggers even more construction, the positive effect will be diluted.
The fourth set is revenue from Meta’s own AI products. Ad efficiency, Business Agents, messaging monetization, subscriptions, glasses, and personal AI products need to provide evidence across engagement, payment, conversion, and revenue. As long as Meta’s own applications grow strongly enough, external compute rental is temporary cash-flow management. If its own applications do not generate clear revenue, external compute rental will be viewed as insufficient demand.
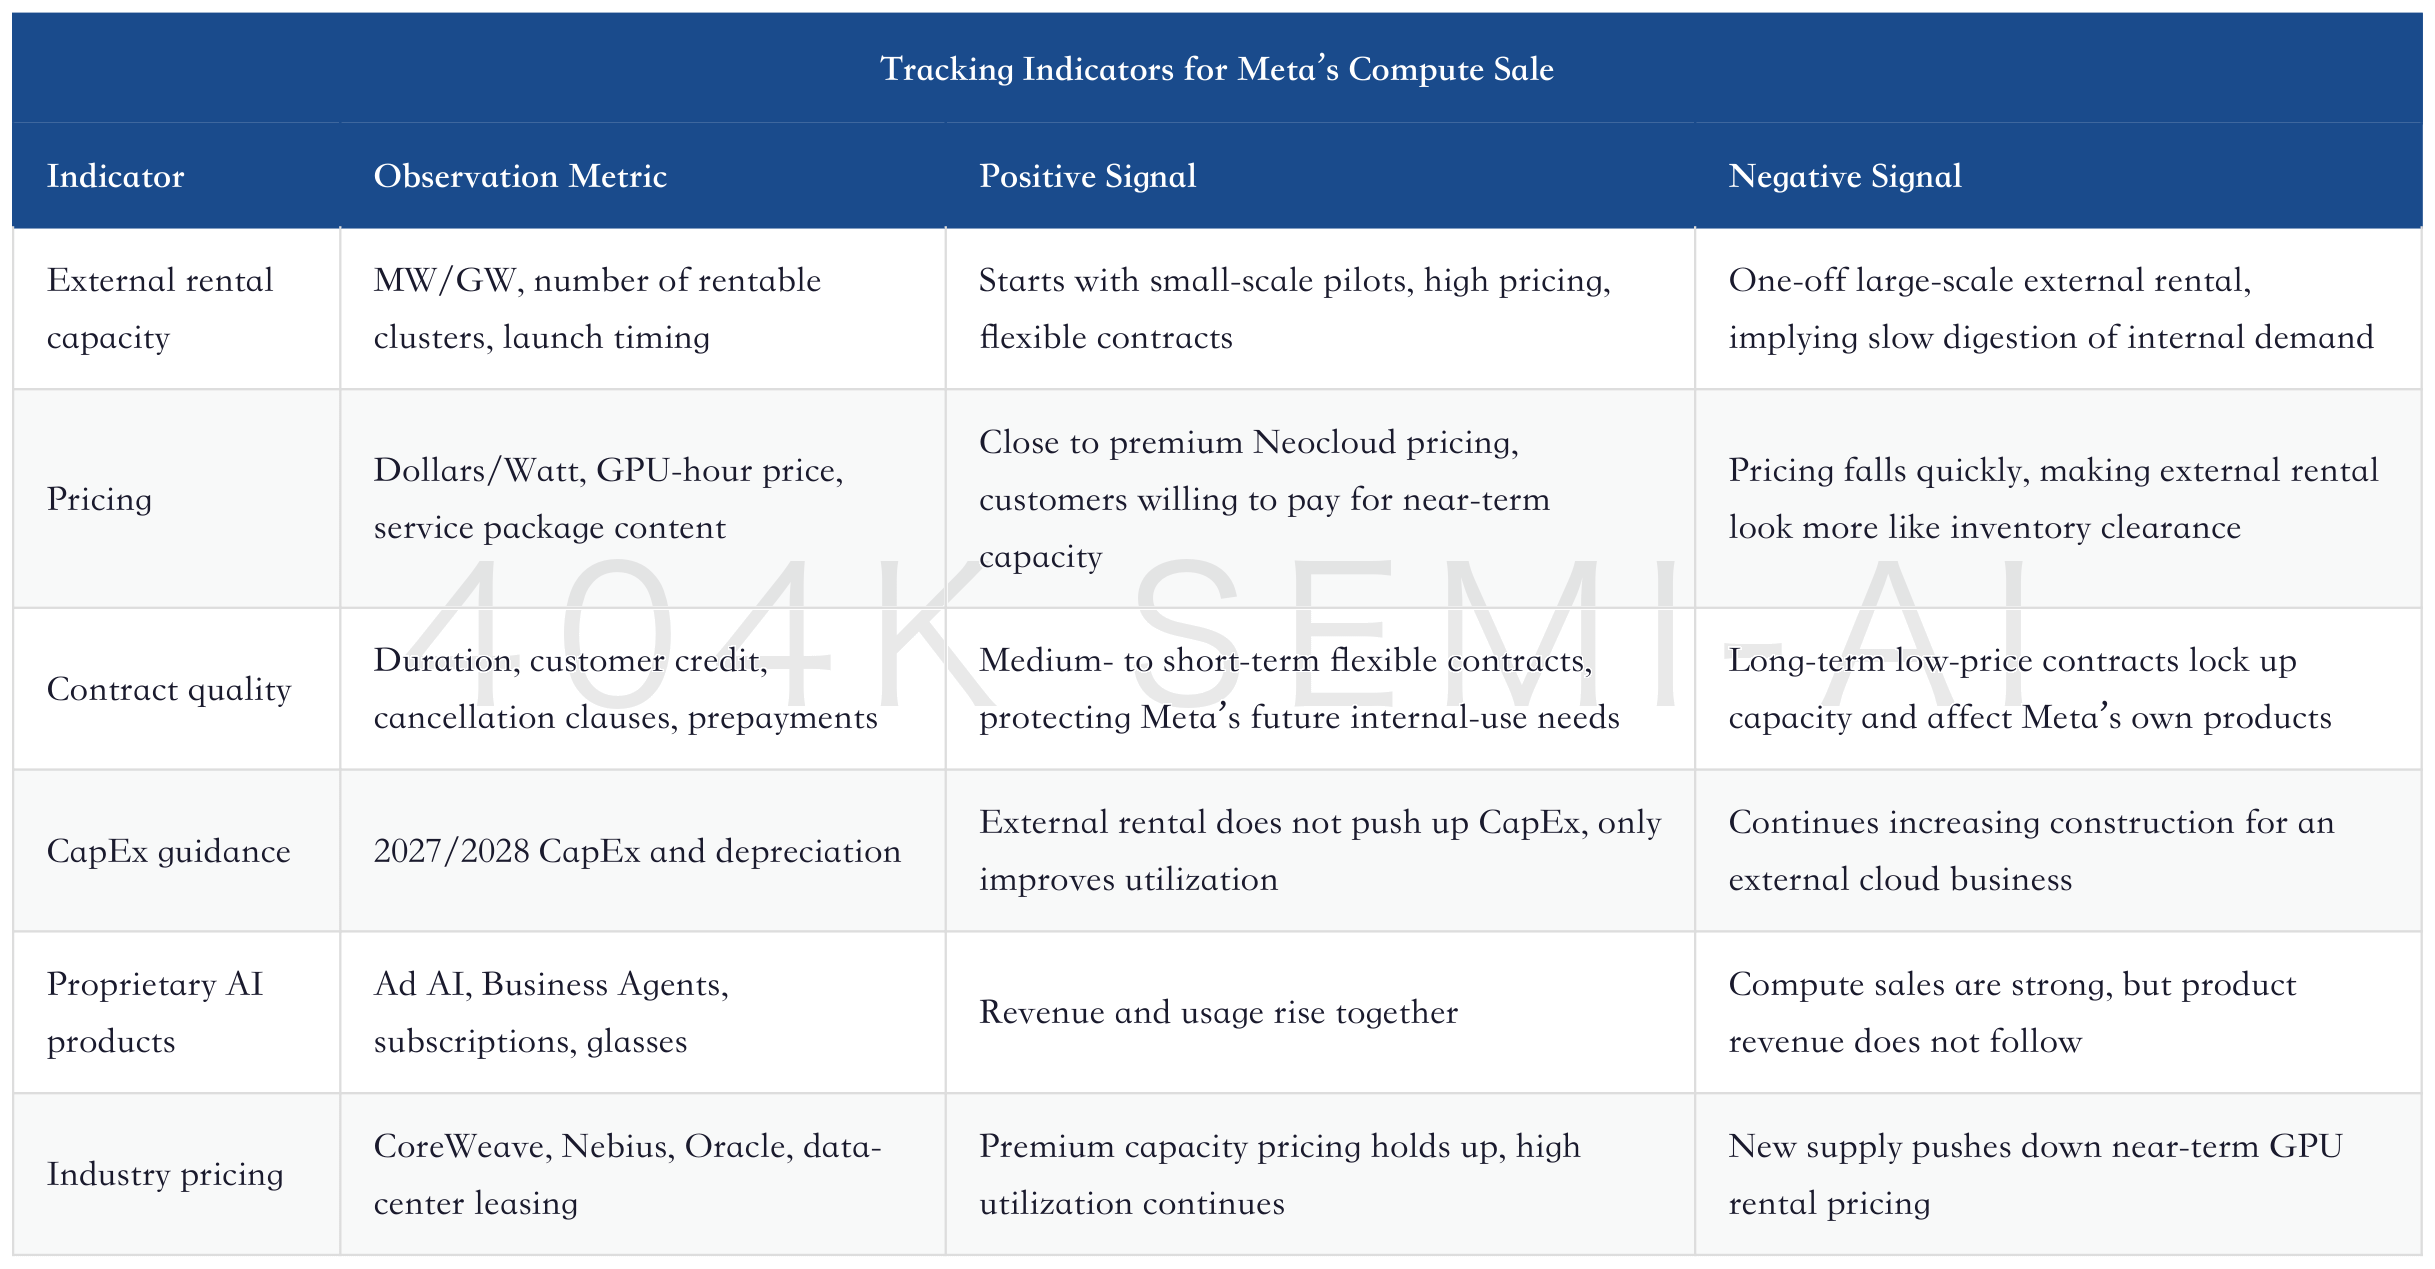
This checklist is more important than the short-term share-price reaction. The first layer of value in Meta selling compute is that the market has finally begun pricing AI infrastructure using MW, GW, dollars/Watt, occupancy rates, and incremental EPS. The second layer is that it forces all cloud vendors to explain the revenue recovery path for their CapEx. The third layer is that it helps investors distinguish “high-quality asset turnover” from “loss mitigation for excess capacity.”
This checklist also provides a more practical order of judgment. First look at product form, then capacity and pricing, then CapEx discipline, and finally revenue from Meta’s own AI products. Product form determines whether Meta is simply turning over raw compute or trying to build a cloud platform. Capacity and pricing determine whether this can translate into EPS. CapEx discipline determines whether external rental instead triggers more construction. Revenue from Meta’s own AI products determines whether the story ultimately has to rely on selling compute. All four variables must be assessed together; looking at any one in isolation can easily lead to misjudgment.
If one only looks at product form, Meta Compute sounds like a new cloud business, making it easy to assign too high a valuation. If one only looks at Morgan Stanley’s EPS sensitivity, it is easy to mistake the 250MW modeling unit for a confirmed scale. If one only looks at upward CapEx revisions, it is easy to continue treating the semiconductor chain as an unconditional beneficiary. If one only looks at JPMorgan’s cautious reminder, normal asset turnover may be misread as demand collapse. The real judgment should be: can Meta sell temporarily available compute at a good price without sacrificing its own AI products, and without losing CapEx discipline?
For the semiconductor chain, this sequence also helps avoid emotional trading. When seeing Meta sell compute, the first question should not be “is this negative for GPUs?” It should be “what type of capacity is being sold, what is the price, who is the customer, how long is the term, and will it affect the next procurement cycle?” If the answers point to high pricing, high customer quality, and high utilization, the hardware chain still has support. If the answers point to low pricing, weak customers, and large-scale passive external rental, that is when the semiconductor rally is truly being capped.
This is also where the question mark in the title of this report lies. It is not asserting that Meta selling compute has already crushed semiconductors. Rather, it signals that the market finally has an event sample with which to challenge the semiconductor boom: when one of the largest buyers starts discussing selling compute outward, every upstream segment must explain what kind of downstream return its orders ultimately correspond to. Segments that can answer this question will continue to retain capital. Segments that cannot answer it will see valuation discounts first, even if near-term orders are still there.
In other words, the most important thing for the semiconductor chain from here is not to keep proving that “demand exists,” but to prove that “demand quality is good enough.” AI orders from high-utilization training clusters, long-term inference workloads, and stable enterprise customers should be worth more than orders driven by one-off rush buying, financing-led expansion, or low-priced external rental used to absorb capacity. The Meta event magnifies this distinction: the market will continue buying scarce supply, but it will no longer be willing to pay the same valuation multiple for every AI order.
This distinction will directly affect stock selection and industry comparisons. In the future, when companies say “AI server orders are growing,” the market will care more about whether the customer is a hyperscale cloud vendor, whether the order is tied to compute already coming online, whether delivery enters a high-utilization cluster, and whether downstream contracts are supported by cash flow. Companies that can answer these questions clearly are the ones truly able to pass through AI CapEx scrutiny.
Therefore, this event is more like adding a revenue-quality threshold to AI semiconductor valuation, rather than putting an end to demand itself.
Whoever can connect orders, customers, utilization, and cash flow can still remain in the AI main line. Whoever can only talk about incremental CapEx will be asked by the market to cool down first.
That is the real dividing line.
XVI. Conclusion: Meta Sells Compute; What the Market Is Buying Is Proof of AI CapEx Recovery
The most important aspect of Meta selling compute is not that Meta has added a cloud business, but that AI CapEx is beginning to be required to provide proof of recovery. Whether Morgan Stanley’s 250MW sensitivity analysis can translate into real capacity and real pricing, whether 1GW can contribute $20 billion to $40 billion in annual revenue, and whether Meta Compute can dispatch capacity between internal use and external rental: these questions will gradually replace the crude narrative of “who is spending the most.”
In the short term, this event will improve the narrative around Meta’s AI investment returns. Citi’s $850 price target, Morgan Stanley’s $775 price target, and JPMorgan’s cautious reminder are essentially all centered on the same line: Meta’s core advertising business remains strong, but AI CapEx is too large, and the market needs to see a recovery path. External compute rental provides an answer that is calculable, trackable, and falsifiable.
It will also reshape the entire AI infrastructure chain. Neoclouds will be repriced, data centers and power assets will be reordered, GPU and ASIC demand will shift from “whether cloud vendors buy” to “whether there is revenue after capacity comes online,” and cloud vendors will move from a comparison of “who builds more” to “who uses it better.”
The more prudent judgment is this: Meta Compute is currently a cash-flow option, not a second AWS. It can buy Meta time and give the market a valuation yardstick. But its long-term value will still depend on Meta’s own AI products absorbing compute and lifting advertising and new-business revenue. Going forward, tracking the four sets of numbers around capacity, pricing, CapEx, and proprietary product revenue will determine whether this event is the start of AI CapEx recovery, or another temporary remedy after a new round of overbuilding.Meta Selling Compute: The Last Straw That Overwhelms the Semiconductor Euphoria?
目录
TL;DR
I. Clarifying the Event: Meta Is Not Selling “Cloud,” but Scarce Compute That Can Be Turned Over
II. The Three Sell-Side Differences: Citi Looks at Cash Flow, Morgan Stanley at the EPS Bridge, JPMorgan at Internal Demand
III. How to Use Morgan Stanley’s 250MW Model: It Is a Sensitivity Ruler, Not an Event Fact
IV. Why Meta Has Capacity to Sell: Not “Idle” Capacity, but a Mismatch Between Buildout Cadence and Product Cadence
V. For Neocloud, This Is Both Validation and a Pricing Stress Test
VI. For Cloud Providers, This Is Not Simple Competition but a Stratification of the AI Cloud Business Model
VII. Impact on the AI Hardware Chain: Orders Remain Strong, but Valuation Starts Looking at “Post-Deployment Revenue”
8. What Is Being Suppressed in the Semiconductor Euphoria Is Not Demand, but the Valuation Narrative
9. Which Segments Are Most Likely to Be Revalued: Not All Semiconductors Face the Same Risk
10. Three Scenarios for This Event: The Same Action Can Be Interpreted by the Market as Three Completely Different Stories
XI. Why This Is Not Yet a Demand Collapse: Four Counterpoints Cannot Be Ignored
XII. Translating the Event into an Investment Framework: Going Forward, Watch Four Operating Variables, Not Just CapEx
XIII. Meta’s Own Long-Term Value Still Depends on Proprietary AI Products
XIV. Why This Changes How the Market Debates AI CapEx
XV. Follow-Up Checklist: Four Sets of Numbers Will Define the Event
XVI. Conclusion: Meta Sells Compute; What the Market Is Buying Is Proof of AI CapEx Recovery
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
Meta selling compute is not hard proof that semiconductor demand has peaked, but it exposes the weakest link in the AI capex boom: it is no longer enough to see cloud providers keep spending. The market is starting to ask whether compute, once brought online, can be sold at the right price, utilization rate, and cash flow. That is the turning point where the semiconductor chain shifts from an order narrative to return verification.
TL;DR
Start with cash flow. Citi puts Meta Compute into the free-cash-flow ledger because Meta’s AI capex is moving from an off-income-statement “future dream” into a daily cash drain that investors must underwrite. Citi estimates Meta’s 2026 and 2027 capex at $139B and $171B, with free cash flow falling to $14.6B and $8.5B, respectively. If part of its externally leased compute can be monetized at high prices, it will first improve the market’s patience with AI investment returns, rather than immediately rewriting the core business.
Morgan Stanley provides the clearest sensitivity analysis. 250MW is not an already-realized leasing scale, but the unit assumption Morgan Stanley uses to decompose EPS sensitivity: if Meta leases out 250MW of self-owned compute for one year at $40/Watt, it could add about $3 to 2028 EPS, or roughly 8% accretion. The value of this model is not in predicting exactly how much compute Meta will sell, but in showing the market that “AI compute assets” can be re-discounted by MW, price, and utilization.
JPMorgan’s reminder defines the risk boundary. JPMorgan acknowledges that external compute leasing can generate revenue and returns, but would rather see Meta’s own AI products, ads, Business Agents, subscriptions, glasses, and other applications absorb the capacity. The more Meta leases out, the more the market will ask two questions: is this active asset turnover, or insufficient demand from its own products; and is this high-return leasing, or loss mitigation after excess high capex?
Neocloud faces validation, not a simple negative shock. If Meta temporarily leases out self-owned compute, it will increase supply and compress some scarcity premium, but it also proves that enterprise AI compute demand remains strong enough that even hyperscalers are willing to break capacity into external products. The real pressure is on low-quality edge compute assets that lack power, customer lock-in, and depend on financing to survive. Platforms that can bundle power, GPUs, networking, customers, and contract duration will become more valuable.
The semiconductor chain will be re-audited. Previously, the market watched “how much more capex cloud providers added.” Now it needs to watch “how much revenue, gross profit, and free cash flow each new 1GW can generate.” GPUs, ASICs, optical modules, power, and data centers still benefit from upward capex revisions, but valuation is shifting from order visibility alone to utilization, price, contract length, and customer usage intensity after compute comes online. What overwhelms the euphoria is not Meta selling compute itself, but the market starting to require every $1 of AI capex to submit its homework.
Watch four hard indicators next. First, whether Meta formally confirms Meta Compute’s product form and pricing. Second, whether the actual externally leasable capacity is at the 10MW, 100MW, or GW level. Third, whether 2027/2028 capex guidance keeps moving higher because of cloud ambitions. Fourth, whether Meta’s own AI products can generate higher ad conversion, Business Agents revenue, and subscription revenue. Until these four numbers come out, the event looks more like a cash-flow option and should not be valued in advance as a second AWS.
I. Clarifying the Event: Meta Is Not Selling “Cloud,” but Scarce Compute That Can Be Turned Over
Meta selling compute can easily be misread as “Meta wants to replicate AWS.” That interpretation is too broad and too early. Based on Citi’s and Morgan Stanley’s breakdowns, the more accurate current framing is this: Meta may open parts of its AI infrastructure to external customers in two product forms. One is model access, similar to AWS Bedrock’s “call models through APIs” format. The other is raw compute, similar to Neocloud selling GPU capacity or usage rights to GPU clusters.
These two product types have completely different levels of difficulty. Model access requires model capability, a developer ecosystem, enterprise sales, billing systems, customer success, and security compliance. Meta has user traffic and open-source model mindshare, but it does not naturally have the enterprise cloud muscles of AWS, Azure, or Google Cloud. Raw compute leasing is much simpler: as long as capacity is available, networking and power are stable, and contract pricing is appropriate, short-term excess or temporarily unused self-owned compute can be converted into revenue.
Morgan Stanley therefore places “Neocloud-style leasing” on the higher-probability path, and a “full hyperscaler-style software cloud” on the higher-execution-risk path. This judgment matters. What is most verifiable for Meta today is not whether it can build a complete cloud platform, but whether it can turn AI compute that is already under construction, about to come online, and not yet fully absorbed internally in the short term into an asset with price, duration, and cash flow.
The value of Meta Compute lies here as well. It is not simply a “new business name,” but a way to put internal compute procurement, data-center construction, model access, and external leasing onto one operating ledger. As long as compute can be dynamically allocated among internal training, internal inference, and external leasing, AI capex no longer has to be justified only by long-term ad efficiency or a superintelligence story. It can also prove asset utilization through near-term cash recovery.
This is also why the market reaction is significant. Over the past year, investors have accepted AI infrastructure spending, but they have become increasingly unwilling to hear only that “products will come in the future.” If Meta can prove that part of its compute can be leased to external customers before its own AI applications mature, the capex narrative will shift from “burning money to buy the future” to “buy scarce assets first, then recover capital through both leasing and self-use.”
II. The Three Sell-Side Differences: Citi Looks at Cash Flow, Morgan Stanley at the EPS Bridge, JPMorgan at Internal Demand
Citi, Morgan Stanley, and JPMorgan do not view the same event in exactly the same way. Their common ground is that AI compute remains scarce and Meta has an opportunity to monetize part of its capacity. Their disagreement is whether the money should be treated as a new growth business, a short-term EPS bridge, or contrary evidence of insufficient product pull.
Citi’s logic looks most like cash-flow protection. Meta’s traditional core business remains strong, and ads, Reels, AI ad tools, and messaging monetization can continue contributing profit. But after a steep rise in capex, free cash flow will be compressed. Citi views Meta Compute as a new business unit that can “recognize revenue and free cash flow earlier.” The core point is not that Meta immediately adds a trillion-dollar cloud platform, but that compute leasing can reduce the cash-flow erosion from AI infrastructure buildout.
Morgan Stanley’s logic looks most like a valuation bridge. It does not treat Meta’s external compute leasing as the main reason for its investment rating, but as an EPS cushion while waiting for AI products to mature. Morgan Stanley is explicit that its bullish view on Meta is not based on Meta becoming a Neocloud, but on Meta generating more durable product and revenue growth on its own platforms. Compute leasing is a bridge, not the destination.
JPMorgan’s logic looks most like a checklist of contrary evidence. It acknowledges that 1GW of compute can generate considerable annual revenue, and that this helps AI infrastructure returns. But it would rather see Meta use the compute for its own AI products. This reminder cannot be ignored. If a social advertising giant sells large amounts of its most expensive compute to others, the market will ask: do its own AI ads, agents, glasses, subscriptions, and personal superintelligence roadmap really have enough throughput demand?
Taken together, these three framings are the full meaning of the event. It is neither bearish nor blindly bullish. It is the natural result of AI capex entering its second phase: in the first phase, the market rewarded whoever dared to build; in the second phase, it starts rewarding whoever can put the built assets to work; in the third phase, it will reward whoever can generate the highest return across self-use and external leasing.
III. How to Use Morgan Stanley’s 250MW Model: It Is a Sensitivity Ruler, Not an Event Fact
The most useful part of Morgan Stanley’s work is that it decomposes the event into three variables: 250MW, one year, and $40/Watt. The framing must be clear: 250MW is not a leasing scale Meta has confirmed, nor is it a fact of the event itself. It is the unit Morgan Stanley selected for EPS sensitivity analysis for investors.
According to Morgan Stanley’s estimates, if Meta leases out part of its self-owned compute, EPS would be highly sensitive to capacity and price. The key is not the single 250MW point, but the slope of price and capacity: the larger the capacity and the closer the price is to the high-end Neocloud range, the more external compute leasing looks like a profit bridge. If pricing falls or capacity is constrained, it looks more like a free-cash-flow cushion.
The real value of this table is not precise EPS prediction, but giving the market a ruler for “AI compute assetization.” In the past, the market looked at AI capex by using total amount, year-over-year growth, and supplier orders. Now there is an approach closer to operating assets: leasable capacity multiplied by price, less depreciation, energy, operations, maintenance, and related costs, with net income and free cash flow considered at the end.
JPMorgan’s assumption of about $20B in annual revenue from 1GW effectively corresponds to the more conservative $20/Watt range. Morgan Stanley’s 1GW at $40/Watt corresponds to about $40B in annualized revenue. The difference is large, but the direction is consistent: when GPU compute remains tight and customers are willing to pay a premium for near-term capacity, 1GW is not an abstract power unit, but a potential asset line capable of generating tens of billions of dollars in annualized revenue.
This will change how investors look at Meta’s capex. Estimates for Meta’s 2026 capex differ across institutions: Citi is at $139B, while Morgan Stanley is at $145B. For 2027, the numbers are higher: Citi at $171B, Morgan Stanley at $175B, and JPMorgan even sees $202B. The disagreement is not about direction; all point to continued upward revisions. The real debate is whether this spending will be recovered only through ads and AI products, or whether part of it can first be recovered through external compute leasing.
From an event-interpretation perspective, the 250MW figure should only be used as an anchor for “how much EPS sensitivity would arise if a standard block of capacity were leased.” Meta does not need to lease 1GW in the first step, nor does it need to formally announce an entry into the cloud market. What needs to be verified is whether it can put forward part of its self-owned capacity and let the market see the price, customers, duration, and gross margin. If those numbers hold up, the valuation discount on capex may begin to narrow.
IV. Why Meta Has Capacity to Sell: Not “Idle” Capacity, but a Mismatch Between Buildout Cadence and Product Cadence
Interpreting Meta’s external compute leasing as “idle compute” misses the point. AI infrastructure buildout is inherently batch-based. Data centers, power, networking, GPUs, liquid cooling, and software stacks cannot be scaled up or down precisely against weekly demand. When a 1GW-scale cluster comes online, internal product demand may still be ramping, while training and inference workloads are also cyclical. Short-term external leasing does not necessarily indicate insufficient demand. It may simply reflect a timing gap between asset commissioning and product absorption.
The Prometheus and Hyperion projects cited by Citi are the context for this issue. Prometheus is a 1GW-plus cluster scheduled to come online in 2026. Hyperion targets more than 5GW by 2030, with initial deployment in 2028. Meta is also advancing its in-house MTIA chip roadmap and building long-term procurement and capacity partnerships with ecosystem partners including Google Cloud, CoreWeave, Nvidia, and AMD. This is not a small-scale experiment, but a multi-year infrastructure plan spanning chips, data centers, and model products.
Morgan Stanley estimates that Meta will add roughly 2GW and 3.5GW of self-operated IT capacity in 2026 and 2027, respectively. It is also leasing around 2.5GW of third-party capacity through channels including CoreWeave, Nebius, Google Cloud, and Oracle. Morgan Stanley believes Meta is unlikely to sublease that third-party capacity to others, but this external capacity gives Meta greater flexibility, allowing it to make its own first-party capacity available for temporary external leasing.
The key here is “owned capacity.” If Meta is leasing capacity that it built, controls, and dispatches itself, it earns asset-turnover revenue. If Meta is merely subleasing third-party capacity, the commercial significance is much weaker and more likely to be constrained by contract terms. Morgan Stanley therefore treats first-party owned capacity as the core variable behind the external leasing opportunity.
This table explains why the event should be understood in layers. The first layer is the most realistic short-term compute leasing opportunity, addressing cash-flow pressure and CapEx concerns. The second layer is model access, which can improve gross margin but requires proving that the Muse model family and Meta ecosystem can attract developers. The third layer is a full cloud platform, where evidence is currently the thinnest and where the market is most likely to overinterpret too early.
V. For Neocloud, This Is Both Validation and a Pricing Stress Test
Meta entering compute leasing will naturally lead the market to think of CoreWeave, Nebius, Oracle, and the broader Neocloud category. The first reaction may be: “More supply means pressure on Neocloud.” That judgment is only half right.
In the short term, if Meta releases high-quality near-term capacity for lease, it will indeed create a pricing benchmark for Neocloud. Suppliers that have mainly captured premium pricing because of “near-term GPU scarcity,” but lack long-term customer lock-in, will be forced to answer a simple question: why should customers not lease capacity directly from Meta, Google, Oracle, or other hyperscalers?
In the medium term, Meta’s willingness to lease externally also proves that compute demand is strong enough to absorb new supply. Citi’s software and telecom teams both emphasize that AI/HPC demand still exceeds supply, and data center leasing has already begun focusing on 2028-2030 delivery. In other words, Meta’s move will reignite the supply-demand debate, but it does not mean the industry immediately enters oversupply.
The real Neocloud beneficiaries will be those with three attributes: first, near-term deliverable capacity; second, the ability to bind power, GPUs, networking, and customer contracts together; third, sufficient financing capacity to turn contracts into buildable, deployable, operable assets. Assets that rely only on slides claiming future power, GPUs, and customers will see their premium compressed by the external leasing option offered by a giant like Meta.
Behind the 138GW Data Center Expansion Plan: AI CapEx Keeps Being Revised Up, and How Cloud Providers, Bond Markets, ABS, and Power Infrastructure Can Absorb This Buildout Cycle
This event will also affect CoreWeave. Citi notes that Meta has roughly $35.2 billion of contracted capacity with CoreWeave. Meta buying from CoreWeave while potentially selling its own compute may look contradictory, but these are two sides of the same issue: AI compute demand is large enough that a single buildout path is insufficient. Meta both needs external capacity to supplement peaks and wants its owned capacity to generate returns during idle windows.
If Meta’s future external leasing prices are below Neocloud market prices, margins for marginal suppliers will be compressed. If Meta’s prices are above market, it indicates that high-quality, near-term deliverable compute with ecosystem credibility remains scarce, which would instead support Neocloud valuations. Price itself will become the industry thermometer.
VI. For Cloud Providers, This Is Not Simple Competition but a Stratification of the AI Cloud Business Model
What AWS, Azure, and Google Cloud should fear most is not Meta leasing out a few hundred MW of compute, but AI cloud customers starting to procure “full cloud platforms” and “pure compute capacity” separately. In the past, enterprise cloud migration focused on compute, storage, databases, security, developer tools, and ecosystem integration. AI training and inference introduce a new purchasing logic: customers first ask where GPUs are available, where they can go online fastest, and where costs are lowest, then consider cloud-platform stickiness.
If Meta only leases raw compute, the direct impact on the big three clouds is limited. It is more like putting high-end GPU capacity into the market to address shortages for some enterprises and model companies. Customers still need to manage data, model deployment, application development, security, and compliance within AWS, Azure, and Google Cloud.
If Meta moves further into model access, the competition becomes clearer. AWS has Bedrock, Google has Vertex AI, and Microsoft has deeply tied OpenAI to Azure. Only if Meta sells Muse Spark, the Llama ecosystem, or third-party models through Meta Compute would it touch the model platform and developer entry point. But Morgan Stanley’s caution is precisely here: the Muse models still need to prove themselves, and Meta also needs enterprise sales and software product capabilities.
The more likely structure is a three-layer AI cloud market. The bottom layer is power, data centers, GPUs, networking, and storage. The middle layer is training/inference compute orchestration and leasing. The top layer is models, tools, applications, and business processes. Meta is most likely to monetize the middle layer first, while the top layer is the hardest. The big three clouds are strongest in the top layer and enterprise systems. Neocloud is strongest in the middle layer and near-term capacity. Meta’s special position is that it has massive internal demand while also potentially selling short-term excess capacity in the middle layer.
This is also why interpreting the Meta event as an “escalation in the cloud war” is insufficient. It looks more like the emergence of an asset-turnover market in the AI infrastructure value chain. Whoever has capacity can sell capacity. Whoever has models can sell model access. Whoever has applications can turn compute into high-margin revenue. Meta’s advantage is that it holds all three cards at once; its weakness is that the latter two have not yet been fully proven.
VII. Impact on the AI Hardware Chain: Orders Remain Strong, but Valuation Starts Looking at “Post-Deployment Revenue”
For the AI hardware chain, Meta selling compute is not a signal that demand has peaked. Quite the opposite: if hyperscalers believe compute can be leased externally, they have more reason to lock in GPUs, ASICs, power, data centers, and networking resources in advance. Capacity no longer has only one use case: if internal products can absorb it, it goes to ads, agents, and inference; if not, it can be leased to external customers; if future model training needs it, it can be recalled or redispatched.
This will strengthen the “option value” of AI hardware demand. GPUs, HBM, networking, switch chips, optical modules, liquid cooling, power supplies, and data center engineering will continue to benefit from hyperscaler buildout. Meta’s MTIA roadmap shows that cloud providers will not only buy external GPUs, but will also develop in-house training and inference chips. Yet in-house chips will not make the external supply chain disappear. They will simply redistribute value among GPUs, ASICs, memory, networking, and system integration.
GPUs Will Not Lose, but XPUs Will Rewrite Profit Allocation: AI Compute Moves from a Chip War to a Compute-per-Watt War
The hardware chain must also accept stricter valuation validation. In the past, once cloud providers raised CapEx, the market could infer upward revisions to demand for GPUs, servers, optical modules, and power equipment. The next step now becomes: once these assets go online, do they have customers, utilization, premium pricing, long-term contracts, and sufficient gross margin? The valuation anchor of the buildout cycle is gradually moving from “order visibility” to “revenue GW” and “cash-flow GW.”
This is equally important for the data center and power chain. Citi notes that industry leasing has begun focusing on 2028-2030 delivery, indicating that near-term high-quality power and data center capacity remain tight. Continued CapEx revisions from buyers such as Meta, Google, Microsoft, and Amazon will keep demand strong for grid interconnection, front-of-the-meter and behind-the-meter power supply, liquid cooling, and interconnect resources. But if future external leasing prices fall, or if 1GW assets struggle to maintain high utilization, the market will turn around and compress valuations for low-quality buildout projects.
Follow the Power: AI Data Centers Move from GPU Shortage to a Revaluation of Grids, 800V, and Power Semiconductors
Therefore, the hardware chain should not treat the Meta event simply as “one more buyer” or “one more seller.” It marks AI infrastructure’s transition from a procurement race to an operations race. What upstream suppliers need to prove in the future is not only that they can deliver equipment, but that this equipment will enter high-utilization, high-price, high-cash-flow compute asset pools.
8. What Is Being Suppressed in the Semiconductor Euphoria Is Not Demand, but the Valuation Narrative
The “last straw” in the title should not be interpreted as AI semiconductor demand collapsing imminently. A more accurate reading is this: Meta selling compute makes the market, for the first time, pull hyperscaler AI capex back from “strategic investment” into the category of an “operating asset.” Once investors start asking whether each GW that comes online can be leased out, at what price, to which customers, under what contract duration, and at what gross margin, valuations across the semiconductor chain that rely only on orders and upward capex revisions will be capped.
Over the past two years, the AI hardware trade has followed a very smooth chain of logic: large models keep getting bigger; both training and inference require more GPUs; hyperscalers keep revising capex upward; the semiconductor supply chain keeps receiving orders; and share prices keep receiving higher multiples. This logic works very well when demand is strong, but it contains an implicit assumption: as long as cloud providers spend, capital markets will believe that this spending can ultimately turn into high-return revenue. The Meta event shakes precisely that assumption.
If Meta takes part of its self-owned compute and sells it externally, it means compute is both scarce and needs to be operated. Scarcity supports semiconductor demand; the need to operate the asset suppresses unconditional euphoria. The market will ask: you can buy more GPUs, more servers, and more optical modules, and you can sign longer data center contracts, but after this equipment comes online, will it be consumed by your own AI products, or will it need external leasing to recover cash? If the answer is unclear, larger orders may instead trigger more questions about returns.
This shifts semiconductor-chain valuations from “capex beta” to “asset-return beta.” In the past, the market liked to directly translate cloud-provider capex upgrades into supply-chain revenue upgrades. Now it needs to ask one more question: can the compute assets formed by this capex maintain high utilization and high pricing? If not, semiconductor suppliers’ near-term revenue may still be very strong, but valuation multiples will compress first, because investors will worry about downstream capex cuts in the next round.
The point of this table is not that the semiconductor chain is ending. Quite the opposite: the segments that can truly prove asset returns will become stronger. Companies that can secure long-term customers, deliver high-utilization clusters, and create bottlenecks in power and networking will still benefit from demand expansion. What gets suppressed is another type of asset: one whose valuation is built entirely on the assumption that “cloud providers will spend endlessly,” but that cannot prove high downstream returns after deployment.
The reason the Meta event is so striking is that it happened at the hottest moment of AI capex. The market had been willing to believe that every dollar invested by hyperscalers was aimed at future superintelligence and AI product revenue. But once the act of “selling compute” appears, capital markets gain one more counter-question: if a company’s own AI products are strong enough, why does it need to sell compute externally? This question may not be fair, because construction cadence and product absorption cadence can naturally be misaligned, but it is enough to change pricing.
So the biggest risk for the semiconductor chain is not short-term orders, but a slower narrative. Orders remain, deliveries remain, and capex may still continue to be revised upward; but share prices no longer reward only “who got the order.” They reward “whose orders correspond to higher-quality downstream cash flow.” This is the meaning of the last straw: it does not crush real demand, but it does crush the valuation inertia that ignored returns.
9. Which Segments Are Most Likely to Be Revalued: Not All Semiconductors Face the Same Risk
It would also be wrong to simplify this into “bad for semiconductors.” The AI semiconductor chain is too long, spanning GPUs, HBM, switch chips, optical modules, servers, liquid cooling, power supplies, advanced packaging, foundries, equipment, and data center engineering. Different segments face completely different verification pressure. Meta selling compute is more like a sieve, separating the segments that are “definitely beneficiaries of construction” from those that “need to prove downstream cash recovery.”
The segments least deserving of indiscriminate selling are those that are genuinely scarce, have long delivery cycles, and are tied to high-utilization clusters. High-end GPUs, HBM, high-speed interconnects, advanced packaging, critical power supplies, and liquid-cooling capabilities still benefit from AI cluster construction in the near term. As long as training and inference demand continues to expand, hyperscalers will not stop procurement just because Meta is exploring external leasing. If external compute leasing can improve asset returns, cloud providers may even have more reason to lock in these scarce resources in advance.
The segments that require more revaluation are those that “only sell construction and do not care about usage.” Examples include server systems, some general-purpose equipment, ordinary data center capacity, financing-driven Neocloud assets, and GPU leasing platforms without locked-in customers. They benefited from the construction boom in the past, but the market will now ask: after these assets come online, can they secure high-priced contracts? Are the contract terms long enough? Is customer credit strong enough? Will depreciation speed and financing costs consume profits?
The assets most vulnerable to compression are those whose valuations already imply “AI capex will always be revised upward.” If a company’s share price assumes higher capex, higher orders, and higher prices every year, but does not explain how downstream customers can earn back that money, then the Meta event becomes a reason for a higher valuation discount rate. Not because it directly takes away orders, but because it reminds the market that AI hardware does not end at delivery; it ultimately has to land in asset returns.
The core of this table is distinguishing between “demand is gone” and “the valuation anchor has changed.” If demand is gone, every segment sells off together. If the valuation anchor changes, the market begins to stratify segments. Companies that can prove they connect to high-quality compute assets will still be bought; companies that rely only on AI buzzwords, order announcements, and short-term capacity expansion stories will be sold first.
For the GPU chain, Meta selling compute is not a direct negative. The real issue is that if cloud providers start operating compute as an asset, they will compare the unit economics of GPUs, ASICs, and in-house chips more precisely. Whichever chip can generate higher revenue under given power, networking, utilization, and software-stack conditions will receive more budget. GPUs remain the strongest general-purpose compute foundation, but XPUs and ASICs will continue to reshape profit distribution.
For the optical-module and networking chain, the key issue is not whether Meta sells compute, but whether utilization and east-west traffic in large clusters can keep growing. If external customers lease complete training clusters, network demand will be stronger. If external leasing is only fragmented inference capacity, network intensity may be lower than in training clusters. The market will begin to split “compute capacity” into training, inference, model services, and ordinary GPU leasing, rather than pricing all interconnect demand at the same multiple.
For power and data centers, the Meta event looks more like long-term validation. If compute can be leased out, then power and data centers are not just cost items, but underlying assets capable of generating cash flow. The issue is that only power and data centers that are near-end, stable, quickly deployable, and backed by customer contracts are valuable. Remote projects that lack network access, customers, or cheap financing will be re-discounted within the same AI construction cycle.
For equipment and foundries, near-term orders may not be hurt, but the cycle debate will arrive earlier. As long as hyperscalers are still expanding, advanced processes, packaging, testing, and key equipment will remain in demand. But if the market begins to worry about returns on downstream compute assets, investors will start asking in advance whether the next round of orders can continue. The biggest risk for equipment stocks and the foundry chain is not weak orders this quarter, but a slower pace of new projects after capital spending shifts from rapid expansion to return assessment.
Therefore, this piece is not arguing that the semiconductor euphoria should be killed outright. The more reasonable conclusion is that the AI hardware chain is entering a phase of differentiation. The first category of companies will continue to benefit from scarce resources and high-utilization assets. The second category will still see revenue growth, but valuations will have to give up part of the “infinite capex” premium. The third category, if supported only by financing, concepts, and order expectations, will be suppressed early by events such as a hyperscaler leasing out compute.
10. Three Scenarios for This Event: The Same Action Can Be Interpreted by the Market as Three Completely Different Stories
The most difficult part of Meta selling compute is that the same action can correspond to three completely different interpretations. It can be high-quality asset turnover, the germination of a new cloud business, or passive loss mitigation after insufficient absorption by internal AI products. In the short term, the market will first trade on the most optimistic story, because “selling idle or temporarily surplus compute” sounds like it can address both capex pressure and free-cash-flow pressure at the same time. But medium-term valuations will return to evidence.
The first scenario is high-quality asset turnover. Meta still believes its own AI products will consume most of the compute, but infrastructure is coming online before product revenue is realized, so it sells temporarily available capacity to external customers. In this case, the external leasing scale should be limited, pricing should be high, contracts should preserve flexibility, and Meta should not continue to materially raise long-term capex for external customers. This is the most positive scenario, because it turns AI capex from a pure cost into a revolving asset.
The second scenario is new-business incubation. Meta does not merely sell raw compute; it also builds model access, developer tools, enterprise customer services, and billing systems, creating a Meta Compute platform. This story has a higher ceiling, but also higher execution risk. Meta needs to prove that the Muse model series, the Llama ecosystem, enterprise sales teams, data security capabilities, and customer-success systems can all function. Otherwise, it can easily end up in the awkward position of “having compute but no software.”
The third scenario is excess-capacity loss mitigation. If external leasing scale grows larger, pricing is weaker than expected, contracts are very long, and Meta’s own AI product revenue fails to keep up, then the market will interpret this as insufficient internal demand. This is the least friendly scenario for the semiconductor chain, because it implies cloud providers built too quickly in the earlier phase and may shift from continuing to add orders toward digesting inventory. Orders will not disappear immediately, but valuations will reflect the next round of capex slowdown in advance.
The difference among these three scenarios is not whether Meta sells compute, but why it sells compute. Active turnover and passive loss mitigation both look like “external leasing,” but they are completely different for valuation. Active turnover temporarily monetizes scarce assets; passive loss mitigation admits that internal demand is insufficient. Active turnover increases tolerance for capex; passive loss mitigation reduces tolerance for capex.
This is also why the title can say “suppresses the semiconductor euphoria,” but the body cannot be written as “semiconductor demand collapses.” What is truly suppressed is unconditional optimism. In the past, the market could simply ask, “Can Nvidia ship more GPUs?“, “Will cloud providers keep buying servers?”, and “Will optical modules keep moving to higher speeds?” Now it also has to ask, “Can customers make money after deployment?”, “What is the price of compute leased out by cloud providers?”, and “Can AI product revenue keep up with depreciation?” This turns the trade from a single line into a multivariable equation.
If Meta later discloses high external-leasing prices, strong customer quality, flexible contract terms, and continued scaling in ad AI and Business Agents revenue, the semiconductor chain will not be crushed. Instead, it will gain more stable proof of downstream returns. Conversely, if external-leasing prices are low, scale is large, contracts are long, and there is still no revenue evidence from its own AI products, the market will view it as a signal that AI infrastructure has been built too quickly, and high valuations across the semiconductor chain will be repriced.
XI. Why This Is Not Yet a Demand Collapse: Four Counterpoints Cannot Be Ignored
Even though the headline used “the last straw,” four counterpoints cannot be ignored. First, compute remains in short supply. The common premise behind Citi and Morgan Stanley is that AI/HPC demand still exceeds supply, and near-term deliverable capacity remains scarce. If the industry were already oversupplied, Meta would not frame external compute leasing as a cash-flow opportunity, and customers would not be willing to discuss capacity at high prices.
Second, hyperscaler buildout cycles are not linear. For a large data center or GW-scale cluster, from planning, power, civil construction, GPU delivery, network debugging, and software-stack launch, there is naturally a timing gap between capacity arriving first and products arriving later. Equating temporary external leasing directly with “insufficient internal AI demand” underestimates the batch nature of infrastructure construction. Cloud providers cannot precisely buy power, GPUs, and optical modules every week according to model demand.
Third, external compute leasing could increase, rather than reduce, procurement appetite. If cloud vendors discover that part of their capacity can generate cash flow before internal use, their tolerance for locking in GPUs, power, and data-center space ahead of time will be higher. In the past, early construction meant cash flow was consumed; now, early construction may add another recovery path. This logic actually supports long-term AI infrastructure investment, but requires more disciplined investment.
Fourth, AI demand is spreading from training to inference and applications. What Meta truly needs to validate over the long term is advertising tools, Business Agents, messaging monetization, glasses, and personal AI. If these applications continue to grow, training clusters, inference clusters, low-latency networks, and edge/cloud collaboration will continue to consume compute. External leasing is only temporary asset management; it does not mean end applications have no demand.
These four counterpoints show that the Meta event is not a mechanically tradable negative. It is more like a watershed: the market is starting to distinguish between “AI CapEx is still growing” and “AI CapEx deserves a high multiple.” The former is a revenue question; the latter is a valuation question. The semiconductor chain may still see revenue upgrades, but valuation multiples may not continue to expand unconditionally.
The easiest mistake here is to conflate revenue and valuation. Supply-chain companies may still receive higher orders in the short term, and performance over the next few quarters may remain strong. But if downstream cloud providers begin to be asked to prove compute returns, the market will first become more cautious about the supply chain’s forward multiples. This is why share prices sometimes move before fundamentals deteriorate. It is not that orders suddenly disappear, but that discount rates and terminal margins are being repriced.
The Meta event pushed the market one step from Phase 1 toward Phase 2. In Phase 1, investors did not care much about how downstream players made money; it was enough to know that demand was large enough, supply was tight enough, and pricing was strong enough. In Phase 2, investors begin to require every link in the chain to answer: who pays, how much they pay, how long they pay, and at what margin. This is not the end of the semiconductor story; it is AI hardware moving from thematic investing into operational validation.
Therefore, the real trading conclusion should be written separately. For segments with scarce supply, long customer relationships, and strong delivery capability, Meta selling compute is not the endpoint; it may only be the beginning of a new round of asset pricing. For segments where valuations have already pulled forward long-term CapEx upgrades but lack proof of downstream returns, the Meta event will become a reason to compress multiples. This distinction is more important than simply calling it bullish or bearish.
XII. Translating the Event into an Investment Framework: Going Forward, Watch Four Operating Variables, Not Just CapEx
This event ultimately needs to be translated into an investment framework; it cannot stop at the headline shock. Going forward, when looking at the AI hardware chain, the first layer is still CapEx, but the second layer must be operating variables. CapEx tells you the scale of construction; operating variables tell you the quality of construction. After Meta sells compute, the market will become increasingly unsatisfied with “cloud providers spent more money again” and will instead demand to see pricing, utilization, contract duration, and customer quality.
The first variable is price. Price is the thermometer for all AI compute assets. High prices indicate that near-term capacity is scarce and customers are willing to pay for delivery certainty; low prices indicate that supply is starting to catch up with demand, or that compute quality, location, network conditions, and service capability are not good enough. Morgan Stanley’s $40/Watt and JPMorgan’s implied $20/Watt are essentially drawing two valuation ranges for the market: the high-end range supports the EPS bridge, while the low-end range is more about cash recovery.
The second variable is utilization. AI clusters are not bought to sit on the balance sheet; they must be used for training, inference, model services, or external customers. The higher the utilization, the easier it is for revenue to cover depreciation pressure; the lower the utilization, the more CapEx looks like demand pulled forward from the future. For the semiconductor chain, utilization is more important than shipments alone, because it determines whether customers will continue to place additional orders in the next cycle.
The third variable is contract duration. Short-term contracts and long-term contracts mean different things. Short-term contracts show that Meta preserves future flexibility for internal use, and also that it treats external leasing as temporary asset turnover. Long-term contracts show strong external customer lock-in, but may also squeeze future capacity for Meta’s own AI products. For investors, the best combination is high pricing, moderate duration, renewability, and no constraint on Meta reclaiming capacity for internal use.
The fourth variable is customer quality. Who rents the compute is more important than how much is rented. If customers are large model companies, enterprise AI platforms, or cloud service providers with cash flow, contract quality is higher. If customers are mainly financing-driven startups, even high prices need to be discounted, because ultimate collections and renewals are unstable. The AI hardware chain will increasingly resemble data-center and infrastructure investment, with customer credit entering valuation models.
This framework also explains why the semiconductor chain will enter a period of dispersion. Previously, as long as cloud providers said they would build more, all upstream segments could rise together. Going forward, the market will ask how each upstream segment relates to these four operating variables. High-end GPUs, HBM, and high-speed interconnects can continue to command premiums if they are tied to high-utilization clusters. Ordinary servers, low-differentiation components, and financing-driven capacity will face multiple compression if high-quality customers are not visible.
The same applies to cloud providers. If Meta can prove high pricing, high utilization, strong customer quality, and flexible contracts, the market will see it as an improvement in “AI infrastructure operating capability.” If it can only prove that it has a lot of compute to sell, but at low prices, to weak customers, and under long contracts, the market will see it as “remediation after building too quickly.” These two interpretations have completely different implications for the stock price and supply chain.
Most importantly, investors will split AI CapEx into two layers going forward. The first is the build layer, answering whether there are enough chips, data centers, power, and networks. The second is the return layer, answering how much revenue and cash flow these assets generate after going online. The semiconductor rally in the past was mainly in the first layer; the Meta event has pushed the second layer to the foreground. The first layer remains important, but it can no longer determine valuation on its own.
Therefore, any future CapEx upgrade by a cloud provider must be evaluated alongside whether it discloses or implies asset returns. If CapEx is upgraded without a disclosed revenue path, the market will become more selective. If CapEx is upgraded while verifiable utilization, pricing, and customer contracts are provided, the semiconductor chain may receive healthier support. This is the real significance of Meta selling compute: it moves AI hardware from the stage of “the more you build, the better” to “you must build a lot and also use it well.”
XIII. Meta’s Own Long-Term Value Still Depends on Proprietary AI Products
The short-term positive comes from cash flow and the EPS bridge; long-term valuation still comes back to Meta’s own AI products. Morgan Stanley put it directly: the bullish case for Meta is not that it becomes a Neocloud, but that it launches new products on its own platforms that can increase engagement, revenue, and multi-year growth.
This main thread includes several directions. First is advertising efficiency: AI recommendations, creative generation, ad automation, and measurement improvements continue to raise monetization efficiency for Reels, Instagram, Facebook, and WhatsApp. Second is Business Agents and messaging monetization, moving enterprise customer service, sales, and conversion into the private domains of Messenger, WhatsApp, and Instagram. Third is subscriptions and AI tools, turning user scale into non-advertising revenue. Fourth is glasses and personal AI, connecting device entry points with social scenarios.
If these products can absorb Meta’s incremental compute, external compute leasing is only temporary asset turnover, and valuation will be healthier. The market will believe that Meta first uses leasing to cover construction pressure, then reclaims capacity once its own products mature, forming a path of “lease first, use internally later.”
If these products fail to generate large-scale revenue for a long time, external compute leasing will be reinterpreted. Investors will worry that Meta originally built capacity for superintelligence and proprietary AI products, but ultimately had to sell compute to others. At that point, Meta Compute will no longer be a high-quality option; it will become “remediation after excess capital expenditure.”
The easiest mistake in trading the event is to look only at the first path. Meta’s strong stock-price reaction to the news shows that the market is willing to price the cash-flow option. But what truly determines sustainability is that external leasing scale cannot be too large, pricing cannot be too low, CapEx cannot lose control, and proprietary AI products cannot remain at the concept stage. If any one of these becomes imbalanced, the market will switch from “cash-flow option” back to “overbuild risk.”
XIV. Why This Changes How the Market Debates AI CapEx
In the past, market discussions around AI CapEx often centered on two questions: who is spending the most, and who is getting the supply-chain orders. After the Meta event, the debate will look more like real estate, shipping, or data-center REITs: where are the assets, when do they come online, what is the occupancy rate, what is the rent, how long are the contracts, what is the customer credit quality, and how high are depreciation and financing costs?
This does not mean AI compute will become a fully traditional asset. GPUs depreciate faster, technology iterations are more aggressive, improvements in model efficiency will compress the unit value of compute, and customer demand may shift from training to inference, or from GPUs to ASICs. But as long as high-quality near-term compute remains scarce, the market will value it through the lens of asset turnover.
This shift will affect every AI infrastructure company. Cloud vendors need to prove CapEx can turn into revenue. Neoclouds need to prove high-priced contracts can cover financing costs and equipment depreciation. Data centers need to prove power and site locations are sufficiently scarce. Hardware suppliers need to prove orders are not one-off inventory replenishment, but long-term demand for capacity coming online. Model companies need to prove rented compute can generate sufficiently high product revenue.
The AI Trade Has Moved Ahead of Macro: Recalibrating Compute CapEx, Earnings Expectations, and Market Pricing
The Meta event brought this question to the forefront. A company with an ecosystem of roughly 4 billion users, advertising cash flow, AI product ambitions, and hyperscale infrastructure plans still needs to explain to the market how its compute investment will be recovered. If it chooses to rent out part of its capacity, that means capital markets have already begun requiring AI infrastructure to move from “strategic investment” toward “operating asset.”
This is also why the event is not simply a Meta story. It will affect how the market discounts the entire AI CapEx chain. Companies focused only on construction will be asked about revenue. Companies focused only on revenue will be asked about gross margin. Companies focused only on gross margin will be asked about depreciation and the supply cycle. Companies focused only on the supply cycle will be asked whether end AI products have real demand. The second stage of the AI trade places more emphasis on cash recovery than the first stage did.
XV. Follow-Up Checklist: Four Sets of Numbers Will Define the Event
This event does not need to be validated by slogans. It only requires tracking four sets of numbers.
The first set is product form. Whether Meta formally confirms Meta Compute, whether it offers both model access and raw compute rental, and whether it discloses the commercialization model for Muse Spark or other models. If it only rents out raw compute, this is asset turnover. Only if model access is also launched can it enter the discussion as a platform business.
The second set is capacity and pricing. 250MW is only the unit used in Morgan Stanley’s model. The key is whether actual externally rented capacity is tens of MW, hundreds of MW, or GW-scale. Pricing needs to be assessed by dollars per watt, GPU-hour pricing, contract duration, and whether power, networking, storage, operations, and model services are included. The closer pricing is to $40/Watt, the clearer the EPS bridge; the closer it is to $20/Watt, the more the significance lies in cash recovery and utilization optimization.
The third set is CapEx guidance. Morgan Stanley’s model assumes Meta’s 2027/2028 CapEx reaches $175 billion/$205 billion, and that this model is primarily used for Meta’s own products rather than a full cloud business. If Meta continues to raise long-term CapEx for an external cloud business, the market will raise the discount rate. External compute rental was originally meant to buffer cash flow; if it instead triggers even more construction, the positive effect will be diluted.
The fourth set is revenue from Meta’s own AI products. Ad efficiency, Business Agents, messaging monetization, subscriptions, glasses, and personal AI products need to provide evidence across engagement, payment, conversion, and revenue. As long as Meta’s own applications grow strongly enough, external compute rental is temporary cash-flow management. If its own applications do not generate clear revenue, external compute rental will be viewed as insufficient demand.
This checklist is more important than the short-term share-price reaction. The first layer of value in Meta selling compute is that the market has finally begun pricing AI infrastructure using MW, GW, dollars/Watt, occupancy rates, and incremental EPS. The second layer is that it forces all cloud vendors to explain the revenue recovery path for their CapEx. The third layer is that it helps investors distinguish “high-quality asset turnover” from “loss mitigation for excess capacity.”
This checklist also provides a more practical order of judgment. First look at product form, then capacity and pricing, then CapEx discipline, and finally revenue from Meta’s own AI products. Product form determines whether Meta is simply turning over raw compute or trying to build a cloud platform. Capacity and pricing determine whether this can translate into EPS. CapEx discipline determines whether external rental instead triggers more construction. Revenue from Meta’s own AI products determines whether the story ultimately has to rely on selling compute. All four variables must be assessed together; looking at any one in isolation can easily lead to misjudgment.
If one only looks at product form, Meta Compute sounds like a new cloud business, making it easy to assign too high a valuation. If one only looks at Morgan Stanley’s EPS sensitivity, it is easy to mistake the 250MW modeling unit for a confirmed scale. If one only looks at upward CapEx revisions, it is easy to continue treating the semiconductor chain as an unconditional beneficiary. If one only looks at JPMorgan’s cautious reminder, normal asset turnover may be misread as demand collapse. The real judgment should be: can Meta sell temporarily available compute at a good price without sacrificing its own AI products, and without losing CapEx discipline?
For the semiconductor chain, this sequence also helps avoid emotional trading. When seeing Meta sell compute, the first question should not be “is this negative for GPUs?” It should be “what type of capacity is being sold, what is the price, who is the customer, how long is the term, and will it affect the next procurement cycle?” If the answers point to high pricing, high customer quality, and high utilization, the hardware chain still has support. If the answers point to low pricing, weak customers, and large-scale passive external rental, that is when the semiconductor rally is truly being capped.
This is also where the question mark in the title of this report lies. It is not asserting that Meta selling compute has already crushed semiconductors. Rather, it signals that the market finally has an event sample with which to challenge the semiconductor boom: when one of the largest buyers starts discussing selling compute outward, every upstream segment must explain what kind of downstream return its orders ultimately correspond to. Segments that can answer this question will continue to retain capital. Segments that cannot answer it will see valuation discounts first, even if near-term orders are still there.
In other words, the most important thing for the semiconductor chain from here is not to keep proving that “demand exists,” but to prove that “demand quality is good enough.” AI orders from high-utilization training clusters, long-term inference workloads, and stable enterprise customers should be worth more than orders driven by one-off rush buying, financing-led expansion, or low-priced external rental used to absorb capacity. The Meta event magnifies this distinction: the market will continue buying scarce supply, but it will no longer be willing to pay the same valuation multiple for every AI order.
This distinction will directly affect stock selection and industry comparisons. In the future, when companies say “AI server orders are growing,” the market will care more about whether the customer is a hyperscale cloud vendor, whether the order is tied to compute already coming online, whether delivery enters a high-utilization cluster, and whether downstream contracts are supported by cash flow. Companies that can answer these questions clearly are the ones truly able to pass through AI CapEx scrutiny.
Therefore, this event is more like adding a revenue-quality threshold to AI semiconductor valuation, rather than putting an end to demand itself.
Whoever can connect orders, customers, utilization, and cash flow can still remain in the AI main line. Whoever can only talk about incremental CapEx will be asked by the market to cool down first.
That is the real dividing line.
XVI. Conclusion: Meta Sells Compute; What the Market Is Buying Is Proof of AI CapEx Recovery
The most important aspect of Meta selling compute is not that Meta has added a cloud business, but that AI CapEx is beginning to be required to provide proof of recovery. Whether Morgan Stanley’s 250MW sensitivity analysis can translate into real capacity and real pricing, whether 1GW can contribute $20 billion to $40 billion in annual revenue, and whether Meta Compute can dispatch capacity between internal use and external rental: these questions will gradually replace the crude narrative of “who is spending the most.”
In the short term, this event will improve the narrative around Meta’s AI investment returns. Citi’s $850 price target, Morgan Stanley’s $775 price target, and JPMorgan’s cautious reminder are essentially all centered on the same line: Meta’s core advertising business remains strong, but AI CapEx is too large, and the market needs to see a recovery path. External compute rental provides an answer that is calculable, trackable, and falsifiable.
It will also reshape the entire AI infrastructure chain. Neoclouds will be repriced, data centers and power assets will be reordered, GPU and ASIC demand will shift from “whether cloud vendors buy” to “whether there is revenue after capacity comes online,” and cloud vendors will move from a comparison of “who builds more” to “who uses it better.”
The more prudent judgment is this: Meta Compute is currently a cash-flow option, not a second AWS. It can buy Meta time and give the market a valuation yardstick. But its long-term value will still depend on Meta’s own AI products absorbing compute and lifting advertising and new-business revenue. Going forward, tracking the four sets of numbers around capacity, pricing, CapEx, and proprietary product revenue will determine whether this event is the start of AI CapEx recovery, or another temporary remedy after a new round of overbuilding.