
Kimi K3 Deep Dive: 2.8 Trillion Parameters, Coding Agents, and an Inflection Point in Chinese Models’ Pricing Power
目录
TL;DR
What K3 Really Changes Is the Basis of Competition
After “Daring to Raise Prices,” K3 Still Faces Three Tests
Control of the Coding-Agent Entry Point Matters More Than Parameter Count
The Text Price War and High-Margin Video Are Becoming Two Different Businesses
Investment Implications: First Identify Who Can Convert Capability Into Revenue, Then Who Supplies the Compute
Falsification Checklist: What Would Disprove the Pricing-Power Thesis?
The Only Six Metrics to Watch Next
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
Kimi K3 is shifting China’s large-model competition from “who is cheaper” to “who can charge more for high-value tasks,” but pricing power still needs to be validated by profitability and retention.
TL;DR
The most important change with Kimi K3 is not merely its 2.8 trillion parameters, but the simultaneous increase in capability and pricing. This open-weight model has reached the global frontier in coding and certain agentic tasks, while its blended API price has risen to $2.30 per million tokens—well above Qwen 3.7 Max, GLM 5.2, MiniMax M3, and DeepSeek V4 Pro. For the first time, Chinese models are sending a clear signal that premium capabilities can command premium prices.
For now, the higher price is only a signal of pricing power, not direct evidence of margin improvement. Kimi K3 costs approximately $0.90 to complete the Artificial Analysis benchmark tasks, roughly three times Kimi K2.6’s $0.30. Over the same period, its blended API price increased approximately 3.3 times, from about $0.70 to $2.30. Pricing has broadly covered the increase in task costs, but there is no evidence that unit gross margin has expanded significantly.
Model companies’ core assets are expanding from benchmark scores to “task entry points plus real-world data.” Coding platforms such as Zhipu’s ZCode, Tencent’s Workbuddy, and Alibaba’s Qoder are competing for developers’ model calls, corrections, and feedback from real projects. Only companies that embed their models into workflows can continuously acquire high-quality data, improve retention, and convert a temporary capability lead into a commercial advantage.
Model economics are stratifying. Low-end text and agentic API pricing may remain compressed at $0.10–0.20 per million tokens, as post-funding cash reserves continue to subsidize price competition. Video generation enjoys stronger demand, constrained compute supply, and more tangible deliverables, supporting relatively healthy pricing and gross margins. Investors can no longer apply the same valuation framework to every model company.
The most investable indicators are three sets of verifiable numbers. At the model layer, track usage of premium versions, customer retention, and gross profit per task; at the infrastructure layer, track AI capital expenditure and cabinet deployment at Alibaba, GDS, VNET, Kingsoft Cloud, and others; at the application layer, assess whether high-value tasks such as coding and video can generate recurring payments. If only benchmark scores and parameter counts rise without an improvement in revenue quality, purported pricing power will amount to little more than more expensive inference.
What K3 Really Changes Is the Basis of Competition
Over the past two years, the defining advantage of Chinese large models has been that they are “good enough—and cheap enough.” DeepSeek brought cost efficiency to the forefront, while models such as GLM continued to narrow the intelligence gap. Kimi K3 takes the question one step further: as coding and agentic capabilities approach the global frontier, can Chinese models stop relying on low prices to gain scale and instead charge customers a capability premium?
Kimi K3 was released on July 17, 2026, with 2.8 trillion parameters and open weights. Citing Coding Arena and Artificial Analysis data, Goldman Sachs believes its coding and certain agentic capabilities have reached the global frontier. Based on chart readings, Kimi K3 has an Artificial Analysis Intelligence Index score of approximately 57, ahead of GLM 5.2 at about 51, Qwen 3.7 Max at about 46, and MiniMax M3 and DeepSeek V4 Pro at about 44. Rankings change quickly, but they at least demonstrate that K3’s price increase is supported by its capabilities.
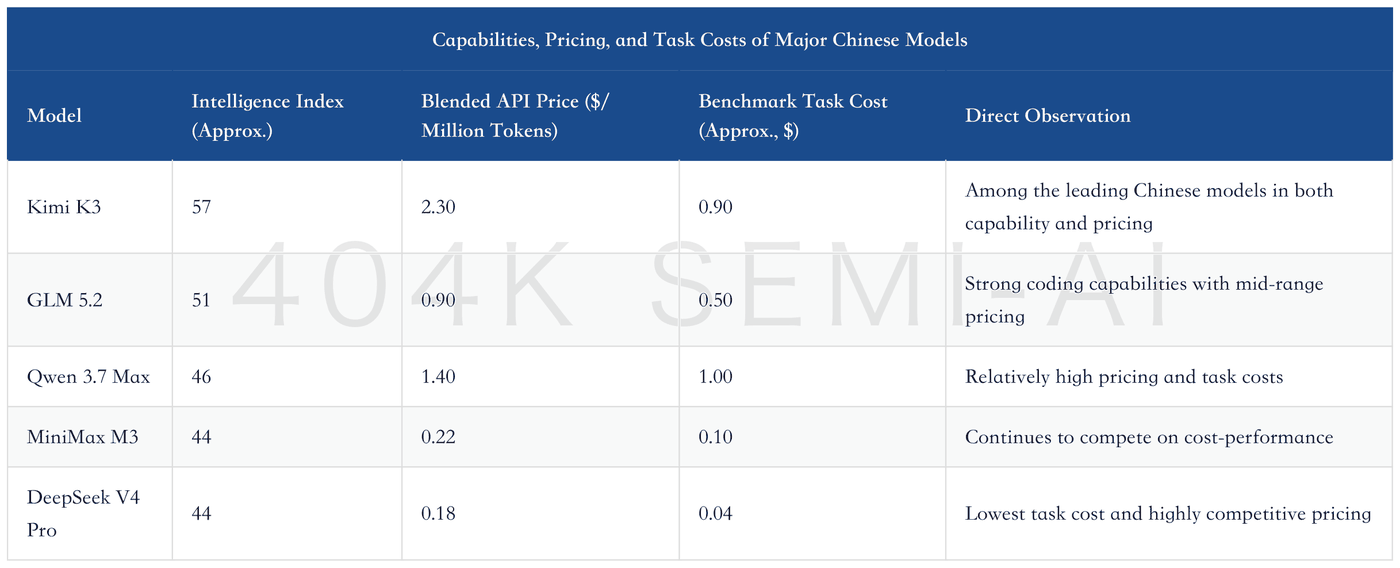
Pricing differences are no longer a matter of a few percentage points, but an order of magnitude. Kimi K3’s blended API price is approximately 64% higher than Qwen 3.7 Max’s, 2.6 times GLM 5.2’s, 10.5 times MiniMax M3’s, and 12.8 times DeepSeek V4 Pro’s. This suggests that China’s model market is beginning to stratify clearly: the cheapest models handle high-volume, low-value calls, while premium models attempt to charge a premium for coding, complex reasoning, and agentic tasks.
