
GPUs Will Not Lose, but XPUs Will Rewrite Profit Allocation: AI Compute Moves from a Chip War to a Performance-per-Watt War
目录
TL;DR
I. The Market Is No Longer Betting on a Binary Choice Between GPUs and XPUs
II. The Total AI Semiconductor Pie Is Still Expanding; Architectural Divergence Cannot Be Separated from Incremental Demand
III. The GPU Moat Is in the System, Not Just the Chip
IV. The Essence of XPU Is Cloud Providers Internalizing the Cost Curve
V. TSMC Puts GPU and XPU Into the Same Bottleneck
VI. Advanced Packaging and Testing Are the Hidden Capacity of AI Chips
VII. Google’s TPU Model Shows Cloud Providers Are Becoming Chip Companies
VIII. The Opportunity for China’s AI Chips Lies in Usable Cost, Not Slogan-Driven Catch-Up
IX. Profit Pools Will Spread from Chip Brands to Bottleneck Assets
10. The Shared Signal from TSMC and Google: Still a Buildout Phase Before 2028
11. The Real Debate: Can Compute Demand Absorb This CapEx Cycle?
12. Company and Segment Ranking: Buy the Gates First, Then the Elasticity
13. Risk List: Where This Chain Is Most Likely to Break
14. The Indicators to Watch Most Closely Over the Next Four Quarters
15. Three Worldviews: This Is a Trade About Return Verification
16. Falsification Checklist: When to Reduce GPU/XPU Chain Weightings
17. Conclusion: GPUs Win on Generality, XPUs Win on Cost Curve, and Bottleneck Assets Win on Shared Constraints
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
The main thread in AI compute is shifting from “who has the strongest single chip” to “who can sell more tokens with the least power, the most stable supply, and the lowest depreciation.” GPUs remain the core asset for training and general-purpose inference, while XPUs are rewriting semiconductor profit allocation in cloud providers’ internal use, vertical workloads, and the China market.
TL;DR
GPUs remain core. AI training, frontier-model iteration, software ecosystems, and general-purpose inference still revolve around GPUs. Nvidia’s system-level advantage is difficult to replace with any single-point chip in the near term. But compute buyers are no longer buying only peak FLOPS; they are buying deployable throughput per watt, software-stack stability, supply certainty, and controllable depreciation.
XPUs change the split. The value of Google TPU, Amazon Trainium, Microsoft Maia, Meta MTIA, and China’s domestic AI accelerators lies in moving highly repetitive, large-scale, predictable internal workloads off general-purpose GPUs, allowing cloud providers to bind chip gross margin, cloud-service gross margin, and model capability together.
TSMC is the hard gate. Advanced nodes, CoWoS, SoIC, and EUV capacity jointly determine the real shipment ceiling for both GPUs and XPUs. When Morgan Stanley raises its TSMC target price to NT$2,888 and assumes nearly 40% revenue growth in 2026, the market is pricing the manufacturing bottleneck behind AI chip orders.
Google is the key variable. The Google research note raises 2028 compute capacity, external TPU sales, and cloud revenue at the same time. The core implication is that TPU is no longer merely an internal cost-reduction tool; it could become a product through which a cloud provider exports its compute architecture. If 1P TPU sales can support roughly $20bn/GW in revenue, the profit structure of AI cloud will need to be remodeled.
China’s path is more about TCO. In the near term, China’s AI chips are focused on restricted supply, lower chip ASPs, domestic ecosystem adaptation, and local inference scenarios, pushing total cost of ownership into an acceptable range. As long as per-token cost approaches parity, domestic GPU/XPU products can find room for commercial deployment.
The opportunity lies in bottleneck ranking. The value-chain ranking should expand from “chip brands” to “advanced nodes, advanced packaging, HBM, testing, AI servers, networking, power, and scheduling software.” The closer an asset is to the delivery gate, and the more it can raise prices as capacity tightens, the more easily it can convert AI CapEx into sustainable profit.
I. The Market Is No Longer Betting on a Binary Choice Between GPUs and XPUs
The GPU-versus-XPU debate is easily framed as a replacement war: whether GPUs will be replaced by ASICs or TPUs, whether Nvidia will be squeezed by cloud providers’ in-house chips, and whether China’s AI chips can bypass the CUDA ecosystem. That framing travels well, but it is not well suited to investment judgment. AI compute is moving from single-chip competition to system competition, from “whether there are cards” to “whether cards, power, packaging, networking, software, and customer workloads can be turned into sellable tokens together.”
In this framework, GPUs will not simply lose. Training frontier models, running complex multi-tenant inference, and supporting large numbers of new models and frameworks still require a mature GPU ecosystem. Nvidia’s advantage is not just the GPU die. It is a system made up of CUDA, NVLink/NVSwitch, InfiniBand/Ethernet, full racks, power and cooling, software libraries, and customer switching costs. Looking only at single-chip performance easily underestimates this system stickiness.
XPUs will not remain supporting actors either. Cloud providers are investing hundreds of billions of dollars in annual capital expenditure and ultimately must deal with depreciation, utilization, gross margin, and customer lock-in. As long as certain workloads are stable enough, large enough, and model architectures controllable enough, cloud providers have an incentive to migrate those workloads from general-purpose GPUs to in-house or semi-custom chips. The commercial meaning of XPUs is to redistribute part of the GPU’s high-profit pool to cloud providers, ASIC designers, foundries, packaging and testing houses, and the supply chain.
Taken together, three Morgan Stanley notes provide three pieces of evidence for this main thread. The first Greater China semiconductor note puts GPUs, XPUs, China chips, advanced packaging, and testing into the same AI semiconductor map. The second TSMC note shows that advanced nodes and advanced packaging remain the hardest supply constraints. The third Google note pushes TPU from “Google’s internal chip” into a 2028 model of cloud revenue, external capacity sales, and revenue per GW.
The short original phrase that best captures the issue set of these materials is “Who Are the Winners in AI?” The answer will not be a single chip company. Winners will fall into three layers: first, GPU platforms with system ecosystems and customer lock-in; second, cloud-provider XPU platforms with stable internal workloads and capital-spending capacity; third, bottleneck assets controlling advanced nodes, advanced packaging, testing, substrates, power, networking, and delivery capability.
Nvidia GTC Deep Dive | From GPU Racks to Token Factories: Nvidia Pulls CPU, Storage, Networking, and Power into the Token Economy, Repricing Full-Stack AI Infrastructure
II. The Total AI Semiconductor Pie Is Still Expanding; Architectural Divergence Cannot Be Separated from Incremental Demand
One of the easiest misreadings of the AI compute chain is to treat share shifts as proof that the total market has peaked. Profit allocation among GPUs, XPUs, CPUs, networking chips, HBM, and advanced packaging will change, but AI semiconductor demand itself is still expanding. Morgan Stanley’s framework in its Greater China semiconductor work is that the global semiconductor market could move toward roughly $1.5 trillion by 2030, with AI semiconductors contributing around half of incremental growth; AI semiconductor TAM is estimated at roughly $485 billion in 2026 and roughly $753 billion in 2030.
A market of this scale can accommodate growth in both GPUs and XPUs. The real question is where incremental profit lands, not explaining every change through “who replaces whom.” Training demand is still rising. Multimodality, video generation, chain-of-thought inference, agent workflows, and enterprise private deployments all continue to consume compute. At the same time, cloud providers cannot rely solely on GPU procurement to absorb all growth, because power, data-center space, CapEx, depreciation, and customer pricing will all become constraints.
Large-model companies initially bought GPUs to rapidly obtain training capability and model iteration speed. After entering scaled commercialization, cloud providers and model platforms care about the cost of each inference request, how many billable tokens each watt of power can create, and how much customer revenue each data-center rack can support. Once AI compute shifts from an “arms race” to “factory operations,” chip selection naturally stratifies.
The first category of workloads will remain on GPUs. Frontier training, unknown model structures, inference services with complex ecosystems, and scenarios where third-party developers need fast migration all have extremely high requirements for flexibility and software support. GPU generality and the developer ecosystem are assets here, not redundant costs.
The second category of workloads will migrate to XPUs. Search, advertising, recommendation, image generation, video understanding, internal office agents, and cloud-hosted model inference can reduce unit costs through dedicated chips as long as the algorithm stack is controllable, runtime patterns are stable, and data-center scale is large enough. This is where Google TPU matters: it is more like a tool for Google to bind models, cloud, CapEx, and chip architecture together than a generic GPU for all customers.
The third category of workloads will form local substitution in regional markets. China has independent constraints in high-end GPU supply, training ecosystems, data compliance, and local customer budgets. If domestic chips do not fully catch up in performance but can provide acceptable solutions in pricing, supply, deployment, service, and per-token cost, demand will first start from inference, industry models, and government-enterprise private deployment scenarios.
This means AI semiconductor investment judgment must move from one variable to three variables: whether total demand continues to expand, how GPU/XPU share stratifies, and whether bottleneck assets have pricing power. Looking only at chip architecture can miss the profit elasticity of advanced packaging, testing, substrates, power, networking, and rack delivery. Looking only at the supply chain can underestimate the structural changes from the GPU ecosystem and cloud providers’ in-house chips.
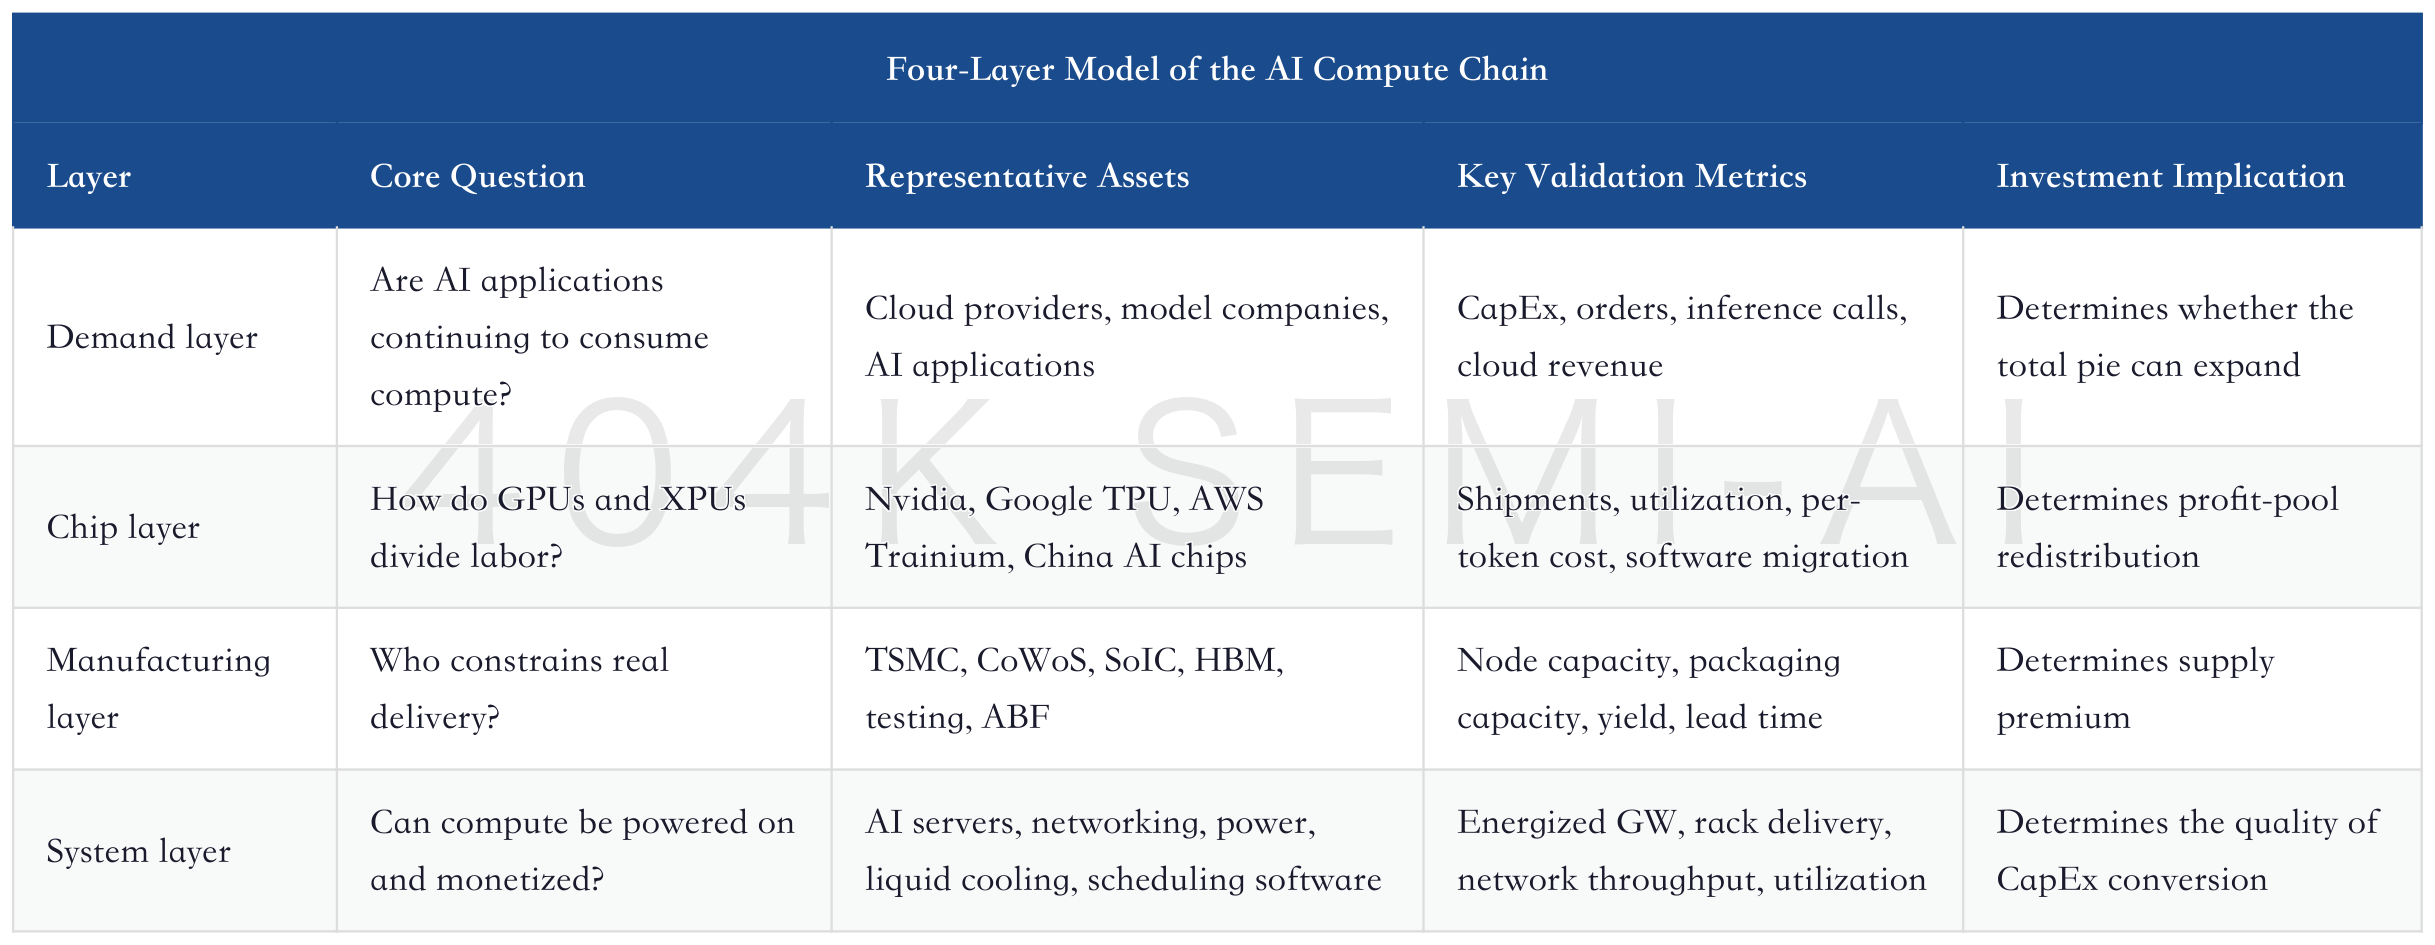
AI Semiconductors Have Only One Main Thread Left: Repricing from Dual Compute Cores to Bottleneck Assets
III. The GPU Moat Is in the System, Not Just the Chip
GPUs remain the core platform for AI training and general-purpose inference, and the reason is not just performance. What Nvidia is really selling has become an operating system for AI factories: GPUs, CPUs, networking, software libraries, racks, power, cooling, cluster management, and the developer ecosystem together form the customer’s default choice. As long as model companies remain in a phase of rapid trial and error, generality matters more than unit chip cost.
This is especially true in training. Frontier-model iteration requires constantly changing network structures, mixture of experts, long context, multimodal inputs, reinforcement learning, and data-processing pipelines. Dedicated chips can improve efficiency on defined workloads, but the adaptation cost for unknown workloads is high. The value of the GPU platform is that it lets customers absorb uncertainty through an already mature software stack.
Inference has not moved off GPUs overnight either. Many inference services are unstable: model versions are updated frequently, service providers need to support multiple models, customer workloads have large peak-trough fluctuations, and latency, throughput, and memory requirements vary significantly. For cloud platforms, a general-purpose GPU can be rescheduled across multiple customers, models, and tasks. This substitutability itself is a utilization asset.
Nvidia has also pushed the value chain from single cards to full racks and networking. Vera Rubin, NVL-series racks, NVLink, switching chips, Ethernet/InfiniBand, storage, and CPUs together turn GPUs from “compute cards” into “operable token factories.” When customers are buying a full system, competitors need to replace not just one chip, but the entire training and inference production line.
The GPU’s second-layer moat comes from ecosystem cost. Developer tools, model libraries, optimized operators, cluster scheduling, fault handling, performance analysis, and talent pools have all formed path dependence around CUDA and the Nvidia ecosystem. Customers certainly want to reduce procurement costs, but they also calculate migration risk, model-performance loss, engineering-team learning costs, and time to deployment. As long as AI demand grows rapidly, time is a cost, and stable supply plus fast deployment will continue to support the GPU premium.
The GPU’s third-layer moat comes from supply-chain orchestration capability. Advanced nodes, HBM, CoWoS, substrates, testing, full racks, and data-center power all need to be locked in ahead of time. Nvidia can organize customer demand, supply-chain capacity, and system roadmaps together. This “general contractor” capability is harder to replicate than any single chip specification.
But the GPU’s advantage does not mean the profit pool will always reside only in GPUs. Precisely because GPUs are too expensive, too tight, and too powerful, customers will migrate predictable workloads to XPUs. Nvidia will not lose its core position because TPUs or Trainium exist, but the GPU premium will force customers to stratify workloads: GPUs for new models and complex tasks, in-house chips for mature high-frequency workloads, domestic chips for regional substitution scenarios, and cheaper accelerators for low-cost batch inference.
This determines why investors should not set GPUs and XPUs against each other. GPUs are the default engine of the AI industry. XPUs are large customers’ redesign of the cost curve. The GPU victory explains the first half of the AI trade; XPU expansion explains the second-half redistribution of profit.
Vera Rubin 1GW Cost Ledger: How a $47B AI Factory Reorders Value Across GPUs, Memory, Networking, Power, and Substrates
IV. The Essence of XPU Is Cloud Providers Internalizing the Cost Curve
The term XPU can sound broad. In practice, it can be split into three categories: cloud providers’ in-house training/inference chips, semi-custom chips involving ASIC design vendors, and local AI accelerators in regional markets. What they share is the trade-off of general-purpose GPU flexibility for cost, power efficiency, and supply control under specific workloads.
The clearest commercial logic for cloud providers’ in-house chips is to turn high-frequency internal workloads from procurement costs into proprietary architecture assets. Google TPU serves Search, ads, recommendations, Gemini, Workspace, cloud AI, and internal foundation models; AWS Trainium serves Bedrock, internal models, and cloud customers; Microsoft Maia is tied to Azure AI and the OpenAI ecosystem; Meta MTIA targets recommendation and inference workloads. They do not need to cover every task. As long as they cover enough internal compute consumption, they can change the long-term cost curve.
The most important numbers in Google-related materials have already moved beyond a single target-price increase, toward putting 2028 compute capacity, external TPU sales, and cloud revenue into the same model. Morgan Stanley assumes Google will add roughly 9GW of compute capacity in 2028, with TPU internal use and external sales jointly driving cloud business growth; 1P external TPU sales could contribute roughly US$62 billion/US$79 billion in revenue in 2027/2028, with revenue per GW of about US$20 billion.
This means the financial attributes of TPU have changed. In the past, the market viewed TPU as a tool for Google to reduce internal inference costs. Now it needs to be viewed as a threefold asset: first, reducing the marginal cost of Google’s internal AI services; second, supporting Google Cloud’s external sale of AI capacity; third, embedding Google’s AI architecture into customer infrastructure through external sales of TPU racks or hosted capacity.
The short phrase in the original title, “Diving into ’28 Compute Capacity,” captures the core point. The market is no longer only concerned with whether Google Search can be reshaped by AI, nor only with cloud business growth. It is calculating how much billable compute Google can bring online in 2028, how much of that compute comes from TPU, how much from GPU, and how much can be converted into revenue through cloud services and external sales.
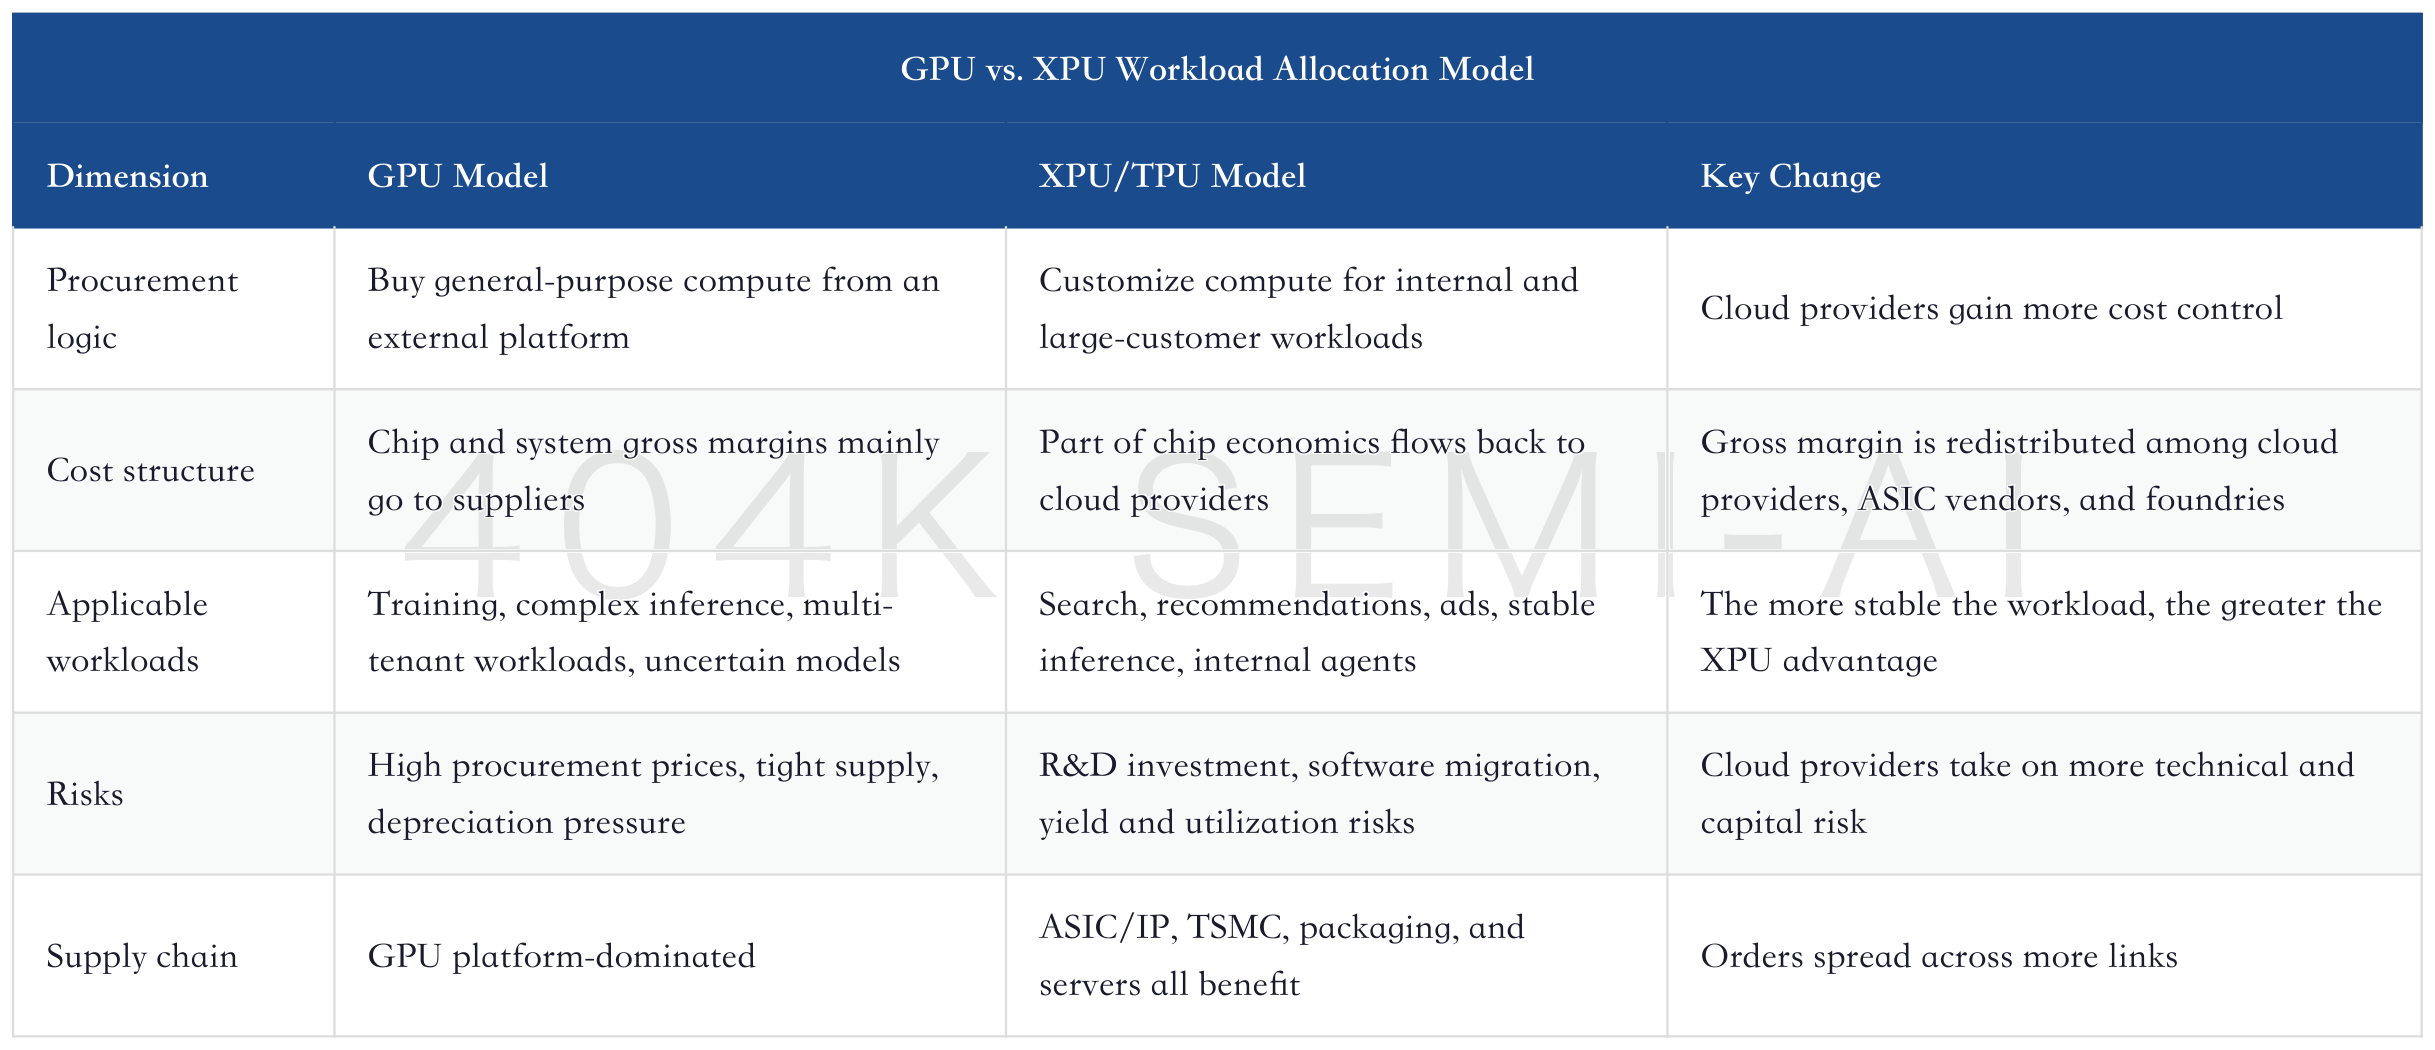
External TPU sales will also change how cloud services are priced. When customers previously bought cloud AI, what they appeared to buy was GPU instances or model APIs; behind that, they were paying the Nvidia platform premium, cloud-provider data-center depreciation, and software services. If Google packages TPU capacity for large customers, customers are buying a deeper Google stack: chips, networking, models, cloud platform, and data services bundled together. This business model is more like “vertical integration of AI infrastructure,” not merely chip sales.
But the boundaries of XPU are also clear. It requires scale, stable workloads, software teams, wafer and packaging capacity, and customers willing to accept a non-GPU ecosystem. Small and mid-sized cloud providers and ordinary enterprises will find it hard to replicate Google TPU, because they lack enough internal workload to amortize chip R&D; and lack a sufficiently strong cloud platform to absorb chip-roadmap risk. The earliest beneficiaries of XPU will be a small number of hyperscale cloud providers and the ASIC/supply-chain companies serving them.
Broadcom, MediaTek, and HBM Re-rating: Google TPU Shipments Revised Up to 35 Million Units
V. TSMC Puts GPU and XPU Into the Same Bottleneck
GPU and XPU compete on the customer side, but they are squeezed into the same channel on the manufacturing side. Whether it is Nvidia GPU, Google TPU, Amazon Trainium, or China’s domestic AI accelerators, any product entering the high-end compute market cannot avoid advanced process nodes, advanced packaging, and high-bandwidth memory. TSMC has therefore become one of the “master switches” for AI compute expansion.
Morgan Stanley’s view on TSMC is direct: it raised the target price from NT$2,588 to NT$2,888 and maintained an Overweight rating. The core rationale is that TSMC’s leading-edge foundry advantage continues to widen, while Samsung and Intel have limited competitive impact on high-end AI orders. It also expects further upside to TSMC’s 2026 revenue-growth guidance, with capex potentially approaching the high end of the US$56 billion range.
The core of this judgment is not the target price itself, but the supply structure. AI accelerators are driving simultaneous demand for 3nm, 2nm, CoWoS, SoIC, and EUV tools. GPU and XPU may divide workloads on the customer side, but both will compete for TSMC’s advanced process and advanced packaging capacity. If CoWoS supply reaches roughly 200kwpm in 2027 and SoIC capacity continues to expand, the market will still focus on effective capacity, yield, package size, and customer allocation, rather than only nominal wafer counts.
The original phrase “Domination in leading-edge foundry continues” is restrained but critical. AI chip architectures can diverge, while concentration in leading-edge foundry continues to rise. TSMC’s advantages come from four things: process yield, priority access to EUV tools, customer co-design capability, and advanced packaging platforms. As long as AI chips continue to evolve toward larger dies, higher bandwidth, and more complex packaging, these four things become pricing power.
There is another important change in TSMC-related materials: advanced process nodes may become a larger incremental constraint than CoWoS. In the past, the market was used to describing the AI supply bottleneck as a CoWoS shortage, later extending that to HBM, ABF, testing, and power. Now, capacity at 2nm/3nm nodes itself is also becoming a core resource contested by major customers. The migration from Blackwell to Rubin, alongside simultaneous volume ramp-ups in Google TPU, CPU, networking chips, and AI ASICs, will push leading-edge node allocation into a tighter state.
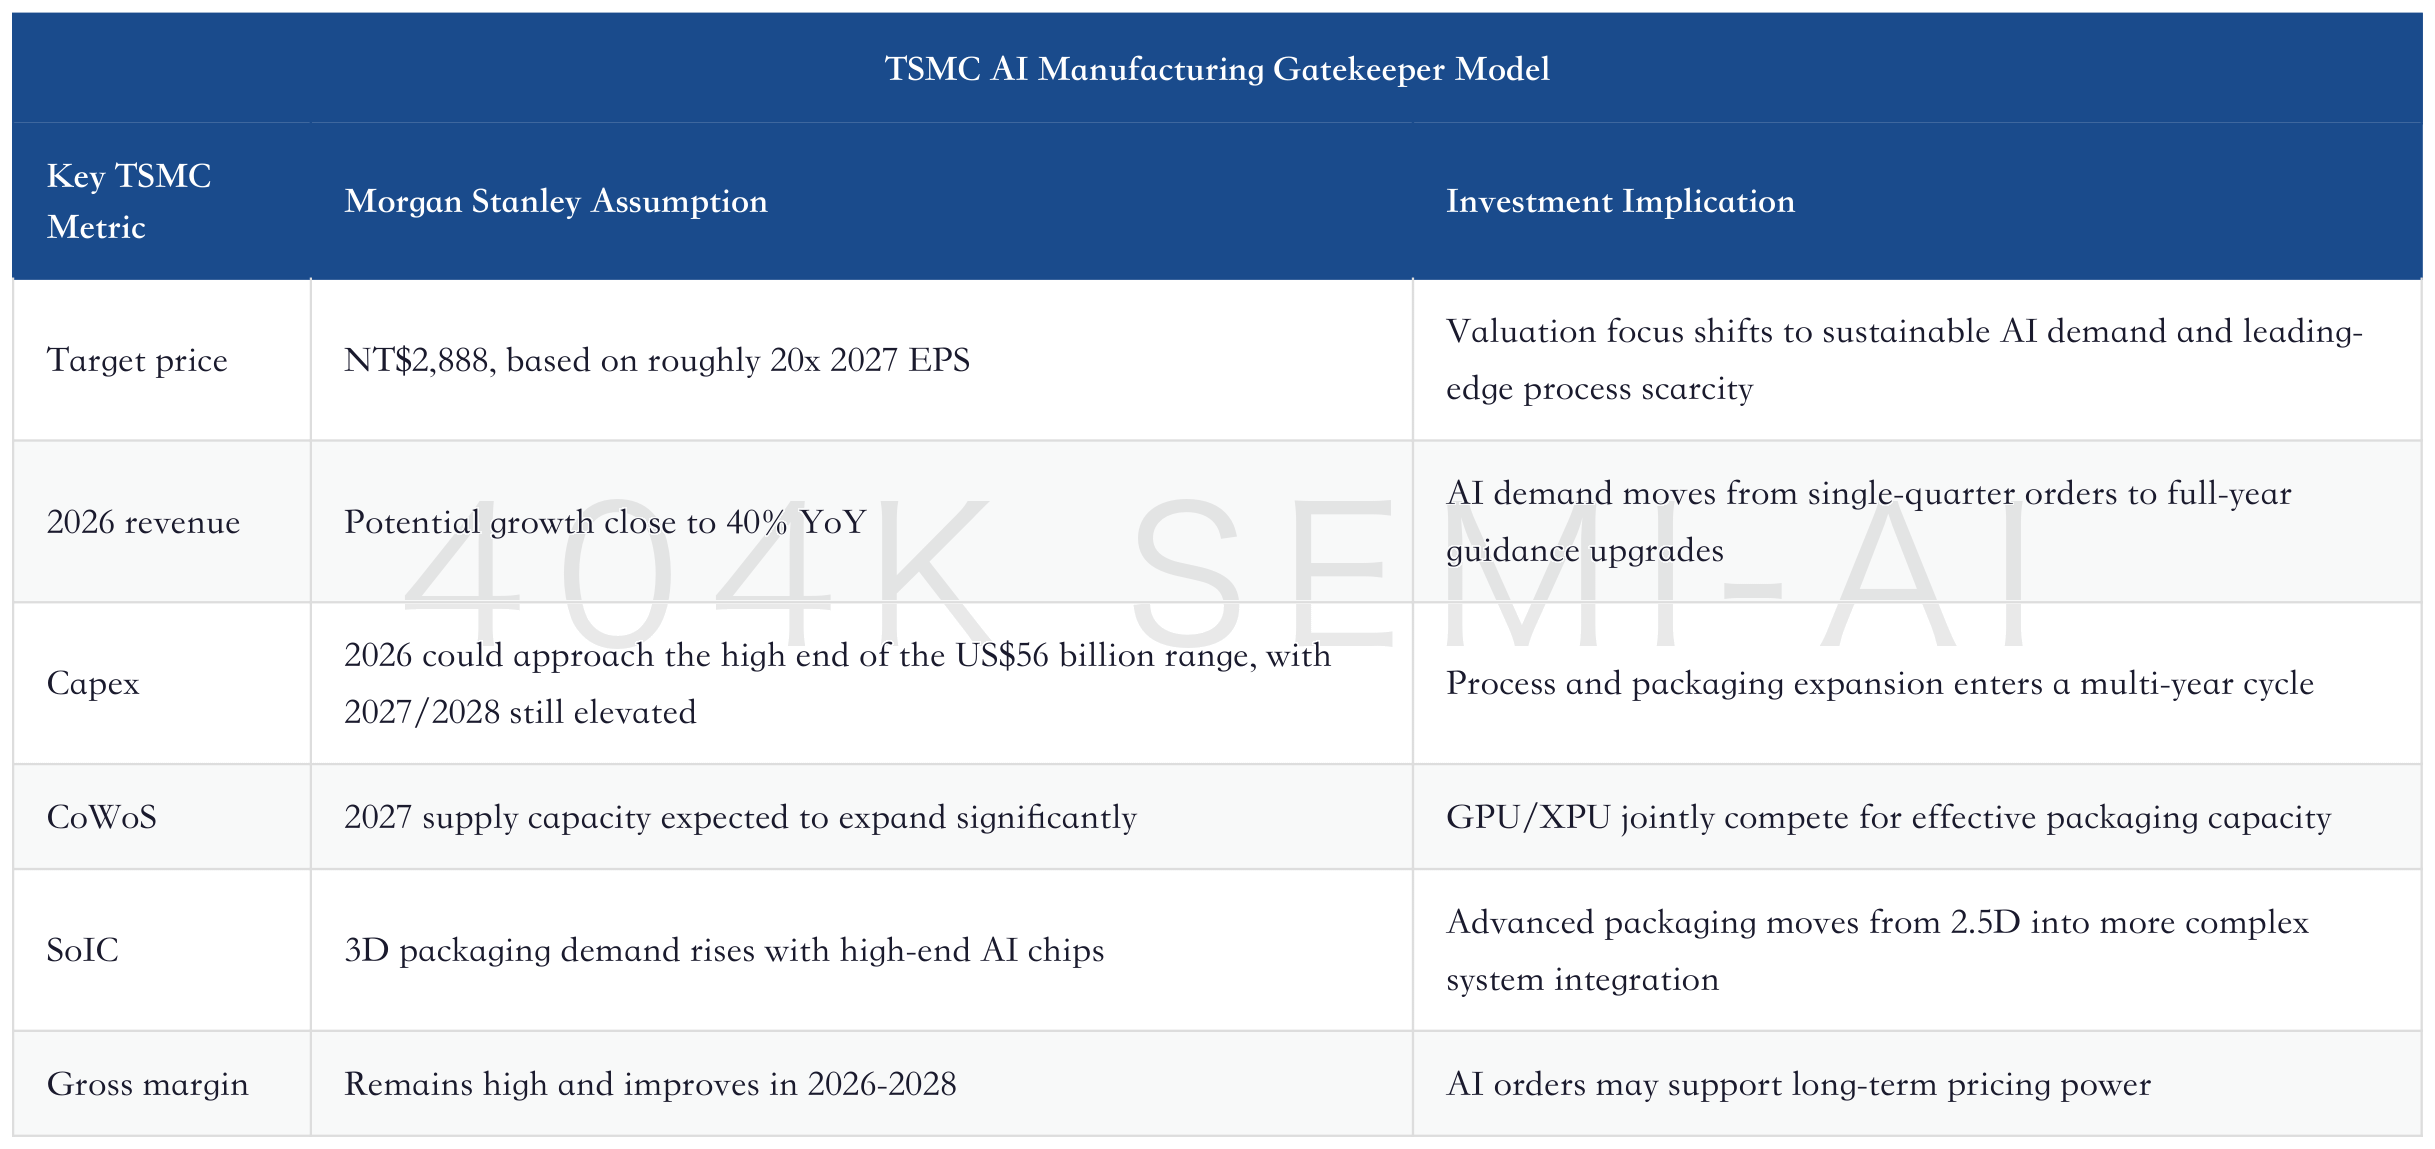
This also explains why TSMC cannot be skipped when judging the GPU vs. XPU outcome. If GPU demand remains strong, TSMC benefits. If XPU volume accelerates, TSMC also benefits. If China’s domestic AI chips require advanced nodes or supporting mature nodes, foundry remains a key link. TSMC’s risk is not whether GPU or XPU wins, but whether customer demand has been pulled forward too aggressively, whether capex is so high that it compresses future returns, and whether advanced packaging expansion creates temporary oversupply.
For investors, TSMC’s signals arrive earlier than any single chip shipment number. If TSMC continues to raise capex, lift advanced-node revenue expectations, maintain high gross margins, and keep CoWoS/SoIC allocation tight, it indicates that aggregate AI chip demand is still rising. Only if advanced-node orders slow, packaging pricing loosens, and customer prepayments and long-term agreements weaken would it indicate that the AI compute cycle has entered a stress test.
VI. Advanced Packaging and Testing Are the Hidden Capacity of AI Chips
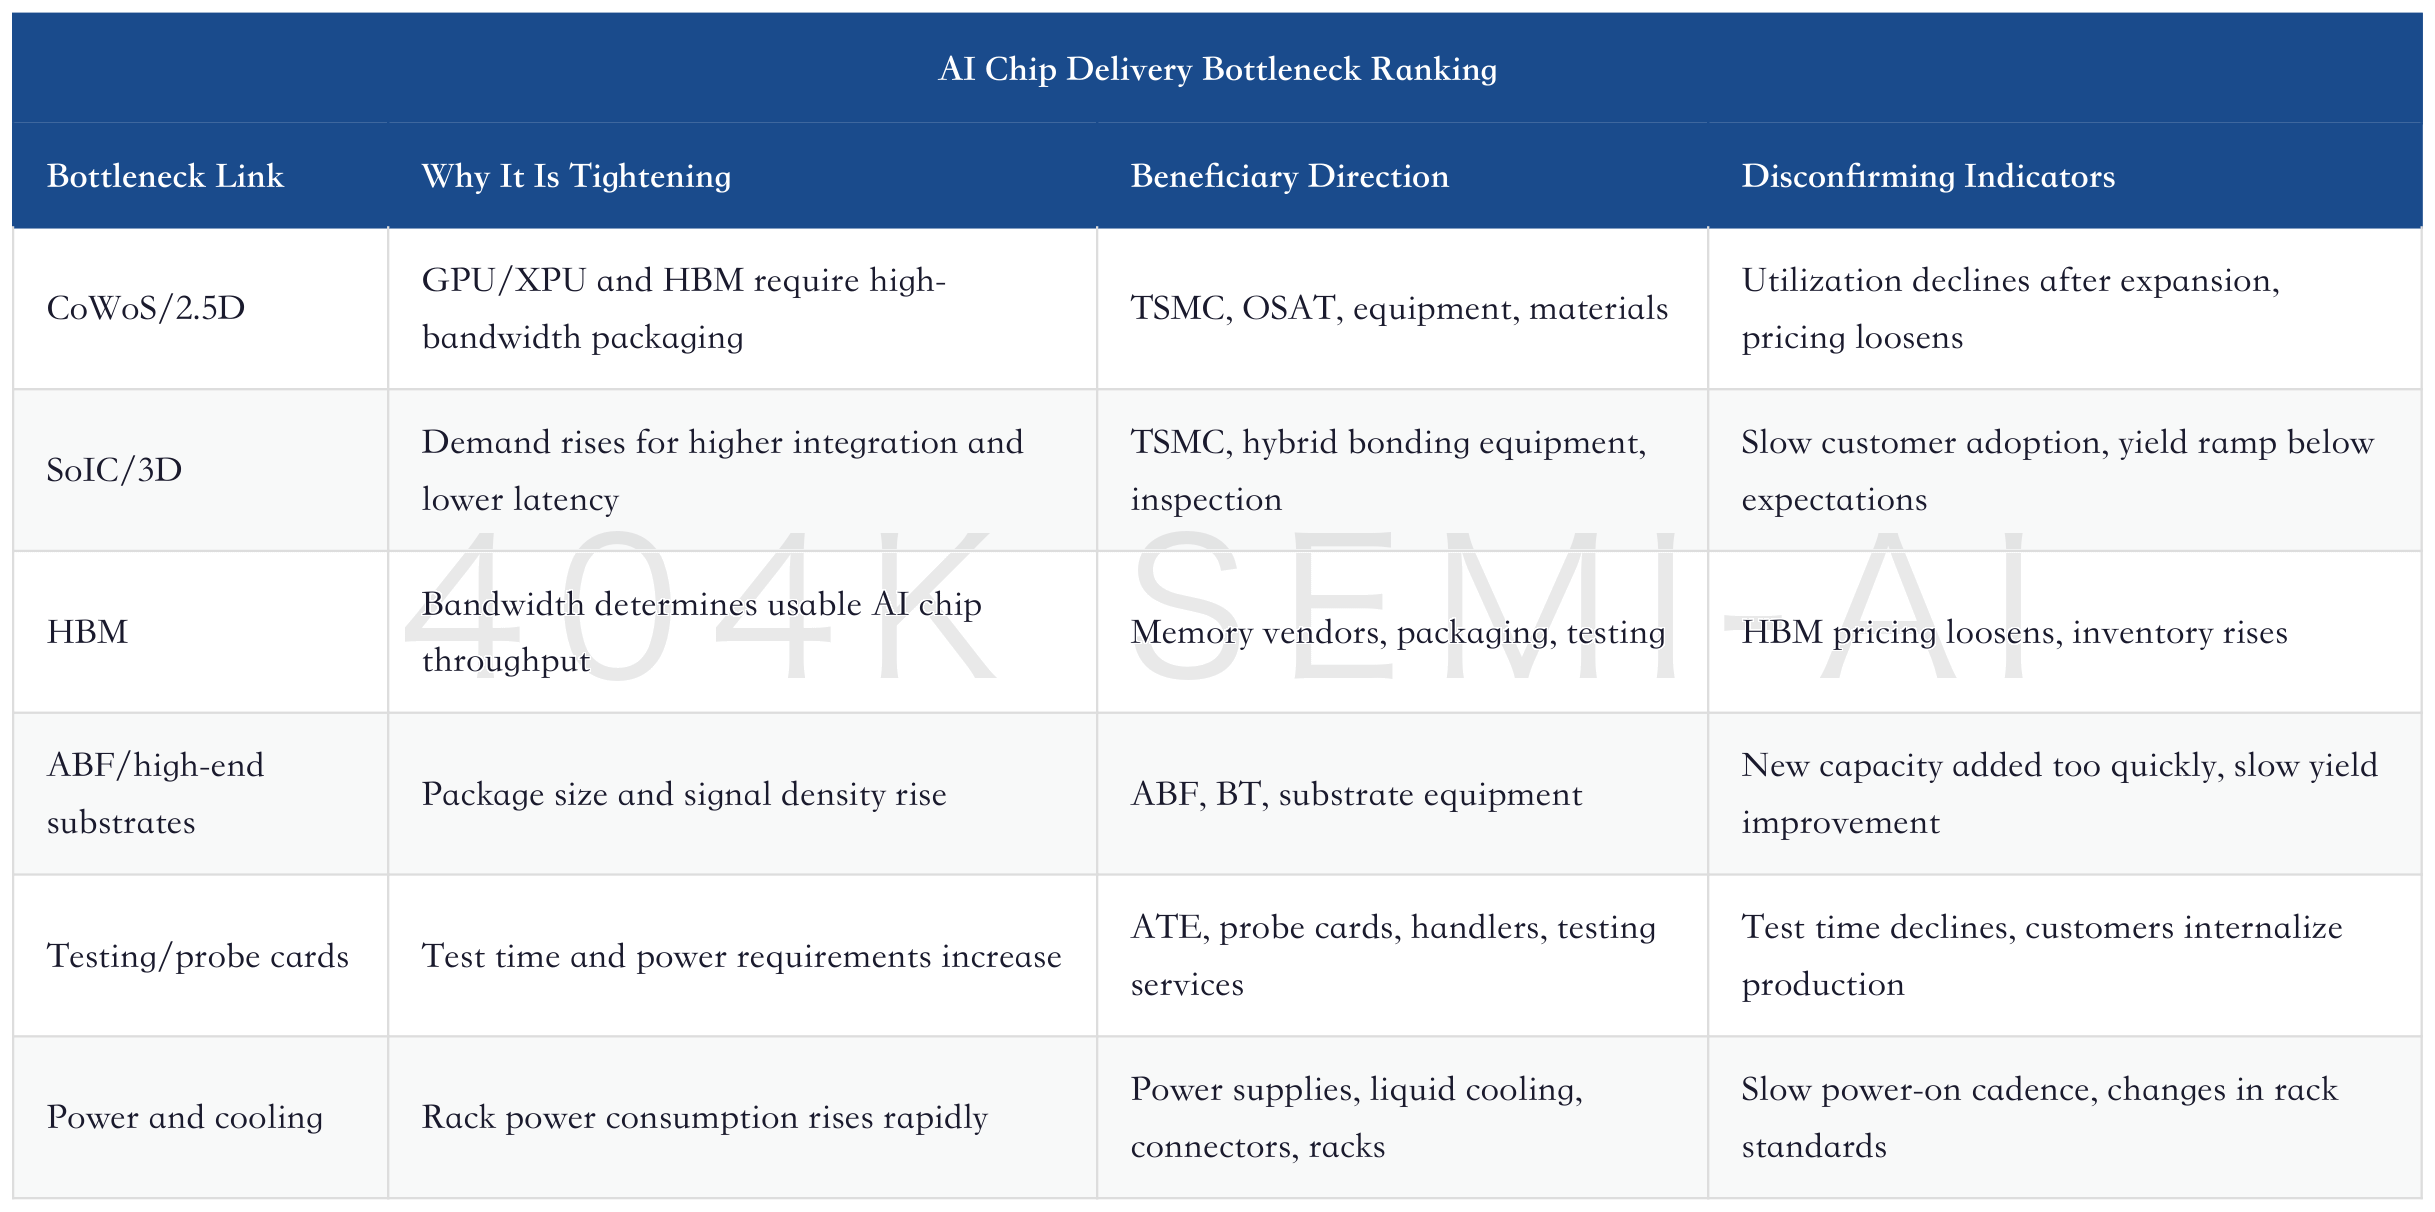
The shipment ceiling for AI chips is not equal to wafer capacity. Large GPU/XPU dies, HBM, silicon interposers, RDL, substrates, advanced packaging equipment, testers, and probe cards jointly determine deliverable volume. The higher-end the chip, the more it resembles a system, and the more packaging and testing resemble critical processes on the production line.
Greater China semiconductor materials place testing and advanced packaging in a very important position. As AI accelerator package sizes grow, HBM stack counts rise, and chip interconnect complexity increases, both test time and test coverage increase. High-end AI chips are not merely “manufactured”; they must also verify performance, power consumption, interconnect stability, and long-term reliability through longer testing processes. Testing equipment, test interfaces, probe cards, and handlers therefore gain stronger growth elasticity than in traditional cycles.
This point is important for company ranking. In past semiconductor investing, testing and packaging were often viewed as back-end support, with weaker valuation elasticity than design and wafer manufacturing. In the AI era, that order is changing. If the value of a single AI chip is very high and customers cannot tolerate volatility in yield and failure rates, back-end testing moves from a cost item to a delivery gatekeeper. Whoever can shorten test time, increase parallelism, and support higher-power chips can participate in AI capacity allocation.
Morgan Stanley materials mention that growth in testing equipment and related suppliers may be significantly higher than in traditional semiconductor cycles. Longer AI chip test times and greater packaging complexity bring WinWay Technology, MPI, Foxconn Technology, Gudeng, King Yuan Electronics, ASE Technology Holding, AllRing Tech, and other links into the investment field of view. They may not have the brand halo of GPU vendors, but they could gain orders, pricing power, and valuation re-rating when the AI supply chain is tight.
Advanced packaging follows the same logic. CoWoS enables high-speed communication between GPU/XPU and HBM in the same package. SoIC pushes 3D stacking and hybrid bonding to higher levels of integration. ABF substrates and high-layer-count PCBs support larger packages, higher current, and more complex signal integrity. If AI chips move from board-level systems toward full-rack systems, the importance of packaging and substrates will continue to increase.
The profit pool in the AI chip value chain will move along with bottlenecks. In 2023-2024, the market focused most on GPU supply. In 2025-2026, it focused on CoWoS and HBM. In 2026-2027, it may further expand to SoIC, ABF, testing, power, and full-rack delivery. The name of the bottleneck itself is not important. What matters is whether it still constrains customer revenue. As long as customers are willing to pay a premium to shorten delivery cycles, bottleneck links have profit elasticity.
VII. Google’s TPU Model Shows Cloud Providers Are Becoming Chip Companies
The most penetrating part of Google’s materials is that they move Google Cloud’s valuation framework away from an ancillary business of an advertising company and toward the revenue model of an AI compute platform. Morgan Stanley raised its target price for Alphabet from US$375 to US$415, citing higher compute capacity in 2028, increased external TPU revenue, upward revisions to Google Cloud revenue and EBIT, and a model implying roughly US$19 of EPS in 2028.
Behind this change is a more important industry judgment: cloud providers are moving from “buying compute and renting it out” to “designing compute, operating compute, and selling architecture.” If Google only buys Nvidia GPUs, it earns cloud-service gross margin while bearing data-center depreciation and customer utilization risk. If Google uses TPUs to support both internal and external workloads, it can also embed chip architecture, software frameworks, and model capability into customer workflows.
Morgan Stanley assumes Google will add roughly 9GW of compute capacity in 2028, a substantial portion of which will come from TPUs. It also expects Google to sell first-party TPUs externally, with 2027/2028 revenue potentially reaching about US$62 billion and US$79 billion, respectively. This framework is aggressive, but it reveals a direction: AI cloud may no longer be priced only by GPU hours, and could gradually shift toward pricing based on architecture, capacity, model services, and customer lock-in.
The Google Cloud model has also been revised up meaningfully. The 2028 cloud revenue and EBIT expectations in the materials imply that cloud will continue to rise as a share of Alphabet’s total profit. If TPU is merely low-margin hardware resale, valuation upside is limited. If it drives customers into long-term use of Google Cloud, model services, and data platforms, the market can no longer value Alphabet only through the traditional advertising-company framework.
External TPU sales also have supply-chain implications. They will drive expansion in ASIC design services, wafer foundry, advanced packaging, HBM, server ODMs, networking, power, and data-center construction. Google’s in-house chips do not mean supply-chain profits disappear; rather, profit is redistributed from the GPU platform to a Google-led architecture chain. Broadcom, MediaTek, TSMC, packaging and testing vendors, and server suppliers may all participate in this process.
Broadcom Earnings Deep Dive: AI ASIC Ramp, AI Networking Demand Expansion, and the High-Margin Picks-and-Shovels Supplier Behind Cloud Vendors
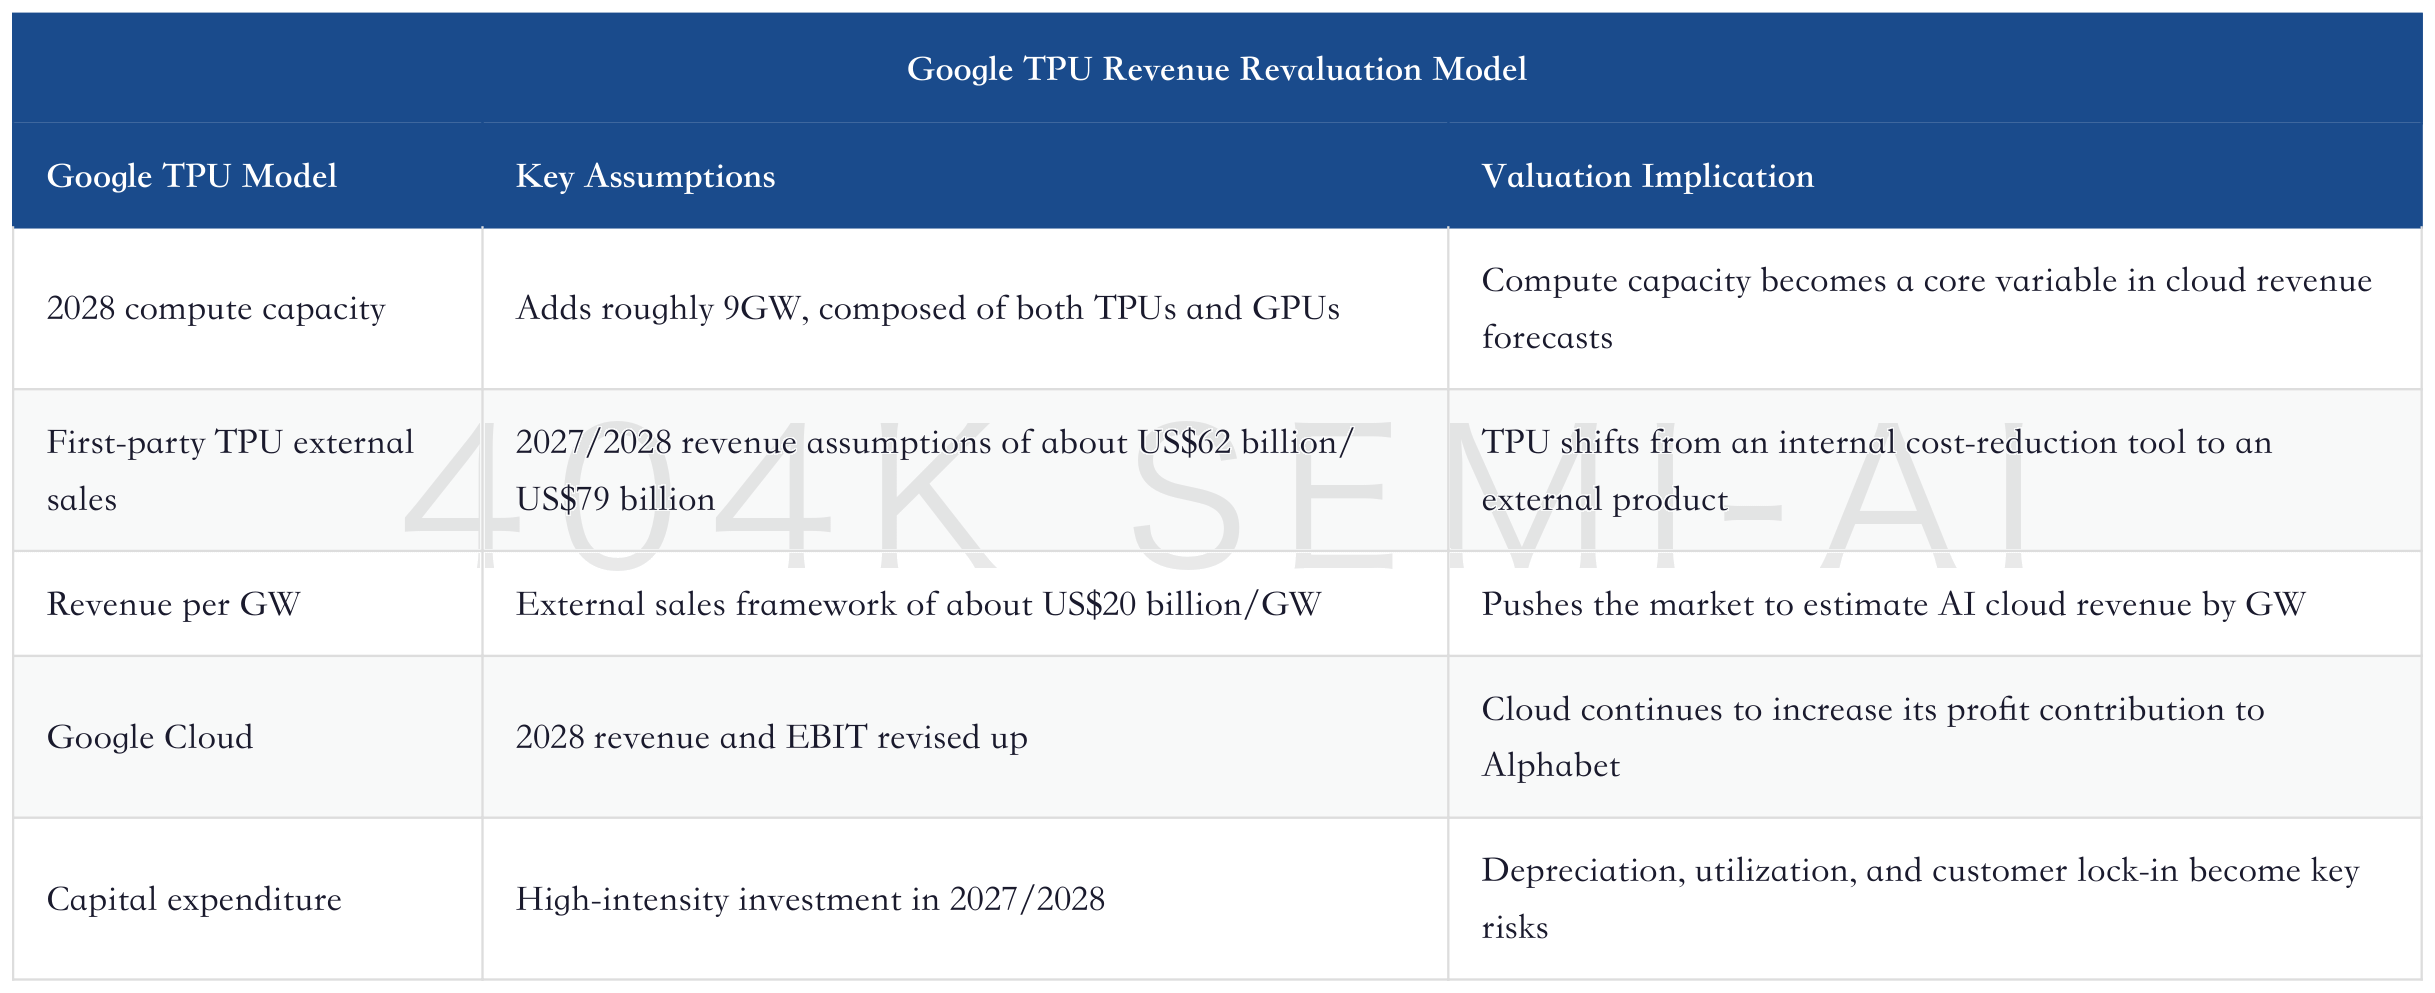
That said, several risks in the Google TPU model must be tracked. First is customer acceptance of externally sold TPUs. Customers will buy TPU capacity only if software migration, model performance, developer tools, and service stability meet requirements. Second is the pace of cloud revenue recognition. Building GW-scale capacity requires data centers, power, chips, networking, and customer contracts to move in sync; delays in any link will affect revenue realization. Third is gross margin. If external TPU sales resemble hardware sales, gross margin will be lower than cloud services; only if TPUs are bundled with models and platforms will profit quality be higher. Fourth is capital-expenditure pressure. High-intensity CapEx increases depreciation and cash-flow pressure, and is justified only if utilization is high enough.
Therefore, the investment conclusion for TPUs cannot simply be written as “positive for Google, negative for Nvidia.” A more accurate ranking is: positive for Google Cloud’s long-term strategic control, positive for the ASIC/foundry/packaging/server supply chain, and marginally weakening the monopoly position of general-purpose GPUs in certain large-scale workloads; but in training, ecosystem, and highly uncertain inference workloads, GPUs still retain a core position.
VIII. The Opportunity for China’s AI Chips Lies in Usable Cost, Not Slogan-Driven Catch-Up
Judgments on China’s AI chips most often fall into two extremes: one frames domestic chips as about to fully replace Nvidia, while the other assumes they have no commercial value because of software ecosystem and process-node gaps. Both views are too crude. The more realistic framework from Morgan Stanley’s Greater China semiconductor materials is to examine China’s AI GPU TAM, self-sufficiency rate, access to advanced process nodes, price gaps, and per-token cost.
The materials note that China’s AI GPU market could reach roughly US$91 billion by 2030, with the domestic self-sufficiency rate likely to rise significantly. This market does not come only from training by large internet platforms, but also from private deployments by government and enterprise customers, carrier clouds, industry models, inference deployment, data-center localization, and adaptation to local ecosystems. Chinese customers will consider performance, supply, compliance, price, delivery, and service when choosing chips, rather than only looking at the absolute benchmark scores of international flagship GPUs.
The first path for domestic AI chips is to offset the performance gap with lower selling prices. If single-card performance is lower than Nvidia’s, but pricing and supply are more favorable, and if usable cost can approach customer requirements in specific model and inference scenarios through clusters, software optimization, and customer adaptation, then commercial deployment has room. Morgan Stanley’s materials mention that Chinese AI chips may have a lower total cost of ownership than Nvidia processors; the key is whether per-token cost can approach or exceed customer requirements.
The second path is deep adaptation to the local ecosystem. China has a large number of government and enterprise customers, carriers, financial institutions, manufacturers, education users, and content platforms. They do not necessarily pursue the world’s most advanced training performance, but they do need stable, controllable, and maintainable inference and industry-model deployment. If domestic chips can connect with domestic frameworks, models, cloud platforms, databases, and industry applications, ecosystem value will gradually accumulate.
The third path is supply-chain pull-through. Volume growth in China’s local AI chips will drive wafer foundry, advanced packaging, assembly and testing, EDA/IP, servers, liquid cooling, power, connectors, and system integration. Even if individual chip-company profits are highly volatile, more certain links in the supply chain may benefit first.
China Semiconductors 2026: Supply-Chain Repricing from Domestic Substitution to Compute Revaluation
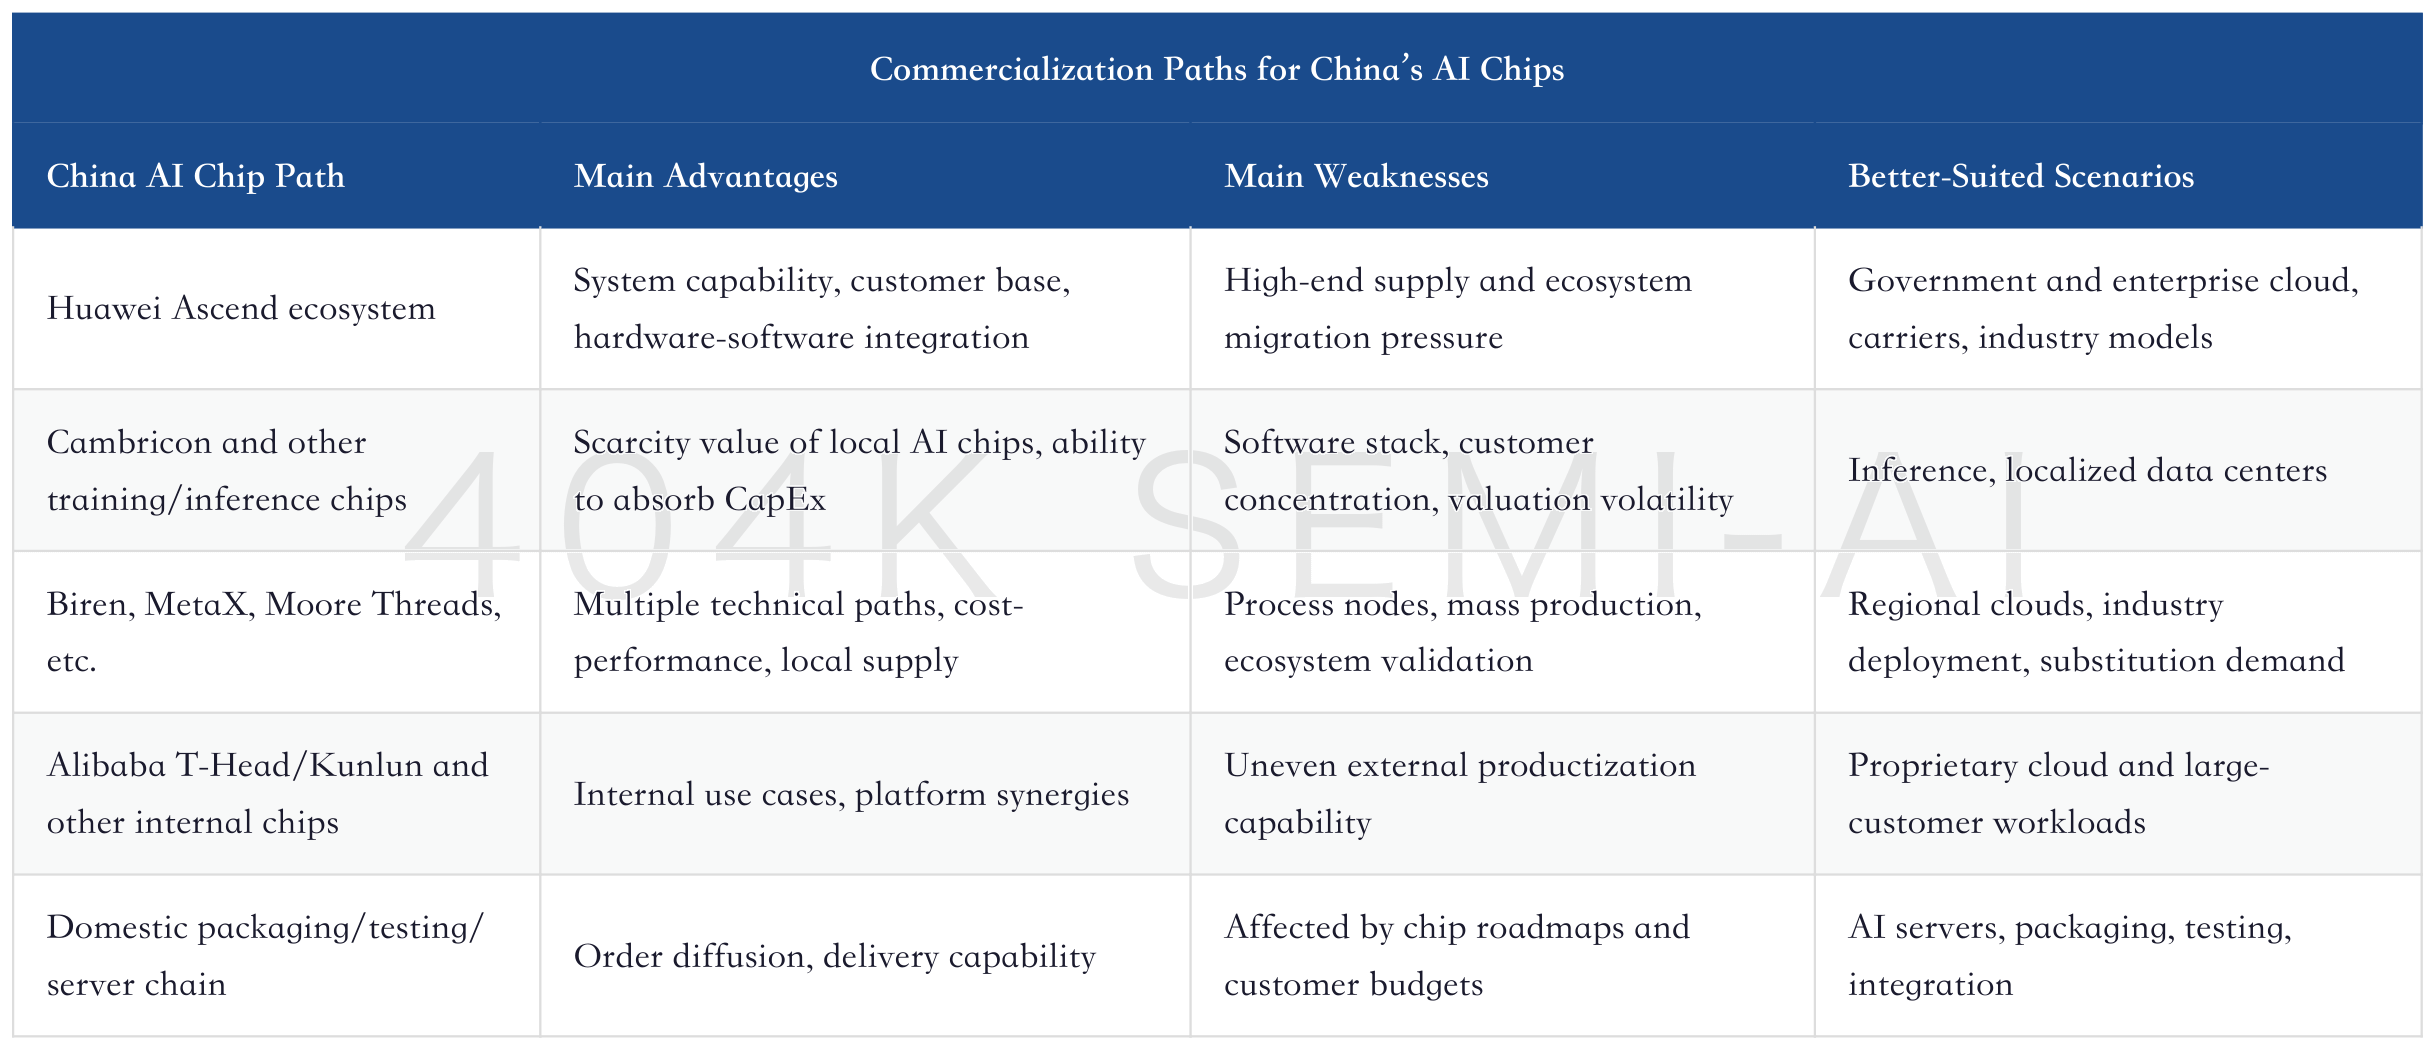
The risks for China’s AI chips also need to be stated clearly. First, ecosystem migration is slow. Moving models from CUDA to other platforms requires engineering effort and performance validation. Second, advanced process nodes are constrained. High-end training chips still require advanced nodes and advanced packaging, and supply constraints will affect performance catch-up. Third, price wars. Low prices can open the market, but may also compress chip-company gross margins. Fourth, customer budgets and data-center power-on pace. Chip orders ultimately need to become operating clusters; tenders and plans alone are not enough. Fifth, valuation volatility. Domestic AI chip companies are easily amplified by thematic sentiment, while financial delivery requires stricter tracking.
From an investment perspective, China’s path is more of a “usable cost” trade than an “absolute performance” trade. As long as customers are willing to pay for controllable supply and local ecosystems, domestic chips have commercial room. But if per-token cost, software migration, and cluster stability remain below requirements over the long term, thematic valuations will retreat before fundamentals catch up.
IX. Profit Pools Will Spread from Chip Brands to Bottleneck Assets
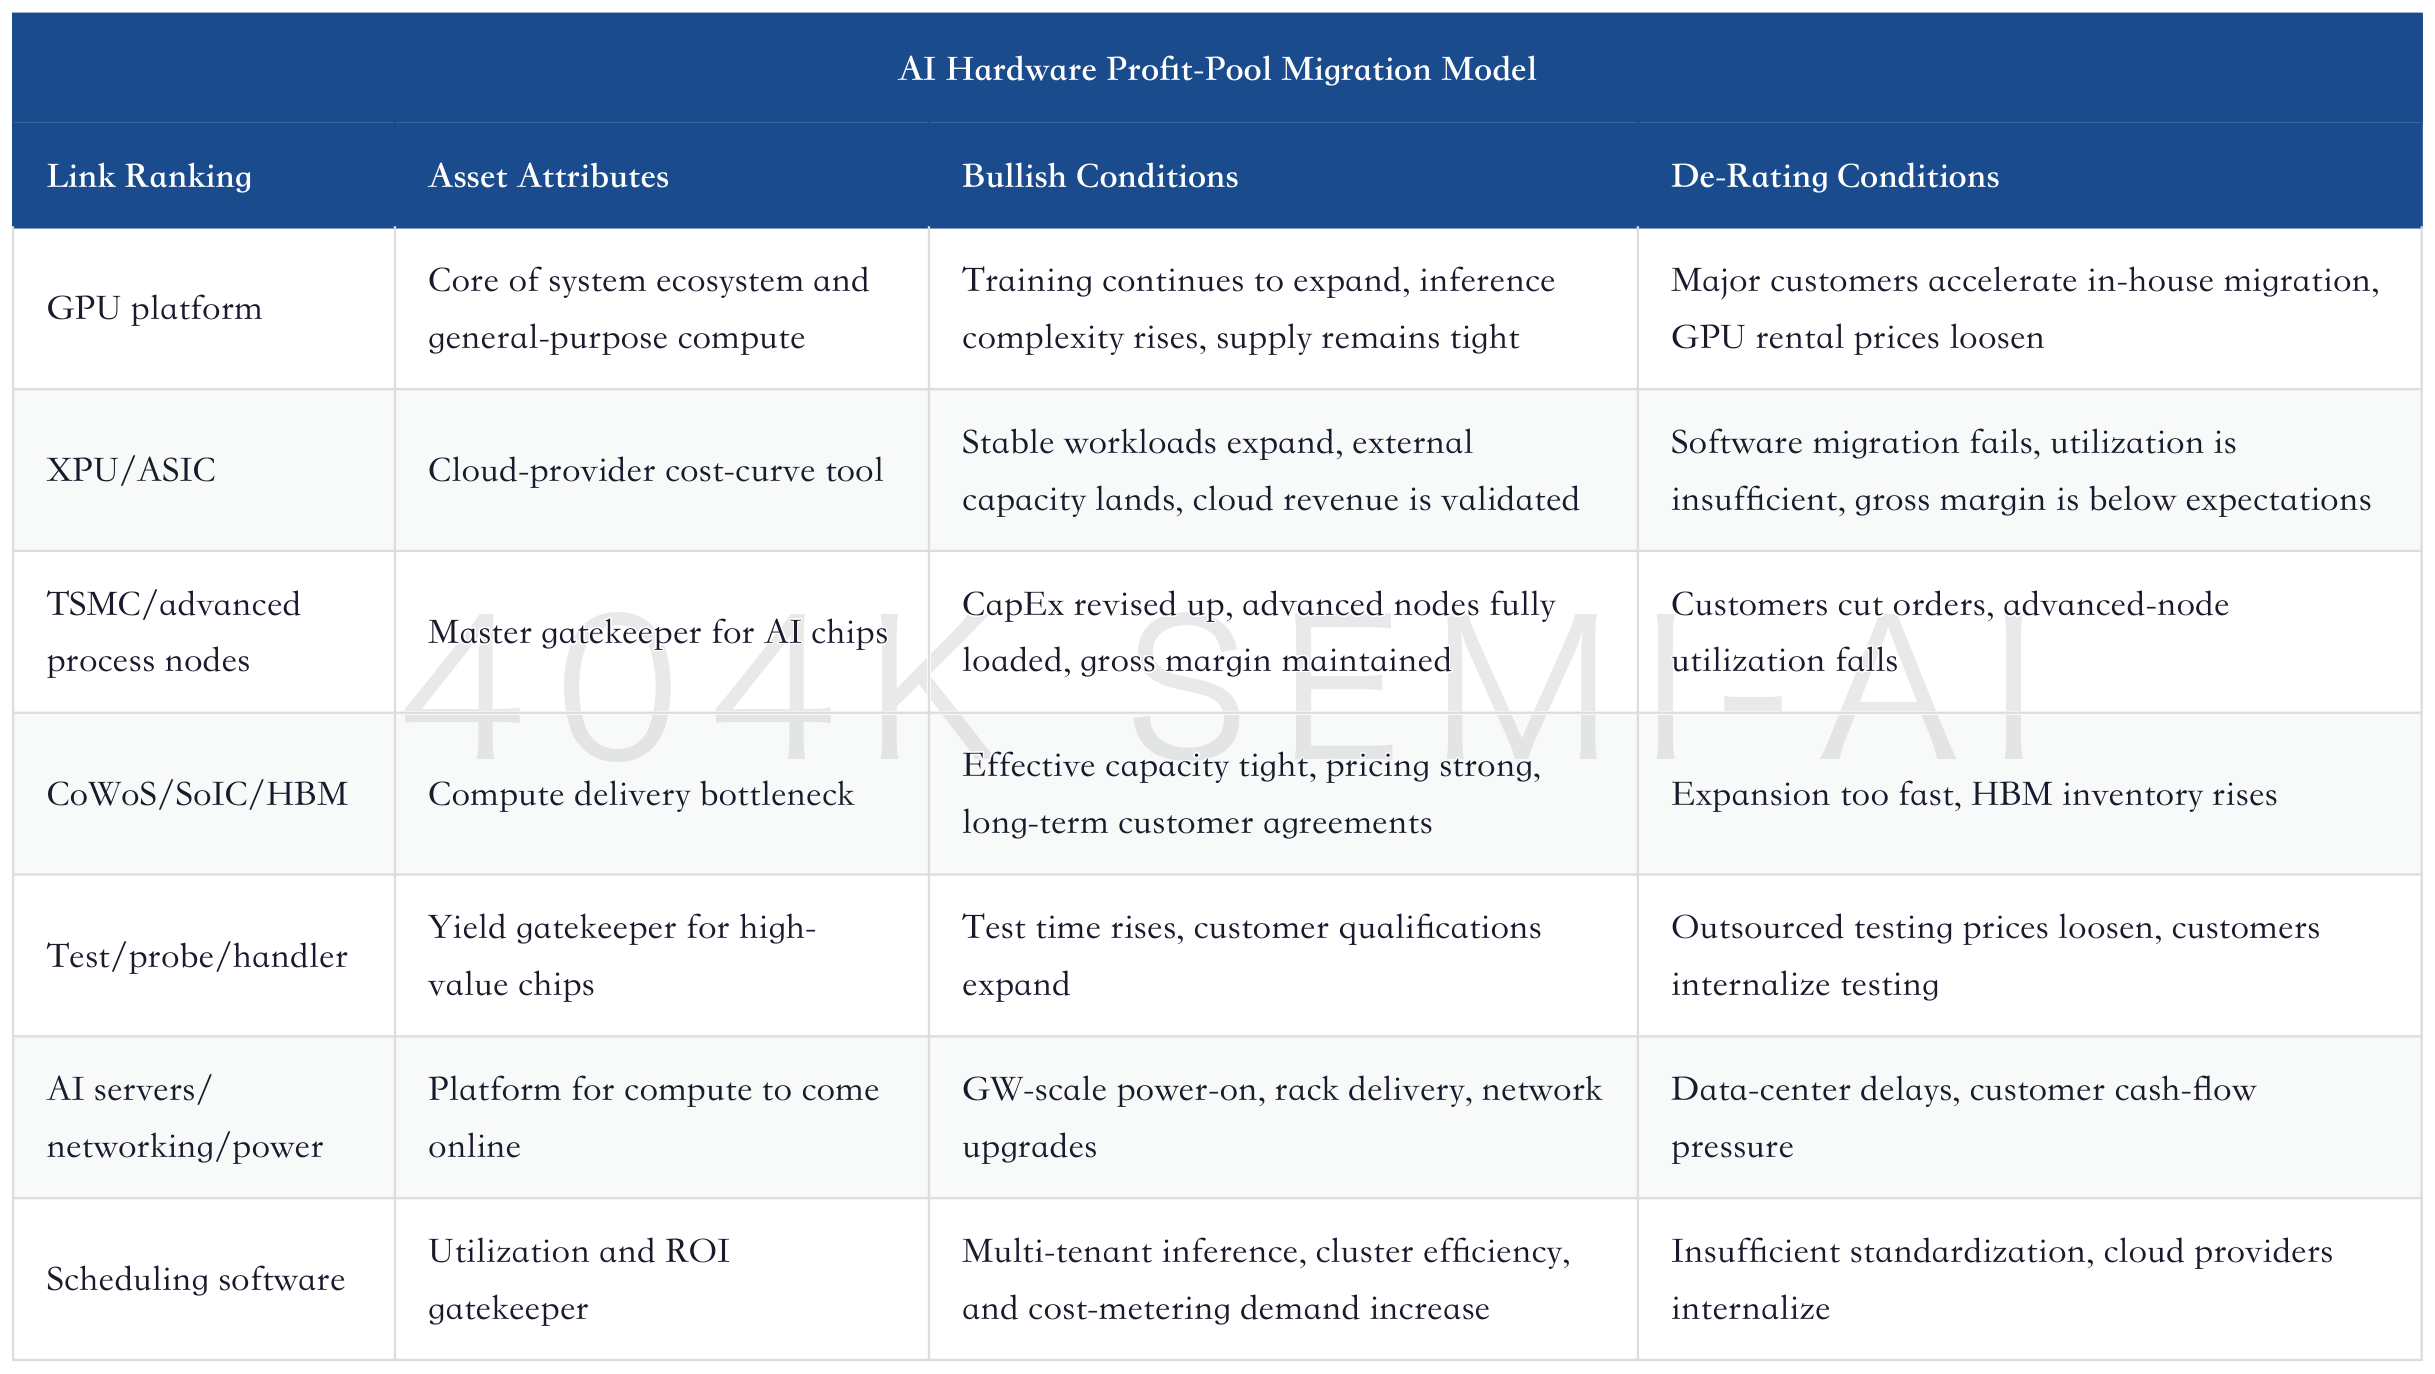
As AI capital expenditure continues to expand, the market will first buy companies with the greatest revenue elasticity, then buy bottleneck assets, and finally revisit who can generate free cash flow. The GPU versus XPU divergence is exactly at the transition from the first phase to the second. Nvidia explains the surge in AI hardware revenue; TSMC and advanced packaging explain supply bottlenecks; Google TPU explains how cloud providers internalize chip economics; and data-center power and scheduling software determine the final ROI.
From an industry-chain allocation perspective, profit pools will spread along four lines.
The first line is advanced process nodes and packaging. TSMC, CoWoS, SoIC, HBM, ABF, and test equipment share a common beneficiary profile when GPUs and XPUs ramp at the same time. More GPUs benefit them; more TPUs also benefit them; more Chinese AI chips also benefit certain links. The key for these assets is judging whether supply remains tight.
The second line is the ASIC platform supply chain. Broadcom, Marvell Technology, MediaTek, and various IP, SerDes, networking, and custom-chip links will benefit from cloud providers’ in-house silicon. Cloud-provider self-development does not mean cloud providers do everything themselves; instead, it requires external ASIC capabilities and supply-chain collaboration. Broadcom’s AI ASIC and networking businesses are representative of this line.
The third line is server and rack delivery. After GPUs/XPUs enter data centers, they must become full racks, networking, power supply, liquid cooling, and operations systems. ODM/OEMs, connectors, PCBs, CCL, power supplies, liquid cooling, racks, and data-center engineering firms will absorb changes in chip platforms. If AI chip procurement moves from single cards to rack-scale delivery, customer qualification and delivery capability in these links will become more valuable.
The fourth line is compute services and software scheduling. End customers do not pay for chips; they pay for usable compute and application outcomes. Given the same number of GPUs, utilization, scheduling efficiency, network congestion, storage throughput, and failure recovery determine true cost. Over the long term, whoever can increase token output per watt will survive hardware depreciation pressure.
How Much Is 1MW of Compute Worth: How Data Centers and Neoclouds Turn Power, GPUs, and Financing into Cash Flow
This ranking also explains why many “second-tier” companies have rallied sharply in the AI trade. The reason is often that a specific production link has suddenly become a prerequisite for customer revenue, rather than that the company has AI in its name. Valuation elasticity in the AI hardware chain often comes from bottlenecks being harder than customers expected and lasting longer than the market expected.
10. The Shared Signal from TSMC and Google: Still a Buildout Phase Before 2028
TSMC and Google appear to sit on opposite sides of the market, one on supply and the other on demand, but the two sets of materials point to the same time window: 2026-2028 remains an AI infrastructure buildout phase. TSMC’s CapEx, advanced-node roadmap, and packaging expansion show that chip supply needs to schedule capacity in advance for major customers; Google’s compute capacity, external TPU sales, and upward cloud revenue revisions show that cloud providers are still converting AI compute into future revenue.
If the period before 2028 is still a buildout phase, investment judgment needs to track two tables at the same time: a CapEx table and a revenue conversion table. The CapEx table tells us where supply-chain orders will land. The revenue conversion table tells us whether those investments can be absorbed by customer demand. Looking only at CapEx can overestimate the length of the cycle, while looking only at revenue can underestimate the advance profitability of the supply chain.
