
目录
Executive Summary
The Individual GPU Is No Longer the Right Unit of Analysis
Tiered HBM Configurations: Using Less Memory to Deliver More Chips
Behind 2.664 Million CoWoS Wafers: More Than GPU Capacity Expansion
Kyber’s Delay Brings the Supernode Back to Engineering Reality
38GW Brings the Chip Roadmap Back to Power and Campus Construction
ASIC Expansion Turns Testing from a Supporting Role into a Throughput Gate
From Allocation to Cash Flow: 5 Gates
Company Mapping: One Key Variable for Each Link
Through 2027, Watch Only Four Sets of Evidence
The unit of competition in AI hardware has shifted from the individual GPU to the complete, power-ready system. Tiered HBM configurations, CoWoS expansion, rack delays, and 38GW of implied power demand represent four distinct constraints across memory, manufacturing, engineering, and electricity.
Executive Summary
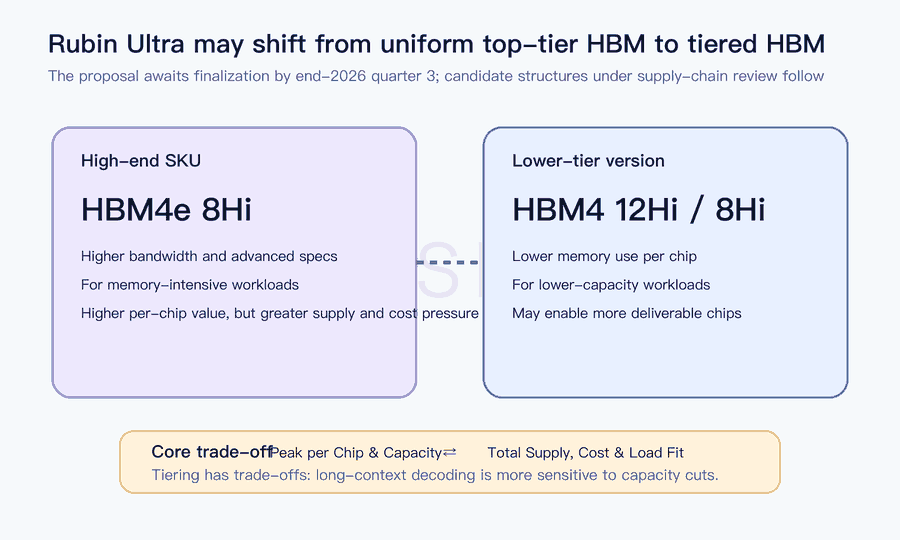
Rubin Ultra may adopt tiered HBM configurations. The high-end version could use HBM4E 8Hi, while lower-tier versions could use HBM4 12Hi or 8Hi. A final decision is expected by the end of 3Q26. The objective is straightforward: reserve scarce HBM for workloads that are most sensitive to memory capacity and bandwidth.
The cost of tiering depends on the workload. Prefill depends more heavily on parallel compute and bandwidth, while long-context decoding is more constrained by KV cache and memory capacity. Whether lower-spec SKUs can expand supply will depend on the ability of scheduling, quantization, and tiered storage to offset the performance loss.
2027 allocations are substantial, but execution matters more. The report’s model implies 2.664 million CoWoS wafers, 33.996 million chips, and 38GW of chip-level power demand. Yields, testing, rack certification, and data-center energization will determine how much is ultimately delivered.
Each company must be assessed against its own bottleneck. For memory vendors, the key variables are aggregate bit demand and product pricing; for TSMC, effective CoWoS capacity; for KYEC, test duration and utilization; for Broadcom and MediaTek, whether design share converts into volume-production revenue; and for PCB, liquid-cooling, and power suppliers, system certification and volume-delivery capability.
The Individual GPU Is No Longer the Right Unit of Analysis
AI hardware value was previously estimated using “GPU shipments × average selling price.” That formula now omits five essential inputs: HBM, CoWoS, testing, racks, and power. GPU volume production creates theoretical compute capacity; that capacity only comes online once every stage of the delivery chain is complete.
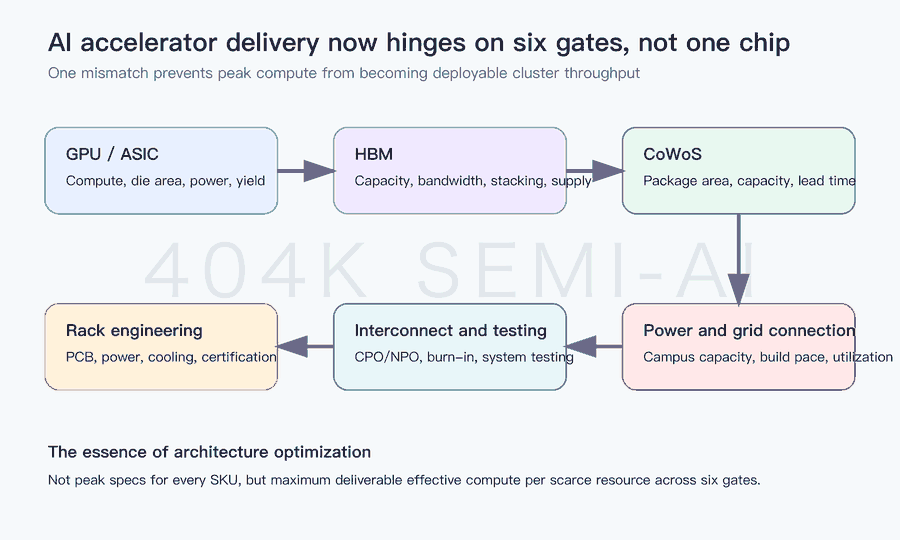
The sequence of these six gates is clear: HBM determines the available specifications; wafer fabrication and CoWoS create the packaged chip; testing screens for qualified units; PCBs, interconnects, and liquid cooling integrate the chips into racks; and the data center completes energization. If any stage falls behind, upstream output may become inventory, work in progress, or deferred revenue.
Our previous research on Rubin racks showed that memory, PCBs, power systems, and liquid cooling are increasing per-rack value beyond the GPU itself. This report advances the analysis by one question: when the highest-end configuration cannot be replicated indefinitely, how will tiering change volumes, pricing, and profitability across the supply chain? For background, see Revaluing the Rubin Rack: As the GPU Share Falls to 51%, AI Hardware Value Is Shifting Toward Memory, PCBs, Power, and Liquid Cooling—Who Captures the Incremental Growth?.
Tiered HBM Configurations: Using Less Memory to Deliver More Chips
Under the candidate Rubin Ultra configurations, the high-end version would use HBM4E 8Hi, while lower-tier versions would use HBM4 12Hi or 8Hi. “8Hi” refers only to the number of stacked layers and does not by itself define the overall GPU tier. Generation, interface speed, stack count, total capacity, and system design jointly determine final performance. The more advanced HBM4E would serve the high-end version, while HBM4 would support workloads with lower cost or capacity requirements.
Nvidia is considering tiering for two reasons. First, HBM must be validated together with GPU packaging, signaling, power delivery, thermals, and yields, making last-minute substitutions impossible during a shortage. Second, workloads vary in their sensitivity to memory capacity. If each lower-tier GPU uses less HBM, the same pool of memory can support more chips, while premium HBM can be reserved for training, long-context workloads, and higher-service-level inference.
The performance penalty appears primarily during decoding. Prefill can process input tokens in parallel, whereas decoding must read weights and state token by token; KV cache also expands with context length and concurrency. With less capacity, the system may need to reduce batch sizes, shorten context windows, increase cross-GPU communication, or move state to slower storage tiers, ultimately sacrificing latency, throughput, or energy efficiency.
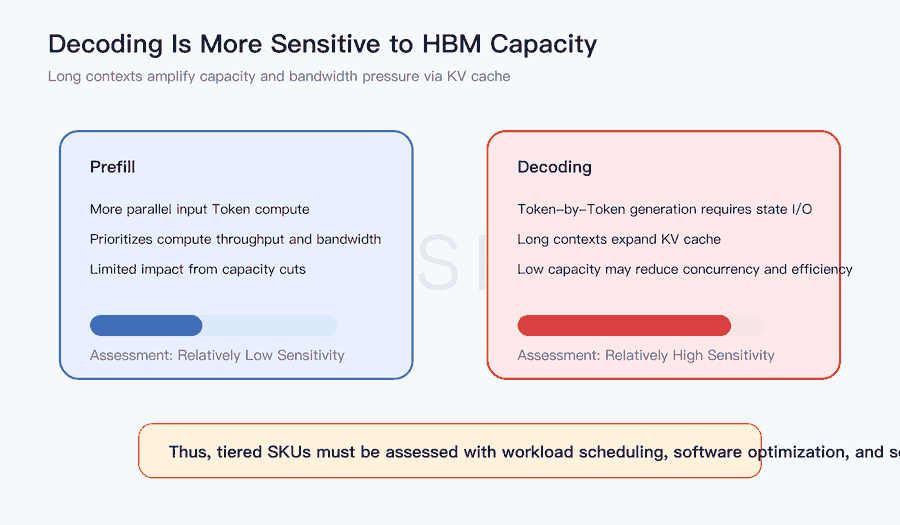
Software will determine whether lower-spec SKUs are viable. Cloud providers must allocate hardware by model, context length, and service level, while KV-cache compression, quantization, tiered storage, and batching can reduce HBM consumption per workload. HBM savings translate into greater supply only if effective tokens per dollar and per watt increase.
Tiering may therefore change the product mix between HBM4E and HBM4 before it changes the overall direction of HBM demand. Aggregate demand depends on both the reduction in memory capacity per chip and the increase in chip volumes. For the historical framework, see The Memory Tax Has Arrived: How AI Is Turning HBM, DRAM, and NAND into Global Macroeconomic Bottlenecks.
Behind 2.664 Million CoWoS Wafers: More Than GPU Capacity Expansion
The report’s bottom-up 2027 model is aggressive: 2.664 million CoWoS wafers, implying 33.996 million GPUs, CPUs, and ASICs and 48.618 billion Gb of HBM demand. The compute chips themselves would consume approximately 2.119 million wafers, corresponding to US$58.798 billion in wafer revenue. Together, these four figures imply simultaneous expansion in compute wafers, memory, and advanced packaging. The AI supply chain is no longer driven by GPUs alone.
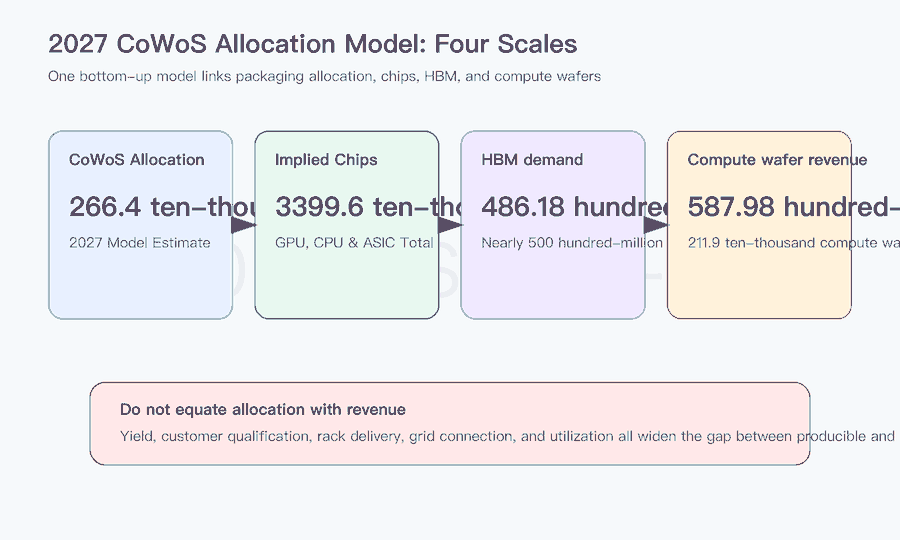
These figures should not be treated directly as revenue forecasts. First, an “allocation” represents intended capacity secured by customers after negotiations and supply-chain checks; it does not mean that every wafer will ultimately be started. Second, chip volumes depend on the number of packages supported by each CoWoS wafer, which varies significantly by product size, yield, and design. Third, HBM demand depends on the number and capacity of stacks per chip. If Rubin Ultra adopts tiered specifications, actual demand could diverge from the model’s current assumption of a uniform configuration. Finally, completed compute wafers must still pass through packaging, testing, rack integration, and deployment, so revenue recognition may not align with the allocation year.
Even after incorporating these constraints, 2.664 million wafers remains highly significant: it defines the upside scenario for which the supply chain must prepare. Customers concerned about future capacity availability often secure CoWoS, HBM, and wafer supply in advance, while suppliers respond to strong demand indications by expanding capacity and ordering equipment. Even if final shipments fall short of allocations, the competition for capacity will still affect pricing, lead times, and capital expenditure. Conversely, if allocations grow much faster than rack deliveries and data-center energization, inventory and capacity utilization will become the principal warning signals in 2H27.
