
Deep Dive on the AI Hardware Ledger: Servers at $473bn, with 1.6T Switches, DCI, and AEC Revised Up in Tandem
目录
Too Long; Didn’t Read
I. What JPM’s Model Really Adds Is the “AI Hardware Ledger”
II. Servers Remain the Entry Point: $473 Billion Is Not the Peak, but the Starting Point of the AI Ledger
III. Data-Center Ethernet: 800G Peaks, 1.6T Takes Over, and 3.2T Opens the Back-End Slope
IV. AI DC Switches: Ethernet Takes the Incremental Growth, InfiniBand Defends the Base
V. DCI: Power Constraints Disperse Data Centers, Making Pluggable Optical Modules the Second Network
6. AEC: A Small-TAM, High-Signal Market, and Why Credo Deserves a Separate Look
7. Traditional IT Markets Are Not the Main Thread, but They Can Determine the Valuation Floor
VIII. Company and Segment Ranking: Who Converts TAM Upgrades into Profit
IX. Three Scenarios: Hardware Does Not Rise Together; It Reorders by Bottleneck
10. Follow-Up Tracking: Five Numbers Determine Whether This Master Ledger Still Holds
11. Conclusion: AI Hardware Is Moving from Single-Point Prosperity to System Budgets
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
JPM’s model pushes the AI hardware budget from GPU servers into the full networking ledger: servers, data-center Ethernet switching, DCI, and AEC are all revised upward, while 1.6T and 3.2T ports are starting to reshape market share. Over the next several years, capital will also reprice the hardware chain based on whether compute can actually be connected.
Too Long; Didn’t Read
The AI hardware trade has entered the ledger stage. JPM is not merely raising estimates for one component this time. It is revising upward four links at once: servers, data-center Ethernet switching, DCI, and AEC. 2026E server TAM rises to $473bn, data-center Ethernet switching to $46bn, DCI to $13bn, and AEC to $1.4bn. The investment implication is clear: AI capex is spreading from “buying GPUs” to “connecting GPU clusters reliably.”
Servers remain the largest entry point. JPM expects the server market to grow at a 31% CAGR in 2026-2030, reaching $1.407tn in 2030. Within that, AI servers rise from $356bn in 2026E to $1.244tn in 2030E, already determining the slope of the entire hardware ledger. The key thing for the market to track is not a recovery in general-purpose servers, but whether AI server budgets from cloud vendors, Rest of Cloud, and enterprise customers continue to be revised upward.
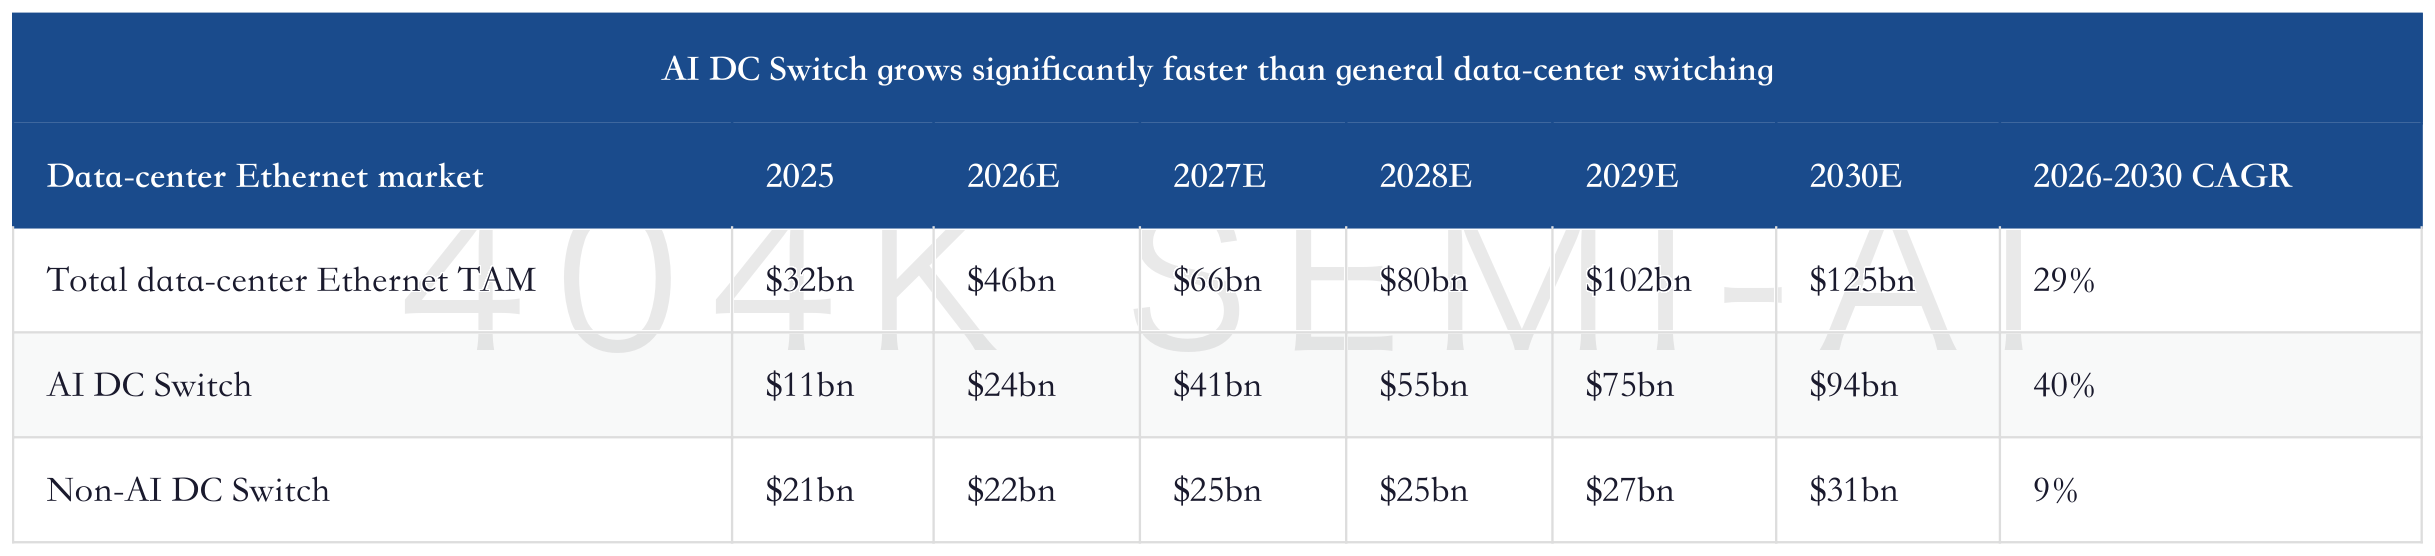
Ethernet switching is the most direct re-rating segment. Data-center Ethernet switching grows from $46bn in 2026E to $125bn in 2030E, while AI DC Switch grows from $24bn to $94bn. In JPM’s model, 800G peaks in 2027, 1.6T starts to ramp in 2026, and 3.2T takes over later in the cycle. That means share shifts among Arista, Celestica, Cisco, Nvidia, and white-box ODMs will matter more than the traditional switch cycle.
DCI turns power constraints into optical interconnect demand. Once AI data centers are constrained by power and land, deployment will become more distributed. Cross-campus and cross-city connectivity becomes a must-have, and JPM pushes the DCI market from $13bn in 2026E to $33bn in 2030E. The most elastic areas are not traditional long-haul systems themselves, but ZR/ZR+/lightweight coherent optics, pluggable optical modules, and equipment vendors that can integrate DCI into switching and routing systems.
AEC is a high-signal segment inside a small TAM. AEC chip revenue is expected to rise from $622mn in 2025 to $1.375bn in 2026E, and approach $3.655bn in 2030E. Credo still captures 78% of chip revenue share in 2025. Short-reach copper interconnect has a smaller absolute TAM than servers and switches, but it provides an early read on in-rack topology, port density, power constraints, and customer qualification cadence.
This cycle’s ranking depends on where the bottleneck sits. The first layer is compute systems and network architecture, where Nvidia, Broadcom, Arista, and Cisco determine closed-loop versus open-network paths. The second layer is delivery leverage, where Celestica, Accton, Dell, Super Micro Computer, and Hewlett Packard Enterprise benefit from demand but also absorb gross-margin pressure. The third layer is the physical layer, where optical modules, PCB/CCL, connectors, AEC, and retimers gain higher elasticity from port upgrades. The four numbers to watch next are AI server estimate revisions, the 1.6T shipment slope, the DCI pluggable mix, and AEC customer expansion.
I. What JPM’s Model Really Adds Is the “AI Hardware Ledger”
The value of this report is not that it once again proves AI servers are strong, but that it lays out the full networking and connectivity ledger after servers. Over the past year, the market’s most familiar narrative has been GPUs, HBM, AI servers, and optical modules. After budgets expanded from training clusters to inference clusters, investors already knew compute spending would be large. But JPM’s industry model provides a more direct framework: the real bottleneck in AI infrastructure is shifting from “whether there are GPUs” to “whether GPU clusters can be powered, switched, connected across campuses, connected within racks, and delivered as systems.”
JPM is not covering a single company, but a full hardware ledger: servers, external storage, campus switching, WLAN, data-center Ethernet, DCI, routing, broadband access, and AEC. The four markets whose growth slopes are truly being lifted by AI are servers, data-center Ethernet, DCI, and AEC. They correspond to four hardware questions: where compute comes from, how compute is switched inside the data center, how compute is interconnected across data centers, and how compute is connected reliably inside racks and nodes.
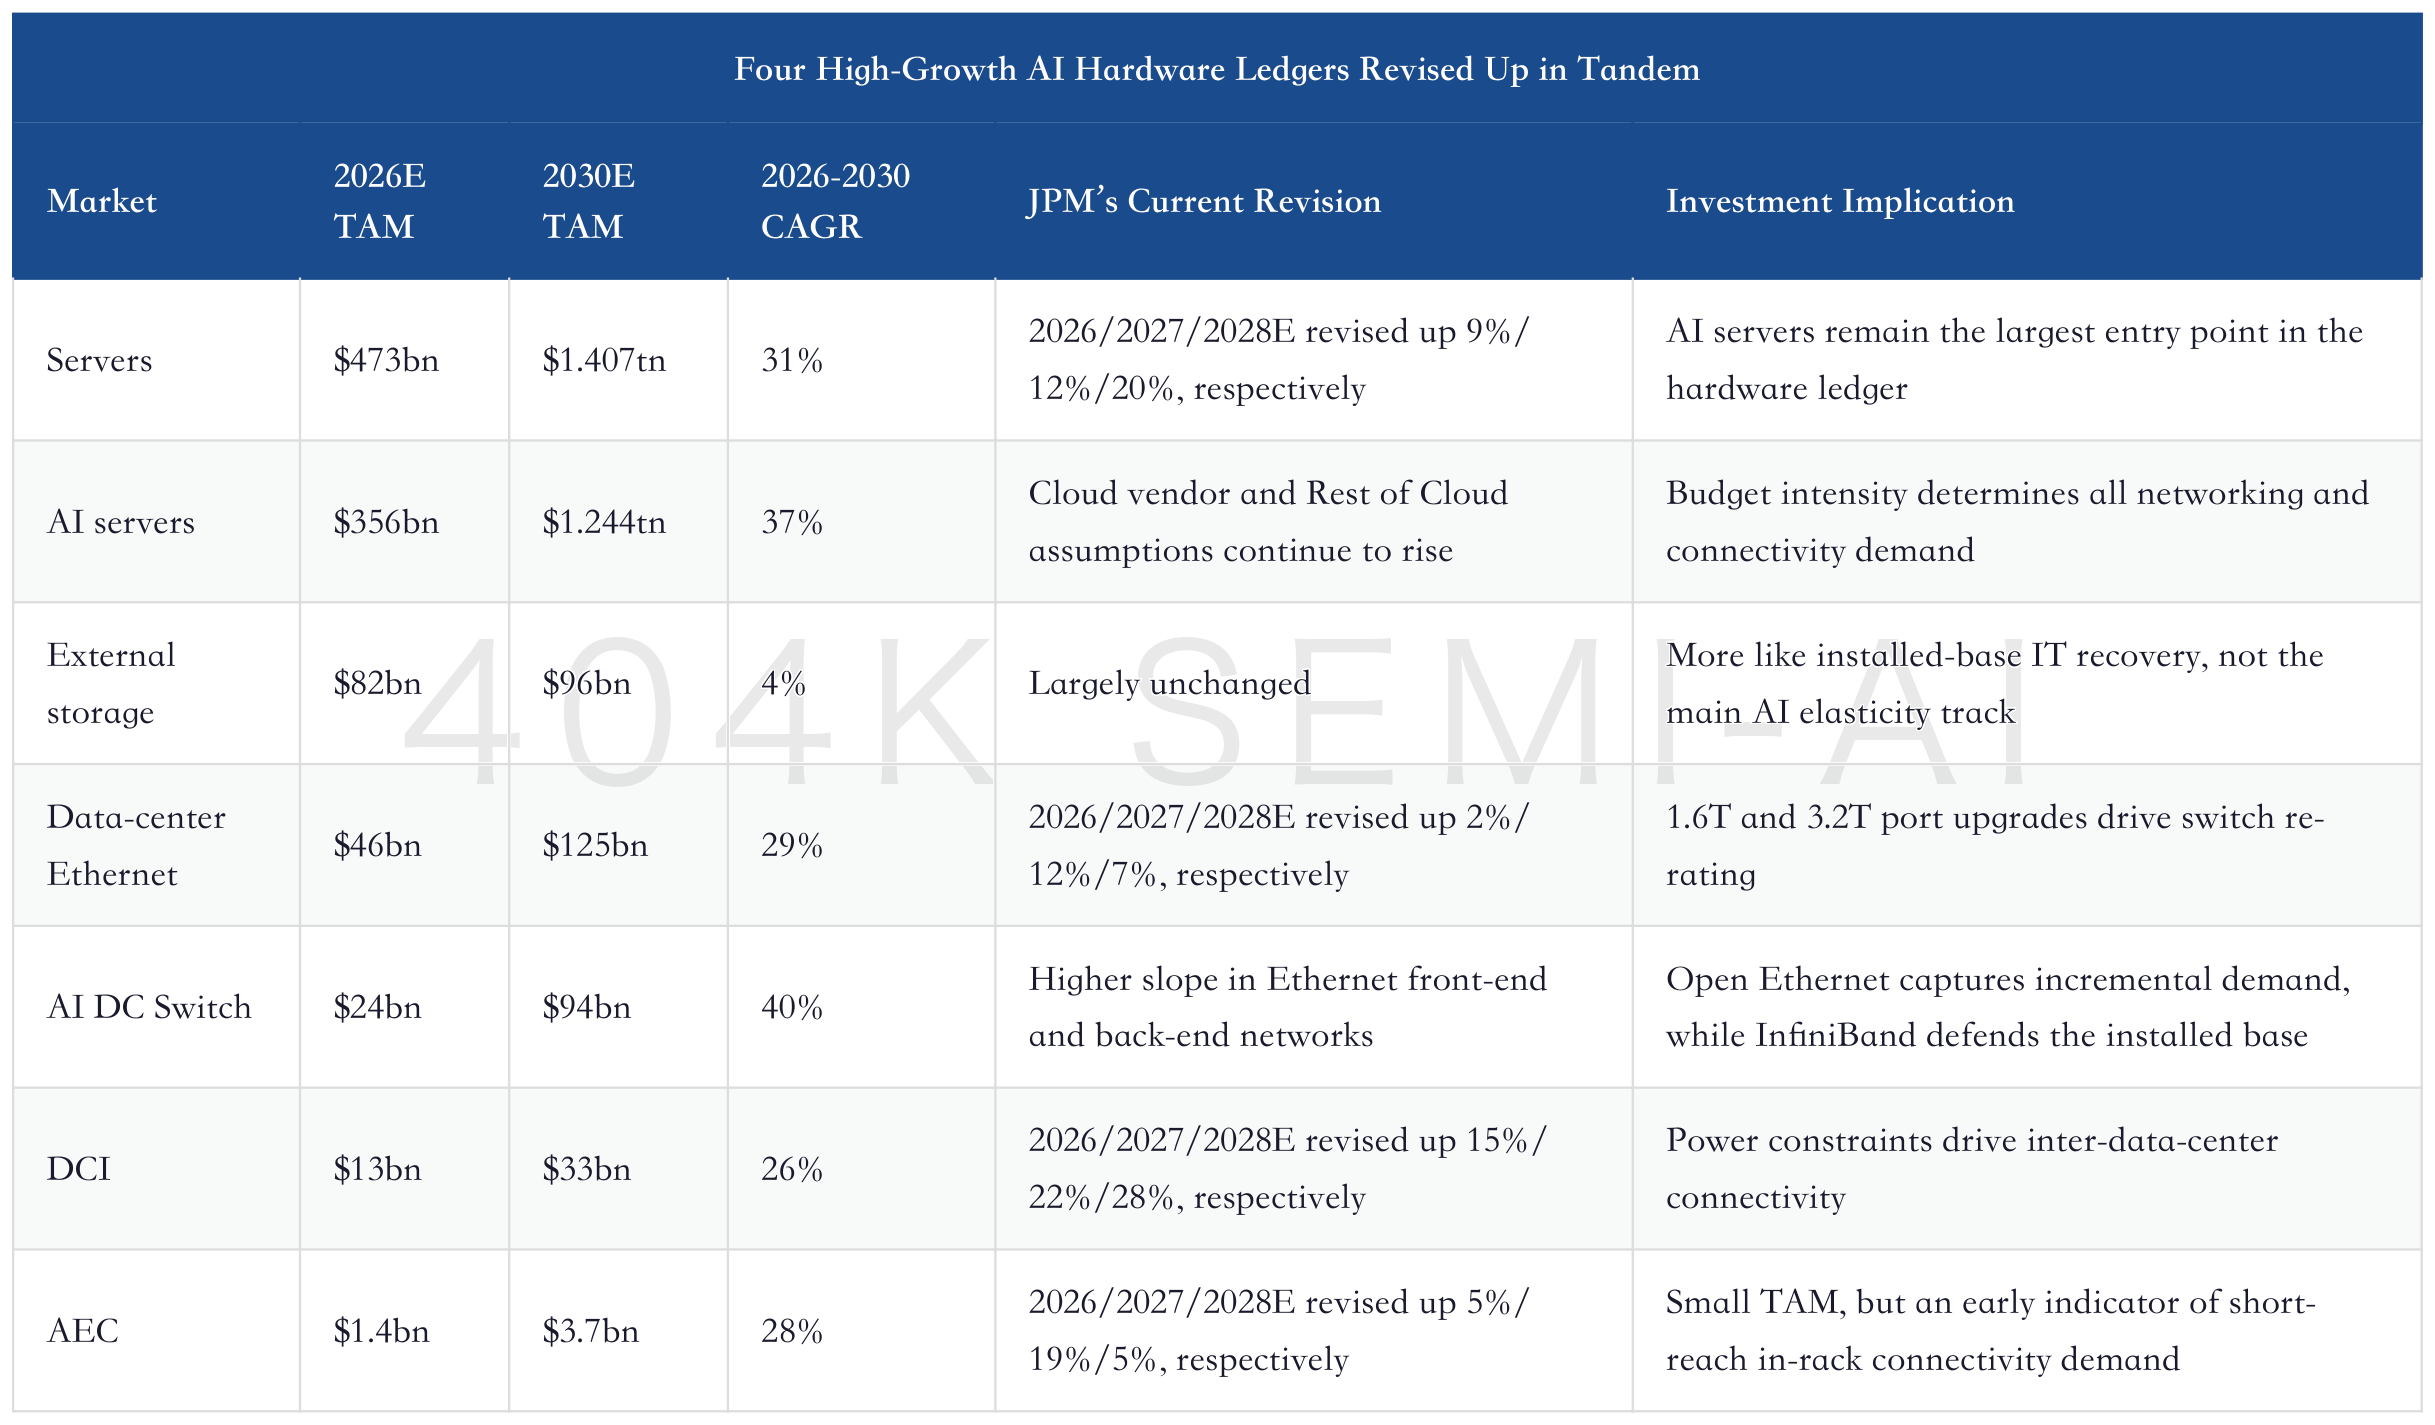
The key point in this table is “same-direction revisions.” If only servers were revised up, that would be a continuation of the AI server chain. If only switches were revised up, that would be an Ethernet substitution trade versus InfiniBand. If only AEC were revised up, that would be a single-name trade in Credo and short-reach copper interconnect. Now JPM is revising servers, Ethernet switching, DCI, and AEC upward inside the same 2026-2030 model, indicating that AI hardware investing has entered the ledger stage, where capital will reorder exposure along the bottlenecks.
There are three layers to the bottleneck ranking. The first is compute systems, where GPUs, AI servers, and systems integration determine the main CapEx entry point. The second is network switching, where front-end networks, back-end networks, 800G, 1.6T, and 3.2T determine whether clusters can scale larger. The third is physical connectivity, where optical modules, DCI, AEC, retimers, PCB/CCL, and connectors determine port density, power consumption, and reliability. The closer a segment is to the new bottleneck, the greater its valuation elasticity; the more it resembles traditional IT recovery, the lower the elasticity.
This is also how this report differs from earlier reports focused on a single networking segment. Previously, 1.6T, 3.2T, AEC, optical modules, and Ethernet switching were more local bottlenecks. This time, JPM embeds them in a broader server ledger, changing the read-through: it is not about a standalone price increase in one component, but about the fact that as AI server scale grows, networking and connectivity budgets become harder to push back toward traditional IT ratios.
At a deeper level, this ledger is answering the transmission sequence of AI CapEx. Customers first decide the scale of training and inference clusters, with server and GPU budgets confirmed first. Once server count and GPU count are determined, switch ports, front-end and back-end networks, optical modules, and in-rack connectivity enter the configuration. When a single campus can no longer keep increasing density because of power and space constraints, DCI demand moves from a network engineering issue to a capital spending issue. By putting these markets into one model, JPM is effectively acknowledging that AI hardware budgets are no longer a linear procurement process, but a systems-engineering program.
This change will affect valuation methods. Traditional hardware companies are priced more on inventory cycles, enterprise IT budgets, and product refreshes. AI hardware companies need to be priced on a “bottleneck tax.” The closer a product is to the constraint on cluster expansion, the more likely it is to receive a higher multiple. The bottleneck tax is clearest in GPUs, while HBM and advanced packaging have already been extensively traded by the market. The next segments that should receive the bottleneck tax are switch chips, AI switching systems, pluggable optics, DCI, AEC, retimers, and high-end PCB/CCL.
This also explains why, within the same JPM model, traditional IT markets still have scale but struggle to become the main theme. Storage, WLAN, campus switching, and routing are not devoid of recovery; rather, their recovery logic differs from the logic of AI cluster expansion. The former depends on enterprise budgets and refresh cycles. The latter depends on whether cloud vendors continue to scale compute clusters, push port speeds higher, and widen campus connectivity. Capital will prefer the latter because it can bring continuous upward revisions, not merely cyclical repair.
II. Servers Remain the Entry Point: $473 Billion Is Not the Peak, but the Starting Point of the AI Ledger
Servers are the entry point of the hardware ledger, because all demand for switches, optical interconnects, and short-reach connectivity is ultimately triggered by the scale of AI servers. JPM reframes the server market from a traditional IT recovery into an AI capex ledger. 2026E is already a materially revised-up high base, and 2030E enters trillion-dollar territory. The number is large enough, but the structure matters more: the recovery in general-purpose servers no longer determines the main line; AI servers determine the slope of the subsequent networking and connectivity cycle.
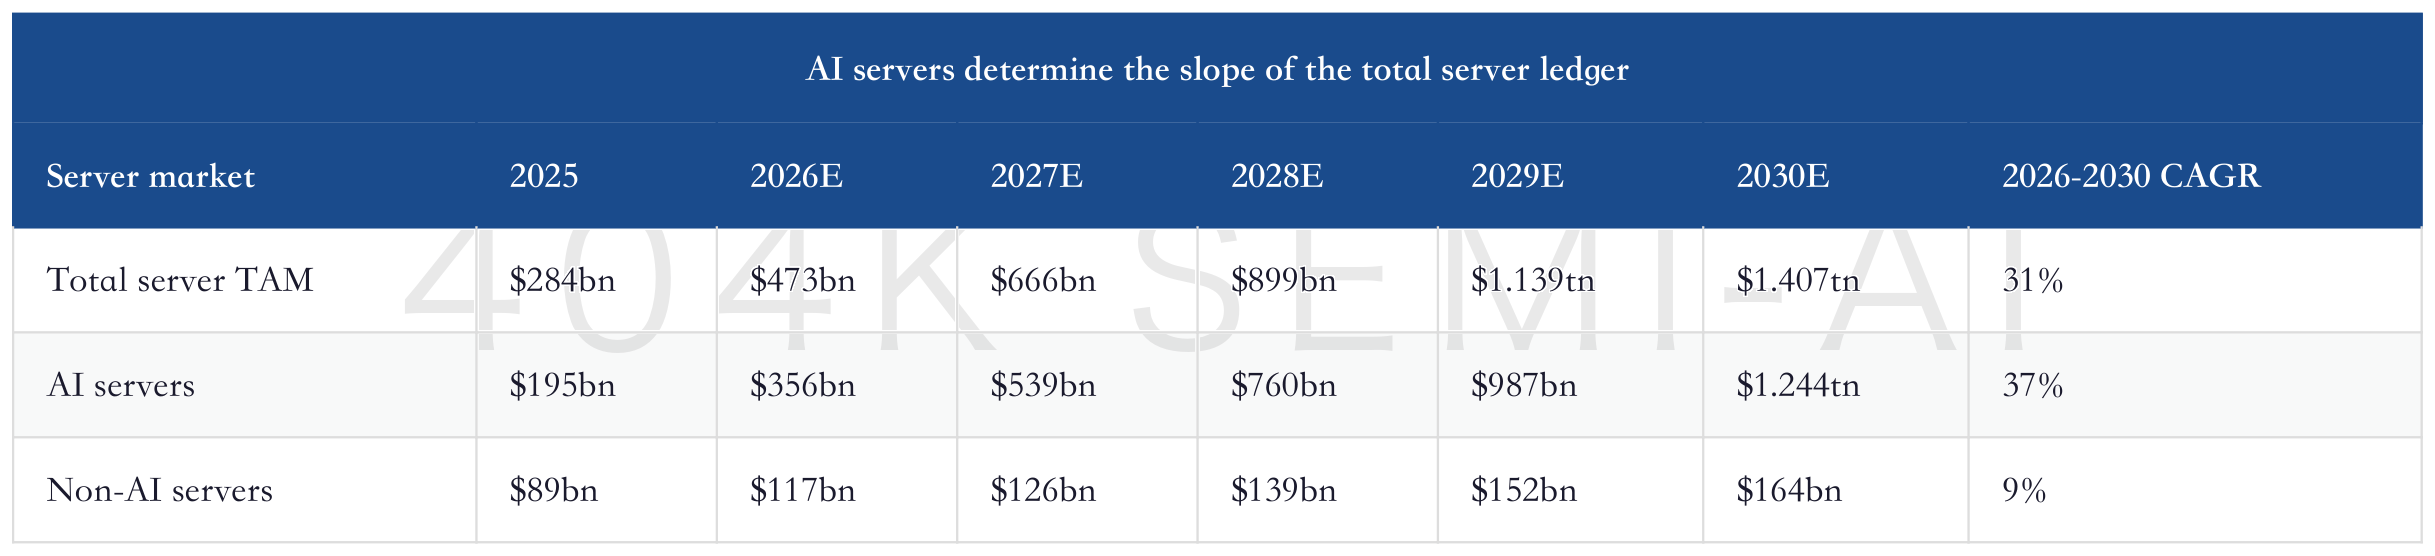
These numbers make the investment read-through very direct: if total server TAM is $473bn in 2026E and AI servers are $356bn, AI servers already account for the majority of the server market. By 2030E, the AI server mix rises further. Traditional servers look more like the chassis; AI servers are the slope.
One point the market may easily underestimate is that the AI server customer base is broadening. Early AI server budgets mainly came from the leading US cloud providers. Subsequent incremental demand comes from three directions: the US Top 5 cloud providers continuing to expand training and inference clusters; Rest of Cloud expanding alongside large models and sovereign AI demand; and China’s Top 3 cloud providers maintaining high growth under domestic AI demand and supply-chain constraints. In JPM’s model, both Rest of Cloud and China’s Top 3 cloud providers grow very quickly, which means AI server demand is not a single-customer cycle but a synchronized uplift in multi-customer budgets.
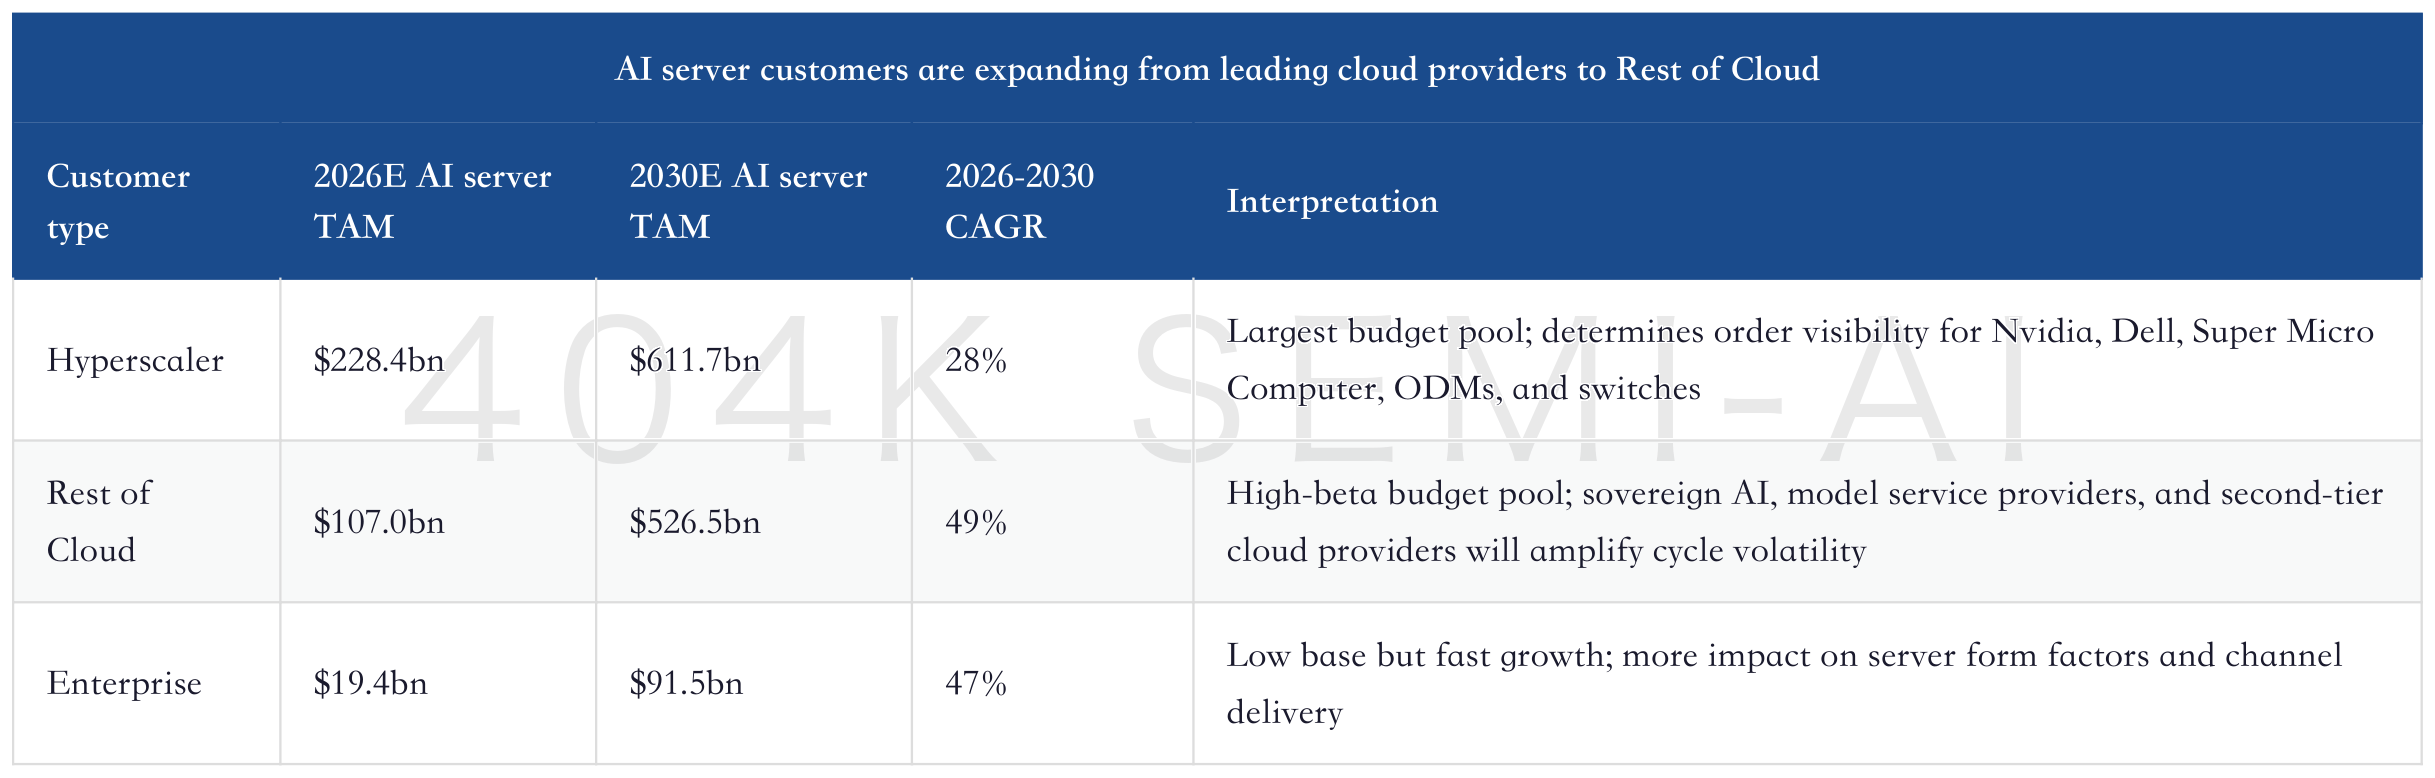
The investment debate in the server chain is not whether demand exists, but who can convert demand into profit. AI servers have high ASPs, complex configurations, and tight delivery windows, giving clear revenue-recognition leverage. But gross-margin and working-capital pressure will rise at the same time. System integrators winning large orders does not mean margins expand in parallel; ODMs and branded server vendors absorbing scale must also contend with component supply, customer bargaining power, warranty obligations, and cash-flow pressure.
This is why JPM assigns high growth to the server market, but investment ranking cannot be based only on revenue growth. Nvidia remains the strongest player in the AI server value chain because the closed loop across GPUs, systems, networking, and software drives customer lock-in. Dell, Super Micro Computer, Hewlett Packard Enterprise, and ODMs capture delivery leverage, with high beta but margins more affected by customer mix. Network white-box and system manufacturers such as Celestica and Accton could see more concentrated beta if they also benefit from AI switch and server-networking orders.
Server Industry Re-rating: From CPU Platforms to AI Acceleration Systems
The falsification conditions for the server segment are also clear. First, if cloud capex shifts from “continued upward revisions” to “reallocation within the existing structure,” AI server TAM will be the first item the market marks down. Second, if inference demand cannot absorb the incremental supply after training clusters are built, server orders will move from long-term certainty to phase-specific pull-ins. Third, if system integrators revise revenue up while gross margins continue to decline, capital markets will reprice them from AI beneficiaries into low-margin manufacturing stocks.
The real challenge in servers is profit capture. AI server revenue can easily be pulled up by orders, but the profit structure depends on three things. First, whether customers hand more system-design authority to suppliers, or treat suppliers only as contract manufacturers and delivery windows. Second, whether key components are customer-designated purchases; if CPUs, GPUs, HBM, NICs, and power supplies are all controlled by customers, the remaining profit pool for server vendors becomes thinner. Third, whether the delivery cadence is stable; if orders are concentrated, acceptance is complex, and warranty responsibility is heavy, revenue upgrades may come with cash-flow pressure.
Therefore, the server chain cannot be assessed only by “who has the fastest revenue growth.” Platform suppliers such as Nvidia control architecture, with stronger margins and customer lock-in. Branded server vendors and ODMs control scale delivery, with more direct revenue beta, but every order must pass through procurement, inventory, prepayments, warranty, and customer negotiation. White-box networking vendors that also participate in AI switches and adjacent server systems will have more beta than pure server assemblers, because they touch the scarcer networking bottleneck.
Another easily overlooked point: as AI server customers broaden from leading cloud providers to Rest of Cloud, total demand rises, but volatility also rises. Leading cloud providers have more transparent procurement cadences and more mature architectures and supply chains. Rest of Cloud demand may be more urgent, more fragmented, and more dependent on financing and sovereign AI projects; order releases can be highly elastic, while budget contraction can also come faster. For server vendors and ODMs, this means they must distinguish customer quality more strictly even as revenue is revised upward.
The best way to validate the server ledger is not to wait for annual TAM updates, but to track quarterly order language. Whether cloud providers continue to raise AI capex, whether server vendors disclose higher AI backlog, whether ODMs see longer lead times and tighter capacity scheduling, and whether GPU platforms simultaneously increase networking and system configurations will all reflect whether the model is working earlier than a single revenue number. If these signals strengthen together, JPM’s server revisions will drive a market re-rating of switches, DCI, and AECs as well.
III. Data-Center Ethernet: 800G Peaks, 1.6T Takes Over, and 3.2T Opens the Back-End Slope
The core change in AI networking is that Ethernet switching is no longer merely a traditional data-center upgrade; it is the system bottleneck determining whether large-scale AI clusters can expand. JPM assigns growth assumptions to data-center Ethernet and AI DC Switch that are materially above traditional networking. The tables below clearly lay out the scale and slope. This is not an ordinary switch cycle, but the result of front-end and back-end networks rising together as AI cluster scale expands.
JPM’s generational assumptions are critical: 800G reaches its revenue peak around 2027, 1.6T starts ramping quickly from 2026, and 3.2T enters the model after 2027 and becomes a meaningful revenue contributor by 2030. For investors, 800G is the “current order book,” 1.6T is the “next round of ASP and share,” and 3.2T is the “back-end ceiling.” Focusing only on 800G misreads the cycle; focusing only on 3.2T ignores revenue realization over the next 12-24 months.
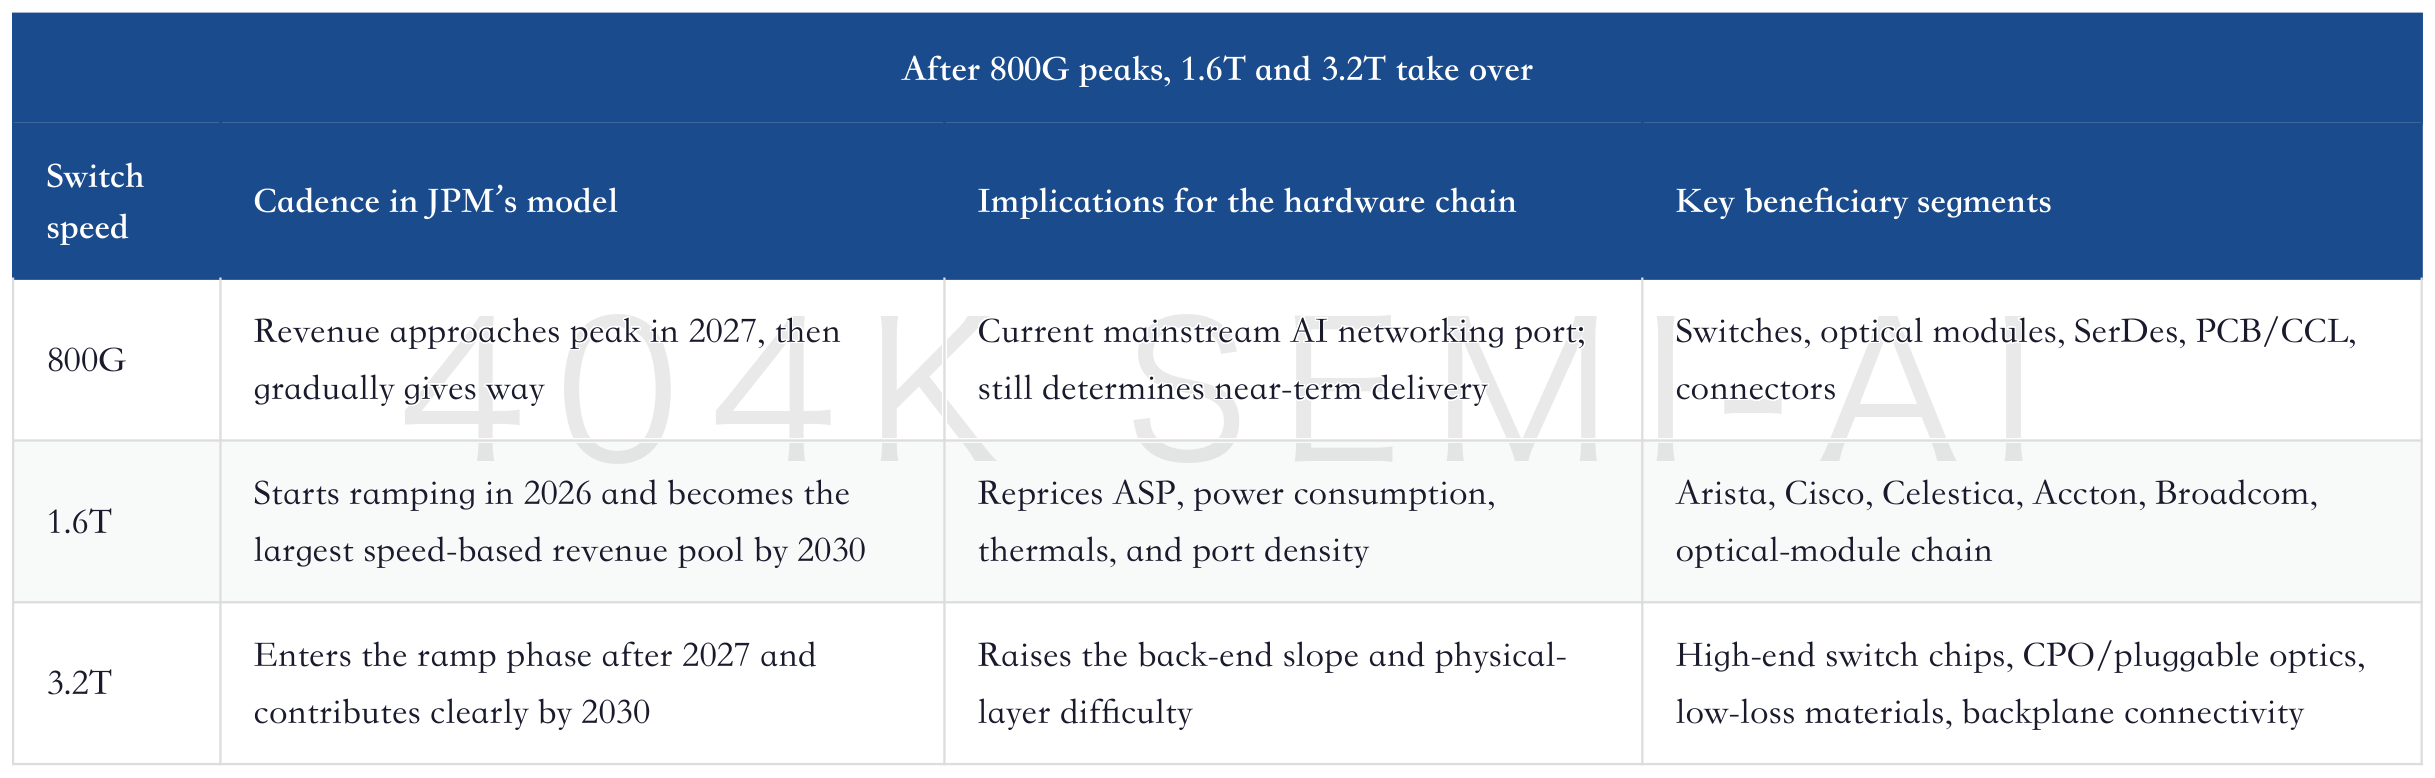
This framework explains why the valuation logic for switch companies is starting to change. Traditional switch companies are valued on enterprise IT budgets, campus-network refreshes, and channel inventory. AI switch companies are valued on GPU cluster scale, port generations, switch-chip supply, white-box delivery capability, and customer architecture choices. Arista’s strengths lie in cloud networking software, system reliability, and relationships with leading customers. Cisco’s strengths are enterprise and installed network assets. Celestica and Accton represent white-box and ODM delivery leverage. Nvidia continues to defend the AI cluster closed loop through InfiniBand and Ethernet solutions.
Nvidia, Broadcom, and Marvell Technology’s Control of AI Networking: Nvidia’s Closed Loop vs. Broadcom’s Open Networking Battle in 2026
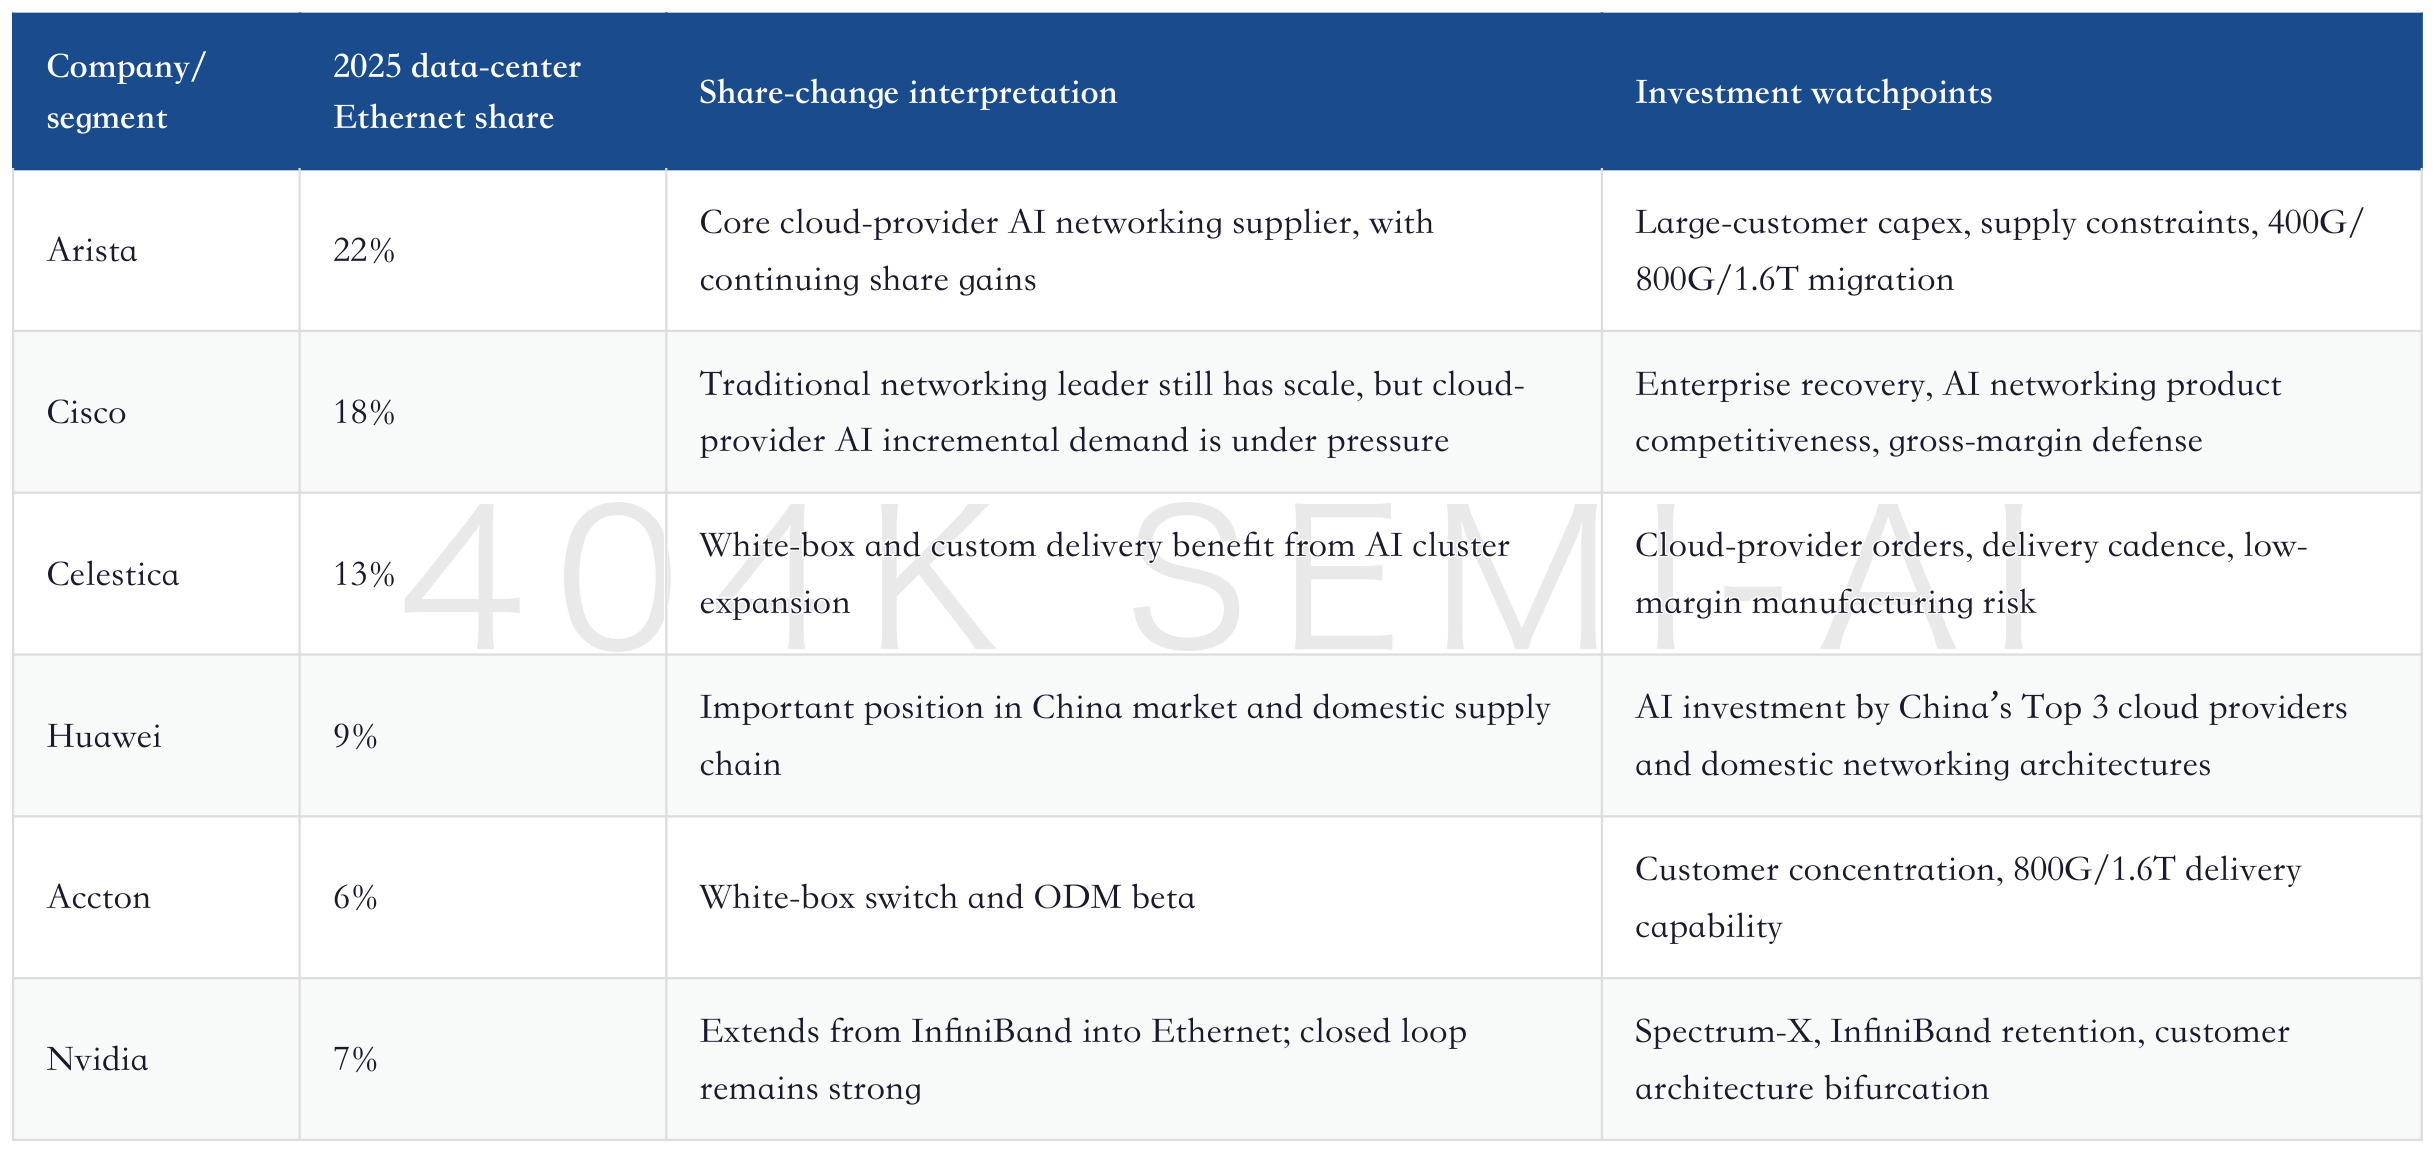
JPM’s share changes also support this line of thinking. In recent years, Cisco has lost share, while Celestica, Arista, and Nvidia have gained share, indicating that incremental orders in AI data centers are more skewed toward direct cloud-provider connections, white-box delivery, and dedicated AI networking systems. The specific shares are shown in the table; the body text retains only the conclusion.
Data-center Ethernet share is migrating toward cloud providers and the white-box chain
The falsification points for the switch chain are more specific than for servers. First, if 1.6T is delayed, the market will revise down the 2027-2028 TAM slope. Second, if customers continue to keep most back-end networking on InfiniBand, the beta for open Ethernet companies will be compressed. Third, if white-box ODMs grow revenue but margins fall short of expectations, the market will again distinguish between “order beneficiary” and “value capture.” Fourth, if GPU cluster supply is constrained, networking orders will lag and near-term inventory risk will increase.
Data-center Ethernet budgets should be stickier than traditional switch budgets. The reason is simple: AI clusters are not ordinary office networks. Packet loss, latency, congestion, and failures directly affect GPU utilization. If an expensive GPU sits idle because of a network bottleneck, the customer’s loss far exceeds the cost of switches and optical modules. As a result, AI networking budgets are usually not simply compressed into “buy cheaper equipment”; customers are more willing to pay for reliability, observability, automated operations, and mature software.
This is exactly why Arista’s valuation is above that of ordinary hardware manufacturers. It sells not just switch boxes, but a network operating system, configuration automation, and large-scale operations experience that cloud providers are willing to trust. Celestica and Accton’s beta comes from cloud-provider white-box orders, but they need to prove they are not merely low-gross-margin delivery vendors. Cisco needs to prove whether it can convert enterprise networking and security assets into incremental AI cloud networking demand, rather than only defending traditional customers. Nvidia needs to prove that Spectrum-X and the InfiniBand closed loop can continue to preserve system control as open Ethernet expands.
Switch generations will also affect physical-layer value. In the 800G era, the market is already familiar with the revenue beta of optical modules and switches. In the 1.6T era, line cards, backplanes, PCB materials, connectors, thermals, and power supplies will all become more difficult together. In the 3.2T era, signal integrity and power-consumption pressure rise further, and system design will look more like semiconductor and materials engineering than simple network equipment procurement. The further the cycle progresses, the scarcer suppliers become if they can simultaneously understand chips, optics, electrical design, thermals, and system reliability.
IV. AI DC Switches: Ethernet Takes the Incremental Growth, InfiniBand Defends the Base
What truly matters in AI DC switches is the technology mix, not simply adding up all switches. JPM breaks AI DC switches into Ethernet front-end, Ethernet back-end, and InfiniBand. The structure in the table is already clear: InfiniBand remains a mature closed-loop architecture, while Ethernet captures the main incremental growth. In particular, as both back-end networks and front-end cloud networks scale, open Ethernet will become the most important incremental market.
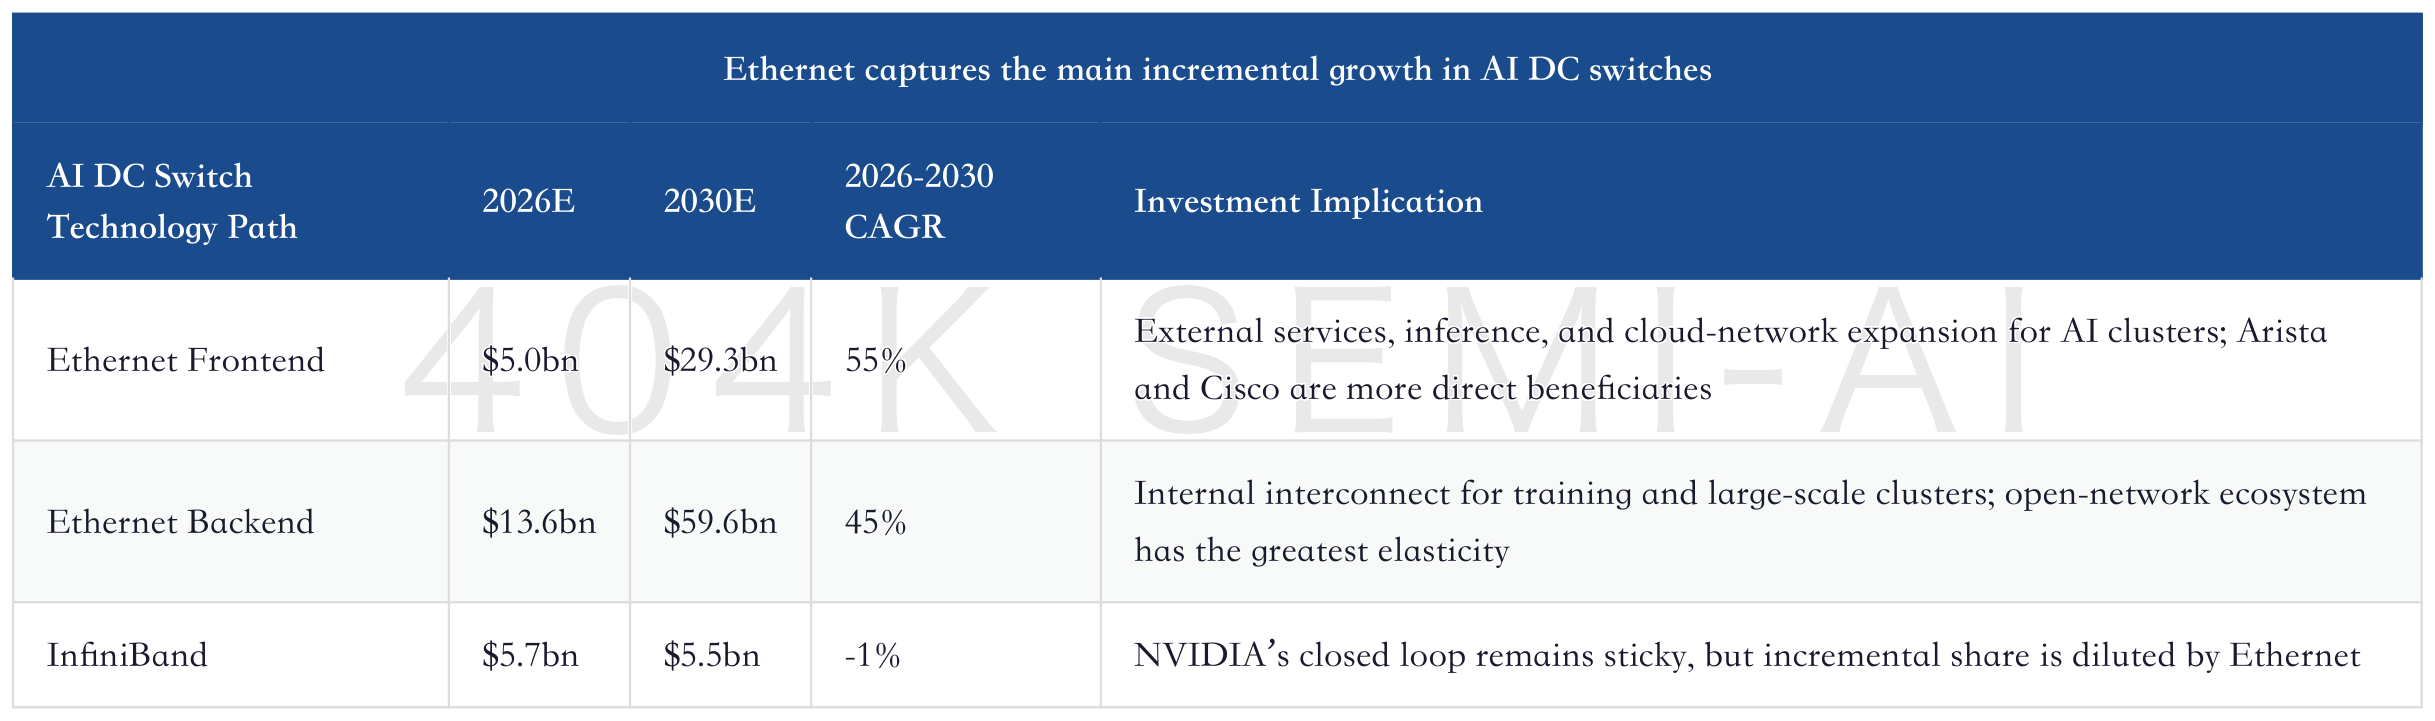
This is not a simple story of “Ethernet replacing InfiniBand.” The more accurate investment read is that InfiniBand still has strong closed-loop advantages, especially in extreme-scale training, customer software stacks, and NVIDIA’s full-stack solution. Ethernet’s advantages lie in its open ecosystem, cloud-vendor customization, supplier choice, cost structure, and multi-vendor coordination. As AI clusters become larger, customers will combine closed-loop performance with open controllability rather than make a binary choice.
Triple Validation for AI Networking: Deep Dive into Lumentum, Astera, and Arista Earnings — Optical Interconnects, PCIe Fabric, and Ethernet Switching Systems Enter Bottleneck Pricing Together
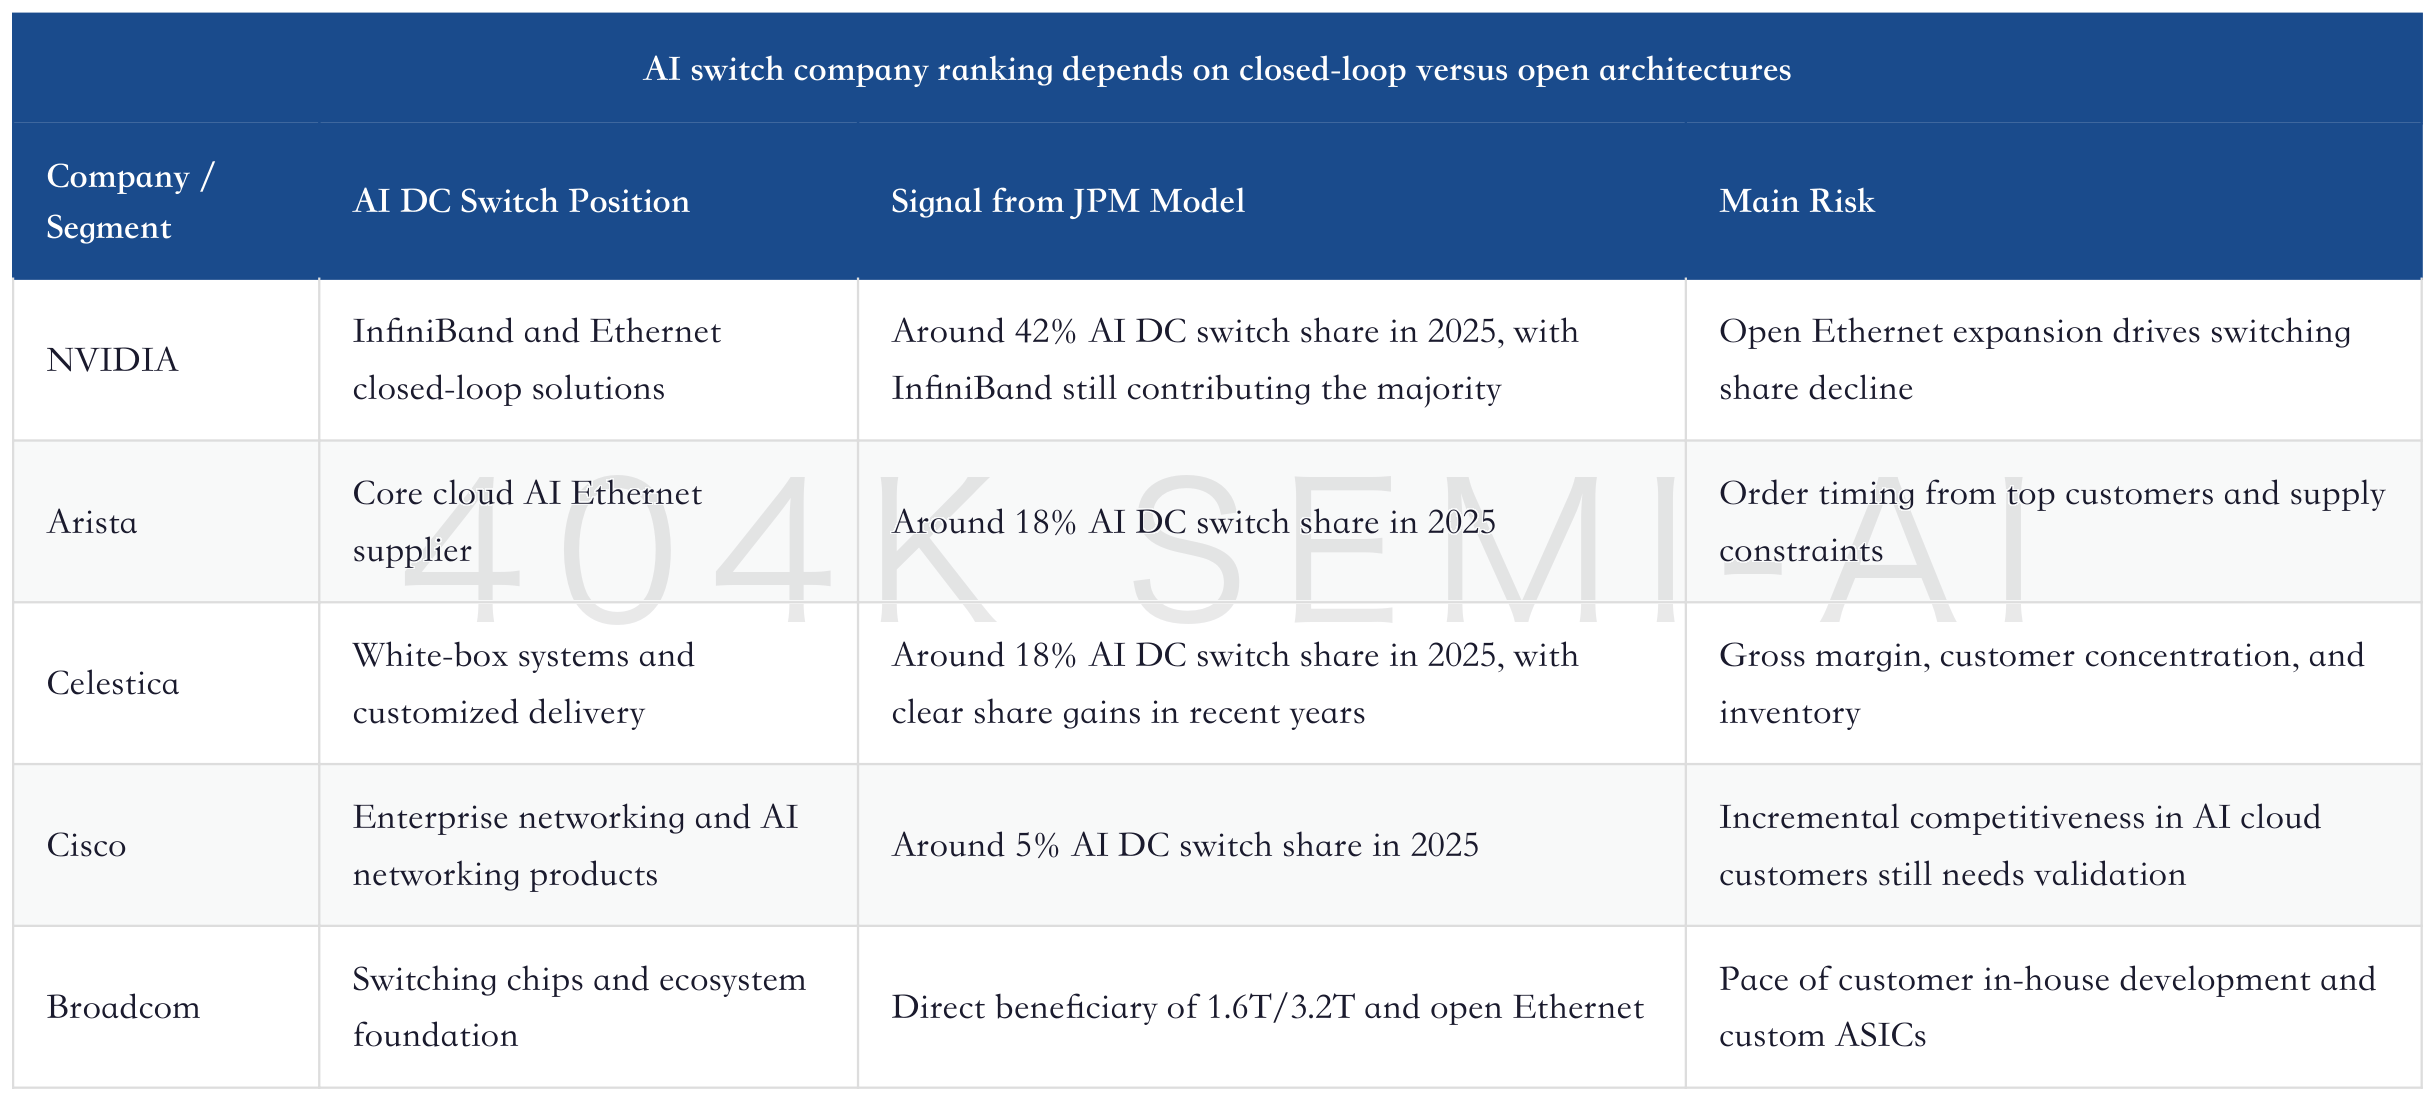
Company ranking therefore needs to be viewed through two frameworks. NVIDIA’s strength is its closed-loop AI system. Even if its InfiniBand share is diverted by open Ethernet, it can still control customer budgets through GPUs, NVLink, systems, switching, and software. Arista’s strength is its cloud networking operating system and highly reliable delivery, making it the core exposure to open Ethernet expansion. Celestica and Accton provide white-box delivery elasticity, with high revenue elasticity, but value capture depends on customer customization and margins. Cisco has advantages in enterprise and networking assets, but it must prove it can regain incremental growth in AI cloud networking.
The investment opportunity in open Ethernet is not only in complete switches, but also in switching chips, SerDes, optical modules, PCB/CCL, connectors, and system software. The reason is simple: higher port speeds raise hardware difficulty at the same time. 1.6T and 3.2T are not simply doubling the number of 800G links. They change requirements for signal integrity, thermal management, power consumption, line-card design, optical-electrical conversion, and backplane connectivity. The physical-layer supply chain will shift from a “cost item” to a key determinant of deliverability.
AI Networking Interconnect Hardware, Part V: Physical-Layer Bottlenecks in the 3.2T Era — Backplanes, Line Cards, AEC, and High-Reliability Connectivity Face Revaluation
This also explains why AI networking reports cannot focus only on optical modules. Optical modules are the most visible elasticity point, but switch generations, backplanes, connectors, PCB materials, retimers, and AECs jointly determine whether the network can run. By separating AI DC switches in this model, JPM makes the main line of network investing clearer: track generations, share, customer architecture choices, and who can turn port upgrades into stable revenue and profit.
The relationship between Ethernet and InfiniBand should also be viewed through customer organizational structure. Large-scale training clusters pursue extreme performance and mature software stacks, making customers more likely to accept NVIDIA’s closed loop. When cloud vendors have strong internal networking teams, want multi-supplier optionality, and are willing to control architecture over the long term, Ethernet becomes more attractive. This division will not end within one quarter. The real change is that incremental orders are starting to tilt toward Ethernet, while legacy clusters and extreme-scale training still leave room for InfiniBand.
For suppliers, the best position is not betting on a single architecture, but maintaining relevance in customers’ hybrid architectures. NVIDIA is strongest in GPUs and closed-loop systems. Broadcom is strongest in switching chips and the custom silicon ecosystem. Arista is strongest in cloud Ethernet systems. Cisco is strongest in enterprise and installed networking assets. Celestica and Accton have the greatest elasticity in white-box delivery. JPM’s model does not point to a single winner, but to a map of architectural competition: the more customers lean toward open Ethernet, the more Arista, Broadcom, white-box ODMs, and related physical-layer suppliers benefit; the more customers value closed-loop performance, the more NVIDIA retains stronger system-level profit.
This is also why AI DC switches look more like a platform business than ordinary switches. Port count is only the surface. The real value lies in network management, congestion control, telemetry, fault recovery, coordination with GPU cluster scheduling, and whether customers can reliably replicate deployment at scale. Whoever can help customers improve GPU utilization is not merely a hardware supplier, but part of AI infrastructure efficiency.
V. DCI: Power Constraints Disperse Data Centers, Making Pluggable Optical Modules the Second Network
The upward revision to DCI is the most easily underestimated part of this model, because it translates power constraints directly into demand for inter-data-center connectivity. AI data centers are increasingly difficult to expand indefinitely within a single campus. Power, land, cooling, and permitting will force compute to be deployed in a more distributed way. Once compute is dispersed, data centers need higher-bandwidth, lower-power, easier-to-deploy connections between them. JPM raises the DCI market from $13.0bn in 2026E to $33.0bn in 2030E, a 26% CAGR, with a significant upward revision to 2026-2028E forecasts.
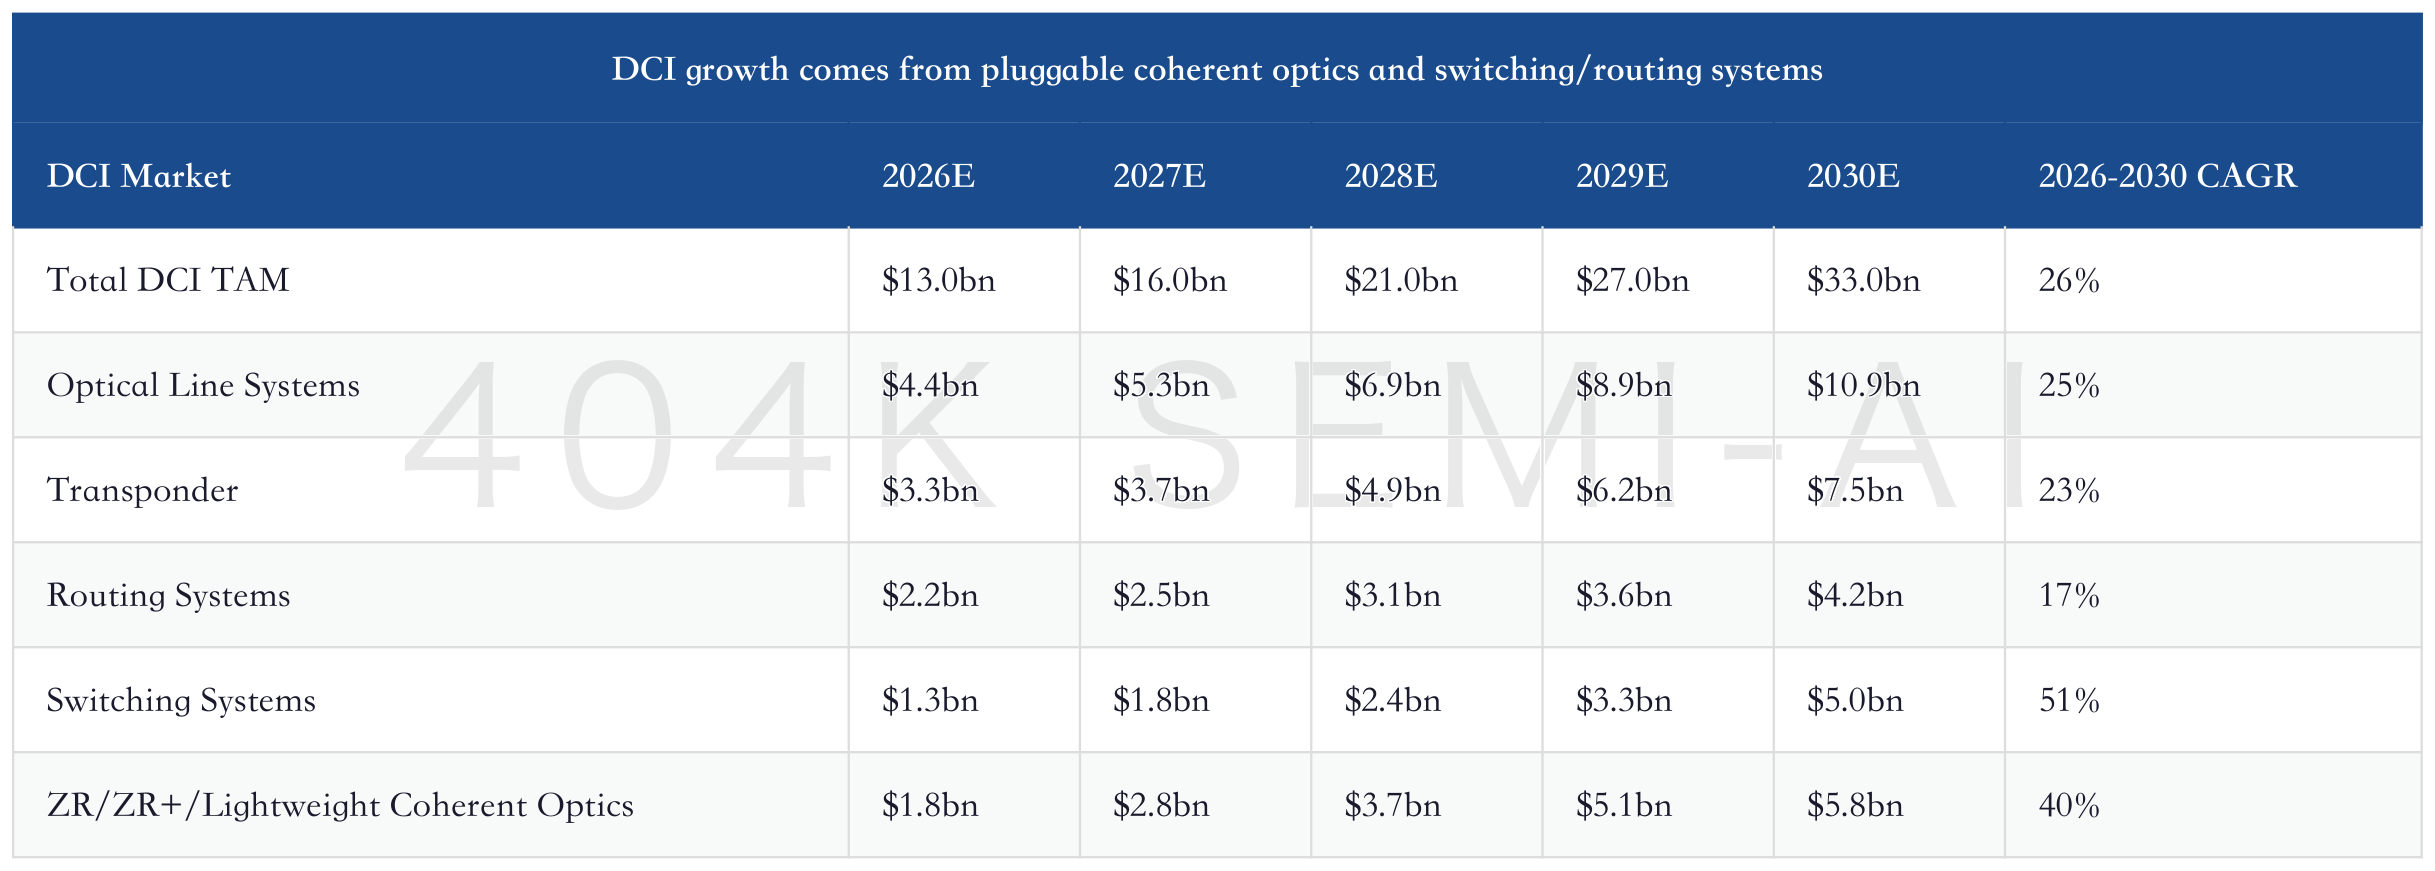
The structural shift in DCI matters more than the total size. Traditional DCI relies on optical systems, line systems, and transport equipment. Next-generation DCI increasingly connects pluggable coherent optical modules into standard switches and routers. This shift will migrate value from closed transport systems toward pluggable optical modules, switching/routing platforms, and cloud-vendor architecture design. In JPM’s model, ZR/ZR+/lightweight coherent optics maintain a 40% CAGR, while switching systems maintain a 51% CAGR. That is the signal of structural migration.
AI Optical Module Demand Revised Up Again: How Morgan Stanley’s May Report Pushes 1.6T, InP, and CPO Bottlenecks to 2028
From a company perspective, DCI divides into two chains. The first is the traditional optical system and coherent optics chain, where Ciena, Nokia/Infinera, Huawei, Coherent, Lumentum, and others benefit from high-speed coherent and line-system upgrades. The second is the switching/routing and pluggable ecosystem, where Arista, Cisco, HPE Aruba/Juniper, Broadcom, and the optical module supply chain are more likely to capture the migration to “standard platform + pluggable.” If the market focuses only on long-haul optical transport equipment, it will miss the incremental role of switches and pluggable optical modules in DCI.
The DCI value chain migrates from optical systems to pluggables and switching/routing
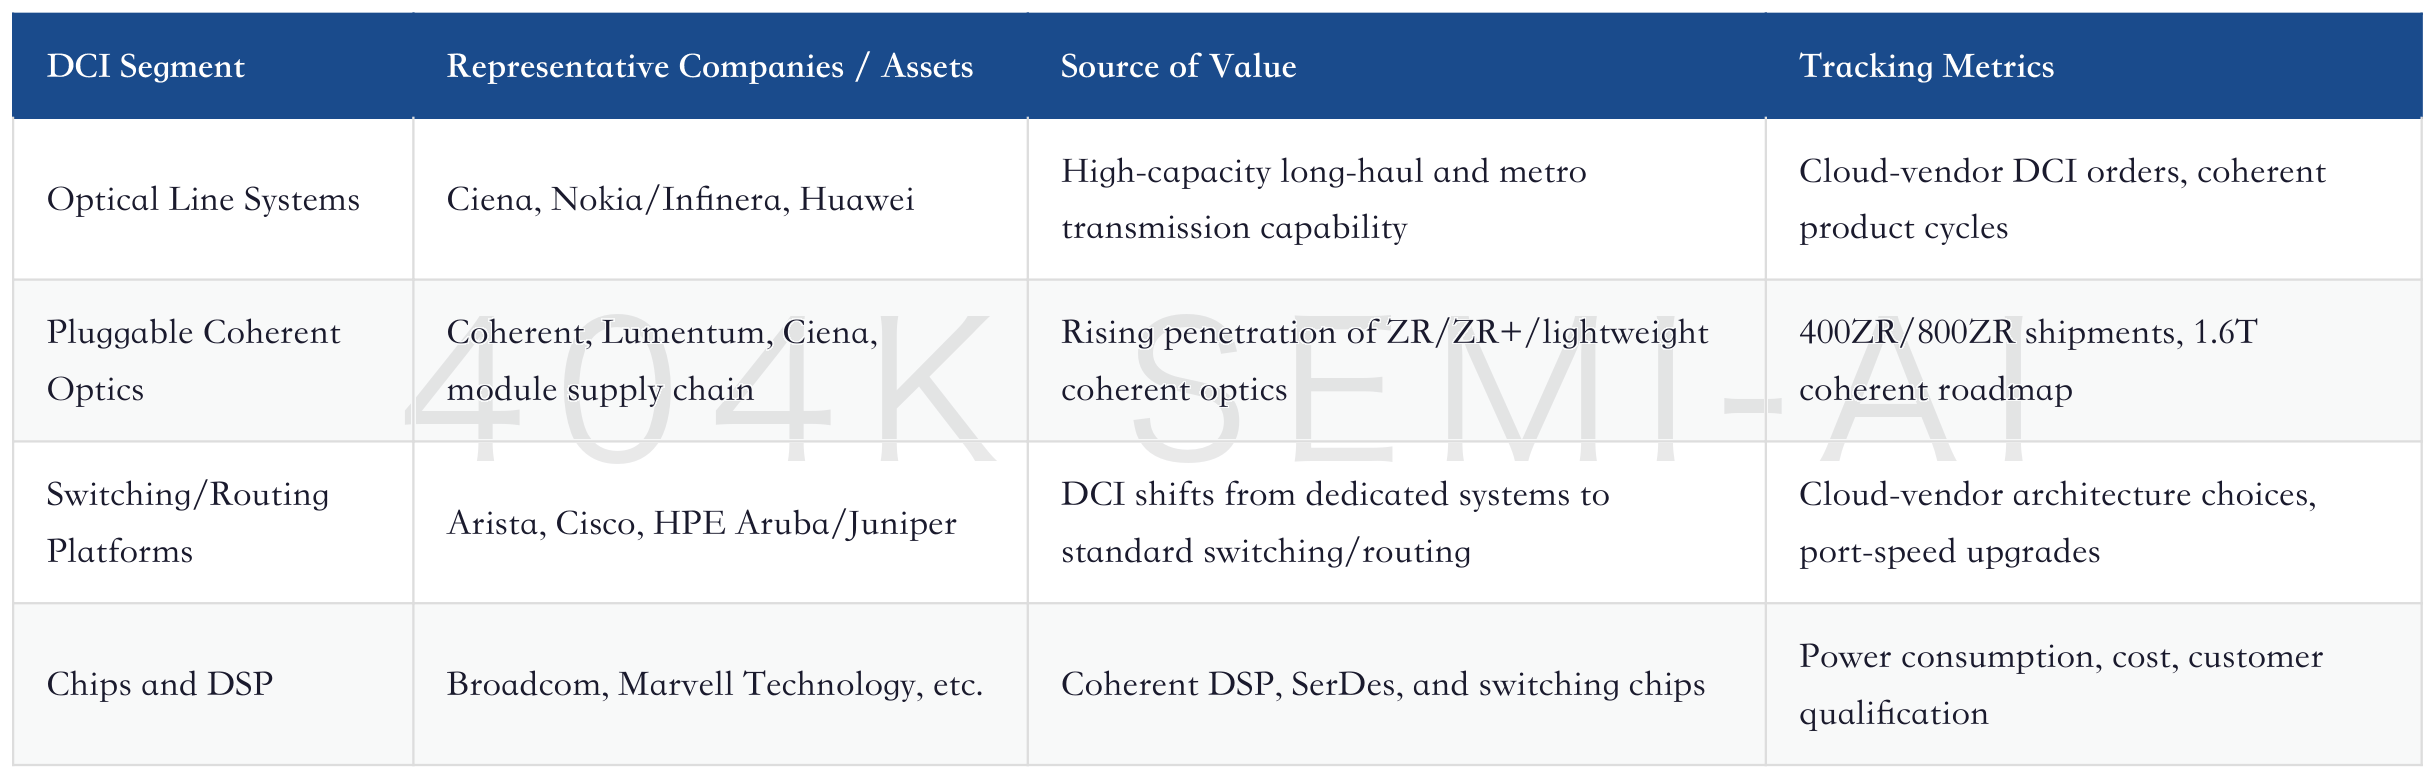
The falsification points for DCI are also relatively clear. First, if AI data centers remain highly concentrated, cross-campus interconnect demand will be lower than JPM assumes. Second, if the power consumption, thermal profile, or cost of pluggable coherent optics cannot meet cloud-vendor requirements, traditional optical systems will retain a higher share. Third, if cloud-vendor network architectures migrate more slowly to standard switching/routing platforms, the DCI elasticity for Arista, Cisco, and related white-box chains will be delayed.
DCI matters because it moves AI data centers from single-campus engineering to multi-campus networking. In the past, many investors treated DCI as part of the communications equipment or optical transport market, growing at a decent but not especially exciting pace. AI has changed that positioning. When a city or campus cannot provide enough power, compute must be dispersed across multiple nodes. For multiple nodes to operate like one large cluster, they must be connected by high-bandwidth, low-latency, operable DCI.
This will change the demand structure of the optical module chain. Ordinary data-center interiors focus more on short- and medium-reach connections, while DCI brings coherent optics, pluggable coherent modules, optical line systems, and routing/switching platforms into the same architecture map. For Ciena, Coherent, Lumentum, and others, AI DCI means traditional telecom capabilities are being redeployed. For Arista, Cisco, and HPE Aruba/Juniper, AI DCI means switching/routing platforms may enter budgets that were previously occupied by dedicated transport systems.
The investment opportunity in DCI is also not simply “long distance equals optical communications.” A better ranking framework is to identify who can help cloud vendors turn cross-campus connectivity into a standardized, scalable, maintainable network. Pluggable coherent optical modules reduce deployment complexity. Standard switching/routing platforms reduce system fragmentation. Cloud-vendor operations software lowers troubleshooting costs. As long as AI data centers continue to be broken apart by power and land constraints, DCI will move from a back-end network budget to part of the AI expansion budget.
6. AEC: A Small-TAM, High-Signal Market, and Why Credo Deserves a Separate Look
AEC is not large in absolute market size, but it is a high-signal variable for assessing the difficulty of in-rack AI connectivity. JPM expects AEC chip revenue to rise from $622 million in 2025 to $1.375 billion in 2026E, then to $2.875 billion in 2027E and close to $3.655 billion in 2030E. This market will not directly support a trillion-dollar total addressable market the way servers do, but it reflects one key question: whether connectivity inside AI racks has moved from passive copper cables to high-reliability solutions with active chips.
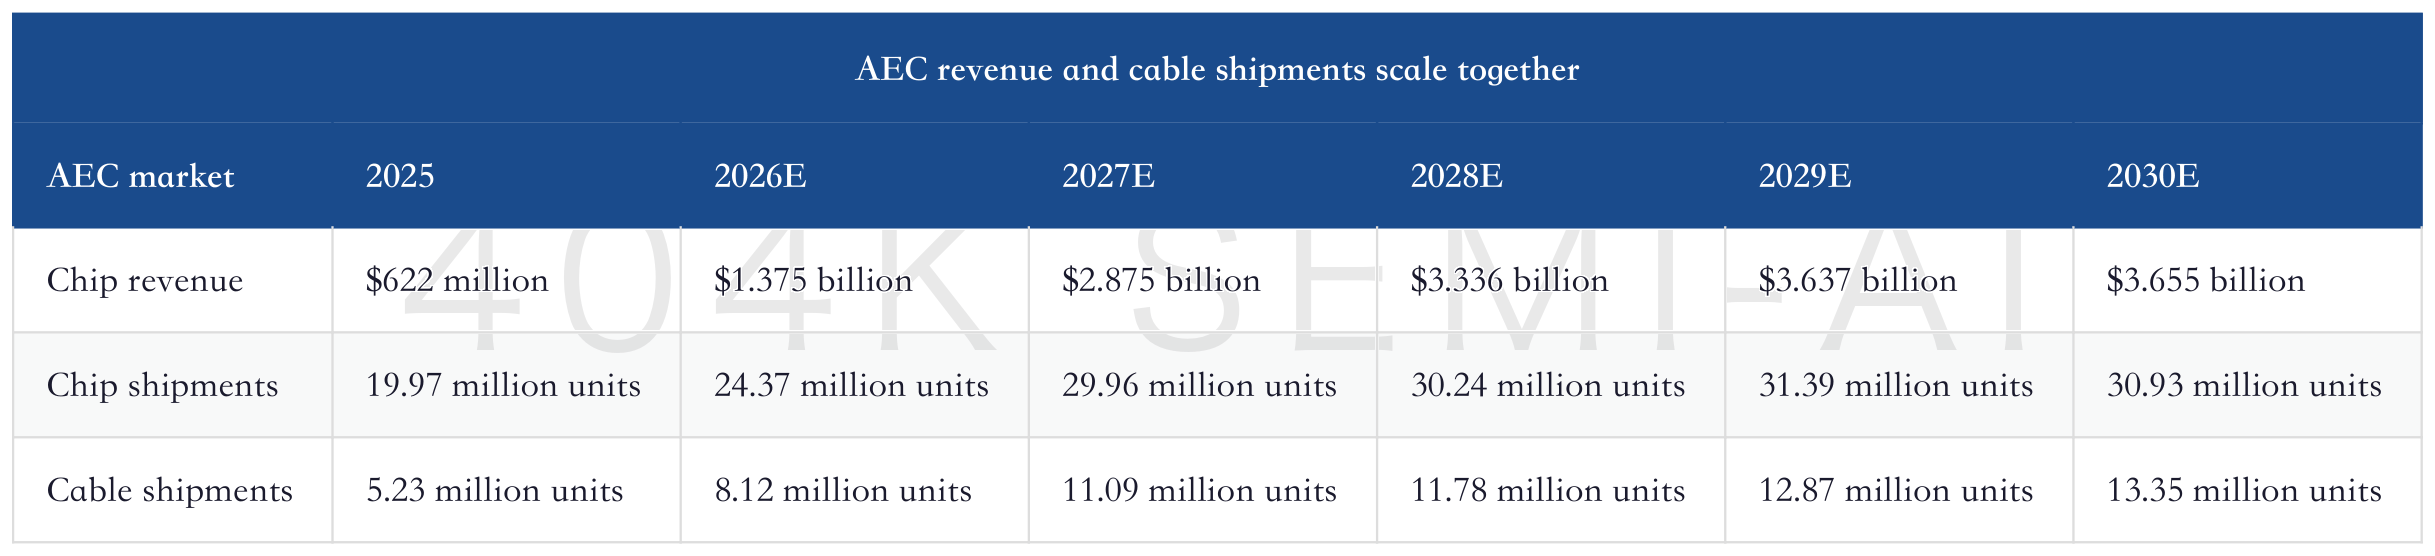
The investment implications of AEC need to be understood through physical constraints. The connection distance between AI servers and switches is not long, but bandwidth is high, power consumption is sensitive, and signal integrity requirements are stringent. Passive copper cables are cheap, but limited by distance and speed; optical modules reach farther, but cost and power consumption are also higher; AEC uses active chips to compensate signals, making it suitable for in-rack and short-reach high-bandwidth connections. As 800G, 1.6T and higher port speeds advance, AEC will become the optimal solution in certain distance ranges and topologies.
