
目录
Executive Summary
Price Competition Is Becoming Segmented
Open Weights Are Evolving from a Customer-Acquisition Tool into a Revenue Contract
Trillion-Parameter Models Are Raising the Financing and Execution Bar
Zhipu Reaches Breakeven First, While MiniMax Faces a Longer Cash-Burn Period
Alibaba Group’s Advantage Lies in Its Full Stack, Not Any Single Ranking
High Price Targets Are Underpinned by Terminal-Value-Dominated Valuations
Six Metrics Will Determine Whether the “Intelligence Battle” Becomes Commercial Reality
Conclusion: From “Who Is Cheapest?” to “Who Can Repeatedly Prove Its Value?”
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
China’s foundation-model industry has not left low-price competition behind. Instead, capability, licensing, compute, and financing are all becoming determinants of success.
Executive Summary
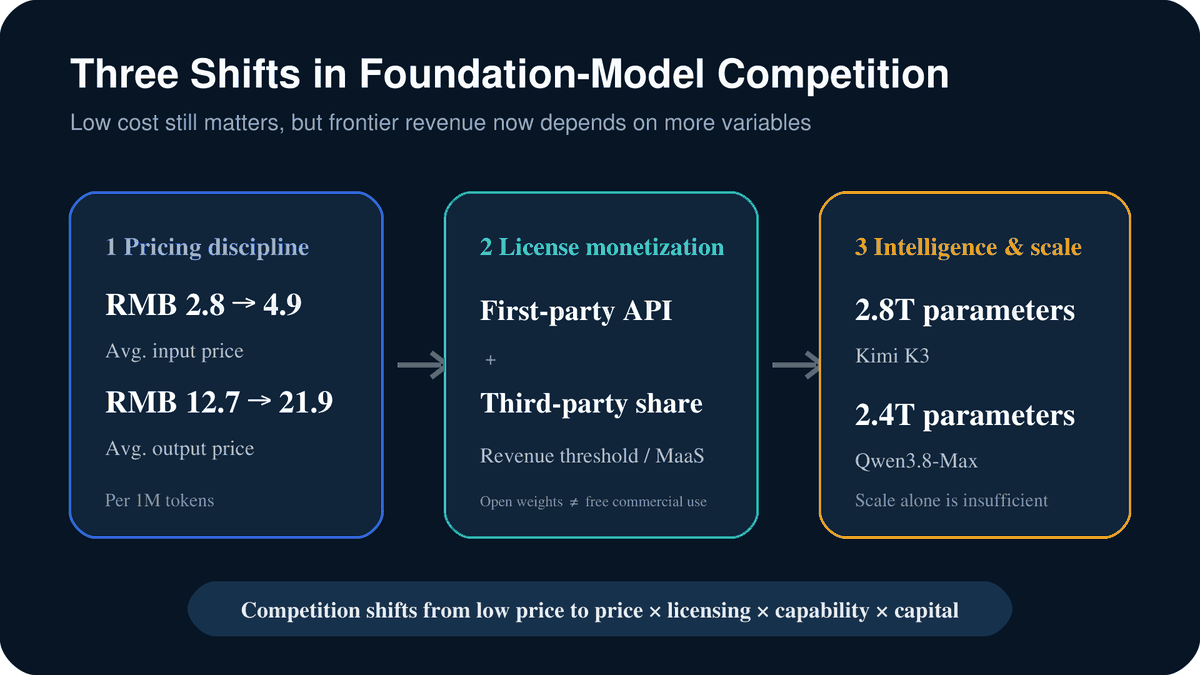
The supposed shift from a “price war” to an “intelligence war” is fundamentally a segmentation of the market. The research report shows that the average input price for Chinese models rose from RMB2.8 per 1 million tokens in 3Q25 to RMB4.9 in 2Q26, while the average output price increased from RMB12.7 to RMB21.9. High-value models are testing capability premiums, while lower-end inference will remain price-competitive.
Open weights no longer mean free commercial use. Models such as Kimi K3 and MiniMax M3 use revenue thresholds, MaaS agreements, and commercial licenses to extend monetization beyond first-party APIs into third-party revenue sharing with cloud providers and aggregation platforms. Adoption becomes a commercial asset only when it translates through licensing, usage, and revenue.
Parameter scale is raising the capital threshold, but it is not sufficient for superior capability. Kimi K3 has 2.8 trillion parameters and QWEN38MAX has 2.4 trillion. Yet V4FLASH achieves an intelligence score close to GLM52 with only 284 billion parameters, showing that architecture, data, training, and inference efficiency can still break the linear assumption that bigger necessarily means better.
The valuation divergence between Zhipu AI and MiniMax reflects different timelines to profitability. Zhipu AI’s 2026 annual recurring revenue (ARR) base-case forecast has been raised to US$2 billion, with operating profit and free cash flow expected to turn positive in 2028; its price target was raised from HK$990 to HK$1,700. MiniMax’s 2026 ARR base case is US$1 billion, with breakeven expected only in 2029; its price target was cut from HK$1,100 to HK$900.
MiniMax received larger revenue upgrades but a lower price target, showing that the market no longer rewards growth fueled by cash burn. Its 2026–2028 revenue forecasts were raised by 104.2%, 71.1%, and 99.2%, respectively, while its non-IFRS operating-loss forecasts widened by 15.1%, 39.7%, and 49.8%. Revenue quality, R&D; efficiency, and cash consumption are beginning to outweigh headline growth.
Alibaba Group’s value lies not only in model rankings but in its full-stack compute platform. Its closed loop across cloud computing, models, enterprise distribution, and capital expenditure makes it more likely to capture aggregate compute demand as open and closed models coexist. Whether higher capital expenditure can translate into utilization, revenue, and cash returns still requires separate validation.
Three developments could most readily invalidate this thesis. Global peers could again launch models that are both stronger and cheaper; open-weight restrictions could suppress adoption without generating revenue share; or ARR growth could fail to convert into gross profit, operating cash flow, and sustainable R&D.; Model rankings are only the starting point; financial outcomes are the ultimate test.
Price Competition Is Becoming Segmented
Low prices have been the defining feature of China’s foundation-model market over the past two years. DeepSeek brought efficiency and pricing to the center of the global debate, while cloud providers and independent laboratories continued to reduce inference costs per 1 million tokens. This produced an intuitive market view: models would rapidly commoditize like bandwidth, capability gaps would continue to narrow, and only platforms controlling cloud infrastructure and traffic would ultimately make money.
The research report offers an important qualification: frontier and lower-end markets are beginning to diverge. From 3Q25 to 2Q26, the average input price for Chinese models rose from RMB2.8 to RMB4.9, while the average output price increased from RMB12.7 to RMB21.9. Even so, average Chinese input and output prices remain only about 19% and 14%, respectively, of US peers, preserving China’s absolute cost advantage. What has changed is that prices no longer move in only one direction—downward.
Capability and pricing are also becoming positively correlated. The report assigns Kimi K3 an intelligence score of 60 and an output price of RMB100 per 1 million tokens; QWEN38MAX scores 58 and costs RMB36; GLM52 scores 53 and costs RMB28. V4FLASH reaches an intelligence score of 52 but costs only RMB2, making it a striking efficiency outlier. These data suggest that the industry is not shifting wholesale from “cheap” to “expensive.” Instead, two business models are emerging: one uses low prices and efficiency to serve high-volume standardized inference, while the other seeks premiums for high-value workloads such as coding, complex reasoning, agents, and video.
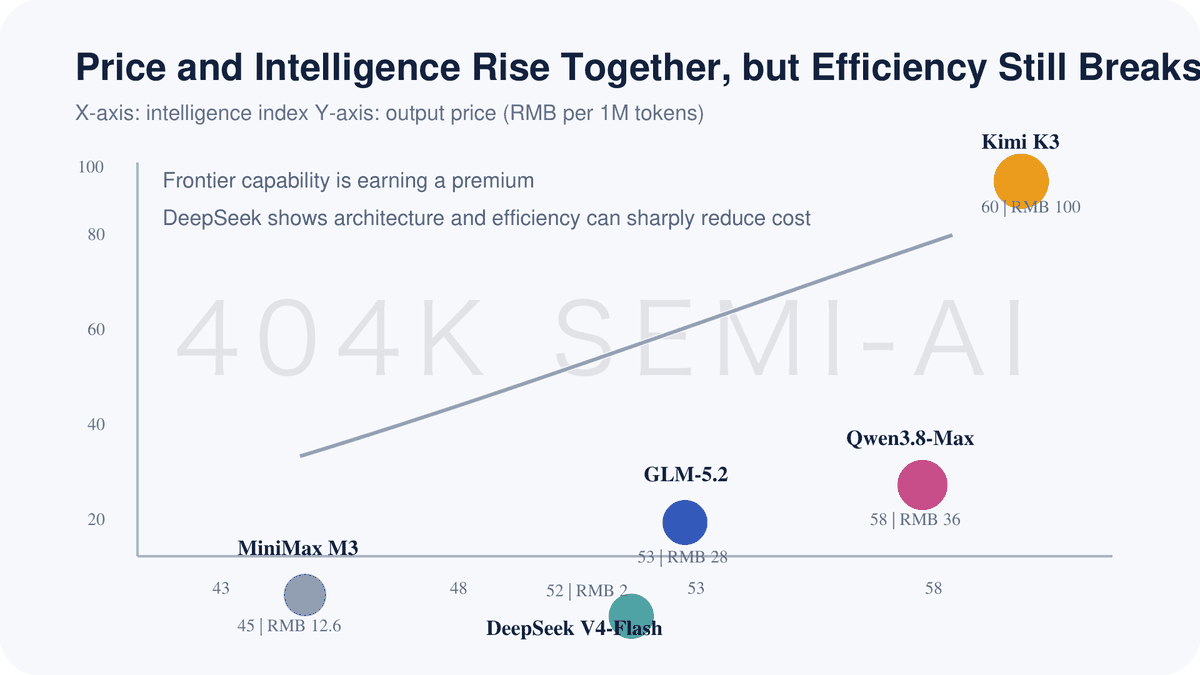
Price increases therefore should not be equated automatically with pricing power. Genuine pricing power requires at least three conditions: higher prices must correspond to higher task success rates; usage and customer retention must not decline materially after an increase; and incremental revenue must exceed incremental inference costs. If prices rise merely to cover larger models, more expensive GPU clusters, and higher latency, the result is cost pass-through rather than margin expansion.
Open Weights Are Evolving from a Customer-Acquisition Tool into a Revenue Contract
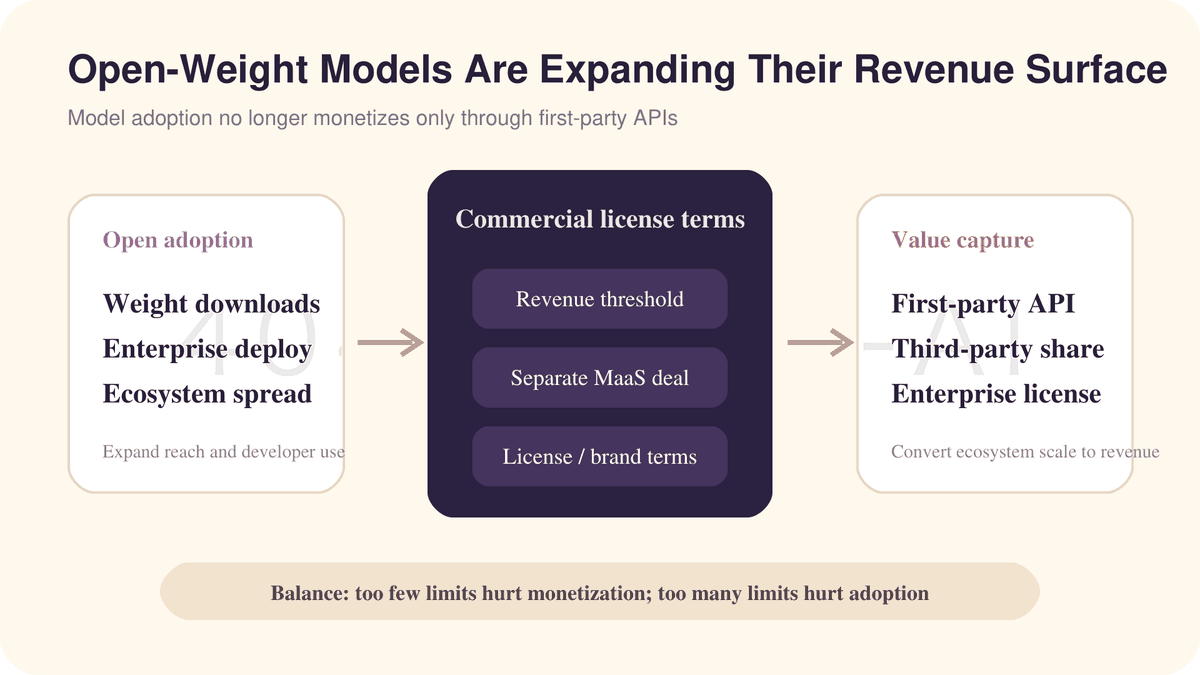
The second structural change is occurring in licensing. Open weights were previously understood as a way to release models broadly, expand developer adoption, and monetize through first-party APIs. The problem is that large-scale usage may occur through cloud providers, MaaS platforms, or enterprise-owned clusters. Model laboratories can gain ecosystem influence without capturing the corresponding revenue.
Leading models are now embedding commercial terms directly into their licenses. Kimi K3 requires MaaS providers with annual model-distribution revenue above US$20 million to negotiate separate terms, while MiniMax M3 imposes licensing requirements on users whose products or services generate more than US$20 million in annual revenue. Licenses are gradually expanding from permissive access to cover branding, revenue thresholds, third-party revenue sharing, and non-commercial restrictions. Open weights can still broaden adoption, but “adoption” is no longer synonymous with “free commercial use.”
This shift matters for industry economics. First-party API revenue depends on customers calling a laboratory’s interface directly, while third-party revenue sharing can cover cloud hosting, aggregation and routing, and enterprise deployment. If licenses can be enforced effectively, model companies may convert open ecosystems into broader revenue pools. If enforcement becomes too restrictive, developers may migrate to alternatives with fewer constraints. The optimal commercial model is neither maximum openness nor maximum closure, but a balance between adoption scale and value capture.
Open weights also will not automatically reduce compute demand. An enterprise survey cited by the report indicates that 63% of respondents use both open and closed models. Multi-model stacks increase requirements for routing, orchestration, observability, governance, and security, while lower inference costs per request may expand total usage. For cloud providers, greater openness at the model layer may not reduce compute revenue; instead, competition may shift from “backing one model” to hosting more models and more workloads.
Trillion-Parameter Models Are Raising the Financing and Execution Bar
Kimi K3 has 2.8 trillion parameters, QWEN38MAX has 2.4 trillion, and MiniMax’s planned M3 Pro is expected to have approximately 2.7 trillion. The move from hundreds of billions of parameters to more than 2 trillion is not merely a product upgrade; it simultaneously raises the difficulty of training operations, GPU clustering, network communications, data engineering, post-training, and inference optimization.
Scale itself, however, is not a moat. In the report’s parameter-versus-intelligence chart, the 1 trillion-parameter MIMOV25PRO has a lower intelligence score than the 284 billion-parameter V4FLASH. If architectural innovation does not offset active parameters, inference latency, and per-task costs, a larger model may deliver only limited capability gains while multiplying costs. The real barrier is the ability to convert more parameters into higher task success rates and then use commercialization proceeds to finance the next generation of models.
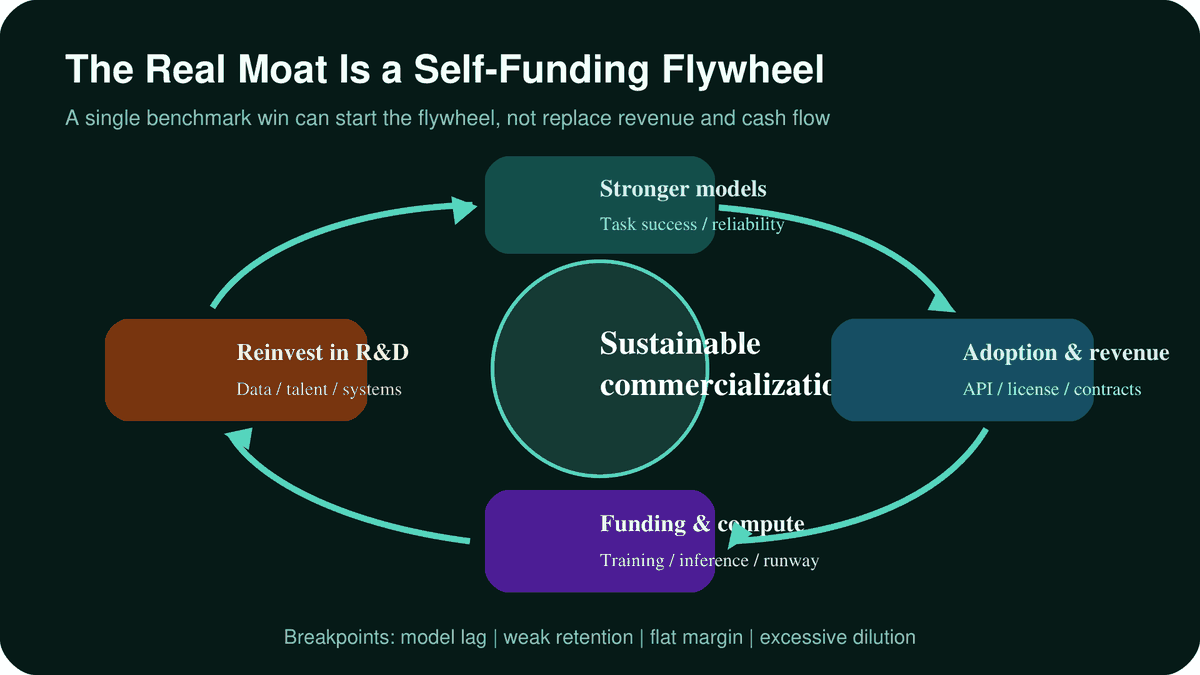
This flywheel has four links: stronger models drive adoption and higher pricing; revenue and financing expand training and inference capacity; compute and data support the next generation of models; and continued iteration improves customer retention. If any link breaks, scale advantages may turn into cash burn. Ranking first proves capability only at a particular point in time. It does not prove that the next generation will remain ahead, much less that enterprise customers will convert test usage into long-term contracts.
Our continued tracking of Kimi K3 and Zhipu AI’s valuation reset supports one enduring conclusion: model companies should no longer be valued as “permanent champions,” but on their ability to remain consistently within the frontier cohort. Leadership may rotate, but commercialization cannot lose momentum. A company can fall behind for one model generation, but revenue, retention, and unit economics cannot deteriorate continuously.
Zhipu Reaches Breakeven First, While MiniMax Faces a Longer Cash-Burn Period
Zhipu’s core investment case rests on scaling cloud revenue. The report forecasts total revenue rising from RMB724 million in 2025 to RMB5.256 billion in 2026, RMB15.374 billion in 2027, and RMB36.85 billion in 2028. Cloud deployment revenue is expected to increase from approximately 26% of the total to 80%, 89%, and 92%, respectively. Gross margin is projected to recover from 34.1% in 2026 to 41.5% in 2028. Although R&D; expenses are expected to reach RMB12.165 billion, the R&D; expense ratio should fall to approximately 33%. If revenue and gross margin follow this trajectory, Zhipu would generate RMB852 million in operating profit and RMB3.863 billion in free cash flow in 2028.
The report raised its base-case estimate for Zhipu’s 2026 ARR from US$1 billion to US$2 billion, with bull- and bear-case estimates of US$3 billion and US$1.5 billion, respectively. Pricing across the GLM series rises with model capability: GLM-5.2 charges RMB8 per 1 million input tokens and RMB28 per 1 million output tokens. Distribution through AWS Marketplace and proceeds from a share placement add overseas reach and computing capacity. The July placement raised HK$31.4 billion, of which 55%, or approximately US$2.2 billion, is earmarked for training and compute expansion. The key issue is not simply that Zhipu raised substantial capital, but whether it can convert that funding into stronger models, cloud revenue, and a lower R&D; expense ratio by 2028.
MiniMax has a more diversified revenue mix. The report forecasts revenue increasing from US$79.04 million in 2025 to US$399 million in 2026, US$1.198 billion in 2027, and US$2.991 billion in 2028. By 2028, open-platform and enterprise-services revenue is expected to reach approximately US$1.988 billion, or roughly 66% of total revenue. AI-native products should contribute approximately US$1.003 billion, with Hailuo AI and MiniMax Agent representing major components. H3 offers video of up to 2K resolution and 15 seconds in length at RMB0.5 per second. It ranked first in video editing in the third-party rankings cited by the report, suggesting that low pricing and strong capability are not necessarily incompatible.
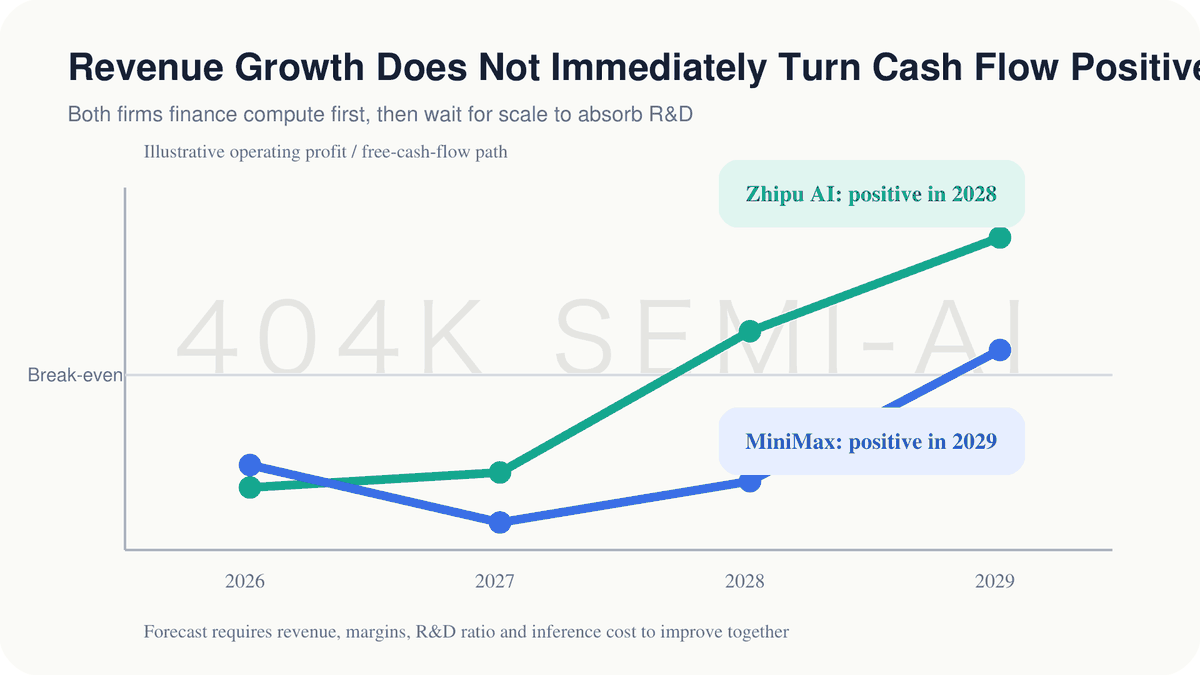
MiniMax’s costs, however, are rising faster. R&D; expenses are projected to increase from US$253 million in 2025 to US$1.483 billion in 2028, when they would still equal approximately half of revenue. Operating cash flow is expected to be -US$359 million, -US$602 million, and -US$210 million in 2026—2028, respectively, before turning positive in 2029. The company plans to allocate 80% of its new financing, or approximately US$1.6 billion, to training and inference compute. A longer cash runway reduces near-term funding risk, but does not demonstrate that the business model has become self-funding.
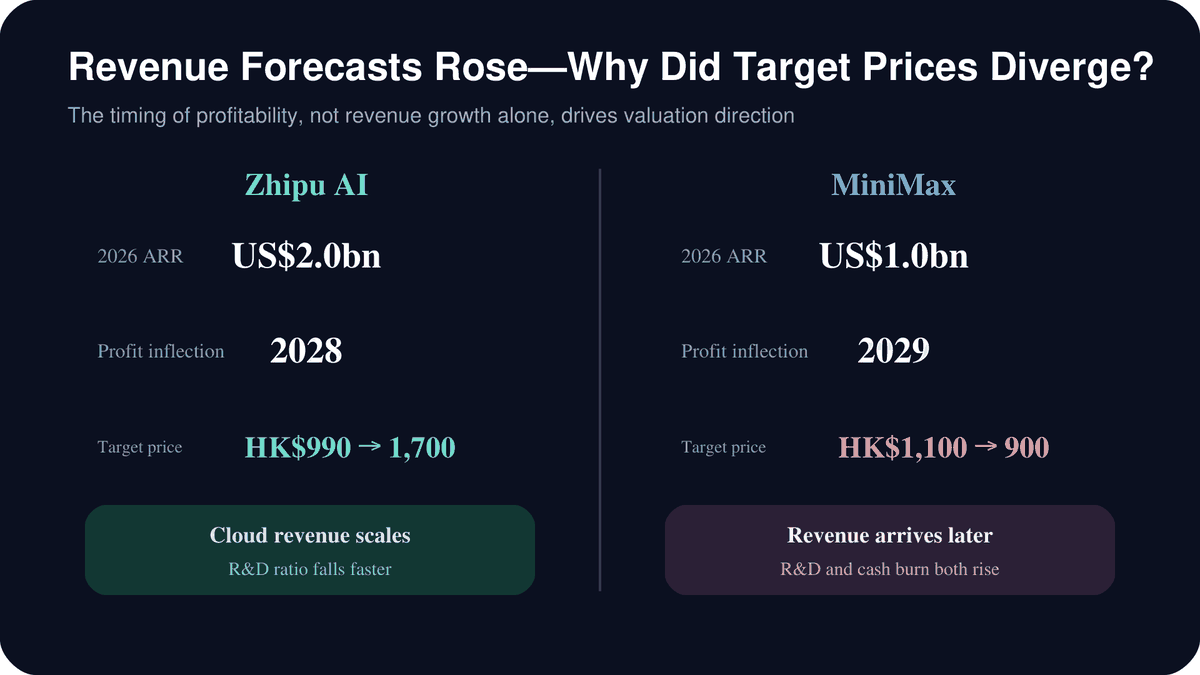
This explains an apparently contradictory outcome: although MiniMax received a larger revenue-forecast upgrade than Zhipu, its price target was cut from HK$1,100 to HK$900, while Zhipu’s price target was raised from HK$990 to HK$1,700. The market is not rewarding growth at any cost; it is rewarding the ability of incremental revenue to cover incremental R&D; spending more quickly. Zhipu is expected to reach breakeven in 2028, versus 2029 for MiniMax. That one-year difference is magnified in a long-duration DCF.
ARR must also be distinguished from recognized revenue. MiniMax’s base-case 2026 ARR is US$1 billion, but its 2026 revenue forecast is only US$399 million. ARR measures the revenue run rate at a point in time, whereas full-year revenue depends on contract signing, deployment timing, and the pace of revenue recognition. Directly comparing the two would overstate the company’s current operating scale and obscure the delayed revenue contribution from models released in the second half.
Alibaba Group’s Advantage Lies in Its Full Stack, Not Any Single Ranking
Independent model companies must purchase computing capacity within available financing windows. Alibaba Group, by contrast, owns cloud infrastructure, models, enterprise customer relationships, and distribution channels. The report remains constructive on Alibaba Group—not because it assumes Qwen will permanently rank first, but because an integrated AI stack can capture aggregate demand from model training, inference, enterprise deployment, and multi-model routing.
This full-stack advantage has three layers. First, the cloud platform can convert model adoption directly into compute revenue, even when customers use both open and closed models. Second, enterprise relationships, developer tools, and model services can reduce distribution costs and move capability upgrades into production more quickly. Third, cloud utilization and customer data can inform infrastructure planning and product iteration. Compared with owning model weights alone, a platform offers more points of value capture.
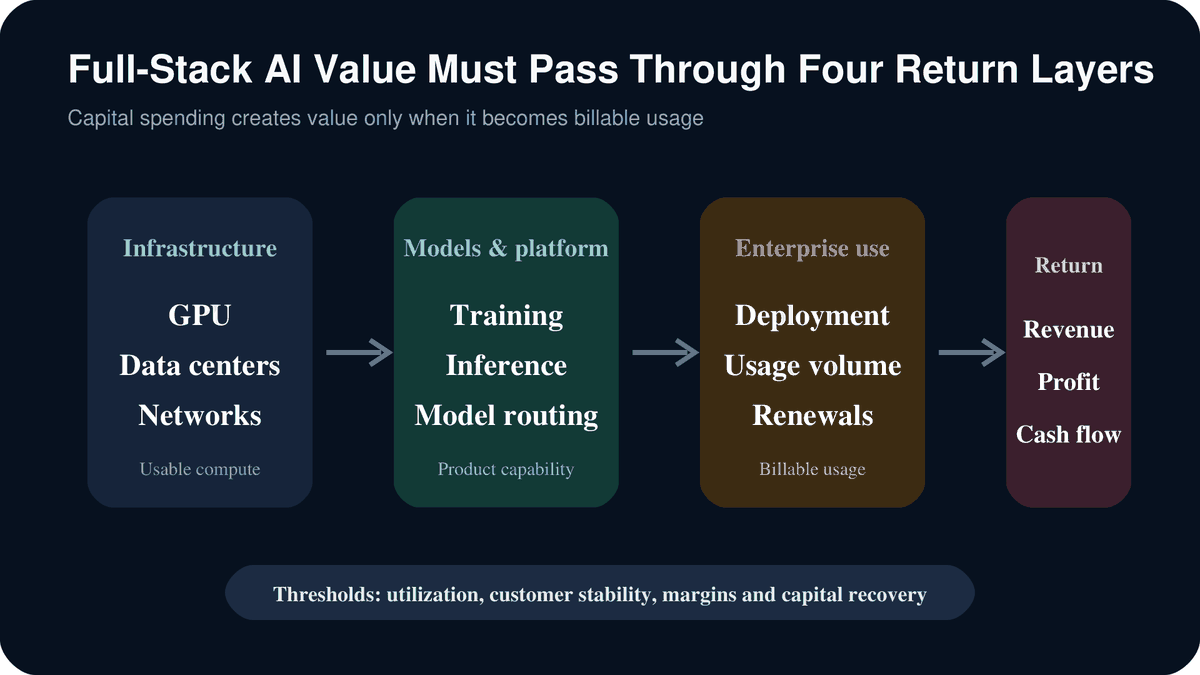
A full stack can also become a capital-expenditure trap. Alibaba Group’s DCF uses a 10% weighted average cost of capital and 3% terminal growth rate. Upside depends on AI demand driving cloud revenue, faster enterprise digitalization, and improved monetization in the core commerce business. Downside risks include intensifying competition, higher-than-expected reinvestment, weak consumption, and slower enterprise digitalization. The critical metric is not announced AI capital expenditure, but how much billable capacity, utilization, cloud revenue, and cash return the additional GPUs and data centers generate.
High Price Targets Are Underpinned by Terminal-Value-Dominated Valuations
The DCFs for Zhipu and MiniMax both use a 15% weighted average cost of capital and 3% terminal growth rate, already reflecting substantial risk. Even so, more than approximately 60% of each company’s enterprise value still comes from terminal value. Zhipu’s price target is HK$1,700, with bull- and bear-case values of HK$3,340 and HK$670. MiniMax’s price target is HK$900, with bull- and bear-case values of HK$2,230 and HK$220. Such wide ranges show that the targets are not precise answers, but conditional mappings of model performance, revenue scale, and the timing of profitability.
Zhipu’s price target implies approximately 42 times 2027 price-to-sales, versus approximately 32 times for MiniMax. These elevated multiples require nonlinear revenue growth, gross-margin expansion, a declining R&D; expense ratio, and positive cash flow to occur together. If model performance falls behind, price competition intensifies, or commercialization is delayed, both revenue forecasts and valuation multiples may be revised downward. Conversely, if globally leading models are successfully released, enterprise usage expands, and competition eases, long-term profit estimates could be raised rapidly.
The report’s price targets are therefore more useful for understanding what the market is paying for than for establishing a definitive fair value. Zhipu receives the higher price target because its path to profitability is shorter. MiniMax offers greater scenario upside because its current valuation embeds less confidence in future model execution. Neither is a low-risk asset; their risks are simply distributed differently over time.
Six Metrics Will Determine Whether the “Intelligence Battle” Becomes Commercial Reality
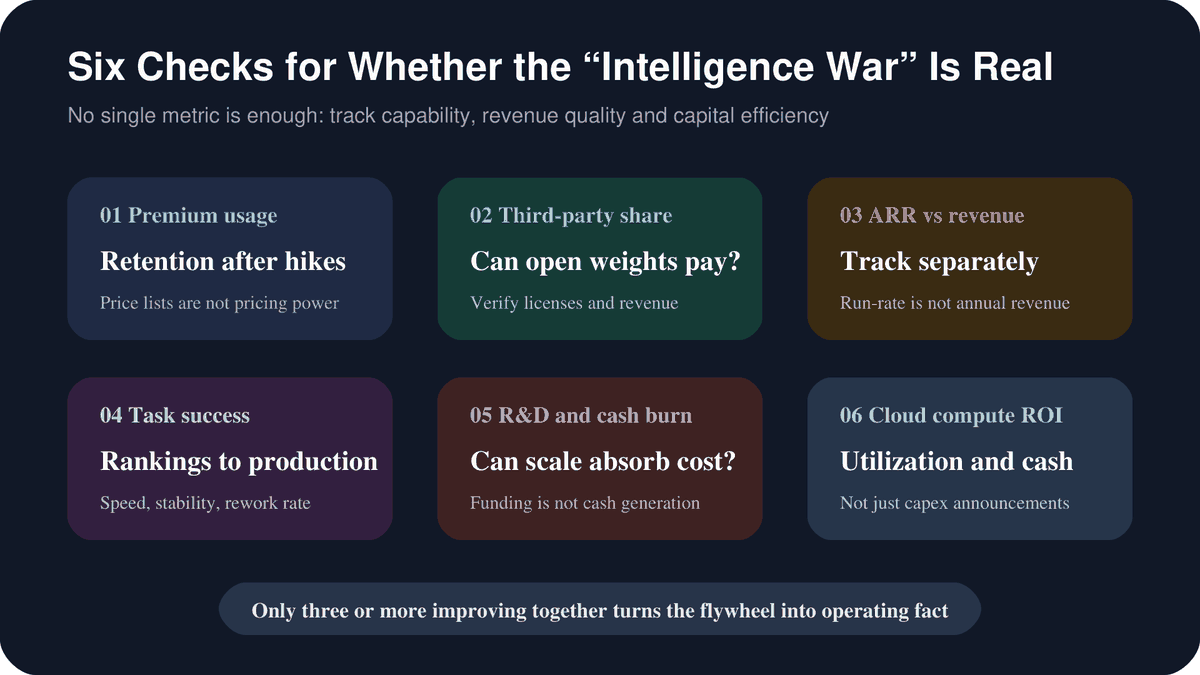
First, track usage and customer retention after premium models raise prices. Second, determine whether third-party revenue sharing for open weights translates into recognized revenue. Third, distinguish ARR from full-year recognized revenue. Fourth, assess success rates on real-world tasks, speed, stability, and rework rates—not rankings alone. Fifth, evaluate whether R&D; expenses, inference costs, and operating cash burn decline as revenue scales. Sixth, monitor cloud-compute utilization and cash returns rather than capital-expenditure commitments alone.
If only model parameters, benchmark scores, and quoted prices rise across these six dimensions, the industry has merely entered a more expensive race. Intelligence competition will create genuine commercial barriers only if usage, licensing revenue, gross profit, and cash flow improve together. The strongest disconfirming evidence would be global peers releasing models that are both stronger and cheaper, commoditizing frontier capabilities once again. A second would be licensing terms that constrain adoption without producing enforceable value sharing. A third would be repeated financing that replenishes cash while operating cash flow fails to turn positive.
Conclusion: From “Who Is Cheapest?” to “Who Can Repeatedly Prove Its Value?”
China’s foundation-model industry has not fully exited the price war. Prices for lower-end text processing, standardized inference, and substitutable APIs will continue to fall, while DeepSeek-style efficiency innovations will keep reducing industry costs. What has changed is that premium models are beginning to charge for capability, open weights increasingly carry commercial conditions, and trillion-parameter models are pushing competition into the domains of capital intensity and systems engineering.
Zhipu, MiniMax, and Alibaba Group represent three distinct strategies. Zhipu is betting on rapid cloud-revenue scaling and reaching breakeven in 2028. MiniMax is using multimodality, an open platform, and enterprise services to pursue greater long-term upside, but must absorb a longer period of cash burn. Alibaba Group relies on its integrated cloud stack and distribution to capture the industry’s aggregate compute demand, but must prove that its capital expenditure can generate returns.