
目录
I. Demand Has Crossed an Inflection Point, With Tokens Emerging as a New Infrastructure Load
II. Why 330% Token Growth Translates Into Only 80% Compute-Demand Growth
III. Effective Advanced-Wafer Output Will Determine Whether Domestic Chips Can Be Delivered
IV. HBM Is a Separate Hard Constraint: Validation and Bandwidth Matter More Than Capacity-Expansion Announcements
V. Multi-Die Architectures and Advanced Packaging Trade System Complexity for Usable Compute
VI. Supernodes Shift Competition from Single-Card Specifications to Rack-Level Efficiency
VII. The Software Stack Determines Whether Supernodes Become Productive Assets
VIII. Aggregate Power Supply Is Sufficient, but AI Data Centers Still Require Redesigned Power Distribution and Cooling
IX. Profits Will Spread Across the Value Chain, but Not Evenly
10. Target-Price Dispersion: Delivery Capabilities and Valuation Assumptions Drive the Differences
11. Three Potential Paths Will Determine How Growth Materializes
12. Eight Sets of Public Data to Monitor
Conclusion: High Industry Growth Is Now Established; Execution and Returns on Capital Will Determine the Winners
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
China’s AI infrastructure market is entering a phase of explosive demand growth amid severe supply constraints. Inference Token consumption is soaring, while effective yields for advanced wafers and supplies of HBM3/3e are struggling to keep pace. This gap will force the industry to extract more usable compute through multi-die designs, supernodes, high-speed interconnects, and software optimization.
J.P. Morgan expects China’s inference compute demand to grow at an approximately 80% CAGR through 2030, while domestic AI chips could meet about 80% of demand by 2028, up from approximately 40% in 2025. If both forecasts hold, the industry will expand rapidly while performance diverges sharply across companies. Nominal capacity, peak compute, and valuation narratives will not determine the winners; deliverable chips, real-world cluster efficiency, customer acceptance, and returns on capital will underpin future valuations.
I. Demand Has Crossed an Inflection Point, With Tokens Emerging as a New Infrastructure Load
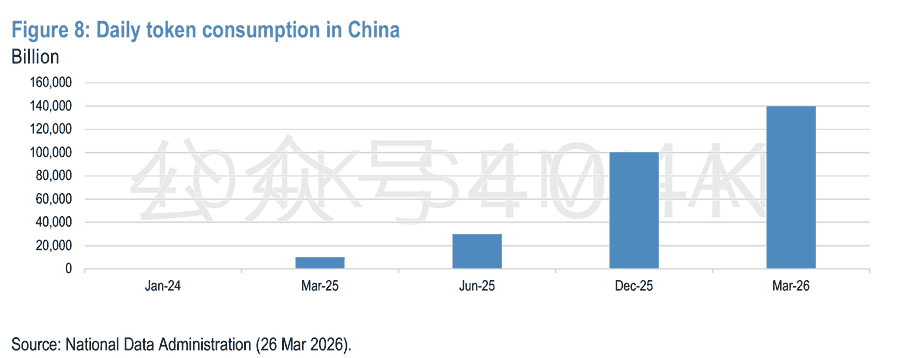
The incremental growth in China’s AI demand is coming from inference, driven primarily by cheaper open-source models and AI agents. Average daily Token consumption in China increased from approximately 100 billion in early 2024 to about 100 trillion by the end of 2025, then exceeded 140 trillion in March 2026. The workload expanded by more than 1,000 times in just over two years.
This growth reflects both a larger user base and higher Token consumption per task. A conventional Q&A; request may invoke a model only once, whereas an agent autonomously plans, searches, calls tools, checks results, and retries repeatedly. A single user request can generate dozens of model interactions. Multimodal workloads, long contexts, and real-time generation are also increasing the computational intensity of each interaction.
Lower-priced models reduce the cost per call while amplifying aggregate usage—a classic efficiency rebound. As each Token becomes cheaper, enterprises embed AI into more workflows and users increase engagement. Consequently, total compute spending may continue to rise even as unit costs decline. Cloud providers and major internet platforms therefore need more inference capacity that can operate continuously, rather than infrastructure deployed primarily for concentrated large-model training runs.
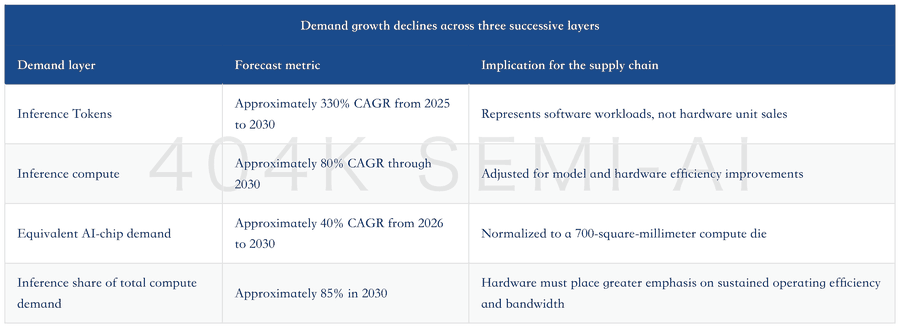
J.P. Morgan estimates that China’s inference Token demand will grow at an approximately 330% CAGR from 2025 to 2030. This figure describes software workload growth and should not be interpreted directly as hardware unit or revenue growth. Model architectures, low-precision data formats, cache management, and cluster utilization will continue to raise effective output per chip. How these growth rates translate across layers will determine the supply chain’s realizable revenue opportunity.
II. Why 330% Token Growth Translates Into Only 80% Compute-Demand Growth
Converting Token demand into hardware demand requires at least three stages of adjustment. The first is the number of floating-point operations required per Token. The second is actual chip utilization and throughput per unit of compute. The third is service quality, including time to first Token, time per output Token, and concurrency. Improvements at any stage reduce the hardware required per unit of workload.
J.P. Morgan’s base-case model uses a 671 billion-parameter large model and requires latency of less than 50 milliseconds per output Token. Batch size is set at 128 and KV Cache length at 4096. The model addresses a specific question: how much compute must be actively deployed to support the forecast Token volume at acceptable latency?
Inference can also be divided into Prefill and Decode stages. Prefill must rapidly process and interpret the full input sequence and is more compute-intensive. Decode generates Tokens sequentially and is more constrained by memory bandwidth and KV Cache. For long-context and large-batch workloads, memory capacity, bandwidth, and interconnect latency are as important as peak FLOPS. This is why HBM is shifting from a supporting component to a system-level bottleneck.
The report assumes that effective throughput per TFLOPS will continue to improve. Each TFLOPS currently generates approximately 1 Token/second, rising to about 3.3 Tokens/second by 2028, equivalent to an approximately 30% annual efficiency gain. The assumptions incorporate chip upgrades, model compression, low-precision computing, speculative runtime optimization, and scheduling improvements. Collectively, these advances absorb a substantial portion of the 330% Token-demand growth.
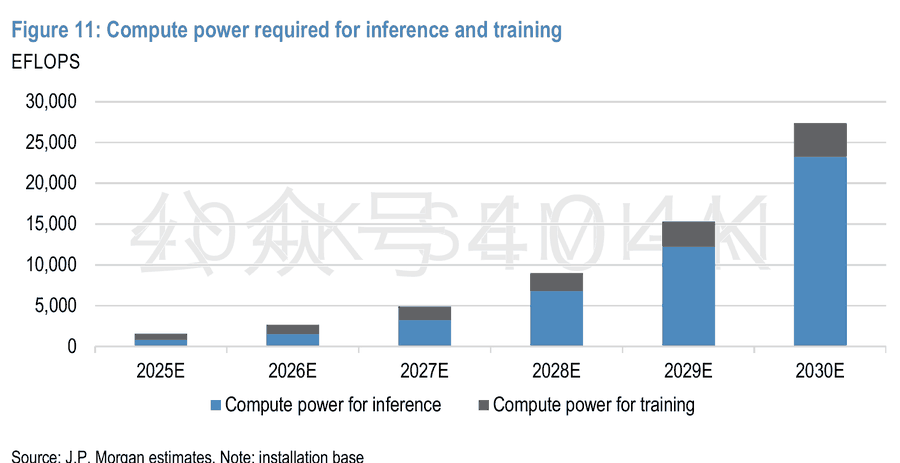
After adjusting for efficiency gains, the report derives an approximately 80% CAGR in inference compute demand and expects inference to account for 85% of total AI compute demand by 2030. Training clusters will remain substantial, but inference will increasingly determine infrastructure utilization, energy consumption, and revenue monetization. Data centers will shift from intermittent large-scale training toward long-duration, high-concurrency online services.
Translating compute demand into chip volumes requires a further adjustment for performance gains per chip. J.P. Morgan expects equivalent AI-chip demand to grow at an approximately 40% CAGR from 2026 to 2030, reaching about 14 million units in 2030. This figure is normalized to a 700-square-millimeter single compute die and does not represent the natural unit count of differently packaged products in the market. Dual-die and multi-die designs will alter the final number of packaged units.
III. Effective Advanced-Wafer Output Will Determine Whether Domestic Chips Can Be Delivered
Nominal wafer capacity will expand rapidly, but effective output of deliverable AI chips will lag materially. The report estimates that Chinese manufacturers plan to add 150,000 to 200,000 wafers/month of advanced logic capacity over the next three years. Although this represents enormous investment, it cannot be translated directly into chip shipments. Yield ramp-up at advanced nodes, customer design migration, and constraints in critical equipment and materials will all limit effective supply.
AI chips impose more demanding requirements for die size and process consistency. A defect anywhere on a large die can render the product unusable, making yield highly sensitive to die area. The same wafer starts can produce vastly different numbers of saleable units depending on whether they are used for small consumer-electronics chips or large AI accelerators. Yield is therefore a better indicator of revenue and cash flow than nominal capacity.
J.P. Morgan expects domestic manufacturers to supply approximately 2 million, 3 million, and 5 million AI chips in 2026, 2027, and 2028, respectively. These figures are also normalized to a 700-square-millimeter single compute die. Domestic chips could meet approximately 40% of demand in 2025, rising to about 80% in 2028 and approximately 90% in 2030. Supply will expand rapidly, but conditions may remain tight through 2028.
The report expects domestic GPUs and ASICs to remain in a seller’s market over the next 6 to 12 months, with supply-demand tightness potentially persisting for 1 to 2 years. Limited supply will favor vendors that have secured wafer allocations and customer validation. This advantage is difficult to capture through peak-performance comparisons. Customers care more about receiving stable production batches on schedule and whether software can operate reliably on the new hardware.
The path from domestic AI chips’ strategic importance to foundry shareholder returns still runs through depreciation and yield. Semiconductor Manufacturing International Corporation is a critical link in the domestic supply chain, but J.P. Morgan maintains a Neutral rating on the company. Low yields, higher depreciation, and product-mix pressure could weigh on gross margin. Even at full utilization, the foundry must demonstrate that incremental capital expenditure can translate into higher value per wafer and stronger cash returns.
The economics are more direct for upstream equipment suppliers. Fab expansion and rising process complexity will increase demand for etching, thin-film deposition, cleaning, thermal-processing, and metrology equipment. NAURA Technology and Advanced Micro-Fabrication Equipment are therefore the report’s preferred names. Equipment companies still face customer-validation, delivery-timing, and accounts-receivable risks, but generally bear less per-wafer yield risk than foundries.
