
Asia AI Semiconductor and Server Deep Dive: The Cycle Has Not Peaked; 2027 Bottlenecks Shift to WoS, CCL, and Small Components
目录
Too Long; Didn’t Read
I. This Pullback Is Not the End of the Cycle, but the Second Stage of the Bottleneck Trade
II. Demand Side: Data-Center Construction Gives the Answer Earlier Than Supply-Chain Orders
III. Supply Side: After CoW Targets Were Revised Up, WoS and Small Components Became Bigger Gates
IV. GPU and TPU Revenue Split Reset: NVIDIA Remains the Largest, While Google and MediaTek Capture Marginal Elasticity
V. Server Demand Continues to Be Revised Upward: CPU, BMC, and OSAT Begin to Develop Independent Logic
VI. Advanced Packaging Roadmaps: EMIB-T, SoIC, CoPoS, and SiC Decide Who Survives Beyond 2028F
VII. PCB/CCL/HDI: The Second Main Battlefield in AI Hardware
VIII. Target Prices Raised for Nine Companies: Not the Same Type of Opportunity
IX. Three Worldviews: How to Decide Whether to Buy the Pullback or Wait for Falsification
X. Mapping the Asian Chain to A-Shares and Portfolio Discipline: Do Not Put All “AI Hardware” in One Basket
XI. Conclusion: AI Semiconductors Are Still Moving Higher, but the Easy-Money Phase Is Over
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
Nomura’s Asia technology overview gives a direct answer: the pullback in AI semiconductors looks more like consolidation at elevated levels than the end of the cycle. The 2027 battleground is shifting from securing CoWoS to who can secure WoS, substrates, CCL, testing, BMC, CPU, and cash-flow support. The investment hierarchy is also broadening from GPU beta to small-gatekeeper assets that determine accelerator-card delivery.
Too Long; Didn’t Read
The cycle has not peaked. The SOX had already rallied substantially, so a pullback is not surprising in itself. The real point is that Nomura’s global new data-center tracker is still being revised upward, with the 2027F incremental deployment target raised to 32GW. This suggests physical construction demand remains behind the order noise. If 2028F visibility continues to improve over the next 3-6 months, AI hardware earnings upgrades could still outweigh valuation volatility.
The bottleneck is migrating. TSMC has sharply raised its 2027F CoWoS target from roughly 1,300-1,350kpcs to 2,000kpcs, but Nomura models only 1,800kpcs because the real shipment constraint may no longer be CoW, which TSMC controls, but WoS, IC substrates, CCL, high-end PCB, capacitors, PMIC, optical components, and testing capacity. This migration will shift the market from “who can buy GPUs” to “who controls small-component delivery rights.”
Google TPU is changing the profit split. Nvidia remains the largest customer, and Nomura estimates it will receive about 55% of TSMC’s 2027F CoWoS allocation. But Google TPU’s share could rise from about 23% in 2026F to about 26% in 2027F, pushing Google’s contribution to TSMC AI revenue to 25%. MediaTek has secured a higher share in TPU 8t and the subsequent TPU v9. TPU-related revenue in 2027F and EMIB-T execution in 2028F will affect the pace at which Asian semiconductor profits spread from GPUs to ASICs.
Servers are not just about GPUs. Nomura also raises AI server and general-purpose/CPU server revenue, indicating that agentic AI, inference workloads, and memory price increases are lifting server ASPs together. BMC, CPU packaging, testing, ODMs, and power/thermal solutions are beginning to gain independent pricing logic, rather than remaining mere appendages to GPU shipments.
PCB and CCL are entering a second round of price increases. VR200, Rubin Ultra, Google TPU 8t/8i, and Trainium 3 are all pushing requirements higher for layer count, low-loss materials, and HDI. Opportunities for EMC, Taiflex, ZDT, Unimicron, Victory Giant, WUS Printed Circuit, and others come from specification upgrades and supply shortages, not just growth in AI server volumes. The key question is not simply whether capacity is being added, but whether M8/M9, HVLP3/HVLP4, mSAP, customer qualification, and yield can all open up at the same time.
The biggest risks are cash flow and 2028 technology validation. Hyperscale cloud providers may face a conflict in 2027F between upward revisions to AI capex and insufficient free cash flow, especially if memory costs keep rising. Technically, EMIB-T, CoPoS, GPU-on-GPU SoIC, CPO, 336G/448G SerDes, M9Q/M10Q PCB, and PTFE materials still need validation. If 2028F data-center project visibility stalls, EMIB-T yield disappoints, or WoS price increases cannot be passed through, bottleneck assets will be the first to face valuation pullbacks.
I. This Pullback Is Not the End of the Cycle, but the Second Stage of the Bottleneck Trade
The easiest mistake in AI semiconductors is to apply traditional semiconductor-cycle signals directly to the current environment. Price increases, long-term agreements, excess ordering, and customers competing for capacity often signal that a peak is approaching in a traditional cycle. This time, however, demand is not coming from smartphone, PC, or automotive inventory. Cloud providers, AI labs, and neoclouds are turning data centers into a new layer of production infrastructure. Price signals have indeed heated up and valuations are crowded, but that does not mean the delivery cycle has ended.
Nomura frames the issue clearly: the near-term pullback has reasonable causes. The market needs to digest what may be a historically large component mismatch, free-cash-flow pressure among cloud providers in 2027F, uncertainty around technology roadmaps after 2028F, and valuation pressure from rising long-end U.S. rates. But these risks do not change the core fact: if more GW-scale data centers still need to come online in 2027F, while greenfield capacity expansion only truly starts from late 2025, supply will remain tight next year. Under this framework, the pullback looks more like a repricing of risk by capital markets than the end of the fundamental cycle.
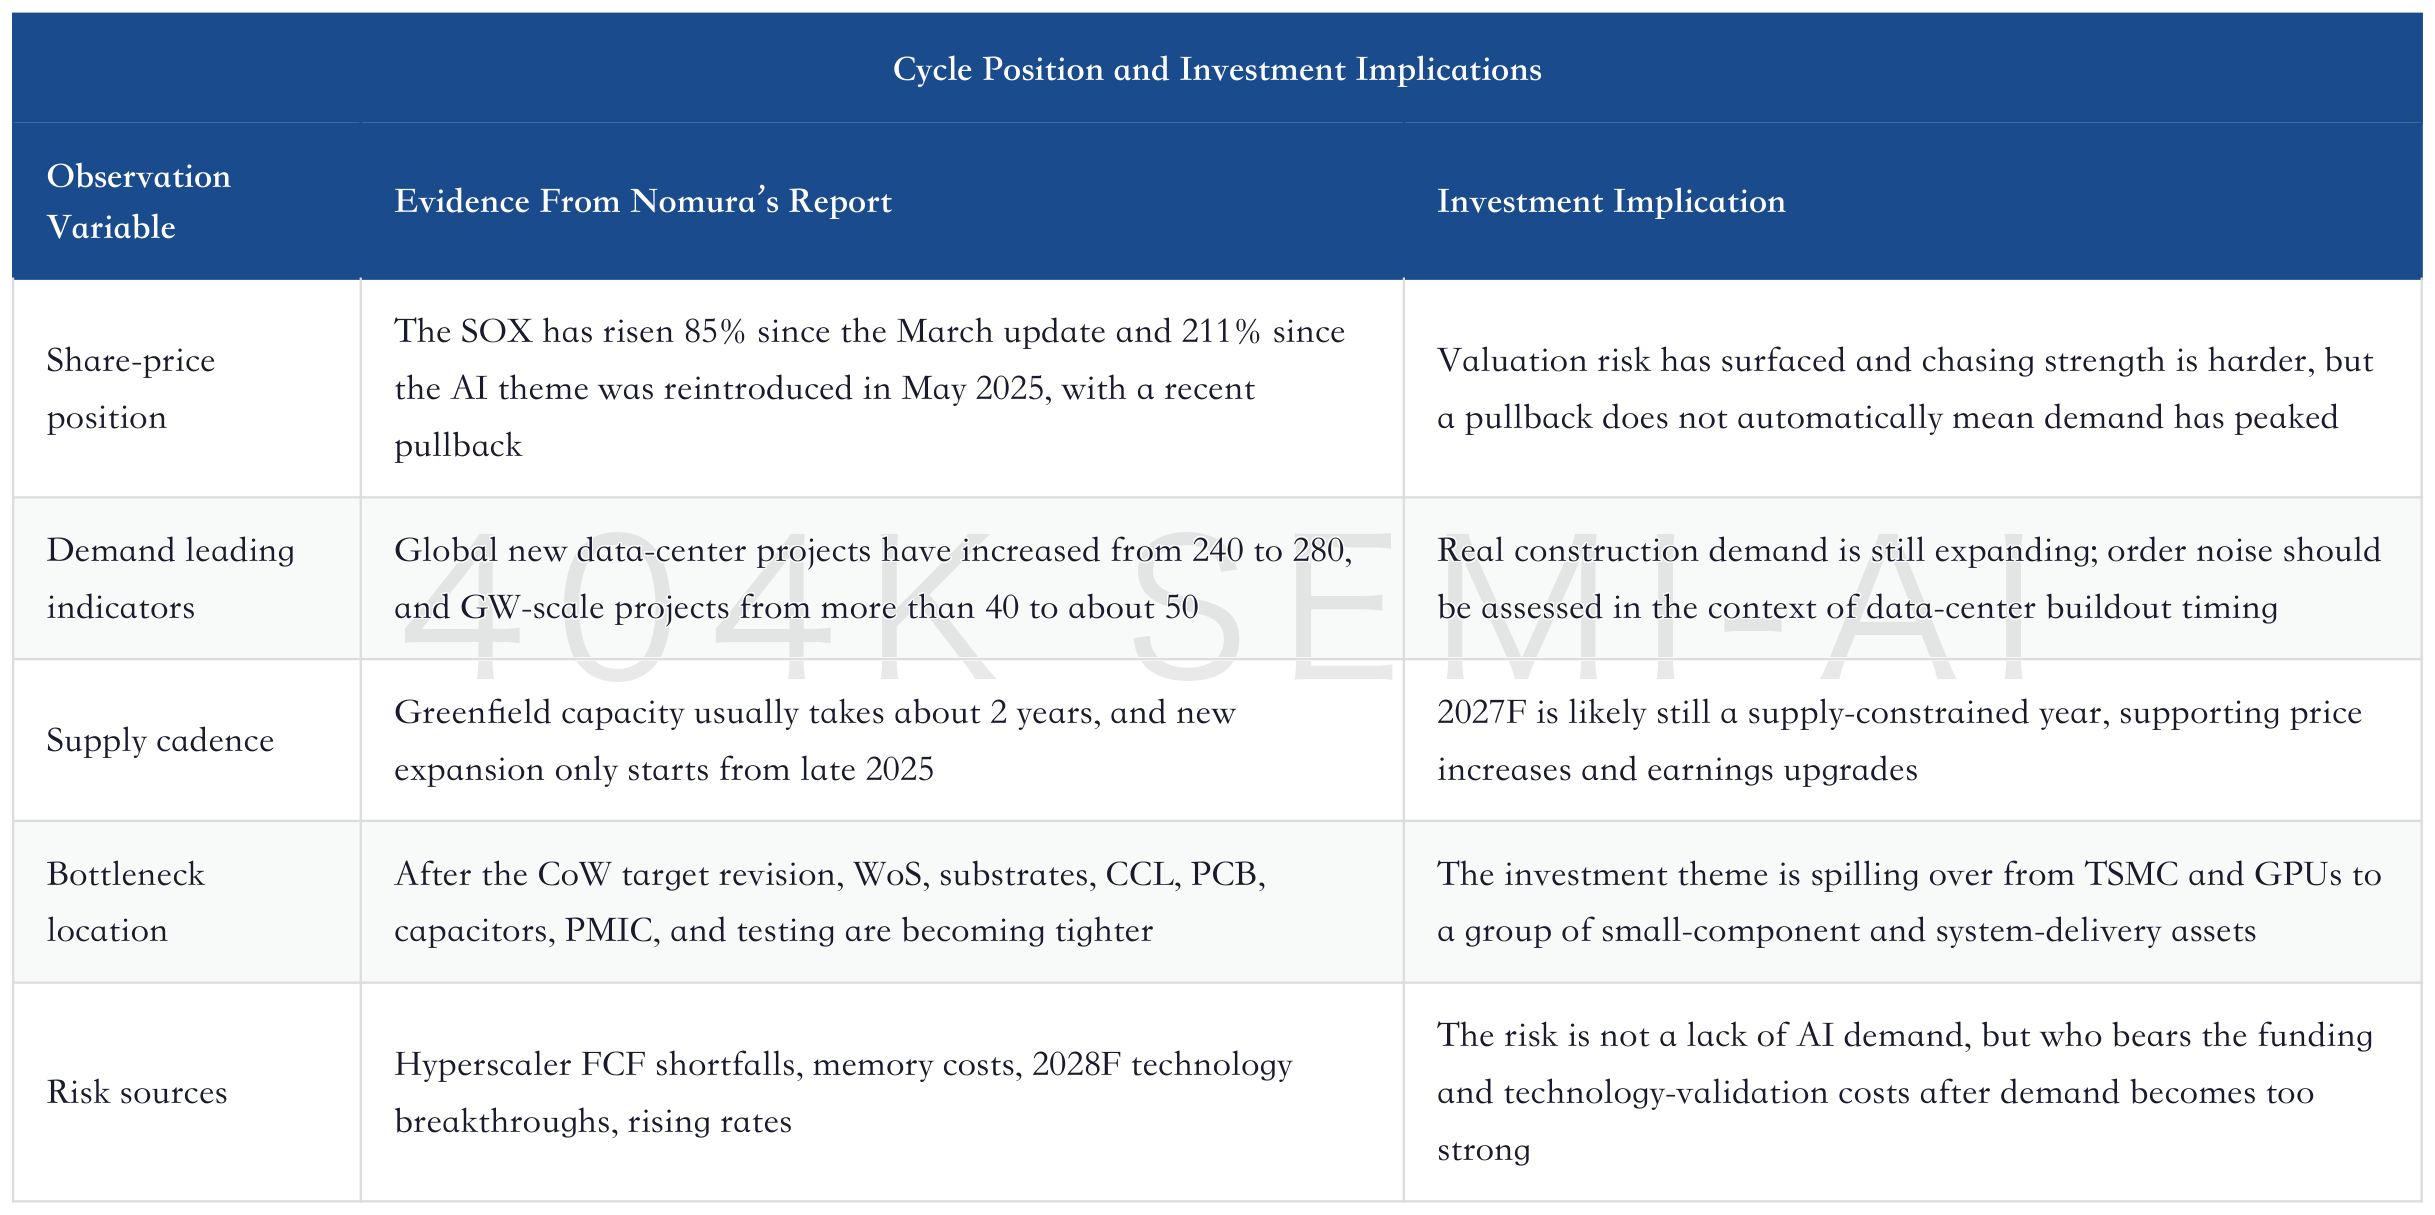
This means the investment hierarchy needs to change. The first stage was buying “GPU supply shortage.” The second stage is buying “who enables GPUs, TPUs, and CPUs to actually come online.” If data centers have already secured power, land, financing, and customer demand, hardware shortages will spread along the value chain: advanced packaging first, followed by WoS, testing, substrates, CCL, PCB, power, liquid cooling, BMC, connectors, and ODM delivery. This diffusion will create more opportunities, while also making low-quality beta easier to eliminate.
The core conclusion of this report can be stated upfront: AI semiconductors have not entered an easy phase. They have entered a harder selection phase. Nvidia, Google, and TSMC remain the systemic core, but 2027F share-price upside is more likely to come from underappreciated small gatekeepers: whose capacity cannot be replicated quickly, whose customer qualification cycle is longer, whose pricing can be passed through, and whose gross margin can keep rising during expansion.
II. Demand Side: Data-Center Construction Gives the Answer Earlier Than Supply-Chain Orders
Sell-side models are easily disturbed by order revisions; data-center construction is closer to real demand. Nomura began tracking global new data-center construction plans in 4Q25 and uses them as a leading indicator for Asian semiconductor hardware demand. The value of this method is that it does not only look at how many orders a given GPU or ASIC customer has placed. It examines whether power, land, campuses, partners, and launch schedules are still moving forward. As long as these construction plans do not disappear, hardware-chain demand will not go to zero because of a change in one quarter’s pull-in cadence.
The three most important numbers in this update are: project count increased from about 240 to about 280; GW-scale projects increased from more than 40 to about 50; and 2027F incremental deployment was revised up from 28GW to 32GW, while visible 2028F demand rose from 21GW to 23GW. 2026F remains broadly unchanged at 26GW, indicating that near-term timing has not moved forward sharply, but construction pressure in 2027F is heavier. In other words, the next year is not about “whether there is demand,” but “which hardware can keep up with the construction schedule.”
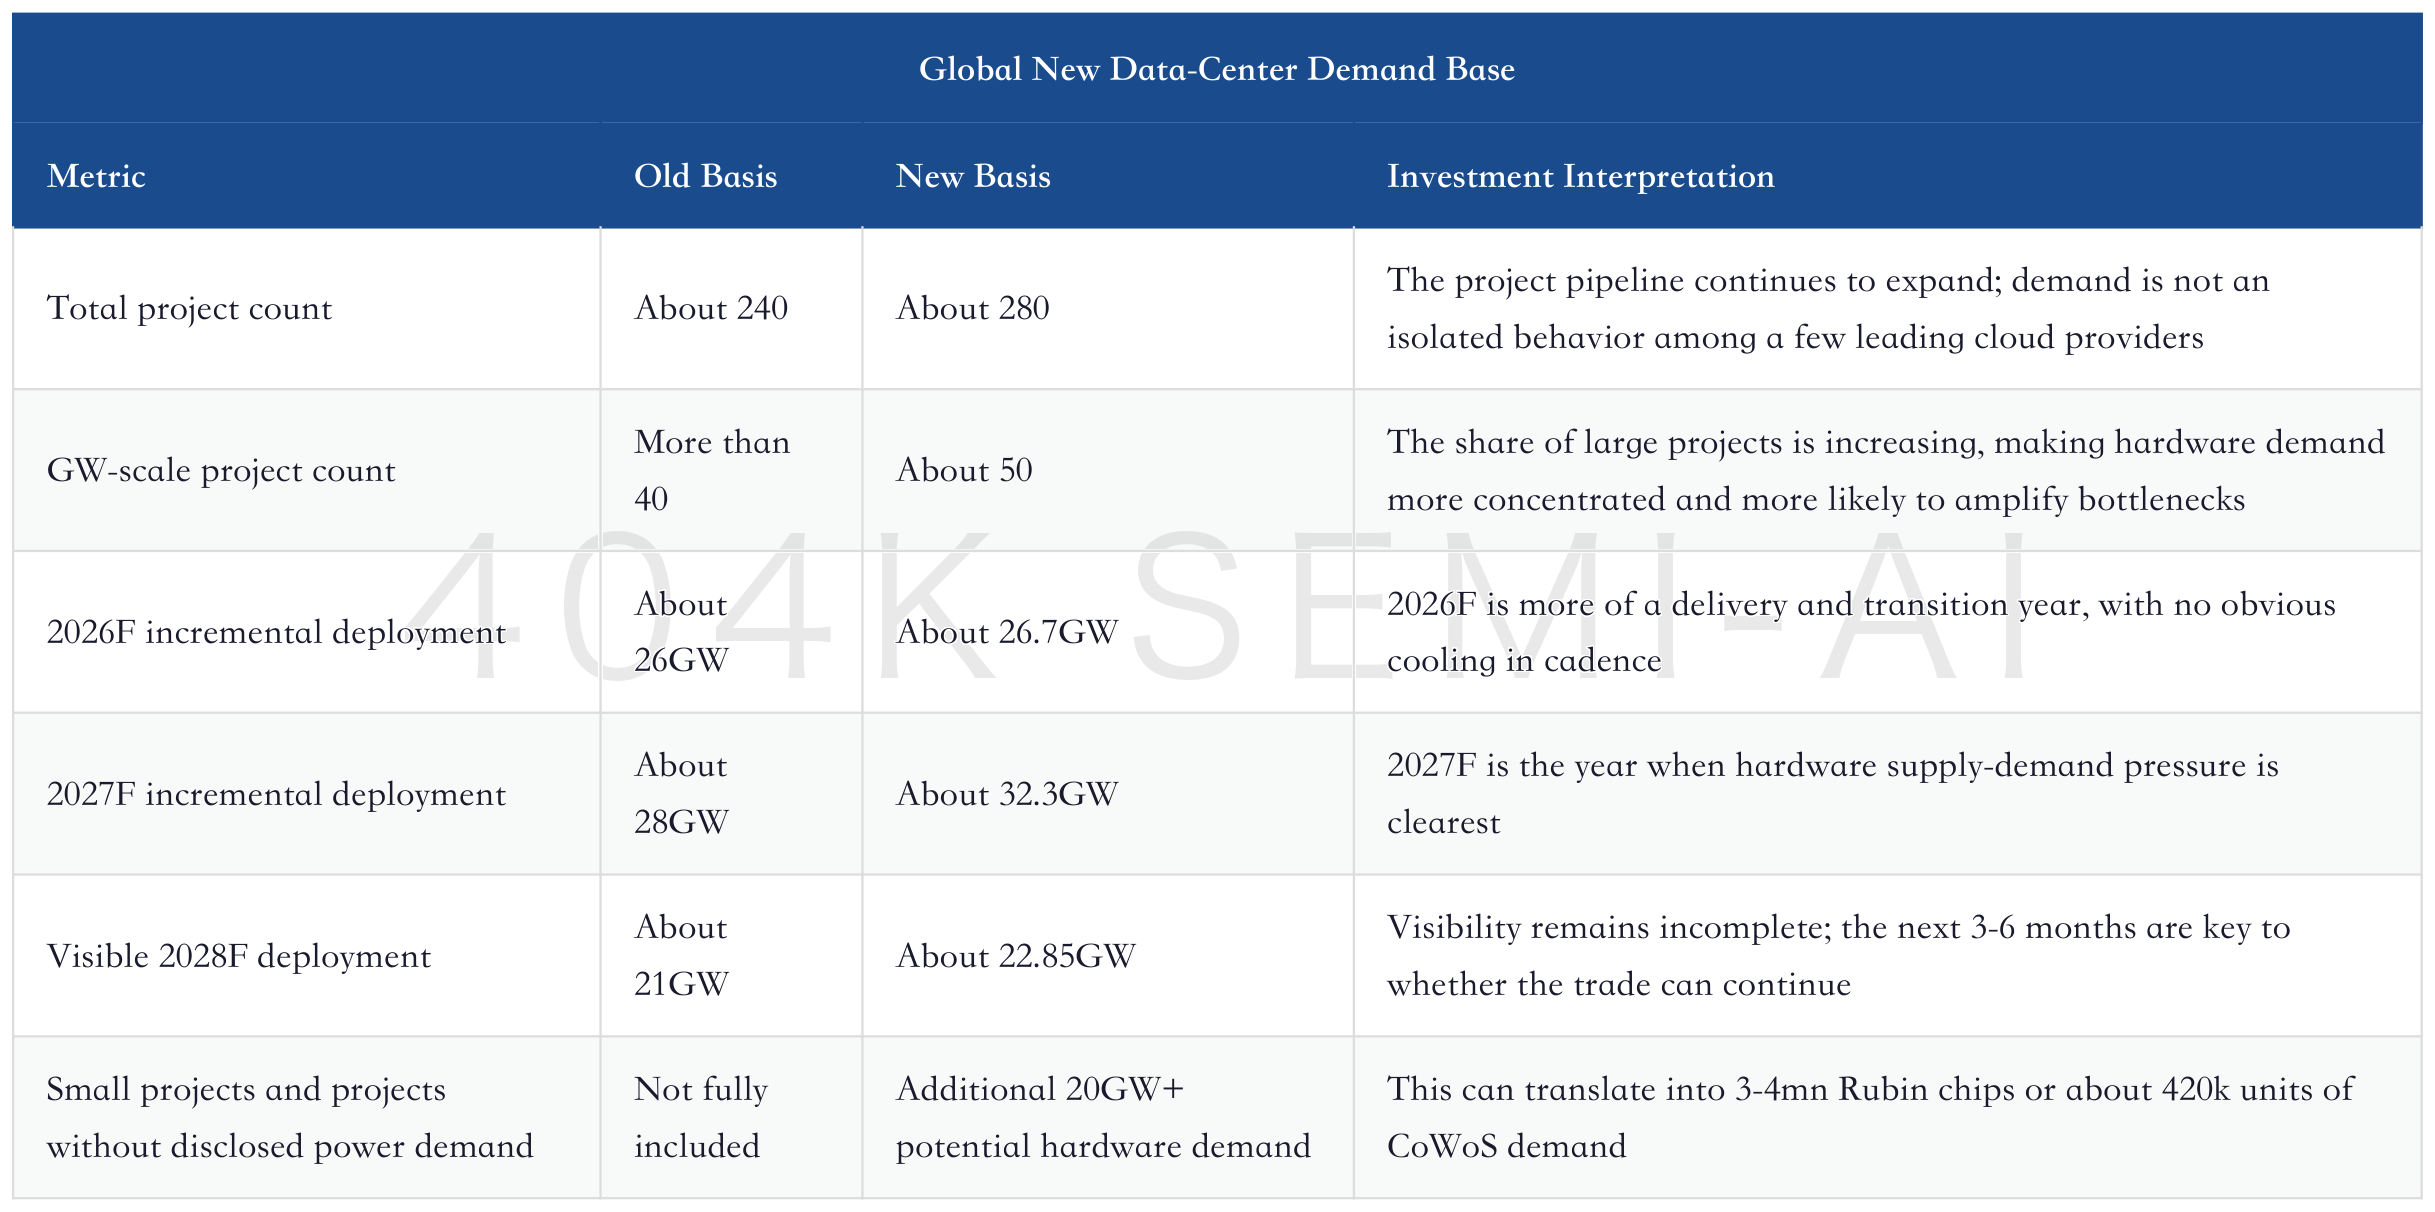
The demand structure is even more notable. The top-four CSPs remain important, but an increasing number of new projects are coming from new infrastructure participants such as OpenAI, Anthropic, CoreWeave, Nebius, HUMAIN, SoftBank Group, SK Telecom, xAI, and IREN. OpenAI and Nvidia’s 10GW project, OpenAI and Broadcom’s 10GW ASIC plan, Google Texas 6.2GW, Meta Hyperion’s expansion from 2GW to 5GW, and SoftBank Group’s multi-GW projects in France and Ohio are turning AI hardware demand from “cloud capex” into broader AI-factory capital spending.
This change will shift how the supply chain should be tracked. In the past, monitoring the capex of the four major cloud providers and Nvidia’s data-center revenue could explain most hardware demand. Now investors also need to track whether AI labs can secure financing, whether neoclouds can obtain customers, whether projects have power access, and whether racks can be delivered at the system level. The supply chain will face more customers, but customer quality will also diverge more. High-quality bottleneck companies benefit from demand diffusion, while lower-quality segments may be misled by excessive orders.
China’s data-center construction is also accelerating, but Nomura does not include Chinese projects in its CoWoS calculation sample. The reason is that these projects are more oriented toward domestic computing power, with lower direct relevance to TSMC’s advanced-packaging capacity. This treatment is important: it shows that the report is not broadly saying “global AI is strong,” but is filtering for demand that can actually drive Asian AI hardware, especially TSMC, packaging, substrates, PCB, and testing. China’s compute supply chain has its own domestic mapping, but it should not be used simplistically to revise up TSMC CoWoS demand.
The demand-side investment implication is straightforward: the market should not only watch whether GPU orders are revised up, but also whether data-center projects can continue turning power demand into hardware procurement. If 2028F visibility keeps improving over the next 3-6 months, valuations for 2027F bottleneck assets will be easier to support. If 2028F projects are delayed, financing costs rise, and cloud-provider free cash flow comes under pressure, the market will quickly shift from a “price-increase thesis” to “who has the highest-quality demand.”
III. Supply Side: After CoW Targets Were Revised Up, WoS and Small Components Became Bigger Gates
TSMC is not failing to expand capacity this time. Nomura now sees TSMC’s 2027F CoWoS target capacity at 2,000kpcs, materially above the previous assumption of roughly 1,300-1,350kpcs; 2026F is also around 1,100kpcs. The issue is that CoWoS is not a single process step. The market tends to treat it as TSMC packaging capacity, but actual delivery is jointly determined by CoW and WoS: CoW attaches chips to wafers and integrates interposers with dies; WoS attaches the wafer-level package to the substrate after wafer-level packaging, involving substrates, substrate supply, materials, outsourced packaging, and yield.
Nomura’s counterintuitive view is that once TSMC-controlled CoW becomes more aggressive, WoS, which is not fully controlled by TSMC, may instead become the bigger bottleneck. This matters for investing. If the bottleneck remains in CoW, TSMC and advanced packaging equipment are the most direct beneficiaries; if the bottleneck migrates to WoS and small components, ASE, Amkor, IC substrates, CCL, PCB, testing, BMC, PMIC, capacitors, and optical components all enter the pricing chain. In other words, TSMC’s capacity expansion has not weakened the bottleneck trade; it has fragmented it.
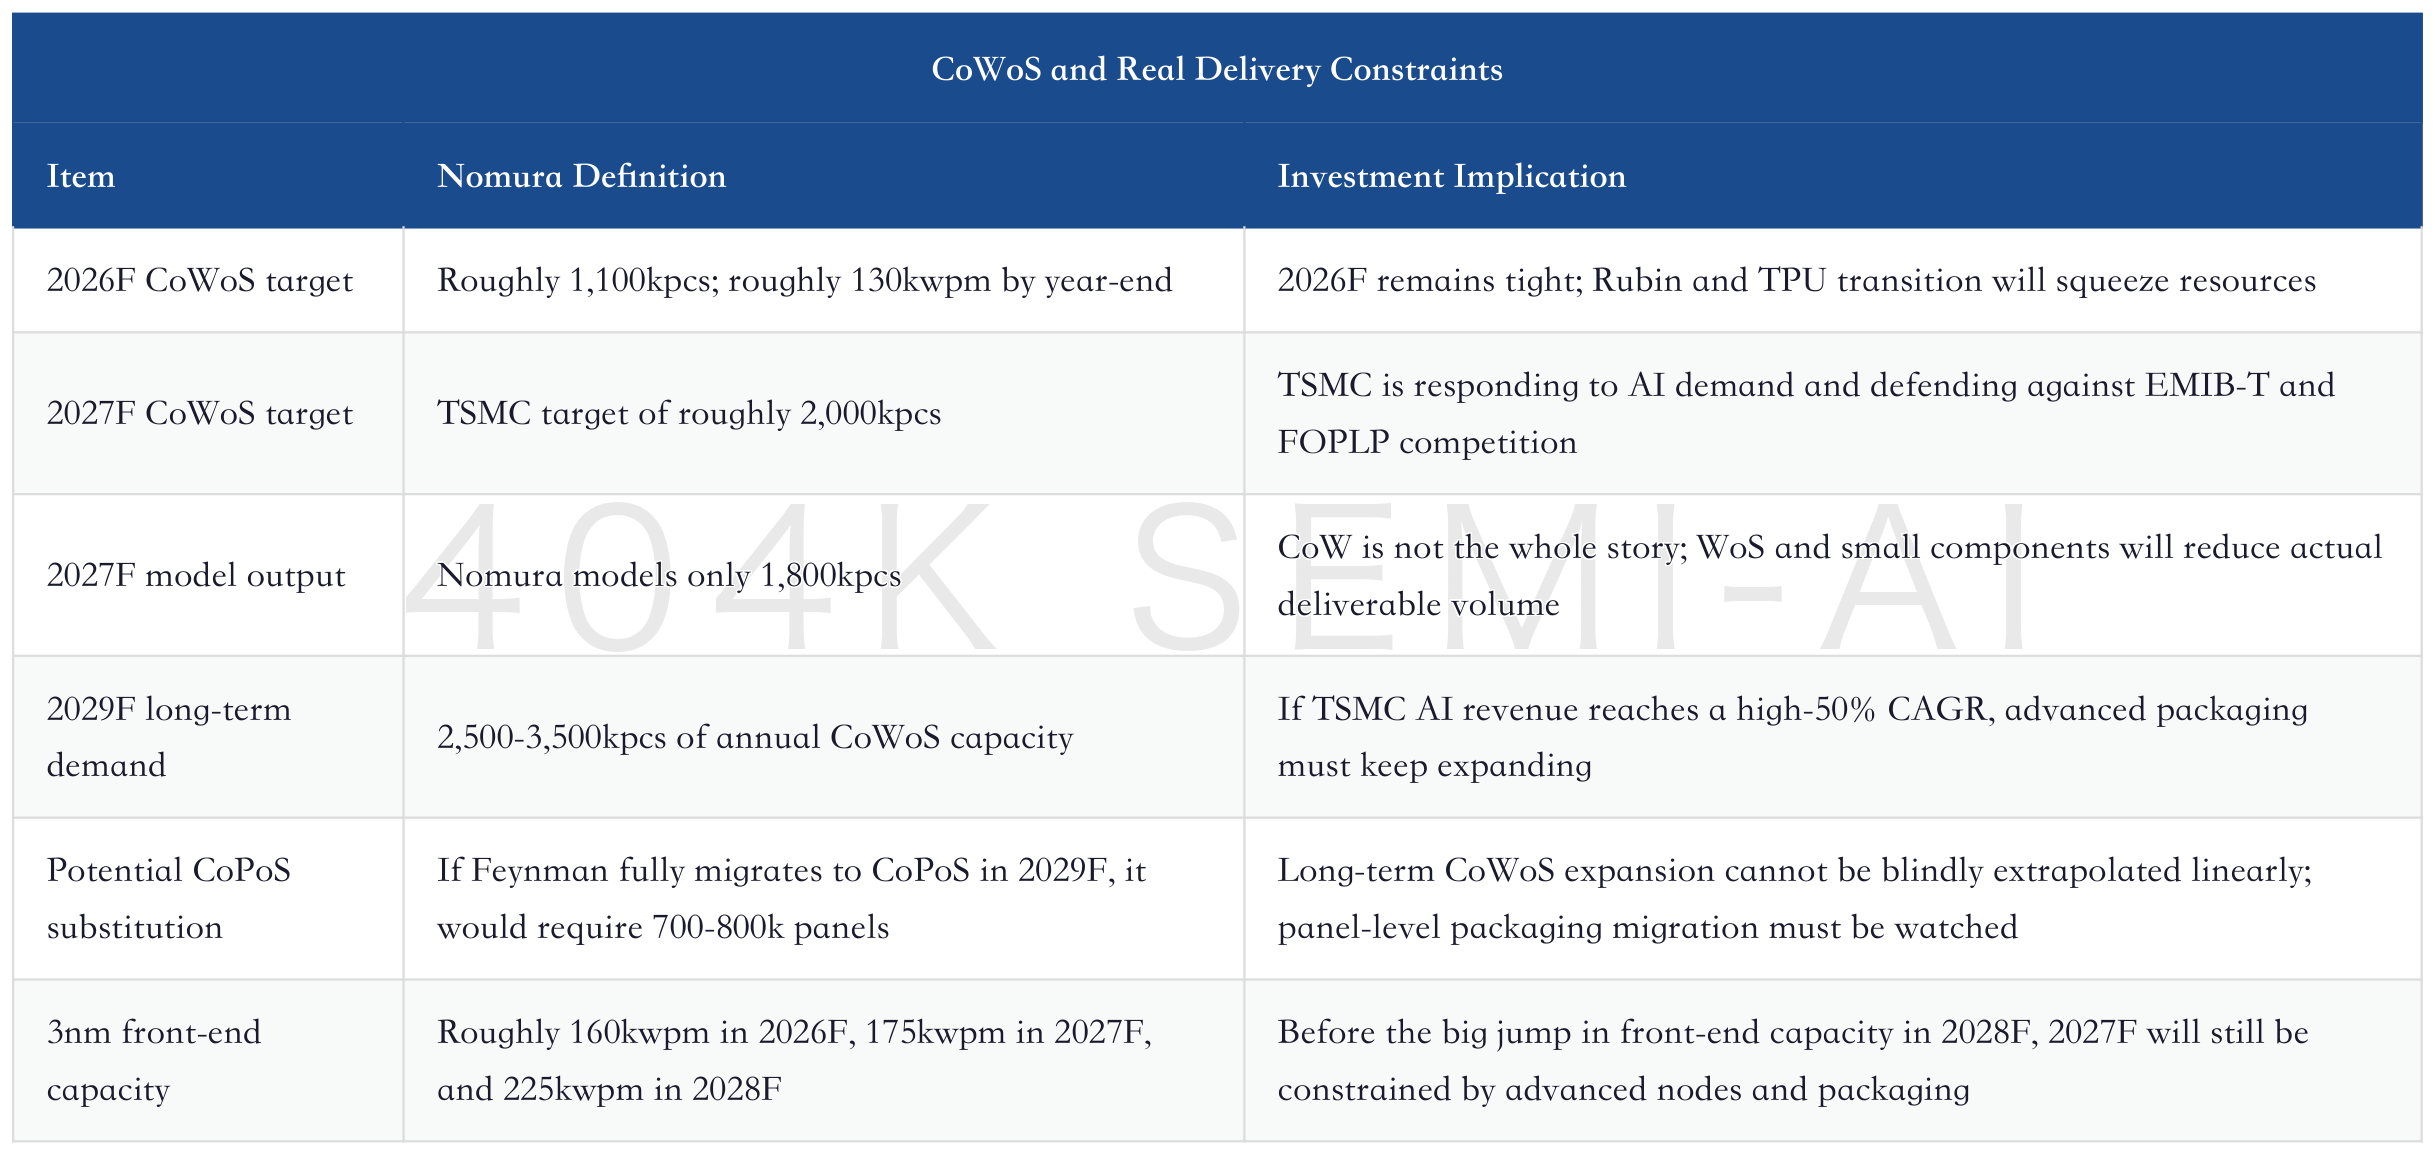
There is also a long-term issue that is easy to overlook: if Feynman moves to CoPoS in 2029F, why would TSMC not expand CoWoS indefinitely? Nomura’s “back-of-the-envelope” estimate is instructive. If NVIDIA still takes roughly 50% of advanced packaging supply in 2029F, Feynman alone could consume roughly 1,400kpcs of CoWoS; but if Feynman migrates to 310x310mm CoPoS panels, TSMC would need 700-800k panels rather than an equivalent wafer-based CoWoS volume. This explains why TSMC is both aggressive and cautious: it must meet Rubin and TPU demand in the short term, while avoiding putting all capex behind linear CoWoS expansion over the long term.
This is also why 2027F will not be a simple year of “capacity increases and prices fall.” When many component suppliers made expansion plans in 2H25, they underestimated the upside potential in AI orders, especially smaller component suppliers, which reacted more slowly than TSMC. As a result, by 2H26F, Rubin, Trainium 3, TPU 8t/8i, CPUs, and high-end server motherboards will ramp together, simultaneously tightening PCB/CCL, IC substrates, high-end capacitors, PMIC, optical components, test interfaces, and BMC. Price increases are not driven by greed in any single segment, but by unsynchronized expansion across the supply chain.
The real debate is here: is bottleneck migration bad or good? In the short term, it will create greater share-price volatility because the market will worry that component shortages may affect system shipments. In the medium term, it may instead extend the cycle, because supply can no longer be solved by one giant expanding capacity. As long as demand remains, the more dispersed the bottlenecks, the easier it is for price increases and earnings upgrades to rotate across more companies.
IV. GPU and TPU Revenue Split Reset: NVIDIA Remains the Largest, While Google and MediaTek Capture Marginal Elasticity
The sharpest line in Nomura’s report can be translated into one supply-chain reality: when elephants fight, the grass gets trampled. The elephants here are NVIDIA and Google. NVIDIA remains the largest contributor to TSMC AI revenue, while Google TPU is the fastest-growing ASIC force in 2027F. Together, they are competing for advanced packaging, 3nm, substrates, CCL, and testing resources. Other GPU/ASIC customers may have real demand, but could still be squeezed by lower scheduling priority.
NVIDIA still takes the largest resources, but Google TPU’s marginal upward revision is faster. This does not mean NVIDIA is weakening; it means Google TPU is lifting TSMC AI revenue, CoWoS allocation, and ASIC supply-chain share at the same time. Beneficiaries include not only Google’s own accelerator ecosystem, but also MediaTek, Broadcom, TSMC, ASE, King Yuan Electronics, and CCL/PCB suppliers.
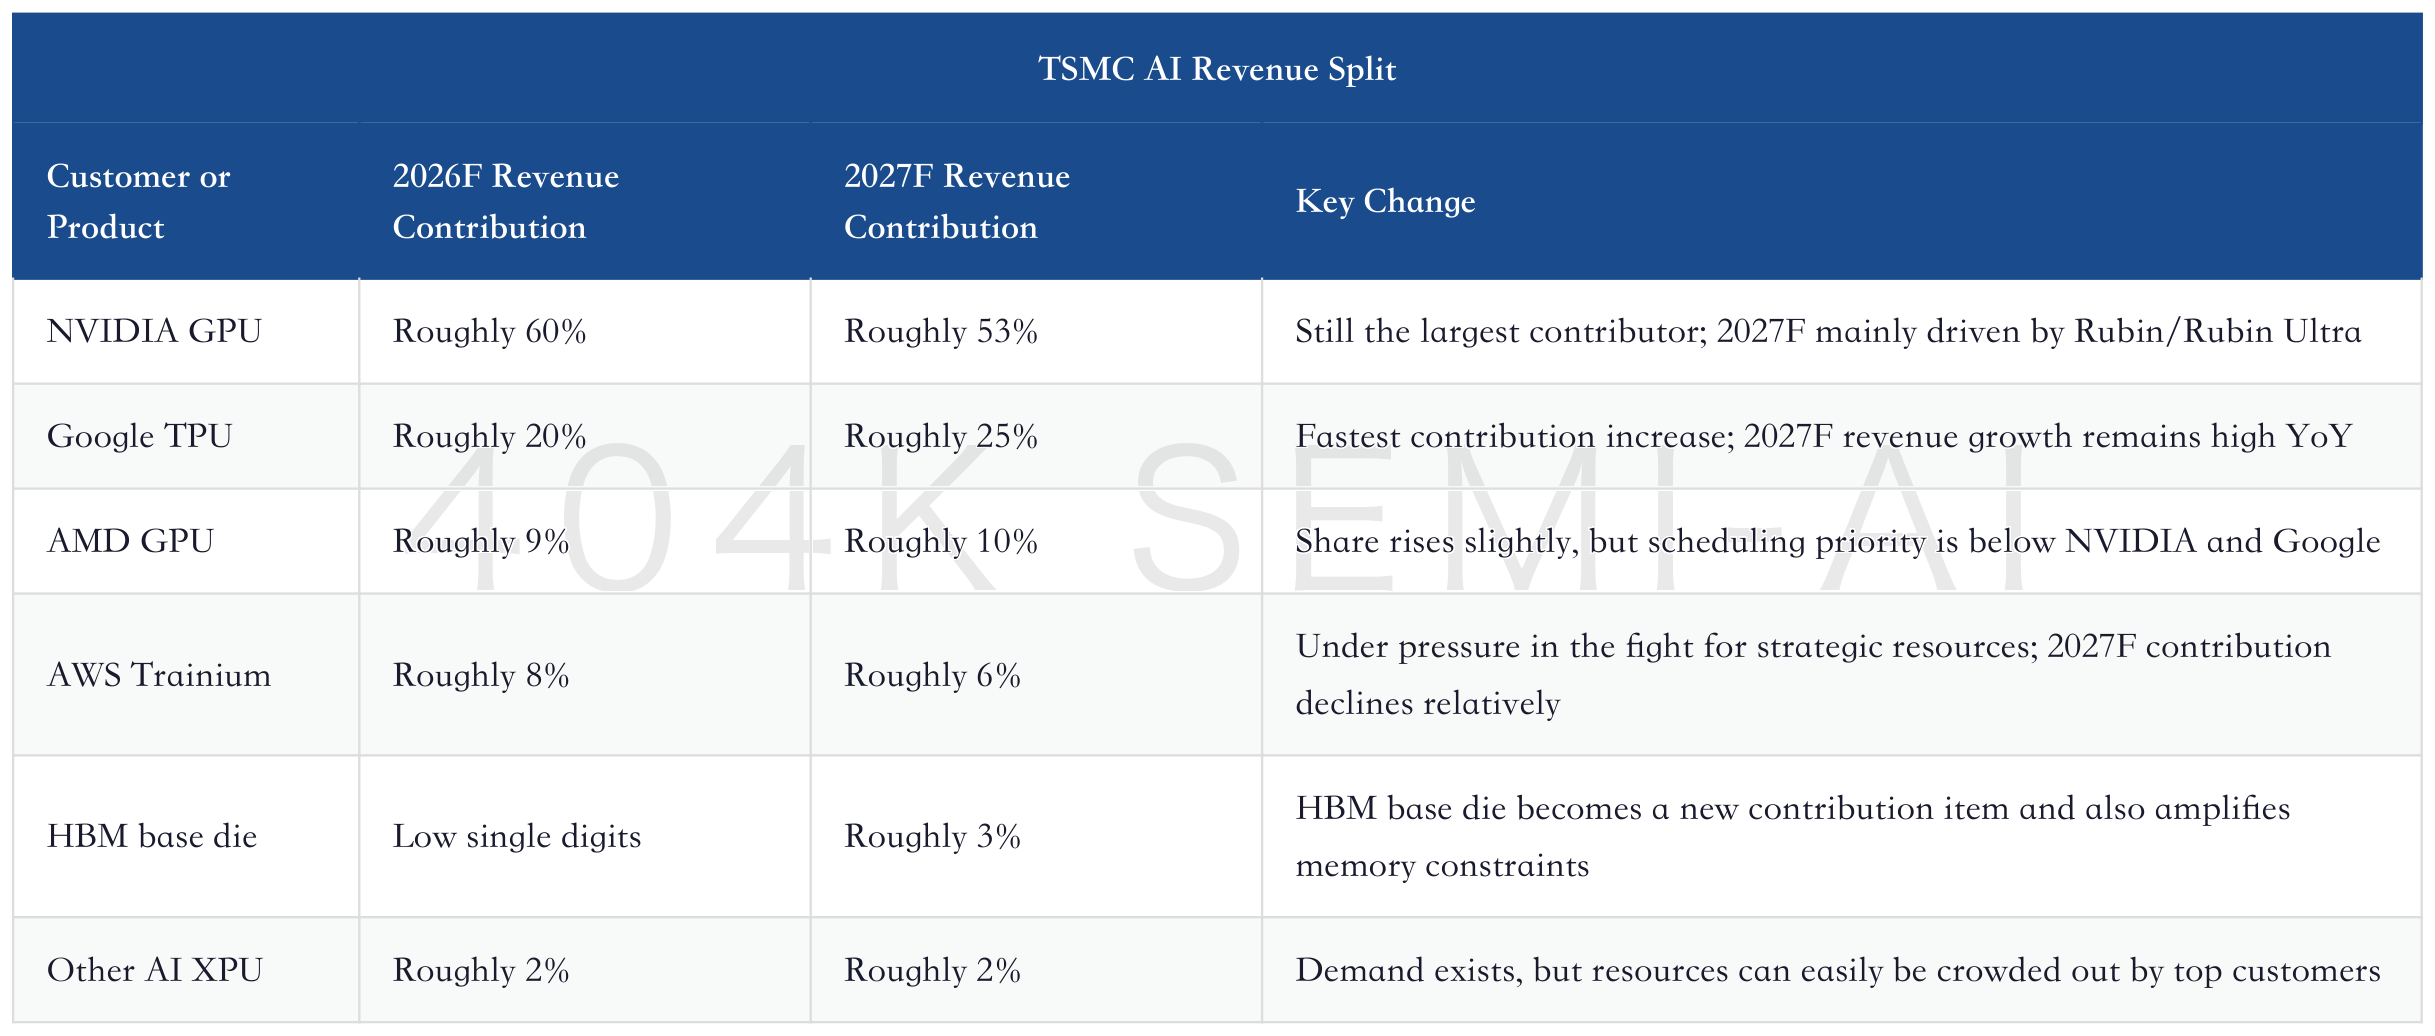
MediaTek is the company with the most elasticity in this chain. Nomura raised its target price not because of a traditional smartphone-chip recovery, but because of upward revisions to Google TPU and non-TPU ASIC contributions. Management has also pulled forward its ASIC share target and raised near-term revenue guidance at the same time, showing that the market is repricing MediaTek from a “smartphone SoC cycle stock” into an “ASIC design platform in the Google TPU chain.”
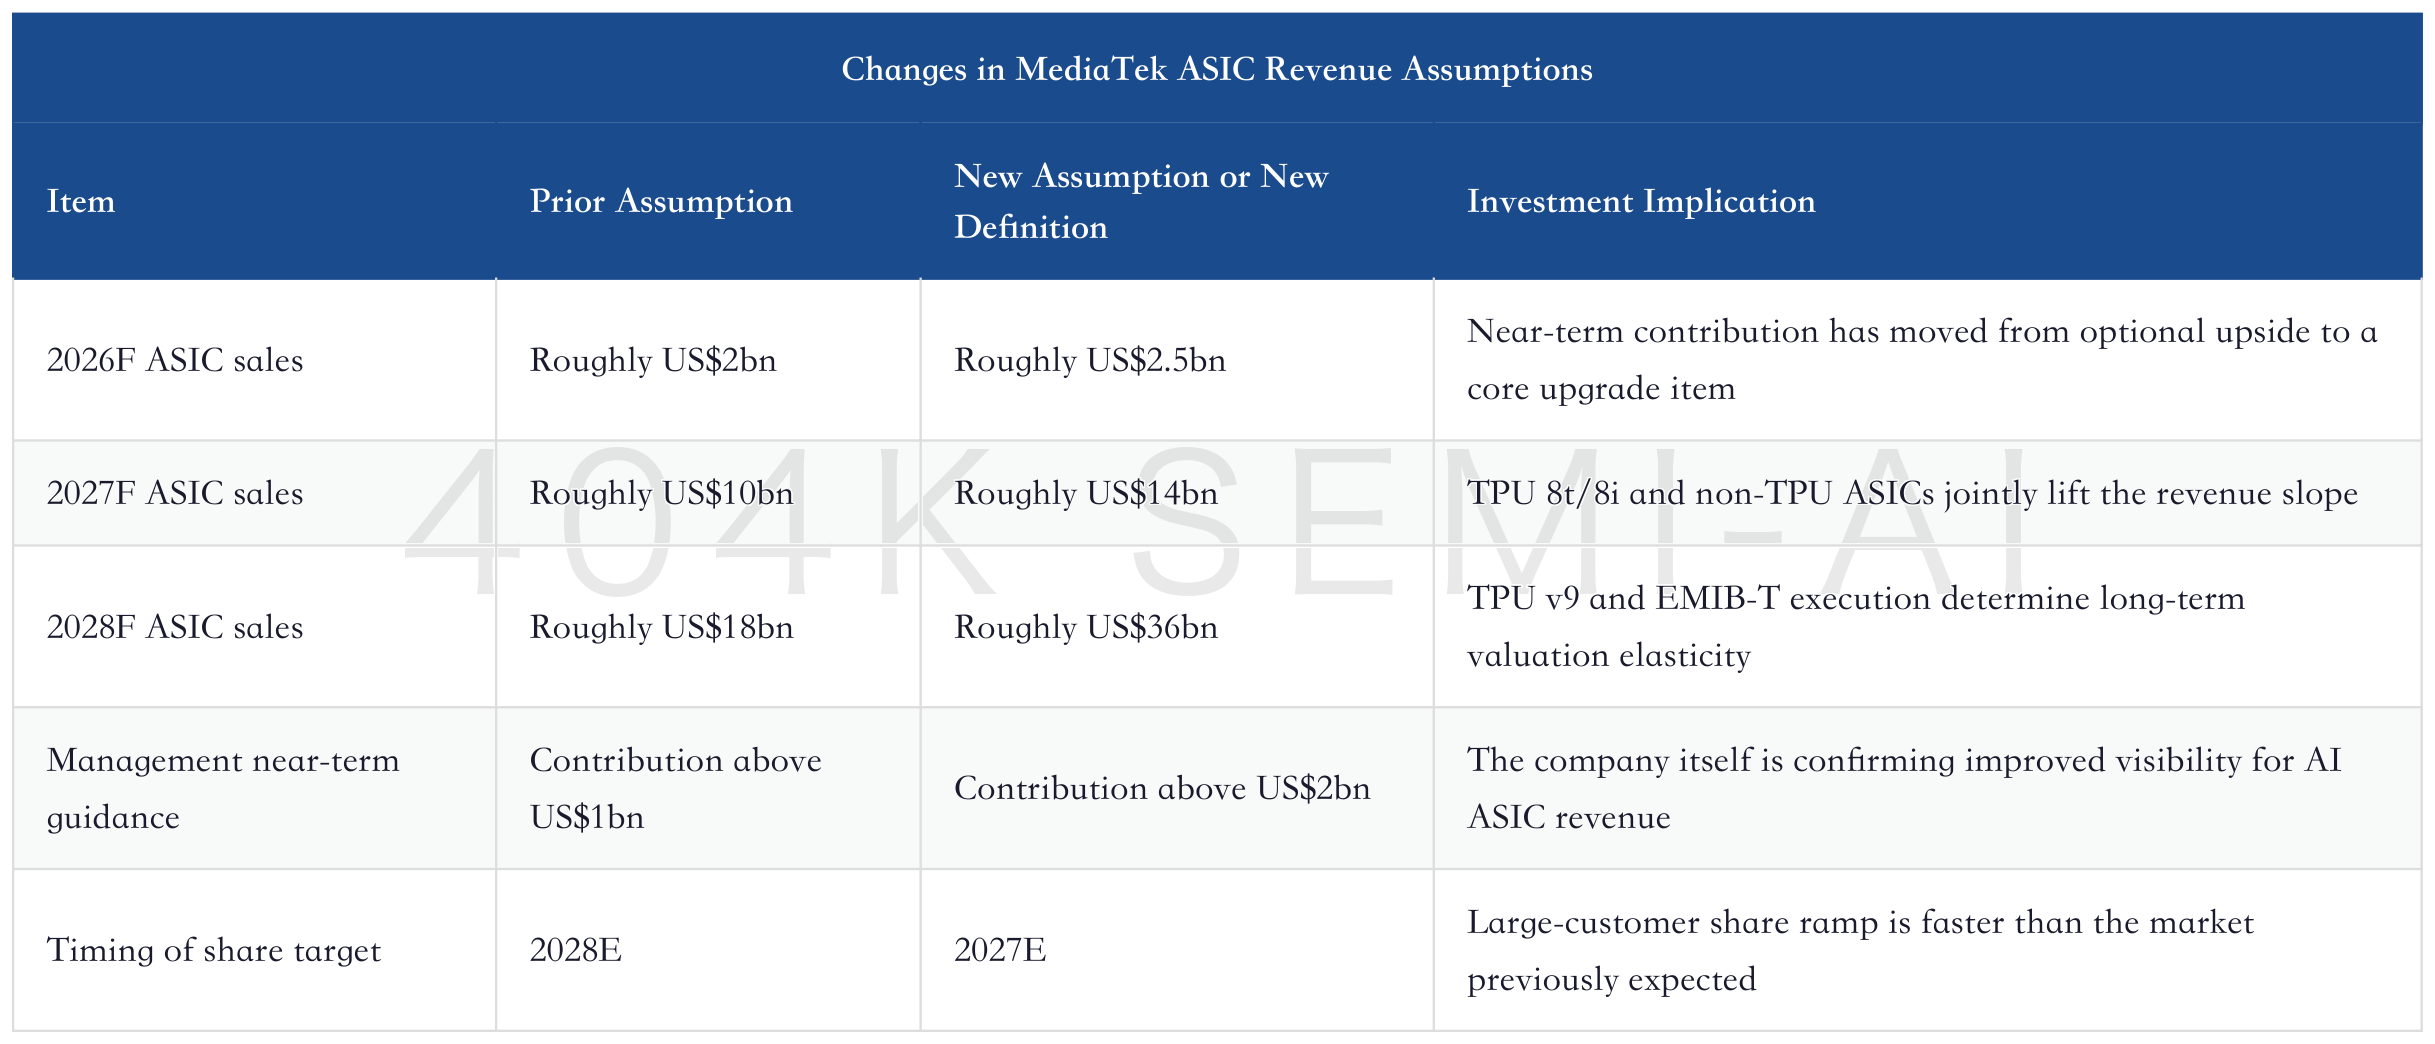
The risks around TPU are also clear. TPU v9 in 2028F may use Intel EMIB-T, with higher MediaTek participation, but EMIB-T still needs to prove yield, packaging complexity, and mass-production cadence. The report notes that TPU v9 could have close to 30 silicon bridges embedded in a large substrate, with specifications deviating from the current AI/HPC substrate architecture; mass-production yield should not be assumed lightly. For investors, this means MediaTek has high elasticity but also clear technical validation milestones: tape-out by end-2026, 2028F ramp, and Intel’s advanced packaging execution capability.
NVIDIA’s marginal change is not “weak demand,” but product cadence and system form factor. Rubin production may not see a significant volume ramp until 4Q26F, with large-scale rack shipments coming even later; Rubin Ultra starts production from 2027E, and its packaging form factor may move back closer to Rubin’s two-GPU-die package from the previously more complex dual-Rubin module interconnect. This would make the Rubin Ultra transition smoother, but also shows that CPO/NPO, Oberon, HBM4, and small-component maturity are still affecting platform cadence.
The investment conclusion for this chain is: GPU remains the base, TPU is the marginal elasticity, and other ASICs depend on whether they can obtain strategic resources. Simply saying “ASICs will replace GPUs” is too crude. A more accurate statement is that AI compute is entering a phase where multiple customers, multiple packaging routes, and multiple small-component bottlenecks coexist. NVIDIA will not lose platform power, but Google TPU will change profit allocation for TSMC, MediaTek, Broadcom, CCL/PCB, and testing suppliers.
V. Server Demand Continues to Be Revised Upward: CPU, BMC, and OSAT Begin to Develop Independent Logic
The server market is moving from “GPU servers standing alone” to “AI servers and CPU servers being revised up together.” Nomura raised total server revenue, AI server revenue, and general-purpose/CPU server revenue at the same time, indicating that demand is not concentrated only in GPU racks. This mix is important: even if GPU shipment timing fluctuates, CPU servers, head-node CPUs, AI inference servers, and agentic AI workloads are still pulling the entire server supply chain.
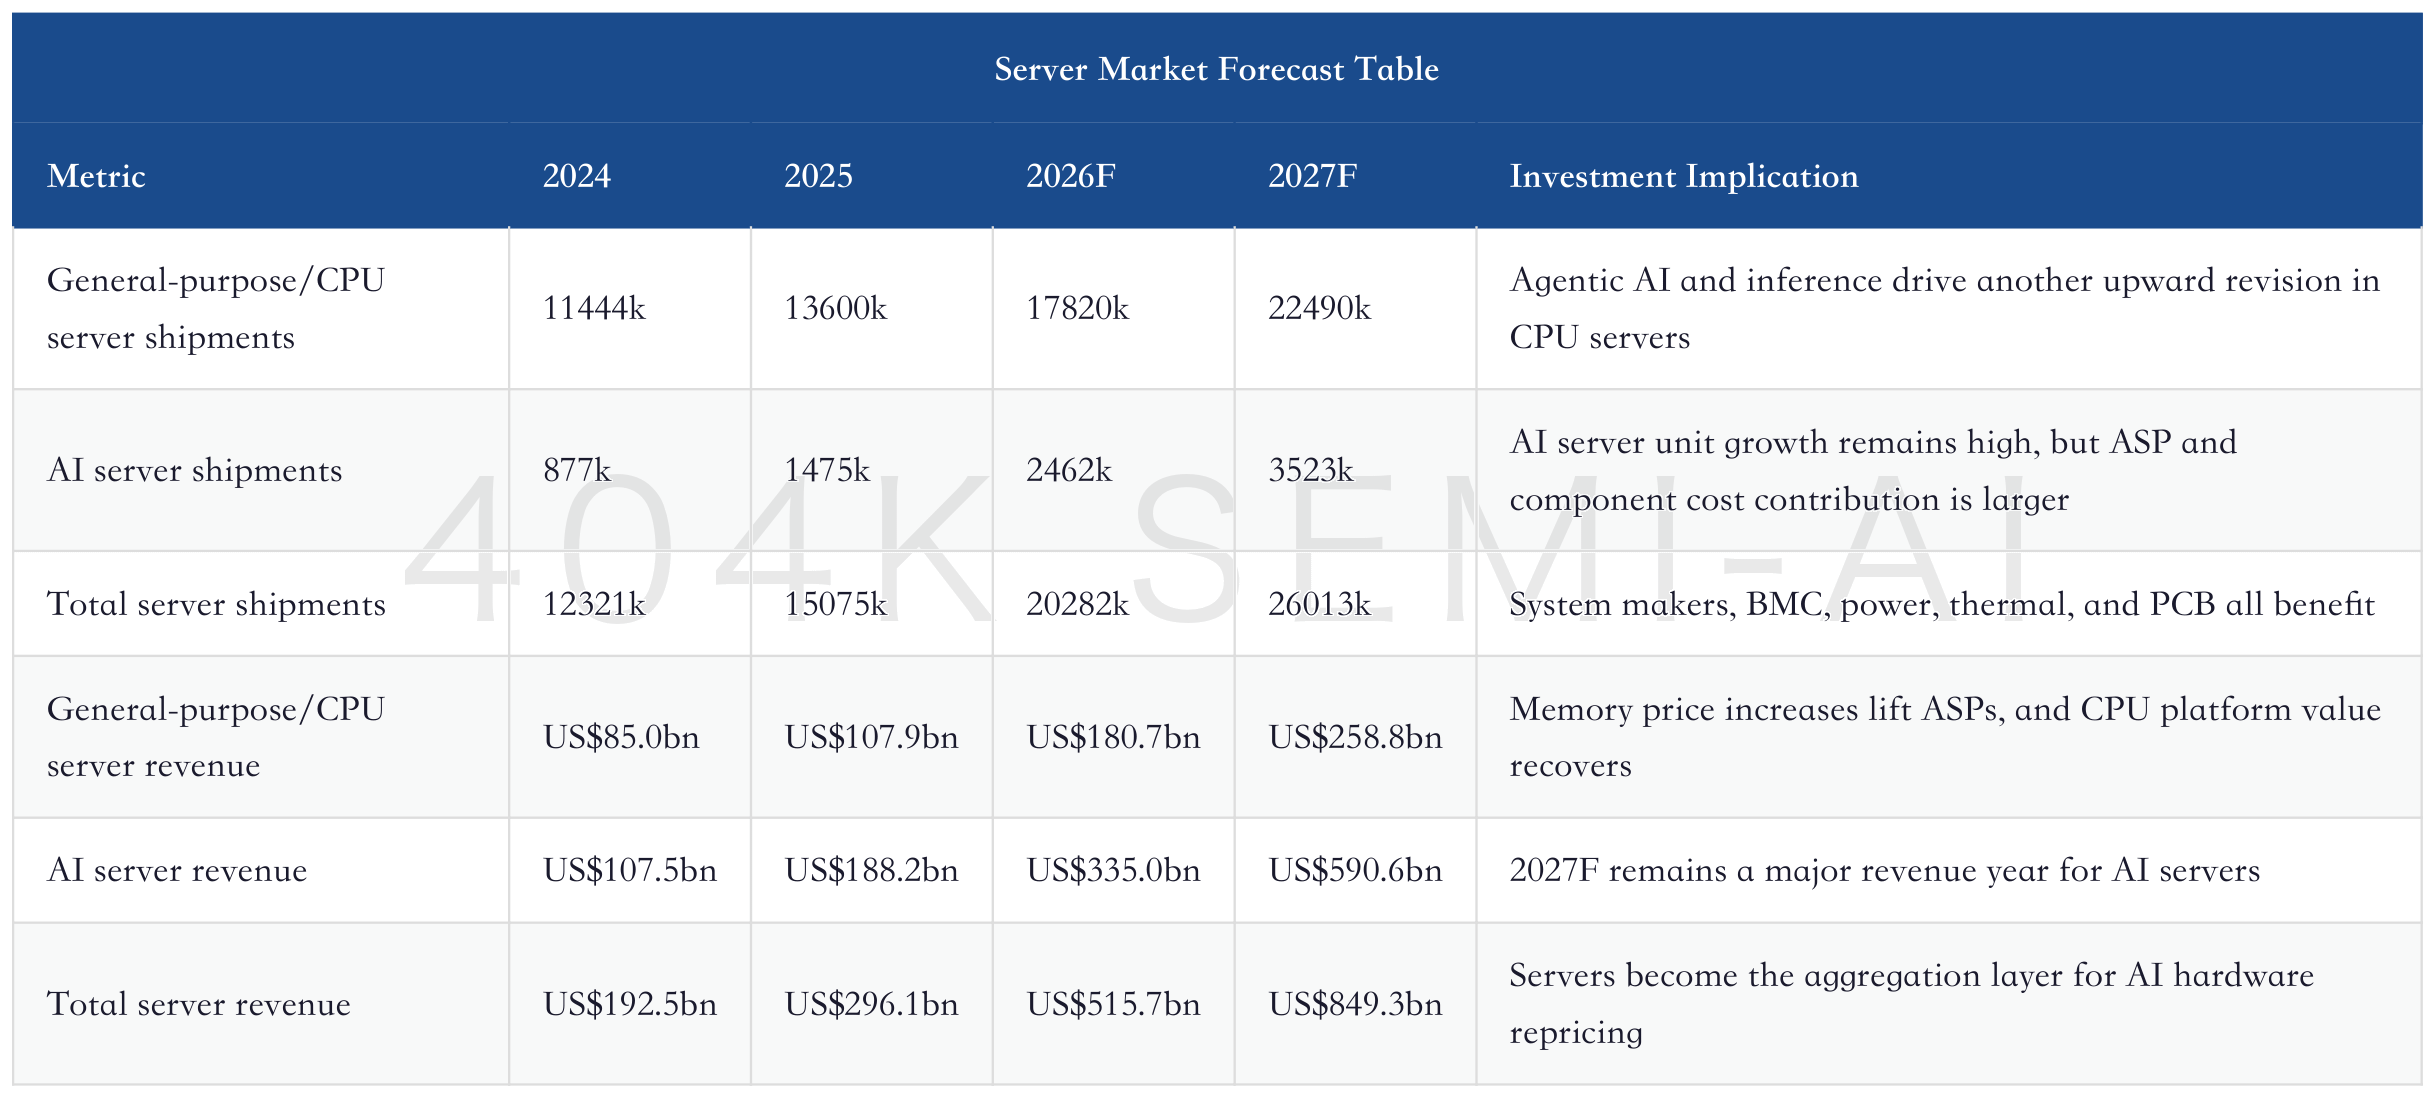
Nvidia racks are also being revised up, but the cadence is more nuanced. Nomura raised its 2026F realistic shipment forecast for GB/VR racks from 50k units to 54.5k units, with VR200 accounting for 15-20%, concentrated in 4Q26F. It also added a 62k-unit forecast for 2027F and assumes the transition from Rubin to Rubin Ultra may occur in 2Q27F. The HGX versus GB/VR mix has also been adjusted: HGX’s 2026F share rises from 18% previously to 30%, because after Rubin is affected by bottlenecks, Nvidia needs more Blackwell GPUs to satisfy committed CoWoS consumption. By 2027F, the market returns to a state where VR200 demand is stronger than supply.
This sends two signals to ODMs and system delivery vendors. First, system makers are not just “contract manufacturers”; during the transition period, they absorb configuration changes, yield issues, inventory, and component shortages. Second, neoclouds will play a larger procurement role during the GB300-to-VR200 transition, helping AI companies sustain token demand growth. This demand is more complex, and order quality will vary more. Strong ODMs and component vendors will increasingly need customer-screening capabilities.
The OSAT opportunity comes from another direction: advanced CPU packaging. ASE Technology and Amkor may not immediately replace TSMC in high-complexity GPU/ASIC CoW, because high HBM content and immature assembly yields could create large losses. But CPU packaging is low-hanging fruit. CPUs do not have expensive HBM, while RDL line width and layer-count requirements are relatively relaxed. OSATs can first enter CoWoS-like full-process flows through projects such as AMD Venice CPU, Nvidia Vera CPU, and Microsoft Cobalt.
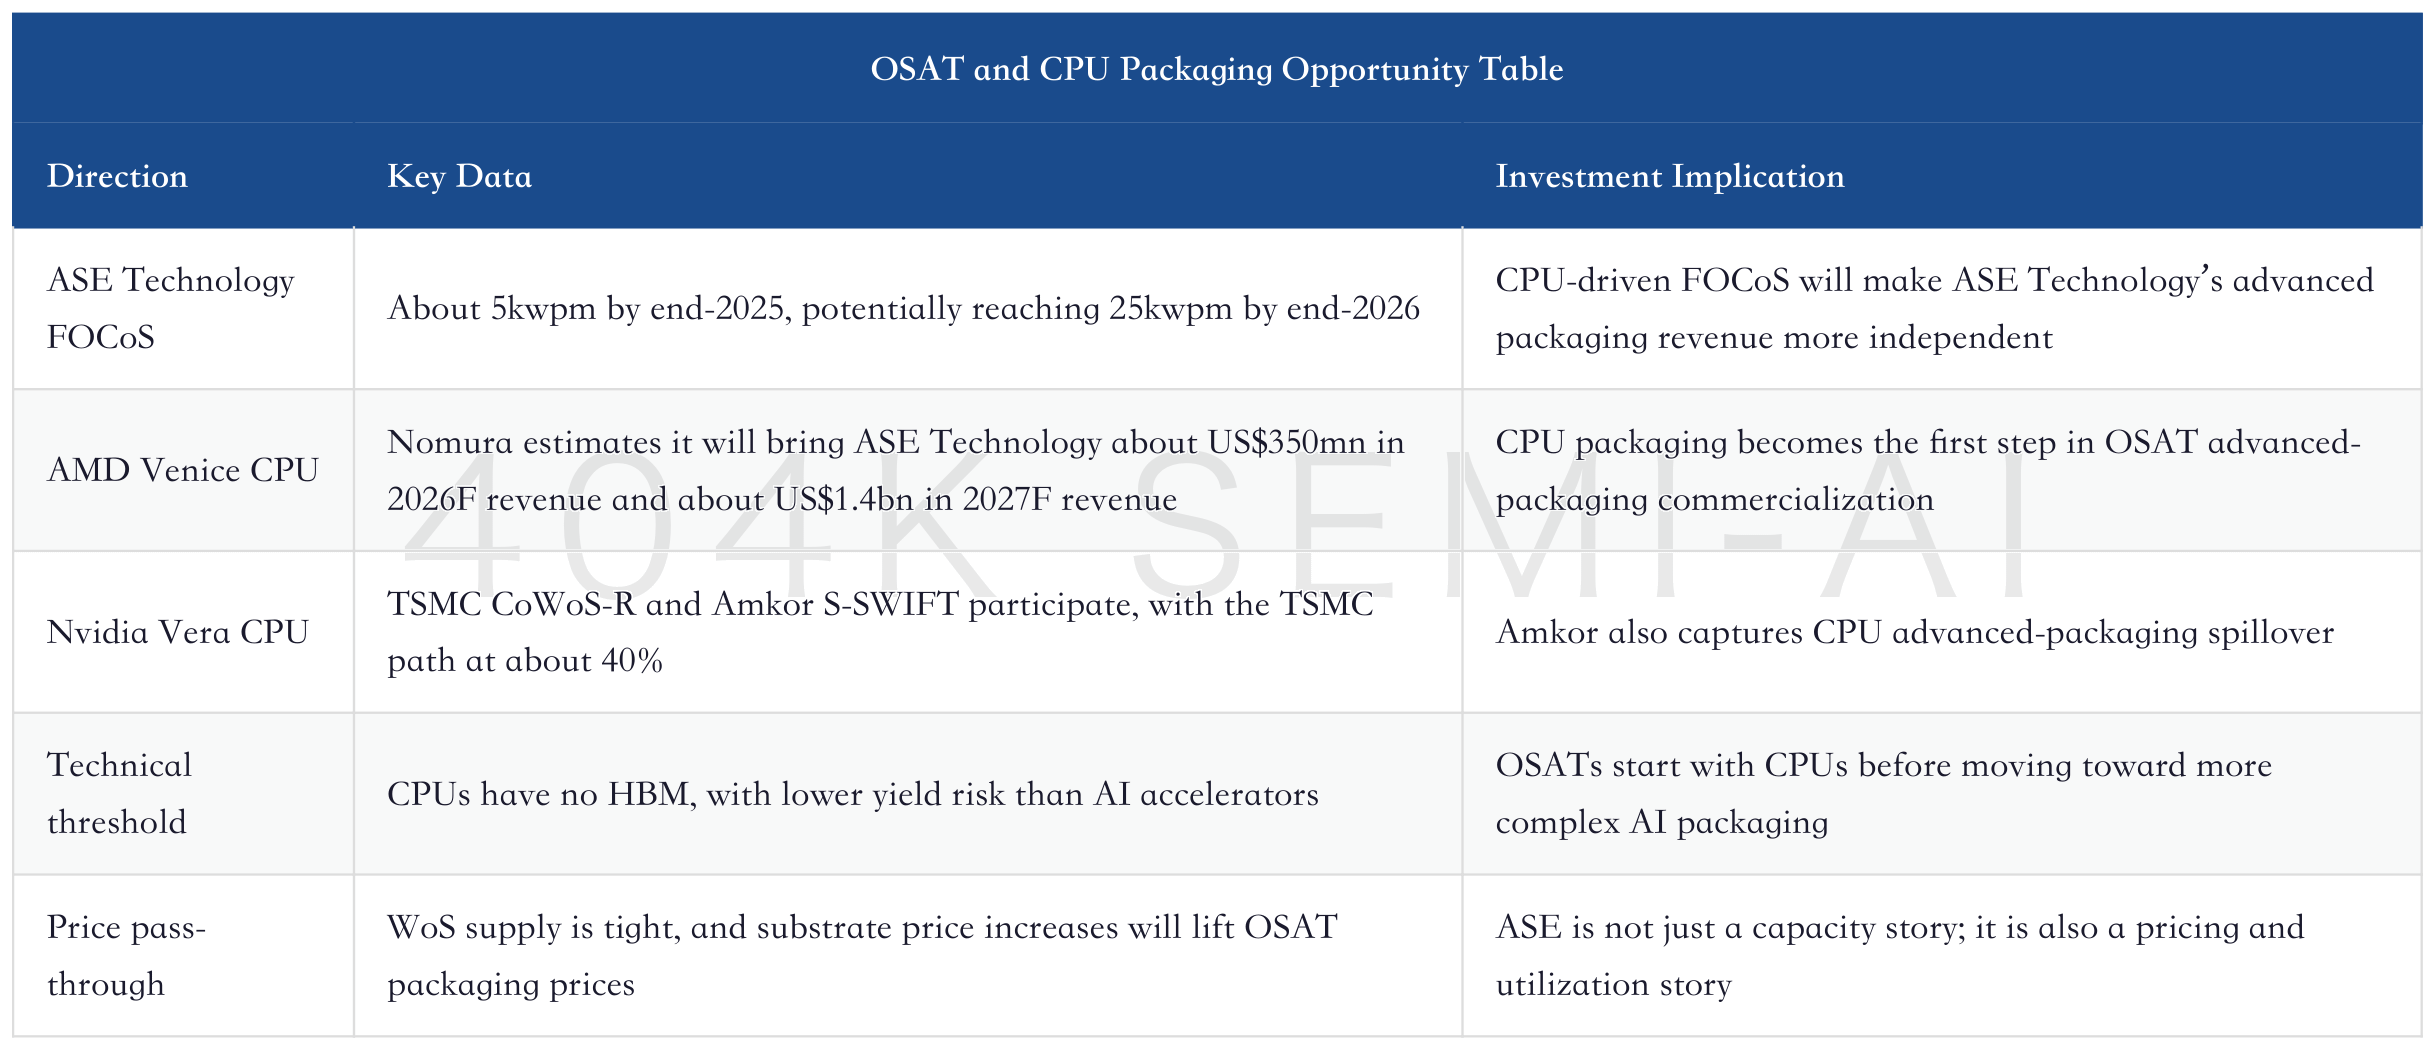
Server Industry Revaluation: From CPU Platforms to AI Acceleration Systems
BMC is another small segment that is easily underestimated. Nomura estimates that the AI server system BMC SAM will expand rapidly, with Google TPU servers among the largest sources of incremental demand. ASPEED Technology’s own shipment forecasts also show AI-related BMC and total BMC shipments rising in tandem. BMC unit prices and value content are not as eye-catching as GPUs, but BMC is the management gateway required in every server. Shipment expansion and supply tightness will flow directly into financial results.
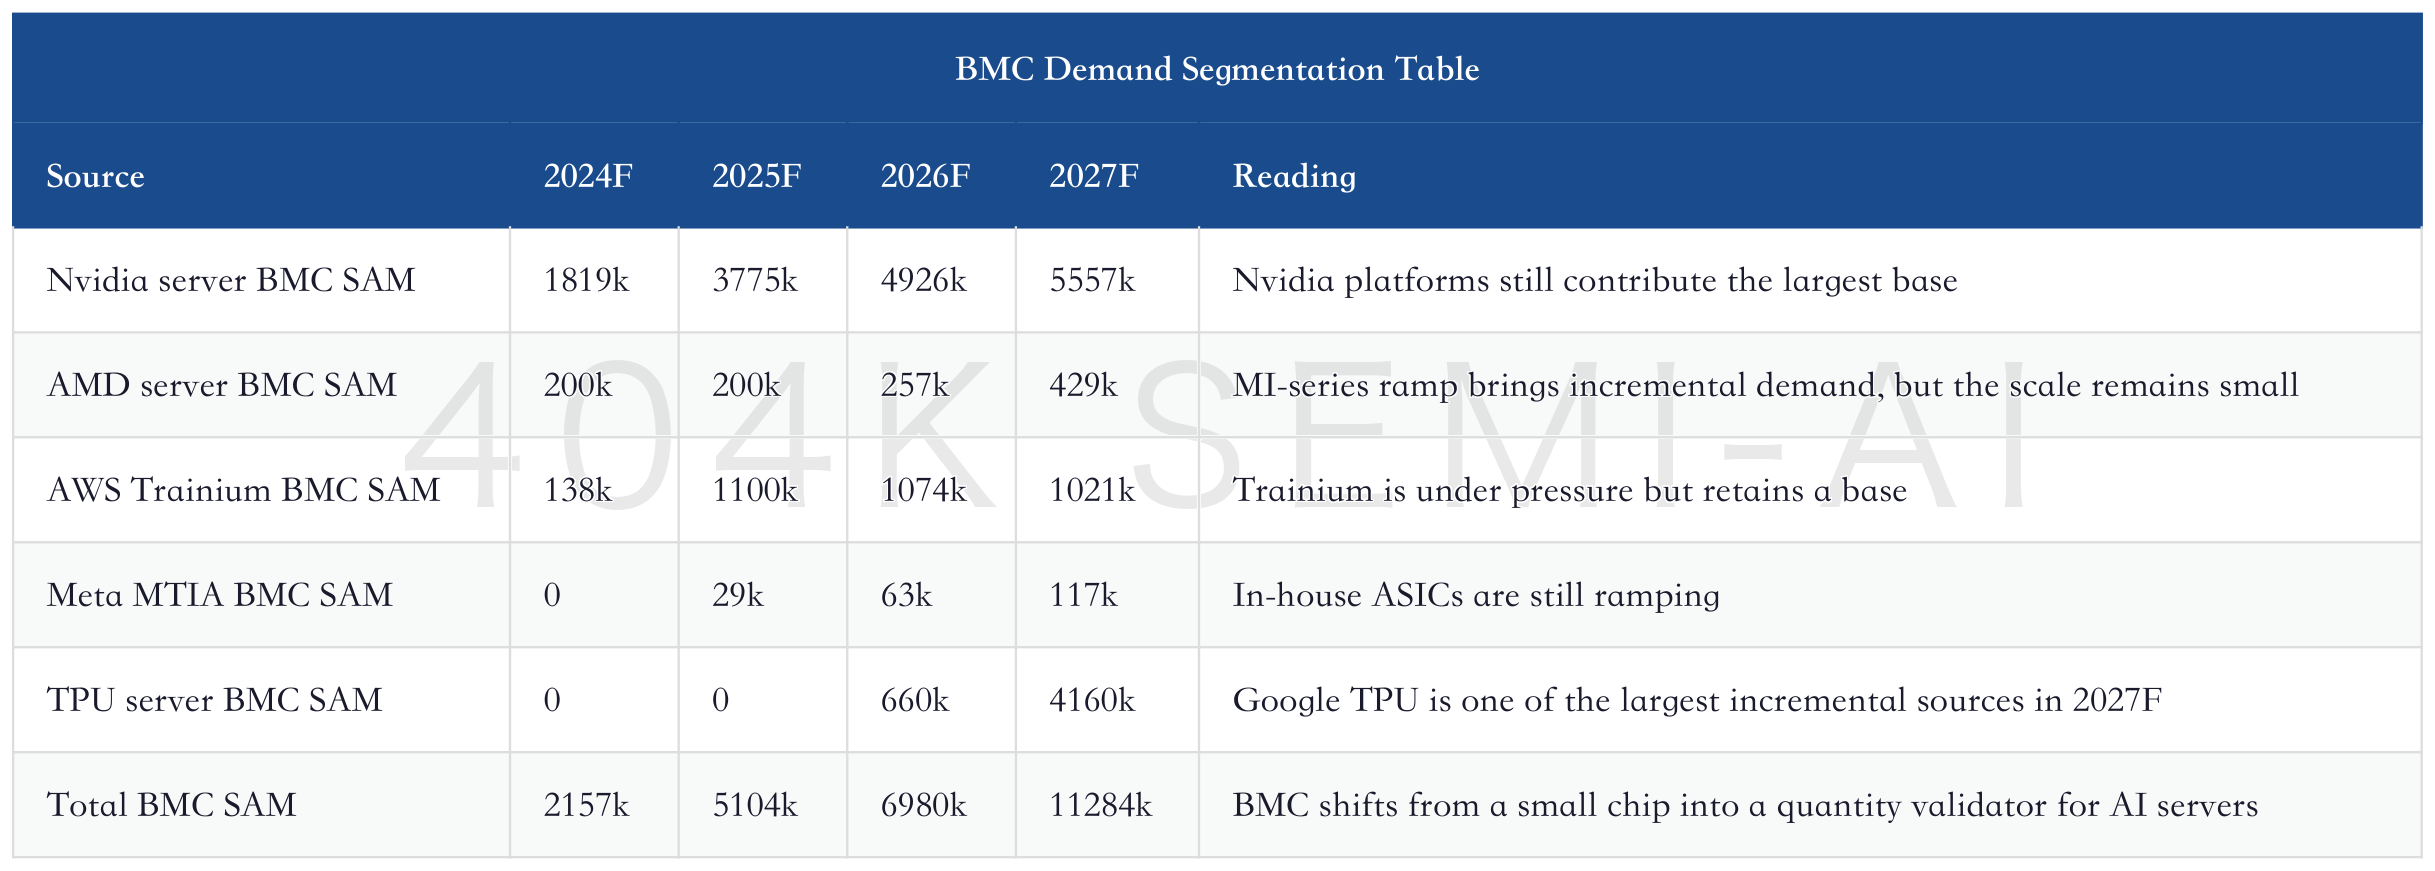
ASPEED’s value is not in telling a scarce small-cap story, but in providing a more granular validation indicator for AI server volumes. If BMC orders, the AST2600-to-AST2700 transition, and progress on new products such as AST1840 continue to improve over the next few quarters, it would indicate that server and CPU inference demand has not stopped. If BMC orders weaken, investors should watch for the server chain shifting from real demand to inventory accumulation.
VI. Advanced Packaging Roadmaps: EMIB-T, SoIC, CoPoS, and SiC Decide Who Survives Beyond 2028F
The bottleneck in 2027F is more about whether the supply chain can deliver. After 2028F, the bottleneck becomes whether technology roadmaps can extend further. Nomura lists a long set of technologies that must be broken through: EMIB-T, CoPoS, GPU-on-GPU SoIC, microchannel lid, CPO, 336G/448G SerDes, M9Q/M10Q PCB, PTFE, and new HDI tools/materials. These are not a pile of technical terms. They answer the same question: when 2.5D packaging, HBM, and PCBs are all close to being fully stretched, how can next-generation AI chip performance continue to scale?
Intel EMIB-T is the external threat to TSMC advanced packaging most worth watching. If Google TPU v9 adopts a MediaTek + Intel EMIB-T path, it will be both a growth opportunity for MediaTek and a real-world test of Intel Foundry’s advanced-packaging capability. EMIB-T adds TSVs into the silicon bridge, shortening the power path and improving power integrity between HBM4/4E and logic chiplets. Intel’s roadmap targets integrating more than 8x reticle top silicon on an approximately 120x120mm substrate in 2026E, and more than 12x reticle top silicon on a substrate larger than 120x180mm in 2028E.
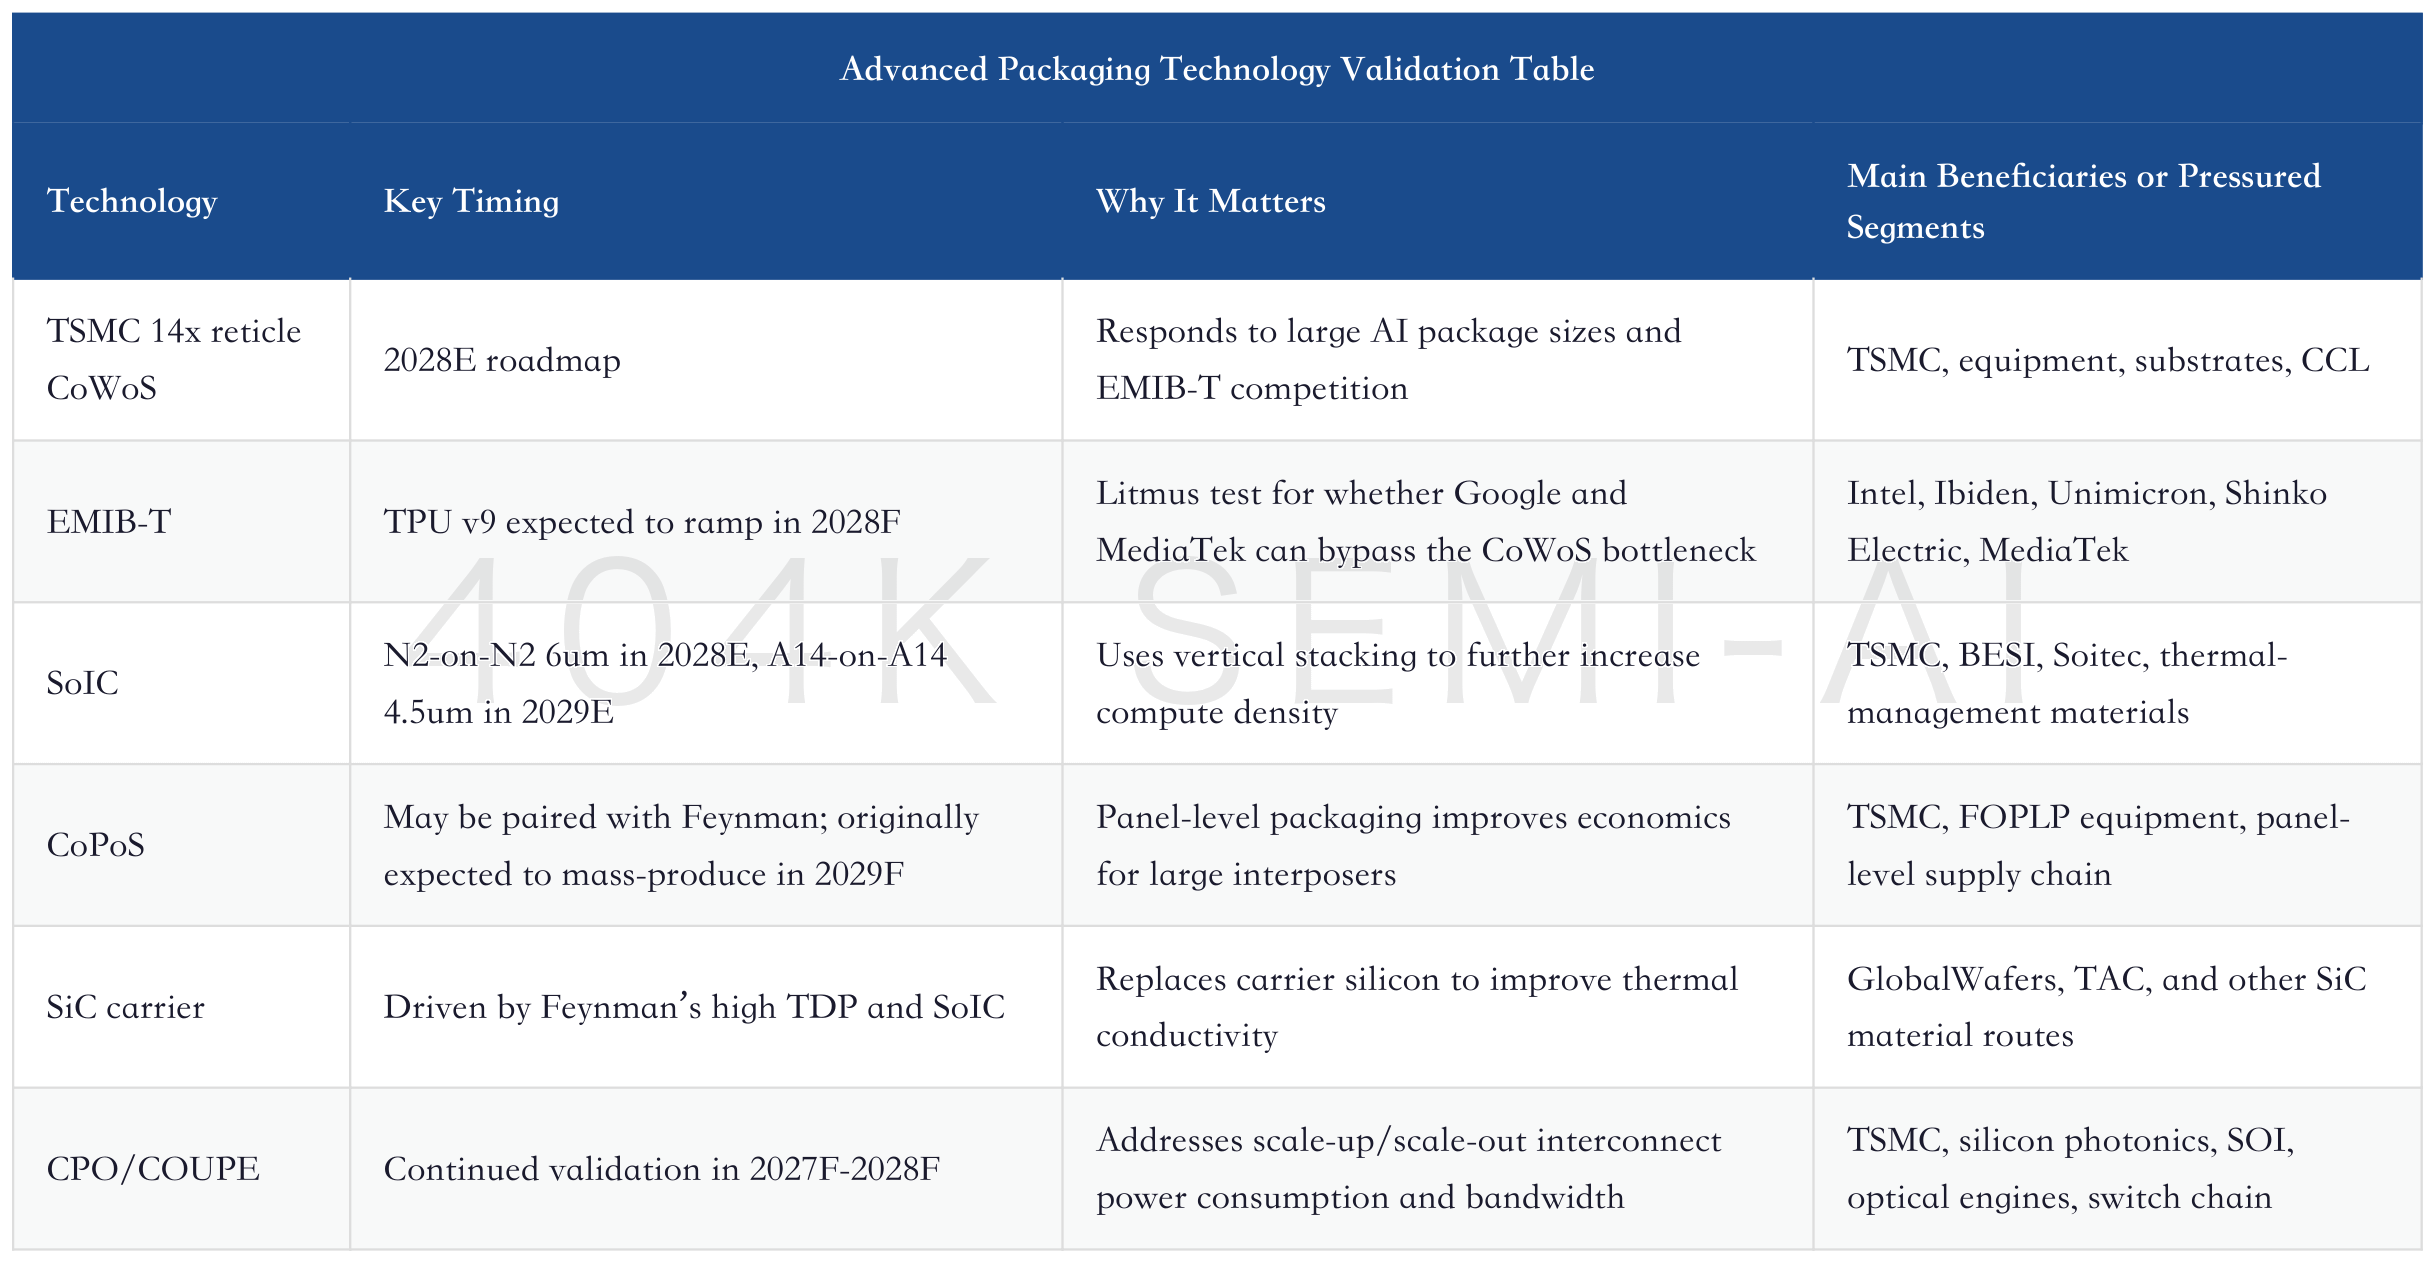
SoIC is critical for TSMC to defend its lead in advanced packaging. 2.5D packaging expands laterally, laying out the GPU, HBM, interposer, and substrate. SoIC stacks vertically, increasing transistor count and compute density within the same area. Nvidia Feynman may attempt GPU-on-GPU SoIC, which would push thermal density and hybrid-bonding yield to a higher level of difficulty. TSMC’s SoIC capacity may rise from about 5kwpm at end-2025 to more than 40kwpm by end-2028, doubling in both 2027F and 2028F.
SiC carrier is a small but representative materials change. If Feynman uses a larger size and higher TDP, traditional silicon carrier will become a problem for thermal conductivity. SiC has higher thermal conductivity than silicon, as well as better mechanical strength and chemical stability. As SiC costs decline due to industry capacity expansion over the past few years, its commercialization in chip-level thermal management may come earlier. Nomura raised its target price for GlobalWafers to NT$1,200, reflecting this option value from migrating out of power semiconductor materials into advanced-packaging thermal-management materials.
This section should not be treated only as a technology optimism narrative. If EMIB-T yields fail to qualify, the 2028F upside for Google TPU v9 and MediaTek will be discounted. If CoPoS is delayed, TSMC will need to continue bearing pressure from large-size CoWoS. If SoIC capacity ramps slowly, the Feynman roadmap may be delayed. If CPO remains immature, the Oberon version of Rubin Ultra may remain optional. After 2028F, technology execution will matter more than the 2026F-2027F order revisions.
VII. PCB/CCL/HDI: The Second Main Battlefield in AI Hardware
PCB and CCL are no longer merely “peripheral materials for AI servers.” GB200, GB300, VR200, Rubin Ultra, Trainium 3, and TPU 8t/8i are lifting motherboards, UBBs, switch trays, CPU boards, all-to-all switch boards, and potential backplanes together. Materials are moving from M7/M8 to M8.5, M9K2, M9Q, and PTFE; copper foil is moving from HVLP2 to HVLP3/HVLP4; structures are moving from ordinary HLC to HDI/mSAP. Every platform upgrade increases the number of boards, layer count, material grade, and certification difficulty.
Nomura’s view on EMC is highly representative. EMC’s 2Q26 revenue is expected to grow 37% QoQ, with gross margin potentially expanding further to 32.4%; demand from Google Ironwood and AWS Trainium 3 is strong, and pricing improvement is proceeding more smoothly than expected. More importantly, CCL content opportunities from Google TPU/CPU boards and switches could nearly triple by 2027F, accounting for 58% of EMC’s AI revenue, up from 38% in 2026F. When customers need more high-end materials, while production lines require certification, lamination, yield, and equipment support, CCL is no longer just copper and resin. It becomes delivery rights.
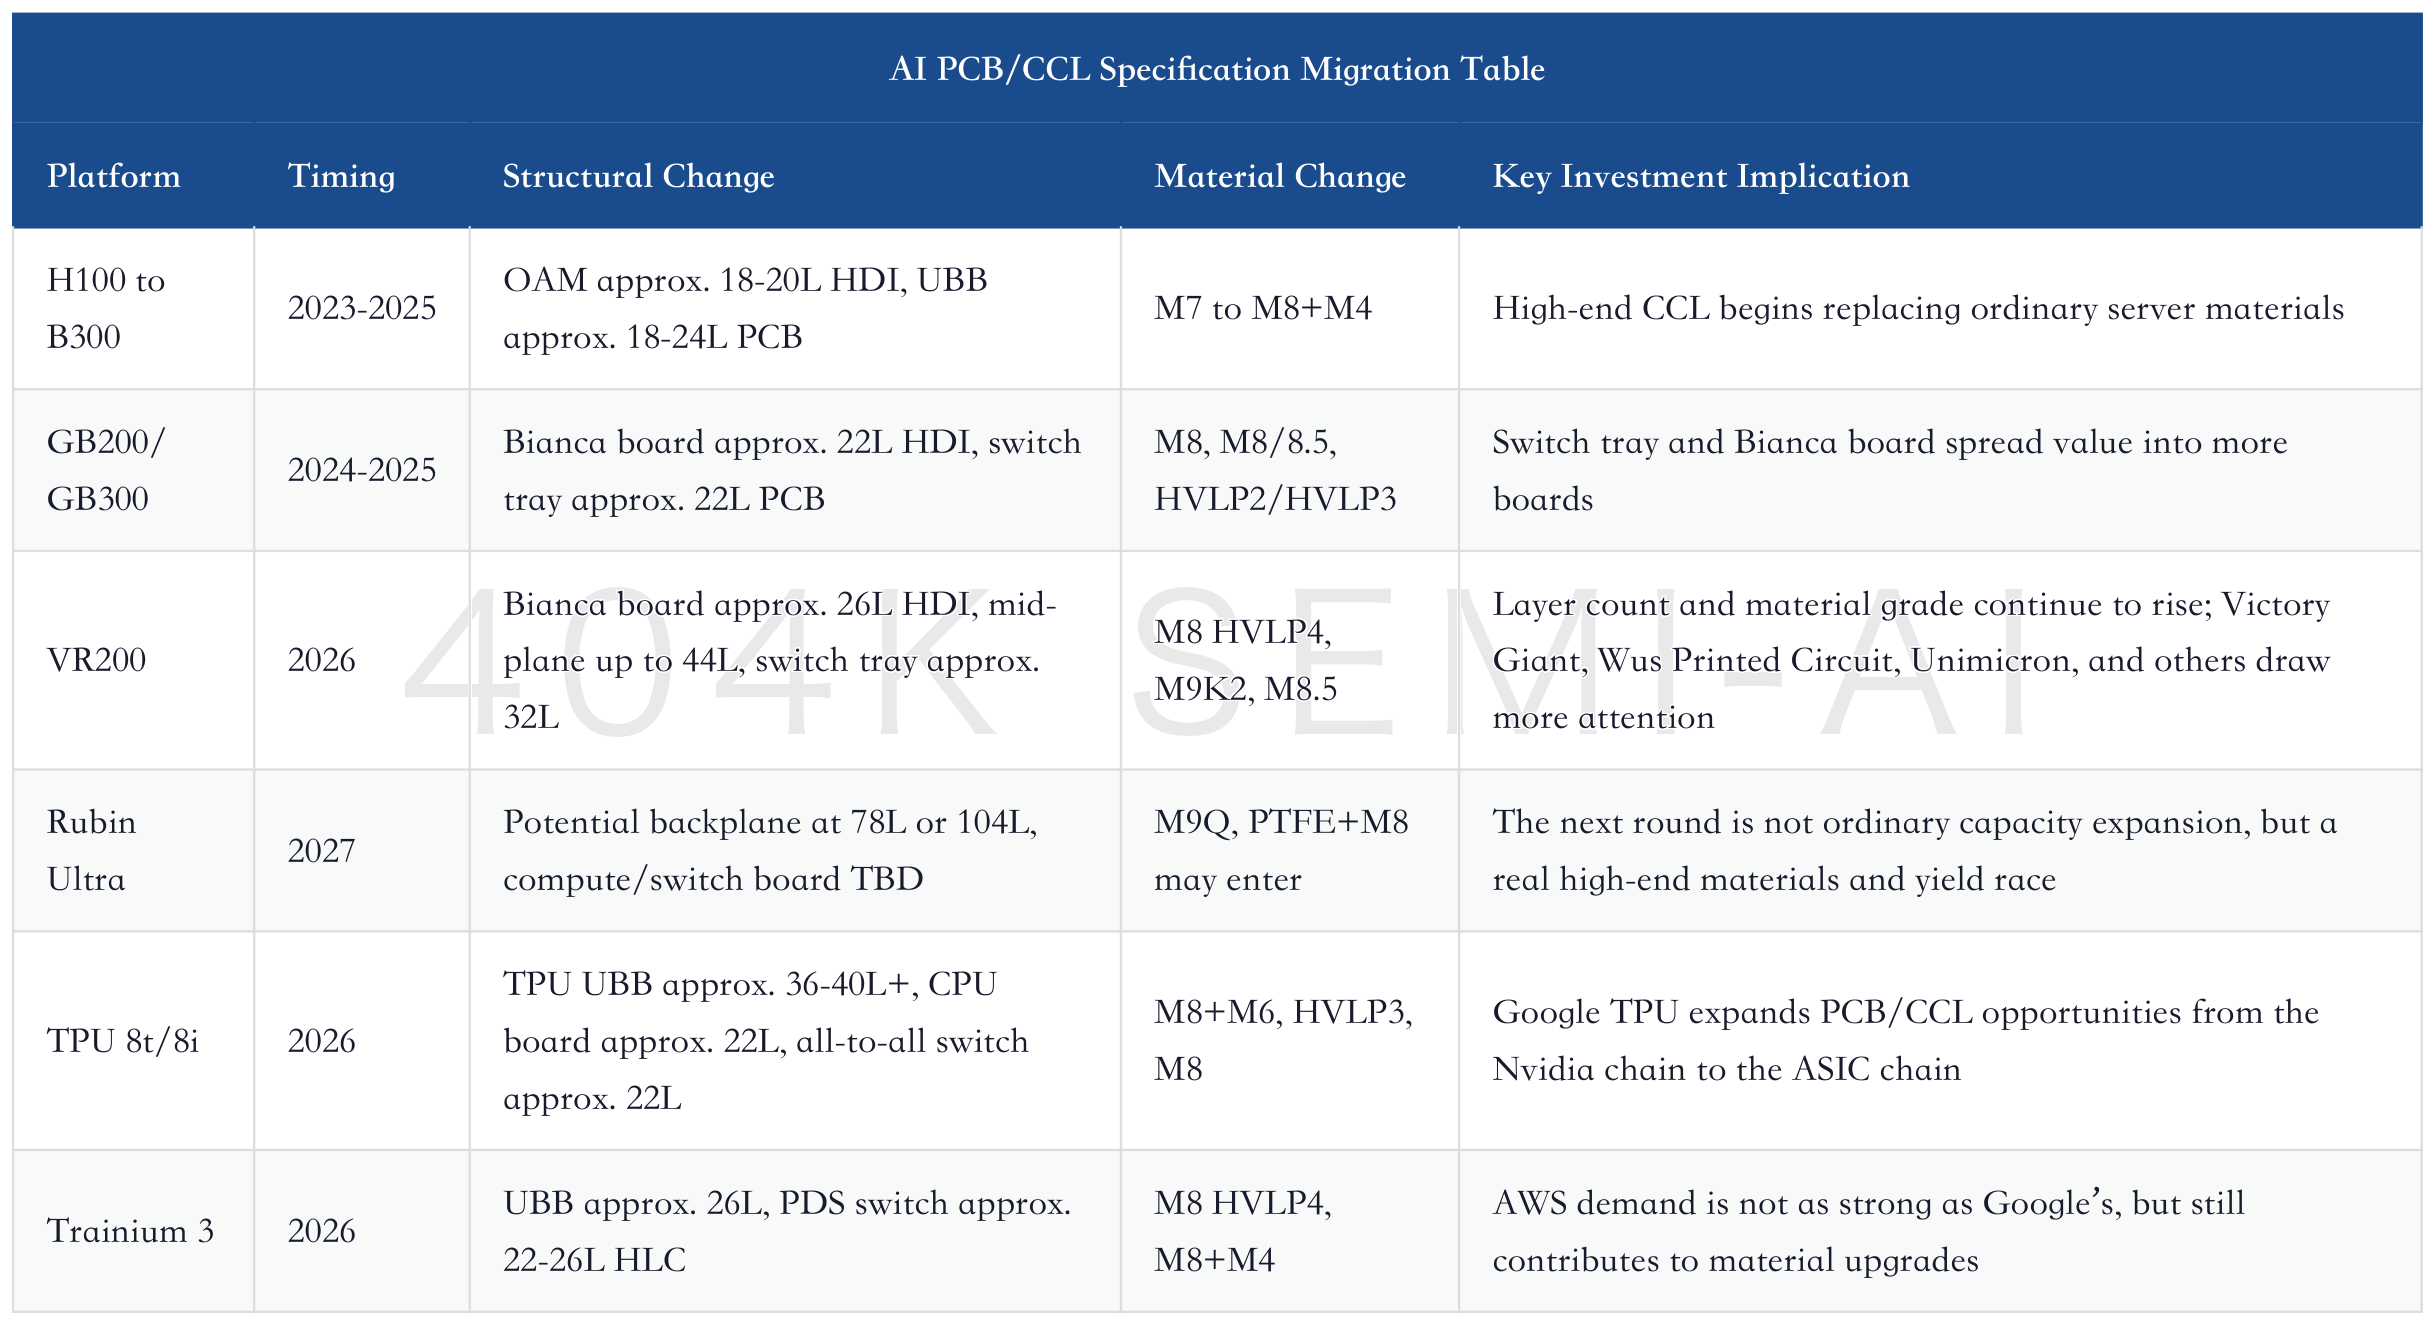
Taiwan Union Technology follows similar logic but with higher earnings sensitivity. Nomura raised its target price for Taiwan Union Technology from TWD 1,710 to TWD 2,115, valuing it at 30x 2027F EPS, based on high-end CCL specification upgrades and worsening supply-demand conditions. Taiwan Union Technology is smaller than EMC, so price increases and mix improvement have greater profit leverage; the downside is that its customer and capacity scale are also more sensitive. EMC is more platform-like, while Taiwan Union Technology is more elasticity-oriented. Together, they validate the view that high-end CCL is not an ordinary materials cycle.
ZDT represents a crossover opportunity across PCB/HDI and substrates. Nomura raised its target price for ZDT from TWD 510 to TWD 720, citing tight supply in AI substrates, PCB, and HDI; a 2026E target of 70%+ growth in IC substrate sales; a target to double server/optical-communications sales in 2026E and 2027F; and a 2026E capex increase from TWD 50bn+ to TWD 80bn+. ZDT has begun producing VR200 Bianca HDI boards and will ramp Google switch boards in late 3Q26F; optical module mSAP boards can grow 10x in 2026E and another 2x in 2027E.
AI Interconnect Enters Board-Level Revaluation: New Incremental Demand from 1.6T, mSAP, and High-End CCL, with TAM Growing 6x in Three Years
The debate in this segment is not demand, but effective supply. Expanding AI PCB and high-end CCL capacity looks easy, but in practice it must pass through six gates: materials, equipment, lamination, drilling, yield, customer certification, and cash flow. Ordinary capacity additions do not immediately become effective capacity for M9, PTFE, HVLP4, 44L, 78L, or 104L. The companies that can actually convert this into profit are not necessarily those announcing the most capex, but those with the deepest customer certifications, most stable yields, highest-end material mix, and smoothest price pass-through.
AI-PCB Deep Dive: After a RMB 562bn TAM Revaluation, Who Can Better Convert Profit, Wus Printed Circuit or Victory Giant Technology?
VIII. Target Prices Raised for Nine Companies: Not the Same Type of Opportunity
Nomura raised target prices for nine companies in one move, but they are not the same type of asset. TSMC is a platform gatekeeper; ASE Technology is spillover from WoS and advanced CPU packaging; Aspeed is a BMC shipment validator; MediaTek is Google TPU leverage; GlobalWafers is an option on SiC carriers and thermal-management materials; King Yuan Electronics is AI test time and customer breadth; EMC/Taiwan Union Technology are high-end CCL bottlenecks; ZDT is a crossover across AI PCB/HDI/substrates. From an investment perspective, they should not all be treated as “AI beta.”
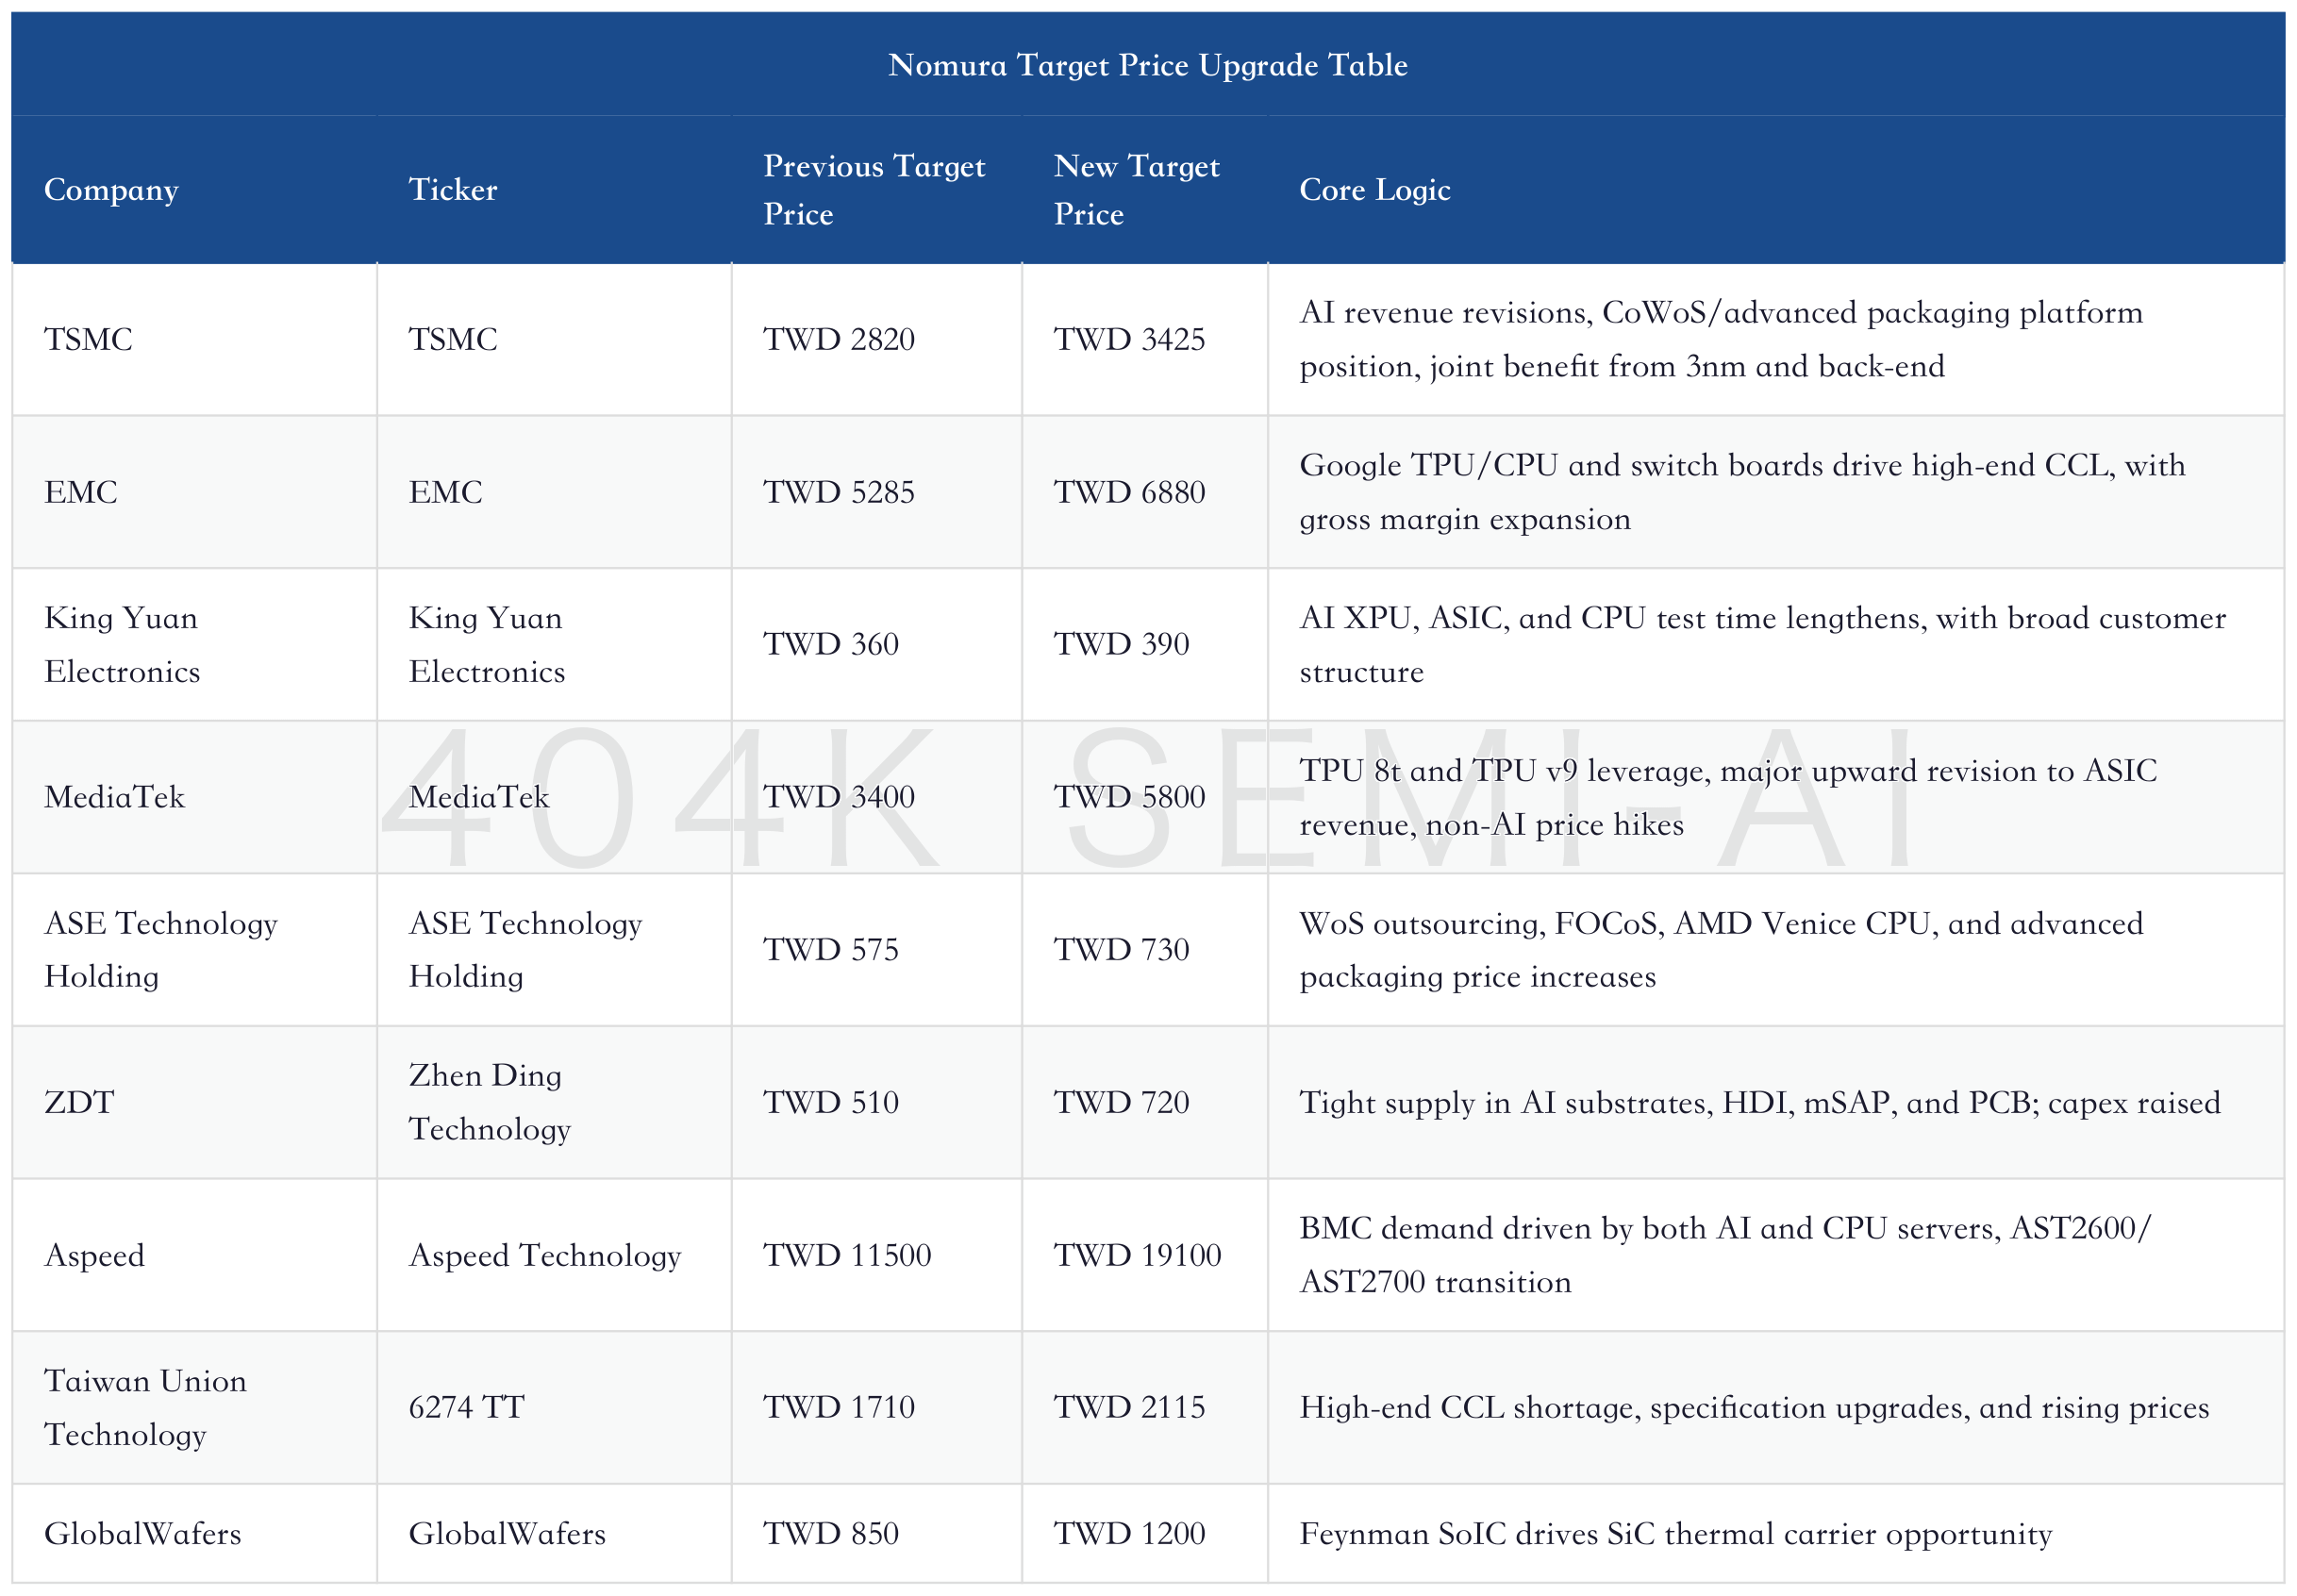
The first group is platform and base-layer assets: TSMC, ASE Technology, and King Yuan Electronics. TSMC controls the main gate for advanced process and advanced packaging, offering steadier valuation but with upside diluted by market cap; ASE Technology captures WoS outsourcing, FOCoS, and advanced CPU packaging, with leverage from packaging spillover; King Yuan Electronics captures test time and AI chip complexity, with relatively less exposure to changes in a single customer’s share because as AI XPUs and ASICs become more complex, total testing volume is more likely to rise.
The second group is demand-side leverage assets: MediaTek, Aspeed, and ZDT. MediaTek’s key variable is whether Google TPU can continue to be revised upward, and whether the TPU v9 EMIB-T path can be validated on schedule; Aspeed’s variable is whether BMC shipments for AI servers and CPU servers can continue; ZDT’s variable is whether AI substrates, VR200/Google switch boards, and optical module mSAP boards can deliver. Their common feature is higher revenue sensitivity; the downside is that valuations are also more prone to being priced in early.
The third group is materials bottleneck assets: EMC, Taiwan Union Technology, and GlobalWafers. EMC and Taiwan Union Technology directly benefit from high-end CCL price increases and material upgrades, where profit leverage and gross margin changes matter more than revenue; GlobalWafers is more of an option on the post-2028F technology roadmap through SiC carriers. The biggest risk for materials stocks is “capacity expansion killing prices,” but high-end AI materials are not only about nominal capacity. They also depend on customer certification, product grade, and yield.
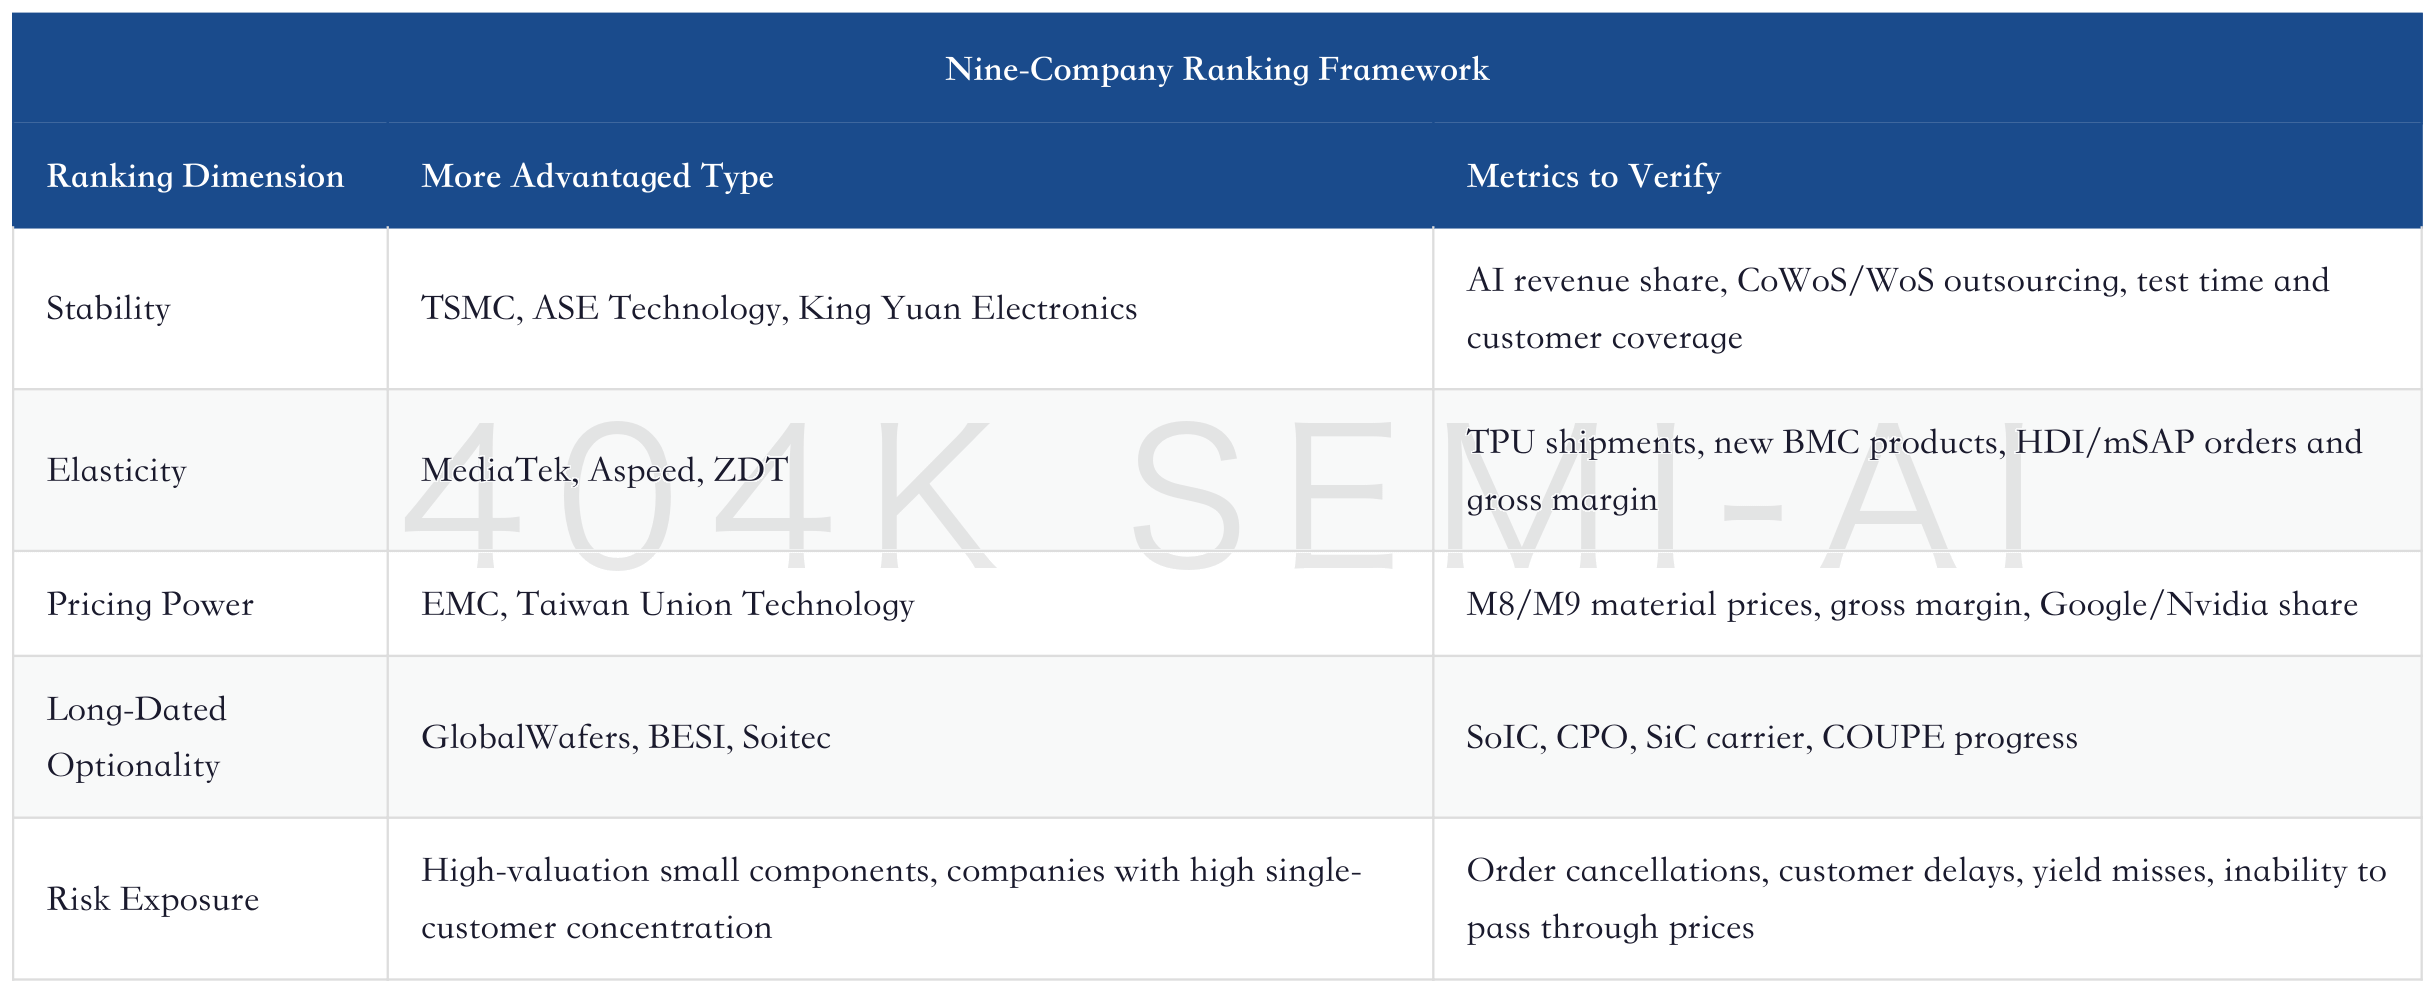
For portfolios, this table is more useful than target prices alone. If the focus is 2026F-2027F earnings upgrades, EMC, Taiwan Union Technology, ZDT, Aspeed, ASE Technology, and King Yuan Electronics are easier to verify through quarterly results. If the focus is post-2028F technology roadmaps, TSMC, MediaTek, GlobalWafers, BESI, and Soitec have more optionality. If the market turns defensive, platform assets such as TSMC and Samsung Electronics are better positioned to absorb volatility; if risk appetite continues to rise, small-component bottleneck stocks will have greater elasticity.
A better ranking method is to break target price upgrades into four types of earnings quality. The first is capacity-platform earnings, where upgrades come from long customer queues and sustained capex investment, represented by TSMC. For these companies, the most important factor is not single-quarter price increases, but whether advanced process, advanced packaging, and customer roadmaps can remain bound to the same platform. Even if TSMC’s target price increase is smaller than that of mid- and small-cap bottleneck stocks, it remains the benchmark asset for the entire chain because it determines advanced process, CoWoS, SoIC, CoPoS, and customer allocation rules. If TSMC’s AI revenue continues to be revised upward, downstream materials, packaging, and testing companies can have sustainable orders; if TSMC’s AI revenue growth slows, the valuation anchor for the entire chain will loosen first.
The second is delivery-spillover earnings, where upgrades come from TSMC or system customers outsourcing part of bottleneck capacity to partners, represented by ASE Technology and King Yuan Electronics. ASE Technology’s FOCoS, WoS outsourcing, and AMD Venice CPU opportunities are essentially about absorbing delivery pressure from TSMC’s back-end and advanced CPU packaging; King Yuan Electronics absorbs longer test time, more ASIC customers, and higher AI chip complexity. Unlike materials stocks, they are not directly about price hikes; unlike MediaTek, they are not a bet on one major customer’s share. Instead, they capture labor hours and service value from “increasing complexity.” This earnings quality is usually less stable than TSMC’s, but more resilient to customer switching than single-product price increases.
The third is customer-share earnings, where upgrades come from a sudden increase in share at a major customer or product line, represented by MediaTek, Aspeed, and ZDT. MediaTek captures ASIC share in Google TPU 8t, 8i, and TPU v9; Aspeed captures BMC shipments after both AI servers and CPU servers expand; ZDT captures Google switch boards, VR200 Bianca HDI, optical module mSAP, and AI substrates. Their advantage is high elasticity, with revenue upgrades quickly entering models; the risk is that validation points are more concentrated, and any major-customer schedule change, yield issue, or price negotiation can shift valuation from “certain growth” back to “order volatility.”
The fourth is materials price-hike earnings, represented by EMC, Taiwan Union Technology, and some high-end PCB/CCL suppliers. These companies look most like cyclical stocks, yet least like traditional cyclical stocks. The similarity is that prices, gross margins, and inventory determine share-price elasticity; the difference is that high-end AI materials are not ordinary chemicals or copper foil. Customer certification, low-loss performance, lamination yield, board layer count, and supply stability all constrain effective supply. As long as supply of M8, M9, HVLP4, PTFE, and high-layer-count PCB cannot keep up, price increases are not a short-term inventory cycle, but a profit revaluation driven by specification upgrades.
Under this framework, investors should not look only at the percentage increase in target prices. MediaTek’s target price saw the largest increase, showing the sharpest revenue leverage from Google TPU; TSMC’s target price increase was relatively moderate, yet it provides the most stable demand anchor for the entire chain; target price changes for EMC and Taiwan Union Technology should be assessed together with gross margin, pricing, and customer certification; ZDT depends on whether capex can translate into effective capacity; Aspeed depends on whether AI BMC and CPU server BMC grow in tandem; ASE Technology and King Yuan Electronics depend on WoS, FOCoS, test time, and customer breadth. Target price is the result; what can truly be tracked is the source of earnings quality.
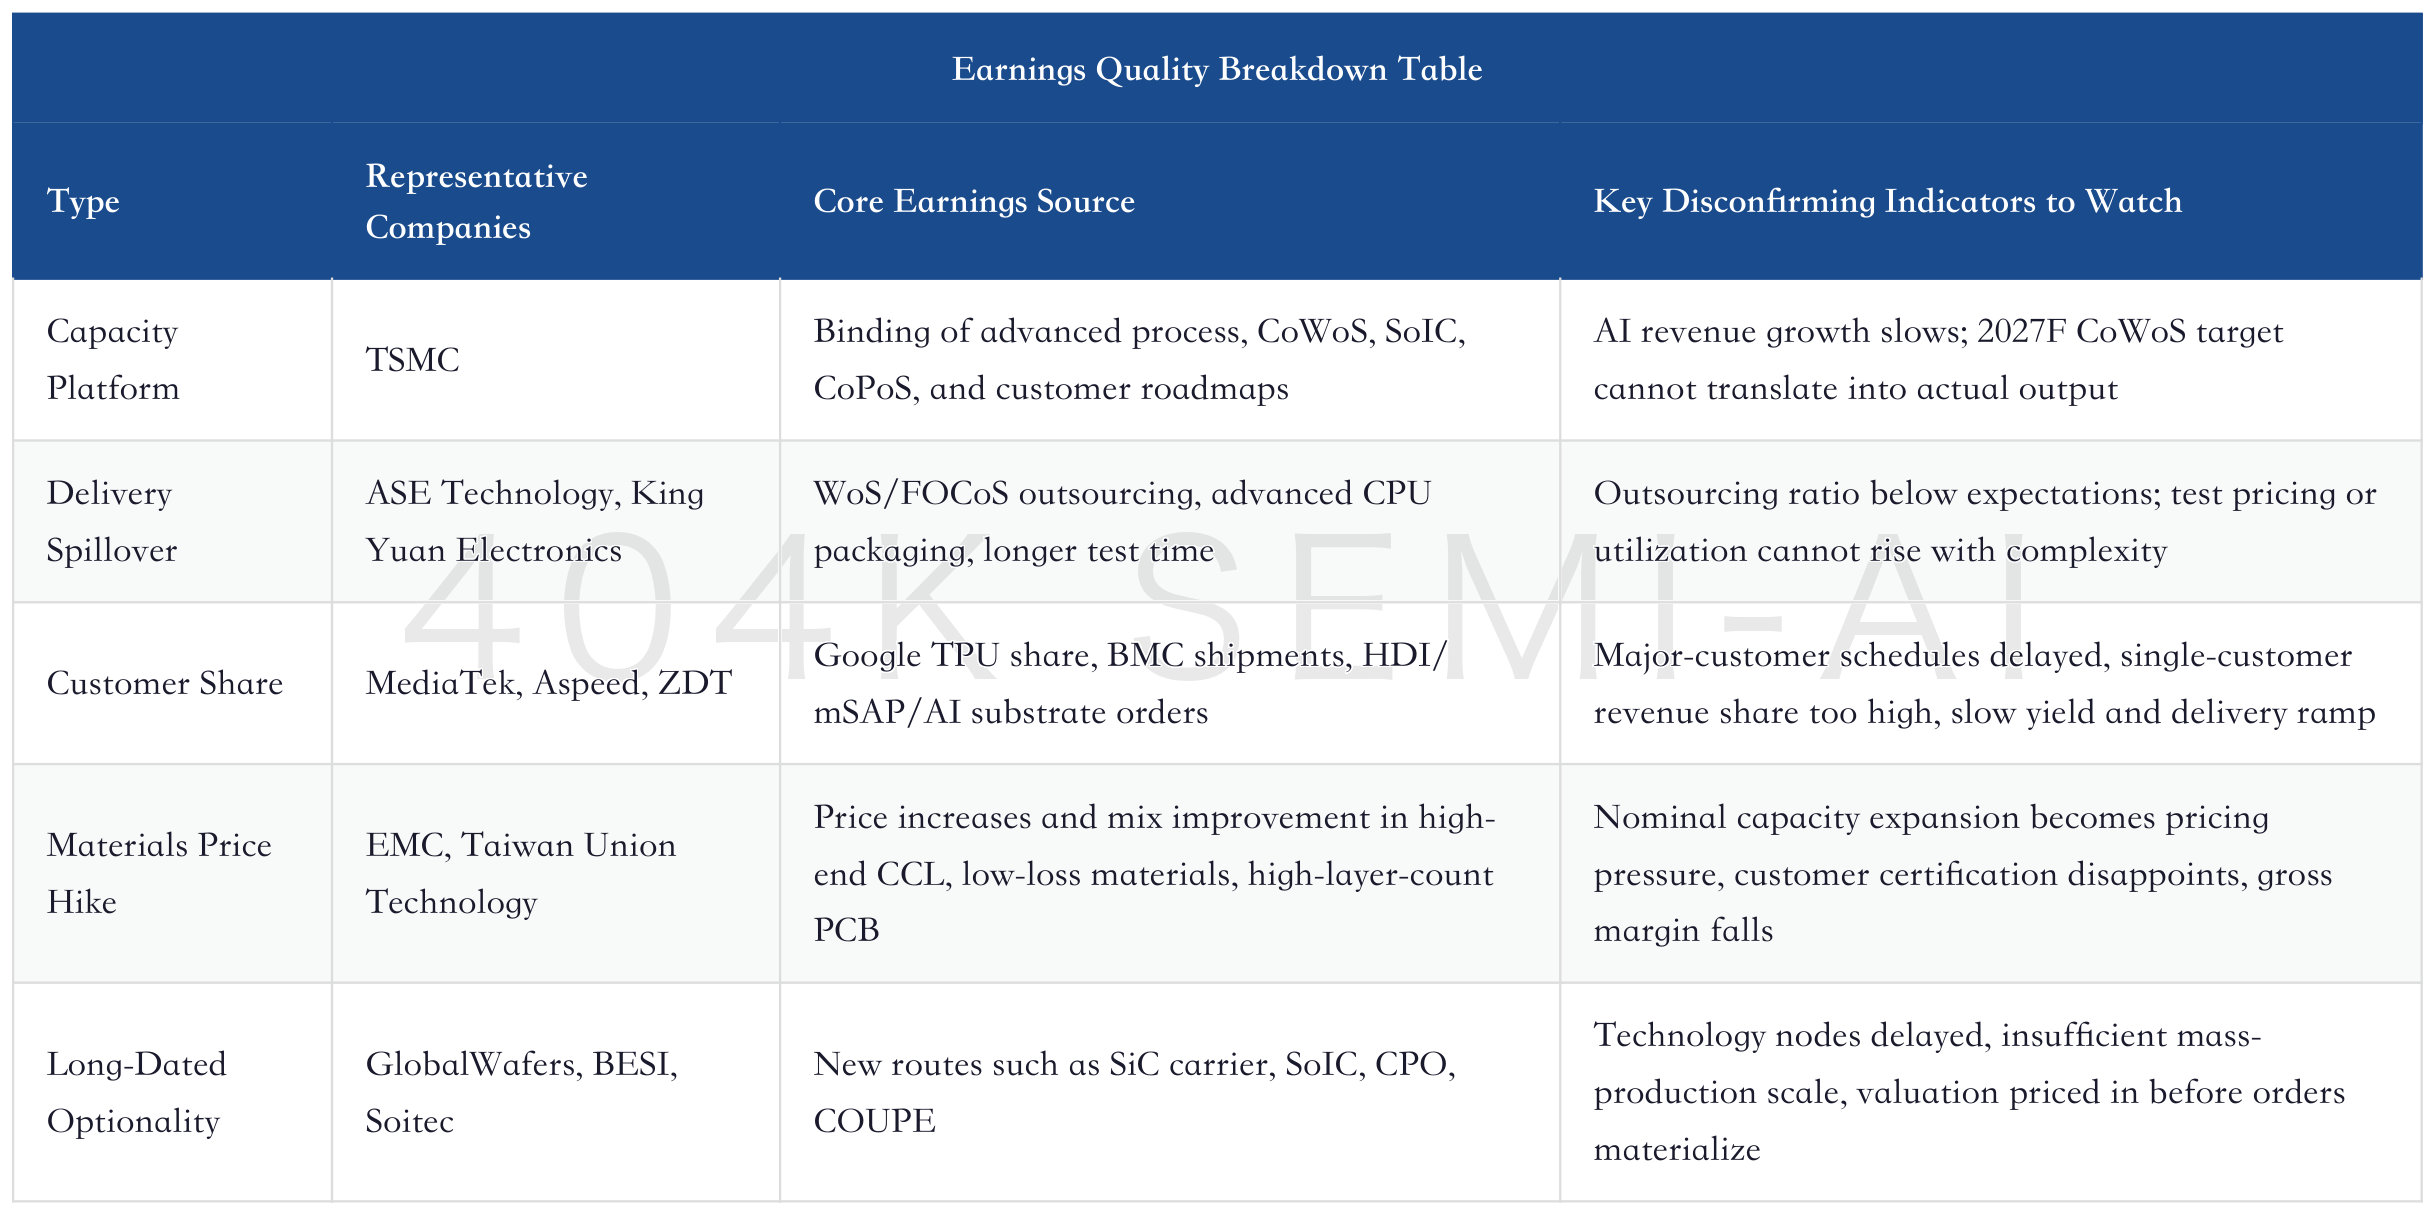
This breakdown also explains why stocks in the same AI chain cannot use the same buy/sell discipline. Platform assets are best assessed by long-term revenue slope and customer lock-in, and behave more like portfolio anchors during drawdowns; delivery-spillover assets should be assessed by quarterly utilization, pricing, and customer breadth, where earnings upgrades matter more than thematic narratives; customer-share assets require dynamic noise reduction around order realization, and one design win should not be capitalized directly across multiple years; materials price-hike assets require strict tracking of gross margin and inventory, because once price pass-through stalls, valuation elasticity can quickly reverse; long-dated option assets require waiting for technology milestones, rather than forcing short-term earnings to justify long-term imagination.
The easiest mistake is to interpret a “bottleneck” as something that is scarce forever. A bottleneck has value only when three conditions hold at the same time: downstream demand is real, capacity expansion cannot be quickly replicated, and pricing can be passed through to customers. If any one condition is missing, the bottleneck turns from an asset into inventory risk. AI hardware still satisfies the first two conditions today; the third must be verified company by company. Elite Material and TUC must be verified through gross margin. ZDT must be verified through effective capacity and customer ramp. ASE must be verified through FOCoS revenue. KYEC must be verified through test time and customer coverage. ASPEED must be verified through BMC shipments. MediaTek must be verified through Google TPU revenue. TSMC must be verified through actual CoWoS output and AI revenue.
Therefore, 2027F looks more like a “profit-quality exam” than a simple order contest. Orders can be placed early, capacity can be expanded early, and target prices can be raised early. But what really determines share-price durability is whether companies can turn orders into recognized revenue, price hikes into gross margin, capex into effective capacity, and design wins into multi-year share. If these indicators are delivered simultaneously, the second stage of AI semiconductors can remain very strong. If there are only orders without profit quality, the pullback will shift from healthy digestion to valuation reset.
IX. Three Worldviews: How to Decide Whether to Buy the Pullback or Wait for Falsification
This report is best understood through three worldviews. The first is “bottlenecks extend the cycle”: demand continues to be revised up, supply remains uneven, pricing and earnings expectations keep rising, and pullbacks are buying opportunities. The second is the “cash-flow constraint cycle”: cloud providers and AI labs still want to expand, but 2027F capex, memory costs, and financing costs pressure free cash flow, and hardware orders begin to diverge. The third is the “technology-roadmap revaluation cycle”: after 2028F, validation of EMIB-T, CoPoS, SoIC, CPO, and high-end PCB materials proves less smooth, and the market starts to mark down long-term linear extrapolation.
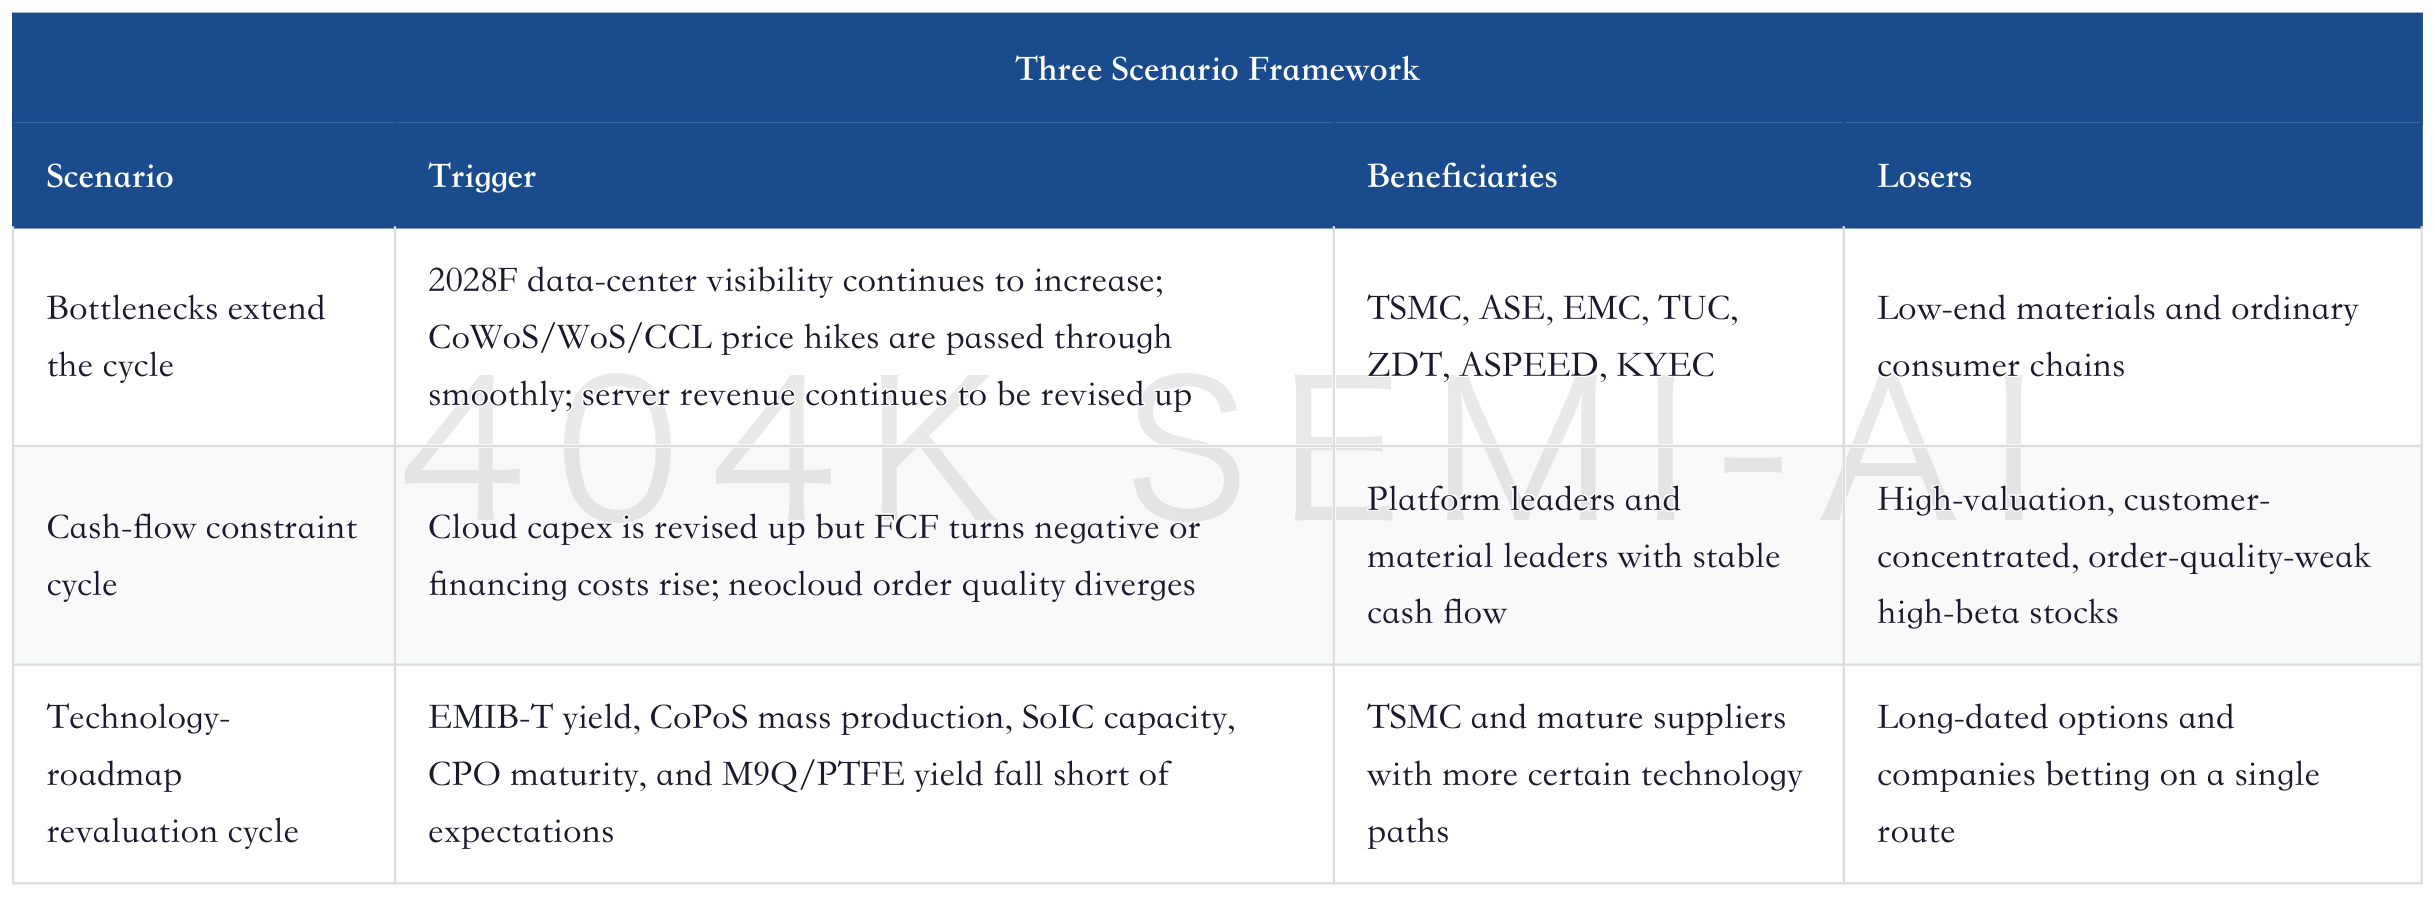
The base case still leans toward the first scenario, but the second and third cannot be ignored. Nomura repeatedly emphasizes insufficient hyperscaler 2027F FCF, especially after memory costs rise. The contradiction here is not that “AI investment has no return,” but that the buildout pace may run ahead of cash-flow recovery. Cloud providers can continue investing, and the market can continue assigning valuations. But once long-end rates rise, valuations will start asking a sharper question: who ultimately bears the cost of capital for the additional USD590.6 billion of AI server revenue in 2027F?
Technology-roadmap risk is not a distant story either. TPU v9’s EMIB-T tape-out, Rubin Ultra’s actual packaging scheme, whether Feynman uses GPU-on-GPU SoIC, whether CoPoS can be pulled in, whether CPO/NPO matures, and whether M9Q/PTFE materials proceed smoothly will all be answered between the end of 2026 and 2028F. If the answers are favorable, Asian AI hardware will upgrade from “packaging shortage” to “technology-roadmap expansion.” If not, the market will re-discount those long-dated options.
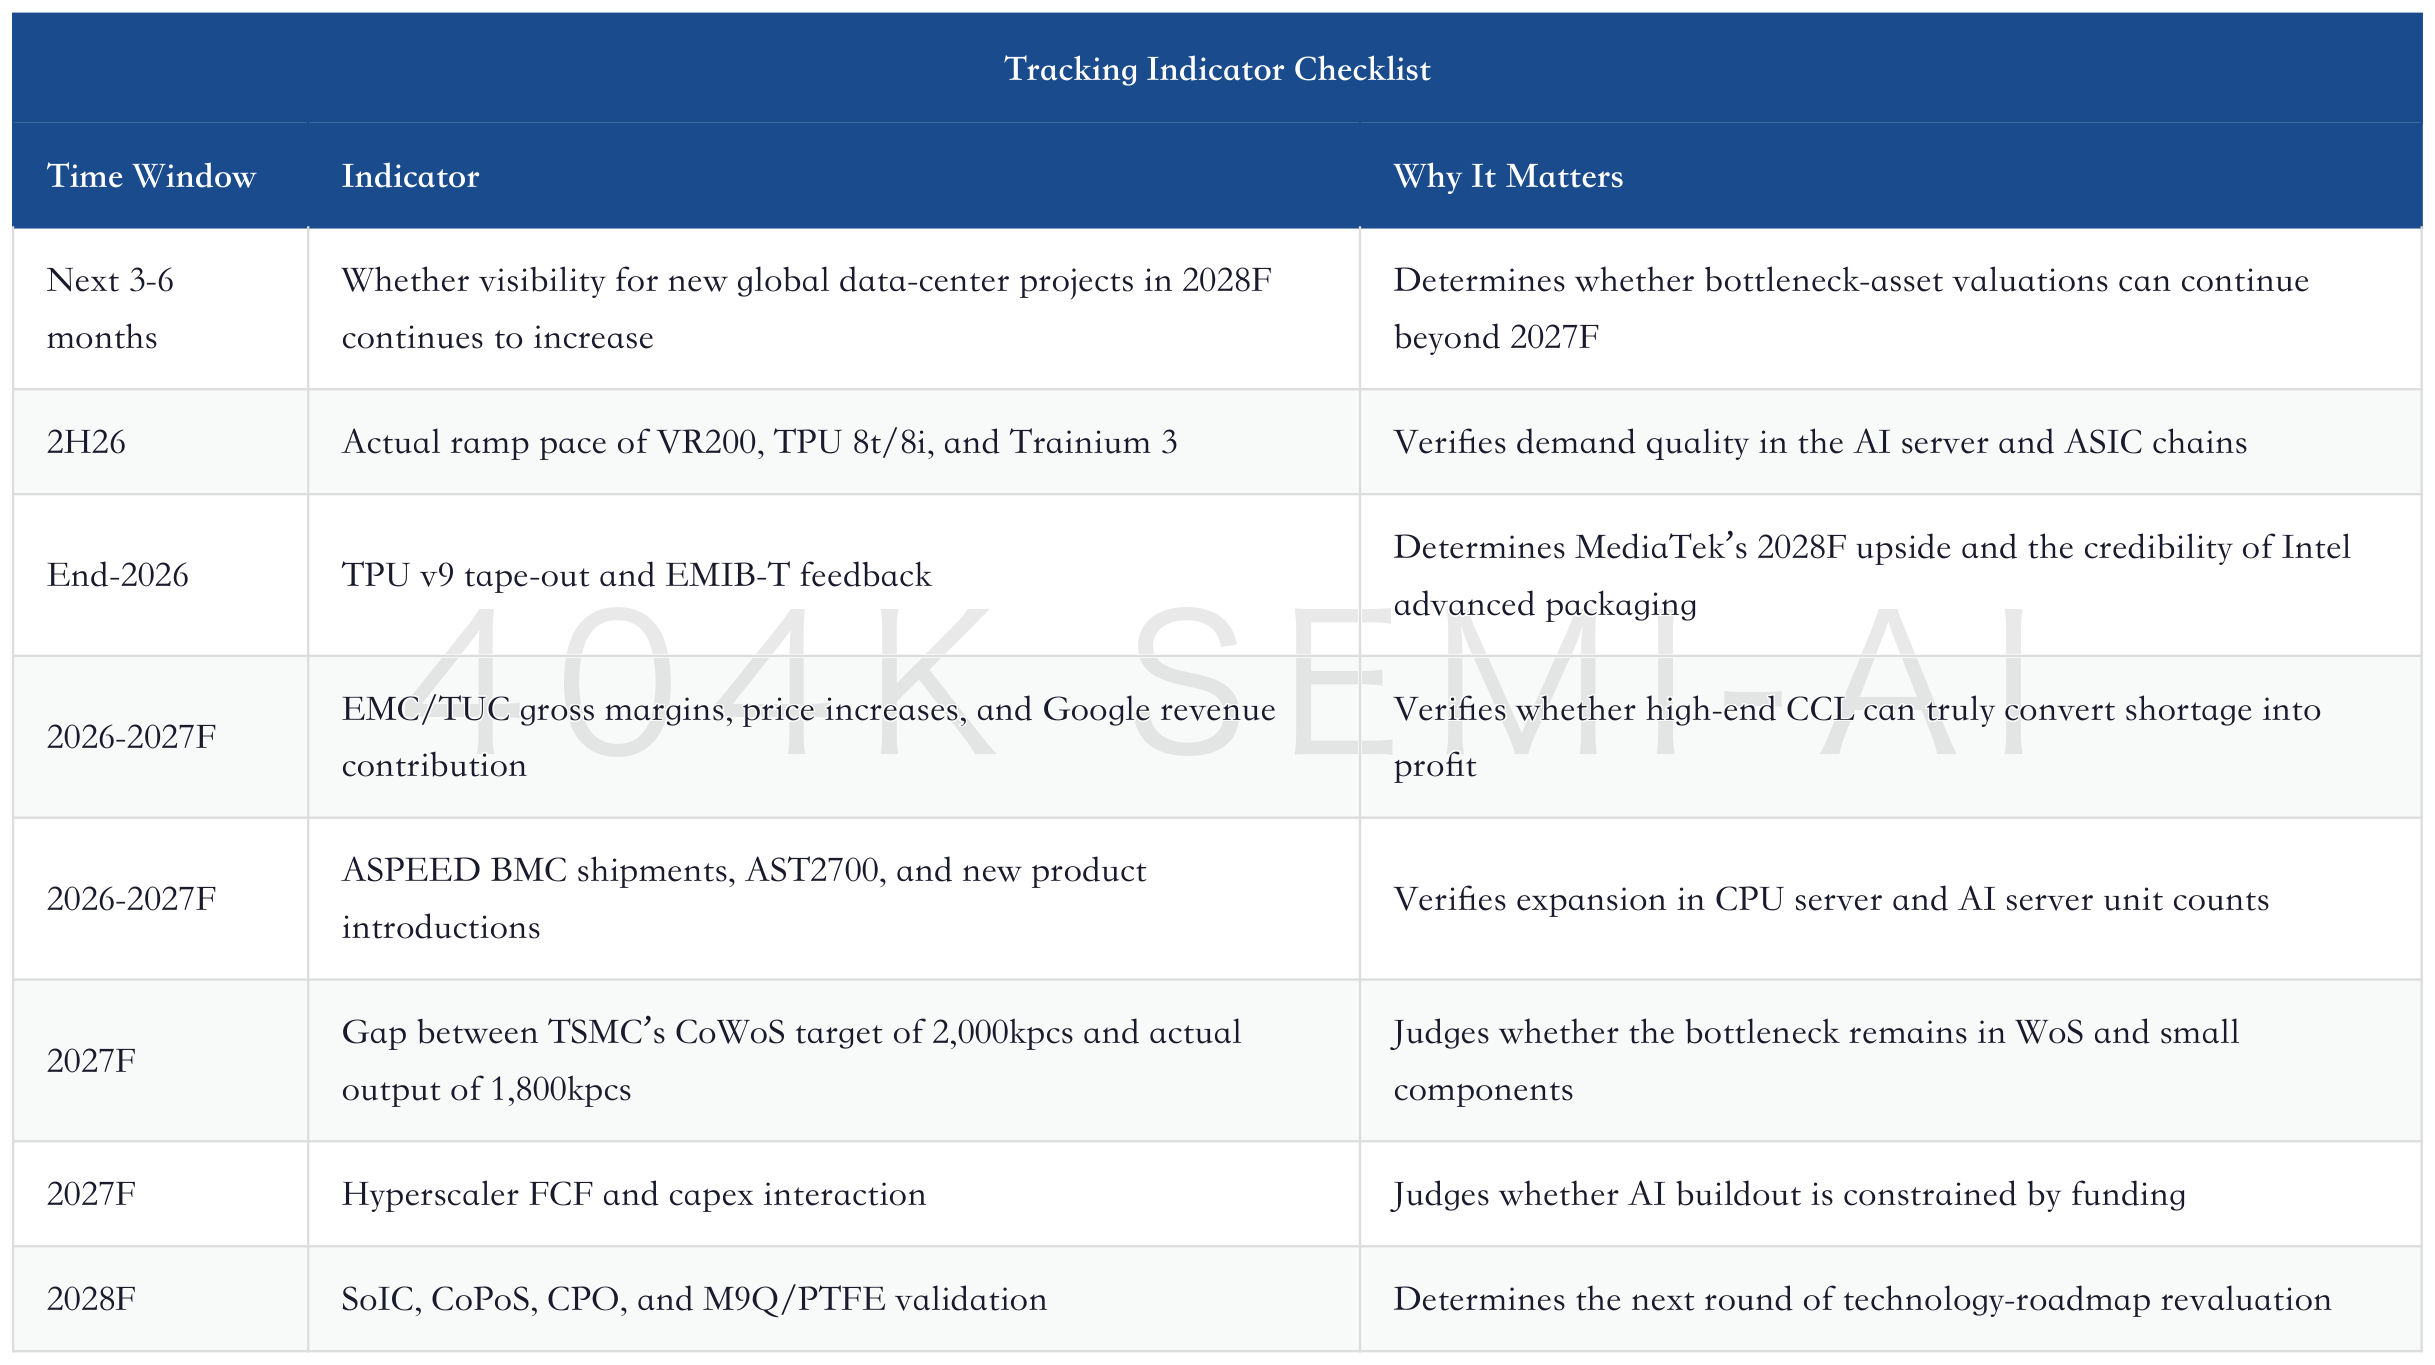
This indicator set can also guide positioning in reverse. If data-center visibility is revised up, CCL gross margins keep expanding, BMC shipments do not decline, and WoS price hikes can be passed through, pullbacks should first be treated as opportunities to add to high-quality bottleneck assets. If capex keeps being revised up but FCF deteriorates, orders are concentrated among financially fragile customers, and component companies show abnormal increases in receivables and inventory, it is time to begin reducing weights in pure high-beta equities. If technology milestones are delayed, long-dated option valuations should be cut back to near-term earnings verification.
X. Mapping the Asian Chain to A-Shares and Portfolio Discipline: Do Not Put All “AI Hardware” in One Basket
Although Nomura’s report covers the Asian semiconductor and server chain, its greater value for A-share investing is that it helps the market redraw mapping boundaries. In A-shares, the areas most often benchmarked are PCB, CCL, server power and cooling, optical modules, connectors, test equipment, and parts of the domestic compute chain. The problem is that Elite Material, TUC, ZDT, ASE, KYEC, and ASPEED in overseas reports cannot be crudely mapped into “all AI hardware companies benefit.” The real task is to identify what type of bottleneck each company is exposed to: material specifications, customer qualification, yield ramp, capacity delivery, or domestic substitution.
PCB and CCL are the areas most likely to generate mapping. Wus Printed Circuit, Victory Giant Technology, Shennan Circuits, Shengyi Technology, Kinwong Electronic, and DSBJ may all be put by the market into the AI PCB or high-end materials framework, but their ways of benefiting are not the same. Wus Printed Circuit and Victory Giant Technology are more likely to be tracked through high-end server boards, switch boards, and overseas AI customer chains. Shengyi Technology is more about materials and CCL capability, where the key is whether high-frequency, high-speed material grades, customer qualification, and gross margin can step up. Shennan Circuits, Kinwong Electronic, and DSBJ must be assessed separately for structural differences across package substrates, automotive electronics, consumer electronics, and server orders. Only by distinguishing order types and product specifications can the A-share mapping avoid becoming mere theme diffusion.
The most important verification indicator for AI PCB is not “whether there are AI orders,” but whether orders pass through three gates. The first is the customer gate: whether the company can enter leading cloud providers, GPU/ASIC platforms, ODMs, and switch supply chains. The second is the specification gate: whether it can handle high layer counts, low loss, high-speed interconnect, HDI, mSAP, and more difficult lamination. The third is the profit gate: whether specification upgrades show up in gross margin, ASP, and yield improvement. If a company only discloses server order growth, without changes in customer tier, product layer count, material grade, and gross margin, it cannot be directly valued as a “bottleneck asset.”
The CCL-materials mapping also needs to be more granular. High-end CCL is not simply about rising prices for copper foil, resin, and glass fabric; it is a material barrier jointly determined by low loss, high reliability, and customer qualification. The overseas report mentions specifications such as M8, M9, HVLP, and PTFE because AI servers and switches are upgrading across board layer counts, signal integrity, power density, and thermal design. For A-share materials companies to truly benefit, they need to prove they are entering high-frequency, high-speed materials, not ordinary server or consumer-electronics materials. From an investment perspective, the biggest risks for materials stocks are “large nominal capacity but little effective capacity” and “apparent price increases eaten up by yield.” Therefore, gross margin, product mix, customer qualification, and inventory turnover matter more than simple capacity-expansion announcements.
The mapping for server systems and power/cooling depends more on customer quality. An AI rack is not an ordinary server with GPUs added. GB/VR racks, TPU pods, Trainium clusters, and future Rubin Ultra platforms all require more complex power, cooling, backplanes, cables, connectors, liquid cooling, and system debugging. If an A-share company only indirectly supplies ordinary structural parts or ordinary server components, its upside will be weaker. Only companies that can enter high-power racks, liquid cooling, board-level interconnect, and core ODM supply chains are closer to the “system-delivery bottlenecks” in Nomura’s report. The risk in this direction is that system-integration value can be large, but profits may be compressed by customers; ultimately, bargaining power and project replicability matter.
Optical modules and optical interconnect are another important mapping, but they cannot be conflated with CoWoS and CCL. The larger AI clusters become, the more important east-west traffic, switch hierarchy, and optical-module speed upgrades become. CPO, NPO, linear drive, and higher-speed SerDes will all become long-term directions. Innolight, Eoptolink, TFC Communication, and Accelink have been repeatedly revalued by the market. The logic is not as simple as “more AI servers mean more optical modules,” but that speed upgrades, customer share, product yield, and supply-chain qualification together raise value per rack. Verification indicators here are shipment speed mix, customer share, gross margin, silicon photonics or CPO progress, not just industry TAM.
The domestic compute chain must be viewed separately and cannot directly apply the TSMC CoWoS model. Demand for data centers and domestic AI chips in China is real, but constraints differ across advanced process, advanced packaging, HBM, EDA, IP, packaging materials, and ecosystem software. Cambricon, Hygon Information, Loongson Technology, and Jingjia Micro face logics around domestic substitution, government and enterprise procurement, compute ecosystems, and supply security. The supply-demand models for overseas TPU, NVIDIA Rubin, and TSMC CoWoS can only provide a framework for “how bottlenecks are priced”; they cannot be directly used to forecast revenue. Domestic compute is better assessed through order landing, software ecosystem, customer repeat purchases, product iteration, and supply-chain self-sufficiency, rather than simply following overseas AI hardware price increases.
In portfolio terms, A-share mapping needs to be divided into three layers. The first is high-conviction assets, focusing on companies that have already entered leading overseas customers or high-end server chains and whose financial performance can be directly verified. The second is high-beta assets, focusing on companies where orders or technology milestones may open up, but customers and profit still need verification. The third is thematic assets, which have only conceptual relevance and lack trackable financial indicators. The first layer can use pullbacks for positioning. The second should be traded around milestones. The third can only be used as a risk-appetite tool; overseas supply-demand gaps in deep research reports should not be used to underwrite it.
This discipline also explains why “AI hardware is not over” and “do not chase AI hardware stocks indiscriminately” can both be true. Demand is very strong and bottlenecks are real, but strong demand does not automatically become profit for every company. The further we move into the second stage, the more important it is to ask four questions: is the company actually selling a bottleneck product; are customers willing to pay a premium for that bottleneck; after capacity expansion, will yield and pricing erode margins; and if the 2028F technology roadmap changes, can the company stay on the new platform? Only companies that can answer these four questions deserve higher valuations.
For tracking cadence, A-share investors should maintain separate tables for the overseas chain and the domestic chain. For the overseas chain, track TSMC’s actual CoWoS output, Google TPU revisions, Rubin/Rubin Ultra racks, EMC and TUC gross margins, ASE FOCoS, and KYEC test time. For the domestic chain, track formal orders, customer qualification, high-end product mix, gross margin, accounts receivable, inventory, and capex efficiency. If the overseas chain remains tight and domestic-chain verification also improves, A-share AI hardware can enjoy mapping diffusion. If the overseas chain remains tight but domestic-company profits do not keep up, investors should beware that it is only thematic premium.
Ultimately, the lesson from Nomura’s report for A-shares is not a command to “buy all hardware,” but a screening framework. What passes through the screen are companies genuinely blocking the process of bringing AI compute capacity online. What gets filtered out are companies merely adjacent to the AI narrative but lacking pricing power and profit verification. If the AI semiconductor cycle continues upward, the second stage will reward more granular research and punish cruder mapping.
XI. Conclusion: AI Semiconductors Are Still Moving Higher, but the Easy-Money Phase Is Over
The value of Nomura’s report is not that it repeats “AI demand is strong,” but that it pushes the AI hardware cycle into a more granular layer: data-center construction is still being revised upward, TSMC is becoming more aggressive on CoW capacity expansion, NVIDIA still captures the largest share, and Google TPU has become the biggest marginal variable. But what truly determines 2027F delivery is WoS, substrates, CCL, PCB, BMC, testing, CPU packaging, thermal management, and cash flow. The cycle is not over; the difficulty has increased.
From an investment perspective, the risk-reward of simply buying AI beta has declined, while the risk-reward of buying bottleneck quality has improved. For platform assets, focus on TSMC and ASE Technology; for high-beta assets, MediaTek, ASPEED, and ZDT; for materials bottlenecks, EMC/Elite Material; for testing, King Yuan Electronics; and for longer-dated options, GlobalWafers, BESI, Soitec, and the CPO/SoIC supply chain. China-related mappings need to be grounded in official security names and real certification progress; overseas materials suppliers, Taiwan PCB names, and A-share PCB names should not be blended into one vague sector bucket.
The real risk to watch is not that AI demand suddenly disappears, but that the market treats every bottleneck as the same kind of certainty. Tight 2027F supply does not mean every company can raise prices; upward revisions to Google TPU do not mean every ASIC can secure resources; CoWoS capacity expansion does not mean WoS and small components are no longer in shortage; and upward revisions to server revenue do not mean cloud providers face no cash-flow pressure. The next phase of alpha will belong to investors who can verify these differences item by item.
After this AI semiconductor rally entered its second stage, the best question is no longer “who is most like NVIDIA,” but “without whom can expensive compute not come online?” That question shifts attention away from large chips and toward a set of smaller, narrower, harder-to-replace links. As long as data-center construction keeps advancing, these small links will continue to have pricing power; once construction slows, cash flow tightens, or technology roadmaps are delayed, they will also be the first to reveal valuation elasticity. AI is not over, but it no longer rewards crude optimism.Asia AI Semiconductor and Server Deep Dive: The Cycle Has Not Peaked; 2027 Bottlenecks Shift to WoS, CCL, and Small Components
目录
Too Long; Didn’t Read
I. This Pullback Is Not the End of the Cycle, but the Second Stage of the Bottleneck Trade
II. Demand Side: Data-Center Construction Gives the Answer Earlier Than Supply-Chain Orders
III. Supply Side: After CoW Targets Were Revised Up, WoS and Small Components Became Bigger Gates
IV. GPU and TPU Revenue Split Reset: NVIDIA Remains the Largest, While Google and MediaTek Capture Marginal Elasticity
V. Server Demand Continues to Be Revised Upward: CPU, BMC, and OSAT Begin to Develop Independent Logic
VI. Advanced Packaging Roadmaps: EMIB-T, SoIC, CoPoS, and SiC Decide Who Survives Beyond 2028F
VII. PCB/CCL/HDI: The Second Main Battlefield in AI Hardware
VIII. Target Prices Raised for Nine Companies: Not the Same Type of Opportunity
IX. Three Worldviews: How to Decide Whether to Buy the Pullback or Wait for Falsification
X. Mapping the Asian Chain to A-Shares and Portfolio Discipline: Do Not Put All “AI Hardware” in One Basket
XI. Conclusion: AI Semiconductors Are Still Moving Higher, but the Easy-Money Phase Is Over
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
Nomura’s Asia technology overview gives a direct answer: the pullback in AI semiconductors looks more like consolidation at elevated levels than the end of the cycle. The 2027 battleground is shifting from securing CoWoS to who can secure WoS, substrates, CCL, testing, BMC, CPU, and cash-flow support. The investment hierarchy is also broadening from GPU beta to small-gatekeeper assets that determine accelerator-card delivery.
Too Long; Didn’t Read
The cycle has not peaked. The SOX had already rallied substantially, so a pullback is not surprising in itself. The real point is that Nomura’s global new data-center tracker is still being revised upward, with the 2027F incremental deployment target raised to 32GW. This suggests physical construction demand remains behind the order noise. If 2028F visibility continues to improve over the next 3-6 months, AI hardware earnings upgrades could still outweigh valuation volatility.
The bottleneck is migrating. TSMC has sharply raised its 2027F CoWoS target from roughly 1,300-1,350kpcs to 2,000kpcs, but Nomura models only 1,800kpcs because the real shipment constraint may no longer be CoW, which TSMC controls, but WoS, IC substrates, CCL, high-end PCB, capacitors, PMIC, optical components, and testing capacity. This migration will shift the market from “who can buy GPUs” to “who controls small-component delivery rights.”
Google TPU is changing the profit split. Nvidia remains the largest customer, and Nomura estimates it will receive about 55% of TSMC’s 2027F CoWoS allocation. But Google TPU’s share could rise from about 23% in 2026F to about 26% in 2027F, pushing Google’s contribution to TSMC AI revenue to 25%. MediaTek has secured a higher share in TPU 8t and the subsequent TPU v9. TPU-related revenue in 2027F and EMIB-T execution in 2028F will affect the pace at which Asian semiconductor profits spread from GPUs to ASICs.
Servers are not just about GPUs. Nomura also raises AI server and general-purpose/CPU server revenue, indicating that agentic AI, inference workloads, and memory price increases are lifting server ASPs together. BMC, CPU packaging, testing, ODMs, and power/thermal solutions are beginning to gain independent pricing logic, rather than remaining mere appendages to GPU shipments.
PCB and CCL are entering a second round of price increases. VR200, Rubin Ultra, Google TPU 8t/8i, and Trainium 3 are all pushing requirements higher for layer count, low-loss materials, and HDI. Opportunities for EMC, Taiflex, ZDT, Unimicron, Victory Giant, WUS Printed Circuit, and others come from specification upgrades and supply shortages, not just growth in AI server volumes. The key question is not simply whether capacity is being added, but whether M8/M9, HVLP3/HVLP4, mSAP, customer qualification, and yield can all open up at the same time.
The biggest risks are cash flow and 2028 technology validation. Hyperscale cloud providers may face a conflict in 2027F between upward revisions to AI capex and insufficient free cash flow, especially if memory costs keep rising. Technically, EMIB-T, CoPoS, GPU-on-GPU SoIC, CPO, 336G/448G SerDes, M9Q/M10Q PCB, and PTFE materials still need validation. If 2028F data-center project visibility stalls, EMIB-T yield disappoints, or WoS price increases cannot be passed through, bottleneck assets will be the first to face valuation pullbacks.
I. This Pullback Is Not the End of the Cycle, but the Second Stage of the Bottleneck Trade
The easiest mistake in AI semiconductors is to apply traditional semiconductor-cycle signals directly to the current environment. Price increases, long-term agreements, excess ordering, and customers competing for capacity often signal that a peak is approaching in a traditional cycle. This time, however, demand is not coming from smartphone, PC, or automotive inventory. Cloud providers, AI labs, and neoclouds are turning data centers into a new layer of production infrastructure. Price signals have indeed heated up and valuations are crowded, but that does not mean the delivery cycle has ended.
Nomura frames the issue clearly: the near-term pullback has reasonable causes. The market needs to digest what may be a historically large component mismatch, free-cash-flow pressure among cloud providers in 2027F, uncertainty around technology roadmaps after 2028F, and valuation pressure from rising long-end U.S. rates. But these risks do not change the core fact: if more GW-scale data centers still need to come online in 2027F, while greenfield capacity expansion only truly starts from late 2025, supply will remain tight next year. Under this framework, the pullback looks more like a repricing of risk by capital markets than the end of the fundamental cycle.
This means the investment hierarchy needs to change. The first stage was buying “GPU supply shortage.” The second stage is buying “who enables GPUs, TPUs, and CPUs to actually come online.” If data centers have already secured power, land, financing, and customer demand, hardware shortages will spread along the value chain: advanced packaging first, followed by WoS, testing, substrates, CCL, PCB, power, liquid cooling, BMC, connectors, and ODM delivery. This diffusion will create more opportunities, while also making low-quality beta easier to eliminate.
The core conclusion of this report can be stated upfront: AI semiconductors have not entered an easy phase. They have entered a harder selection phase. Nvidia, Google, and TSMC remain the systemic core, but 2027F share-price upside is more likely to come from underappreciated small gatekeepers: whose capacity cannot be replicated quickly, whose customer qualification cycle is longer, whose pricing can be passed through, and whose gross margin can keep rising during expansion.
II. Demand Side: Data-Center Construction Gives the Answer Earlier Than Supply-Chain Orders
Sell-side models are easily disturbed by order revisions; data-center construction is closer to real demand. Nomura began tracking global new data-center construction plans in 4Q25 and uses them as a leading indicator for Asian semiconductor hardware demand. The value of this method is that it does not only look at how many orders a given GPU or ASIC customer has placed. It examines whether power, land, campuses, partners, and launch schedules are still moving forward. As long as these construction plans do not disappear, hardware-chain demand will not go to zero because of a change in one quarter’s pull-in cadence.
The three most important numbers in this update are: project count increased from about 240 to about 280; GW-scale projects increased from more than 40 to about 50; and 2027F incremental deployment was revised up from 28GW to 32GW, while visible 2028F demand rose from 21GW to 23GW. 2026F remains broadly unchanged at 26GW, indicating that near-term timing has not moved forward sharply, but construction pressure in 2027F is heavier. In other words, the next year is not about “whether there is demand,” but “which hardware can keep up with the construction schedule.”
The demand structure is even more notable. The top-four CSPs remain important, but an increasing number of new projects are coming from new infrastructure participants such as OpenAI, Anthropic, CoreWeave, Nebius, HUMAIN, SoftBank Group, SK Telecom, xAI, and IREN. OpenAI and Nvidia’s 10GW project, OpenAI and Broadcom’s 10GW ASIC plan, Google Texas 6.2GW, Meta Hyperion’s expansion from 2GW to 5GW, and SoftBank Group’s multi-GW projects in France and Ohio are turning AI hardware demand from “cloud capex” into broader AI-factory capital spending.
This change will shift how the supply chain should be tracked. In the past, monitoring the capex of the four major cloud providers and Nvidia’s data-center revenue could explain most hardware demand. Now investors also need to track whether AI labs can secure financing, whether neoclouds can obtain customers, whether projects have power access, and whether racks can be delivered at the system level. The supply chain will face more customers, but customer quality will also diverge more. High-quality bottleneck companies benefit from demand diffusion, while lower-quality segments may be misled by excessive orders.
China’s data-center construction is also accelerating, but Nomura does not include Chinese projects in its CoWoS calculation sample. The reason is that these projects are more oriented toward domestic computing power, with lower direct relevance to TSMC’s advanced-packaging capacity. This treatment is important: it shows that the report is not broadly saying “global AI is strong,” but is filtering for demand that can actually drive Asian AI hardware, especially TSMC, packaging, substrates, PCB, and testing. China’s compute supply chain has its own domestic mapping, but it should not be used simplistically to revise up TSMC CoWoS demand.
The demand-side investment implication is straightforward: the market should not only watch whether GPU orders are revised up, but also whether data-center projects can continue turning power demand into hardware procurement. If 2028F visibility keeps improving over the next 3-6 months, valuations for 2027F bottleneck assets will be easier to support. If 2028F projects are delayed, financing costs rise, and cloud-provider free cash flow comes under pressure, the market will quickly shift from a “price-increase thesis” to “who has the highest-quality demand.”
III. Supply Side: After CoW Targets Were Revised Up, WoS and Small Components Became Bigger Gates
TSMC is not failing to expand capacity this time. Nomura now sees TSMC’s 2027F CoWoS target capacity at 2,000kpcs, materially above the previous assumption of roughly 1,300-1,350kpcs; 2026F is also around 1,100kpcs. The issue is that CoWoS is not a single process step. The market tends to treat it as TSMC packaging capacity, but actual delivery is jointly determined by CoW and WoS: CoW attaches chips to wafers and integrates interposers with dies; WoS attaches the wafer-level package to the substrate after wafer-level packaging, involving substrates, substrate supply, materials, outsourced packaging, and yield.
Nomura’s counterintuitive view is that once TSMC-controlled CoW becomes more aggressive, WoS, which is not fully controlled by TSMC, may instead become the bigger bottleneck. This matters for investing. If the bottleneck remains in CoW, TSMC and advanced packaging equipment are the most direct beneficiaries; if the bottleneck migrates to WoS and small components, ASE, Amkor, IC substrates, CCL, PCB, testing, BMC, PMIC, capacitors, and optical components all enter the pricing chain. In other words, TSMC’s capacity expansion has not weakened the bottleneck trade; it has fragmented it.
There is also a long-term issue that is easy to overlook: if Feynman moves to CoPoS in 2029F, why would TSMC not expand CoWoS indefinitely? Nomura’s “back-of-the-envelope” estimate is instructive. If NVIDIA still takes roughly 50% of advanced packaging supply in 2029F, Feynman alone could consume roughly 1,400kpcs of CoWoS; but if Feynman migrates to 310x310mm CoPoS panels, TSMC would need 700-800k panels rather than an equivalent wafer-based CoWoS volume. This explains why TSMC is both aggressive and cautious: it must meet Rubin and TPU demand in the short term, while avoiding putting all capex behind linear CoWoS expansion over the long term.
This is also why 2027F will not be a simple year of “capacity increases and prices fall.” When many component suppliers made expansion plans in 2H25, they underestimated the upside potential in AI orders, especially smaller component suppliers, which reacted more slowly than TSMC. As a result, by 2H26F, Rubin, Trainium 3, TPU 8t/8i, CPUs, and high-end server motherboards will ramp together, simultaneously tightening PCB/CCL, IC substrates, high-end capacitors, PMIC, optical components, test interfaces, and BMC. Price increases are not driven by greed in any single segment, but by unsynchronized expansion across the supply chain.
The real debate is here: is bottleneck migration bad or good? In the short term, it will create greater share-price volatility because the market will worry that component shortages may affect system shipments. In the medium term, it may instead extend the cycle, because supply can no longer be solved by one giant expanding capacity. As long as demand remains, the more dispersed the bottlenecks, the easier it is for price increases and earnings upgrades to rotate across more companies.
IV. GPU and TPU Revenue Split Reset: NVIDIA Remains the Largest, While Google and MediaTek Capture Marginal Elasticity
The sharpest line in Nomura’s report can be translated into one supply-chain reality: when elephants fight, the grass gets trampled. The elephants here are NVIDIA and Google. NVIDIA remains the largest contributor to TSMC AI revenue, while Google TPU is the fastest-growing ASIC force in 2027F. Together, they are competing for advanced packaging, 3nm, substrates, CCL, and testing resources. Other GPU/ASIC customers may have real demand, but could still be squeezed by lower scheduling priority.
NVIDIA still takes the largest resources, but Google TPU’s marginal upward revision is faster. This does not mean NVIDIA is weakening; it means Google TPU is lifting TSMC AI revenue, CoWoS allocation, and ASIC supply-chain share at the same time. Beneficiaries include not only Google’s own accelerator ecosystem, but also MediaTek, Broadcom, TSMC, ASE, King Yuan Electronics, and CCL/PCB suppliers.
MediaTek is the company with the most elasticity in this chain. Nomura raised its target price not because of a traditional smartphone-chip recovery, but because of upward revisions to Google TPU and non-TPU ASIC contributions. Management has also pulled forward its ASIC share target and raised near-term revenue guidance at the same time, showing that the market is repricing MediaTek from a “smartphone SoC cycle stock” into an “ASIC design platform in the Google TPU chain.”
The risks around TPU are also clear. TPU v9 in 2028F may use Intel EMIB-T, with higher MediaTek participation, but EMIB-T still needs to prove yield, packaging complexity, and mass-production cadence. The report notes that TPU v9 could have close to 30 silicon bridges embedded in a large substrate, with specifications deviating from the current AI/HPC substrate architecture; mass-production yield should not be assumed lightly. For investors, this means MediaTek has high elasticity but also clear technical validation milestones: tape-out by end-2026, 2028F ramp, and Intel’s advanced packaging execution capability.
NVIDIA’s marginal change is not “weak demand,” but product cadence and system form factor. Rubin production may not see a significant volume ramp until 4Q26F, with large-scale rack shipments coming even later; Rubin Ultra starts production from 2027E, and its packaging form factor may move back closer to Rubin’s two-GPU-die package from the previously more complex dual-Rubin module interconnect. This would make the Rubin Ultra transition smoother, but also shows that CPO/NPO, Oberon, HBM4, and small-component maturity are still affecting platform cadence.
The investment conclusion for this chain is: GPU remains the base, TPU is the marginal elasticity, and other ASICs depend on whether they can obtain strategic resources. Simply saying “ASICs will replace GPUs” is too crude. A more accurate statement is that AI compute is entering a phase where multiple customers, multiple packaging routes, and multiple small-component bottlenecks coexist. NVIDIA will not lose platform power, but Google TPU will change profit allocation for TSMC, MediaTek, Broadcom, CCL/PCB, and testing suppliers.
V. Server Demand Continues to Be Revised Upward: CPU, BMC, and OSAT Begin to Develop Independent Logic
The server market is moving from “GPU servers standing alone” to “AI servers and CPU servers being revised up together.” Nomura raised total server revenue, AI server revenue, and general-purpose/CPU server revenue at the same time, indicating that demand is not concentrated only in GPU racks. This mix is important: even if GPU shipment timing fluctuates, CPU servers, head-node CPUs, AI inference servers, and agentic AI workloads are still pulling the entire server supply chain.
Nvidia racks are also being revised up, but the cadence is more nuanced. Nomura raised its 2026F realistic shipment forecast for GB/VR racks from 50k units to 54.5k units, with VR200 accounting for 15-20%, concentrated in 4Q26F. It also added a 62k-unit forecast for 2027F and assumes the transition from Rubin to Rubin Ultra may occur in 2Q27F. The HGX versus GB/VR mix has also been adjusted: HGX’s 2026F share rises from 18% previously to 30%, because after Rubin is affected by bottlenecks, Nvidia needs more Blackwell GPUs to satisfy committed CoWoS consumption. By 2027F, the market returns to a state where VR200 demand is stronger than supply.
This sends two signals to ODMs and system delivery vendors. First, system makers are not just “contract manufacturers”; during the transition period, they absorb configuration changes, yield issues, inventory, and component shortages. Second, neoclouds will play a larger procurement role during the GB300-to-VR200 transition, helping AI companies sustain token demand growth. This demand is more complex, and order quality will vary more. Strong ODMs and component vendors will increasingly need customer-screening capabilities.
The OSAT opportunity comes from another direction: advanced CPU packaging. ASE Technology and Amkor may not immediately replace TSMC in high-complexity GPU/ASIC CoW, because high HBM content and immature assembly yields could create large losses. But CPU packaging is low-hanging fruit. CPUs do not have expensive HBM, while RDL line width and layer-count requirements are relatively relaxed. OSATs can first enter CoWoS-like full-process flows through projects such as AMD Venice CPU, Nvidia Vera CPU, and Microsoft Cobalt.
Server Industry Revaluation: From CPU Platforms to AI Acceleration Systems
BMC is another small segment that is easily underestimated. Nomura estimates that the AI server system BMC SAM will expand rapidly, with Google TPU servers among the largest sources of incremental demand. ASPEED Technology’s own shipment forecasts also show AI-related BMC and total BMC shipments rising in tandem. BMC unit prices and value content are not as eye-catching as GPUs, but BMC is the management gateway required in every server. Shipment expansion and supply tightness will flow directly into financial results.
ASPEED’s value is not in telling a scarce small-cap story, but in providing a more granular validation indicator for AI server volumes. If BMC orders, the AST2600-to-AST2700 transition, and progress on new products such as AST1840 continue to improve over the next few quarters, it would indicate that server and CPU inference demand has not stopped. If BMC orders weaken, investors should watch for the server chain shifting from real demand to inventory accumulation.
VI. Advanced Packaging Roadmaps: EMIB-T, SoIC, CoPoS, and SiC Decide Who Survives Beyond 2028F
The bottleneck in 2027F is more about whether the supply chain can deliver. After 2028F, the bottleneck becomes whether technology roadmaps can extend further. Nomura lists a long set of technologies that must be broken through: EMIB-T, CoPoS, GPU-on-GPU SoIC, microchannel lid, CPO, 336G/448G SerDes, M9Q/M10Q PCB, PTFE, and new HDI tools/materials. These are not a pile of technical terms. They answer the same question: when 2.5D packaging, HBM, and PCBs are all close to being fully stretched, how can next-generation AI chip performance continue to scale?
Intel EMIB-T is the external threat to TSMC advanced packaging most worth watching. If Google TPU v9 adopts a MediaTek + Intel EMIB-T path, it will be both a growth opportunity for MediaTek and a real-world test of Intel Foundry’s advanced-packaging capability. EMIB-T adds TSVs into the silicon bridge, shortening the power path and improving power integrity between HBM4/4E and logic chiplets. Intel’s roadmap targets integrating more than 8x reticle top silicon on an approximately 120x120mm substrate in 2026E, and more than 12x reticle top silicon on a substrate larger than 120x180mm in 2028E.
SoIC is critical for TSMC to defend its lead in advanced packaging. 2.5D packaging expands laterally, laying out the GPU, HBM, interposer, and substrate. SoIC stacks vertically, increasing transistor count and compute density within the same area. Nvidia Feynman may attempt GPU-on-GPU SoIC, which would push thermal density and hybrid-bonding yield to a higher level of difficulty. TSMC’s SoIC capacity may rise from about 5kwpm at end-2025 to more than 40kwpm by end-2028, doubling in both 2027F and 2028F.
SiC carrier is a small but representative materials change. If Feynman uses a larger size and higher TDP, traditional silicon carrier will become a problem for thermal conductivity. SiC has higher thermal conductivity than silicon, as well as better mechanical strength and chemical stability. As SiC costs decline due to industry capacity expansion over the past few years, its commercialization in chip-level thermal management may come earlier. Nomura raised its target price for GlobalWafers to NT$1,200, reflecting this option value from migrating out of power semiconductor materials into advanced-packaging thermal-management materials.
This section should not be treated only as a technology optimism narrative. If EMIB-T yields fail to qualify, the 2028F upside for Google TPU v9 and MediaTek will be discounted. If CoPoS is delayed, TSMC will need to continue bearing pressure from large-size CoWoS. If SoIC capacity ramps slowly, the Feynman roadmap may be delayed. If CPO remains immature, the Oberon version of Rubin Ultra may remain optional. After 2028F, technology execution will matter more than the 2026F-2027F order revisions.
VII. PCB/CCL/HDI: The Second Main Battlefield in AI Hardware
PCB and CCL are no longer merely “peripheral materials for AI servers.” GB200, GB300, VR200, Rubin Ultra, Trainium 3, and TPU 8t/8i are lifting motherboards, UBBs, switch trays, CPU boards, all-to-all switch boards, and potential backplanes together. Materials are moving from M7/M8 to M8.5, M9K2, M9Q, and PTFE; copper foil is moving from HVLP2 to HVLP3/HVLP4; structures are moving from ordinary HLC to HDI/mSAP. Every platform upgrade increases the number of boards, layer count, material grade, and certification difficulty.
Nomura’s view on EMC is highly representative. EMC’s 2Q26 revenue is expected to grow 37% QoQ, with gross margin potentially expanding further to 32.4%; demand from Google Ironwood and AWS Trainium 3 is strong, and pricing improvement is proceeding more smoothly than expected. More importantly, CCL content opportunities from Google TPU/CPU boards and switches could nearly triple by 2027F, accounting for 58% of EMC’s AI revenue, up from 38% in 2026F. When customers need more high-end materials, while production lines require certification, lamination, yield, and equipment support, CCL is no longer just copper and resin. It becomes delivery rights.
Taiwan Union Technology follows similar logic but with higher earnings sensitivity. Nomura raised its target price for Taiwan Union Technology from TWD 1,710 to TWD 2,115, valuing it at 30x 2027F EPS, based on high-end CCL specification upgrades and worsening supply-demand conditions. Taiwan Union Technology is smaller than EMC, so price increases and mix improvement have greater profit leverage; the downside is that its customer and capacity scale are also more sensitive. EMC is more platform-like, while Taiwan Union Technology is more elasticity-oriented. Together, they validate the view that high-end CCL is not an ordinary materials cycle.
ZDT represents a crossover opportunity across PCB/HDI and substrates. Nomura raised its target price for ZDT from TWD 510 to TWD 720, citing tight supply in AI substrates, PCB, and HDI; a 2026E target of 70%+ growth in IC substrate sales; a target to double server/optical-communications sales in 2026E and 2027F; and a 2026E capex increase from TWD 50bn+ to TWD 80bn+. ZDT has begun producing VR200 Bianca HDI boards and will ramp Google switch boards in late 3Q26F; optical module mSAP boards can grow 10x in 2026E and another 2x in 2027E.
AI Interconnect Enters Board-Level Revaluation: New Incremental Demand from 1.6T, mSAP, and High-End CCL, with TAM Growing 6x in Three Years
The debate in this segment is not demand, but effective supply. Expanding AI PCB and high-end CCL capacity looks easy, but in practice it must pass through six gates: materials, equipment, lamination, drilling, yield, customer certification, and cash flow. Ordinary capacity additions do not immediately become effective capacity for M9, PTFE, HVLP4, 44L, 78L, or 104L. The companies that can actually convert this into profit are not necessarily those announcing the most capex, but those with the deepest customer certifications, most stable yields, highest-end material mix, and smoothest price pass-through.
AI-PCB Deep Dive: After a RMB 562bn TAM Revaluation, Who Can Better Convert Profit, Wus Printed Circuit or Victory Giant Technology?
VIII. Target Prices Raised for Nine Companies: Not the Same Type of Opportunity
Nomura raised target prices for nine companies in one move, but they are not the same type of asset. TSMC is a platform gatekeeper; ASE Technology is spillover from WoS and advanced CPU packaging; Aspeed is a BMC shipment validator; MediaTek is Google TPU leverage; GlobalWafers is an option on SiC carriers and thermal-management materials; King Yuan Electronics is AI test time and customer breadth; EMC/Taiwan Union Technology are high-end CCL bottlenecks; ZDT is a crossover across AI PCB/HDI/substrates. From an investment perspective, they should not all be treated as “AI beta.”
The first group is platform and base-layer assets: TSMC, ASE Technology, and King Yuan Electronics. TSMC controls the main gate for advanced process and advanced packaging, offering steadier valuation but with upside diluted by market cap; ASE Technology captures WoS outsourcing, FOCoS, and advanced CPU packaging, with leverage from packaging spillover; King Yuan Electronics captures test time and AI chip complexity, with relatively less exposure to changes in a single customer’s share because as AI XPUs and ASICs become more complex, total testing volume is more likely to rise.
The second group is demand-side leverage assets: MediaTek, Aspeed, and ZDT. MediaTek’s key variable is whether Google TPU can continue to be revised upward, and whether the TPU v9 EMIB-T path can be validated on schedule; Aspeed’s variable is whether BMC shipments for AI servers and CPU servers can continue; ZDT’s variable is whether AI substrates, VR200/Google switch boards, and optical module mSAP boards can deliver. Their common feature is higher revenue sensitivity; the downside is that valuations are also more prone to being priced in early.
The third group is materials bottleneck assets: EMC, Taiwan Union Technology, and GlobalWafers. EMC and Taiwan Union Technology directly benefit from high-end CCL price increases and material upgrades, where profit leverage and gross margin changes matter more than revenue; GlobalWafers is more of an option on the post-2028F technology roadmap through SiC carriers. The biggest risk for materials stocks is “capacity expansion killing prices,” but high-end AI materials are not only about nominal capacity. They also depend on customer certification, product grade, and yield.
For portfolios, this table is more useful than target prices alone. If the focus is 2026F-2027F earnings upgrades, EMC, Taiwan Union Technology, ZDT, Aspeed, ASE Technology, and King Yuan Electronics are easier to verify through quarterly results. If the focus is post-2028F technology roadmaps, TSMC, MediaTek, GlobalWafers, BESI, and Soitec have more optionality. If the market turns defensive, platform assets such as TSMC and Samsung Electronics are better positioned to absorb volatility; if risk appetite continues to rise, small-component bottleneck stocks will have greater elasticity.
A better ranking method is to break target price upgrades into four types of earnings quality. The first is capacity-platform earnings, where upgrades come from long customer queues and sustained capex investment, represented by TSMC. For these companies, the most important factor is not single-quarter price increases, but whether advanced process, advanced packaging, and customer roadmaps can remain bound to the same platform. Even if TSMC’s target price increase is smaller than that of mid- and small-cap bottleneck stocks, it remains the benchmark asset for the entire chain because it determines advanced process, CoWoS, SoIC, CoPoS, and customer allocation rules. If TSMC’s AI revenue continues to be revised upward, downstream materials, packaging, and testing companies can have sustainable orders; if TSMC’s AI revenue growth slows, the valuation anchor for the entire chain will loosen first.
The second is delivery-spillover earnings, where upgrades come from TSMC or system customers outsourcing part of bottleneck capacity to partners, represented by ASE Technology and King Yuan Electronics. ASE Technology’s FOCoS, WoS outsourcing, and AMD Venice CPU opportunities are essentially about absorbing delivery pressure from TSMC’s back-end and advanced CPU packaging; King Yuan Electronics absorbs longer test time, more ASIC customers, and higher AI chip complexity. Unlike materials stocks, they are not directly about price hikes; unlike MediaTek, they are not a bet on one major customer’s share. Instead, they capture labor hours and service value from “increasing complexity.” This earnings quality is usually less stable than TSMC’s, but more resilient to customer switching than single-product price increases.
The third is customer-share earnings, where upgrades come from a sudden increase in share at a major customer or product line, represented by MediaTek, Aspeed, and ZDT. MediaTek captures ASIC share in Google TPU 8t, 8i, and TPU v9; Aspeed captures BMC shipments after both AI servers and CPU servers expand; ZDT captures Google switch boards, VR200 Bianca HDI, optical module mSAP, and AI substrates. Their advantage is high elasticity, with revenue upgrades quickly entering models; the risk is that validation points are more concentrated, and any major-customer schedule change, yield issue, or price negotiation can shift valuation from “certain growth” back to “order volatility.”
The fourth is materials price-hike earnings, represented by EMC, Taiwan Union Technology, and some high-end PCB/CCL suppliers. These companies look most like cyclical stocks, yet least like traditional cyclical stocks. The similarity is that prices, gross margins, and inventory determine share-price elasticity; the difference is that high-end AI materials are not ordinary chemicals or copper foil. Customer certification, low-loss performance, lamination yield, board layer count, and supply stability all constrain effective supply. As long as supply of M8, M9, HVLP4, PTFE, and high-layer-count PCB cannot keep up, price increases are not a short-term inventory cycle, but a profit revaluation driven by specification upgrades.
Under this framework, investors should not look only at the percentage increase in target prices. MediaTek’s target price saw the largest increase, showing the sharpest revenue leverage from Google TPU; TSMC’s target price increase was relatively moderate, yet it provides the most stable demand anchor for the entire chain; target price changes for EMC and Taiwan Union Technology should be assessed together with gross margin, pricing, and customer certification; ZDT depends on whether capex can translate into effective capacity; Aspeed depends on whether AI BMC and CPU server BMC grow in tandem; ASE Technology and King Yuan Electronics depend on WoS, FOCoS, test time, and customer breadth. Target price is the result; what can truly be tracked is the source of earnings quality.
This breakdown also explains why stocks in the same AI chain cannot use the same buy/sell discipline. Platform assets are best assessed by long-term revenue slope and customer lock-in, and behave more like portfolio anchors during drawdowns; delivery-spillover assets should be assessed by quarterly utilization, pricing, and customer breadth, where earnings upgrades matter more than thematic narratives; customer-share assets require dynamic noise reduction around order realization, and one design win should not be capitalized directly across multiple years; materials price-hike assets require strict tracking of gross margin and inventory, because once price pass-through stalls, valuation elasticity can quickly reverse; long-dated option assets require waiting for technology milestones, rather than forcing short-term earnings to justify long-term imagination.
The easiest mistake is to interpret a “bottleneck” as something that is scarce forever. A bottleneck has value only when three conditions hold at the same time: downstream demand is real, capacity expansion cannot be quickly replicated, and pricing can be passed through to customers. If any one condition is missing, the bottleneck turns from an asset into inventory risk. AI hardware still satisfies the first two conditions today; the third must be verified company by company. Elite Material and TUC must be verified through gross margin. ZDT must be verified through effective capacity and customer ramp. ASE must be verified through FOCoS revenue. KYEC must be verified through test time and customer coverage. ASPEED must be verified through BMC shipments. MediaTek must be verified through Google TPU revenue. TSMC must be verified through actual CoWoS output and AI revenue.
Therefore, 2027F looks more like a “profit-quality exam” than a simple order contest. Orders can be placed early, capacity can be expanded early, and target prices can be raised early. But what really determines share-price durability is whether companies can turn orders into recognized revenue, price hikes into gross margin, capex into effective capacity, and design wins into multi-year share. If these indicators are delivered simultaneously, the second stage of AI semiconductors can remain very strong. If there are only orders without profit quality, the pullback will shift from healthy digestion to valuation reset.
IX. Three Worldviews: How to Decide Whether to Buy the Pullback or Wait for Falsification
This report is best understood through three worldviews. The first is “bottlenecks extend the cycle”: demand continues to be revised up, supply remains uneven, pricing and earnings expectations keep rising, and pullbacks are buying opportunities. The second is the “cash-flow constraint cycle”: cloud providers and AI labs still want to expand, but 2027F capex, memory costs, and financing costs pressure free cash flow, and hardware orders begin to diverge. The third is the “technology-roadmap revaluation cycle”: after 2028F, validation of EMIB-T, CoPoS, SoIC, CPO, and high-end PCB materials proves less smooth, and the market starts to mark down long-term linear extrapolation.
The base case still leans toward the first scenario, but the second and third cannot be ignored. Nomura repeatedly emphasizes insufficient hyperscaler 2027F FCF, especially after memory costs rise. The contradiction here is not that “AI investment has no return,” but that the buildout pace may run ahead of cash-flow recovery. Cloud providers can continue investing, and the market can continue assigning valuations. But once long-end rates rise, valuations will start asking a sharper question: who ultimately bears the cost of capital for the additional USD590.6 billion of AI server revenue in 2027F?
Technology-roadmap risk is not a distant story either. TPU v9’s EMIB-T tape-out, Rubin Ultra’s actual packaging scheme, whether Feynman uses GPU-on-GPU SoIC, whether CoPoS can be pulled in, whether CPO/NPO matures, and whether M9Q/PTFE materials proceed smoothly will all be answered between the end of 2026 and 2028F. If the answers are favorable, Asian AI hardware will upgrade from “packaging shortage” to “technology-roadmap expansion.” If not, the market will re-discount those long-dated options.
This indicator set can also guide positioning in reverse. If data-center visibility is revised up, CCL gross margins keep expanding, BMC shipments do not decline, and WoS price hikes can be passed through, pullbacks should first be treated as opportunities to add to high-quality bottleneck assets. If capex keeps being revised up but FCF deteriorates, orders are concentrated among financially fragile customers, and component companies show abnormal increases in receivables and inventory, it is time to begin reducing weights in pure high-beta equities. If technology milestones are delayed, long-dated option valuations should be cut back to near-term earnings verification.
X. Mapping the Asian Chain to A-Shares and Portfolio Discipline: Do Not Put All “AI Hardware” in One Basket
Although Nomura’s report covers the Asian semiconductor and server chain, its greater value for A-share investing is that it helps the market redraw mapping boundaries. In A-shares, the areas most often benchmarked are PCB, CCL, server power and cooling, optical modules, connectors, test equipment, and parts of the domestic compute chain. The problem is that Elite Material, TUC, ZDT, ASE, KYEC, and ASPEED in overseas reports cannot be crudely mapped into “all AI hardware companies benefit.” The real task is to identify what type of bottleneck each company is exposed to: material specifications, customer qualification, yield ramp, capacity delivery, or domestic substitution.
PCB and CCL are the areas most likely to generate mapping. Wus Printed Circuit, Victory Giant Technology, Shennan Circuits, Shengyi Technology, Kinwong Electronic, and DSBJ may all be put by the market into the AI PCB or high-end materials framework, but their ways of benefiting are not the same. Wus Printed Circuit and Victory Giant Technology are more likely to be tracked through high-end server boards, switch boards, and overseas AI customer chains. Shengyi Technology is more about materials and CCL capability, where the key is whether high-frequency, high-speed material grades, customer qualification, and gross margin can step up. Shennan Circuits, Kinwong Electronic, and DSBJ must be assessed separately for structural differences across package substrates, automotive electronics, consumer electronics, and server orders. Only by distinguishing order types and product specifications can the A-share mapping avoid becoming mere theme diffusion.
The most important verification indicator for AI PCB is not “whether there are AI orders,” but whether orders pass through three gates. The first is the customer gate: whether the company can enter leading cloud providers, GPU/ASIC platforms, ODMs, and switch supply chains. The second is the specification gate: whether it can handle high layer counts, low loss, high-speed interconnect, HDI, mSAP, and more difficult lamination. The third is the profit gate: whether specification upgrades show up in gross margin, ASP, and yield improvement. If a company only discloses server order growth, without changes in customer tier, product layer count, material grade, and gross margin, it cannot be directly valued as a “bottleneck asset.”
The CCL-materials mapping also needs to be more granular. High-end CCL is not simply about rising prices for copper foil, resin, and glass fabric; it is a material barrier jointly determined by low loss, high reliability, and customer qualification. The overseas report mentions specifications such as M8, M9, HVLP, and PTFE because AI servers and switches are upgrading across board layer counts, signal integrity, power density, and thermal design. For A-share materials companies to truly benefit, they need to prove they are entering high-frequency, high-speed materials, not ordinary server or consumer-electronics materials. From an investment perspective, the biggest risks for materials stocks are “large nominal capacity but little effective capacity” and “apparent price increases eaten up by yield.” Therefore, gross margin, product mix, customer qualification, and inventory turnover matter more than simple capacity-expansion announcements.
The mapping for server systems and power/cooling depends more on customer quality. An AI rack is not an ordinary server with GPUs added. GB/VR racks, TPU pods, Trainium clusters, and future Rubin Ultra platforms all require more complex power, cooling, backplanes, cables, connectors, liquid cooling, and system debugging. If an A-share company only indirectly supplies ordinary structural parts or ordinary server components, its upside will be weaker. Only companies that can enter high-power racks, liquid cooling, board-level interconnect, and core ODM supply chains are closer to the “system-delivery bottlenecks” in Nomura’s report. The risk in this direction is that system-integration value can be large, but profits may be compressed by customers; ultimately, bargaining power and project replicability matter.
Optical modules and optical interconnect are another important mapping, but they cannot be conflated with CoWoS and CCL. The larger AI clusters become, the more important east-west traffic, switch hierarchy, and optical-module speed upgrades become. CPO, NPO, linear drive, and higher-speed SerDes will all become long-term directions. Innolight, Eoptolink, TFC Communication, and Accelink have been repeatedly revalued by the market. The logic is not as simple as “more AI servers mean more optical modules,” but that speed upgrades, customer share, product yield, and supply-chain qualification together raise value per rack. Verification indicators here are shipment speed mix, customer share, gross margin, silicon photonics or CPO progress, not just industry TAM.
The domestic compute chain must be viewed separately and cannot directly apply the TSMC CoWoS model. Demand for data centers and domestic AI chips in China is real, but constraints differ across advanced process, advanced packaging, HBM, EDA, IP, packaging materials, and ecosystem software. Cambricon, Hygon Information, Loongson Technology, and Jingjia Micro face logics around domestic substitution, government and enterprise procurement, compute ecosystems, and supply security. The supply-demand models for overseas TPU, NVIDIA Rubin, and TSMC CoWoS can only provide a framework for “how bottlenecks are priced”; they cannot be directly used to forecast revenue. Domestic compute is better assessed through order landing, software ecosystem, customer repeat purchases, product iteration, and supply-chain self-sufficiency, rather than simply following overseas AI hardware price increases.
In portfolio terms, A-share mapping needs to be divided into three layers. The first is high-conviction assets, focusing on companies that have already entered leading overseas customers or high-end server chains and whose financial performance can be directly verified. The second is high-beta assets, focusing on companies where orders or technology milestones may open up, but customers and profit still need verification. The third is thematic assets, which have only conceptual relevance and lack trackable financial indicators. The first layer can use pullbacks for positioning. The second should be traded around milestones. The third can only be used as a risk-appetite tool; overseas supply-demand gaps in deep research reports should not be used to underwrite it.
This discipline also explains why “AI hardware is not over” and “do not chase AI hardware stocks indiscriminately” can both be true. Demand is very strong and bottlenecks are real, but strong demand does not automatically become profit for every company. The further we move into the second stage, the more important it is to ask four questions: is the company actually selling a bottleneck product; are customers willing to pay a premium for that bottleneck; after capacity expansion, will yield and pricing erode margins; and if the 2028F technology roadmap changes, can the company stay on the new platform? Only companies that can answer these four questions deserve higher valuations.
For tracking cadence, A-share investors should maintain separate tables for the overseas chain and the domestic chain. For the overseas chain, track TSMC’s actual CoWoS output, Google TPU revisions, Rubin/Rubin Ultra racks, EMC and TUC gross margins, ASE FOCoS, and KYEC test time. For the domestic chain, track formal orders, customer qualification, high-end product mix, gross margin, accounts receivable, inventory, and capex efficiency. If the overseas chain remains tight and domestic-chain verification also improves, A-share AI hardware can enjoy mapping diffusion. If the overseas chain remains tight but domestic-company profits do not keep up, investors should beware that it is only thematic premium.
Ultimately, the lesson from Nomura’s report for A-shares is not a command to “buy all hardware,” but a screening framework. What passes through the screen are companies genuinely blocking the process of bringing AI compute capacity online. What gets filtered out are companies merely adjacent to the AI narrative but lacking pricing power and profit verification. If the AI semiconductor cycle continues upward, the second stage will reward more granular research and punish cruder mapping.
XI. Conclusion: AI Semiconductors Are Still Moving Higher, but the Easy-Money Phase Is Over
The value of Nomura’s report is not that it repeats “AI demand is strong,” but that it pushes the AI hardware cycle into a more granular layer: data-center construction is still being revised upward, TSMC is becoming more aggressive on CoW capacity expansion, NVIDIA still captures the largest share, and Google TPU has become the biggest marginal variable. But what truly determines 2027F delivery is WoS, substrates, CCL, PCB, BMC, testing, CPU packaging, thermal management, and cash flow. The cycle is not over; the difficulty has increased.
From an investment perspective, the risk-reward of simply buying AI beta has declined, while the risk-reward of buying bottleneck quality has improved. For platform assets, focus on TSMC and ASE Technology; for high-beta assets, MediaTek, ASPEED, and ZDT; for materials bottlenecks, EMC/Elite Material; for testing, King Yuan Electronics; and for longer-dated options, GlobalWafers, BESI, Soitec, and the CPO/SoIC supply chain. China-related mappings need to be grounded in official security names and real certification progress; overseas materials suppliers, Taiwan PCB names, and A-share PCB names should not be blended into one vague sector bucket.
The real risk to watch is not that AI demand suddenly disappears, but that the market treats every bottleneck as the same kind of certainty. Tight 2027F supply does not mean every company can raise prices; upward revisions to Google TPU do not mean every ASIC can secure resources; CoWoS capacity expansion does not mean WoS and small components are no longer in shortage; and upward revisions to server revenue do not mean cloud providers face no cash-flow pressure. The next phase of alpha will belong to investors who can verify these differences item by item.
After this AI semiconductor rally entered its second stage, the best question is no longer “who is most like NVIDIA,” but “without whom can expensive compute not come online?” That question shifts attention away from large chips and toward a set of smaller, narrower, harder-to-replace links. As long as data-center construction keeps advancing, these small links will continue to have pricing power; once construction slows, cash flow tightens, or technology roadmaps are delayed, they will also be the first to reveal valuation elasticity. AI is not over, but it no longer rewards crude optimism.