
AI Supply Chain Deep Dive: 2027 CoWoS Allocations, ASIC Pull-Ins, and Capacity Reallocation in Optical Interconnects
目录
TL;DR
1. This Update Moves the Trade From “Overall Tightness” to “Allocation Ranking”
2. AMD’s 240k Allocation Has Not Been Revised Up; the Real Incremental Signals Are MI450, MI455, and Venice CPU
III. TPU Is Not Canceled; Revenue Recognition Is More Skewed to 4Q and 2027
IV. Blackwell Inventory Is Reinterpreted, While Rubin Rack Volumes Continue to Support the Systems Chain
V. Changes in Meta ASICs Show In-House Chips Are Entering the Engineering Screening Phase
VI. OSAT and Testing Are Not Supporting Roles; They Start Benefiting from CoW Spillover in 2027
VII. Optical Interconnect Remains Long-Term Beta, but It Must Be Viewed Within ASICs and Rack Systems
8. Supply-Chain Ranking: TSMC and HBM Are the Base; ASIC/OSAT/Substrates Are the Slope
9. The Profit Pool Is Shifting from “Single-Chip Points” to “Full-Rack Delivery Bills”
10. Data Definitions: CoWoS, HBM, Wafer Revenue, and Rack Volume Are Not Interchangeable
XI. The Most Important Risk Is Not Demand Disappearing, but a Mismatch Between Capacity Allocation and Timing
XII. The Numbers to Watch Over the Next Four Quarters
XIII. Conclusion: What Matters in 2027 Is Not “AI Is Still There,” but Who Is at the Front of the Queue
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
The central tension in the 2027 AI supply chain is shifting from “whether TSMC has enough capacity” to “who actually gets the allocation.” Morgan Stanley puts AMD, Google TPU, Rubin, Meta ASIC, and OSAT spillover on the same ledger. The allocation order will also determine whether second-tier supply chains can move from thematic mapping to revenue realization.
TL;DR
Advanced packaging has entered the allocation-ranking phase. Morgan Stanley measures global demand next year at close to doubling, while year-end supply also continues to expand. Overall tightness is no longer new information. The new signal is that second-tier customers outside Nvidia are competing for allocations at the same time, and supply-chain optionality is spreading from a single accelerator-card chain to custom chips, assembly and test, testing, substrates, and optical interconnects.
AMD’s allocation has not been revised upward. Morgan Stanley still puts AMD’s 2027 TSMC-side CoWoS at around 240k wafers. The new focus is not a sudden increase in allocation, but how the MI series, Meta’s custom version, Venice CPU, and OSAT CoW each translate into execution.
TPU timing has moved later, but orders have not disappeared. Sunfish is more likely to be confirmed in 4Q26, and King Yuan Electronics’ near-term revenue slope is below prior expectations. Zebrafish ramp timing is unchanged. Google TPU remains a core source of incremental demand for Broadcom, MediaTek, King Yuan Electronics, HBM, and substrates.
Blackwell inventory concerns have been reframed. Morgan Stanley argues that Blackwell chip “inventory” is essentially supply-chain buffer stock and will be consumed in 2026. In 2027, Rubin/Rubin Ultra approaches 7 million chips, and Rubin NVL72 is around 90k racks. This view supports the Nvidia chain continuing to consume the largest allocation and also explains why HBM, ABF, PCB, liquid cooling, and optical interconnects still cannot be de-rated like ordinary cyclical products.
ASIC is moving from thematic trading to production-schedule trading. Broadcom remains the largest platform, but MediaTek, Global Unichip, and Marvell Technology have also entered the production-schedule ledger. After Meta canceled Olympus, Apollo takes over; Global Unichip may win projects from the Rivos team. Going forward, ASIC analysis cannot stop at customer stories. Tape-out, CoWoS out, HBM, OSAT, and testing schedules must line up.
Investment ranking should be layered by “allocation, spillover, and falsification.” The first layer remains TSMC, HBM, and the main CoWoS chain. The second layer is OSAT CoW, King Yuan Electronics testing, ABF/T-glass, and high-end PCB. The third layer is the optionality in Marvell Technology, Global Unichip, Alchip, optical interconnects, and CPO. The most important falsification signals are AMD cutting reservations again, TPU delays continuing, Rubin rack volume falling below 90k, non-TSMC CoW yield proving insufficient, or HBM4/ABF prices peaking first.
1. This Update Moves the Trade From “Overall Tightness” to “Allocation Ranking”
The AI supply chain no longer lacks a volume narrative. Over the past few months, the market has repeatedly discussed TSMC CoWoS, HBM4, ABF, AI PCB, liquid cooling, and CPO. They all point to the same underlying issue: AI compute delivery increasingly looks like a full-rack system bill. If any critical link cannot get a slot in the queue, expensive GPUs and ASICs turn into inventory rather than revenue.
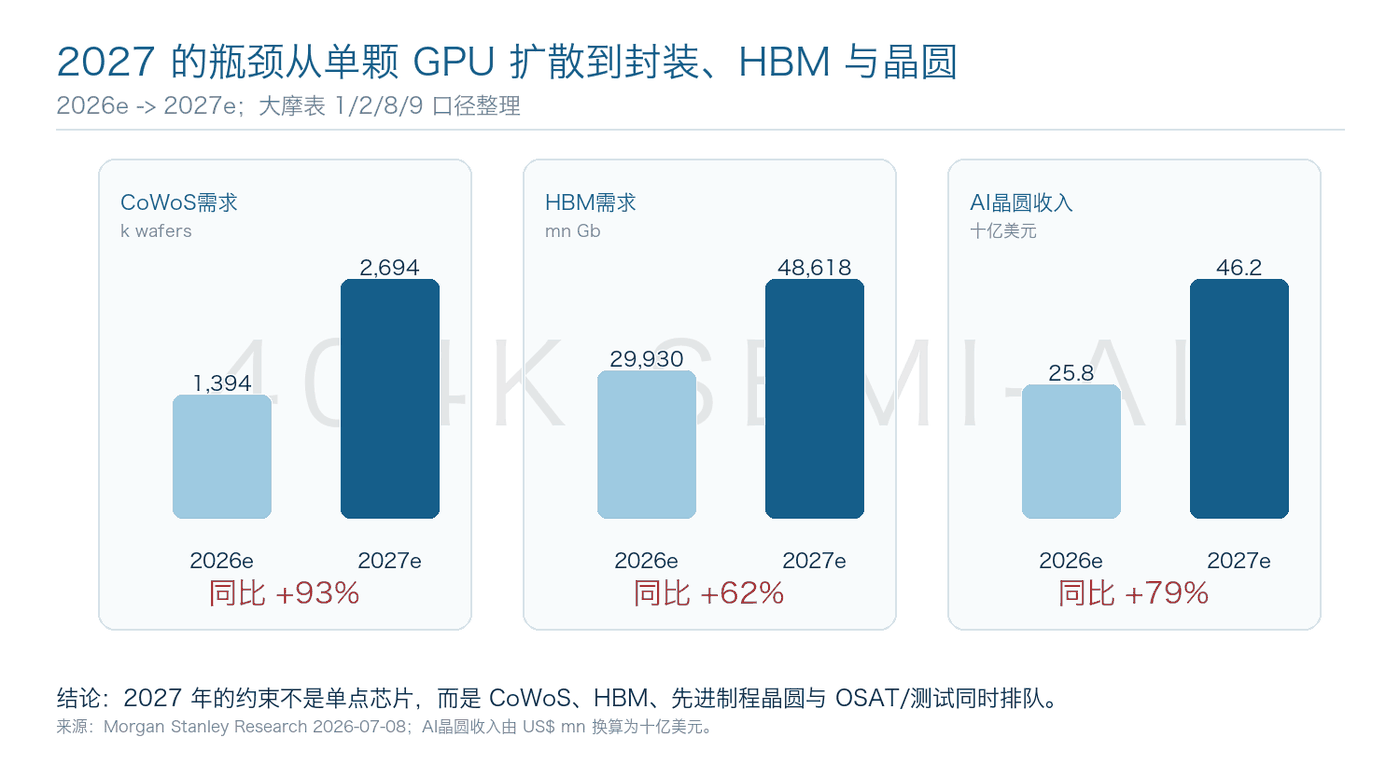
The value of this Morgan Stanley update is that it does not simply repeat that “CoWoS is tight.” Instead, it breaks 2027 demand down by customer, product, and packaging method. Morgan Stanley estimates global CoWoS demand in 2027 at about 2,694k wafers, up roughly 93% from 2026.
In the same table, 2027 HBM demand reaches about 48,618 mn Gb. AI advanced-node wafer revenue is about US$46.2 billion. The total is already large enough. The real question becomes who gets the allocation in this table.
This shift will change investment ranking. In 2025-2026, the strongest trade line was Nvidia and TSMC, with a simple logic: whoever controls general-purpose GPUs and advanced packaging controls compute supply. But after 2027, cloud-vendor self-developed ASICs, AMD as a second supplier, Rubin CPU/GPU combinations, OSAT CoW spillover, and optical-interconnect architectures all enter the production schedule at the same time. The supply chain starts moving from a “single leader bottleneck” to a “multi-customer queue bottleneck.”
TSMC CoWoS Deep Dive: 200kwpm Packaging, US$75bn CapEx, and Reallocation Across CPU, GPU, ASIC, and Optical Interconnects
If 2027 CoWoS allocation is split by customer, the most striking point is not that Nvidia remains first, but the slope of the second tier. Nvidia rises from 780k to 1,222k and remains the largest consumer. Broadcom rises from 300k to 484k. AMD rises from 130k to 530k. MediaTek rises from 40k to 180k. Global Unichip rises from 14k to 60k. Marvell Technology rises from 17k to 64k. The fastest-growing lines are precisely the ASIC and design-service chains that the market previously preferred to treat as “optionality mapping.”
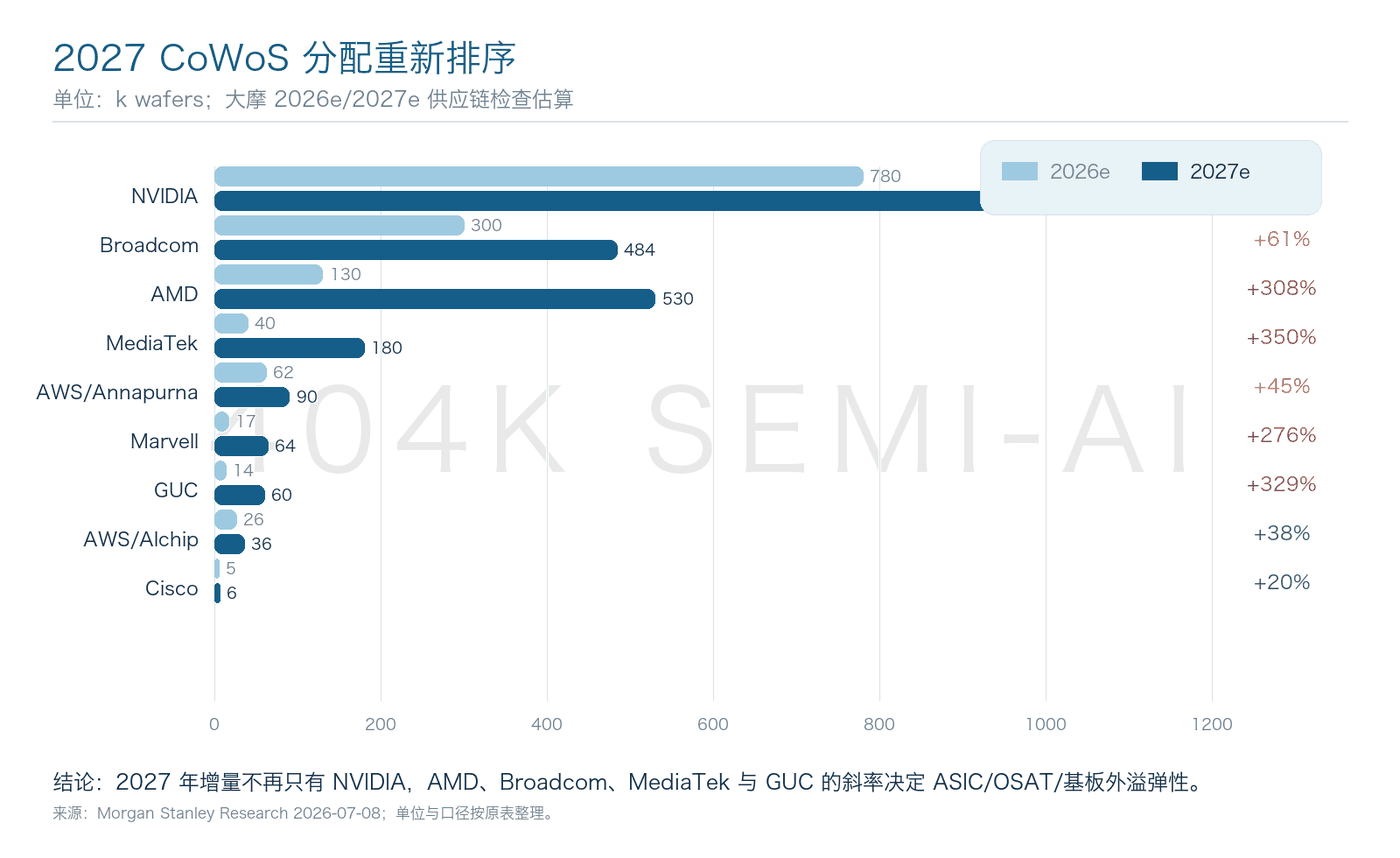
This does not mean the Nvidia chain is over. Quite the opposite: Nvidia still consumes about 45% of 2027 CoWoS demand. Rubin/Rubin Ultra volume, HBM4, and NVL72 rack volume determine the overall AI hardware ledger. But the marginal trade will become more complex: Nvidia is the base; AMD/Broadcom/MediaTek/Global Unichip/Marvell Technology are the slope; OSAT, testing, ABF, PCB, and optical interconnects are the spillover.
2. AMD’s 240k Allocation Has Not Been Revised Up; the Real Incremental Signals Are MI450, MI455, and Venice CPU
Morgan Stanley’s AMD update is restrained. The question investors care about most is whether AMD’s 2027 CoWoS allocation will be revised up meaningfully. Morgan Stanley’s answer is: it remains 240k for now, and execution risk cannot be ruled out.
We still expect AMD's 2027 CoWoS at 240k. We estimate chip shipments in 2027 will be 1mn for MI455 and 500k for MI450. For CPU, Venice is AMD's first CPU to adopt CoWoS.
These three sentences are important. If the market only hears “AMD’s 2027 MI455/MI450 shipments total 1.5 million chips,” it can easily infer a major upward revision to AMD’s allocation. But Morgan Stanley separates chip versions, packaging sources, and execution risk.
MI455 is the standard version, with 2 compute dies and 12 HBM4 12hi stacks, corresponding to Helios rack. Customers include Microsoft, AWS, and Oracle. MI450 is Meta’s custom half-size version, with 1 compute die and 6 HBM4 12hi stacks, corresponding to 9 CPUs and 36 GPUs. Combined shipments look sizable, but TSMC-side CoWoS remains only 240k, meaning part of production, packaging, and CoW spillover must be assessed separately through OSAT.
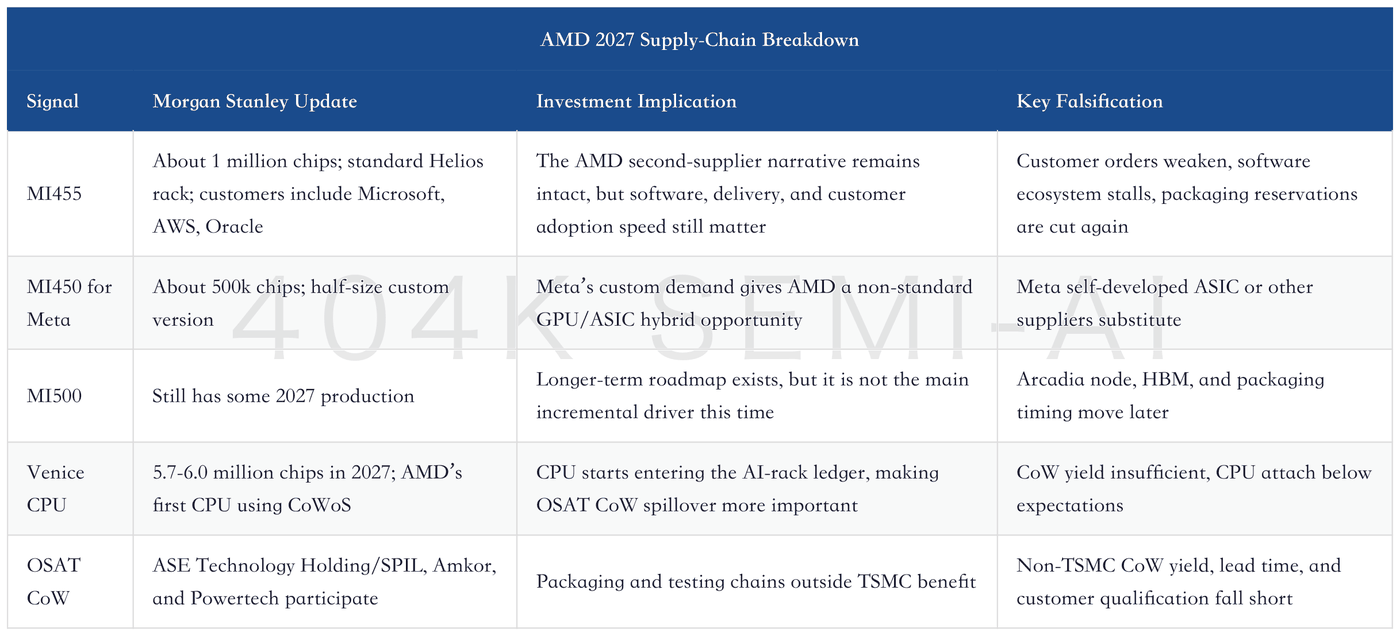
This affects how AMD’s valuation should be explained. AMD remains the most important GPU second supplier outside Nvidia, but the 2027 trade cannot rely solely on “allocation revision.” A sturdier formulation is: MI455/MI450 validate cloud vendors’ willingness to use a second supplier; Venice CPU validates that AI racks are starting to include CPUs in the advanced-packaging bill; OSAT CoW validates whether packaging spillover is real.
AMD’s risk is also more direct than Nvidia’s. Morgan Stanley notes that AMD previously trimmed CoWoS reservations in 2026. If there is another cut in the future, the market will treat the 2027 total demand of 530k as “customer interest” rather than an “executable production schedule.” Therefore, the four numbers to watch most closely in the AMD chain are MI455 customer adoption, MI450 Meta custom shipments, Venice CPU attach, and CoW yield at ASE Technology Holding/SPIL/Amkor/Powertech.
III. TPU Is Not Canceled; Revenue Recognition Is More Skewed to 4Q and 2027
The Google TPU clues in this report have also been modestly adjusted. KYEC’s 3Q26 revenue may be close to 10% QoQ growth, below Morgan Stanley’s prior expectation of around 15%, due to factors including slight delays in Rubin and Sunfish, as well as trimmed MediaTek smartphone SoC orders. This change will push some test, packaging, and supply-chain revenue from 3Q26 into 4Q26 or 1Q27.
We do see Sunfish shipments largely in 4Q, with full-year volume at 960k units. With Sunfish and Rubin pushed out, we believe more revenue will concentrate in 4Q26 or 1Q27. Many investors asked about Zebrafish delays; we still see its 4Q26 volume ramp unchanged.
The investment implication here is that “timing pushed out” should not be directly written as “orders canceled.”
Sunfish’s full-year 2026 volume is around 960k units, with more concentrated in 4Q.
Zebrafish’s 4Q26 production ramp is unchanged. This creates near-term pressure on quarterly revenue recognition for KYEC, packaging, substrates, and some suppliers, but in 2027 TPU remains a core incremental driver for Broadcom, MediaTek, HBM, and CoWoS.
Morgan Stanley’s table shows a very large Google TPU scale in 2027: TPU v8i Sunfish corresponds to 330k CoWoS wafers and 3.96 million chips; TPU v8t Zebrafish corresponds to 180k CoWoS wafers and 3.6 million chips; TPU v9 Humufish has another 400k chips estimated. In other words, Google TPU remains one of the largest customers on the ASIC side; the recognition cadence is simply shifting from 3Q26 toward 4Q26/1Q27.
Broadcom, MediaTek, and HBM Re-rating: Google TPU Shipments Revised Up to 35 Million Units
The TPU line should be broken into five links, rather than focusing only on Broadcom or MediaTek.
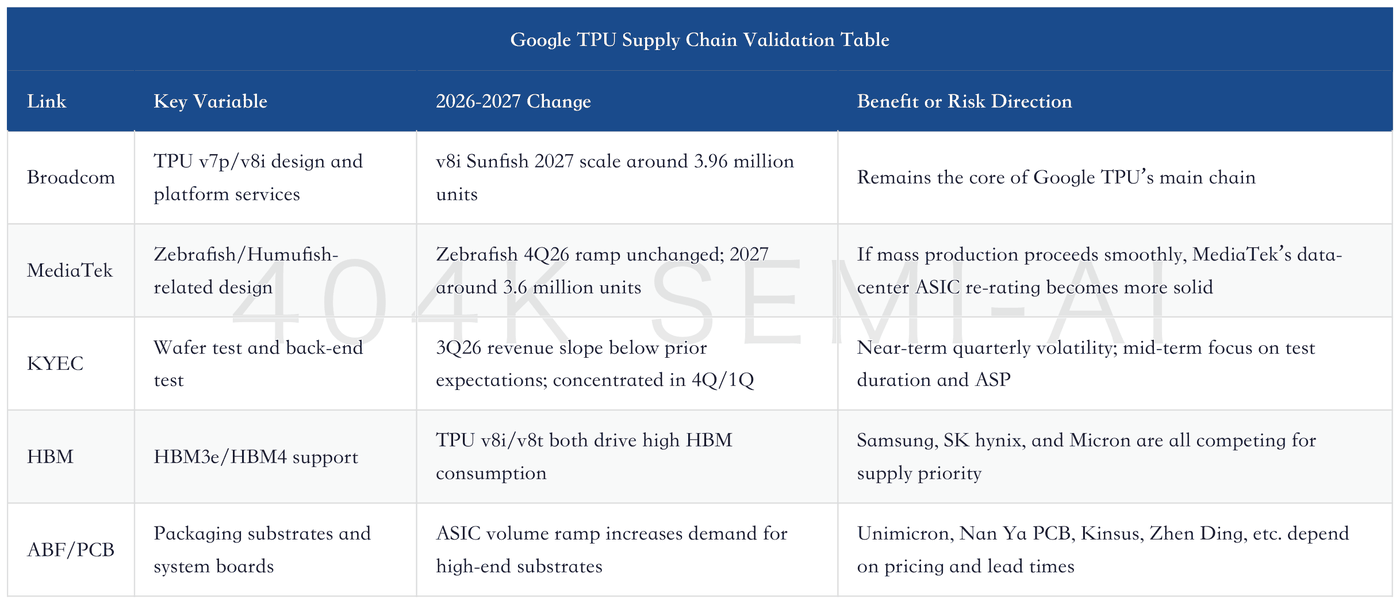
The most common mistake on this line is interpreting a TPU production delay as a fading ASIC trade. The real question is whether Google remains willing to keep expanding TPU deployments, and whether Broadcom/MediaTek’s generational designs tape out, enter mass production, and get scheduled on cadence. If Sunfish and Zebrafish are only delayed by one quarter, the supply chain is merely seeing revenue recognition pushed out; only if successive generations are repeatedly delayed would ASIC valuations need to be clearly marked down.
IV. Blackwell Inventory Is Reinterpreted, While Rubin Rack Volumes Continue to Support the Systems Chain
Morgan Stanley’s update on the NVIDIA chain mainly reinterprets Blackwell chip “inventory” as supply-chain buffer, and puts 2027 Rubin/Rubin Ultra and NVL72 rack volumes into the same model.
Morgan Stanley expects around 5.4 million Blackwell chips in 2026. Chip supply in 2H26 can match Grace Blackwell NVL72 demand; in 2027, Rubin/Rubin Ultra is close to 7 million chips, with around 90k Rubin NVL72 racks.
All Blackwell chip "inventory" turned out to be a supply-chain buffer and will be fully consumed by 2026. We think Rubin will follow a similar pattern. Rubin will start ramping in 3Q26, with rack shipments starting in 4Q26.
This should ease market concern about “Blackwell inventory build.” AI racks are not consumer electronics inventory. Chips, boards, HBM, NVSwitch, networking, liquid cooling, and full-system delivery naturally arrive on different timelines. Chips arriving first in a given quarter does not necessarily mean end demand is weakening; it may also be supply-chain buffering to support the subsequent full-rack ramp.
NVIDIA Roadshow Deep Dive: GB300 Tokens per Watt, ACIE as Half of Revenue, and $1 Trillion Blackwell and Rubin Visibility
This also explains why the Rubin chain cannot be assessed only by looking at GPUs. Rubin/Rubin Ultra at close to 7 million chips corresponds not only to NVIDIA chip revenue, but also to demand pull for HBM4, ABF, M9/M9+ PCB, rack-level power, liquid cooling, optical interconnect, test equipment, and ODM delivery. The previous AI trade focused on whether GPUs could ship; the next round will focus on whether GPUs can come online as full rack systems.
Vera Rubin 1GW Cost Ledger: How a $47 Billion AI Factory Reorders Value Across GPUs, Memory, Networking, Power, and Substrates
Rubin has three layers of supply-chain implications.
The first layer is TSMC and HBM. In Morgan Stanley’s 2027 table, Rubin R200 corresponds to 740k CoWoS wafers and around 5.92 million chips. Rubin Ultra corresponds to 130k CoWoS wafers and around 1.04 million chips.
Together, the two imply HBM demand of around 2.1 million kGB, with HBM4/HBM4e as the key. As long as Rubin scheduling remains unchanged, tightness in HBM and CoWoS is unlikely to ease quickly.
The second layer is rack systems. Around 90k NVL72 racks means value is not only in chips. PCB, ABF, connectors, power, liquid cooling, ODMs, testing, and networking all need to be reorganized around rack-level delivery. Explaining the trade previously by “GPU count” is no longer enough; it now requires a combined judgment across “rack volume + chips + HBM + packaging + online cadence.”
The third layer is supply-chain buffering. Blackwell has already shown that chips arriving first does not equal inventory risk, and Rubin is likely to follow a similar cadence. Investors need to distinguish between two types of inventory: passive inventory caused by demand falling short of expectations, and active buffer prepared for full-rack delivery. The two have completely different valuation implications.
V. Changes in Meta ASICs Show In-House Chips Are Entering the Engineering Screening Phase
The Meta signal is interesting. Morgan Stanley wrote that Meta canceled its original 2nm ASIC, Olympus, earlier this year. The new 2nm chip, Apollo, has taken over, with Broadcom continuing to provide design services and mass production pointing to 1Q28. At the same time, Global Unichip may have won an ASIC project led by Meta’s Rivos team, potentially a side project outside the regular MTIA line, targeting tape-out in 1H27 and CoWoS out by late 2027 or 1H28.
This update shows two things.
First, cloud vendors’ in-house ASIC programs do not move forward in a straight line. Project cancellations, renaming, architecture changes, service-provider changes, and team changes are all normal. The truly valuable signal is not that “a cloud vendor wants to build an ASIC,” but whether it has entered tape-out, secured CoWoS out, formed a multi-generation product roadmap, and is being consistently supported by a design-service provider.
Second, the ASIC ecosystem is not just Broadcom. Broadcom remains the strongest platform-level supplier, but Global Unichip, Alchip, Marvell Technology, and MediaTek will all win positions across different customers, generations, and modules. In Morgan Stanley’s 2027 CoWoS table, Global Unichip demand rises from 14k to 60k, Marvell Technology from 17k to 64k, and Alchip-related AWS projects from 26k to 36k. These are not the largest absolute volumes, but they are high-beta denominators.
Broadcom Earnings Deep Dive: AI ASIC Ramp, Expanding AI Networking Demand, and the High-Margin “Picks-and-Shovels” Supplier Behind Cloud Vendors
The correct sequence for trading ASICs should be: first look at the customer’s real workload, then the chip generation, then the design-service provider, then CoWoS/HBM/ABF scheduling, and only finally the liquid high-beta names in the secondary market. Jumping directly from “Meta/Google/AWS wants to build ASICs” to “a certain company deserves a valuation re-rating” skips a lot of engineering risk.
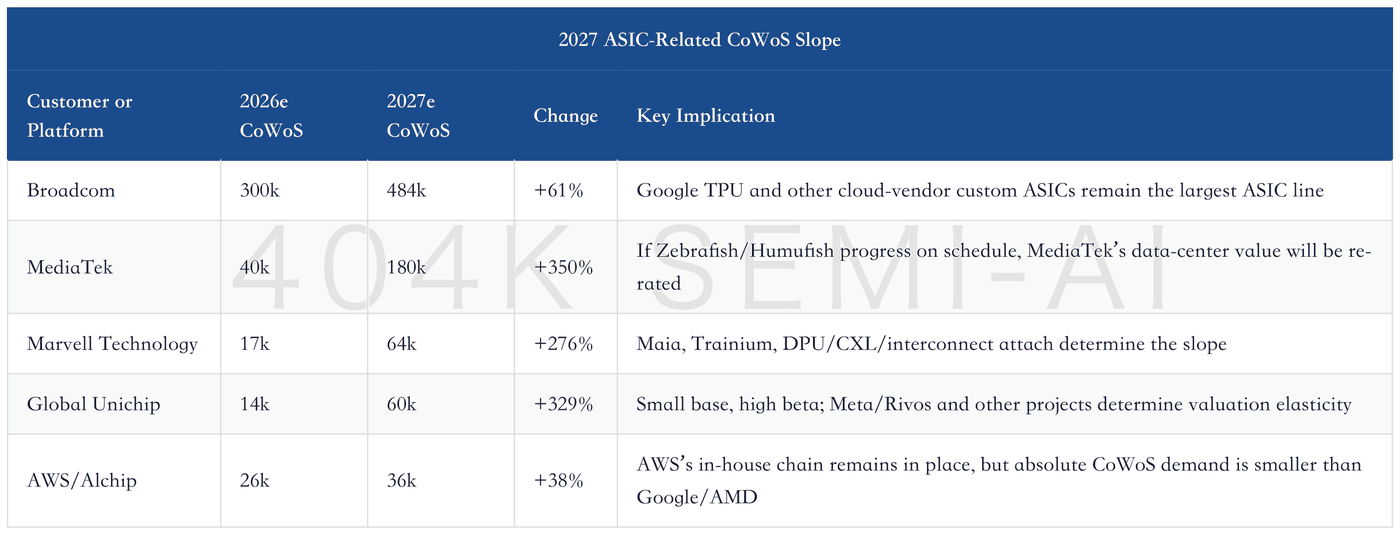
This table also shows that ASIC is not a single-track market. Broadcom is a platform; MediaTek is design-outsourcing beta tied to Google TPU; Marvell Technology is more tilted toward interconnect and selected custom silicon; Global Unichip and Alchip offer project-based beta. Their valuation frameworks cannot be mixed. Platform companies should be valued on customer count, generations, networking value, and cash flow; project-based companies should be valued on tape-out, CoWoS out, gross margin, and customer-concentration risk.
VI. OSAT and Testing Are Not Supporting Roles; They Start Benefiting from CoW Spillover in 2027
When discussing CoWoS in the past, it was easy to assign all the value to TSMC. TSMC remains the main chain, but Morgan Stanley’s table explicitly incorporates non-TSMC supply into the 2027 framework. On year-end supply, TSMC rises from about 120kwpm in 2026 to about 200kwpm in 2027, while non-TSMC supply rises from about 50kwpm to about 80kwpm. On the demand side, AMD CPUs, some GPUs/ASICs, and CoW spillover will bring OSATs such as ASE Technology/SPIL, Amkor, and Powertech Technology to the foreground.
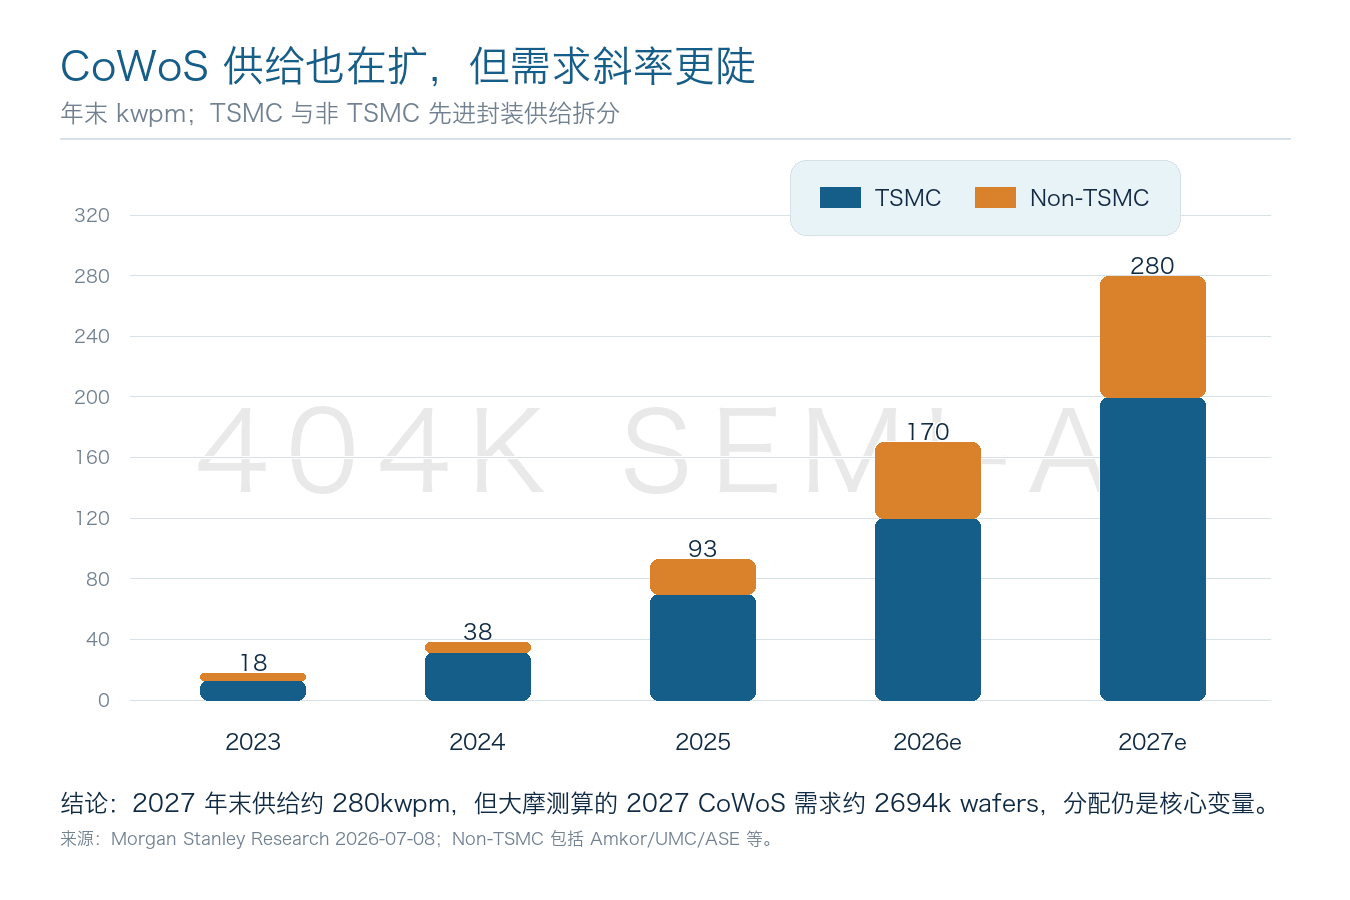
The key to the OSAT line is not replacing TSMC, but absorbing spillover from outside the TSMC system. Advanced-packaging demand for AI accelerators and CPUs is too large to keep entirely inside TSMC. As long as customers are willing to outsource part of CoW, CoWoS-S/R, or related back-end processes, OSAT value will shift from the traditional packaging-and-testing cycle to AI advanced-packaging beta.
Testing follows the same logic. King Yuan Electronics’ 3Q26 revenue slope was below expectations in the short term, but the reason was that some Rubin, Sunfish, and smartphone SoC schedules moved out, not that AI testing demand disappeared. AI chips have large die sizes, complex HBM, and more difficult packaging and system-level validation, so test time and test ASP will continue to rise. The real question is whether customer scheduling has merely shifted by a quarter or whether product generations are seeing systemic delays.
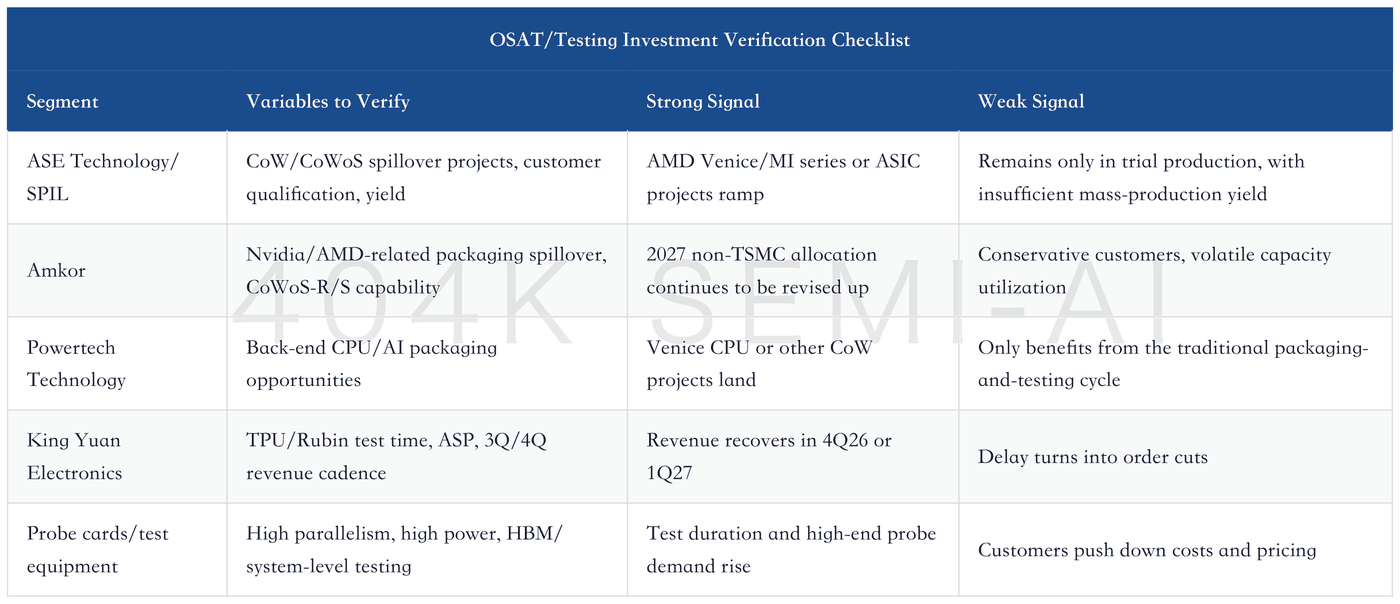
This layer of the supply chain has one characteristic: the absolute profit pool is smaller than TSMC and HBM, but stock-price beta may be higher. The reason is not that they are more important, but that the market previously assigned them a lower AI weighting. As long as CoW spillover and longer test times are validated by orders, valuations will move from the traditional packaging-and-testing cycle toward advanced-packaging infrastructure.
VII. Optical Interconnect Remains Long-Term Beta, but It Must Be Viewed Within ASICs and Rack Systems
This report’s title does not put CPO at the very front, but optical interconnect cannot be omitted. The reason is simple: after CoWoS, HBM, ASIC, and Rubin rack volumes rise, the cost of moving data among chips, boards, switching systems, and racks will continue to increase. Optical interconnect is not a standalone theme; it is the networking and power-consumption problem that inevitably emerges after AI racks scale.
AI Hardware Deep Update: How PCB, CPO, and MLCC Become the Three Physical Gates for Rubin Racks
Optical interconnect has three layers in this main thread.
The first layer is traditional optical modules and 1.6T/3.2T. Rubin, TPU, and AI ASICs will continue to drive scale-out network traffic higher, supporting demand for optical modules, DSPs, EML, silicon photonics, FAU, connectors, and high-speed PCBs. As long as cluster scale keeps rising, total optical-interconnect demand is unlikely to peak suddenly.
The second layer is NPO/CPO. The CPO timeline may fluctuate, but the architectural direction is unchanged. The higher the power, density, and latency requirements of AI switching systems, the closer optical capability needs to move toward the switch ASIC. The truly valuable companies are those that can understand switch chips, optical engines, silicon photonics, WDM, TGV glass, and test yield at the same time, not those that merely attach a CPO label.
The third layer is ASIC networking. This is where Broadcom and Marvell Technology differ. Broadcom can link custom ASICs, Ethernet switching, SerDes, and infrastructure software; Marvell Technology is more tilted toward optical interconnect, DSP, DPU, CXL, and selected custom silicon attach. Morgan Stanley’s CoWoS table raises Marvell Technology from 17k to 64k, showing that the combination of interconnect and custom silicon is entering larger production schedules.
The Next Trillion-Dollar Company in Jensen Huang’s View | Marvell Deep Dive: From Data-Movement Chips to an AI Interconnect Platform, and How CPO, Switching, and Custom Silicon Re-Rate Marvell Technology
The risks in optical interconnect also need to be made clear. If CPO/NPO is delayed, that does not mean optical-interconnect demand disappears, but it will affect the valuation structure: in the short term, traditional pluggable modules, DSPs, and high-speed PCBs continue to benefit; over the medium to long term, CPO optical engines, silicon photonics, and system-level testing benefit. In portfolio construction, not all optical-interconnect companies can be priced on the same timetable.
8. Supply-Chain Ranking: TSMC and HBM Are the Base; ASIC/OSAT/Substrates Are the Slope
This report ultimately has to come back to investment ranking. The 2027 AI supply chain cannot simply be split into a “GPU chain” and an “ASIC chain.” A more reasonable framework is: base, slope, and options.
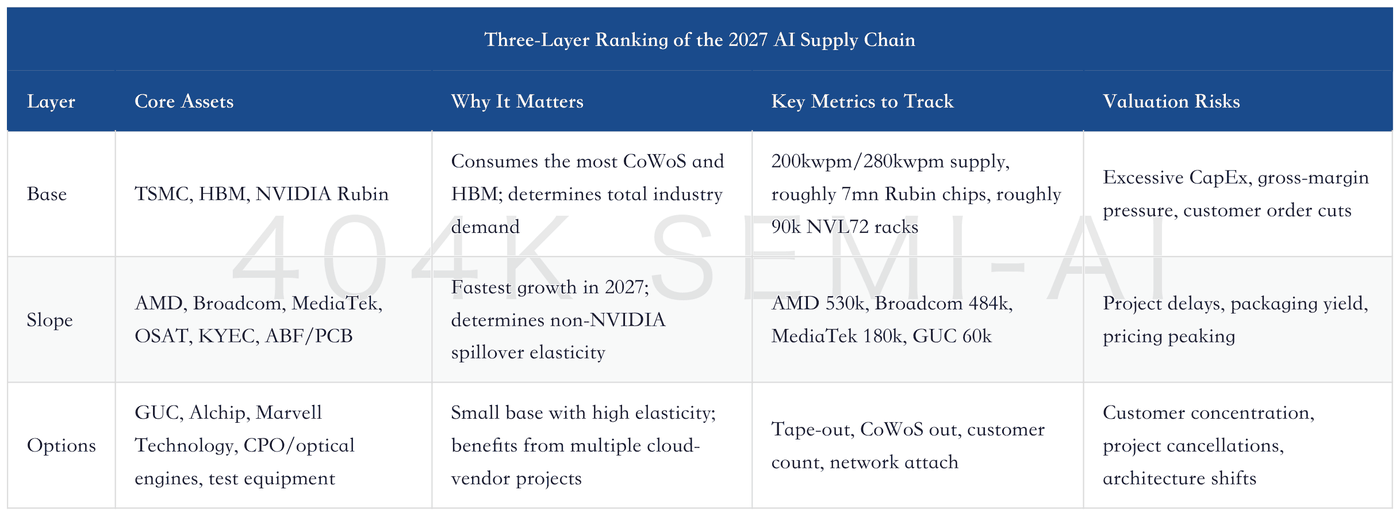
TSMC and HBM are the hardest base. Their advantage is high certainty; their drawback is that valuation is already more fully priced. In 2027, CoWoS demand is expected to be roughly 2,694k wafers, while HBM demand is roughly 48,618mn Gb. As long as this framework is not overturned, TSMC, SK Hynix, Samsung, Micron, and key equipment and materials suppliers remain the main line of AI hardware.
AMD, Broadcom, MediaTek, and OSAT are the slope. AMD’s issue is execution; Broadcom’s issues are customers and gross margin; MediaTek’s issue is whether TPU generations can materialize on schedule; OSAT’s issues are yield and customer qualification. Their elasticity comes from the fact that the market has not fully capitalized their 2027 allocations.
GUC, Alchip, Marvell Technology, and CPO are options. This does not mean they lack value, but their validation paths are narrower and more easily disrupted by a single customer or project. For these companies, the most important question is not whether “industry demand is large,” but whether specific projects enter tape-out, CoWoS out, mass production, and revenue recognition.
9. The Profit Pool Is Shifting from “Single-Chip Points” to “Full-Rack Delivery Bills”
What is truly worth revisiting in this report is that it places CoWoS, HBM, and advanced-node wafer revenue into the same model. In the past, the market liked to break AI hardware into single points: GPU ASP, HBM capacity, packaging capacity, PCB layer count, and optical-module speed. Single-point narratives can capture share-price elasticity, but they can also misread the cycle. As AI servers move from boards to full racks, supply-chain revenue recognition becomes a long bill: chips are scheduled first, HBM supply is locked first, packaging capacity is reserved first, test time lengthens first, racks are then delivered, and only at the end does usable compute appear in cloud-vendor CapEx.
