
AI Supernode Deep Dive Update: 1,024 Accelerators, PCIe 6.x, and the Incremental Value of Cross-Rack Optical Interconnects
目录
TL;DR
I. The Core of This Update: Supernodes Shift from a Global Architecture Question to a Domestic Execution Question
II. From 64 to 1,024 Accelerators: The Scale Ceiling Has Risen, but Maturity Still Varies
III. 3.6 TB/s Does Not Necessarily Mean Faster: Bandwidth Comparisons Must Return to Applications
IV. Redrawing the Electrical-Optical Boundary: Cross-Rack in the Near Term, Near-Package in the Long Term
V. Montage Technology: A Relatively Short Chain, but It Must Progress from Interoperability to Mass Production
VI. Hygon Information Technology, Cambricon, and Iluvatar CoreX: Upside Comes from Systems, Not Just Chips
VII. Valuations Already Price In High Growth; Operating Evidence Must Keep Pace
VIII. What to Watch Over the Next Four Quarters: Six Evidence Sets to Validate or Falsify the Thesis
Conclusion: Near-Term Certainty in PCIe, Long-Term Upside in Optics, and the Ultimate Contest at the System Level
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
Morgan Stanley’s new report advances the question from “Will networks become optical?” to “Can 64 to 1,024 accelerators truly deliver effective compute?” The answer depends on PCIe content, cross-rack optical connectivity, and system-level execution.
TL;DR
Competition in domestic AI infrastructure is shifting from individual chips to complete systems. Scale-up domains showcased or announced at the 2026 World Artificial Intelligence Conference span 64 to 1,024 accelerators, while Huawei’s Atlas 950 is designed to scale to 8,192 NPUs. The upper bounds are striking, but effective compute is ultimately determined by parallel efficiency, utilization, availability, and software coordination.
Scale-up and scale-out networks will not replace each other. The former handles tightly coupled communications within a supernode, while the latter connects multiple supernodes. The mainstream architecture will remain a dedicated scale-up interconnect layered over an Ethernet or InfiniBand backbone, with incremental value arising from simultaneous upgrades across both network tiers.
The boundary between electrical and optical connectivity is moving closer to the inside of the rack, but the transition will not happen overnight. Within a single rack, short-reach electrical connectivity retains advantages in cost, maintenance, and maturity. Beyond the rack, signal loss, power consumption, and cabling density increase the relative value of optical connectivity. Near-packaged optics (NPO) system prototypes already exist, but volume revenue still requires validation through design wins, reliability, and repeat orders.
Montage Technology has one of the shortest paths to benefiting among the names covered in the report. As supernodes expand, the number, speed, and reach of PCIe links among CPUs, GPUs, switch chips, network interface cards, and peripherals all increase, supporting higher content for PCIe retimers, PCIe switch chips, and active electrical cables. However, completing interoperability testing does not mean volume-production revenue has already materialized.
Hygon Information Technology, Sugon, Cambricon, and Iluvatar CoreX offer greater upside sensitivity but are also more dependent on full-system validation. Running a model on a chip is only the starting point. Whether more than 64 accelerators can scale reliably, collective-communications efficiency can be maintained, advanced-node capacity can keep pace, and customers place repeat orders will determine whether valuations progress from technology expectations to earnings delivery.
The metrics that truly warrant monitoring are actual delivery volumes, communications efficiency after scaling, the number of cross-rack optical ports, PCIe 6.x/CXL 3.x volume-production progress, repeat orders, and cost per Token. Until these operating indicators emerge in parallel, architecture demonstrations should be separated from revenue forecasts.
I. The Core of This Update: Supernodes Shift from a Global Architecture Question to a Domestic Execution Question
The July 13 report, AI Scale-Up Networking Deep Dive: Morgan Stanley Raises Forecasts Again—1,152 GPUs, 6-Meter Copper Interconnects, and Co-Packaged Optics in 2029, discussed three long-term themes in global scale-up networking: rapid growth in the scale-up market, continued extension of copper connectivity’s effective reach, and the potential for co-packaged optics (CPO) to enter systems progressively at higher bandwidth densities. Morgan Stanley’s new July 27 report does not overturn these conclusions. Instead, it adds a more critical piece of the puzzle—how domestic vendors can actually integrate scale-up architectures into supernodes.
The incremental takeaways can be summarized in three shifts.
First, vendors are moving their focus from “building another chip” to “organizing dozens to more than 1,000 accelerators into a single compute domain.” Marginal improvements in process technology, memory bandwidth, and die area are becoming increasingly expensive, leaving systems engineering to amplify compute performance.
Second, the dimensions of competition are expanding beyond interface specifications to topology, collective communications, memory semantics, fault isolation, cooling and power delivery, and software scheduling. Nominal bandwidth is only the architectural ceiling; only bandwidth that applications can use consistently translates into training or inference throughput.
Third, industry value is spreading from individual GPUs to interconnects and complete systems. PCIe retimers, switch chips, active electrical cables, NPO, silicon-photonics engines, and dynamic optical switching are gaining incremental content. Chip and server vendors, meanwhile, must demonstrate system delivery and operating economics.
This shift can be understood through a simplified relationship:
Effective compute ≈ peak compute × parallel efficiency × system utilization × operating availability
This is an operating checklist, not a financial forecasting formula. If a supernode’s peak compute doubles but communications waits reduce parallel efficiency, or faults and software adaptation issues depress utilization, the compute actually available to customers will not double in tandem. The core value of a supernode lies in minimizing the time chips spend waiting for one another.
II. From 64 to 1,024 Accelerators: The Scale Ceiling Has Risen, but Maturity Still Varies
Morgan Stanley placed the principal solutions presented at the 2026 World Artificial Intelligence Conference into a single architectural map. The most striking common feature is that scale-up domains generally contain at least 64 accelerators, while some next-generation solutions target 512, 640, or even 1,024 accelerators.
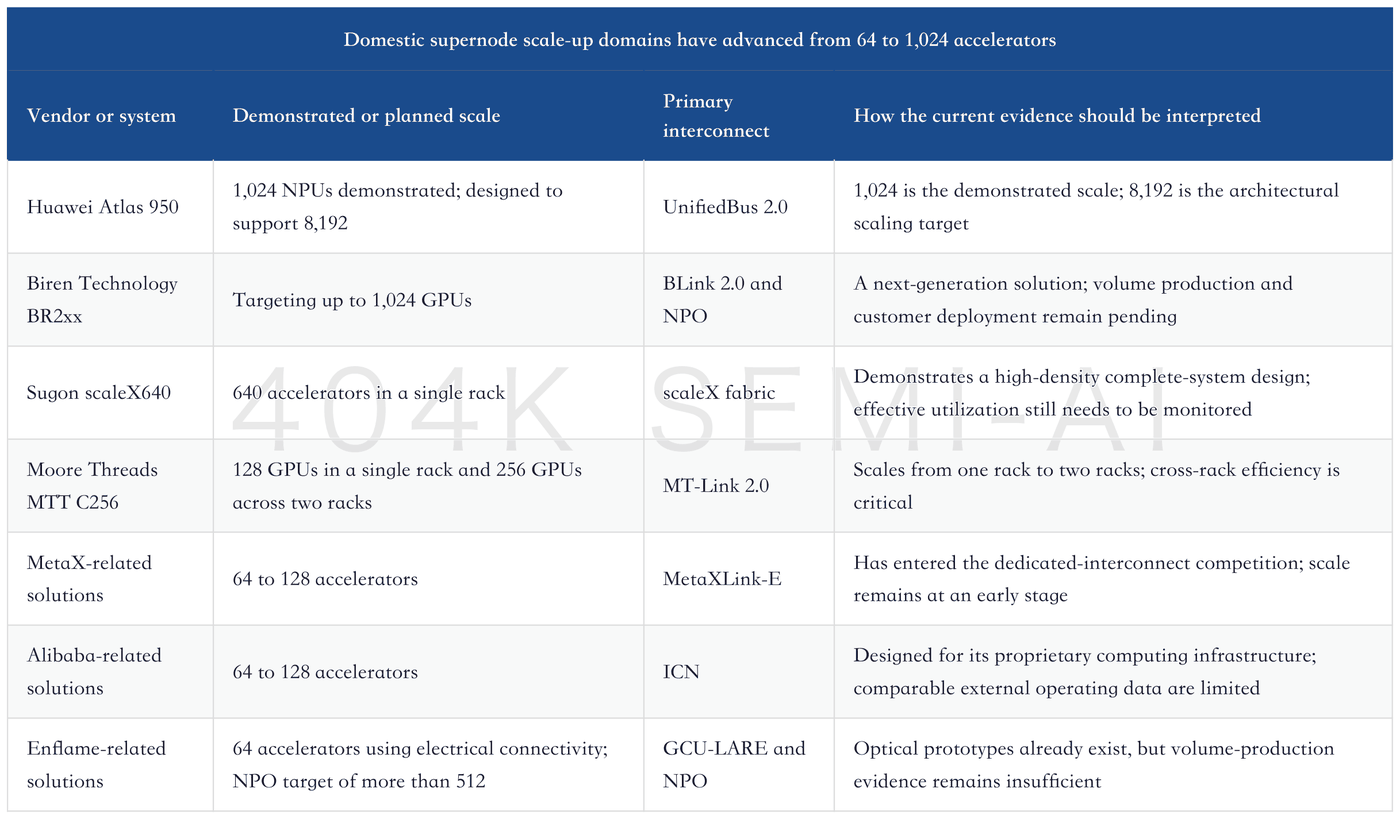
“Demonstrated,” “designed to support,” and “target scale” must be strictly distinguished. Demonstrating 1,024 accelerators does not mean customers have already deployed 1,024 accelerators at scale, while an architecture capable of scaling to 8,192 accelerators does not mean it can maintain the same communications efficiency at that scale.
