
AI Scale-Up Networks Go Deeper: 1,152 GPUs, 6-Meter Copper Interconnects, and Co-Packaged Optics by 2029
目录
TL;DR
I. Revaluing the Market at $73 Billion: Networking Content Begins to Catch Up With Compute Expansion
II. Data Movement Lags Compute: Why the Bottleneck Is Shifting to Scale-Up Networks
III. 6-Meter Copper Interconnects: Near-Term Focus Is Extending Lifespan, Not Exiting
IV. From Rubin Ultra to Feynman: Optics Enters Between Racks First
V. Five Protocols Coexist: The Open Ecosystem Has Yet to Select a Unified Standard
VI. Profit Pool Ranking: Chips in 2026–2027, Optics After 2028
VII. Optical Beneficiary Ranking: Prioritize Architecture-Agnostic Assets
VIII. Industry Trends and Share Prices Are Not Synchronized: Earnings Sensitivity Still Lags
IX. Three Scenarios: Whether Feynman Deploys with 1,152 GPUs
X. Falsification Checklist: Four Changes That Would Alter the Current Sequencing
XI. What to Watch Over the Next Four Quarters: From Technology Narratives to Order Evidence
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
AI clusters continue to expand, shifting network constraints from inter-data-center throughput to data movement within and between racks. The investment sequence over the next three years will not be a simple transition from copper to optics: 2026–2027 will focus on extending copper’s useful life and protocol fragmentation, 2028 on hybrid copper-optical architectures, and 2029 on whether co-packaged optics can achieve meaningful volume.
TL;DR
The $73 billion market reflects dual expansion in scale and bandwidth. Morgan Stanley has raised its 2030 scale-up networking market estimate to approximately $73 billion, roughly four times its previous $17 billion forecast for 2029, implying a 2026–2030 CAGR of about 46%. The drivers include higher AI capex and the expansion of individual scale-up domains from 72 GPUs to 576 and 1,152 GPUs, which increases switching bandwidth and interconnect ports per accelerator.
Copper interconnects can hold their ground for at least another two years. Passive copper cables still offer the lowest latency, power consumption, and cost over short distances. 448G SerDes, PAM6 modulation, and 200G retimers could extend usable reach to approximately six meters. Rubin Ultra is more likely to adopt a hybrid architecture with copper within racks and optics between racks. Copper’s share will decline, but it will not disappear abruptly from next-generation systems.
2029 will be the critical validation year for co-packaged optics. Co-packaged optics penetration in scale-up networks may remain in the low single digits in 2028. Once Feynman expands a single domain to 1,152 GPUs, inter-rack bandwidth density and I/O power savings will have a better chance of overcoming barriers including cost, yield, maintenance, and supply-chain lock-in. Fully integrated 3D co-packaged architectures are more likely to arrive after 2030.
Protocol selection will determine where the profit pools accrue. NVIDIA preserves its closed-system advantage through NVLink and NVSwitch; Broadcom addresses the open ecosystem through scale-up Ethernet and custom accelerators; PCIe remains a transitional bridge in 2026–2027; and UALink is the largest variable beyond 2027. Cloud providers will not follow a single path, creating incremental value for protocol conversion, retiming, switching silicon, and test and measurement.
Connectivity silicon leads near term; optical upside comes later. The more direct beneficiaries in 2026–2027 are NVIDIA, Broadcom, Astera Labs, Semtech, Credo, and Marvell Technology. From 2028 onward, demand begins to accelerate for Corning’s fiber arrays, Lumentum’s and Coherent’s lasers and optical engines, optical circuit switching, and Keysight Technologies’ test equipment. A sound industry thesis must still align with earnings delivery and valuation; the base case for optical companies is not uniformly above market consensus.
Four disconfirming scenarios would delay the optical transition trade. Further improvements in copper reach, scale-up domains remaining within a single rack, inference workloads not requiring ultra-large shared domains, and persistently high co-packaged-optics failure rates and maintenance costs would all push the revenue inflection further out. Key indicators to monitor include Rubin Ultra’s actual rack architecture, copper-cable reach at 200G per lane, initial scale-up optical-engine orders, and whether Feynman retains its 1,152-GPU design.
I. Revaluing the Market at $73 Billion: Networking Content Begins to Catch Up With Compute Expansion
Scale-up networking is evolving from a rack accessory into core AI system infrastructure. Historically, the market tended to extrapolate server value based on GPU counts, treating networking as an ancillary component that grew in line with compute. Next-generation systems change this relationship: as accelerator counts, per-accelerator bandwidth, and switching tiers increase, networking content value will grow faster than GPU volumes.
Morgan Stanley’s latest estimate puts the scale-up networking market at approximately $73 billion in 2030, roughly four times its previous $17 billion forecast for 2029, representing a 2026–2030 CAGR of approximately 46%. This estimate excludes network interface cards, pluggable optical modules, and cables, making it closer to the switching and interconnect foundation than to total revenue across the entire AI networking supply chain.
Market expansion includes three multipliers. The first is AI capex. Higher cluster budgets from cloud providers and model developers translate into more accelerators. The second is the expansion of scale-up domains, allowing a single workload to access more GPUs simultaneously. The third is higher bandwidth per GPU, which increases demand for switching silicon, SerDes, retimers, cables, and optical engines as both port counts and data rates rise.
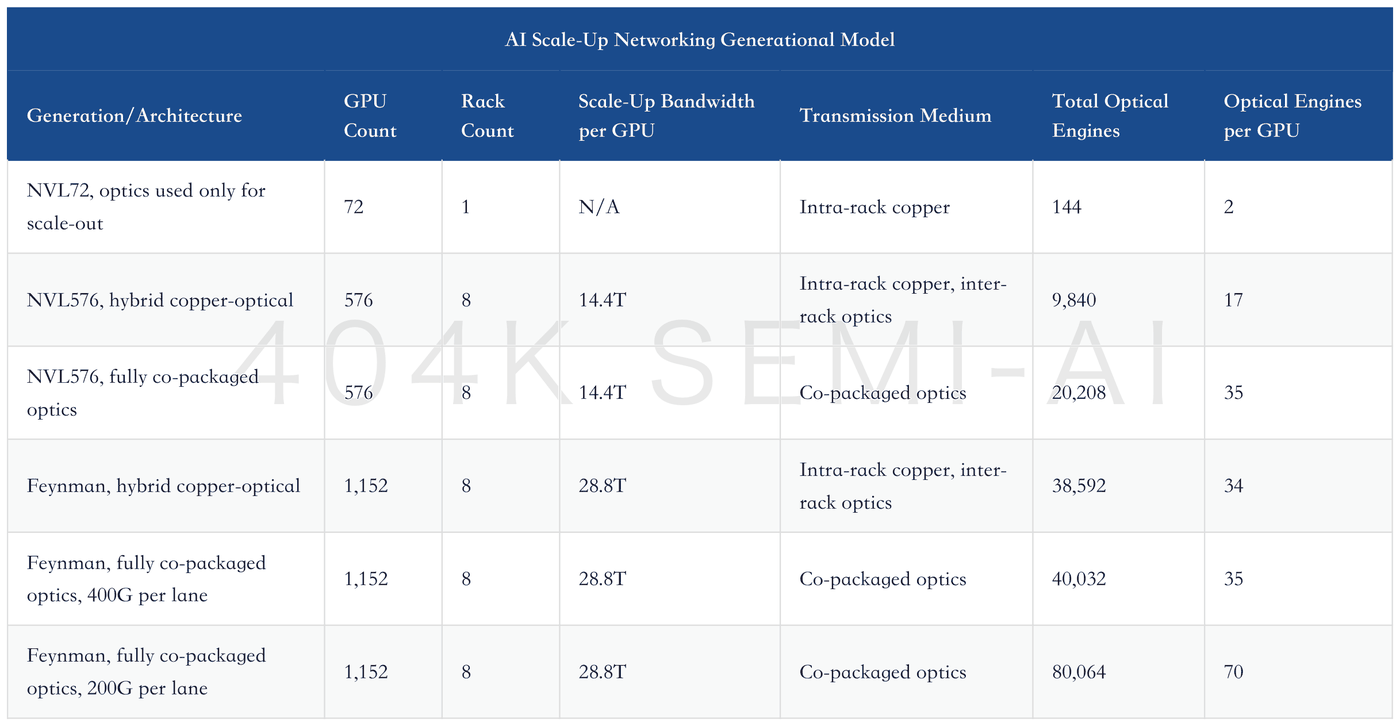
The table highlights the most important order of magnitude: from NVL72 to Feynman, GPU count increases 16-fold, while optical-engine content per GPU could rise from two to 34–70. Whether the final architecture is hybrid or fully optical remains contested, but the increase in networking content value does not depend on a single technology path.
AI Networking Interconnect Hardware, Part I: Value Migration Behind 1.6T/3.2T
II. Data Movement Lags Compute: Why the Bottleneck Is Shifting to Scale-Up Networks
The long-term divergence between compute and interconnect performance continues to widen. According to the report, hardware floating-point performance has increased approximately six million-fold over the past 30 years, or roughly threefold every two years. Interconnect bandwidth has increased only about 450-fold over 23 years, averaging approximately 1.6-fold every two years. The faster compute performance grows, the more costly the time spent waiting for communication, synchronization, and memory access becomes.
Large-model training magnifies this imbalance. Tensor parallelism, pipeline parallelism, and expert parallelism all generate substantial accelerator-to-accelerator communication during each iteration. As models adopt mixture-of-experts architectures, all-to-all data exchange among GPUs increases, and network congestion directly reduces utilization of expensive accelerators. Saving one watt of I/O power or eliminating one synchronization delay translates into meaningful power and depreciation value across clusters containing tens of thousands of accelerators.
Scale-up and scale-out networks serve different purposes. Scale-up networks connect GPUs within the same high-performance computing domain, prioritizing low latency, memory semantics, and high reliability. Scale-out networks connect multiple servers, racks, or clusters, emphasizing general-purpose connectivity, routing, and manageability. The boundary between the two shifts as systems expand: when a scale-up domain extends from one rack to eight, distance constraints previously associated with scale-out networking become part of the scale-up design.
This is also why Rubin Ultra matters. A configuration of 576 GPUs across eight racks means copper can still be prioritized within racks, while inter-rack connections must address longer distances, higher port density, and greater I/O power consumption. When Feynman expands the domain further to 1,152 GPUs, the power and density benefits of optical interconnects increase accordingly.
Copper interconnects remain the preferred medium for short-reach connectivity because they provide the lowest latency, lowest power consumption and lowest cost. However, as signalling speeds increase, electrical losses, insertion loss and noise become progressively more difficult to manage, requiring increasingly sophisticated SerDes, digital signal processors, retimers and equalization techniques simply to preserve signal integrity. This phenomenon is often referred to as the industry’s “copper wall.”
This assessment establishes the starting point for technology selection: system designers will continue to prioritize copper wherever distance and loss budgets permit. Optics enters only when its bandwidth-density, transmission-distance, and power advantages are sufficient to offset the added complexity.
III. 6-Meter Copper Interconnects: Near-Term Focus Is Extending Lifespan, Not Exiting
Copper retains compelling economics. Passive direct-attach copper cables require no optical-electrical conversion, resulting in lower latency, power consumption, and cost than optical modules. Short distances, manageable cabling, and easy maintenance within racks make copper the default choice for next-generation AI systems.
Copper’s physical losses worsen at higher data rates. The supply chain is extending reach through more advanced serializers/deserializers, equalization, retiming, and modulation. 448G SerDes, PAM6 modulation, and 200G retimers are expected to extend high-speed connectivity to approximately 6 meters. This is sufficient for most intra-rack links and some adjacent-rack connections.
Copper interconnects will split into three tiers. Passive direct-attach copper cables are suited to the shortest distances. Active copper cables (ACCs) use analog redrivers to extend reach to approximately 3 meters while maintaining relatively low power consumption. Active electrical cables (AECs) add retiming, equalization, and clock recovery, with typical reach of 7–9 meters, potentially contracting to approximately 5 meters at 200G per lane. AEC power consumption can still be approximately 50% lower than that of pluggable optical modules.
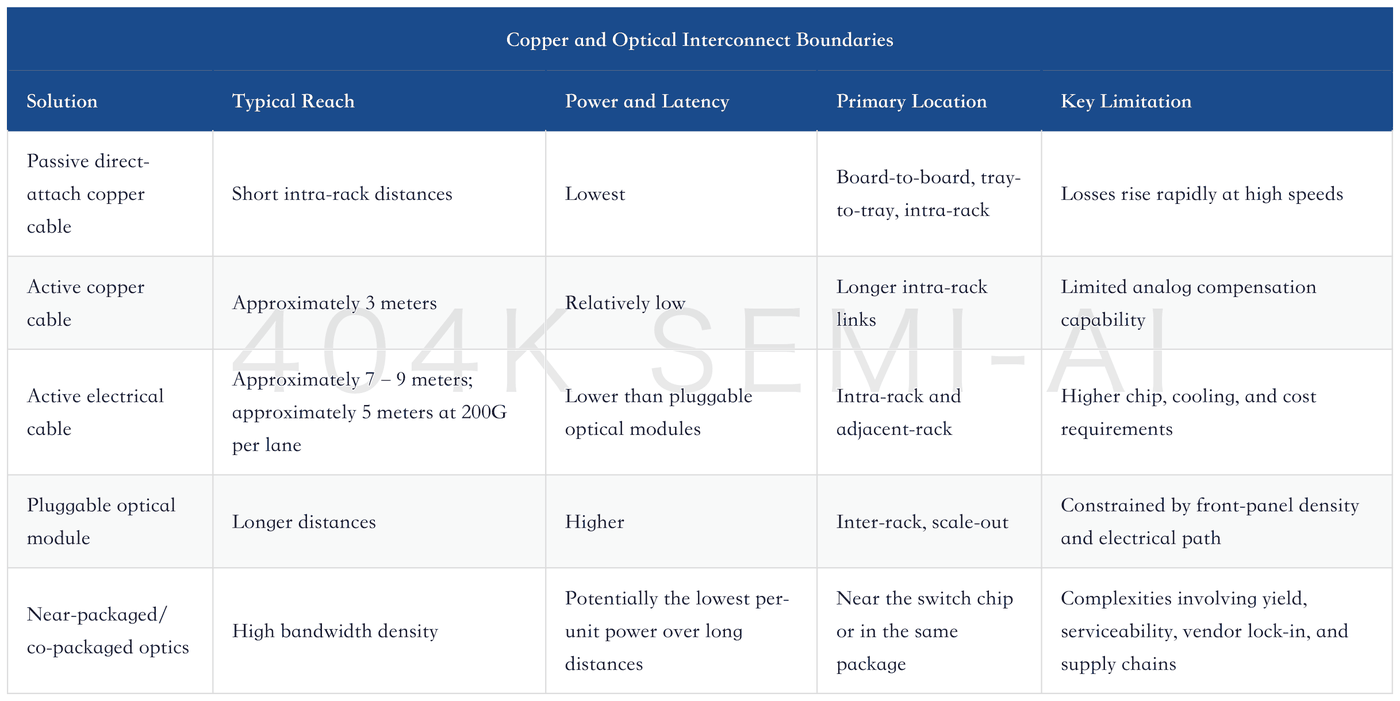
The investment cadence is therefore closer to “copper monetizes first, optics takes over later.” Astera Labs, Credo, Semtech, and Marvell Technology can generate near-term revenue from retiming, protocol conversion, AECs, and high-speed SerDes. Pure-play copper suppliers without an optical roadmap will face a growth ceiling after 2029, but their 2026–2027 orders should not be discounted prematurely because of longer-term optical adoption.
CPO Bull-Case Expectations Cool: Architectural Competition Cannot Stop Incremental Optical Demand
IV. From Rubin Ultra to Feynman: Optics Enters Between Racks First
Rubin Ultra is more likely to adopt a hybrid copper-optical architecture. Using copper within racks preserves its cost, power, and latency advantages, while using optics between racks overcomes distance and density bottlenecks. This structure materially increases optical content without committing the entire system at once to still-immature co-packaging processes.
Co-packaged optics (CPO) reduces the approximately 15–30-centimeter electrical path between the switch chip and front-panel optical modules to a few millimeters, lowering high-speed electrical-signal losses across the printed circuit board. The report estimates that optical-interconnect-related power consumption could decline by approximately 50%–80%. As bandwidth, port counts, and rack counts increase simultaneously, these energy savings will shift from a component-level advantage to a data-center-level power advantage.
2028 will remain a trial period. The report expects only limited CPO adoption in scale-up networks in 2028, followed by a meaningful increase after 2029. Feynman plans to expand a single domain to 1,152 GPUs; higher cross-rack traffic and 28.8T of bandwidth per GPU provide a clearer economic case for CPO. Full 3D co-packaged architectures are more difficult to manufacture and are more likely to scale after 2030.
Near-packaged optics (NPO) will become an important transitional solution. Optical engines are placed near the switch chip but are not fully integrated into the same package, preserving openness, pluggability, and serviceability. For customers unwilling to entrust lasers, silicon photonics, packaging, and switch chips entirely to a single supplier, near-packaged solutions trade some energy efficiency for supply-chain flexibility.
Optical circuit switching (OCS) offers another path. It switches connections directly in the optical domain and is suited to training workloads with relatively stable traffic patterns and high-volume data transmission. Microelectromechanical systems offer the highest maturity, relatively low insertion loss, and fast switching; liquid crystal on silicon solutions have longer lifespans but slower speeds. Google’s adoption of optical circuit switching and torus topology shows that very large scale-up domains do not necessarily require conventional switch chips plus CPO.
Full Transcript of Lumentum Investor Meeting: Optical Interconnect Demand Continues to Accelerate from Scale-Out to Scale-Up
AI Optical-Module Demand Revised Higher Again: How Morgan Stanley Pushes 1.6T, InP, and CPO Bottlenecks Out to 2028
V. Five Protocols Coexist: The Open Ecosystem Has Yet to Select a Unified Standard
Network protocols will determine chip market share and the degree of supply-chain openness. NVIDIA’s NVLink provides higher bandwidth, lower latency, and comprehensive software integration, at the cost of a more closed system. NVLink Fusion allows third-party CPUs, accelerators, and custom chips to connect to NVLink, expanding the ecosystem while keeping protocol conversion and interconnect control within NVIDIA’s platform.
PCIe will remain the most practical bridge for non-NVIDIA scale-up networks in 2026–2027. Its performance trails dedicated memory-semantic interconnects, but it offers a mature ecosystem, broad compatibility, and available silicon. Astera Labs’ Scorpio-P and Scorpio-X are positioned precisely for this transition period.
UALink represents the largest variable in open memory-semantic interconnects. Commercial switch chips and large-scale deployment are not expected until after 2027. Whether members can deliver on schedule, whether the software stack can stabilize, and whether cloud providers are willing to converge on a common standard will all affect the revenue trajectories of Astera Labs and Marvell Technology.
Ethernet scale-up solutions use switch chips such as Broadcom’s Tomahawk to bring openness, a mature supply chain, and economies of scale inside the rack. Ethernet still requires enhancements in ultra-low latency and memory semantics, but cloud providers can compensate through coordination across software, NICs, and internally developed accelerators. Amazon Web Services’ random network generation topology reduces router counts by 69%, increases throughput by up to 33%, and lowers networking-equipment power consumption by approximately 40%, demonstrating that topology innovation can also reshape hardware demand.
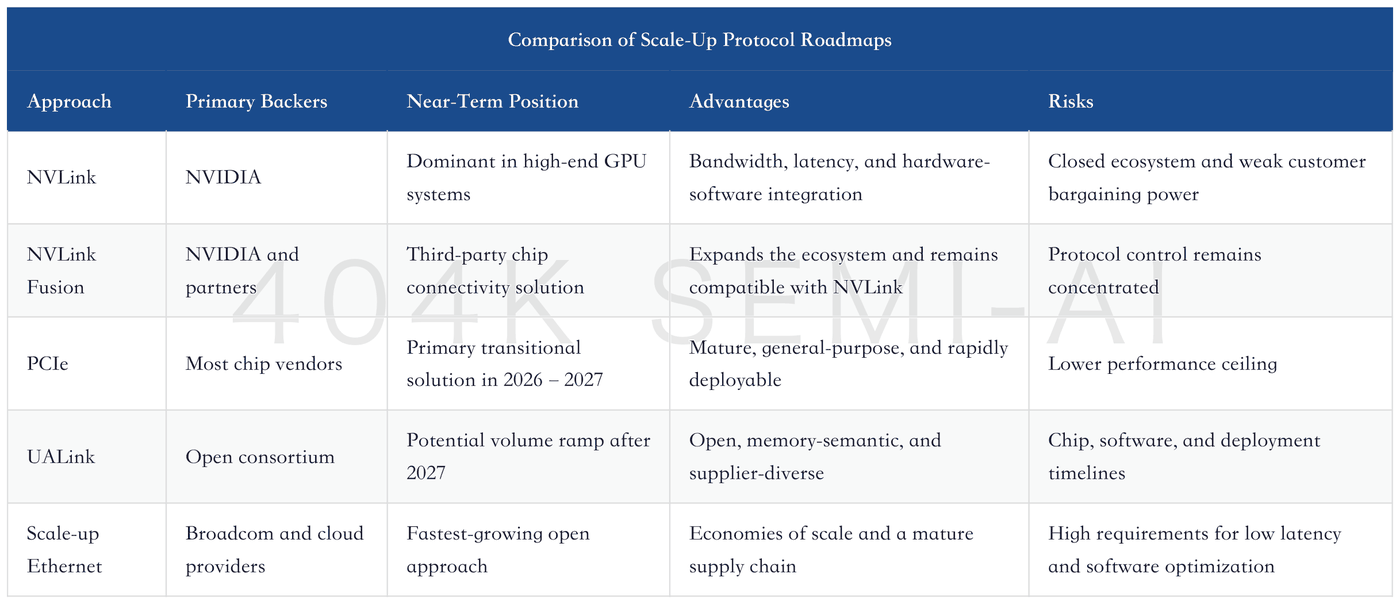
Whether this ultimately proves advantageous as AI clusters continue to scale remains an important question. The non-NVIDIA ecosystem remains largely undecided. Over the next two years, architectural decisions made by hyperscalers and ASIC customers will determine which fabrics emerge as industry standards, creating a significant greenfield opportunity for Broadcom, Marvell Technology, and Astera Labs.
The lack of protocol convergence will increase R&D; costs but benefit cross-architecture components. Retimers, protocol-conversion chips, test equipment, fiber arrays, and lasers can serve multiple systems without requiring an accurate bet on the eventual networking standard.
Control of AI Networking: NVIDIA, Broadcom, and Marvell Technology
VI. Profit Pool Ranking: Chips in 2026–2027, Optics After 2028
Nvidia remains the top beneficiary in the system profit pool. NVLink, NVSwitch, GPUs, and the system platform collectively provide end-to-end control, allowing rising networking content to flow directly into overall system value. Risks include growing custom-accelerator share and customers using open protocols to reduce vendor concentration.
Broadcom (AVGO) has the most comprehensive open-ecosystem portfolio. Custom accelerators, Tomahawk switch silicon, SerDes, Ethernet, PCIe, NICs, and optical capabilities can be combined into a complete solution. Even if co-packaged optics is delayed, Broadcom can still generate revenue from copper, switching, and custom chips; if scale-up Ethernet prevails, its content value should rise further.
Astera Labs offers the greatest near-term upside among pure-play connectivity names. Content per accelerator was approximately $50–100 when the company went public and has now risen above $1,000. Once Scorpio-X begins shipping, investor focus will increasingly shift toward UALink adoption and customer diversification. Risks include a premium valuation, customer concentration, and slower-than-expected adoption of open protocols.
Semtech and Credo are positioned on both sides of copper life extension and the transition to optics. Semtech’s CopperEdge benefits from copper connectivity, while FiberEdge, DirectEdge, and HieFo address linear optics, 1.6T, 3.2T, and near-/co-packaged applications. Credo derives near-term revenue from AECs while expanding into scale-up switching and optical components; management expects FY2027 revenue growth of more than 80% and optical-product revenue above $600 million. A crowded new-product pipeline and rising execution complexity are common risks for both companies.
Marvell Technology has broad exposure, but its monetization timeline requires the most validation. The company participates in UALink, scale-up Ethernet, and NVLink Fusion, while acquisitions have expanded its optical-interconnect and silicon-photonics capabilities. It can benefit from multiple technology paths, but the investment challenge is determining when customer programs will translate into visible revenue and whether integration costs will offset growth.
