
目录
I. Why Expensive GPUs Still Sit Idle Waiting for Data
II. Why a 140GB Model File Can Require Nearly 1TB During Training
III. After Training, Every User Adds Another Cache
IV. Agents Turn a Single Request into Sustained Resource Occupancy
V. When HBM Fills Up, Data Starts Moving Outward
VI. Every 1GB Saved by Software Is Usually Spent Again by the Product
VII. This Bill Is Reshaping Server Hardware Budgets
VIII. Revenue Depends First on Bit Shipments and Pricing; Profit Also Depends on Yield and Depreciation
IX. Three Outcomes Would Put Memory Demand on Different Growth Trajectories
X. Over the Next Four Quarters, Ten Metrics Matter More Than the Market Narrative
XI. Five Developments Could Push the Memory Bill Below Expectations
XII. Ultimately, Only Two Operating Questions Matter
An AI server is likely to exhaust memory before compute. Training loads weights, activations, and optimizer states into HBM simultaneously; inference expands the KV cache with context length and concurrency; and agents extend state residency to minutes or longer.
I. Why Expensive GPUs Still Sit Idle Waiting for Data
Once a server equipped with high-end GPUs begins processing, data moves through a clearly defined hierarchy. The hottest weights, activations, and KV caches remain in HBM; indices and tool states currently being processed by the CPU reside in system DRAM; and colder sessions and checkpoints spill into CXL memory and SSDs. If any tier cannot supply data fast enough, the GPU must wait.
Memory demand therefore spans four ledgers. The model ledger tracks weights and runtime buffers; the training ledger covers gradients, optimizer states, and activations; the inference ledger records each session’s KV cache; and the system ledger holds datasets, indices, checkpoints, and tool states. These four ledgers overlap within the same machine but are driven by entirely different variables.
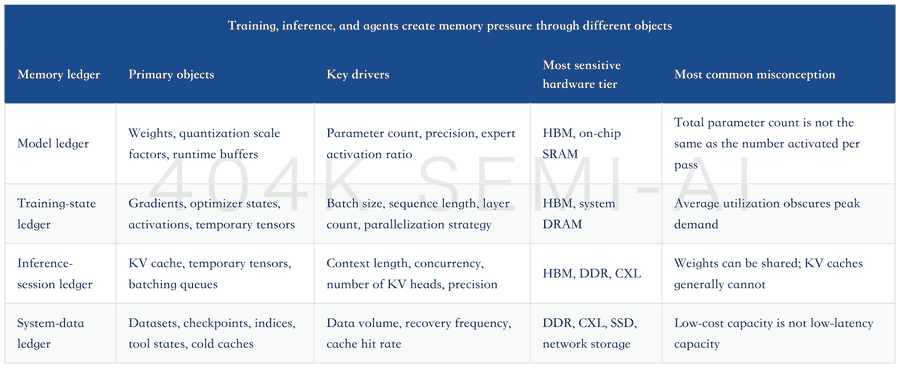
Capacity and bandwidth are separate gates. Capacity determines how many models and sessions can fit; bandwidth determines how much data can reach the compute units each second. Adding memory can increase concurrency without necessarily improving tokens generated per second. Increasing bandwidth can reduce idle time but does not automatically support longer contexts.
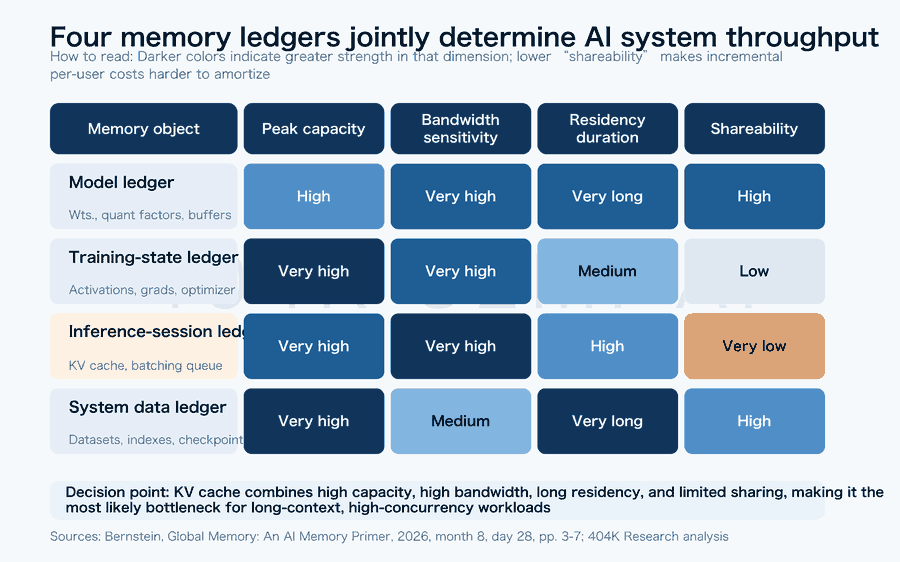
This also explains AI-server procurement. Customers pay for GPUs, but what they are really buying is a system capable of sustaining useful work. If HBM, system DRAM, interconnects, or SSDs fall behind, expensive compute silicon sits idle and the server’s revenue-generating capacity declines.
II. Why a 140GB Model File Can Require Nearly 1TB During Training
Loading a 70-billion-parameter model onto a server is only the starting point for training. At 2 bytes per parameter, FP16 or BF16 weights occupy approximately 140GB. Once training begins, the machine must also retain intermediate forward-pass results, backpropagation gradients, and the optimizer states used to update each parameter.
A Bernstein expert interview from December 2025 provided an intuitive breakdown. In this scenario, weights account for approximately 140GB, activations and other temporary states for approximately 500GB, and gradients for approximately 140GB. Optimizer states, master weights, and framework buffers consume the remaining space, bringing the total close to 1TB.
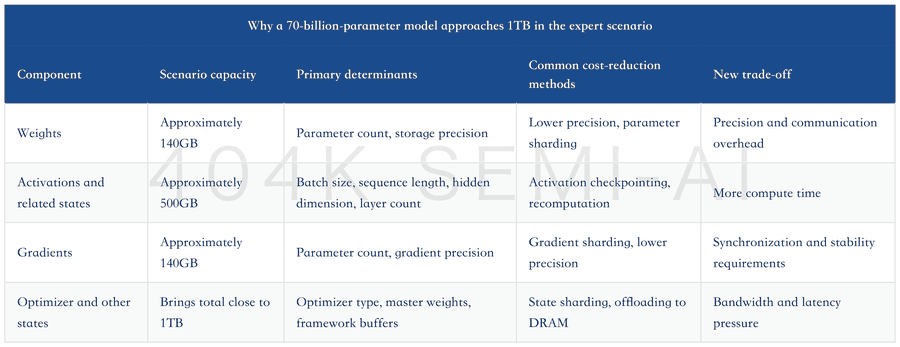
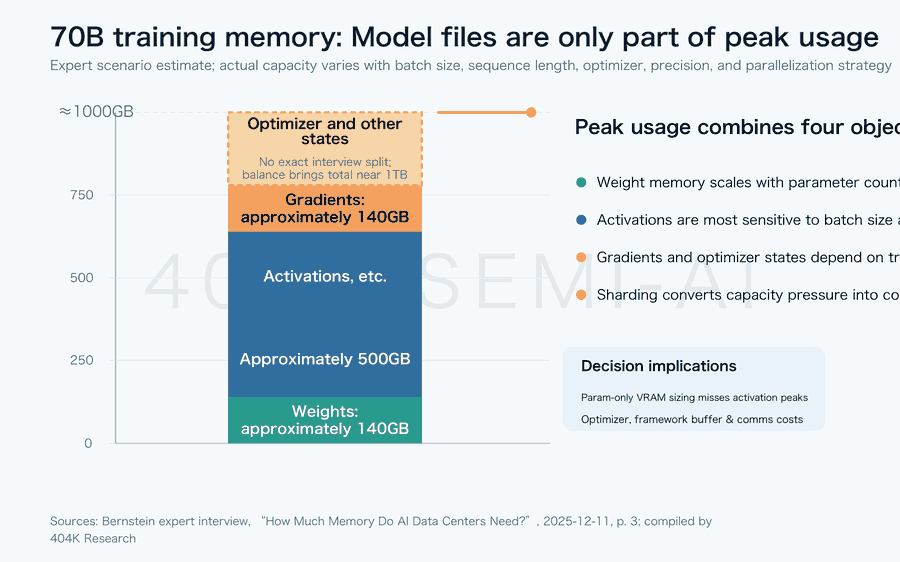
The 1TB figure represents one expert scenario and should not be applied to every 70-billion-parameter model. Batch size, sequence length, hidden dimension, optimizer, and parallelization strategy all affect peak demand. Still, it illustrates a durable relationship: the model file records “what the model is,” while training must also preserve “what was just computed” and “how the model will be updated next.”
Training clusters typically trade communication for capacity through sharding. ZeRO or fully sharded data parallelism distributes weights, gradients, and optimizer states across multiple accelerators, reducing per-GPU pressure. The additional communication consumes interconnect bandwidth; as synchronization slows, HBM savings can translate into longer training times.
Activation checkpointing makes a similar trade-off. The system retains only selected intermediate results and recomputes the rest when needed, freeing memory. This can support larger batches but may also slow each training step. Enterprises ultimately care about time to completion, cluster utilization, and failure recovery; per-GPU memory is only one constraint.
Datasets and checkpoints push additional pressure onto system DRAM and SSDs. Training data must be cleaned, sharded, shuffled, and prefetched, while checkpoints must periodically move from HBM back to persistent storage. Checkpointing too infrequently wastes compute after failures; checkpointing too often allows storage and network traffic to disrupt training.
The same expert interview characterized training-side memory demand as 100–1000 times that of a single inference workload. This range should be treated only as a directional scenario, not as a direct forecast of industry-wide demand. It reminds buyers to assess the full workflow: how much GPU runtime is spent on actual computation versus waiting for data, communication, checkpointing, and recovery.
III. After Training, Every User Adds Another Cache
Once an inference server has loaded the model, its weights can be shared across many users. The KV cache created by each active session generally cannot be shared; it grows with context length and continues occupying capacity for the life of the session. The inference ledger therefore tracks both model replicas and user state.
The prefill stage processes the entire input and is typically more compute-intensive. During decoding, each generated token requires reading the model weights and the accumulated KV cache, making memory bandwidth more likely to become the bottleneck. Time to first token and subsequent generation speed are often governed by different constraints.
A simplified formula for KV-cache capacity is:
KV capacity ≈ 2 × number of layers × number of KV heads × dimension per head × bytes per element × context tokens × active sequences
The leading 2 represents Key and Value. Multi-query attention and grouped-query attention reduce the number of KV heads, quantization lowers the bytes per element, and paged attention reduces fragmentation. These techniques lower the coefficient, but the multiplicative relationship between context length and concurrency remains.
A simple illustrative scenario demonstrates this amplification. Assume a model with 80 layers, 8 KV heads, and 128 dimensions per head, with the KV cache stored at 2-byte precision. A single 8K-token context requires approximately 2.5GiB; 32K requires approximately 10GiB; and 128K requires approximately 40GiB. With 64 active 128K sequences, the cache reaches approximately 2.5TiB—before model weights and runtime buffers are included.
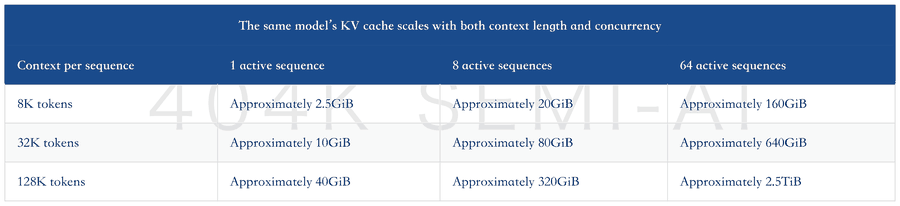
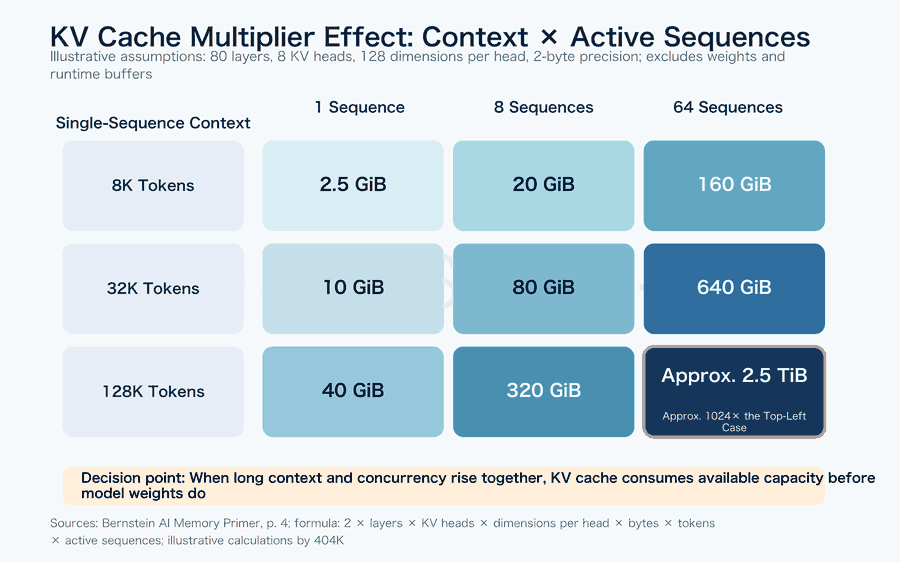
This table maps directly to the economics of inference services. Longer contexts can increase the value of each task but reduce the number of users an accelerator can serve simultaneously. Higher concurrency expands revenue opportunities while also increasing cache capacity and data-movement bandwidth requirements. Providers must price the trade-offs among response speed, context length, concurrency, and cost per token.
Temporarily inactive KV caches can be moved to system DRAM, CXL memory, or SSDs and prefetched before the session resumes. The cheaper the medium, the farther the data sits from the compute units and the higher the typical recovery latency. Real-time voice and code completion cannot tolerate noticeable pauses; long-running research tasks are better suited to storing cold state in outer tiers while waiting for tools to return.
IV. Agents Turn a Single Request into Sustained Resource Occupancy
A conventional chat session may release resources soon after completing a response. An agent, by contrast, plans tasks, invokes tools, reads results, revises its approach, and carries intermediate outputs into subsequent model calls. The user submits one request, but the backend may perform multiple rounds of prefill and decoding.
Agents add four multipliers to the memory equation: active task count, model calls per task, tokens per call, and state retention time. Parallel branches increase peak demand, sequential steps extend occupancy, and tool wait times allow parts of the hot cache to cool.
As query volume grows, latency may deteriorate faster than KV-cache capacity increases. Sufficient capacity only means the data fits; meeting service levels also requires moving it on time. If bandwidth, scheduling, or tail latency approaches its limit, users will experience stalls.
Agents also expand the CPU-side working set. API responses, retrieval indexes, state databases, and task scheduling are typically handled by CPUs, while intermediate results must remain available after one model call ends and before the next step begins. Servers therefore require more HBM beside the accelerator and more DRAM beside the CPU.
These workloads must also be measured in “cache-hours.” A 40GiB cache occupied for 1 minute implies a completely different hardware turnover rate than one occupied for 30 minutes. Task completion rates, average step counts, tool wait times, and recovery hit rates directly affect how many tasks a server can complete each day.
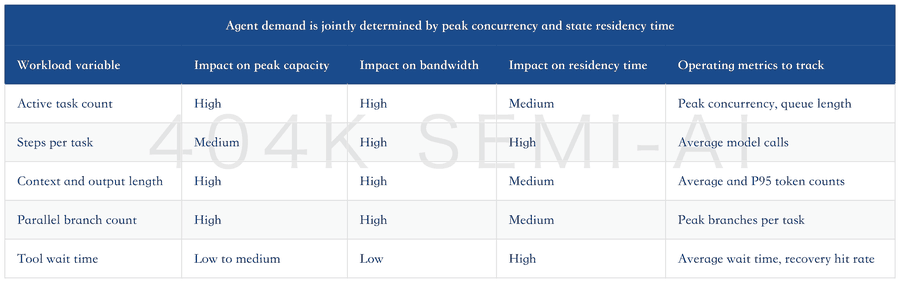
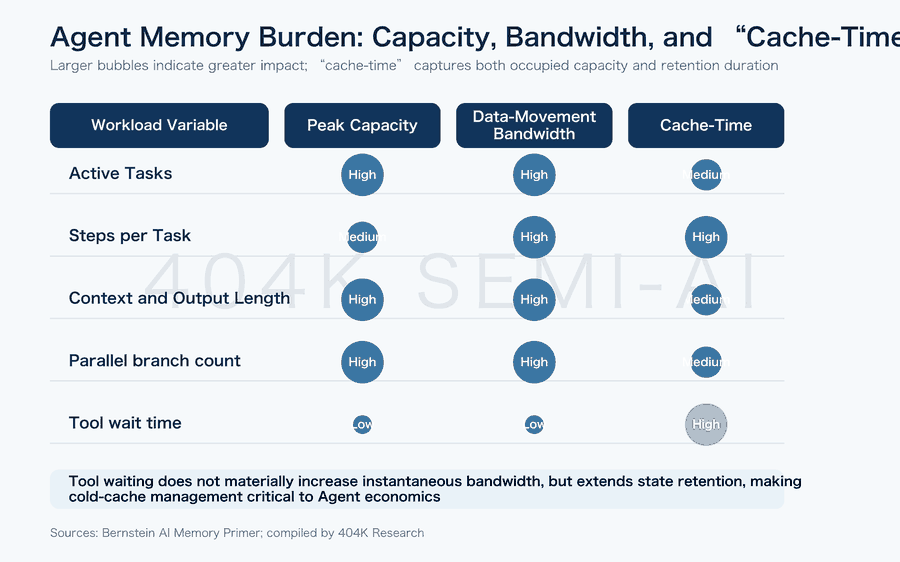
Agent completion rates determine whether this investment generates revenue. As task success rates improve, enterprises may delegate more workflows to models, potentially increasing step counts, concurrency, and state residency time. If completion rates remain stagnant, customers will constrain steps and context length, leaving memory demand below hardware vendors’ linear projections.
V. When HBM Fills Up, Data Starts Moving Outward
HBM is reserved for data needed immediately in computation. It sits close to the accelerator, offers high bandwidth and low energy consumption, and is also the most expensive memory per unit of capacity. System DRAM holds preprocessing data, retrieval indexes, CPU tool state, model-loading buffers, and cold KV caches. SSDs accommodate datasets, checkpoints, and long-idle state.
CXL adds a shareable memory channel between these tiers. The first stage adds memory expanders to individual servers; the second allows multiple CPUs or accelerators to access a memory pool; only the third uses switches to create rack-scale resource pools. Pooling can reduce the idle capacity provisioned for peak demand on each machine and improve overall utilization.
CXL cannot deliver HBM-class bandwidth. It operates over the PCIe physical layer, and routing data through controllers, switches, and links adds latency. Software must also determine which data has cooled, when to migrate or prefetch it, and whether a failed recovery could delay the entire task.
In June 2026, UBS estimated the CXL market from accelerator, head-node CPU, and standalone CPU volumes, deriving a 2030 valuation range of US$7 billion to US$10 billion. Attachment rates, content per system, and product form factors remain uncertain. Protocol support, demonstration systems, volume-production customers, and revenue recognition are all at different stages.
Industry adoption will also unfold in phases. Volume production of expanders first increases revenue from controllers and memory modules; pooling then adds value from switch chips, firmware, and management software. Rack-scale sharing must still wait for accelerator vendors to open access and will face competition from proprietary interconnects and customer-designed solutions.
VI. Every 1GB Saved by Software Is Usually Spent Again by the Product
Quantization, grouped-query attention, paged attention, and prefix caching can all reduce memory use per task. Weight quantization lowers resident model capacity, KV quantization reduces per-session cache requirements, paged attention limits fragmentation, and prefix caching avoids recomputing identical prompts.
These savings introduce new trade-offs. Lower precision may affect model quality; paging and offloading increase scheduling complexity; prefix caching depends on request similarity; and speculative decoding introduces an additional model or verification compute. Memory-cost reductions must therefore be assessed alongside accuracy, response speed, and system complexity.
Conditional memory illustrates another shift. Morgan Stanley’s research on DeepSeek Engram describes separating some static facts from general-purpose computation and placing them in CPU system DRAM for lookup and prefetching. For a 100 billion-parameter configuration at 2 bytes per parameter, the report estimates approximately 200GB of system DRAM. Lower HBM pressure shifts memory demand to another tier.
Freed resources rarely remain idle for long. Smaller weights allow more models to be deployed on each card; smaller KV caches support longer contexts and greater concurrency; and higher cache hit rates allow providers to cut prices and expand request volumes. Even as unit demand declines, total demand remains determined by task volume and complexity.
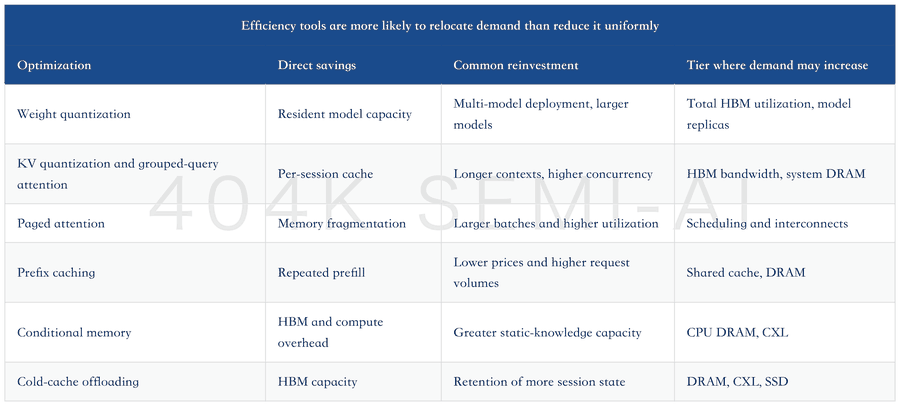
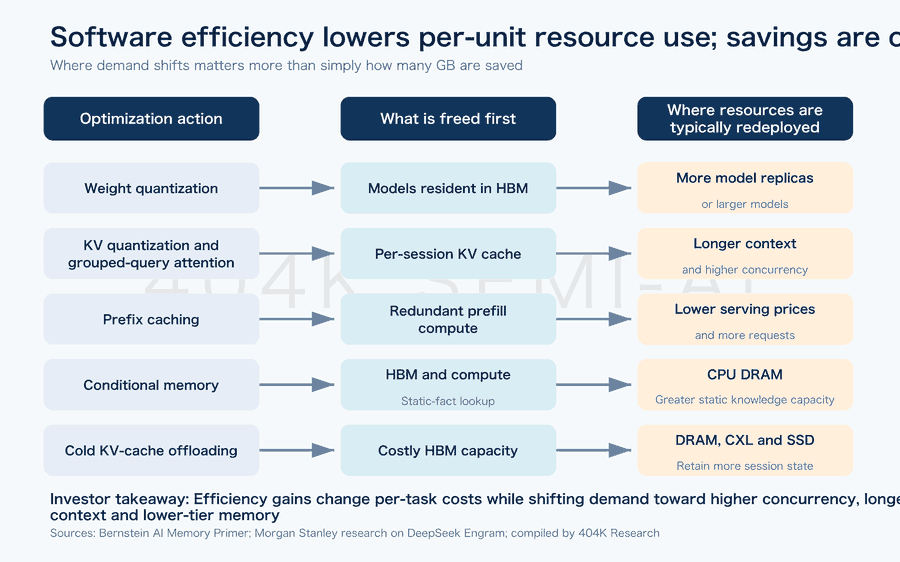
Total demand can be expressed through two equations. Peak capacity approximately equals per-session capacity multiplied by peak concurrency, plus model replicas and runtime buffers. Bandwidth demand approximately equals data read per token multiplied by tokens generated per second. Software may reduce one multiplier while product upgrades push another higher.
VII. This Bill Is Reshaping Server Hardware Budgets
HBM receives budget first because it directly determines whether the hottest data can continuously feed the accelerator. Wide buses and advanced packaging provide high bandwidth but require more DRAM dies and more complex stacking, testing, packaging, and thermal design. Each additional layer of capacity increases manufacturing difficulty and yield risk.
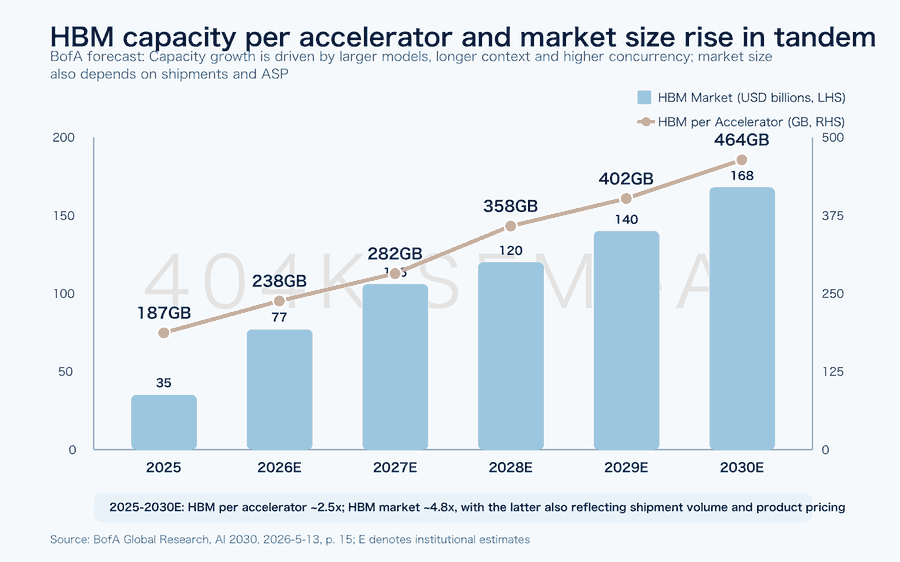
In May 2026, Bank of America projected that HBM content per accelerator would rise from 187GB in 2025 to 464GB in 2030, representing a compound growth rate of approximately 20%. Over the same period, it expects the HBM market to expand from approximately US$35 billion to approximately US$168 billion. This forecast depends on accelerator shipments, product mix, and ASPs and should not be treated as firm orders.
Bank of America used Vera Rubin to illustrate the growth in CPU-side memory. Its estimate pairs 288GB of HBM4 per accelerator with approximately 750GB of Vera CPU-side LPDDR. Standalone CPU racks will add still more memory capacity, extending server memory budgets from the GPU side to the CPU side.
HBM expansion will also constrain conventional DRAM supply. Both share front-end wafer capacity, while each HBM stack consumes more dies and requires additional TSV, stacking, and advanced-packaging steps. As manufacturers prioritize wafer allocation and capital spending, server DDR supply may tighten, transmitting AI demand into conventional memory prices.
High margins will attract capacity expansion. Cleanrooms, EUV equipment, advanced packaging, and customer qualification all involve long lead times, limiting the near-term supply response. New capacity will ultimately come online in stages. HBM yields, wafer allocation to conventional DRAM, and new capacity ramps must be tracked alongside orders.
VIII. Revenue Depends First on Bit Shipments and Pricing; Profit Also Depends on Yield and Depreciation
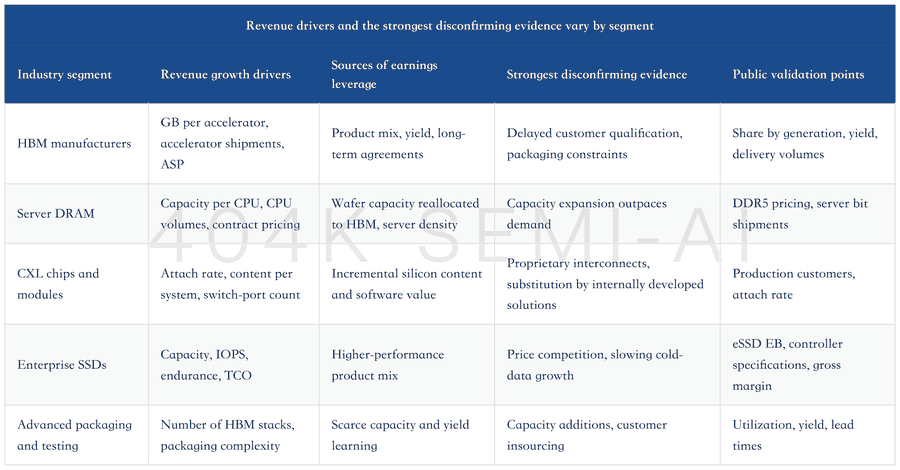
A memory company’s revenue can be simplified as bit shipments multiplied by price per bit. Profit must also account for wafer costs, yield, packaging, depreciation, and inventory costs. AI is simultaneously increasing volumes, shifting the product mix, and affecting industry utilization, making the earnings transmission more complex than a conventional PC or smartphone replacement cycle.
HBM captures the product-mix premium first. Higher stack counts, customer qualification, and advanced packaging raise unit value but also increase yield risk. Conventional DRAM benefits from rising server density, larger CPU-side working sets, and wafer capacity being reallocated to HBM. Enterprise SSDs store cold data, checkpoints, and retrieval data; profitability depends on controllers, endurance, tail latency, and energy efficiency.
CXL controllers and switches remain a small-base, high-elasticity opportunity. Attach rates determine the revenue ceiling, while customer concentration and substitution by internally developed solutions determine the valuation discount. Advanced packaging and testing add process steps and silicon content, but capacity constraints can also make them delivery bottlenecks. Growth in aggregate demand will not produce the same gross-margin uplift across every segment.
JPMorgan’s May 2026 supply-demand model projected continued increases in wafer allocation to HBM and strong demand for server DRAM and enterprise SSDs. The report also cautioned that high prices could destroy some demand and that substantial capital expenditure would eventually expand supply. The longer the cycle lasts, the more important inventory and capacity expansion become to the earnings outlook.
IX. Three Outcomes Would Put Memory Demand on Different Growth Trajectories
In the base case, model efficiency continues to improve and memory use per task declines. Longer contexts, Agent calls, and lower service prices expand usage. HBM content per accelerator continues to rise; system DRAM grows with CPU-side workloads and cache offloading; and CXL progresses from expanders toward selective pooled-memory deployments.
The upside case requires Agents to complete materially more work. As enterprises automate a larger share of tasks, average step counts, concurrency, and state residency all increase. To preserve response times, service providers retain more hot KV cache and provision more system DRAM. HBM and packaging remain constrained, while conventional DRAM faces additional pressure from wafer reallocation.
The downside case emerges if software advances faster than usage grows. Small models, quantization, prefix sharing, and cache scheduling rapidly reduce memory use per task, while enterprises remain unwilling to pay for long contexts. Agent completion rates stagnate, CXL remains limited to a small number of expanders, and new capacity eases shortages in HBM and DDR.
Publicly disclosed metrics can progressively distinguish among the three scenarios
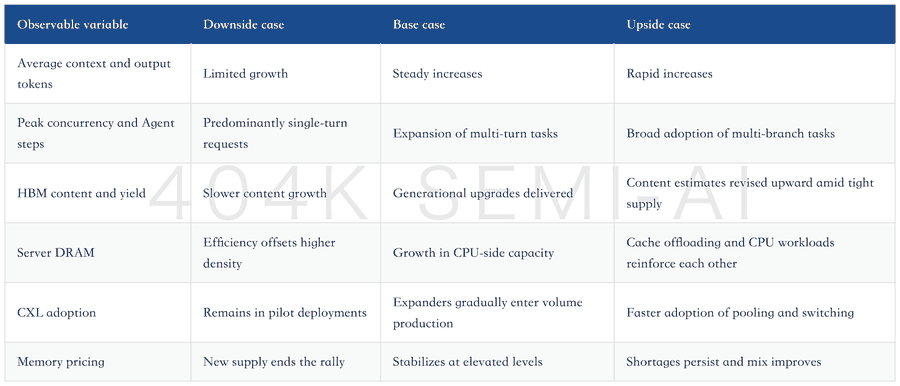
The dividing line among all three outcomes is actual usage. Parameter counts and advertised context windows indicate only technical capability. Completed task volumes, peak concurrency, state residency, and cost per token are what translate capability into server demand and revenue.
X. Over the Next Four Quarters, Ten Metrics Matter More Than the Market Narrative
First, track HBM capacity and stack counts for each accelerator generation. Design specifications determine unit value; actual shipments determine revenue. Second, monitor HBM customer qualification, production yield, and advanced-packaging deliveries. If any of the three falls behind, demand remains trapped in the order book.
Third, track DDR or LPDDR capacity per AI CPU and per server. As CPUs take on scheduling, retrieval, and tool execution, system-memory density should rise with each generation. Fourth, monitor wafer allocation between HBM and conventional DRAM. If HBM continues to displace DDR, conventional memory pricing will receive additional support.
Fifth, track average and P95 context lengths for model services. Advertised windows indicate only capability; actual usage determines cache requirements. Sixth, monitor peak concurrency, average batch size, and model calls per Agent. Together, these metrics determine both the revenue capacity of each model replica and peak cache requirements.
Seventh, track KV-cache quantization, hit rates, and offload ratios. Higher hit rates can reduce repeated prefill, while greater offloading can conserve HBM; recovery latency must be assessed alongside both. Eighth, monitor latency per output token and time to first token. Deterioration in either usually indicates that capacity, bandwidth, or scheduling is approaching its limit.
Ninth, track actual CXL attach rates, production customers, and switch-port counts. Protocol support, demonstration systems, and revenue recognition are far apart. Tenth, monitor contract prices, inventories, and capital expenditure for HBM, DDR5, and enterprise SSDs. The duration of earnings strength can be judged only by considering demand alongside the supply response.
XI. Five Developments Could Push the Memory Bill Below Expectations
First, memory use per task could continue to decline faster than usage grows. If quantization, grouped-query techniques, cache sharing, and combinations of small models are adopted rapidly, total hardware demand will fall below linear extrapolations. Second, Agent completion rates could remain stagnant. If multi-turn calls fail to generate sufficient commercial value, enterprises will restrict step counts, context lengths, and concurrency.
Third, service providers could pass expensive memory costs through to customers, reducing usage. Long contexts and real-time responses have value, but willingness to pay remains finite. Fourth, CXL and cold-cache offloading may fail to meet tail-latency requirements. Greater addressable capacity does not help if effective concurrency and tokens per second do not improve in parallel.
Fifth, supply could come online faster than demand. High HBM margins will attract investment in wafers, packaging, and equipment, while conventional DRAM capacity will also expand. Qualification, yield ramp-up, and construction timelines delay the supply response, but they do not make shortages permanent. When prices and capital expenditure rise simultaneously from already elevated levels, cyclical risk is accumulating.
XII. Ultimately, Only Two Operating Questions Matter
The first is how many tasks each server can complete per day while meeting latency and quality requirements. Training requires weights, activations, gradients, and optimizer states to be resident simultaneously. Inference must accommodate shared weights and session KV cache, while Agents extend state lifetimes and enlarge CPU-side working sets. Insufficient data delivery at any layer reduces task throughput.
The second is how much memory cost each successfully completed task consumes. HBM holds the hottest data; system DRAM handles preprocessing, retrieval, tool calls, static memory, and cold cache; CXL improves capacity utilization; and SSDs store colder data and checkpoints. Tiering reduces costs only when recovery latency remains manageable.
Software will continue to reduce memory use per task, while products continue to add context, concurrency, and Agent steps. If task volumes and complexity grow faster than unit memory requirements decline, the value of HBM and system DRAM will continue to rise. If efficiency gains fail to translate into real usage, the memory-demand curve will flatten.
Both operating questions ultimately converge on the same result: server revenue comes from completed tasks, while profit equals the price of each task less compute, memory, networking, and depreciation costs. How far the next memory cycle can run will depend on whether growth in successfully completed tasks can continue to outpace cost per task.