
目录
Executive Summary
Beyond GPUs, AI Factories Are Competing as Integrated Systems
Agentic AI Brings CPUs Back into the Core Expansion Cycle
Advanced Packaging Turns Chipmaking into System Manufacturing
Optics Takes the Baton: Focus on Energy and Serviceability, Not the Narrative
800V and Liquid Cooling Will Determine Whether Megawatt Racks Become Viable
After Capex Broadens, Who Is Best Positioned to Convert Specifications into Revenue
The Greatest Risk Is Getting the Technology Roadmap Right but the Timeline Wrong
Which Public Data Points Could Change the View
本内容基于公开资料和研报数据整理,不构成任何投资建议,不代表任何个人观点,仅供学习参考,请理性阅读
The marginal bottleneck in AI infrastructure is shifting from GPU supply to data movement, power delivery, cooling and system reliability. Near-term revenue is flowing first to pluggable optics, advanced packaging, sidecar power systems, DC-DC conversion, liquid cooling and rack-scale delivery. NPO, CPO, native 800V architectures and on-chip optics still require customer qualification and repeat orders.
Executive Summary
The competitive unit in AI infrastructure has expanded from the chip to the entire AI factory. Compute, memory, networking, packaging, power delivery, liquid cooling, control and operations collectively determine cost per Token and usable compute capacity. A shortfall in any layer leaves expensive accelerators waiting for data, throttling or offline, reducing output.
Revenue realization follows a clear sequence. Over the next several quarters, the focus should be on pluggable optical modules, switching and retiming, CoWoS and SoIC, sidecar power systems, DC-DC conversion, liquid cooling and rack-scale systems. From 2027—2029, investors should look for multi-customer volume production of NPO, CPO, 800V architectures and larger packages. Native high-voltage DC, solid-state transformers and on-chip optics are more likely to become facility-level choices around 2030.
Agentic AI will increase demand for both CPUs and GPUs, but 1:1 is not a fixed formula. AMD has observed CPU-to-GPU ratios in some inference systems shifting from roughly 1:4 toward 1:1, while Arm believes certain agentic workloads could require 3—5 times more CPU capacity. Actual configurations will still depend on the model, concurrency, cache hit rates, number of tools and system efficiency.
Demand will benefit supply chains across Asia-Pacific, but earnings leverage will vary. TSMC and ASE Technology Holding must translate qualified capacity, yields and customer certifications into advanced-packaging revenue. Delta Electronics must substantiate its 800V and liquid-cooling opportunity through orders, installed capacity and operating efficiency. Hon Hai Precision, Quanta Computer, Wistron and Wiwynn must demonstrate that higher rack-level content can overcome working-capital pressure and convert into profit. ASPEED, King Slide and BizLink must show that attachment rates and per-system content gains are sustainable rather than one-off.
Every long-dated technology roadmap should be assessed against the same evidence ladder. Specifications and standards establish direction; samples and customer qualification demonstrate engineering feasibility. A technology enters the income statement only when orders and shipments become recurring and ultimately drive improvements in yield, gross margin and free cash flow.
Beyond GPUs, AI Factories Are Competing as Integrated Systems
The common message from the 2026 OCP Asia-Pacific Summit was that the competitive unit in AI infrastructure has expanded from the “chip” to the “AI factory.” UBS summarized presentations from AMD, Applied Materials, Arm, ASE Technology Holding, Broadcom, Google, Microsoft, NVIDIA, TSMC and suppliers of power systems, servers, optical interconnects and management chips. Despite their different positions in the stack, they identified remarkably similar constraints: as accelerator counts rise, data movement, power conversion, cooling, reliability and maintenance increasingly hold back system performance.
Microsoft estimated at the summit that global data-center capacity could increase from 70GW in 2024 to 400GW in 2030, with related investment exceeding US$1 trillion. This was a company presentation estimate, not contracted orders, but it illustrates the widening scope of capital expenditure. Customers must simultaneously procure CPUs, GPUs, custom ASICs, HBM, switching chips, optical components, advanced packaging, rack-level power systems, liquid-cooling equipment, telemetry and software controls. The longer procurement list is only the visible change: the real shift is that these components must be delivered as an integrated system. Best-in-class performance in one component does not necessarily produce the lowest cost per Token.
Systems competition also creates an easily overlooked tension: openness and vertical integration are advancing simultaneously. OCP promotes common interfaces to broaden supplier choice, shorten design cycles and reduce lock-in. At the same time, Google, Microsoft and NVIDIA are optimizing their workloads through proprietary chips, networks, racks and software. Open standards expand the market for compatible components but may also make generic hardware easier to replace. Vertical integration improves system efficiency but can compress supplier value into a small number of genuinely indispensable interfaces. A larger market does not automatically translate into greater pricing power for any individual company.
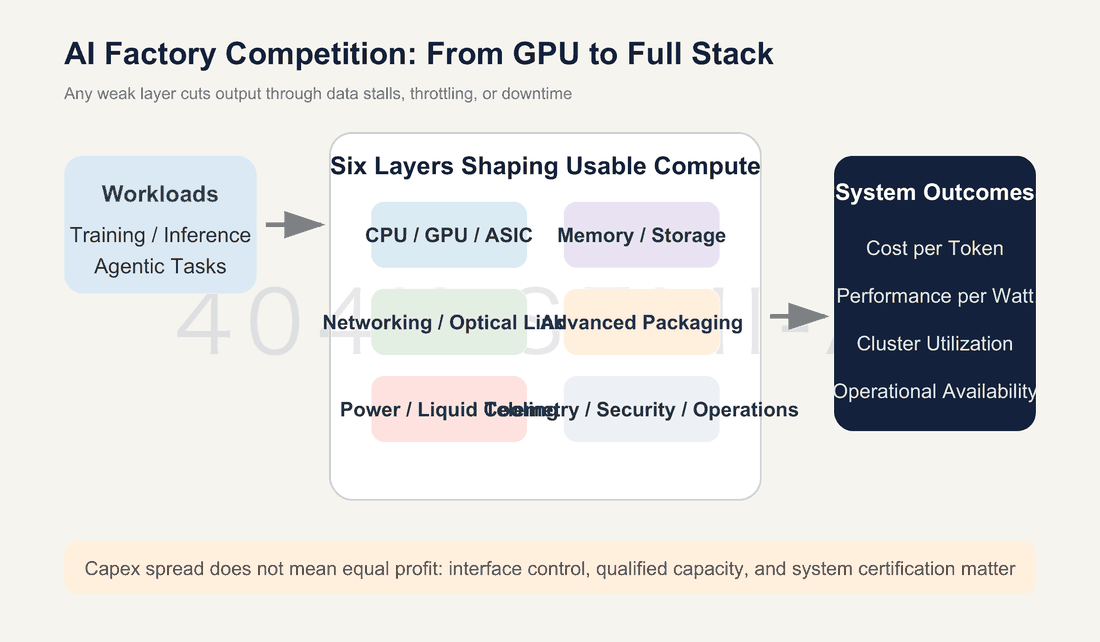
This shift will also redefine revenue recognition. Historically, once a high-end GPU was delivered, most of its standalone value was secured. In the systems era, value also depends on whether the customer can obtain all remaining components on schedule, complete data-center retrofits and pass stability acceptance testing. Suppliers involved in customer co-design, controlling critical interfaces and providing system-level validation generally have more durable revenue than vendors of interchangeable parts. For cloud providers, the relevant objective is to increase “usable compute,” not the nominal number of chips installed in the data center.
The full-stack system also includes an often-overlooked control and security layer. Baseboard management controllers (BMCs), data processors, telemetry, firmware security and hardware roots of trust detect failures, isolate anomalies, update firmware and support remote operations across tens of thousands of chips. ASPEED’s AST2700 series and open-platform root-of-trust roadmap, presented at the summit, point to higher attachment rates for management chips in high-end AI servers in 2027. However, this revenue opportunity still requires validation through design wins on leading platforms, per-system content and volume-production penetration; it cannot be extrapolated solely from server volumes.
Accordingly, this report divides evidence into four tiers: specifications and standards, samples and qualification, orders and shipments, and financial realization. Evidence from the later tiers provides stronger confirmation that the profit pool has shifted. Earlier-stage roadmaps should be treated only as future possibilities, not substitutes for evidence of current revenue.
Agentic AI Brings CPUs Back into the Core Expansion Cycle
Agentic AI turns inference from a single question-and-answer interaction into a continuous workflow. A task may begin with planning, access vector databases and external tools, invoke models across multiple rounds, save state and then verify the result. GPUs excel at massively parallel computation, but orchestration, retrieval, caching, I/O and control require CPUs, memory, networking and management systems to work together. AMD said at the summit that conventional inference environments use roughly 1 CPU server for every 4 GPU units, while emerging agentic infrastructure is moving toward approximately 1:1. Arm outlined a more aggressive scenario in which balancing agentic workloads could increase CPU requirements by 3—5 times.
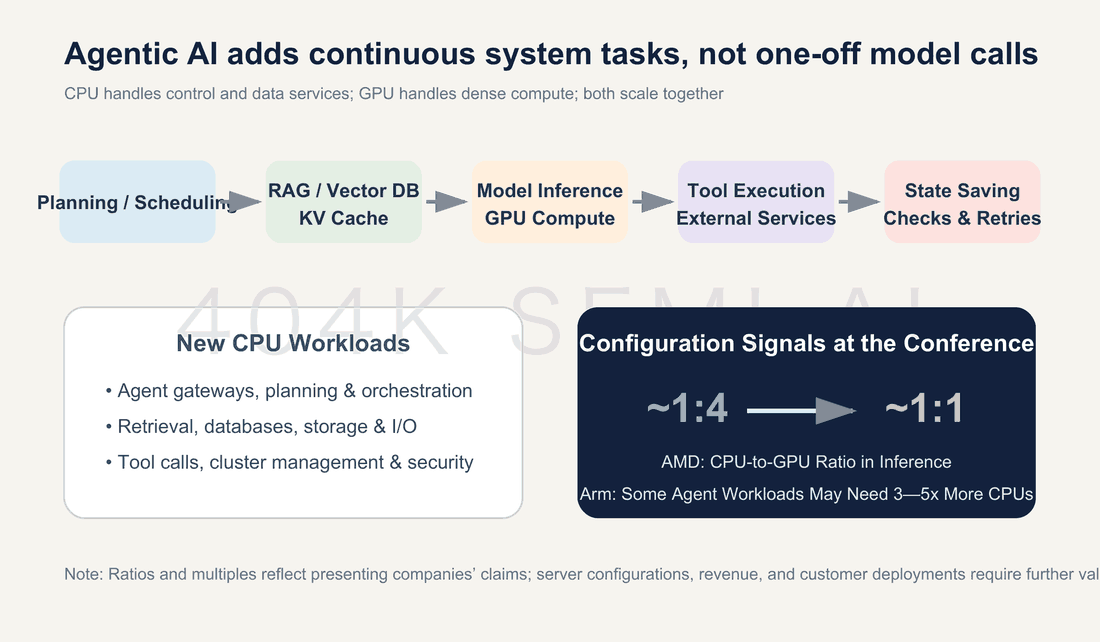
This shift does not imply lower GPU demand. As each agent uses more tools, processes longer contexts and executes more steps, both GPU computation and CPU control requirements may rise. Incremental CPU demand will be concentrated in agent gateways, planning and scheduling, retrieval-augmented generation, vector databases, KV caches, tool execution, storage and cluster management. Configurations originally designed for training clusters—with a small number of hosts supporting large numbers of GPUs—are adding dedicated CPU racks and more complex heterogeneous-computing layers.
Nor should 1:1 be treated as a fixed bill-of-materials ratio for every data center. Model size, context length, concurrency, number of tools, cache hit rates and CPU virtualization efficiency will all affect system configuration. More reliable validation would come from cloud providers consistently expanding CPU instances and agentic control planes, server vendors disclosing related platform revenue, and concurrent increases in system memory, storage and network usage. If higher CPU counts fail to improve end-to-end throughput, the additional hardware may simply become underutilized redundancy.
