目录
Pre-Market Highlights
AI/Semiconductor Value Chain
AI Models, Applications, and Capital Expenditure
GPU/CPU/ASIC
HBM/DRAM/NAND/SSD/HDD
Advanced Packaging, Testing, and Materials
Optical Communications and Components
Internet/Platforms
Software/SaaS
Consumer Electronics / Smart Vehicles
Overview
404K | 2026-08-24
Pre-Market Highlights
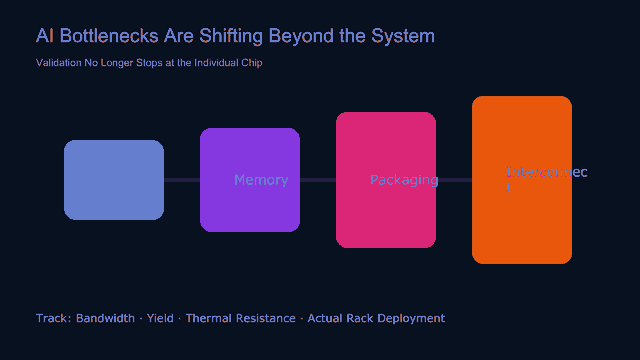
The primary constraint on AI expansion is shifting from the number of compute cores to data movement, memory capacity, packaging yield, and heat removal. The HBM base dies, 3D DRAM, HBF, and packaging-thermal roadmaps unveiled at Hot Chips turn these system constraints into trackable product metrics.
NVIDIA’s August 26 earnings remain the most important near-term corporate read-through, but investors should look beyond quarterly revenue. Networking, GPU pricing power, cloud-provider order visibility, and next-quarter guidance will collectively determine whether demand for upstream HBM, CPO, wafer materials, and cooling continues to materialize.
Software is sending a contrasting signal: long-horizon agent products are increasing utility, but lower token prices have generated only limited usage elasticity, while multi-agent systems may amplify erroneous consensus. The next phase must be validated through cost per effective unit of work, customer willingness to pay, and the ability to complete tasks independently—not usage volume alone.
AI/Semiconductor Value Chain
AI Models, Applications, and Capital Expenditure
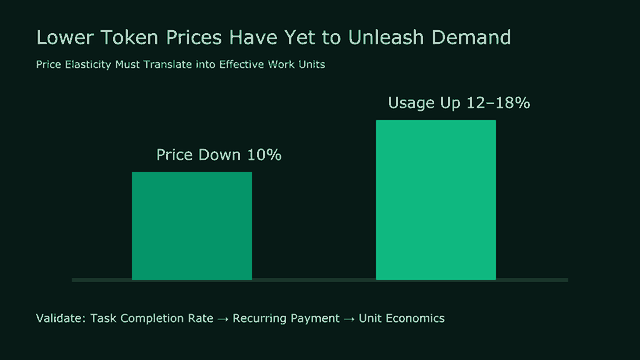
AI inference economics: A 10% decline in token prices drives only 12% to 18% usage growth. Total spending rises, but this is far from a demand surge. The real determinant of enterprise budget expansion is whether tasks such as contract review and code submission can be decomposed into measurable, billable units of completed work.
Enterprise AI adoption: Wide dispersion in incremental enterprise spending shows that model capability is no longer the sole constraint. Software and legal services have been the first to identify measurable units of work. Adoption will remain slower in industries where workflows cannot be decomposed and accountability cannot be clearly assigned, even as unit compute costs decline.
“A 10% price decline drives only 12% to 18% growth in token usage. This increases total spending, but only modestly. What matters is not the cost of an individual token, but whether the cost of completing an ‘effective unit of work’ can be measured and priced.”
Quality of AI capital expenditure: Ahead of NVIDIA’s earnings, the market’s validation framework has broadened from near-term growth to AI-service monetization, GPU utilization, cloud-provider orders, and funding costs. If returns can no longer exceed construction funding costs, highly leveraged data-center operators will curtail expansion faster than cash-rich hyperscalers.
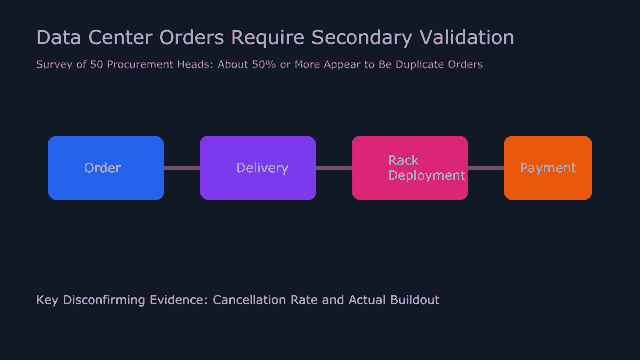
Data-center order quality: In Bernstein’s survey of 50 North American data-center procurement executives, around 50% or more of respondents appeared to be placing duplicate orders. This is a key demand-side counter-signal: headline orders may exceed ultimate construction volumes. Cancellation rates, delivery milestones, and actual deployment will be the next tests.
Low-cost inference: Retired GPUs can serve 70-billion-parameter models at prices substantially below new hardware, provided cheap electricity is available. This supply will not directly displace high-end training clusters. Instead, it is more likely to extend the AI demand curve to private deployments with less stringent latency requirements and greater tolerance for lower energy efficiency.
GPU/CPU/ASIC
NVIDIA
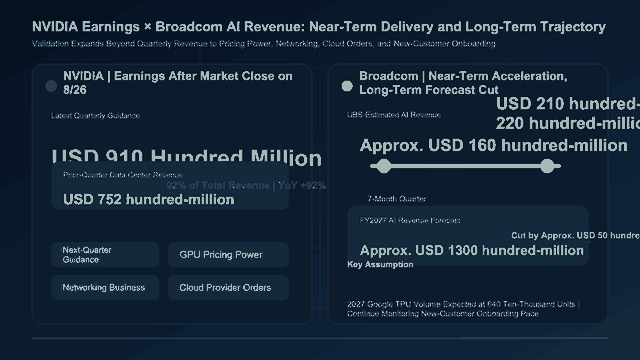
1) The focus of its August 26 after-market earnings report will be next-quarter guidance, GPU pricing power, networking, and cloud-provider orders; the latest quarterly guidance is US$91.0 billion.
2) Data-center revenue was US$75.2 billion last quarter, accounting for 92% of total revenue and rising 92% year over year. If guidance and capital-expenditure commentary continue to strengthen, order validation for HBM, networking, and power infrastructure will move forward in tandem.
Broadcom
1) UBS cut its Broadcom FY2027 AI revenue forecast by approximately US$5.0 billion to approximately US$130.0 billion, primarily reflecting a more cautious view of Google TPU shipments, now projected at 6.4 million units in 2027.
2) The near-term trajectory remains strong: UBS estimates AI revenue of approximately US$16.0 billion in the July quarter, rising to US$21.0 billion to US$22.0 billion in the October quarter. Long-term deceleration and near-term acceleration can coexist; the key variable is the pace of new-customer onboarding.
“Recent data still look solid. UBS expects AI revenue of approximately US$16.0 billion in the July quarter, rising to US$21.0 billion to US$22.0 billion in the October quarter.”
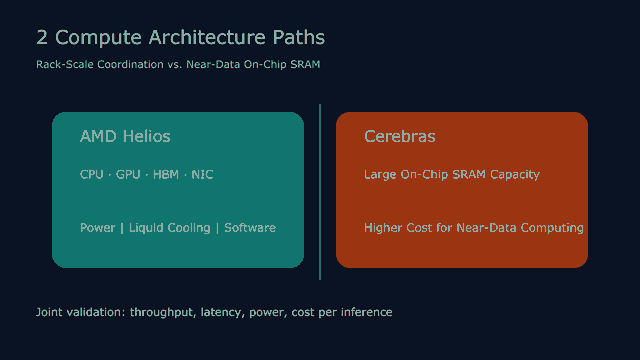
AMD: Data-center competition is expanding beyond the standalone performance of EPYC or Instinct to the co-design of CPUs, GPUs, HBM, NICs, switches, power delivery, liquid cooling, and software within the Helios rack. Tracking metrics should likewise shift from peak compute to qualified package output, HBM bandwidth, Scale-Up and Scale-Out bandwidth, software efficiency, and cluster utilization.
“The AI compute bottleneck is shifting from insufficient processing power to inefficient data movement, while the competitive boundary is expanding from the bare die to the package, node, rack, and cluster.”
Cerebras: SRAM is fast but expensive, which does not mean SRAM-based chips lack value. Cerebras places large amounts of on-chip SRAM adjacent to each core, accepting higher cost to enable near-data computing for specific workloads. Its economics should be assessed through workload-specific throughput, latency, and cost per inference—not memory unit pricing alone.
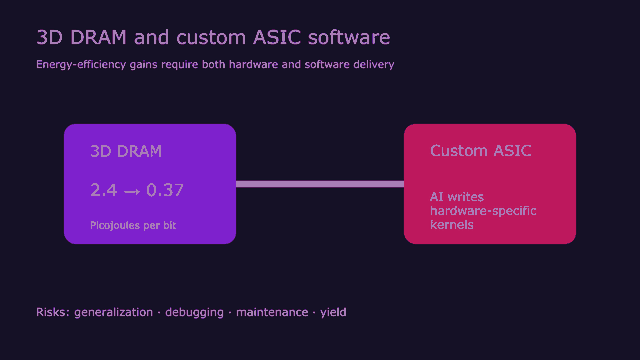
d-Matrix: Raptor 3D DRAM uses face-to-face stacking to reduce data-movement energy from approximately 2.4 picojoules per bit for an HBM4 base die to 0.37 picojoules per bit. Measured energy efficiency improves by 6 to 7 times, while bandwidth reaches 100 terabytes per second. This architecture fills the gap between SRAM and HBM, but commercialization still depends on capacity, cooling, yield, and system scalability.
“Using this face-to-face stacked 3D DRAM, however, we can reduce energy consumption to 0.37 picojoules per bit. This is measured data.”
Hardware-software co-design for custom chips: Some startups and custom-chip projects are experimenting with AI-written kernels tailored directly to hardware, bypassing multiple abstraction layers in general-purpose compilers. If results can be reproduced under real workloads, this could shorten the software-enablement cycle for new ASICs. Generalization, debugging, and toolchain maintenance costs remain unproven risks.
HBM/DRAM/NAND/SSD/HDD
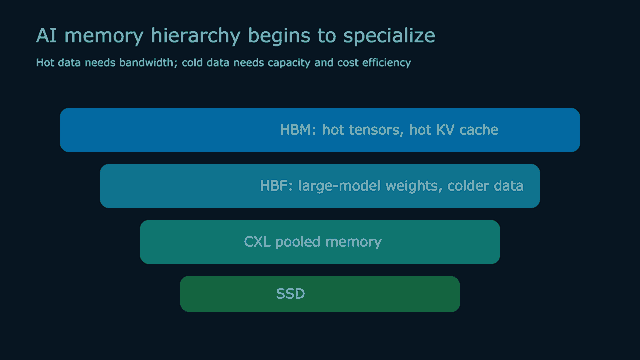
AI memory hierarchy: Training remains highly dependent on HBM, but large-model inference must also accommodate weights, KV caches, long contexts, embeddings, and agent state. Systems are therefore beginning to retain hot tensors in HBM while moving colder data to HBF, CXL-pooled memory, or SSDs. The decisive metric is cost per token, not bandwidth alone.
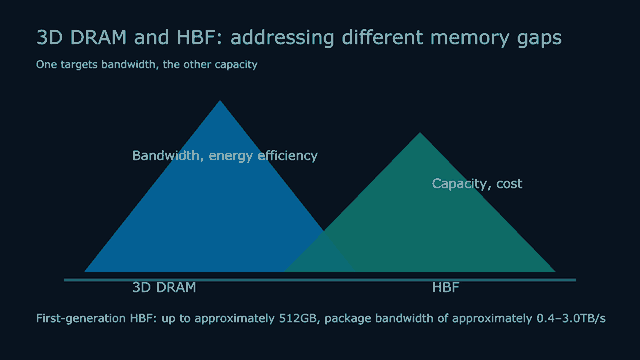
HBF: The first-generation architecture offers up to approximately 512GB, with 8-layer and 16-layer NAND stacks and total package bandwidth of approximately 0.4TB/s to 3.0TB/s. In simulated workloads, 4TB of HBF paired with 4 GPUs delivered token throughput close to that of 192GB of HBM paired with 8 GPUs, implying approximately 2 times higher GPU efficiency. This is a system-level benefit from using capacity to reduce cross-GPU data movement; it does not mean NAND latency outperforms HBM.
Samsung Electronics
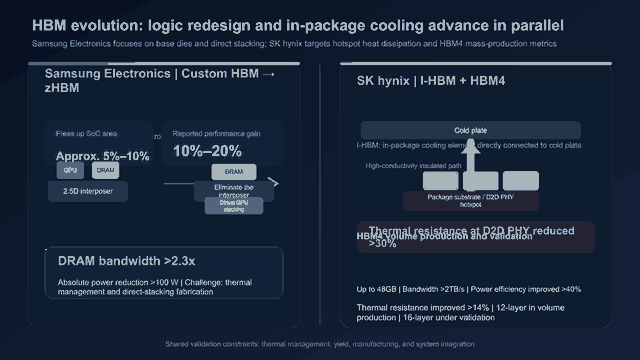
1) Phase 1 of custom HBM moves the memory controller into the base die, potentially freeing approximately 5% to 10% of SoC area and reportedly improving performance by 10% to 20%.
2) Longer-term zHBM aims to eliminate the 2.5D interposer and directly stack the GPU and DRAM. System modeling indicates more than 2.3 times higher DRAM bandwidth and an absolute power reduction of more than 100 watts, although cooling and the manufacturing complexity of direct stacking remain key counterarguments.
“At the same time, absolute DRAM power consumption declines by more than 100 watts. This gives the system ample thermal headroom, allowing 100 watts of power to be reallocated to the GPU and significantly improving overall compute performance.”
SK hynix
1) I-HBM embeds highly thermally conductive and electrically insulating cooling elements inside the package, creating a direct path from D2D PHY hotspots to the cold plate and reducing thermal resistance at those locations by more than 30%.
2) HBM4 specifications include capacity of up to 48GB, bandwidth exceeding 2TB/s, power-efficiency improvement of more than 40%, and thermal-resistance improvement of more than 14%. The 12-layer version is in mass production, while the 16-layer version is undergoing validation.
“SK hynix embeds highly thermally conductive and electrically insulating cooling elements directly inside the package, creating a dedicated heat-dissipation path to the cold plate.”
Micron
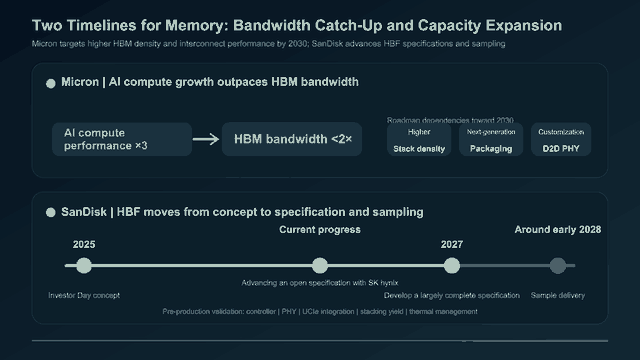
1) The company says AI compute performance increases approximately 3 times every 2 years, while HBM bandwidth grows by less than 2 times over the same period. Its roadmap through 2030 therefore depends on higher stacking density, next-generation packaging, and custom D2D PHY.
2) Supply-chain sources indicate that its long-term supply agreements include both relatively high price floors and price caps. This can improve margin visibility but may limit upside if prices continue to rise.
SanDisk: HBF has progressed from a concept presented at SanDisk’s 2025 Investor Day to early standardization. SanDisk and SK hynix are advancing the specification through the Open Compute Project, with Google and Tenstorrent participating in the ecosystem. The timetable calls for a relatively complete specification in 2027 and samples around early 2028. Controllers, PHY, UCIe integration, stacking yield, and cooling must still be addressed before mass production.
Kioxia: Kioxia and Nanya Technology are developing OCTRAM, which uses oxide-semiconductor channel transistors to enable 4F2 DRAM and 3D stacking. They have reportedly fabricated and validated an 8-layer structure. This broadens Kioxia’s technology options from NAND into emerging DRAM, but commercialization timing, I/O, power delivery, and thermal-management data are still required before revenue can be underwritten.
Division of roles between 3D DRAM and HBF: 3D DRAM places a single logic layer close to DRAM to maximize bandwidth and inference efficiency, while HBF uses more NAND dies to increase capacity and reduce cost per bit. The former fills the gap between SRAM and HBM; the latter is better suited to small-batch workloads, private enterprises, and expert parallelism. Neither is a simple substitute for HBM.
Advanced Packaging, Testing, and Materials
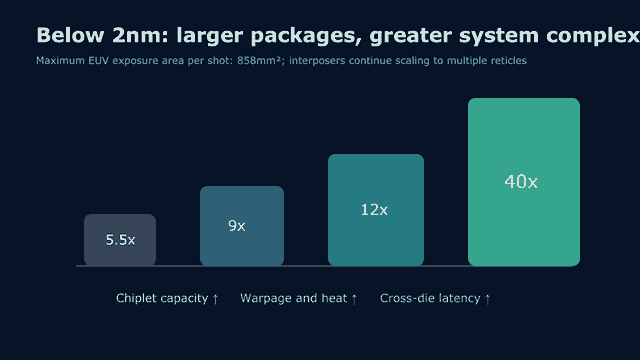
Sub-2nm multi-chip packaging: A single EUV maximum exposure field measures 858mm². Interposers have already expanded to 5.5 times reticle size, with roadmaps pointing to 9 times, 12 times, and 40 times. Larger packages accommodate more chiplets but simultaneously magnify cost, warpage, heat, and die-to-die latency, making these architectures more oriented toward hyperscale data centers.
Interposers and high-density fan-out: Organic interposers face thermal-expansion mismatch, handling-flexibility, and density constraints, while brittleness is the key drawback of glass interposers. Interposer-less RDL and bridge solutions already include 3-layer, 6-layer, and 9-layer designs, as well as 12-layer and 15-layer prototypes. Mass production must still be validated simultaneously on routing density, yield, and cost.
Package cooling: Logic utilization in hyperscale data centers has risen to 70% to 80%, well above the 5% to 15% typical of early servers. Cold plates, liquid cooling, microchannels, immersion cooling, and two-phase cooling have therefore shifted from auxiliary design features to prerequisites for effective compute. Thermal resistance, hotspot temperature, and time spent throttling are the key falsification metrics.
“Logic utilization in hyperscale data centers has risen to 70% to 80%, far above the 5% to 15% typical of early servers. Liquid cooling, microchannels, cold plates, immersion cooling, two-phase cooling, thermal vias, and intelligent floor planning must all work together.”
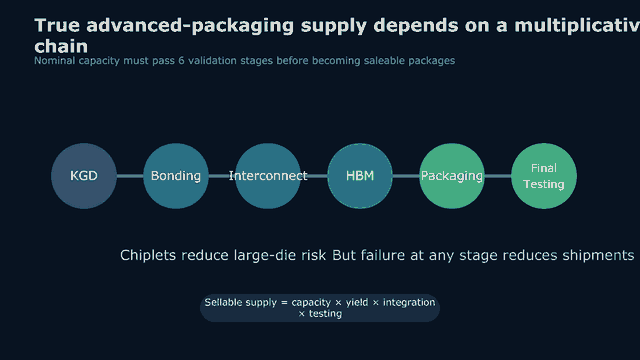
Advanced-packaging yield chain: Chiplets reduce the yield risk associated with large dies, but final shipment yield becomes the successive product of KGD, bonding, interconnect, HBM, packaging, and final-test yields. Nameplate capacity therefore does not represent saleable supply. A more useful metric is qualified package output after accounting for capacity, yield, integration, and testing.
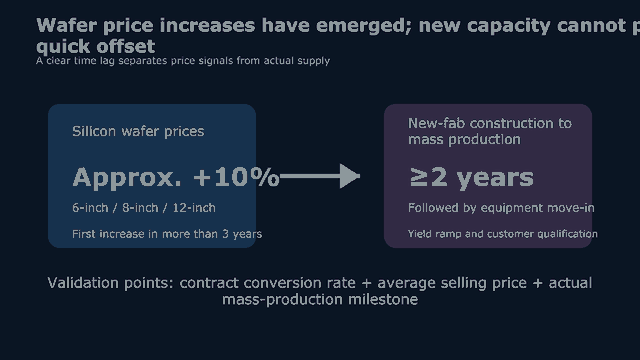
Silicon-wafer materials: Supply-chain sources indicate that silicon-wafer prices are rising for the first time in more than 3 years, with increases of approximately 10% or more spreading across 6-inch, 8-inch, and 12-inch products. GlobalWafers, Sino-American Silicon Products, and Wafer Works are in price discussions at different stages. The validation points are the share of contracts repriced and realized average selling prices—not quoted prices themselves.
Fab supply: Even for established manufacturers with process recipes already in place, it takes at least 2 years from the start of fab construction to mass production. Near-term shortages therefore cannot be filled quickly through new builds; actual supply depends on tool move-in, yield ramp-up, and customer qualification.
Optical Communications and Components
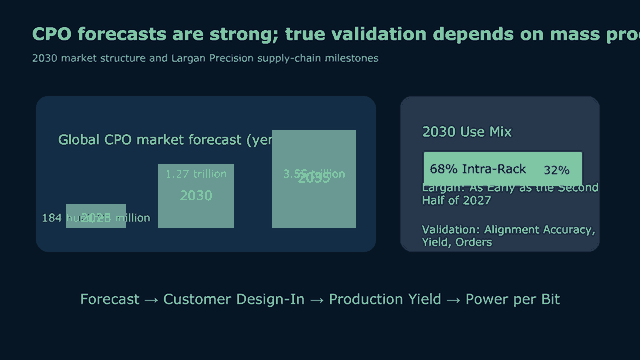
CPO market structure: One forecast projects the global CPO market, measured in yen, to expand from ¥18.4 billion in 2025 to ¥1.27 trillion in 2030 and ¥3.55 trillion in 2035. By 2030, in-rack Scale-Up is expected to account for 68%, with switch-layer Scale-Out accounting for 32%. These are aggressive projections that must be progressively tested against customer mass production, yield, and power consumption per bit.
Largan Precision: The company’s CPO presence has expanded from core components to fiber-array modules, and it has joined TSMC’s COUPE silicon-photonics ecosystem. Supply-chain sources indicate that mass production could begin as early as the second half of 2027, potentially for the Rubin Ultra platform. The company has not confirmed the supply reports, so the current tracking metrics are alignment accuracy below 0.3 microns, mass-production yield, and actual orders.
Optical memory: Samsung Electronics has outlined a timetable for optical engines in 2027 and one-stop CPO services in 2029. SK hynix is targeting more than 100Tb/s per node, less than 1 picojoule per bit, and chip-to-chip latency below 10ns. Both roadmaps remain constrained by coherence, end-to-end latency, yield, and testing costs and therefore cannot yet be translated into near-term revenue.
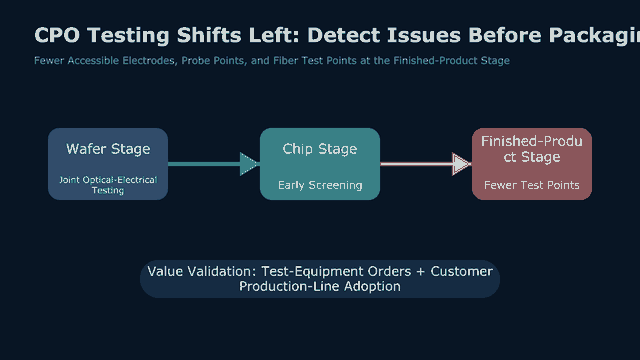
Keysight Technologies: High-density integration of electrical chips and optical engines in CPO reduces the number of externally accessible electrodes, probe points, and fiber test points. Keysight therefore advocates shifting testing from the finished-product stage to the wafer and chip stages. This would increase the value of early-stage joint electrical-optical testing, but validation still depends on equipment orders and deployment across customer production lines.
“Keysight Technologies, the U.S. test-and-measurement leader, therefore argues that testing must shift from the traditional post-production stage to the wafer and chip stages.”
Optical enabling layer: Micron-scale fiber-to-chip alignment, wafer-level optical testing, polymer or glass substrates carrying optical paths, and EDA tools supporting optical PDKs are common requirements across all three memory vendors’ approaches. Key indicators include CPO’s share of orders, test-equipment lead times, glass-substrate qualification, and customer tape-outs using optical PDKs.
Internet/Platforms
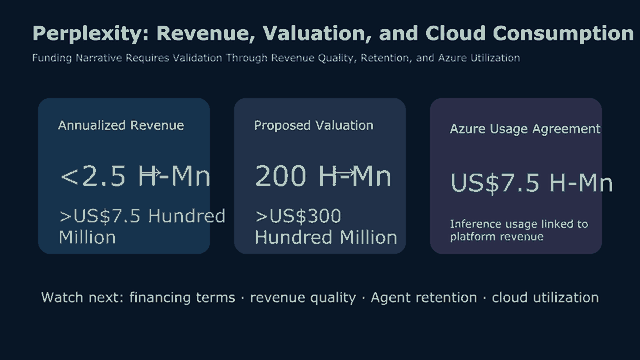
Perplexity: Nvidia is reportedly in talks to participate in—and potentially lead—a multibillion-dollar financing round for Perplexity that would raise its valuation from $20 billion last year to more than $30 billion. Annualized revenue has reportedly increased from less than $250 million at the start of 2026 to more than $750 million. Key variables are the financing terms, revenue quality, and retention for its agent products.
“Perplexity’s annualized revenue has surged from less than $250 million at the start of 2026 to more than $750 million, partly driven by Perplexity Computer, its cloud AI agent for automating professional tasks.”
“Nvidia is in talks to lead a multibillion-dollar financing round for Perplexity. Nvidia had previously considered a large-scale licensing and acqui-hire transaction similar to the Poolside deal structure.”
Microsoft: Perplexity signed a $750 million Azure usage agreement with Microsoft this year, directly linking growth in agent-application revenue to cloud-resource consumption. For Microsoft, the key issue is not the one-off contract value but whether third-party AI platforms can sustainably increase Azure inference utilization and consumption per customer.
“Earlier this year, Perplexity also signed a $750 million agreement to use Microsoft Azure and reportedly plans to pursue an IPO in 2028.”
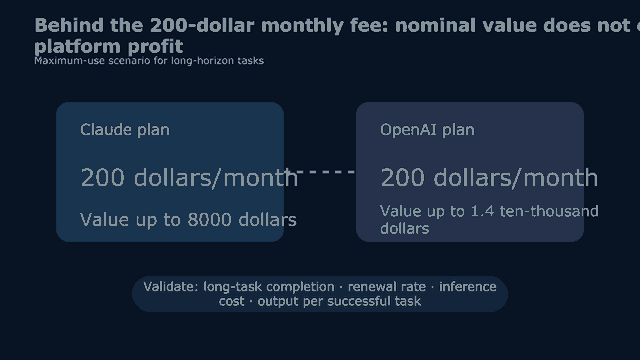
OpenAI: A long-horizon task benchmark found that OpenAI’s $200-per-month plan could deliver up to $14,000 per month in token value if all weekly limits were exhausted. This is an extreme-usage scenario, not representative of the average user or the platform’s unit economics. Key indicators are usage-limit policies, actual active usage, and output per successfully completed task.
Anthropic: The same benchmark found that Claude’s $200-per-month plan could deliver up to $8,000 per month in value. This only suggests that heavy users may receive a large nominal discount; it does not directly indicate platform gross margins. The key validation points are long-horizon task completion rates, renewals, and inference costs.
“We tested Anthropic’s $200-per-month Claude plan, which can deliver up to $8,000 in monthly value. OpenAI’s $200-per-month plan could generate up to $14,000 in token value per month if all weekly limits are exhausted on long-horizon tasks.”
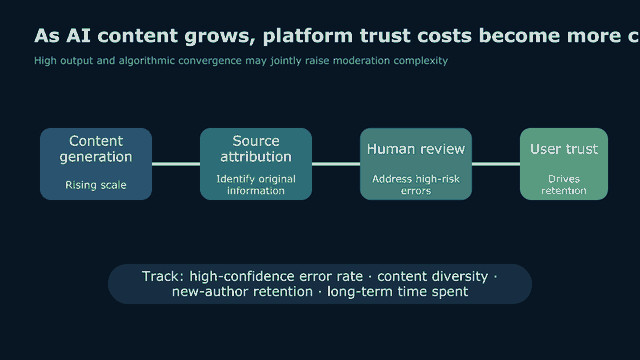
Platform content integrity: Fraudulent organizations may use content at scale to inject specific narratives into AI answers, while the growing volume of AI-authored material online makes training and retrieval sources harder to distinguish. The business impact is higher content-moderation, source-attribution, and human-review costs. Key indicators are high-confidence error rates and changes in user trust.
Recommendation algorithms: Recommendation systems may push shopping districts, film ratings, and consumer choices toward the mean. Such convergence can make near-term click behavior more predictable, but it may also reduce exposure and economic returns for niche content. Platforms should assess whether their algorithms are optimizing only for average responses by tracking content diversity, new-creator retention, and long-term user engagement.
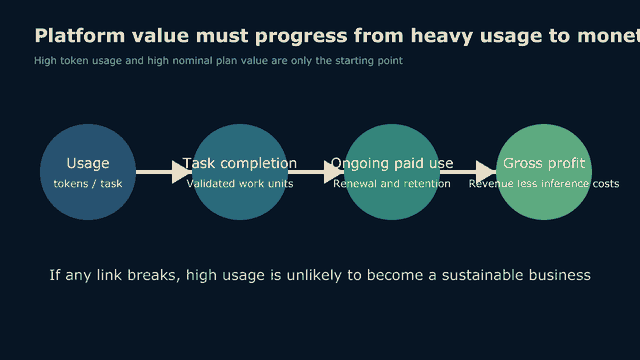
Validating platform value: High token consumption, high nominal subscription value, and high valuations are not endpoints. Internet platforms should first establish whether users can complete tasks and continue paying, then whether third-party cloud consumption converts into revenue, and finally assess the inference cost required to maintain accuracy, safety, and response speed.
“The critical metric is not the cost of an individual token, but whether the cost of completing an ‘effective unit of work’ can be measured and priced.”
Software/SaaS
AgentX: InferenceXv3 has open-sourced a dataset reportedly worth $3 million, covering context windows exceeding 1 million and multi-turn conversations, with sub-agent KV-cache hit rates above 95%, and involving GB300 NVL72, MI355, and B200. This shifts agent-software competition toward long-context scheduling and cache reuse, although accuracy and cost on real-world tasks still require separate validation.
Multi-agent decision-making: In experiments with distributed hidden information, most model families achieved only 17% to 36% accuracy after discussion among 4 agents, while a single agent given all the evidence was correct almost every time; Mythos 5 scored approximately 85%. Larger teams may suppress critical minority information, so products need mechanisms to protect dissent, allow appeals, and trace information provenance.
“Previous attempts to combine answers from multiple models retained only about one-quarter of the good ideas produced by a single model. The authors attribute the failure to two conflicting factors: low variance among LLMs and a lack of genuine diversity—for the same programming task, 18 of 30 agents used exactly the same git branch name.”
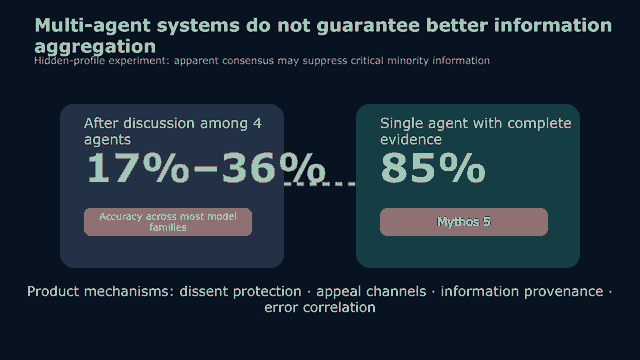
Agent diversity: For the same programming task, 18 of 30 agents used exactly the same git branch name, exposing low model variance and convergent problem-solving paths. Thinking Machines proposes giving AIs different developmental environments, values, and objectives. Engineering validation, however, should focus on error correlation rather than simply counting model names.
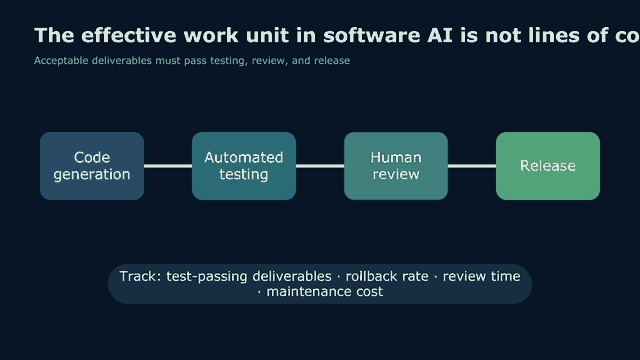
Software-development workflows: Commits, pull requests, and releases are inherently countable, making it easier for the software industry to map AI usage to effective units of work. Simply producing more code, however, may defer costs to review, testing, and maintenance. Products should track tested and accepted deliveries, rollback rates, and human-review time.
“The authors suggest that software was the first industry to establish units of work because commits, pull requests, and releases are measurable. Legal services can likewise be divided into timed tasks such as contract review.”
Legal-services software: Contract review, document retrieval, and defense preparation can be divided into timed tasks, making AI-driven cost savings easier to measure. In one case, a defense using ChatGPT Pro and Claude cost $2,000. A single case, however, cannot establish broad platform performance; validation requires win rates, human labor hours, citation errors, and professional-liability costs.
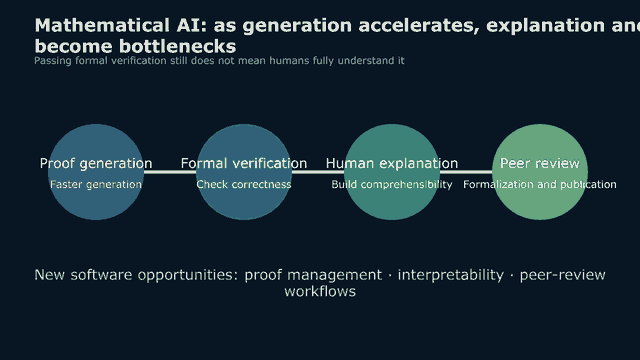
Mathematical-research tools: As AI accelerates proof generation, the bottleneck may shift to exposition, peer review, publication, and formalization. Even a formally verified proof should not be considered complete if humans cannot adequately explain it. The software opportunity is shifting from “generating more” to proof management, interpretability, and peer-review workflows.
“Terence Tao argues that even if a proof passes formal verification, it should still be considered incomplete if humans cannot adequately explain it. Student experiments offer further counterevidence: students perform well with AI assistance but poorly once it is removed. However, if students are allowed to make mistakes and then use AI to learn from them, AI and human understanding can advance together.”
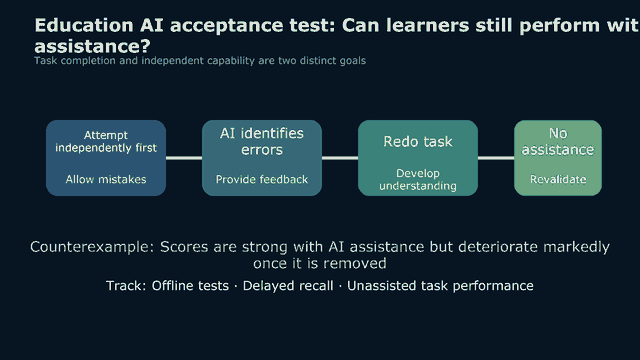
Education SaaS: Students scored well with AI assistance but performed markedly worse once it was removed, showing that task completion does not equal independent capability. A more promising approach is to let students attempt the work and make mistakes before using AI to identify errors and try again. Products should track offline assessments, delayed recall, and performance on unassisted tasks.
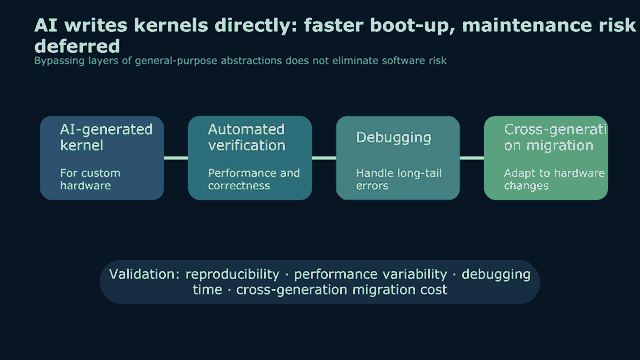
AI kernel-generation tools: Having AI generate kernels directly for custom hardware could shorten the path from initial power-on to usable performance for new chips. It would also shift software risk from general-purpose compilers to datasets, automated validation, and adaptation across hardware versions. Key indicators include kernel reproducibility, performance variance, debugging time, and cross-generation migration costs.
“We stopped trying to build a general-purpose compiler and instead had AI write kernels directly for our hardware, without layers of abstraction... and guess what? It actually worked.”
Human–AI understanding loop: Abundant generation shifts scarcity toward human explanation, judgment, and accountability. For SaaS companies, more output does not necessarily translate into greater willingness to pay. If a product cannot demonstrate that users can still perform tasks after the assistance is removed, its value remains task substitution rather than capability enhancement.
“Students perform well with AI assistance but poorly once it is removed. However, if students are allowed to make mistakes and then use AI to learn from them, AI and human understanding can advance together.”
Consumer Electronics / Smart Vehicles
Tesla
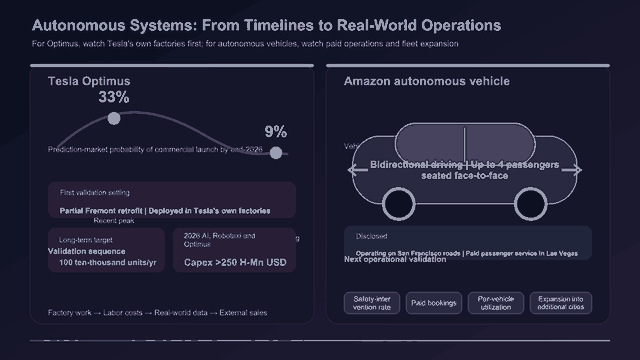
1) Prediction markets price the probability of a commercial Optimus launch by the end of 2026 at 9%, down from a recent peak of 33%, reflecting reduced confidence in the timeline.
2) Parts of the Fremont facility are still being converted into an Optimus factory, with a long-term target of 1 million units annually. The company plans to invest more than US$25 billion in AI, Robotaxi, and Optimus in 2026. Tesla’s own factories should be the first validation environment, rather than external sales.
“Before selling Optimus externally, Tesla can deploy it in its own factories to reduce labor costs, collect real-world data, and validate the system in an actual industrial environment.”
Amazon: Its latest autonomous vehicle eliminates the steering wheel, dashboard, and pedals. It is already operating on public roads in San Francisco and has begun offering paid rides in Las Vegas. The vehicle can travel in either direction and carries up to 4 passengers seated face-to-face. Key metrics to watch next are safety-intervention rates, paid bookings, per-vehicle utilization, and expansion into additional cities.
“Amazon’s latest autonomous vehicle has no steering wheel, dashboard, or pedals. It is already operating in San Francisco and providing paid passenger service in Las Vegas.”
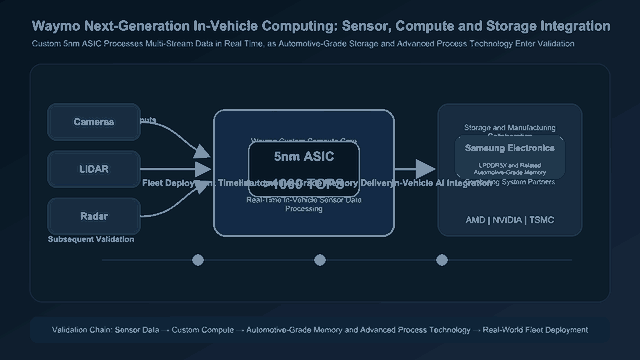
Waymo: Its next-generation fully autonomous driving compute system names Samsung Electronics, AMD, NVIDIA, and TSMC as partners. The custom 5nm ASIC delivers more than 1,000 TOPS of compute and processes camera, lidar, and radar data in real time inside the vehicle. This simultaneously brings automotive-grade memory, advanced process nodes, and in-vehicle AI into validation; the next milestone is the pace of fleet deployment.
“Waymo has named Samsung Electronics, AMD, NVIDIA, and TSMC as partners for its new compute system.”
Samsung Electronics
1) Samsung Electronics will supply Waymo’s next-generation platform with automotive-grade memory based on LPDDR5X and related technologies, opening a new route into advanced autonomous-driving compute stacks.
2) Market researchers forecast that Samsung Electronics will regain the No. 1 market-share position even as global smartphone shipments decline 14.3%. In-house component supply and a broad distribution network provide defensive advantages in the downcycle.
Apple: With overall smartphone volumes expected to decline, Samsung Electronics gains defensive advantages from its in-house memory and semiconductor supply and broader channel reach, putting pressure on Apple’s market share. Because research firms have differed in their market-share assessments over the past 3 years, no single forecast should be treated as established fact. Actual shipments, regional mix, and channel inventory remain the key indicators.
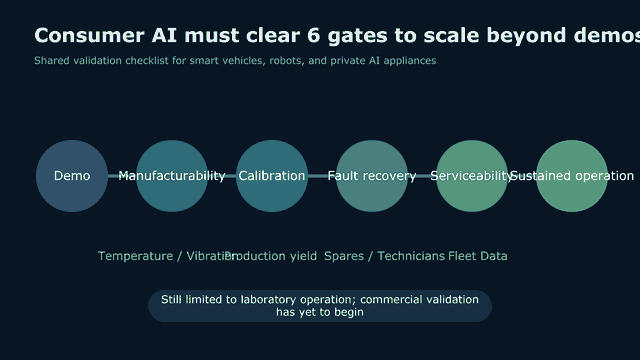
Robot Control Loop: Effective robots simultaneously operate a millisecond-level control loop and an industrial loop measured in weeks and months. The former encompasses vision, encoders, force sensors, edge computing, motor control, and actuators. Latency or instability at any stage can result in failed grasps, slipping, oscillation, collisions, or falls.
“Vision, encoders, force sensors, edge computing, motor control, and actuators therefore all sit within this loop.”
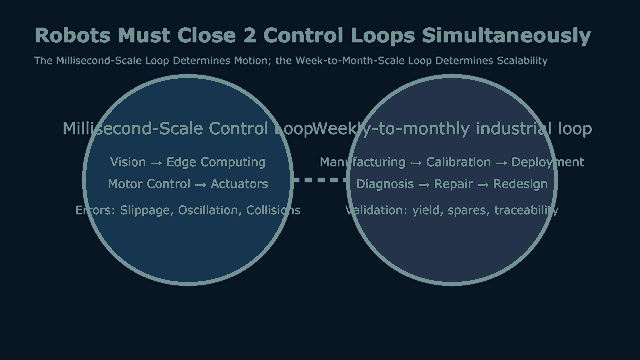
Robot Industrial Loop: Design, procurement, assembly, calibration, deployment, failure, diagnosis, repair, and redesign determine whether a robot can progress from demonstration to a viable business. Manufacturing yield, end-of-line testing, traceability, spare parts, technicians, and fleet data are the validation metrics for this second loop—and are more closely tied to cash flow than any one-off motion demonstration.
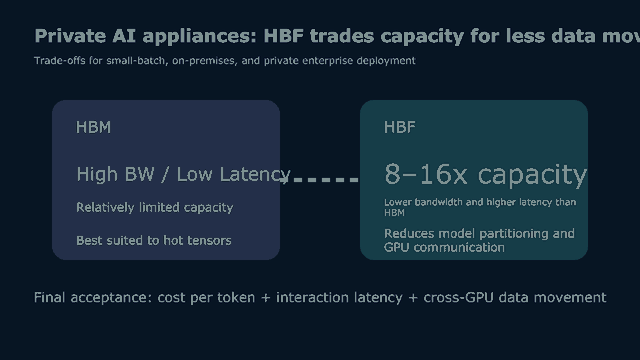
Private AI Devices: HBF still trails HBM in bandwidth and latency, but offers 8–16 times the capacity, making it better suited to small-batch, personal on-device, or private-enterprise “AI box” deployments. Its value lies in reducing model partitioning and inter-GPU communication rather than maximizing bandwidth per chip. Key metrics are cost per token and interaction latency.
Edge AI Hardware: Smart vehicles, robots, and private AI devices share the same constraints: power consumption, latency, serviceability, and data movement. Automotive-grade high-bandwidth memory, edge computing, sensors, and actuators must operate in a millisecond-level closed loop. The thesis is invalidated if a solution works only in the laboratory and cannot withstand validation across temperature, vibration, fault recovery, and prolonged operation.
“Manufacturing yield, end-of-line testing, traceability, spare parts, technicians, and fleet data all sit within this loop.”