
目录
Overall Weekly View
Cloud Revenue and AI Capital Expenditure
Data Centers, Compute Procurement, and Custom Silicon
Models, Software, and Application Monetization
Diverging Models: M7 vs. Neocloud Providers
Divergent Views, Disconfirming Evidence, and Next Week’s Watchlist
AI compute demand continues to spread from hyperscalers to neoclouds, with Amazon AWS placing a major incremental GPU order as Google improves TPU energy efficiency. The investment stance remains bullish, but cash conversion, guarantee exposure, and power delivery have become more important validation points.
Overall Weekly View
The most important development this week is that demand for AI infrastructure has not contracted as in-house chip development accelerates. Instead, it is expanding along two tracks. Amazon AWS plans to deploy approximately 2 million additional NVIDIA GPUs in 2027–2028, while Google continues to specialize TPUs for training and inference and scale up its clusters. Cloud providers want both the time-to-market of general-purpose GPUs and the unit economics of proprietary silicon, shifting procurement from an either-or decision to a dual-track strategy.
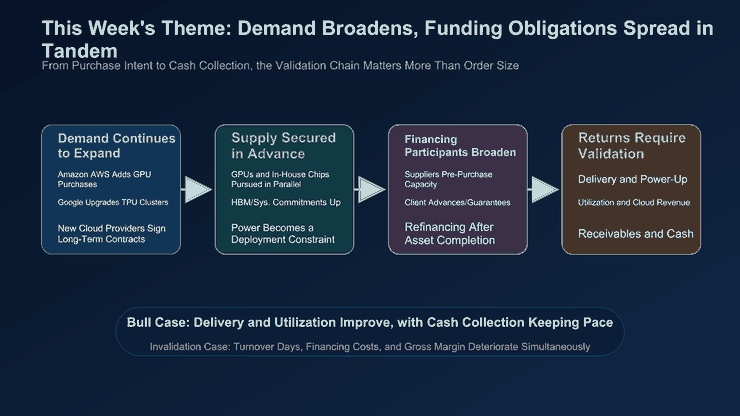
The two procurement tracks serve different business objectives. Proprietary chips give cloud providers control over silicon costs, software orchestration, and power efficiency, while externally sourced GPUs provide a mature development environment, early access to advanced products, and broader customer reach. As long as model iteration remains rapid, cloud providers are unlikely to commit all demand to a single architecture. For investors, actual share shifts should be measured by how much power each chip category consumes and how many paid workloads it runs—not procurement announcements alone.
Supplier-side demand indicators remain very strong. NVIDIA reported FY2027 Q2 revenue of $96.2 billion, including $89.0 billion from Data Center. Hyperscale customers contributed $48.7 billion, while ACIE—AI cloud, industrial, enterprise, and sovereign customers—contributed $40.3 billion. ACIE revenue grew 138% year over year and 25% sequentially, reaching 83% of the hyperscale business. This shows that incremental demand no longer depends solely on a handful of large cloud providers, but it also warrants caution: customer classifications are becoming less distinct, so supplier segmentation should not be treated as a direct proxy for individual cloud providers’ revenue.
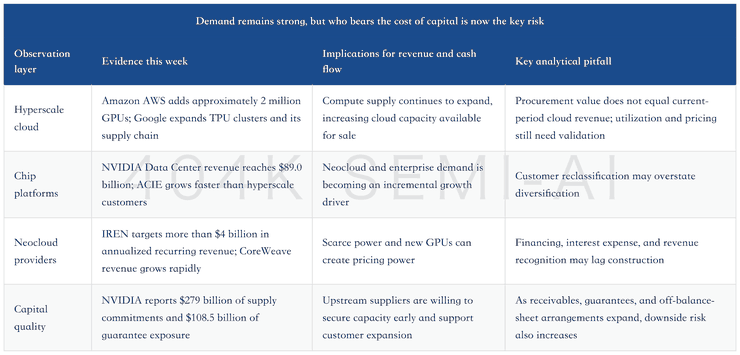
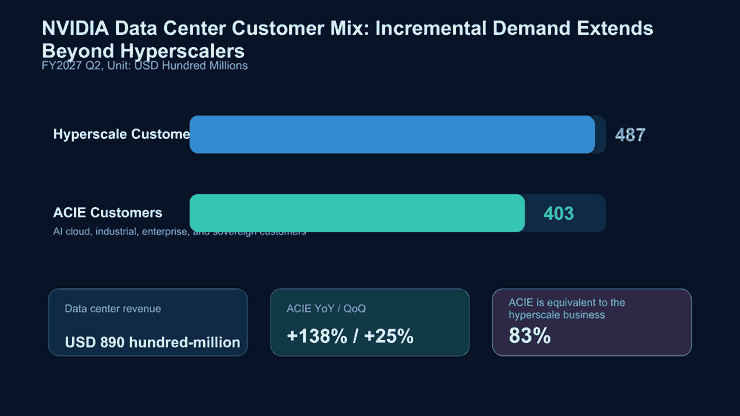
Customer reclassification deserves particular scrutiny. One AI cloud customer was moved into the hyperscale category this quarter following a change in its business model, illustrating how the boundary between neoclouds and traditional CSPs shifts with customer scale and business mix. A lower hyperscale share does not necessarily indicate a genuine decline in concentration, while a higher ACIE share does not necessarily come entirely from new customers. Investors should track the largest end customers, tenant concentration at cloud providers, and accounts-receivable quality together.
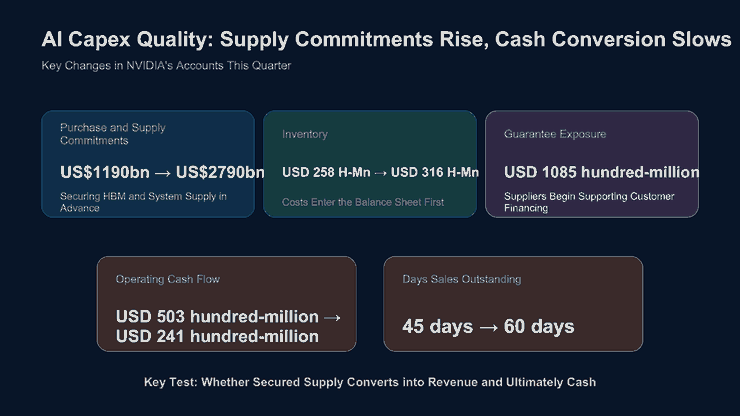
AI capital expenditure should still be viewed as an expansion cycle rather than one that has already peaked. However, the counterevidence is now more concrete: NVIDIA’s operating cash flow fell sequentially from $50.3 billion to $24.1 billion, accounts receivable rose to $63.1 billion, and days sales outstanding lengthened from 45 days to 60 days. Neocloud providers, meanwhile, increasingly rely on customer prepayments, GPU financing, and asset refinancing. Looking only at orders overstates quality, while focusing only on debt understates the acceleration in underlying demand. Procurement, delivery, deployment, utilization, revenue, and cash collection now need to be verified sequentially.
Cloud Revenue and AI Capital Expenditure
There were no new like-for-like quarterly disclosures for M7 cloud revenue this week, so NVIDIA sales cannot be used as a proxy for revenue at Amazon AWS, Microsoft Azure, or Google Cloud. What can be confirmed is that cloud providers’ procurement appetite and supply readiness continue to strengthen. NVIDIA Data Center revenue grew 117% year over year, while FY2027 Q3 total revenue guidance is $108.0 billion, plus or minus 2%. These figures support continued growth in cloud capacity available for sale, but the ultimate conversion into cloud revenue will depend on customer deployment speed, hourly pricing, and inference utilization.
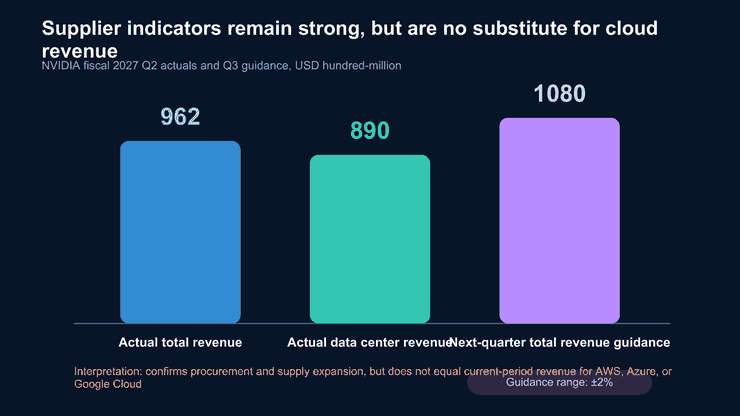
Cloud revenue typically appears at least two operating stages after chip orders. Equipment first enters construction in progress or fixed assets. Only after power-up, networking, and software acceptance does it become a saleable instance, after which customers must migrate workloads and raise utilization. Capital expenditure and depreciation appear first during construction; revenue and gross-margin improvement follow later. Mapping a supplier’s current-quarter revenue directly onto current-quarter cloud growth will therefore distort both timing and margins.
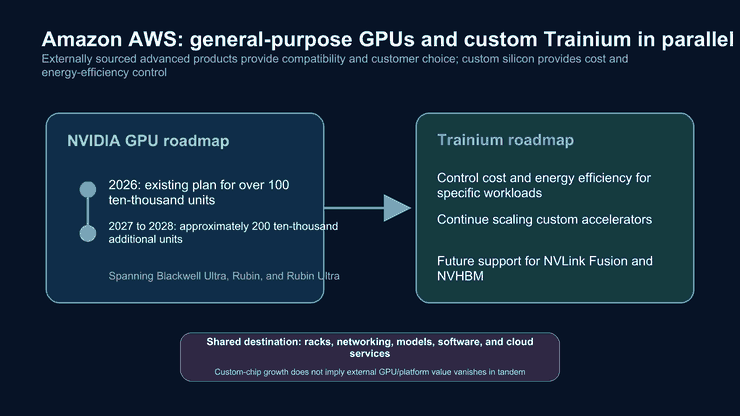
Amazon AWS has taken the clearest action. Its approximately 2 million additional GPUs span Blackwell Ultra, Rubin, and Rubin Ultra and are separate from the existing plan to deploy more than 1 million GPUs beginning in 2026. Amazon AWS is also continuing to invest in Trainium. This combination suggests that proprietary silicon primarily addresses controllable costs, energy efficiency, and specific workloads, while NVIDIA GPUs provide model compatibility, early access to advanced products, and customer choice. The two are likely to coexist for a considerable period.
Capital-expenditure pressure has not disappeared; it is simply being distributed across more parties. NVIDIA inventory rose from $25.8 billion to $31.6 billion, while purchase and supply commitments increased from $119.0 billion to $279.0 billion, primarily to secure HBM and system supply. Suppliers’ advance capacity purchases can shorten cloud providers’ lead times for complete racks, but they also expose upstream vendors to inventory, gross-margin, and customer-performance risk. NVIDIA’s next-quarter gross-margin guidance of 74.0%, down 1 percentage point from this quarter, is one indication that costs are being recognized before the related revenue is realized.
Cash flow is a better indicator of cycle quality than procurement value. NVIDIA’s days sales outstanding lengthened to 60 days this quarter, while the company disclosed $108.5 billion of guarantee exposure. Operating cash flow remained positive but declined sharply sequentially. If cloud providers and model developers secure longer payment terms, suppliers may recognize revenue well before collecting cash. Over the next quarter, investors should monitor NVIDIA’s accounts receivable, cloud providers’ free cash flow, and neocloud financing rates together. Only a concurrent deterioration across all three would constitute firm evidence that capital-expenditure intensity needs to be revised downward.
This expansion cycle differs in another respect: the financing entity is no longer limited to the end cloud provider. Chip suppliers pre-purchase HBM and system capacity, model developers sign multiyear leases, neocloud providers obtain customer prepayments and equipment financing, and completed infrastructure assets are subsequently refinanced on a long-term basis. Each layer can accelerate construction, but it can also cause the same end demand to appear in the commitments and contracts of multiple entities. These figures therefore cannot simply be added to estimate total demand, nor can risk be assessed solely from any one company’s reported debt.
Returns on capital should ultimately be tested against unit economics. Cloud providers must demonstrate higher revenue per unit of power and rack capacity; chip suppliers must show that securing supply does not continuously depress gross margins; and neocloud providers must prove that cash generated by long-term contracts can cover interest and maintenance capital expenditure. If any layer depends on another financing round to fill the cash shortfall from existing projects, the quality of growth will deteriorate.
Data Centers, Compute Procurement, and Custom Silicon
The unit of competition in data centers has shifted from individual chips to complete systems delivered on schedule. Customers are buying usable training throughput, inference capacity, and reliability within a fixed power budget. A delay in any component—GPU, HBM, networking, power, cooling, or rack delivery—prevents contracted compute capacity from generating revenue. Amazon AWS is therefore purchasing at significant scale, but its actual contribution in 2027–2028 must still be recognized progressively as capacity is installed, energized, and utilized by customers.
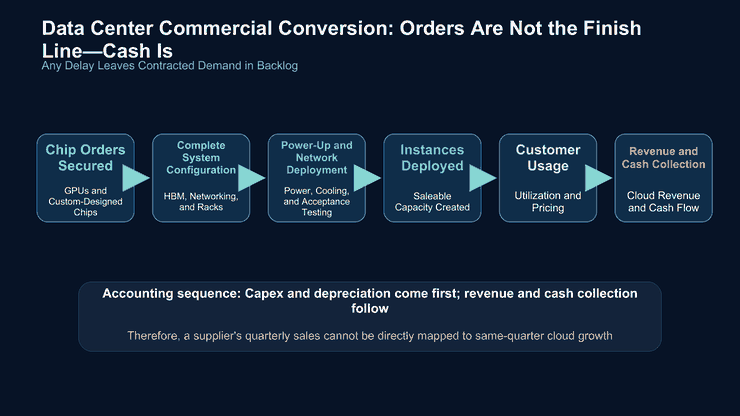
In this chain, chips are typically secured first, but their revenue impact materializes last. HBM and networking components determine whether complete racks can be delivered; substations and grid-connection quotas determine whether equipment can operate; and software orchestration determines whether expensive compute capacity can sustain high utilization. Any delay leaves orders in backlog. Rising supply commitments indicate management’s willingness to bet on future demand, but do not by themselves prove that data centers are already generating sustainable cash flow.
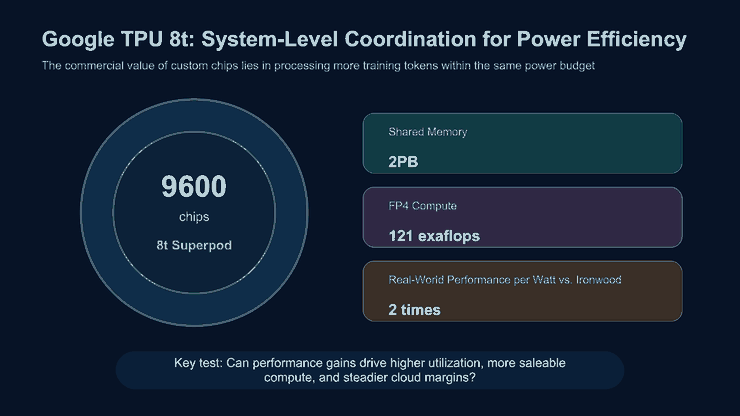
Google’s TPU 8t addresses the costliest constraint: power. The disclosed 8t Superpod contains 9600 chips, accesses 2PB of shared memory, and delivers 121 exaflops of FP4 compute. Its real-world performance per watt is 2 times that of Ironwood. In commercial terms, the same gigawatt-scale data center can process more training tokens, allowing Google either to perform the same work with less power and fewer racks or to sell more compute within the same budget.
The next-generation TPU v10 supply chain is evolving toward multiple suppliers and more complex packaging. MediaTek continues to handle the I/O chiplet and system integration, while other design-service providers may participate in selected modules. For Google, a multi-supplier structure reduces single-point risk and makes it easier to scale custom-silicon production in line with data-center deployment. For external suppliers, share of an individual chip may fragment, but the value attached to I/O, HBM, packaging, and interconnects should rise with system complexity.
Custom silicon has not displaced Nvidia from cloud-provider racks. Amazon AWS plans to add NVLink Fusion and NVHBM support to future Trainium generations while also procuring Nvidia CPUs, networking, models, and software. Nvidia also plans to deliver Vera Rubin to Google Cloud, Microsoft Azure, Oracle, and Nebius. Competition is intensifying at the chip level even as cooperation expands across racks, interconnects, and software. Nvidia must defend its GPU share, but whether the rest of the system continues to be built around its interfaces will matter even more for the value of its platform.
Apple is pursuing a more closed architecture. One engineering assessment indicates that M5 is entering Private Cloud Compute servers in serviceable modular form, with unified memory and lower power consumption used primarily for Apple’s internal inference workloads. The design still appears closer to engineering validation or early production and does not support conclusions about large-scale training capacity or external cloud revenue. The investment implication is narrower: M7 companies that control devices, chips, and service distribution can retain part of their inference workloads within their own ecosystems, reducing incremental purchases from external clouds.
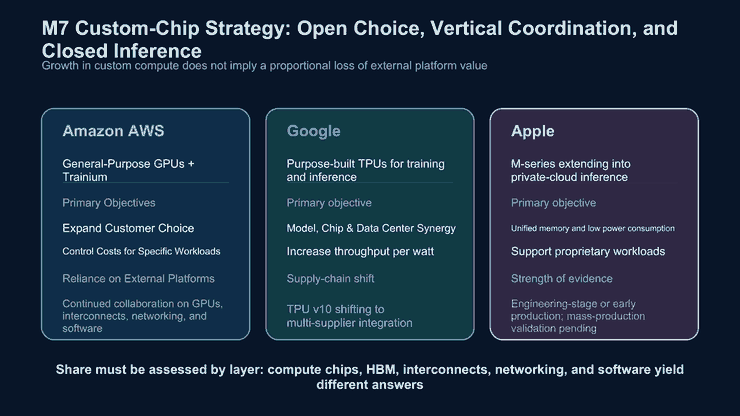
The 3 strategies represent 3 distinct moats. Amazon AWS emphasizes customer choice between general-purpose GPUs and Trainium; Google emphasizes coordination across models, chips, and data centers; and Apple emphasizes devices, unified memory, and private-cloud security. All 3 reduce dependence on any single external chip supplier, but differ in openness. General-purpose GPUs retain an advantage when cloud customers need portability across models and mature software. Custom silicon becomes more economical as workloads grow larger and more stable, allowing development costs to be amortized more effectively.
Supplier share should also be assessed by layer. Even if custom compute chips gain share, HBM, interconnects, networking, packaging, and system software may still come from external platforms. Nvidia’s expanding collaboration with Amazon AWS across these layers shows that lower GPU share does not necessarily translate into a proportional decline in platform revenue. Platform value would come under genuine pressure only if cloud providers progressively replace its interconnect and software interfaces.
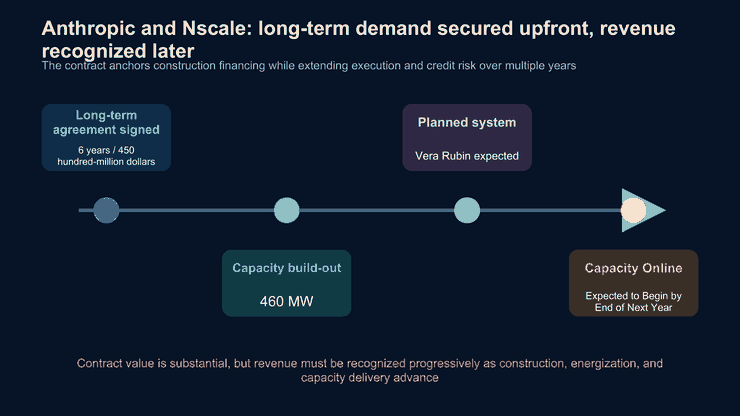
Power remains the final gate to system deployment. Anthropic has reportedly signed a 6-year, US$45 billion compute agreement with Nscale covering 460 MW of power capacity, expected to use Vera Rubin and begin coming online by the end of next year. Such long-term contracts support data-center financing and lock in demand for longer, but construction delays, changes in model economics, and customer credit risk accumulate over a multiyear term. The contract value is substantial, but revenue can only be recognized progressively as capacity comes online.
Models, Software, and Application Monetization
This week’s developments show further divergence in monetization models, but no new revenue figures that can be compared directly across the M7. Amazon AWS is bundling GPUs, Vera CPUs, Spectrum networking, Nemotron models, and CUDA-X libraries, while extending the stack into Amazon’s robotics operations. It sells both compute time and an end-to-end deployment stack spanning models and physical workloads. When customers use networking, storage, models, and operations services on the same cloud, each AI workload generates more cloud revenue than a bare-GPU rental.
Meta is placing greater emphasis on the consumer-relationship layer. One member of its superintelligence lab has argued that model recipes may converge, leaving data collection, reward systems, compute, and consumer distribution as the main sources of differentiation. This should be treated only as a strategic signal, not as formal company guidance. It suggests that Meta is more likely to monetize its investment first through advertising, recommendations, and consumer products than through standalone cloud-computing sales. The key question is whether AI features improve advertising conversion, engagement time, and revenue per unit of compute.
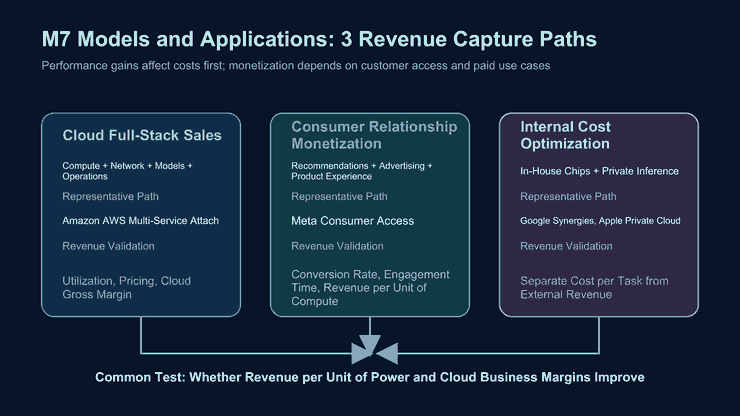
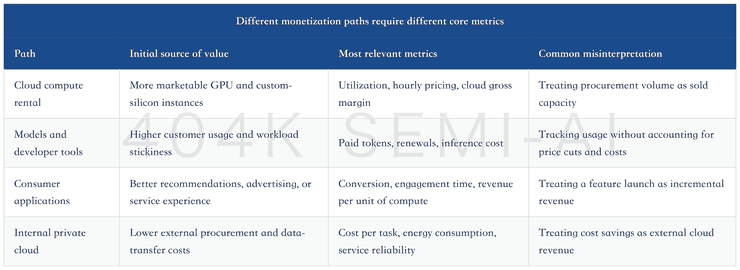
Google and Apple are more focused on using custom silicon to protect the economics of their own applications. Google optimizes training and inference chips separately to reduce the die area and power consumed by unnecessary circuitry, while Apple is extending the M-series unified-memory architecture into private-cloud inference. The immediate benefit for both companies is lower internal service costs. External revenue must emerge through Google Cloud’s marketable TPU capacity, Search and model products, or Apple’s device and services experience. Until those revenue metrics appear, silicon advances should be treated primarily as cost and supply advantages.
Model developers are also reshaping cloud infrastructure. Anthropic’s long-term compute contract directly secures power and future chips, while Amazon AWS is bringing models, software libraries, and robotics workloads into the same partnership. As models require more persistent inference, cloud providers gain an opportunity to shift from one-off training demand toward recurring compute revenue. However, falling inference prices may offset token growth. Higher usage alone is insufficient validation; simultaneous improvement in revenue per unit of power, GPU utilization, and cloud margins would be a more meaningful signal.
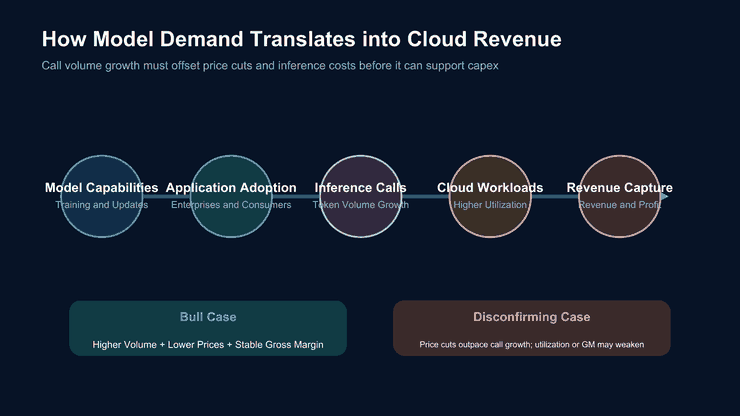
Inference economics is the link that determines whether application monetization can fund capital expenditure. Faster chips reduce the cost per query but may also drive prices lower. If demand is sufficiently elastic, token growth will outpace price declines, lifting cloud revenue and utilization together. If customers merely use cheaper inference to replace existing workloads, total revenue may not improve. Next week and in subsequent earnings reports, investors should prioritize evidence of “higher volume, lower pricing, stable margins” over isolated performance records.
Diverging Models: M7 vs. Neocloud Providers
Neocloud providers compete on price, while M7 cloud providers command a premium through broader services, vendor choice, and balance-sheet strength. This week’s market data show CoreWeave and Nebius pricing comparable GPUs below Amazon AWS, Microsoft Azure, and Oracle. Newer GPUs can command higher hourly rates by delivering greater throughput while reducing cost per token. Price competition has not simply depressed revenue; it has shifted pricing power from merely owning GPUs to deploying the latest GPUs fastest and maintaining high utilization.
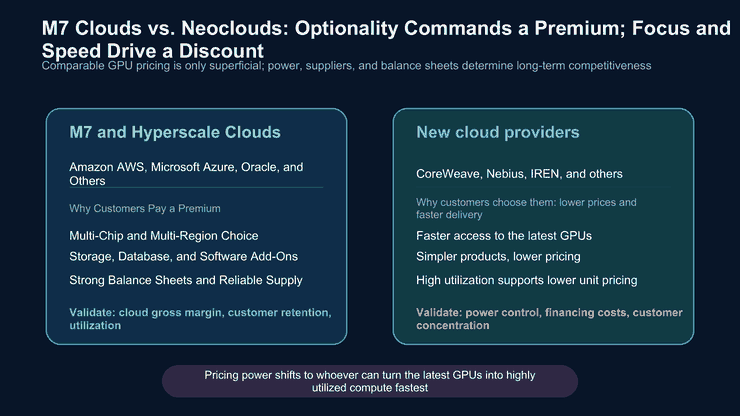
What M7 cloud providers ultimately sell is optionality. Customers can combine multiple chips, regions, storage products, databases, and software tools while relying on cloud providers’ balance sheets for stable, long-term capacity. Neocloud providers sell speed and focus: faster access to the latest GPUs, simpler products, and lower prices. The former may charge more per unit, while the latter can still generate attractive returns at lower prices if utilization remains high.
Closing the gap requires neocloud providers to control both power and financing. GPUs without grid capacity cannot determine deployment timing; power without low-cost capital cannot support sustained purchases of next-generation equipment. IREN is expanding from power, land, and data centers into cloud operations, while CoreWeave is using large-scale debt to accelerate construction. For both models, the central question is whether revenue can grow faster than the cost of capital.
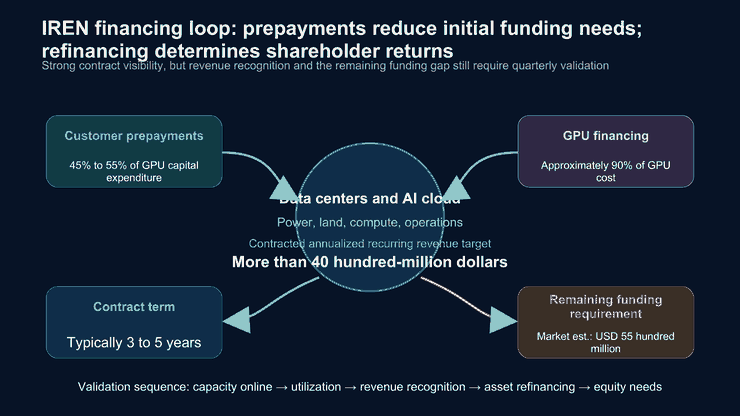
IREN represents the ideal neocloud expansion model. The company is targeting more than US$4 billion in contracted annual recurring revenue from capacity scheduled to enter service by year-end and approximately 800 MW of IT capacity by 2027. Customers can currently prepay roughly 45%–55% of GPU capital expenditure, while the company plans to finance approximately 90% of GPU costs; typical contract terms are 3–5 years. If power, customer prepayments, and asset refinancing all materialize as planned, equity funding requirements should decline and power resources can be converted into compute revenue more quickly.
The risks are embedded in the same structure. Most new capacity is scheduled to come online late in the quarter, so a meaningful revenue contribution is not expected until the following March quarter. Market estimates suggest a funding gap of approximately US$5.5 billion may remain beyond committed capital, GPU financing, and prepayments. Contracted annualized revenue, revenue from operating capacity, and cash collected are three different figures. Investors should prioritize capacity commissioning, utilization, refinancing rates, and changes in share count rather than focusing solely on total contract value.
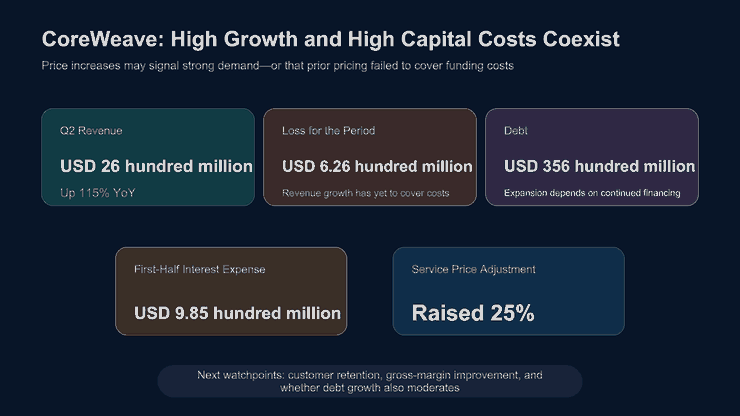
CoreWeave illustrates the stressed version of the model. Second-quarter revenue increased 115% year over year to US$2.6 billion, while the company’s loss for the same period totaled US$626 million. Debt stood at US$35.6 billion, first-half interest expense alone reached US$985 million, and service prices rose 25%. Revenue is growing rapidly, but so are interest expense and construction funding needs. The price increase may reflect strong demand, or it may indicate that previous pricing failed to cover the cost of capital. The next indicators to watch are customer retention after the increase, gross-margin improvement, and debt growth—not headline growth in isolation.
Nvidia has paused some transactions with smaller AI cloud providers that exchanged credit support for revenue sharing, covering approximately US$36 billion of commitments. The reasons included concerns about potential antitrust scrutiny. Broader customer support has not stopped, but the move establishes a boundary for neocloud financing: chip suppliers can help customers secure compute capacity, but direct participation in customer revenue creates greater regulatory and conflict-of-interest risks. If the original arrangements are replaced with conventional debt, guarantees, or asset financing, neocloud funding costs and equity returns could both change.
This also explains why traditional software multiples are insufficient for valuing neocloud providers. These companies simultaneously assume data-center construction, equipment depreciation, energy procurement, cloud operations, and customer credit risk. Contracted revenue provides visibility, but the financing structure determines how much return accrues to shareholders. Higher debt costs, faster equipment-refresh cycles, or excessive customer concentration can make seemingly stable multiyear contracts fragile.
Divergent Views, Disconfirming Evidence, and Next Week’s Watchlist
The bullish evidence still predominates: Nvidia reported strong data-center revenue and next-quarter guidance, Amazon AWS increased purchases, Google expanded its TPU clusters, and neocloud providers signed multiyear contracts. Bearish evidence, however, has moved beyond the abstract concern that capital expenditure is simply too high. It now includes weaker operating cash flow, longer accounts-receivable days, declining gross margins, and expanding debt and guarantees. The greatest analytical risk is assuming that strong demand will generate equal returns for every participant.
The next quarter can be framed through three scenarios. In the bullish case, Rubin ships on schedule, cloud-provider utilization rises, Nvidia’s receivables days decline, and neocloud providers complete low-cost refinancing; capital expenditure would continue converting into revenue. In the base case, demand remains strong, but power and HBM constraints delay delivery, pressuring gross margins without causing order cancellations. The bearish case requires several signals to emerge simultaneously: customers extending payment terms, more expensive financing, insufficient utilization, and gross margins falling below the validation threshold.
No single metric is sufficient to identify an inflection point. Lower gross margins may reflect a new-product ramp, higher receivables may result from quarterly delivery timing, and neocloud equity issuance may fund the acquisition of scarce power. Only when these changes corroborate one another and persistently impair cash collection should the risk assessment escalate from “requires monitoring” to “deteriorating returns on capital expenditure.”
Next week’s validation should proceed sequentially from hardware delivery to cash collection
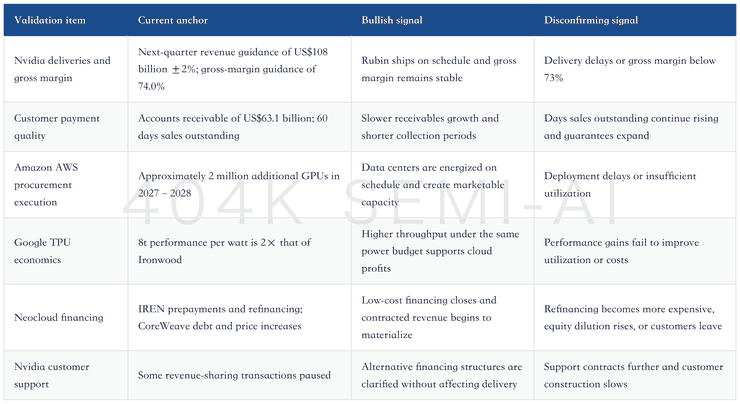
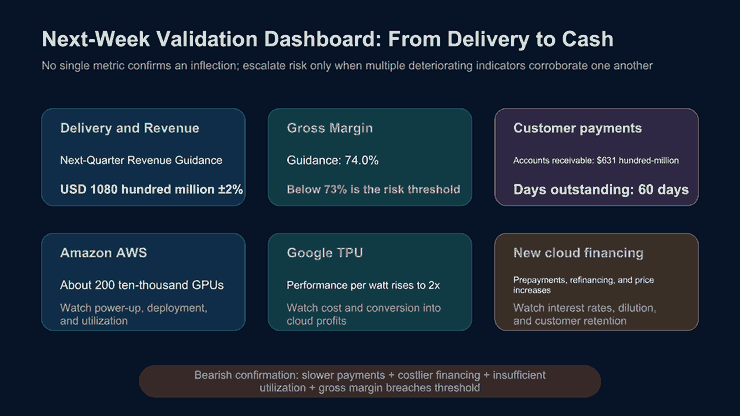
From an investment perspective, the companies fall into three categories. The first comprises M7 cloud providers with cloud revenue, customer relationships, and multi-chip choice, whose advantages are financing capacity and value-added services. The second includes neocloud providers that control power and land and can deploy new GPUs quickly, benefiting from speed and scarce capacity. The third consists of platform suppliers providing chips, networking, and financing support across the ecosystem; they offer the greatest revenue sensitivity, but their off-balance-sheet risks are also rising. All three benefit from broadening demand, but their disconfirming indicators are entirely different.
It is still too early to conclude that capital expenditure has become excessive, just as large orders alone do not validate returns. A more measured assessment is that demand is broadening, supply is being committed earlier, and capital responsibility is spreading with it. As long as delivery and utilization continue to improve, current investment can still convert into revenue. If collection periods, financing costs, and gross margins deteriorate simultaneously, however, the cycle will shift from an expansion challenge to a capital-recovery problem.