
目录
Overall Assessment
Model Releases, Upgrades, and Capability Changes
Reasoning, Training, Multimodality, and Agent Capabilities
Open- vs. Closed-Source Competition, Benchmarks, and the Developer Ecosystem
API Pricing, Commercialization, and Vendor Divergence
Diverging Views, Disconfirming Evidence, and What to Watch Next Week
Model competition shifted this week from “who tops the leaderboard” to “who can complete the task at the lowest cost.” Narrowing capability gaps and lower API prices should support broader demand, but agent reliability, differences in revenue recognition, and customer concentration remain the principal risks.
Overall Assessment
Frontier capabilities continue to improve, but leading an individual benchmark has less investment significance. Grok 4.6 scored 94.9% on GPQA Diamond, just 0.4 percentage points above Gemini 3.7 Flash, which has a lower cost per task. A narrow lead will make it difficult for model vendors to sustain a premium based solely on being “the smartest.”
Open-source models are competing simultaneously on performance, price, and deployment flexibility. QWEN38270 ranked No. 1 among open-source models and No. 7 overall in the Image-to-WebDev Arena. Open-source models’ share of tokens on Vercel rose from 28% to 62% in 2 months. Although this reflects only one developer platform, it is sufficient evidence that routers are choosing “good enough and inexpensive” models more aggressively.
Agents are moving into longer-duration tasks, but reliability has not crossed the threshold at the same pace. Claude unified memory across Chat and Cowork, Claude Code added isolated subagents, and OpenAI is testing a Codex mode that can continue working across sessions. Meanwhile, the best run on real-world e-commerce tasks completed only 66 of 107 tasks, while multi-agent discussions produced correct answers in just 17%–36% of runs in hidden-information experiments.
The price war is now measurable at the task level. OpenAI cut both input and output prices for GPT-5.6 Sol. In one coding test, GPT-5.6 Luna completed more fixes in less time and at lower cost. The sample is small, but buyers will increasingly route workloads based on completed outcomes.
Monetization is expanding beyond subscriptions and APIs into advertising, tool gateways, and enterprise workflows. OpenAI is testing sponsored units below responses for some Free and Go subscribers in India. Meta’s spending on Anthropic, while reportedly declining, is still said to amount to hundreds of millions of dollars per month. Model revenue is growing, but customer concentration, traffic monetization, and privacy boundaries will also enter valuation frameworks more quickly.
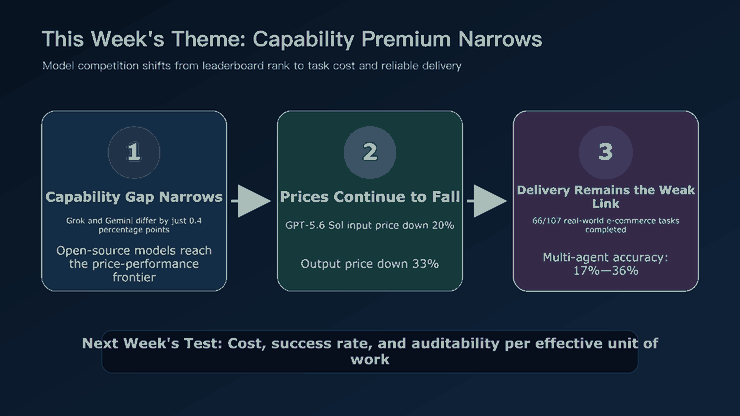
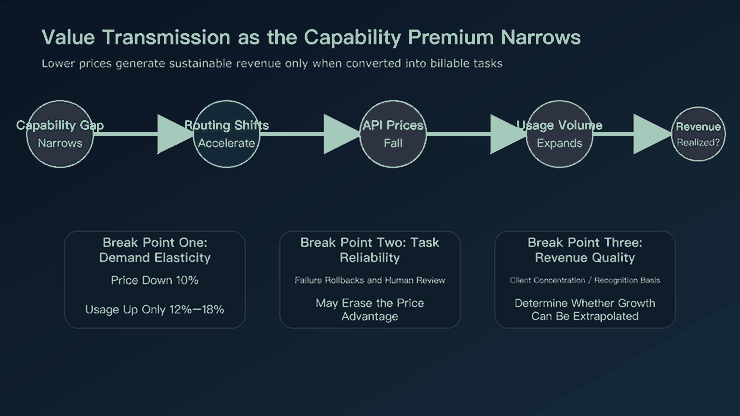
This week’s most important development can be summarized as a transmission chain: narrowing capability gaps make it easier for developers to switch models; API prices then decline, potentially expanding usage; and as agents take on longer tasks, enterprises increasingly require proof that the model actually made, saved, and submitted the requested changes. Value is no longer determined solely by parameter count and static benchmark scores, but jointly by cost per effective unit of work, success rate, and auditability.
The valuation implication is straightforward. Capability leadership still matters, but if the lead is insufficient to offset differences in price, latency, and integration costs, customers will direct more traffic to lower-cost models. To protect revenue, model vendors must continually enable new tasks that older models cannot perform, while achieving success rates high enough to deliver genuine labor savings. Using price cuts alone to drive volume will pressure margins first.
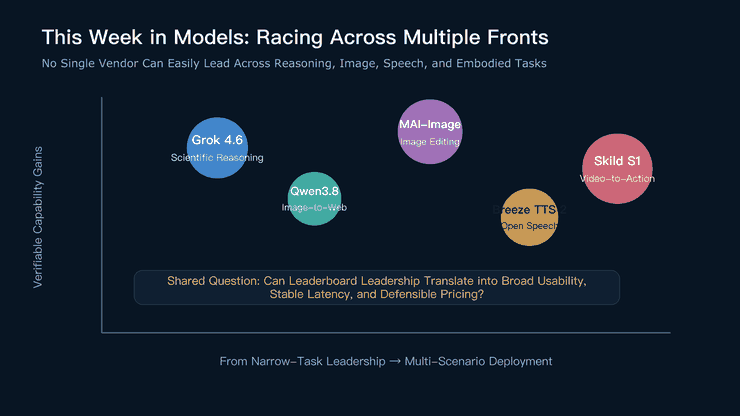
There was also no evidence this week of a winner-takes-all market. Different models stood out in scientific reasoning, image editing, speech synthesis, code repair, and robotic learning. A portfolio-based routing strategy therefore fits enterprise procurement logic better: flagship models for difficult tasks, lower-cost models for high-volume workloads, open-weight or privately deployed models for sensitive data, and a unified evaluation and permissions layer for governance. Model vendors are competing not only for inference volume, but also to become the default routing gateway.
Model Releases, Upgrades, and Capability Changes
Release activity remained high this week, but gains were distributed across scientific reasoning, imaging, speech, and embodied intelligence. No single model established an overwhelming lead across all dimensions; vendors instead appear to be pursuing leadership in the tasks they can monetize most readily.
Capability upgrades fall into 3 categories. The first pushes established task formats to higher performance, as with Grok 4.6 in scientific reasoning. The second raises generation quality to professional-work standards, as with Microsoft’s image editing. The third changes how tasks are specified and executed, as Skild S1 does by learning robotic actions from video. The first 2 categories can enter APIs and subscriptions more quickly. If the third proves replicable, it could generate greater value per customer, but it also entails longer deployment cycles, hardware variability, and greater safety liability.
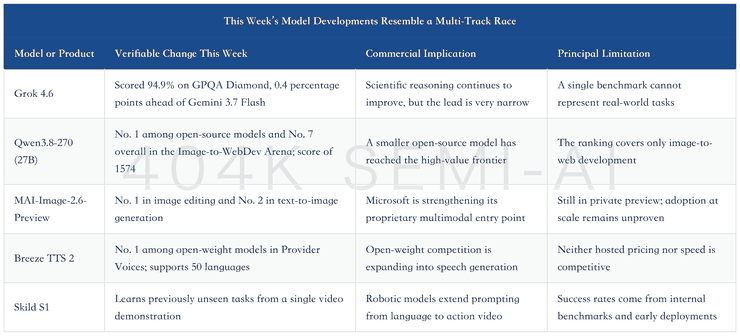
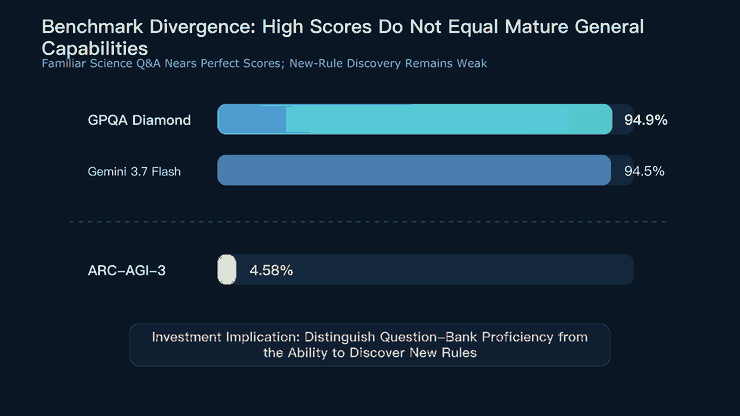
Grok 4.6’s 94.9% shows that the ceiling for scientific question answering continues to rise, but Gemini 3.7 Flash trails by only 0.4 percentage points and has a lower cost per task. At the other extreme, the new high on ARC-AGI-3 is still just 4.58%. Taken together, the 2 benchmarks support a clear conclusion: models are progressing rapidly on familiar knowledge and reasoning formats but remain weak at tasks requiring them to discover new rules. Investors should not extrapolate a near-perfect score on one leaderboard into evidence that general intelligence has matured.
The divergence between these leaderboards also underscores the need to understand what each test measures. GPQA emphasizes difficult scientific question answering, whereas ARC-AGI-3 is closer to discovering unfamiliar rules from limited examples. They measure different capabilities. For products that only need to retrieve, analyze, and explain established knowledge, near-perfect models can already create value. For tasks requiring new-process discovery, operation in anomalous environments, or sustained self-correction, low-scoring benchmarks reveal the risks more clearly.
Microsoft’s MAI-Image-2.6-Preview is best understood through the lens of product control. It ranks No. 1 in image editing and No. 2 in text-to-image generation, including first place in 5 of 19 text-to-image categories. Microsoft’s continued iteration of proprietary image models means its enterprise AI platform need not cede every high-value multimodal workload to external model vendors. The decisive test will come after the private preview becomes broadly available: whether quality, latency, and pricing can all be sustained.
The monetization paths for multimodal models are also more concrete than for text chat. Image editing maps directly to marketing assets, product images, and design workflows; speech models to customer service, real-time companionship, and voice agents; and robotics models to physical tasks. The closer a use case is to an existing budget line, the easier it is for customers to quantify time savings. The closer it is to physical equipment, however, the higher the cost of a single failure—and the less adequate average benchmark scores become for acceptance testing.
Breeze TTS 2 illustrates another side of open weights. With an Elo score of 1215 on the Provider Voices leaderboard, it ranks No. 6 among all models and leads the next open-weight model by 90 Elo. Open weights provide the option of private deployment, but do not automatically make hosted inference less expensive.
It processes 45 characters per second, below Fish Audio S2 Pro’s 102 characters per second. Its hosted price is $34 per 1 million characters, versus $15 for Fish Audio S2 Pro. Buyers choosing self-hosting must also include compute, operations, and peak-capacity requirements in total cost.
