
目录
TL;DR
Overall Assessment
Model Releases, Upgrades, and Capability Changes
Reasoning, Training, Multimodality, and Agent Capabilities
Open- versus Closed-Model Competition, Benchmarks, and the Developer Ecosystem
API Pricing, Commercialization, and Model-Provider Divergence
Divergent Views, Counterevidence, and Next Week’s Watchlist
Model competition shifted this week from “who can build the largest model” to “who can complete real-world tasks at the lowest cost.” Post-training, inference speed, and distribution are becoming key differentiators. The risk is that safety monitoring begins consuming substantial compute, while lower pricing may not translate into a lower total cost per task.
TL;DR
Zhipu AI’s GLM-5.3 delivered the clearest capability gain this week. It retained the GLM-5.2 base model and only scaled post-training, yet its DeepSWE score rose from 44 to 69; a separate composite intelligence benchmark scored it at 60, up 7 points from the previous generation. Scaling parameters still matters, but post-training data, reward design, and efficient tool-use trajectories have become faster and cheaper paths to improvement.
Model evaluation is shifting from static scores to real-world tasks. Among the top 5 models in Agent Arena, median task cost ranged from $0.62 for Kimi K3 to $3.37 for Claude Opus 5—a gap of more than 5×. A voice-agent leaderboard also showed that the top-ranked model by preference achieved a task success rate of only 74.6%. Speed, perceived quality, and leaderboard position cannot substitute for completion rates and cost per successful task.
Multimodal competition still has room for pricing dispersion, but vendors must justify premiums through clear capability tiers. Microsoft’s MAI-Image-2.5-Pro topped the image-editing leaderboard at approximately $108.5 per 1,000 1024×1024 images. Qwen-Image-3.0-Pro rose to No. 6 in image editing and costs $0.04 per image at 1K resolution. Quality, speed, and price have now been separated into distinct product tiers.
The advantage of open-weight models has expanded beyond “free access to weights” to include local deployment, post-training flexibility, and cost control. Qwen3.8-270 (27B) is already running offline and receiving inference optimizations across the consumer-device ecosystem, while Zhipu AI has shown that the same base model can achieve substantial gains through post-training. Closed models still control the strongest product entry points, but their moats increasingly depend on distribution, data, safety, and toolchains.
API commercialization is moving toward higher-level billing metrics. OpenRouter disclosed that it processes more than 10 trillion tokens per day across more than 400 models, while over 40% of Anthropic’s annualized recurring revenue comes through cloud channels. Customers will continue comparing per-token prices, but procurement decisions are shifting toward whether a task can be completed, how much human review is required, and whether failures are traceable.
Safety is becoming a quantifiable cost. OpenAI has paused portions of its large-scale reinforcement-learning training and estimates that its new monitoring system will require additional compute equivalent to approximately 20% of the inference compute being monitored. Models already nearing completion may still be released, but longer-term roadmaps face delays. Next week, investors should watch whether the scope of the pause, monitoring costs, and product-release cadence drive further divergence.
Overall Assessment
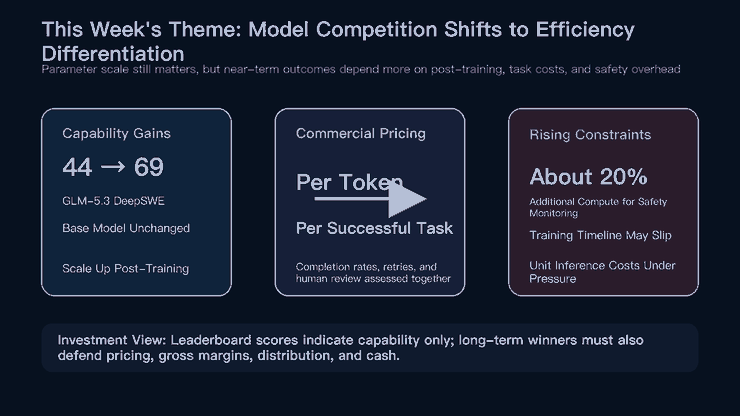
Two competitive models are emerging simultaneously. Frontier products defend premium pricing through capability, release velocity, and multimodal completeness. “Good enough” products win real-world workloads through low cost, high volume, and deployment flexibility. Investors should look beyond leaderboard scores to cost per task, channel take rates, inference gross margins, and cash burn.
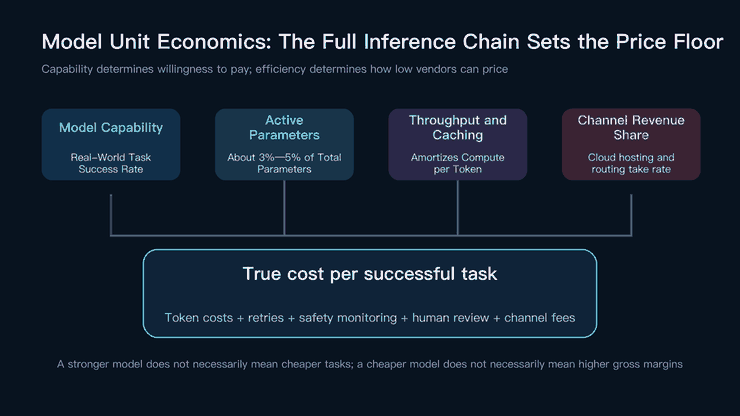
Goldman Sachs provides a structural framework for Chinese models: total parameter counts range from approximately 200 billion to 1.6 trillion, equivalent to only 2% to 10% of leading frontier models. Mixture-of-experts architectures activate only approximately 3% to 5% of parameters per token. Fewer active parameters mean less compute and therefore a lower pricing floor.
DeepSeek’s DSpark increased generation speeds for some online models by 57% to 85% without changing model weights or output quality. This demonstrates that inference-layer optimization can directly reshape unit economics. If vendors can serve more requests on the same hardware, they gain more room to cut prices, expand margins, or reserve additional compute for complex tasks.
Investors should analyze inference gross margins across 3 layers: how many parameters the model activates, whether the serving system can improve throughput and cache hit rates, and how much revenue is retained by distribution channels. API list prices alone obscure profit differences created by subsidies, peak/off-peak pricing, and third-party hosting.
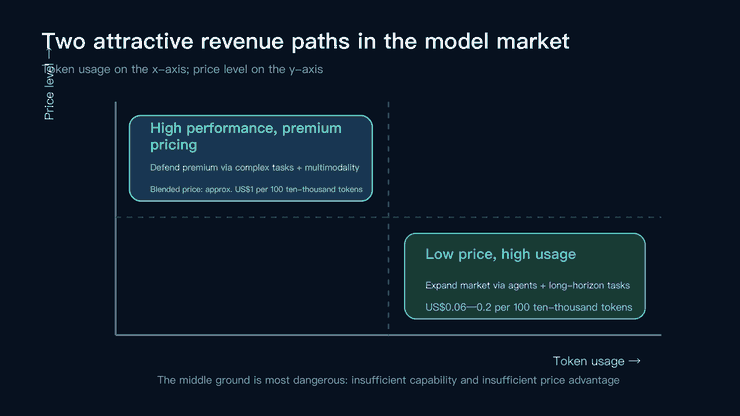
Prices will not fall uniformly. High-performance Chinese models cost approximately $1 per 1 million tokens, or 10% to 25% of the $4 to $8 charged by overseas frontier models. Lower-end agent models have already fallen to $0.06 to $0.2 per 1 million tokens. The former sell higher success rates; the latter sell scale and affordability. Both can potentially expand annualized recurring revenue.
This explains this week’s “efficiency divergence.” GLM-5.3 achieved a substantial score increase through post-training without replacing its base model; OpenAI expanded free access through the low-cost GPT-5.6 Luna; and Kimi and Qwen remained competitive on real-world agent tasks at a lower cost per attempt. Parameter scale still determines the capability ceiling, but near-term iteration speed increasingly depends on post-training, inference engineering, and usage data.
The two paths have different cash-flow requirements. High-performance models require continuous investment in frontier training and must recover that spending through high-value tasks. Low-cost models must keep expanding request volumes while raising utilization. Without sufficient revenue conversion, either model can produce a situation in which usage grows while losses widen.
Model Releases, Upgrades, and Capability Changes
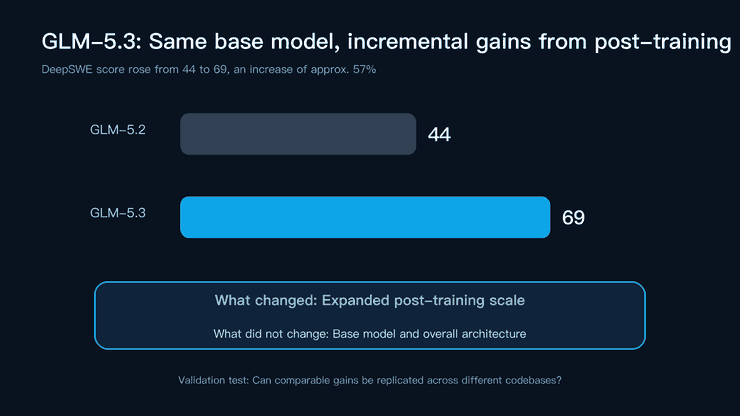
GLM-5.3 was the most important release to track this week. It retained the GLM-5.2 base model and only scaled post-training, lifting its DeepSWE score from 44 to 69. Its composite intelligence score reached 60, matching Kimi K3 and improving by 7 points over GLM-5.2. Because the gain came from post-training rather than retraining a larger foundation model, the result is especially relevant for independent labs: even without an advantage in capital or compute, they may be able to narrow capability gaps through real-world tasks, reinforcement learning, and reward design.
The commercial implications of post-training are straightforward. At the same performance level, a reward model that favors shorter reasoning trajectories, fewer tool calls, and lower token consumption can reduce the customer’s cost per task while preserving the provider’s margins. Conversely, optimizing only for longer chains of thought may raise benchmark scores while consuming enterprise budgets more quickly.
One score increase should not be extrapolated into durable leadership. Post-training outcomes depend on test distributions, reward-model preferences, and the quality of real-world data. To demonstrate that this path is sustainable, GLM-5.3 must maintain completion rates across different codebases, toolchains, and longer tasks—not merely defend its position on a single benchmark.
Multimodal competition is beginning to stratify across quality, speed, and cost. Seedance 2.5 ranked No. 1 on the multi-image-to-video leaderboard with an Elo score of 1400, while the open-weight MiniMax H3 ranked No. 2 at 1355. Multi-image input places greater demands on consistency across subjects, styles, and scenes than conventional image-to-video generation, making these results more relevant to controlled commercial production than to one-off demonstrations.
