
目录
Executive Summary
Overall View This Week
Cloud Revenue and AI Capital Expenditure
Data Centers, Compute Procurement, and Custom Silicon
Model, Software, and Application Monetization
Divergence Between the M7 and Emerging Cloud Providers
Divergences, Counter-Evidence, and What to Watch Next Week
This week’s order data again confirmed that AI compute remains undersupplied, with committed balances rising at Microsoft, Google, and Amazon. The real dividing line is now which provider can convert capacity under construction into cloud revenue, profit, and cash flow most quickly.
Executive Summary
Demand visibility continues to improve at Microsoft, Google, and Amazon. Microsoft’s commercial remaining performance obligations rose 84% to $678 billion, or 25% excluding OpenAI. Google Cloud’s backlog increased by more than $50 billion sequentially to $514 billion. Amazon’s backlog reached $496 billion, posting triple-digit year-over-year growth. Orders have not weakened, and enterprise customers are expanding their commitments, but revenue conversion remains constrained by the delivery pace of power, data-center space, and chips.
The capex debate has shifted from whether spending will happen to when capacity will enter service, when depreciation will begin, and when the investment will generate returns. One industry estimate puts 2026 capex by seven AI infrastructure builders at approximately $863 billion, including about $550 billion related to AI, with roughly $315 billion of assets not yet in service. Although these figures are not based on standardized company disclosures, they point to the same risk: before capacity comes online, the income statement understates future depreciation and fixed-rent pressure.
CoreWeave and Nebius continue to demonstrate strong neocloud demand through price increases, long-term contracts, and prepayments. CoreWeave’s second-quarter backlog was approximately $104 billion; it raised prices across compute products by about 25% in July, and more than 50% of its backlog has entered delivery. Nebius’s AI Cloud revenue grew 514% year over year, while contracted capacity reached 5 GW. For both companies, the key metrics have shifted from order growth to revenue per unit of power, delivery progress, and free cash flow.
Custom silicon is becoming a critical tool for cloud providers seeking to control inference costs. Microsoft’s Maia 300 is reportedly designed for inference at scale, but its production target of approximately 1 million chips remains constrained by foundry capacity. Google, meanwhile, combines TPUs, its cloud platform, and Gemini distribution. Whether custom silicon genuinely improves returns on capital depends on fully loaded cost, utilization, and cloud-service pricing—not merely the cost of a single chip.
Model demand has become a stronger gateway to cloud revenue. Gemini has surpassed 1 billion monthly active users, OpenAI’s annualized revenue has exceeded $40 billion, and annual recurring revenue from CoreWeave’s hosted inference offering has risen from approximately $1 million to more than $100 million. User growth and model revenue validate compute demand, but do not directly establish cloud-provider margins. Next week, investors should continue to monitor cloud-revenue growth, backlog conversion, depreciation, interest expense, and customer prepayments.
Overall View This Week
The clearest common signal this week is that orders remain strong, but returns on capital are beginning to diverge. Microsoft, Google, and Amazon all reported higher contractual commitments or backlogs, while CoreWeave and Nebius demonstrated through price increases, long-term contracts, and prepayments that near-term supply remains tight. The market is no longer asking whether customers still want compute. It is asking who can assemble power, data-center space, chips, and networking into usable capacity on schedule—and ramp revenue before depreciation and interest expense rise.
Incumbent cloud providers retain the advantages of broad customer bases, diversified product portfolios, and lower financing costs. AWS, Microsoft Azure, and Google Cloud can sell foundation models alongside databases, networking, security, and enterprise software, while custom silicon can reduce some training and inference costs. Even if a single major customer cuts purchases, enterprise demand and existing workloads can absorb capacity.
Neoclouds derive their operating leverage from acute scarcity. CoreWeave and Nebius can secure new GPUs more quickly, provide large dedicated clusters, and sell scarce capacity at higher prices. When supply is tight, this concentrated model can drive faster revenue growth and margin expansion. Once supply loosens, however, customer concentration, debt costs, and renewal pricing will become visible more quickly.
The accounting lag in capex makes current profits appear lighter than the ultimate burden. During construction, spending is initially capitalized as assets under construction. Depreciation begins only after data centers are powered and ready for use, while lease and financing costs continue to flow through the income statement. High current profits do not mean capex has already been absorbed. The real test is whether incremental cloud revenue can grow faster than depreciation, rent, and interest expense.
This week’s developments can be summarized as a single chain: enterprises and model developers increase compute commitments; cloud providers and neoclouds lock in more power and equipment; orders first enter backlog; completed capacity then converts into revenue; and only afterward do returns on capital become visible. Delays at any stage turn strong demand into cash-flow pressure, while acceleration at any stage amplifies the earnings leverage created by scarce supply.
Cloud Revenue and AI Capital Expenditure
Order data from the three largest cloud providers indicate that demand continues to broaden.
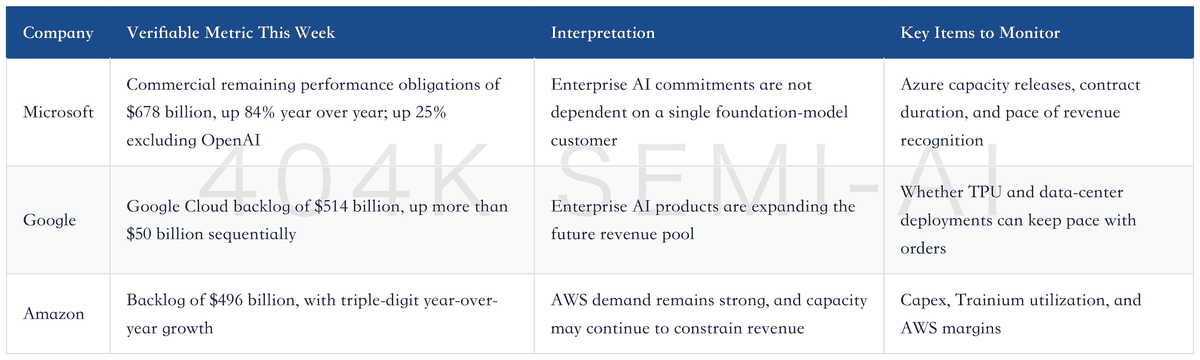
Microsoft’s figures are the most informative. All sequential growth in commercial remaining performance obligations came from customers other than frontier-model companies, while growth remained 25% excluding OpenAI. This indicates that enterprise customers are moving from trials to longer-term purchasing commitments, and Microsoft’s AI demand can no longer be explained solely by OpenAI. The caveat is that remaining performance obligations include contracts of varying durations and cannot be treated as equivalent to next quarter’s revenue.
Google Cloud’s backlog increased by more than $50 billion sequentially, driven primarily by enterprise AI products. Google’s advantage lies in integrating TPUs, models, its cloud platform, and a vast user-distribution channel within a single ecosystem. Order growth confirms customers’ willingness to sign contracts. The next question is whether TPU supply, data-center commissioning, and sales execution can convert those contracts into revenue and profit.
Amazon’s backlog reached $496 billion, with triple-digit year-over-year growth. AWS has a more comprehensive business model than pure compute rental, with database, storage, networking, and security services increasing customer switching costs. Graviton and Trainium could reduce certain computing costs, but the materials provide no standalone data on cost savings or utilization. This week’s evidence therefore supports the strategic direction of custom silicon, but not the conclusion that margins have already improved.
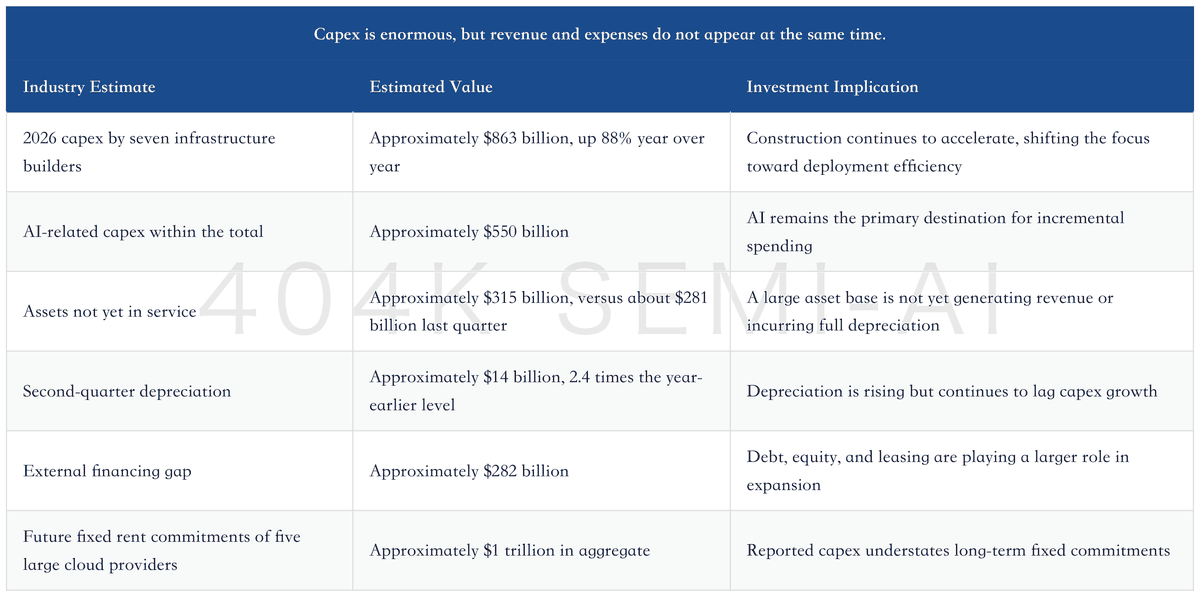
These figures are industry estimates calculated on a standardized basis, rather than company disclosures prepared under identical standards, and should not be used for precise company-level comparisons. They are more useful as directional indicators: the later a project enters service, the lower current depreciation will be and the more concentrated future expenses become; the greater the use of leasing, the less reported capex captures total commitments.
This also explains why cloud-revenue growth and free cash flow can temporarily diverge. After enterprises sign multiyear contracts, cloud providers must first purchase chips, secure power, and build data centers; revenue can be recognized only as capacity is delivered. Near-term free-cash-flow pressure does not necessarily indicate weaker demand, but it will increase the market’s sensitivity to capital efficiency, depreciation periods, and financing costs.
Data Centers, Compute Procurement, and Custom Silicon
The bottleneck in data center development is expanding beyond GPU procurement to power, permitting, networking, and construction. CoreWeave brought more than 300 MW online in June alone and has secured 4.2 GW of contracted power; Nebius raised its contracted-capacity target to 5 GW. Both companies have ample orders, but the timing of usable capacity coming online continues to determine the pace of revenue realization.
Demand at emerging cloud providers can now be corroborated through both pricing and delivery data.
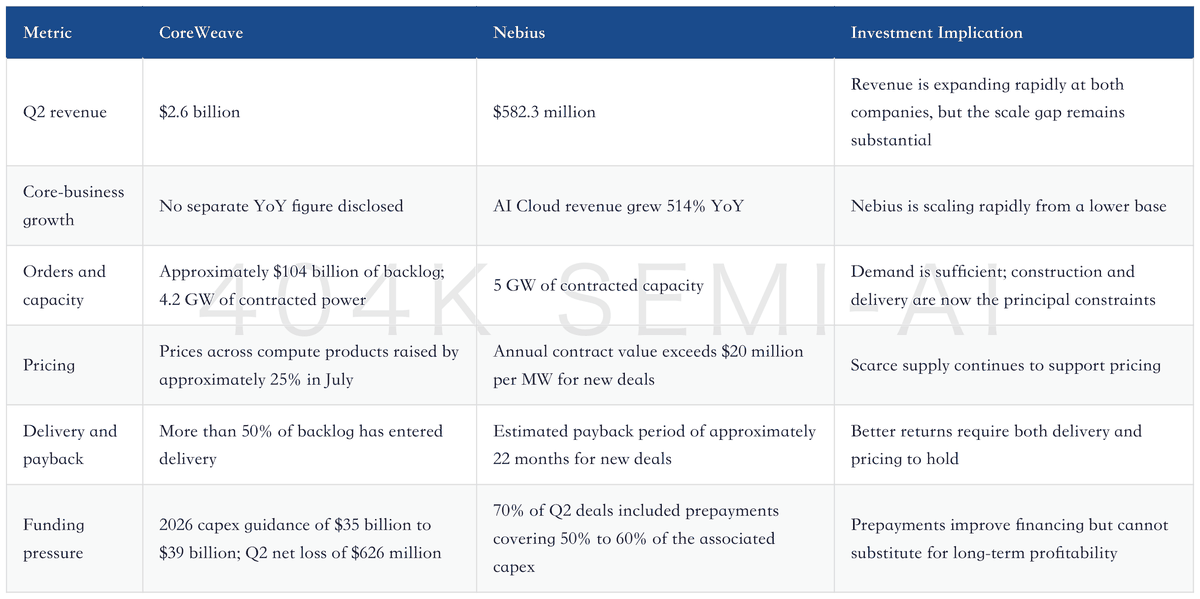
CoreWeave’s A100 contracts extend through 2029, providing an important data point on the economic life of older-generation GPUs. GPUs launched in 2020 can still be leased under long-term contracts, indicating that not every inference or long-tail workload requires the latest chips. This can extend the revenue-generating life of these assets and ease concerns that older hardware will depreciate rapidly after a new GPU generation launches.
The counterevidence is equally clear. CoreWeave generated $1.5 billion of adjusted EBITDA in Q2, representing a 59% margin, yet still reported operating profit of -$49 million and a net loss of $626 million. High EBITDA does not substitute for cash returns after interest, depreciation, and capex. Raising full-year capex guidance to $35 billion to $39 billion means that stronger orders could also drive greater near-term financing needs.
Nebius’s improving unit economics are primarily price-driven. The company disclosed that annual contract value for new deals increased from approximately $12 million to more than $20 million per MW; its estimated payback period of approximately 22 months excludes customer prepayments. Prepayments provide cash to fund construction, but higher contract pricing is what actually shortens payback. If pricing for older-generation GPUs and revenue per MW subsequently decline, the payback period will lengthen again.
Project approvals are a hard constraint independent of demand. A 300 MW Nebius-related data center project reportedly received a stop-work order because its on-site power solution required planning modifications. One case does not establish an industry-wide pattern of delays, but it reminds investors that contracted power, planned capacity, and energized capacity are three different concepts. Only the last can begin generating revenue.
The purpose of custom silicon is not to replace every GPU, but to move high-frequency, scaled inference workloads onto a more controllable cost structure. Microsoft’s Maia 300 is reportedly targeting large-scale inference and production of approximately 1 million units, although foundry capacity could constrain volume manufacturing. Because the launch date, full specifications, and actual production volumes remain unconfirmed, it is more appropriate at this stage to view Maia 300 as a cost-control initiative rather than a realized source of incremental profit.
Google’s TPU strategy is also extending into financing. Institutional capital can fund TPU racks and data center projects against long-term lease commitments, equipment collateral, and vendor support. This converts future compute demand into construction capital upfront while distributing payment, residual-value, and delay risks across more participants. Broader financing channels should help Google Cloud expand TPU supply, but sustainability must ultimately be demonstrated through recurring revenue and reliable payments from customers such as Anthropic.
Cisco’s orders provide supply-chain corroboration of cloud expansion. The company secured $9.3 billion of AI orders last quarter and expects AI revenue to reach $7.5 billion in FY2027; P200 has been adopted by three hyperscalers. Networking orders confirm that cluster expansion is underway, but also show that AI capex is spreading from GPUs into switching, optics, and data center interconnects, continuing to raise the total cost of each cluster.
Model, Software, and Application Monetization
Model demand is beginning to provide a more visible revenue pathway for cloud capex, although companies remain at different stages. Google has consumer distribution at scale, Microsoft controls the enterprise software entry point, Amazon supports model training and inference through AWS, and Meta primarily funds internal compute infrastructure with advertising cash flow. Emerging cloud providers are seeking to layer inference, storage, networking, and software services on top of GPU rentals.
Google disclosed that Gemini has surpassed 1 billion monthly active users and is among the company’s fastest-growing products. This demonstrates distribution strength but does not directly address paid conversion, revenue per user, or inference costs. For investors, the implication is that Google already has a sufficiently large user funnel; the next question is whether Gemini can increase revenue across Search, advertising, Workspace, and Google Cloud while covering rising inference costs.
OpenAI’s annualized revenue has exceeded $40 billion, approximately double its level at the end of 2025, with growth accelerating further in July. Revenue growth at model developers can improve the credit quality of long-term compute commitments and increase order visibility for Microsoft, Amazon, Google, and emerging cloud providers. However, because cloud providers’ equity investments, credit support, and capacity commitments to model companies are intertwined, investors must continue distinguishing genuine third-party paid revenue from contract growth driven by partnership arrangements.
Microsoft’s order mix provides strong counterevidence. Excluding OpenAI, Microsoft’s commercial remaining performance obligations still grew 25%, indicating that enterprise AI procurement is not wholly dependent on a single model company. If Azure revenue growth slows while remaining performance obligations continue to rise, capacity delivery or contract duration would be the more likely issue. Only if both decelerate together would the evidence more clearly indicate weakening demand.
CoreWeave is demonstrating that software layered on top of compute can become a second revenue stream. Annualized recurring revenue from managed inference increased from approximately $1 million to more than $100 million in a single quarter, and the company expects it to exceed $250 million by the end of 2026. Annualized recurring revenue from storage, CPUs, networking, and software has already surpassed $400 million. Inference services and supporting software can increase customer retention and revenue per GPU while reducing the risk that price competition compresses a pure rental business.
Meta’s advantage is that advertising cash flow can fund AI infrastructure internally, avoiding the need to rely initially on high-cost debt as emerging cloud providers do. The challenge is that returns on internally consumed compute are difficult to isolate. Meta must justify capex through advertising conversion, recommendation efficiency, agent revenue, or paid adoption of new products—not merely through model capabilities and usage volumes.
Divergence Between the M7 and Emerging Cloud Providers
This week’s divergence is not about the strength of demand, but about funding sources, customer mix, and product depth.
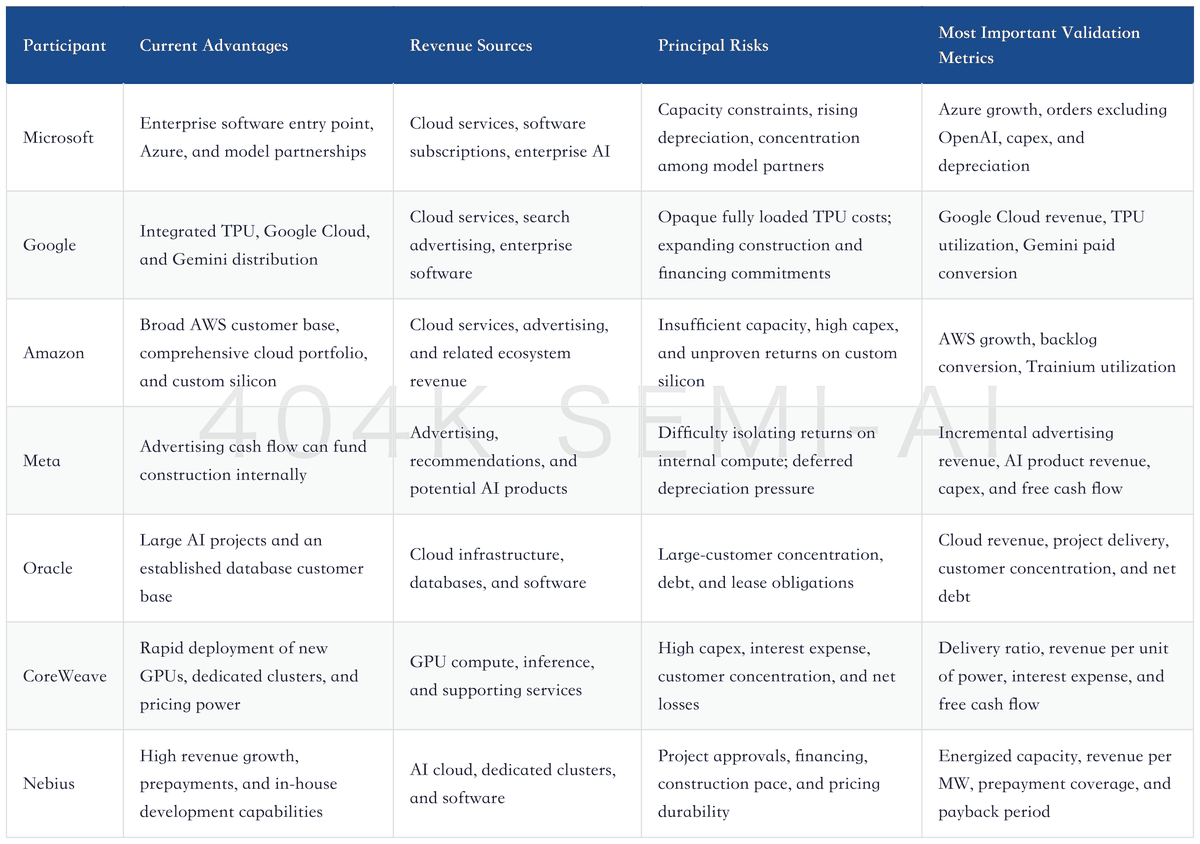
Established cloud providers resemble integrated cloud platforms, while emerging providers are more specialized suppliers of scarce compute. The former can generate more stable gross margins from databases, networking, security, and software; the latter have greater pricing leverage when supply is tight. Both groups can grow simultaneously, but they should not be assessed under the same valuation and risk framework.
Oracle sits between the two groups. It has an established enterprise and database customer base while also taking on larger AI infrastructure orders. Its advantages are existing customer relationships and cloud cross-selling; its risks are exposure to large projects, a limited number of customers, and the effect of external financing on its capital structure. If new orders come primarily from a small group of frontier model developers, revenue could grow quickly, but cash-flow volatility would also increase.
CoreWeave and Nebius are actively expanding their platform capabilities. Growth in managed inference, storage, networking, and software revenue shows that neither intends to remain solely a GPU rental provider. Whether they can evolve from dedicated-cluster suppliers into more complete cloud platforms will determine whether current price increases are cyclical scarcity gains or can translate into durable margins.
Divergence within the M7 will also continue. Google’s TPU and Gemini, Microsoft’s Azure and enterprise software, Amazon’s AWS and custom silicon, and Meta’s advertising cash flow represent four distinct approaches to recouping capex. The ultimate winners will not be determined by who invests the most, but by who can generate the most sustainable revenue and cash flow from each ¥1 of incremental capex.
Divergences, Counter-Evidence, and What to Watch Next Week
The first debate is whether backlog can be treated as future revenue. Bulls point to simultaneous order growth at Microsoft, Google, Amazon, and CoreWeave as evidence that demand can absorb incremental capacity. Bears worry that customers are double-booking to hedge against shortages, while longer construction timelines keep pushing out order recognition. Next week, the focus should be on new orders, the share entering delivery, and any cancellations or renegotiated terms—not merely total backlog.
The second debate is whether compute pricing will rapidly commoditize. CoreWeave raised prices by approximately 25% in July, while prices for Nebius’s previous-generation GPUs are also rising, indicating that the market remains tight. Bears argue that prices for undifferentiated compute could decline as more capacity comes online over the next several years. If inference, software, and networking services continue to increase their share of revenue, neoclouds can offset lower standalone compute prices through deeper product offerings. If they remain primarily dependent on GPU rentals, falling prices will directly compress returns.
The third debate is whether custom silicon can materially improve cloud profitability. Google’s TPUs, Amazon’s Trainium, and Microsoft’s Maia all have explicit cost-control objectives, but outside investors lack full visibility into R&D;, packaging, networking, software, and utilization costs. The success of custom silicon should be judged by cloud-service pricing, utilization, customer adoption, and returns on capital—not simply whether a chip has launched.
The fourth debate is whether financing-led expansion signals infrastructure maturity or the wider distribution of risk. Long-term leases, customer prepayments, equipment-backed financing, and vendor support can reduce near-term funding pressure, but they also spread residual-value, credit, and delay risks across banks, asset managers, and suppliers. As long as model revenue and compute utilization continue to grow, this structure can expand supply. If revenue falls short of expectations, however, fixed lease and debt obligations must still be serviced.
The most important issue to track next week is whether revenue, delivery, and cash flow can improve simultaneously.
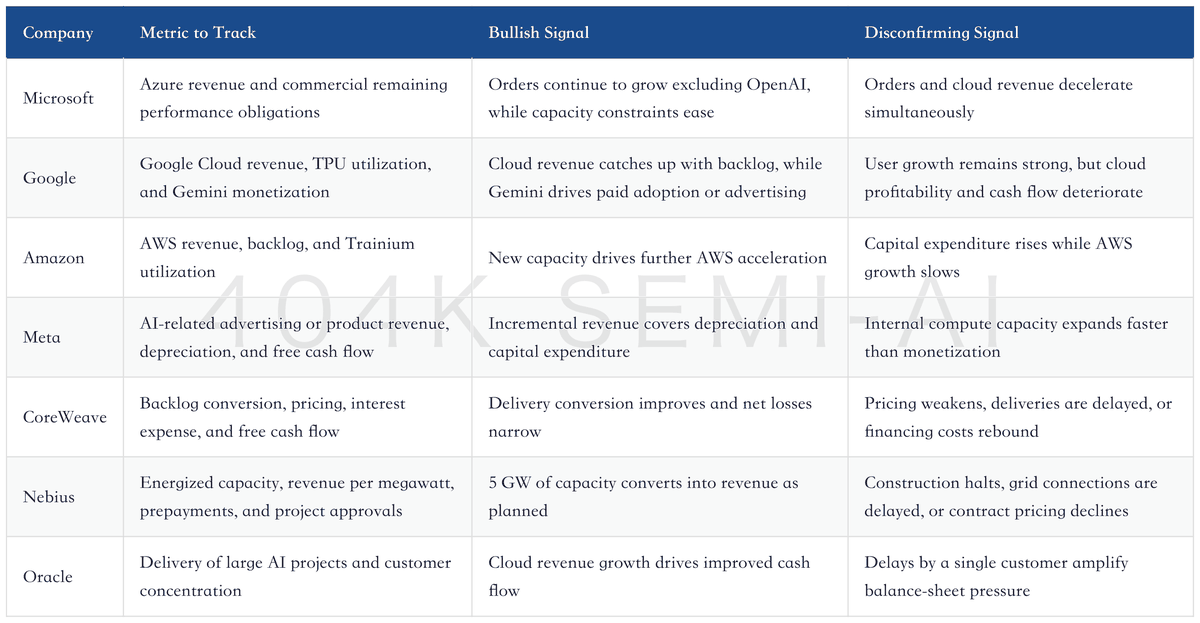
This week’s evidence more strongly supports the view that demand is robust and supply remains tight, but it is not yet sufficient to prove that all capital expenditure will earn high returns. For established cloud providers, investors should continue comparing cloud revenue, depreciation, and free cash flow. For neoclouds, the key comparisons remain pricing, delivery, interest expense, and revenue per unit of power. Orders are the starting point; cash flow is the ultimate answer.