
目录
Executive Summary
Overall Assessment
Model Releases, Upgrades, and Capability Changes
Reasoning, Training, Multimodal, and Agent Capabilities
Open versus Closed Models, Benchmarks, and the Developer Ecosystem
API Pricing, Monetization, and Model-Vendor Differentiation
Debates, Counterevidence, and Next Week’s Watchlist
This week, model competition moved beyond “bigger and faster” toward completing work at a controllable cost. New releases were plentiful, but investors should focus on task-completion rates, retry costs, and routing efficiency. The biggest risk is that benchmark leadership fails to translate into sustained usage.
Executive Summary
Google, OpenAI, xAI, Nvidia, Alibaba, Zhipu AI, and Ant Group are simultaneously pushing toward lower latency, longer-duration tasks, and greater parameter efficiency. Gemini 3.7 Flash materially outperformed its predecessor across several coding and agentic benchmarks; the preview Ultrafast mode for GPT-5.6 Sol delivers up to a 14-fold speedup and 750 output tokens per second; and Grok 4.6 approaches premium closed models at lower API prices. Model capabilities continue to improve, but the evidence for a winner-takes-all market is weakening.
Agent performance is increasingly measured not by tokens generated per second, but by how long it takes, how many failures occur, and how much it costs to complete a task. Nvidia disclosed that Nemotron 3.5 Lightning can generate output at up to 4 times the speed of comparable models, yet completes 10,000 tasks only 30% faster. This suggests that tool calls, result verification, and sub-agent coordination have become the primary sources of latency. Vendors that can integrate planning, execution, routing, and verification into a reliable system are more likely to retain enterprise budgets.
Open-weight models are advancing at both ends of the market. Alibaba’s Qwen3.8-2.4T-A95B targets complex reasoning and agentic workloads with 2.4 trillion total parameters and 95 billion active parameters. Ant Group’s Ling 3.0 Tiny targets local deployment with 7.9 billion total parameters, 1.3 billion active parameters, and a 262K-token context window. The commercial case for open models has expanded from offering a cheaper substitute to giving enterprises control over models, context, and runtime frameworks. However, parameter efficiency does not necessarily translate into lower task costs.
API pricing remains under pressure. Anthropic made Claude Sonnet 5’s launch pricing of $2 per 1 million input tokens and $10 per 1 million output tokens permanent. Google priced Gemini 3.7 Flash at $0.75 and $3.75 through the end of 2026, before doubling its standard prices in 2027; Grok 4.6 is priced at $2 and $6. List prices provide only a first-pass comparison. Retry frequency, tool usage, and task-success rates ultimately determine customers’ actual bills.
Benchmarks are becoming more representative of real work, but also more susceptible to methodological differences. AA-AnalystAgent measures reliability using 80 real-world analytical tasks and a requirement to pass each task 5 consecutive times; Claude Opus 5, GPT-5.5, and Claude Fable 5 scored 54%, 50%, and 49%, respectively. Arena AutoEval, meanwhile, shortened the feedback cycle from several weeks to several hours. Next week, the key question is whether these leads persist in independent replications, real code repositories, and enterprise workloads—not whether vendors can accumulate more rankings across incompatible leaderboards.
Vendor differentiation is beginning to extend into organizational structure and revenue. OpenAI’s annualized revenue has reportedly exceeded $40 billion, with coding products among its recent growth drivers. Google has launched a more competitively priced Flash model while reportedly restructuring DeepMind and delaying a new flagship release. Near-term winners will be determined by release cadence; long-term winners must simultaneously deliver model capability, distribution, developer tooling, and attractive unit economics per task.
Overall Assessment
The central development this week is the industry’s growing recognition that “faster output” does not necessarily mean “faster work.” Historically, comparisons centered on parameter counts, context windows, tokens per second, and individual benchmark scores. Agents make the equation more complex: a model must understand the objective, invoke tools, read its environment, verify results, correct errors, and, when necessary, delegate work to another model. Instability at any stage can erase the advantages of higher speed and lower pricing.
This shift will change what customers buy. A single frontier model will continue to handle difficult reasoning, architecture design, and high-stakes decisions, while smaller and cheaper models can execute much of the routine work. By launching Nemotron 3.5 Lightning alongside NeMo Switchyard, Nvidia is productizing this division of labor: large models plan, small models execute, and the routing layer decides which model handles each step. Model providers will increasingly need to sell not just the “smartest brain,” but an operating system for controlling cost, latency, and failure rates.
Price competition therefore will not simply compress the entire market. Lower prices should expand usage, but the distribution of revenue will depend on whether customers entrust more tasks to a given model and how many tokens each successfully completed task consumes. Even at identical API list prices, differences in retry rates and instruction-following can produce severalfold differences in final costs. Investors should distinguish growth in token demand from growth in model-provider revenue, with pricing, routing, success rates, and channel revenue shares separating the two.
The open-weight market is also segmenting. Qwen3.8-2.4T-A95B uses an extremely large mixture-of-experts architecture to approach frontier-level capabilities, while Ling 3.0 Tiny and Nemotron 3.5 Lightning emphasize low active-parameter counts, local execution, and sustained task performance. The former asks whether open models can become powerful enough; the latter two ask whether they can operate in more cost- and latency-sensitive environments. Closed-model vendors retain an advantage in reliability and product distribution, but open models are no longer competing solely on price.
There is still insufficient evidence that any vendor has established an irreversible lead. Gemini 3.7 Flash has improved substantially in coding and agentic benchmarks; Grok 4.6 is rapidly closing the gap across several long-duration task tests; Claude retains an advantage in highly reliable analytical work; and OpenAI continues to expand its reach through product distribution and differentiated speed tiers. The more defensible conclusion is that capability gaps are narrowing, while product and cost gaps are becoming more important.
Model Releases, Upgrades, and Capability Changes
This week’s releases spanned general-purpose reasoning, coding agents, local execution, image generation, and video, further broadening the competitive landscape.
The common objective across new releases is higher effective throughput, not merely larger parameter counts.
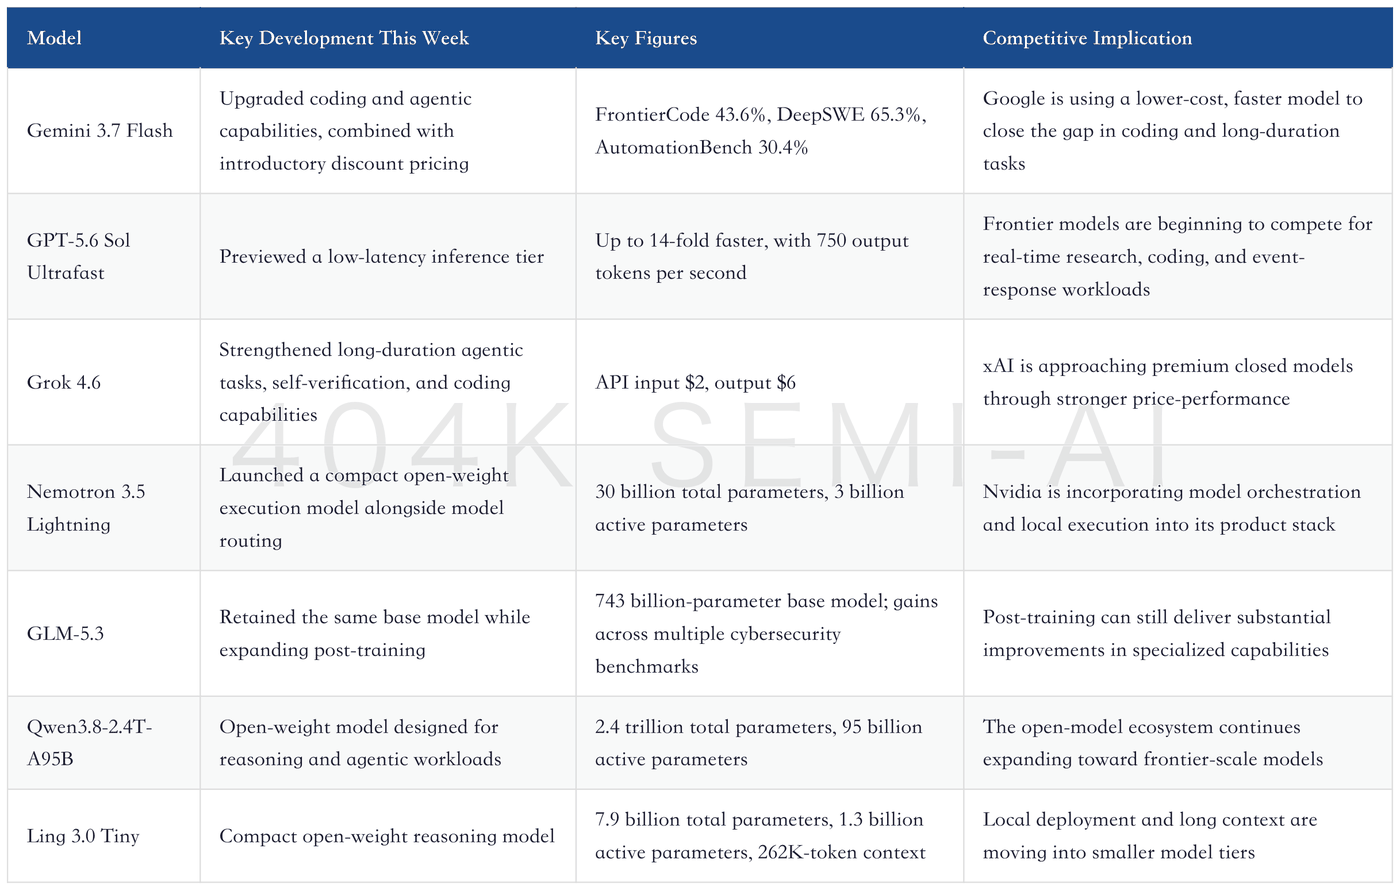
Gemini 3.7 Flash delivered the week’s most complete combination of capability gains and pricing. Compared with 3.6 Flash, its FrontierCode score rose from 34.4% to 43.6%, DeepSWE from 48.6% to 65.3%, and AutomationBench from 17.0% to 30.4%. Another test reported a DeepSWE score of 65.5%; the discrepancy reflects differences in test records, so the directional conclusion is consistent, but the two figures should not be treated as the same precise result. More importantly, Google did not trade the upgrade for a higher introductory price, instead offering a meaningful discount through the end of 2026.
