
404K SEMI-AI 2026-07-24 Weekly AI Model Update — Kimi K3, Frontier Rotation, and Agent Commercialization
目录
TL;DR
Overall Assessment This Week
Model Releases, Upgrades, and Capability Changes
Reasoning, Training, Multimodal, and Agent Capabilities
Open-Source vs. Closed-Source Competition, Benchmarks, and the Developer Ecosystem
API Pricing, Commercialization, and Model-Vendor Divergence
Divergent Views, Falsification Tests, and Next Week’s Watchlist
The most important change this week is that open-weight models are beginning to challenge capability rankings, pricing tiers, and commercial valuations simultaneously. From an investment perspective, investors should place less emphasis on a one-off top ranking and focus more on cross-generation iteration, cost per task, available compute, and actual usage.
TL;DR
Moonshot AI’s Kimi K3 has pushed open-weight models into a new phase of 2.8 trillion parameters, a 1 million-token context window, and long-running agents. Its independent Intelligence Index score is 57, ranking 3rd–4th among 189 models, with a cost per task of approximately $0.94. More importantly, K3 demonstrated 24-hour kernel optimization, 48-hour unattended chip design, and multi-agent knowledge work. Model competition has shifted from chat quality to whether models can work continuously, use tools, and deliver results.
Kimi K3 does not prove that a single laboratory can sustain a long-term lead; instead, it reinforces the view that “frontier positions rotate.” The relevant research report lowered the long-term valuation framework for Zhipu AI and MiniMax from 30x to 20x 2030E P/E. Going forward, model vendors must defend their premiums by returning to the frontier across multiple successive generations, sustaining API demand, and demonstrating commercialization efficiency—not merely by topping a leaderboard once.
Open weights and low prices have not automatically weakened closed-source models or turned the market into a zero-sum game. K3’s standard input and output prices are $3 and $15 per 1 million tokens, respectively, approximately 4x those of the previous-generation coding model, indicating that stronger capabilities can move into higher pricing tiers. Enterprises will also route workloads across multiple models based on capability, latency, cost, and data requirements. Benchmark rankings will change faster than revenue share.
Agents and multimodality were the shared themes this week. MiniMax plans to launch the 3 trillion-parameter-class M3 Pro in September–October and is preparing to release H3, covering text, images, video, audio, and music. Market reports indicate that Gemini 3.6 Flash and Gemini 3.5 Flash-Lite have entered aggregation platforms, delivering throughput of more than 150 tokens/second; ChatGPT Work and Codex have reached 10 million weekly active users. The next round of competition will focus more on cost per successful task, continuous runtime, and tool-calling reliability.
Commercial value is beginning to spill over into model routing and developer access points. Stripe is reportedly in talks to acquire OpenRouter at a potential valuation of approximately $10 billion. OpenRouter provides model comparison, switching, and unified billing to more than 5 million developers. The deal could still change, but it indicates that when model performance rotates rapidly, an access point that selects models for customers, routes requests, and handles settlement may generate more stable revenue than betting on a single winner.
Overall Assessment This Week
This week was not simply a case of “Kimi won and other models lost.” Three changes occurred simultaneously at the model layer: open-weight models entered the ultra-large-parameter and long-running-agent phase, the effective duration of any single lead shortened, and commercial competition shifted from per-token pricing to the total cost per successful task.
Kimi K3 sits at the intersection of these three changes. Moonshot AI released K3 on July 16 and plans to open the full model weights on July 27. According to the report, K3 has 2.8 trillion parameters, native vision capabilities, a 1 million-token context window, and a continuous reasoning mode. Rather than merely improving chat scores, it targets long-duration coding, knowledge work, visual reasoning, and tool orchestration.
The way model capabilities are measured is also changing. K3 scored 57 on the Artificial Analysis Intelligence Index, ranking 3rd–4th among 189 models and placing it in a similar range to some leading overseas frontier models. Its cost per task is approximately $0.94, below that of some overseas premium models listed in the report but significantly above domestic models such as Zhipu AI’s GLM-5.2. Capability rankings, task costs, and output speed must be assessed together; comparing token prices in isolation is increasingly likely to produce misleading conclusions.
For investors, the value of a one-off lead is declining, while the value of remaining consistently within the frontier cohort is increasing. Model rankings can be materially reshuffled after a single release. On this basis, the research report lowered the long-term valuation framework for Zhipu AI and MiniMax from 30x to 20x 2030E P/E. This adjustment does not negate the model companies’ long-term revenue potential; rather, it requires valuations to incorporate discounts for technological rotation, R&D; investment, and commercialization uncertainty.
This week’s materials also offer a counterintuitive signal: more efficient models may still consume more total compute. K3 improves scaling efficiency through its attention mechanisms and sparse mixture-of-experts architecture, but its parameter scale, long context window, and longer sessions can reabsorb the resources saved. The company said demand approached the limit of its existing GPU capacity within 48 hours of launch, prompting it to suspend new subscriptions and prioritize service for existing members. This demonstrates strong near-term demand but does not yet prove that demand will sustain the same growth trajectory over the long term.
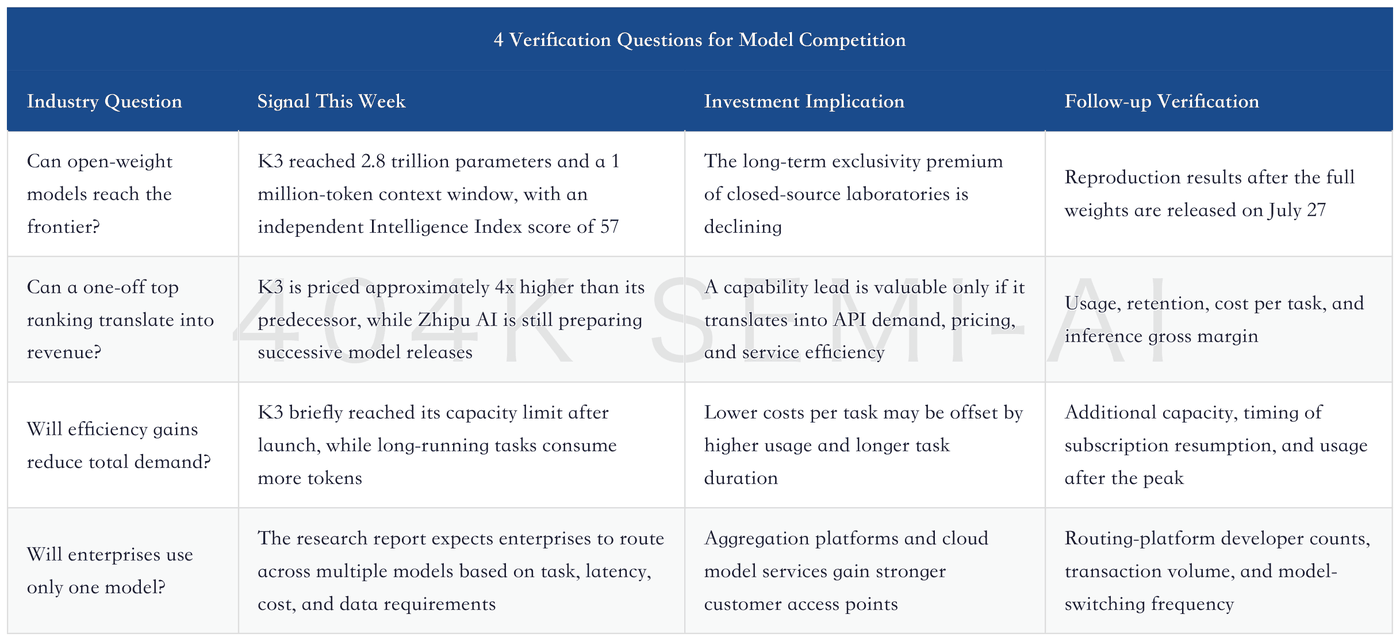
This week’s changes at the model layer can be distilled into 4 verifiable questions.
Model Releases, Upgrades, and Capability Changes
Kimi K3 simultaneously raised the parameter ceiling and working duration of open-weight models. It uses Kimi Delta Attention, Attention Residuals, and Stable LatentMoE. Its sparse mixture-of-experts component activates 16 of 896 experts per inference step. Together with adjustments to training and data methods, this improves overall scaling efficiency by approximately 2.5x compared with Kimi K2.
These architectural terms ultimately need to translate into a commercial question: with the same amount of compute, can the model complete longer and more complex tasks that customers are willing to pay for? K3’s demonstrations included 24-hour GPU kernel optimization on platforms such as H200, building a Triton-like compiler from scratch, and running continuously for 48 hours on open-source electronic design automation tools to complete a chip design. The latter produced a design measuring 4 mm², achieving timing closure at 100 MHz, and containing 1.46 million cells.
The knowledge-work cases likewise emphasized sustained execution. Using more than 120 rounds of recursive improvement, K3 built a research website covering 42 years of the ASIC industry and accessed more than 2,800 webpages, 87 quarterly reports, and 99 PDFs. Another task orchestrated more than 20 concurrent sub-agents to process 391 gravitational-wave events. These cases were presented by the company and cannot be directly equated with stable success rates in enterprise production environments, but they indicate that evaluation is shifting from one-off question answering to long-workflow delivery.
K3’s limitations must also be clearly stated. The report acknowledges that it still trails the most advanced overseas models, and the full weights will not be available before July 27. The company’s demonstrations may also have used task-specific tools, prompts, and environments. The real test is not a launch-event video, but whether third parties can reproduce the tasks with the same budget, whether the model can recover automatically from failures, and whether errors accumulate after several hours of continuous operation.
Alibaba is also stepping up its commitment to the large-parameter open-weight approach. Market reports indicate that Alibaba previewed Qwen3.8, a 2.4 trillion-parameter-class open-weight model positioned within the global frontier range. Current information is insufficient to support precise cross-model rankings; the official weights, context window, activated parameters, training data, and third-party evaluations still need to be confirmed. Its significance currently lies in the pace of competition: domestic model vendors are no longer satisfied with defending the local market through low prices and are instead using ultra-large parameter counts and open distribution to compete for global developers.
Fast models are taking a different path. Market reports indicate that Gemini 3.6 Flash and Gemini 3.5 Flash-Lite have entered OpenRouter, emphasizing high throughput of more than 150 tokens/second. The former targets coding and knowledge work, while the latter is suitable for low-latency, high-volume sub-agents. Large models may handle complex planning, while small models perform retrieval, classification, verification, and parallel subtasks, potentially becoming a more common cost structure for agent systems.
Multimodality is beginning to shift from “generating content” to “understanding and acting.” MiniMax management defines H3 as an omni-modal model designed to understand text, images, video, audio, and music and to reliably produce different media in response to prompts. Black Forest Labs disclosed that FLUX 3 expands from images into video, audio, and physical-action prediction, while its first robotics model, FLUX-mimic, has entered testing in automotive factories. The company said some tasks can be adapted using as little as 30 minutes of robot data, compared with 30 hours or longer under previous methods, and that deployed systems have a reaction time of 101 milliseconds.
These multimodal cases remain some distance from large-scale revenue, but their validation path is clearer than the claim that “models are getting smarter.” Investors can directly track the amount of data required per task, response latency, deployment counts, human-intervention rates, and customer renewals. Unless these metrics improve consistently, multimodality remains a demonstration capability rather than a stable business.
Reasoning, Training, Multimodal, and Agent Capabilities
Training has not lost its value because of K3’s high efficiency. K3’s performance reflects the combined effects of a larger parameter count, sparse experts, attention improvements, training recipes, and data methodologies. Models still require pretraining to expand their capability frontier, as well as post-training and reinforcement learning to translate those capabilities into higher success rates in coding, tool use, and industry-specific tasks. Interpreting K3 simply as “architectural optimization replacing compute” ignores that it is itself a 2.8-trillion-parameter model.
The changes on the inference side are more direct. A 1-million-token context window, continuous reasoning, and long-running agents will lengthen sessions and increase caching, tool calls, and intermediate results. Smaller attention caches can reduce per-step costs, but users may consequently submit longer documents, run more iterations, and operate more sub-agents concurrently. Whether lower per-task costs lead to a rebound toward higher aggregate token consumption will be the most important volume-price variable over the next several quarters.
Capacity constraints after K3’s launch provided the first demand signal. The company said requests approached the limit of its existing GPU capacity within 48 hours, prompting it to suspend new subscriptions and prioritize service for existing members. This event is inconsistent with the view that efficiency gains will immediately create excess compute capacity. It may also merely reflect a product-launch spike; determining whether the Jevons effect holds will require monitoring normalized usage and paid retention after capacity expansion.
Anthropic’s plan changes provided another pricing signal. According to market reports, Anthropic removed its flagship Claude Fable 5 model from the fixed allowances of certain lower-tier plans. Higher-tier plans retain fixed allowances but impose usage caps, while lower-tier plans switch to usage-based billing after their one-time allowances are exhausted; usage-based pricing is $10 per 1 million input tokens and $50 per 1 million output tokens. If this framework persists, it would indicate that flagship-model inference costs remain difficult to absorb through unlimited low-priced monthly subscriptions.
These changes have two-sided implications for model vendors’ revenue. Usage-based billing can reduce the erosion of fixed-plan gross margins by heavy users, but it may also suppress usage frequency and encourage customers to switch to cheaper models or multi-model routing. Key follow-up indicators include whether caps are relaxed, whether usage-based prices decline, whether heavy users churn, and whether higher-end models can offset higher prices through better success rates.
MiniMax is placing cost competition at the forefront of its product roadmap. Management said M3 has reached daily usage of several trillion tokens while maintaining healthy gross margins across its open platform and API businesses. Its long-term target is to raise gross margin to a high-double-digit level through greater inference efficiency. M3 Pro, scheduled for launch in September—October, is a 3-trillion-parameter-class model, with cost optimization derived from sparse attention, activated parameters, and key-value caching.
MiniMax’s approach shows that large parameter counts do not require abandoning price-performance. Vendors must solve 3 problems simultaneously: how much a single training run costs, how much serving each token costs, and how much completing a customer task costs. The first two determine costs; the last determines whether customers are willing to pay over the long term. If future model launches discuss only parameter counts and rankings without disclosing successful-task costs, inference gross margins, and utilization, their commercial significance will diminish.
Developer tools are already showing signs of usage amplification. Market data indicate that ChatGPT Work and Codex reached 10 million weekly active users, up 67% from 6 million slightly more than one week earlier and approximately 5 times the March level. The metric still requires confirmation on a consistent basis, but the direction is clear: coding and cloud-based agents are moving from experiments by a small number of developers toward broader entry points for everyday work.
Google management disclosed that Gemini API throughput increased from 16 billion tokens per minute last quarter to approximately 22 billion tokens, up 38% quarter over quarter. Usage growth can demonstrate distribution and demand, but cannot establish profitability on its own. Investors must also monitor the model mix, inference costs, paid-user share, cloud gross margins, and whether more traffic is shifting to Google’s internally developed tensor processing units.
Open-Source vs. Closed-Source Competition, Benchmarks, and the Developer Ecosystem
The boundary between open and closed models is shifting from a binary choice to tiered competition. Open-weight models expand usage through deployability, customization, and lower distribution friction; closed frontier models sustain premium pricing through best-in-class capabilities, reliable service, and security tools. Enterprise customers will route tasks between the two rather than committing all workloads to a single model.
K3’s pricing already shows that open weights do not imply permanently low prices. Its cached-input, standard-input, and output prices are $0.30, $3, and $15 per 1 million tokens, respectively, approximately 4 times those of the previous-generation coding model. Open models can also raise prices as long as task success rates and labor savings are sufficiently high. Conversely, if third-party deployments can replicate their capabilities at lower cost, the pricing ceiling for the official API will also be constrained.
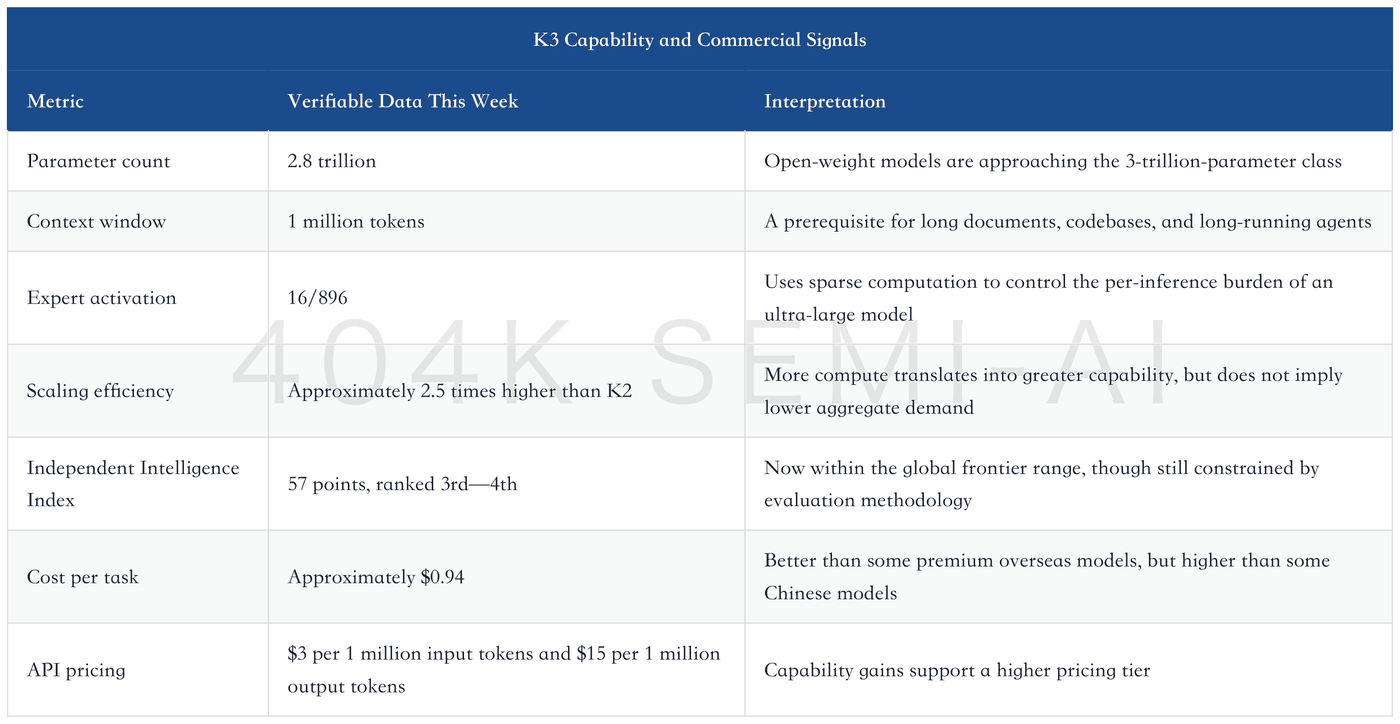
Benchmarks are screening tools, not substitutes for product validation. Different models may each have advantages in coding, long-context processing, visual understanding, scientific reasoning, and output speed. Composite indices compress multiple capabilities into a single number and are also influenced by test sets, agent frameworks, inference budgets, and output length. Investment analysis must at minimum add real-world customer-task success rates and per-task costs.
Rotating frontier leadership will reshape the developer ecosystem. The harder it is for developers to predict which model will be strongest next quarter, the more willing they will be to use unified interfaces, automated routing, and backup models. OpenRouter enables more than 5 million developers to compare, switch among, and settle payments for hundreds of models. Stripe is reportedly in talks to acquire OpenRouter at a potential valuation of approximately $10 billion; the negotiations could still collapse, and other buyers may emerge.
The implication of this potential transaction lies not in the valuation figure itself, but in control of the customer entry point. Stripe already provides OpenRouter with payment, invoicing, tax, and anti-fraud services. If it also gains control of the model-routing entry point, it could participate throughout the process by which developers select models and pay inference fees. The more fragmented the model layer becomes, the greater the switching value of aggregation platforms; however, their bargaining power would decline if leading laboratories restrict resale or cloud providers divert traffic to their own platforms.
Microsoft is demonstrating another routing approach. Microsoft management said that, in certain use cases, its internally developed MAI models can match or outperform general-purpose frontier models using fewer tokens, and that it has begun routing first-party product traffic to MAI. The key issue is not whether MAI leads across the board, but that companies controlling product entry points can select the cheapest qualified model for each task, turning external model procurement into a replaceable cost.
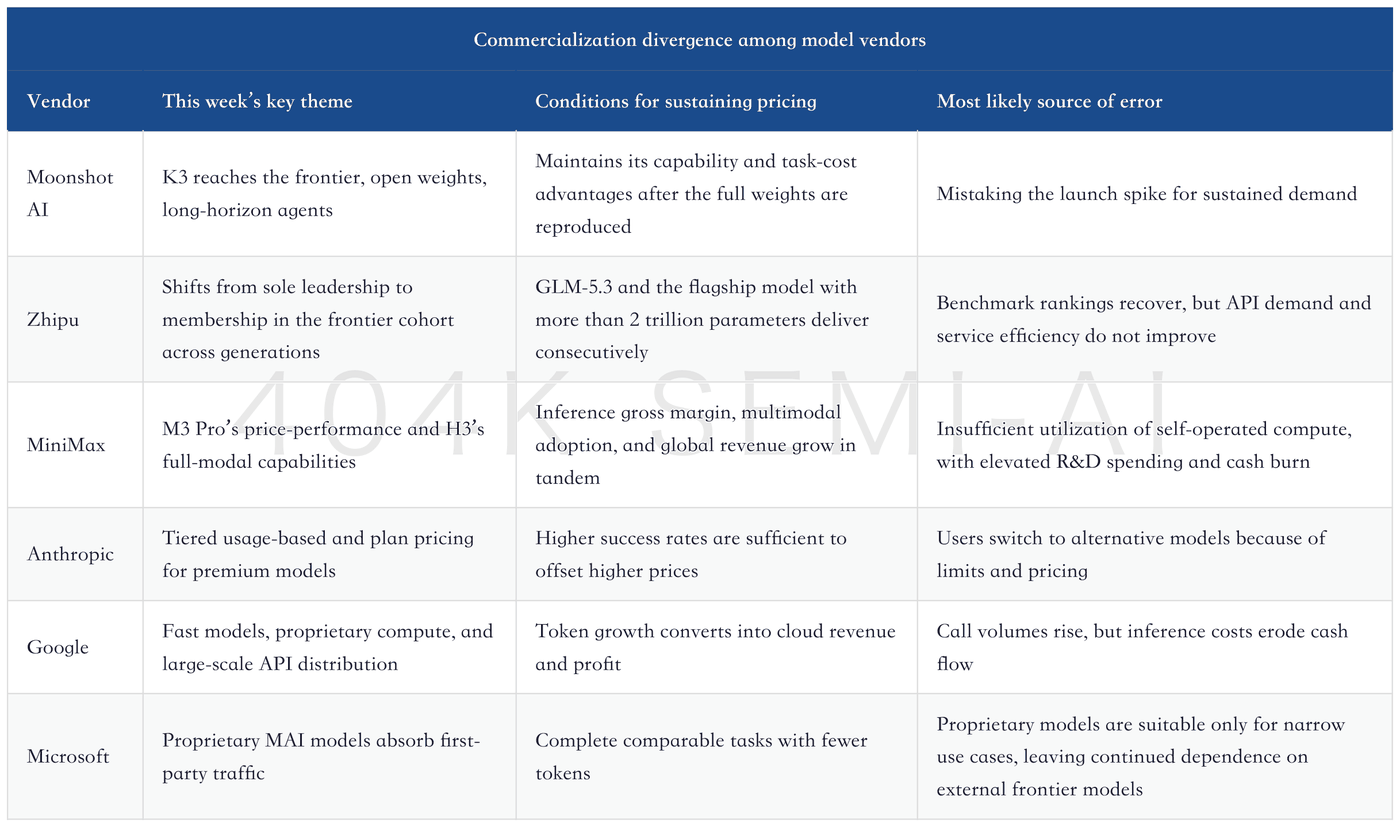
This will divide model vendors into 3 categories. The first possesses sustained frontier capabilities and strong brands, enabling it to defend premium pricing. The second controls product or cloud entry points and can reduce costs through routing and internally developed models. The third achieves only a one-time benchmark lead and lacks stable distribution, resulting in the greatest revenue volatility. Valuations of publicly listed model companies should separate “model capabilities, customer entry points, compute supply, and inference gross margins” rather than subsuming them under a single frontier label.
API Pricing, Commercialization, and Model-Vendor Divergence
Model commercialization is shifting from “cheap tokens for growth” to tiered pricing based on task value. K3’s approximately 4-fold price increase still leaves it with a cost advantage over premium overseas models, while Anthropic protects the inference economics of its flagship models through plan limits. Their approaches differ, but the objective is the same: align heavy usage with actual marginal costs.
The test for Zhipu is whether it can remain in the frontier cohort across model generations. K3 has shortened GLM-5.2’s relative lead, but the relevant research reports still regard GLM-5.2 as a leading domestic production model and identify two validation milestones: GLM-5.3 is expected to be released from late July to August, while a flagship model with more than 2 trillion parameters is expected in September–October. The former will test coding, agentic capabilities, and service efficiency; the latter will test whether Zhipu can advance to the next scale tier.
Model revenue remains at an early stage, and indicative figures are useful only for gauging order of magnitude.
The 4 independent model vendors have approximately US$2.1 billion in combined annualized revenue
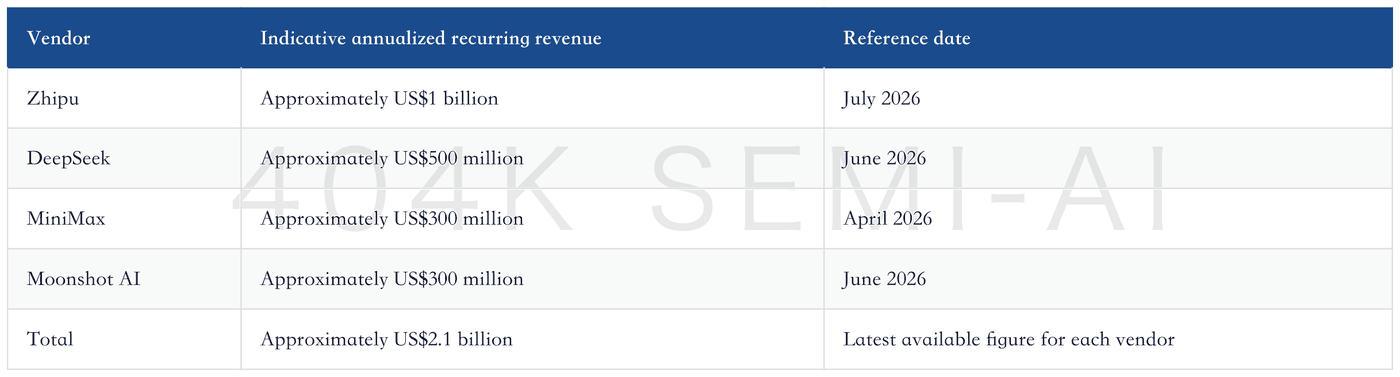
The report also cautions that these figures may differ in scope, definition, and timing, making them unsuitable for precise market-share rankings.
MiniMax’s materials further illustrate the differences in measurement. A management meeting report stated that the company’s annualized recurring revenue had exceeded US$400 million by early June, above the approximately US$300 million as of April used in another report. The difference may reflect growth or variations in scope. The useful indicators to track are not isolated rumored figures, but whether quarterly revenue, API calls, subscription retention, gross margin, and cash burn corroborate one another over time.
Divergent valuations of MiniMax stem from different assumptions. One view requires the company to first demonstrate that M3 Pro has returned to the frontier before assigning a higher premium; another places greater weight on H3’s multimodality, global distribution, per-token cost, and long-term market share. The former is a bet on technological certainty, while the latter is a bet on commercialization and multimodal differentiation. M3 Pro’s capabilities, cost, and adoption rate in September–October will determine which set of assumptions is closer to reality.
Divergent Views, Falsification Tests, and Next Week’s Watchlist
The largest disagreement is whether improvements in model efficiency reduce or amplify total compute demand. This week’s near-term evidence favors the latter: capacity tightened following K3’s launch, long-context and agentic tasks extended session duration, and Gemini API throughput continued to grow. However, this may still reflect a combination of a new-product demand spike and lagging supply, and cannot be directly extrapolated over multiple years.
The first falsification test is whether call volumes fall rapidly after capacity expands. If usage and paid retention decline significantly after K3 subscriptions resume, capacity constraints were primarily driven by launch enthusiasm. The case that efficiency gains are driving demand expansion will become more robust only if call volumes remain steady and average sessions continue to lengthen.
The second falsification test is a failure to reproduce the open-weight model. K3’s full weights are scheduled for release on July 27. Third parties need to verify the actual context window, tool use, VRAM consumption, throughput, quantization loss, and long-horizon task success rate. If independent deployment costs are materially higher than official figures, the open model’s pricing advantage will narrow.
The third falsification test is an improvement in model rankings without revenue growth. Zhipu’s GLM-5.3 and flagship model with more than 2 trillion parameters, as well as MiniMax’s M3 Pro and H3, all have clearly defined release windows. After release, investors should concurrently monitor API calls, subscriptions, enterprise customers, per-task costs, and inference gross margins. Higher rankings without higher revenue would indicate that technological leadership has not translated into business.
The fourth falsification test is a rapid removal of premium-model limits or a substantial price reduction. If Anthropic relaxes fixed quotas while lowering usage-based prices, this may indicate that supply has caught up with demand or that competition is forcing price cuts. If limits persist, scarcity in model services remains; however, user attrition would remind the market that high prices do not automatically translate into high profits.
The fifth falsification test is whether closed ecosystems weaken multi-model routing. OpenRouter’s potential transaction and Microsoft’s shift of traffic toward MAI both demonstrate the value of controlling the routing gateway. If model labs restrict third-party distribution or cloud providers lock customers into their own model marketplaces, the growth potential of independent aggregation platforms will come under pressure.
Next week, 6 indicators warrant priority monitoring: whether K3’s full weights open as scheduled; third-party reproduction results for long-horizon agents; when new K3 subscriptions resume; whether GLM-5.3 enters its release window; whether developer-tool call volumes for Gemini and ChatGPT hold up; and whether Anthropic’s plan limits or usage-based pricing change. Any one of these would provide more evidence of model vendors’ genuine competitiveness than a single day’s benchmark ranking.