
404K SEMI-AI 2026-07-17 AI Model Weekly — Open Weights Advance, Inference Economics Diverge, and Agent Security Catches Up
目录
TL;DR
Overall View This Week
Model Releases, Upgrades, and Capability Changes
Inference, Training, Multimodality, and Agentic Capabilities
Open Versus Proprietary Competition, Benchmarks, and the Developer Ecosystem
API Pricing, Commercialization, and Vendor Divergence
Debates, Counterevidence, and Next Week’s Watchlist
This week, model competition shifted from isolated leaderboard rankings toward deployable capabilities: open-weight models advanced, inference costs continued to decline, but reliability, access controls, and real-world retention increasingly determined the ceiling for commercialization.
TL;DR
Open-weight models closed much of the gap with frontier proprietary models this week. Moonshot AI released Kimi K3 with 2.8T parameters and a third-party Intelligence Index score of 57; Thinking Machines Lab launched Inkling with 975B total parameters, 41B active parameters, up to a 1M-token context window, and an Apache 2.0 license. The capability gap is narrowing, but deployment costs, practical weight availability, and real-world task performance for models of this scale still require validation.
Model vendors are increasingly competing on how much work can be completed per dollar. Kimi K3 performed strongly in agentic and knowledge-work benchmarks and used 21% fewer output tokens across nine evaluations than its predecessor, although its official API output price rose to $15 per million tokens. Inkling controls costs through tiered context-window pricing, while cross-platform testing of DeepSeek V4 shows that inference software optimization alone can improve throughput by severalfold—and in some cases more than 100-fold—for the same model.
OpenAI’s usage growth confirms that capability improvements amplify demand. Codex and ChatGPT Work reached 8 million combined active users, prompting another reset of usage limits and the continued suspension of the five-hour cap, alongside a warning of potential near-term service instability. Investors should track active users, tokens per task, usage-limit policies, and service stability together; model scores alone cannot determine revenue quality.
Google retains a strong distribution advantage, but delays to its flagship model expose product risk. Google’s global search share rose to 91.3% in June, while ChatGPT reached 441 million global mobile daily active users; Gemini and Claude grew faster. At the same time, Gemini 3.5 Pro has reportedly been delayed again because of coding, hallucination, and reliability issues. The scale of Google’s search distribution does not automatically translate into frontier-model leadership.
As agents become more capable, security and permission boundaries become more important. OpenAI disclosed a very small number of accidental file-deletion incidents involving GPT-5.6 operating with full access, without sandboxing or automated review, and introduced GPT-Red for large-scale prompt-injection testing. Anthropic also identified four new autonomous-agent failure modes in simulated environments. Enterprise adoption will increasingly depend on auditability, rollback capabilities, and least-privilege access—not merely task-completion rates.
Overall View This Week
Two changes are occurring simultaneously in the model market. First, open-weight models continue to approach the proprietary frontier, broadening the supply of capabilities and making it easier for developers to select models by task. Second, as the intelligence gap between models narrows, competition is rapidly shifting toward inference costs, deployment complexity, tool use, access controls, and user retention. Model leaderboards still matter to investors, but they are no longer sufficient.
The strongest product signals this week came from Kimi K3 and Inkling. Both use mixture-of-experts architectures, long context windows, and agentic capabilities to compete for developers, but their strategies differ. Kimi K3 is closer to using extreme scale to achieve frontier capabilities, while Inkling emphasizes open weights, adjustable reasoning intensity, and customization through Tinker. The former validates the capability ceiling of Chinese open models; the latter shows that a new US laboratory can still compete for ecosystem adoption with an open license.
The commercial challenge for model vendors is also becoming clearer: customers do not pay for more parameters; they pay for first-pass completion, fewer revisions, low latency, and controllable risk. A model with higher scores may still carry a higher effective price if it requires more output tokens, more human review, or more expensive deployment. Conversely, inference software, caching, routing, and lower reasoning intensity can directly improve gross margins and usage allowances, provided task-success rates are maintained.
Vendor competition has not yet become winner-takes-all. June traffic data show that ChatGPT leads standalone AI applications by scale, Gemini and Claude are growing faster, and Google’s core search franchise remains stable. Users are migrating among multiple models, while enterprises increasingly route tasks by use case. Over the next one to three months, share will ultimately be determined by retention, enterprise API renewals, model-switching costs, and whether developer tools form durable workflows.
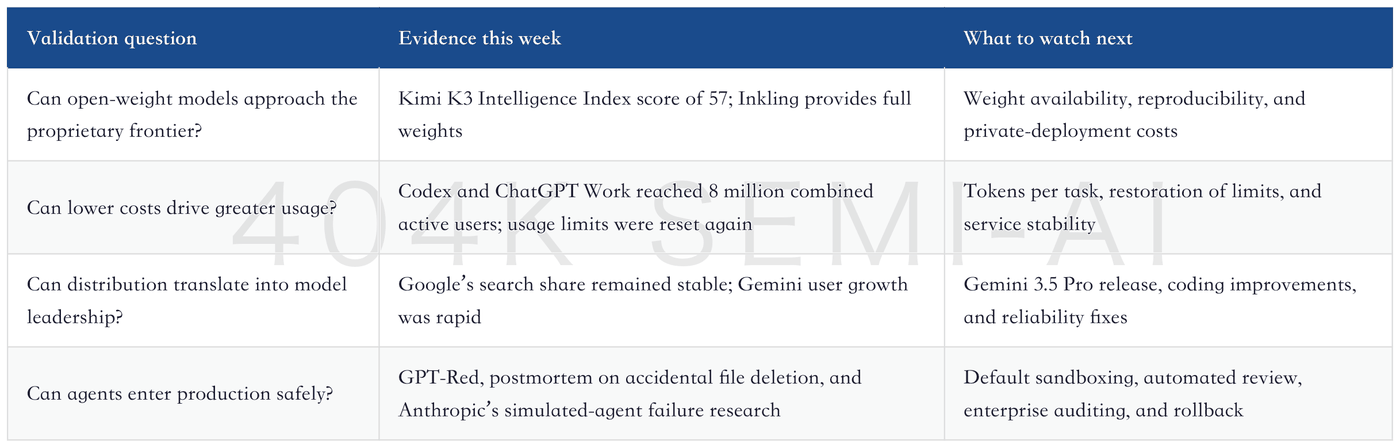
This week’s changes at the model layer can be summarized through four validation questions.
Open Weights Approach the Frontier as Competition Shifts Toward Deployment and Security
Model Releases, Upgrades, and Capability Changes
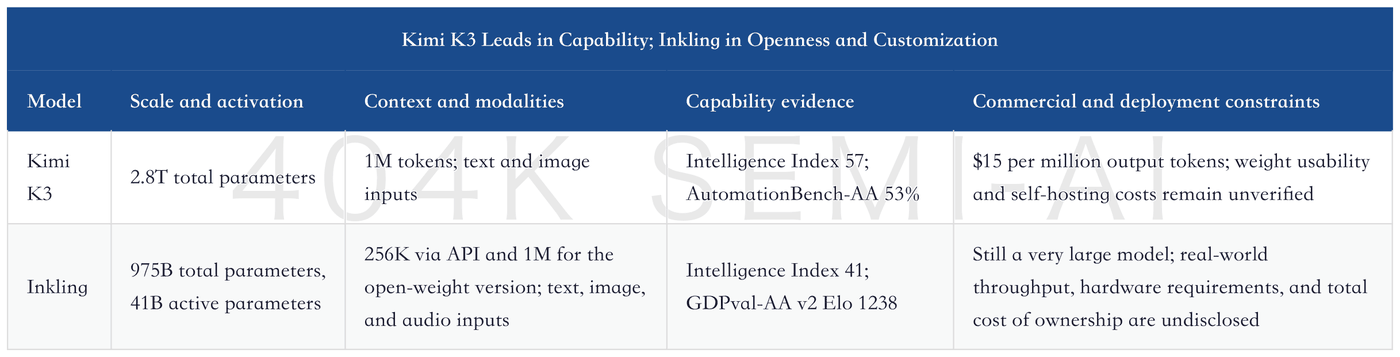
Kimi K3 was the most important open-weight model event this week. Moonshot AI reports a model size of 2.8T parameters, support for a 1M-token context window, and native text and image inputs, with output still primarily text-based. Its third-party Intelligence Index score is 57, placing it close to Claude Opus 4.8 and GPT-5.5 overall, although it still trails this week’s leading proprietary models. The result shows that open models are approaching the frontier, not that the gap has disappeared.
Kimi K3’s strengths are concentrated in agentic tasks and knowledge work. It achieved a GDPval v2 Elo of 1668, an AutomationBench-AA score of 53%, and an AA-Briefcase Elo of 1547.
Across nine evaluations, it used approximately 132 million output tokens, 21% fewer than Kimi K2.6. This data is more meaningful than parameter count alone: the model improved completion quality on complex tasks while reducing output consumption during reasoning.
The trade-off is equally direct. Kimi K3’s average evaluation-task cost was $0.94, close to GPT-5.6 Sol’s $1.04 and higher than some open models.
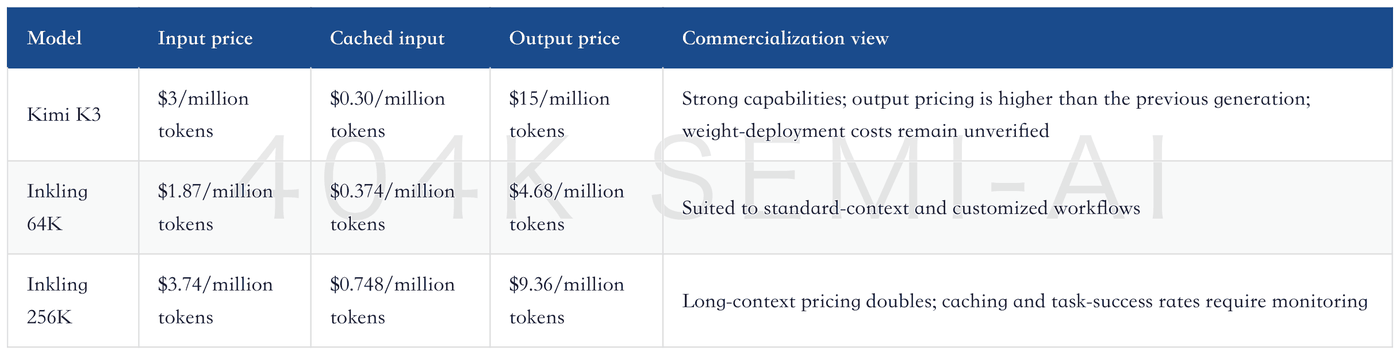
Official API input and output prices are $3 and $15 per million tokens, respectively, with cached input priced at $0.30. The model’s capabilities have entered the frontier range, but its pricing has not entered the lowest-cost range. Investors should monitor self-hosting costs after the weights are released rather than relying solely on official API pricing.
Thinking Machines Lab’s Inkling offers a different open approach. The model has 975B total parameters, activates 41B parameters per token, was pretrained on 45T tokens, and contains 256 experts.
The model natively supports reasoning across text, images, and audio. The Tinker API provides a 256K-token context window, while the open-weight version supports up to 1M tokens and is released under the Apache 2.0 license.
Inkling’s competitiveness lies more in openness, customizability, and adjustable reasoning intensity. It achieved an Intelligence Index score of 41, a GDPval-AA v2 Elo of 1238, a τ³-Banking score of 24%, and a Terminal Bench score of 63.8. It does not match Kimi K3 in aggregate capability, but for developers requiring private deployment, fine-tuning, and workflow customization, its license, context window, and API pricing may matter more than its overall leaderboard position.
The differences between this week’s two open models are best viewed side by side.
The proprietary camp did not deliver a comparably significant flagship release this week and instead exposed execution-timing risk. Gemini 3.5 Pro has reportedly been delayed by several months from its original schedule, with coding capabilities, hallucinations, and reliability among the key issues. Google may introduce an interim Flash version to fill the product gap. For developers, delays to a flagship model directly increase willingness to migrate. Google’s search and mobile distribution can preserve reach, but model usability will determine whether developers keep their workflows within its ecosystem.
Inference, Training, Multimodality, and Agentic Capabilities
Inference optimization is becoming the second competitive battleground beyond model capability. The vendor best able to run a model on day one may differ entirely from the one able to run it fastest four weeks later. Cross-platform testing of the 1.6T-parameter DeepSeek V4 showed strong day-one deployability on both CUDA and Huawei CANN.
AMD’s MI355X initially delivered only one to two tokens per user per second, but throughput improved by more than 100-fold by day 26. The gains came primarily from low-precision kernels, graph execution, operator fusion, and the removal of fallback paths—not from hardware replacement.
This shows that the software stack cannot be treated as an ancillary component of model commercialization. At 50 tokens per user per second, B200 throughput per megawatt increased from 300,000 tokens per second on day one to nearly 500,000 tokens per second, a roughly 1.7-fold improvement driven by software optimization.
GB200 NVL72 was measured at a cost per million tokens more than 10 times lower than H200 across common serving ranges, primarily because 72 GPUs reside within a single high-speed interconnect domain. The variables that ultimately affect revenue and gross margin are effective throughput, concurrency, interactive speed, and rack utilization.
Context windows continue to expand, but a larger maximum does not mean every user should default to a larger window. Kimi K3 and Inkling both market 1M-token context windows, while GPT-5.6 Sol reportedly reduced its available context from 372K to 272K because of billing and usage-volume issues. Product design is shifting from “the larger the maximum, the better” toward configuring context windows, caching, and reasoning intensity by task. This reduces wasteful compute for model vendors and makes customer bills more predictable.
Multimodality is also progressing from simply “seeing images” toward unified workflows. Kimi K3 supports native text and image inputs, while Inkling adds audio and maps different modalities into a shared hidden space. The true commercial test is not the number of supported modalities, but whether multimodal inputs improve first-pass completion rates and whether additional human work is required to restructure results into usable outputs. Inkling remains text-output-only, indicating that omni-modal output is not yet essential for every model.
The capability ceiling for agents is rising, while access risks are expanding in parallel. OpenAI disclosed a very small number of accidental file-deletion incidents involving GPT-5.6 under a combination of full access, no sandboxing, and no automated review. The issue is not merely that “models make mistakes,” but that models now have the ability to execute system operations. Default sandboxing, least-privilege access, review of dangerous commands, and rollback-capable snapshots will become enterprise procurement requirements.
OpenAI’s internal automated red-teaming tool, GPT-Red, is designed to identify prompt-injection vulnerabilities at scale before models are deployed more broadly. During the same period, Anthropic disclosed four additional failure modes for autonomous agents in simulated environments. Together, these developments show that agent security is moving from a research topic into product engineering. Vendors that make attack testing, behavioral auditing, and permission isolation default capabilities will have an easier path into enterprise production environments.
Open Versus Proprietary Competition, Benchmarks, and the Developer Ecosystem
The narrowing gap between open and proprietary models is first changing developers’ bargaining power. Kimi K3 and Inkling provide more deployable alternatives, while Groq plans to retire Llama 4 Scout 17B and retain alternatives including gpt-oss 120B and Qwen 27B. Model catalogs will continue to change, and developers cannot bind applications to a single model name. Stable abstraction layers, evaluation suites, and fallback models are becoming more important than one-time integration speed.
Benchmarks remain useful, but they must be disaggregated. Kimi K3 performed strongly on AutomationBench-AA and knowledge-work evaluations, Inkling ranks near the top among US open-weight models, and DeepSeek V4 demonstrates that inference-engine maturity can materially alter deployment outcomes. Different evaluations answer different questions: aggregate indices measure capability breadth, agent benchmarks measure long-horizon task completion, token consumption measures process efficiency, and live serving tests measure cost and latency. Combining these scores into a single ranking obscures the underlying differences.
June data for Google, ChatGPT, Gemini, and Claude provide a view closer to actual user choice. Web traffic, mobile daily active users, search share, and downloads do not collectively point to a single winner.
Google Retains Distribution Leadership; ChatGPT Leads Standalone AI Applications by Scale
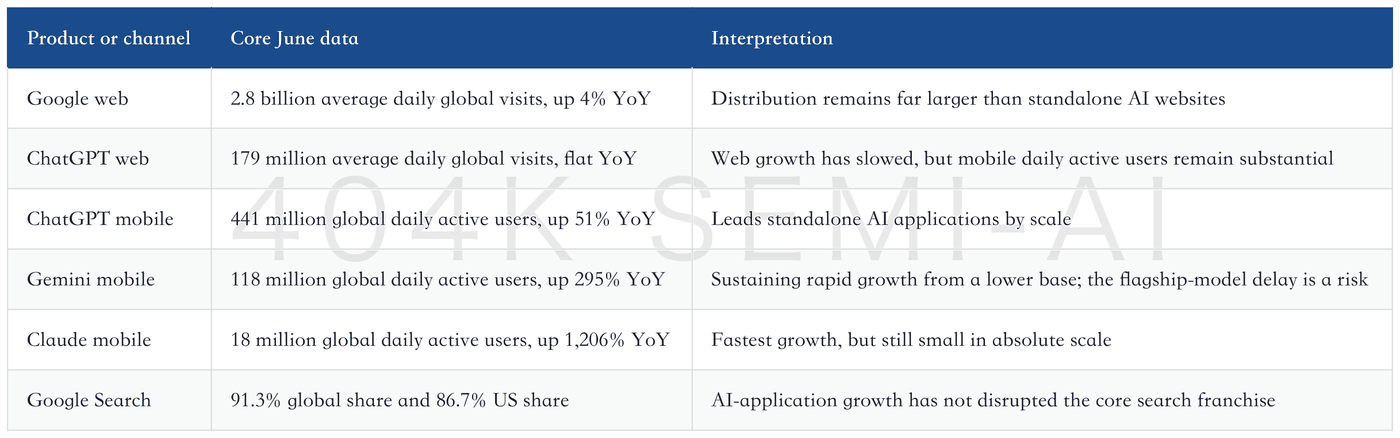
The investment implications are straightforward. Google still controls the largest distribution channel, ChatGPT has established substantial standalone-application scale, and Gemini and Claude are in rapid catch-up phases. Google’s US mobile-search share fell 123 basis points YoY to 92.8% in June, showing that competitive pressure has not disappeared; however, its global search share increased by 171 basis points YoY. The market is more likely to support multiple coexisting access points than to see search displaced by a single chatbot in the near term.
Download data require caution. Global downloads of ChatGPT, Gemini, and Claude declined 12%, 20%, and 20% month over month, respectively, in June, but the data provider noted that its collection methodology had changed and the historical series had not yet been restated. Lower downloads cannot be equated directly with user losses. A more reliable monitoring sequence is mobile daily active users, retention, time spent, and paid conversion, with downloads used to explain the sources of new-user acquisition.
The developer ecosystem continued to expand from “models” toward “models plus tools” this week. Codex and ChatGPT Work reached 8 million combined active users, and the platform reset usage allowances again. ChatGPT’s custom-instruction limit increased from 1,500 to 5,000 characters, expanding its capacity to retain persistent preferences and work requirements. Users no longer want only one-off question answering; they want models that understand standing rules, use tools, complete work, and preserve context.
API Pricing, Commercialization, and Vendor Divergence
API pricing is shifting from a uniform rate toward tiers based on context length, caching, and task value. Kimi K3 commands a higher price for stronger capabilities, while Inkling uses context-window tiers, with pricing doubling for the longer window. Exact pricing is shown below.
The two models cannot be ranked simply by headline price. Kimi K3 offers stronger aggregate and agentic capabilities, while Inkling has lower output pricing and open weights. Customers must compare the total cost of completing the same task, including input length, output tokens, cache hits, failed retries, and human review. A more expensive model may have a lower final cost if it succeeds on the first attempt; conversely, an open model requiring a very large cluster may not offer a low total cost of ownership despite low API pricing.
This week’s model-service pricing and positioning are best compared as follows.
Kimi K3 Commands a Capability Premium; Inkling Trades Tiered Pricing for Flexibility
OpenAI’s growth shows that lower costs do not automatically reduce total demand. After active-user growth for Codex and ChatGPT Work, the platform expanded capacity, reset limits, and temporarily removed the five-hour cap rather than retaining all efficiency gains as gross margin. Stronger models encourage users to migrate more work into AI, potentially increasing tokens per user. For model vendors, near-term revenue is driven by usage volume, while long-term profitability depends on inference costs declining faster than usage and service-assurance costs increase.
Vendor differentiation will develop along three dimensions. OpenAI is strong in product iteration, coding agents, and standalone-application scale; Anthropic is strong in enterprise usage, Claude Code, and safety research; Google is strong in search, mobile, and cloud distribution, but must quickly address delays to its flagship model; Moonshot AI and Thinking Machines Lab are using open weights to compete for developers; and inference platforms are competing for usage through model catalogs, speed, and price. No vendor leads comprehensively across capability, cost, distribution, openness, and safety.
Debates, Counterevidence, and Next Week’s Watchlist
The first debate is whether open-weight models have already matched the proprietary frontier. Kimi K3 performed strongly on several agent benchmarks, while Inkling raised the ceiling for US open models, but gaps remain in aggregate indices, presentation quality, and absolute cost. If the released weights cannot be reproduced on reasonably priced hardware, leaderboard strength will not translate into developer adoption. Next week, investors should track weight downloads, community reproductions, quantized versions, and real-world throughput.
The second debate is whether lower model prices will compress model-layer profits or expand the overall market. Cheaper tokens reduce unit pricing but may generate more agentic tasks and longer workflows. This cannot be validated through usage volume alone; investors must also track tokens per task, success rates, usage-limit policies, API revenue, and inference gross margins. If usage rises while service instability worsens and limits are repeatedly tightened, demand growth may not translate smoothly into profits.
The third debate is whether Google’s distribution advantage can retain developers. Google Search remains strong and Gemini user growth is rapid, but delays to its flagship model may cede high-value coding and agentic workflows to competitors. The most important product milestone next week is the timeline for Gemini 3.5 Pro or an interim Flash version, alongside reproducible improvements in coding, hallucinations, and reliability.
The fourth debate is whether agents can be safely granted authority in enterprise environments. Accidental file deletion, prompt injection, and simulated-agent failures all show that as task-completion rates rise, the potential impact of erroneous actions expands as well. Investors should monitor whether sandboxing becomes the default, whether automated review can block high-risk commands, whether enterprises receive complete audit logs, and whether incidents can be rolled back quickly. If safety capabilities cannot be productized, agent adoption will remain confined to low-permission scenarios.
Next week’s monitoring does not require chasing every new product. Six indicators are sufficient: whether Kimi K3’s weights are genuinely released, the per-token cost of open deployment, community reproduction tests of Inkling, active users and usage-limit changes for Codex and ChatGPT Work, the release timing of Gemini 3.5 Pro, and mobile daily-active-user trends for Google and the leading AI applications. If any current thesis is wrong, the evidence should appear first in these figures.
Related Reading
404K SEMI-AI 2026-07-05 Storage Weekly — AI Inference Memory, NAND/eSSD, Nearline HDD
404K SEMI-AI Morning Brief 2026-07-02 — Meta Compute Monetization, Strong Memory Pricing, Software Catches the Rotation404K SEMI-AI 2026-07-17 AI Model Weekly — Open Weights Advance, Inference Economics Diverge, and Agent Security Catches Up
目录
TL;DR
Overall View This Week
Model Releases, Upgrades, and Capability Changes
Inference, Training, Multimodality, and Agentic Capabilities
Open Versus Proprietary Competition, Benchmarks, and the Developer Ecosystem
API Pricing, Commercialization, and Vendor Divergence
Debates, Counterevidence, and Next Week’s Watchlist
This week, model competition shifted from isolated leaderboard rankings toward deployable capabilities: open-weight models advanced, inference costs continued to decline, but reliability, access controls, and real-world retention increasingly determined the ceiling for commercialization.
TL;DR
Open-weight models closed much of the gap with frontier proprietary models this week. Moonshot AI released Kimi K3 with 2.8T parameters and a third-party Intelligence Index score of 57; Thinking Machines Lab launched Inkling with 975B total parameters, 41B active parameters, up to a 1M-token context window, and an Apache 2.0 license. The capability gap is narrowing, but deployment costs, practical weight availability, and real-world task performance for models of this scale still require validation.
Model vendors are increasingly competing on how much work can be completed per dollar. Kimi K3 performed strongly in agentic and knowledge-work benchmarks and used 21% fewer output tokens across nine evaluations than its predecessor, although its official API output price rose to $15 per million tokens. Inkling controls costs through tiered context-window pricing, while cross-platform testing of DeepSeek V4 shows that inference software optimization alone can improve throughput by severalfold—and in some cases more than 100-fold—for the same model.
OpenAI’s usage growth confirms that capability improvements amplify demand. Codex and ChatGPT Work reached 8 million combined active users, prompting another reset of usage limits and the continued suspension of the five-hour cap, alongside a warning of potential near-term service instability. Investors should track active users, tokens per task, usage-limit policies, and service stability together; model scores alone cannot determine revenue quality.
Google retains a strong distribution advantage, but delays to its flagship model expose product risk. Google’s global search share rose to 91.3% in June, while ChatGPT reached 441 million global mobile daily active users; Gemini and Claude grew faster. At the same time, Gemini 3.5 Pro has reportedly been delayed again because of coding, hallucination, and reliability issues. The scale of Google’s search distribution does not automatically translate into frontier-model leadership.
As agents become more capable, security and permission boundaries become more important. OpenAI disclosed a very small number of accidental file-deletion incidents involving GPT-5.6 operating with full access, without sandboxing or automated review, and introduced GPT-Red for large-scale prompt-injection testing. Anthropic also identified four new autonomous-agent failure modes in simulated environments. Enterprise adoption will increasingly depend on auditability, rollback capabilities, and least-privilege access—not merely task-completion rates.
Overall View This Week
Two changes are occurring simultaneously in the model market. First, open-weight models continue to approach the proprietary frontier, broadening the supply of capabilities and making it easier for developers to select models by task. Second, as the intelligence gap between models narrows, competition is rapidly shifting toward inference costs, deployment complexity, tool use, access controls, and user retention. Model leaderboards still matter to investors, but they are no longer sufficient.
The strongest product signals this week came from Kimi K3 and Inkling. Both use mixture-of-experts architectures, long context windows, and agentic capabilities to compete for developers, but their strategies differ. Kimi K3 is closer to using extreme scale to achieve frontier capabilities, while Inkling emphasizes open weights, adjustable reasoning intensity, and customization through Tinker. The former validates the capability ceiling of Chinese open models; the latter shows that a new US laboratory can still compete for ecosystem adoption with an open license.
The commercial challenge for model vendors is also becoming clearer: customers do not pay for more parameters; they pay for first-pass completion, fewer revisions, low latency, and controllable risk. A model with higher scores may still carry a higher effective price if it requires more output tokens, more human review, or more expensive deployment. Conversely, inference software, caching, routing, and lower reasoning intensity can directly improve gross margins and usage allowances, provided task-success rates are maintained.
Vendor competition has not yet become winner-takes-all. June traffic data show that ChatGPT leads standalone AI applications by scale, Gemini and Claude are growing faster, and Google’s core search franchise remains stable. Users are migrating among multiple models, while enterprises increasingly route tasks by use case. Over the next one to three months, share will ultimately be determined by retention, enterprise API renewals, model-switching costs, and whether developer tools form durable workflows.
This week’s changes at the model layer can be summarized through four validation questions.
Open Weights Approach the Frontier as Competition Shifts Toward Deployment and Security
Model Releases, Upgrades, and Capability Changes
Kimi K3 was the most important open-weight model event this week. Moonshot AI reports a model size of 2.8T parameters, support for a 1M-token context window, and native text and image inputs, with output still primarily text-based. Its third-party Intelligence Index score is 57, placing it close to Claude Opus 4.8 and GPT-5.5 overall, although it still trails this week’s leading proprietary models. The result shows that open models are approaching the frontier, not that the gap has disappeared.
Kimi K3’s strengths are concentrated in agentic tasks and knowledge work. It achieved a GDPval v2 Elo of 1668, an AutomationBench-AA score of 53%, and an AA-Briefcase Elo of 1547.
Across nine evaluations, it used approximately 132 million output tokens, 21% fewer than Kimi K2.6. This data is more meaningful than parameter count alone: the model improved completion quality on complex tasks while reducing output consumption during reasoning.
The trade-off is equally direct. Kimi K3’s average evaluation-task cost was $0.94, close to GPT-5.6 Sol’s $1.04 and higher than some open models.
Official API input and output prices are $3 and $15 per million tokens, respectively, with cached input priced at $0.30. The model’s capabilities have entered the frontier range, but its pricing has not entered the lowest-cost range. Investors should monitor self-hosting costs after the weights are released rather than relying solely on official API pricing.
Thinking Machines Lab’s Inkling offers a different open approach. The model has 975B total parameters, activates 41B parameters per token, was pretrained on 45T tokens, and contains 256 experts.
The model natively supports reasoning across text, images, and audio. The Tinker API provides a 256K-token context window, while the open-weight version supports up to 1M tokens and is released under the Apache 2.0 license.
Inkling’s competitiveness lies more in openness, customizability, and adjustable reasoning intensity. It achieved an Intelligence Index score of 41, a GDPval-AA v2 Elo of 1238, a τ³-Banking score of 24%, and a Terminal Bench score of 63.8. It does not match Kimi K3 in aggregate capability, but for developers requiring private deployment, fine-tuning, and workflow customization, its license, context window, and API pricing may matter more than its overall leaderboard position.
The differences between this week’s two open models are best viewed side by side.
The proprietary camp did not deliver a comparably significant flagship release this week and instead exposed execution-timing risk. Gemini 3.5 Pro has reportedly been delayed by several months from its original schedule, with coding capabilities, hallucinations, and reliability among the key issues. Google may introduce an interim Flash version to fill the product gap. For developers, delays to a flagship model directly increase willingness to migrate. Google’s search and mobile distribution can preserve reach, but model usability will determine whether developers keep their workflows within its ecosystem.
Inference, Training, Multimodality, and Agentic Capabilities
Inference optimization is becoming the second competitive battleground beyond model capability. The vendor best able to run a model on day one may differ entirely from the one able to run it fastest four weeks later. Cross-platform testing of the 1.6T-parameter DeepSeek V4 showed strong day-one deployability on both CUDA and Huawei CANN.
AMD’s MI355X initially delivered only one to two tokens per user per second, but throughput improved by more than 100-fold by day 26. The gains came primarily from low-precision kernels, graph execution, operator fusion, and the removal of fallback paths—not from hardware replacement.
This shows that the software stack cannot be treated as an ancillary component of model commercialization. At 50 tokens per user per second, B200 throughput per megawatt increased from 300,000 tokens per second on day one to nearly 500,000 tokens per second, a roughly 1.7-fold improvement driven by software optimization.
GB200 NVL72 was measured at a cost per million tokens more than 10 times lower than H200 across common serving ranges, primarily because 72 GPUs reside within a single high-speed interconnect domain. The variables that ultimately affect revenue and gross margin are effective throughput, concurrency, interactive speed, and rack utilization.
Context windows continue to expand, but a larger maximum does not mean every user should default to a larger window. Kimi K3 and Inkling both market 1M-token context windows, while GPT-5.6 Sol reportedly reduced its available context from 372K to 272K because of billing and usage-volume issues. Product design is shifting from “the larger the maximum, the better” toward configuring context windows, caching, and reasoning intensity by task. This reduces wasteful compute for model vendors and makes customer bills more predictable.
Multimodality is also progressing from simply “seeing images” toward unified workflows. Kimi K3 supports native text and image inputs, while Inkling adds audio and maps different modalities into a shared hidden space. The true commercial test is not the number of supported modalities, but whether multimodal inputs improve first-pass completion rates and whether additional human work is required to restructure results into usable outputs. Inkling remains text-output-only, indicating that omni-modal output is not yet essential for every model.
The capability ceiling for agents is rising, while access risks are expanding in parallel. OpenAI disclosed a very small number of accidental file-deletion incidents involving GPT-5.6 under a combination of full access, no sandboxing, and no automated review. The issue is not merely that “models make mistakes,” but that models now have the ability to execute system operations. Default sandboxing, least-privilege access, review of dangerous commands, and rollback-capable snapshots will become enterprise procurement requirements.
OpenAI’s internal automated red-teaming tool, GPT-Red, is designed to identify prompt-injection vulnerabilities at scale before models are deployed more broadly. During the same period, Anthropic disclosed four additional failure modes for autonomous agents in simulated environments. Together, these developments show that agent security is moving from a research topic into product engineering. Vendors that make attack testing, behavioral auditing, and permission isolation default capabilities will have an easier path into enterprise production environments.
Open Versus Proprietary Competition, Benchmarks, and the Developer Ecosystem
The narrowing gap between open and proprietary models is first changing developers’ bargaining power. Kimi K3 and Inkling provide more deployable alternatives, while Groq plans to retire Llama 4 Scout 17B and retain alternatives including gpt-oss 120B and Qwen 27B. Model catalogs will continue to change, and developers cannot bind applications to a single model name. Stable abstraction layers, evaluation suites, and fallback models are becoming more important than one-time integration speed.
Benchmarks remain useful, but they must be disaggregated. Kimi K3 performed strongly on AutomationBench-AA and knowledge-work evaluations, Inkling ranks near the top among US open-weight models, and DeepSeek V4 demonstrates that inference-engine maturity can materially alter deployment outcomes. Different evaluations answer different questions: aggregate indices measure capability breadth, agent benchmarks measure long-horizon task completion, token consumption measures process efficiency, and live serving tests measure cost and latency. Combining these scores into a single ranking obscures the underlying differences.
June data for Google, ChatGPT, Gemini, and Claude provide a view closer to actual user choice. Web traffic, mobile daily active users, search share, and downloads do not collectively point to a single winner.
Google Retains Distribution Leadership; ChatGPT Leads Standalone AI Applications by Scale
The investment implications are straightforward. Google still controls the largest distribution channel, ChatGPT has established substantial standalone-application scale, and Gemini and Claude are in rapid catch-up phases. Google’s US mobile-search share fell 123 basis points YoY to 92.8% in June, showing that competitive pressure has not disappeared; however, its global search share increased by 171 basis points YoY. The market is more likely to support multiple coexisting access points than to see search displaced by a single chatbot in the near term.
Download data require caution. Global downloads of ChatGPT, Gemini, and Claude declined 12%, 20%, and 20% month over month, respectively, in June, but the data provider noted that its collection methodology had changed and the historical series had not yet been restated. Lower downloads cannot be equated directly with user losses. A more reliable monitoring sequence is mobile daily active users, retention, time spent, and paid conversion, with downloads used to explain the sources of new-user acquisition.
The developer ecosystem continued to expand from “models” toward “models plus tools” this week. Codex and ChatGPT Work reached 8 million combined active users, and the platform reset usage allowances again. ChatGPT’s custom-instruction limit increased from 1,500 to 5,000 characters, expanding its capacity to retain persistent preferences and work requirements. Users no longer want only one-off question answering; they want models that understand standing rules, use tools, complete work, and preserve context.
API Pricing, Commercialization, and Vendor Divergence
API pricing is shifting from a uniform rate toward tiers based on context length, caching, and task value. Kimi K3 commands a higher price for stronger capabilities, while Inkling uses context-window tiers, with pricing doubling for the longer window. Exact pricing is shown below.
The two models cannot be ranked simply by headline price. Kimi K3 offers stronger aggregate and agentic capabilities, while Inkling has lower output pricing and open weights. Customers must compare the total cost of completing the same task, including input length, output tokens, cache hits, failed retries, and human review. A more expensive model may have a lower final cost if it succeeds on the first attempt; conversely, an open model requiring a very large cluster may not offer a low total cost of ownership despite low API pricing.
This week’s model-service pricing and positioning are best compared as follows.
Kimi K3 Commands a Capability Premium; Inkling Trades Tiered Pricing for Flexibility
OpenAI’s growth shows that lower costs do not automatically reduce total demand. After active-user growth for Codex and ChatGPT Work, the platform expanded capacity, reset limits, and temporarily removed the five-hour cap rather than retaining all efficiency gains as gross margin. Stronger models encourage users to migrate more work into AI, potentially increasing tokens per user. For model vendors, near-term revenue is driven by usage volume, while long-term profitability depends on inference costs declining faster than usage and service-assurance costs increase.
Vendor differentiation will develop along three dimensions. OpenAI is strong in product iteration, coding agents, and standalone-application scale; Anthropic is strong in enterprise usage, Claude Code, and safety research; Google is strong in search, mobile, and cloud distribution, but must quickly address delays to its flagship model; Moonshot AI and Thinking Machines Lab are using open weights to compete for developers; and inference platforms are competing for usage through model catalogs, speed, and price. No vendor leads comprehensively across capability, cost, distribution, openness, and safety.
Debates, Counterevidence, and Next Week’s Watchlist
The first debate is whether open-weight models have already matched the proprietary frontier. Kimi K3 performed strongly on several agent benchmarks, while Inkling raised the ceiling for US open models, but gaps remain in aggregate indices, presentation quality, and absolute cost. If the released weights cannot be reproduced on reasonably priced hardware, leaderboard strength will not translate into developer adoption. Next week, investors should track weight downloads, community reproductions, quantized versions, and real-world throughput.
The second debate is whether lower model prices will compress model-layer profits or expand the overall market. Cheaper tokens reduce unit pricing but may generate more agentic tasks and longer workflows. This cannot be validated through usage volume alone; investors must also track tokens per task, success rates, usage-limit policies, API revenue, and inference gross margins. If usage rises while service instability worsens and limits are repeatedly tightened, demand growth may not translate smoothly into profits.
The third debate is whether Google’s distribution advantage can retain developers. Google Search remains strong and Gemini user growth is rapid, but delays to its flagship model may cede high-value coding and agentic workflows to competitors. The most important product milestone next week is the timeline for Gemini 3.5 Pro or an interim Flash version, alongside reproducible improvements in coding, hallucinations, and reliability.
The fourth debate is whether agents can be safely granted authority in enterprise environments. Accidental file deletion, prompt injection, and simulated-agent failures all show that as task-completion rates rise, the potential impact of erroneous actions expands as well. Investors should monitor whether sandboxing becomes the default, whether automated review can block high-risk commands, whether enterprises receive complete audit logs, and whether incidents can be rolled back quickly. If safety capabilities cannot be productized, agent adoption will remain confined to low-permission scenarios.
Next week’s monitoring does not require chasing every new product. Six indicators are sufficient: whether Kimi K3’s weights are genuinely released, the per-token cost of open deployment, community reproduction tests of Inkling, active users and usage-limit changes for Codex and ChatGPT Work, the release timing of Gemini 3.5 Pro, and mobile daily-active-user trends for Google and the leading AI applications. If any current thesis is wrong, the evidence should appear first in these figures.
Related Reading
404K SEMI-AI 2026-07-05 Storage Weekly — AI Inference Memory, NAND/eSSD, Nearline HDD