
404K SEMI-AI 2026-07-12 Weekly AI Model Update — Intelligence Inflection Point, Diverging Open-Source Winners, and Agentic Workflows
目录
Overall View This Week
Model Releases, Upgrades, and Capability Changes
GLM-5.2 Combines Long Context, Coding, and Agentic Capabilities in a Commercially Deployable Model
DeepSeek Focuses Its Upgrade on the Inference-Service Layer
LongCat 2.0 Demonstrates That Ultra-Large Models and Sparse Activation Can Coexist
MiniMax M3 Completes the Product Portfolio, but Pricing Power Remains Unproven
Reasoning, Training, Multimodal, and Agent Capabilities
Inference Efficiency Has Become Part of Model Capability
Agents Are Shifting Competitive Metrics from Token Volume to Task Output
Multimodal Remains One of the Few Areas with Relatively Strong Pricing
Open- vs. Closed-Source Competition, Benchmarks, and the Developer Ecosystem
Open Weights Have Changed Revenue Distribution, Not Eliminated Official APIs
Open Source, Open Weights, and Closed Source Are Forming a Tiered Mix
Benchmarks Must Be Paired with Real-World Usage Data
API Pricing, Commercialization, and Divergence Among Model Providers
The Addressable Market Is Large, but Value Is More Likely to Concentrate in Platforms and Leading Models
Zhipu’s Rising Prices and Volumes Are the Other Side of Its Heavy Investment
MiniMax Needs Its Next-Generation Model to Restore Pricing Power
Platform Providers and Independent Labs Will Coexist Over the Long Term
Divergent Views, Disconfirming Evidence, and Items to Watch Next Week
Chinese models crossed two thresholds this week: capability and commercialization. Coding, long-context, and agentic tasks are entering the global top tier, while official APIs, cloud channels, and first-party workflows are becoming the primary mechanisms for value capture. Open weights have expanded model distribution but also accelerated price comparison and traffic rerouting, exposing pricing pressure earlier for vendors with weaker models. GLM-5.2, DeepSeek V4, LongCat 2.0, and MiniMax M3 represent different approaches. Competition has shifted from “who can train a model” to “who can reliably complete work at a lower cost per task.”
404K SEMI-AI | 2026-07-12
Overall View This Week
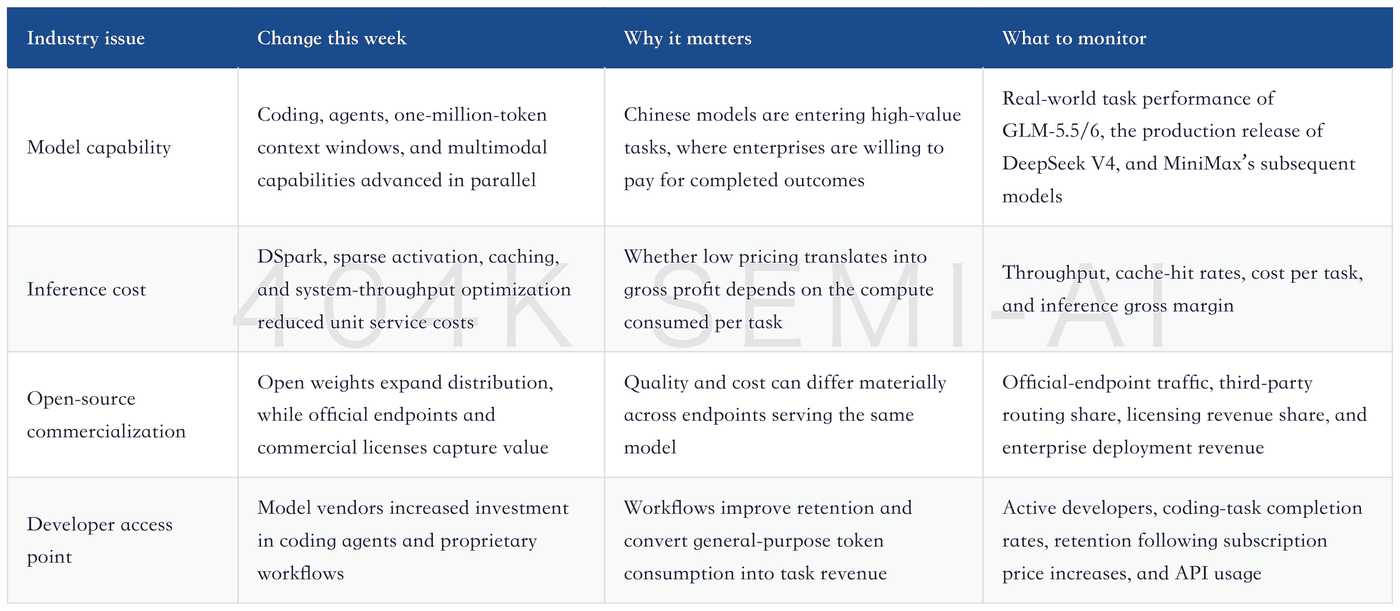
Chinese foundation models have entered a stage of “sufficient capability and stratified commercialization.” Goldman Sachs believes Chinese models have become “good enough” for global adoption in certain coding and agentic tasks. GLM-5.2 combines a one-million-token context window, long-horizon task execution, and coding capabilities in a single model. DeepSeek continues to reduce unit costs through inference-service optimization, while Meituan’s LongCat 2.0 demonstrates that ultra-large parameter counts, sparse activation, and domestic computing clusters can be deployed together. Capability gains can now influence enterprise model selection. Competition will increasingly depend on task-completion rates, service reliability, and total cost per job.
Open weights are amplifying the advantages of strong models while accelerating the elimination of weaker ones. Publicly available weights make it easier for developers, cloud platforms, and enterprises to test, deploy, and migrate models, materially increasing distribution speed. The trade-off is that third parties can deploy models independently, pushing basic dialogue, summarization, translation, and question-answering more rapidly into price competition. Strong models can still monetize through their latest versions, long-context reliability, tool use, caching, service-level agreements, and enterprise support. Models without a clear capability advantage are more vulnerable to replacement by routing platforms.
Model companies are competing to control workflow entry points. Z Code, MiniMax Code, and other coding-agent products share a straightforward objective: charge customers for completed tasks while embedding token consumption into repository indexing, memory, tool execution, debugging, and permission management. If model vendors only sell general-purpose APIs, customer relationships remain with cloud platforms, aggregation routers, and AI coding tools. Controlling first-party workflows gives vendors access to real-world usage data, improves retention, and reduces exposure to pure price competition.
Competitive outcomes diverged materially this week. JPMorgan raised its price target for Zhipu AI from HK$1,800 to HK$2,000 while cutting its MiniMax target from HK$400 to HK$300. Goldman Sachs rates Zhipu AI Neutral with a HK$1,880 price target, recognizing its model position but arguing that the current valuation already reflects substantial growth. Institutions disagree on valuation but broadly agree on the industry direction: model leadership, inference efficiency, and financial strength must all be present to convert open distribution into sustainable revenue.
Capability, cost, distribution, and access points jointly determine this week’s winners
Model Releases, Upgrades, and Capability Changes
GLM-5.2 Combines Long Context, Coding, and Agentic Capabilities in a Commercially Deployable Model
GLM-5.2 is the clearest capability benchmark this week. According to Goldman Sachs, GLM-5.1 can work autonomously on a single task for up to eight hours, while GLM-5.2 extends long-horizon task execution into a usable one-million-token context window. The model ranks second globally on Code Arena’s web-development leaderboard and third globally on GDPval-AA, a benchmark for agents performing real-world work, while also ranking among the leading Chinese and open-source models.
The commercial value of a one-million-token window comes from engineering tasks, not simply the ability to “read more text.” Coding agents must repeatedly access repositories, tool definitions, historical changes, and intermediate states. Only a sufficiently long context gives a model the opportunity to sustain multi-step task execution. If context handling is unstable, a large headline window will not translate into customer spending. Next week, attention should remain on GLM-5.2’s completion rates in repository-level understanding, long-horizon debugging, tool execution, and error recovery rather than static benchmark rankings alone.
Zhipu AI’s accelerating iteration cycle is shortening the useful life of capability leadership. Goldman Sachs reports that Zhipu AI typically releases minor upgrades every one to two months and major versions every seven to eight months. The company plans to continue advancing GLM6, Z Code, and its agent products. The investment implication of rapid iteration is straightforward: leading models can absorb real-world coding data more quickly, leaving lagging models less time to catch up. The risk is equally clear: a weak major release could rapidly redirect pricing power and developer traffic elsewhere.
DeepSeek Focuses Its Upgrade on the Inference-Service Layer
DeepSeek demonstrated this week through DSpark that the user experience can improve materially without changing model weights. Goldman Sachs reports that DSpark has already been deployed in the online services for DeepSeek V4 Flash and V4 Pro. Per-user generation speed increased by 60%–85% for V4 Flash and 57%–78% for V4 Pro, with no changes to model weights or output quality.
This development shifts industry attention from training parameters back to service efficiency. When enterprises purchase APIs, what they ultimately experience is latency, throughput, caching, tool-use reliability, and time to task completion. As official services continue to improve, material performance differences may emerge between endpoints serving the same model. If third-party deployments cannot keep pace with the service stack, lower prices alone may not win high-value workloads.
The production release of DeepSeek V4 and time-of-day pricing will test demand elasticity. Goldman Sachs expects the production version of DeepSeek V4 to launch in mid-July, with peak-period pricing for V4 Pro and V4 Flash set at twice off-peak rates. Time-of-day pricing indicates that compute demand from work and productivity use cases is already creating congestion. Three data points should be monitored: whether usage holds after peak-period price increases, whether traffic can be shifted effectively to off-peak periods, and whether improved service reliability can offset higher prices.
LongCat 2.0 Demonstrates That Ultra-Large Models and Sparse Activation Can Coexist
Meituan’s LongCat 2.0 offers an alternative to activating the full parameter set. Goldman Sachs reports that the model was released on June 30 with 1.6 trillion total parameters and was trained and deployed on a cluster of 50,000 domestically produced accelerators. It uses a mixture-of-experts architecture and LongCat sparse attention and supports a one-million-token context window. Each token activates an average of only 48 billion parameters, or approximately 3% of the total.
Model scale and inference cost can therefore be managed separately. Total parameters provide capacity, while sparse activation controls compute per request. If this approach can maintain quality in real-world coding tasks, model vendors may continue expanding capabilities despite compute constraints. The risk is that successful training does not automatically translate into commercial success. Long-context reliability, inference throughput, tool use, and developer adoption still require validation.
MiniMax M3 Completes the Product Portfolio, but Pricing Power Remains Unproven
With a one-million-token context window, native multimodality, an API, and MiniMax Code, M3 completes MiniMax’s product portfolio. JPMorgan believes M3 strengthens MiniMax’s product narrative and preserves its ability to compete for overseas developers and in multimodal and agentic use cases. The central issues remain capability differentiation and paid conversion: institutions view the prolonged 50% discount on M3 as a sign that the model has yet to establish a capability premium.
Discounting can increase near-term usage but cannot independently prove commercial quality. MiniMax must validate three points with its next-generation model: a narrower capability gap with leading domestic models, sustained API usage after discounts are withdrawn, and improved user retention from MiniMax Code. If any one of these is missing, traffic generated by open weights may continue to migrate to cloud platforms and aggregation routers.
Reasoning, Training, Multimodal, and Agent Capabilities
Inference Efficiency Has Become Part of Model Capability
Enterprise customers are buying task-completion services; per-token pricing is only one component of cost. Models must repeatedly read system prompts, code repositories, tool definitions, and intermediate states within long contexts, making cache hit rates a direct driver of actual bills. Throughput determines how many requests can be served per unit of time, while the share of activated parameters determines the compute required for each generation. Together, these three factors determine inference gross margin and response speed.
Goldman Sachs incorporates throughput, cache hit rate, parameter activation ratio, and inference gross margin into its model competition framework. This framework is closer to the underlying economics than leaderboard rankings alone: leaderboards indicate whether a model can perform a task, while service metrics indicate how much customers must pay, whether the task can be completed reliably, and whether the provider can generate a gross profit. Chinese models commonly use mixture-of-experts and sparse attention architectures to reduce the activated share per token to 3%–5% of total parameters, offsetting constraints on access to high-end compute.
Zhipu’s system optimizations provide verifiable figures. According to Goldman Sachs, the GLM-5 series increased system throughput by as much as 132% in coding-agent scenarios through LayerSplit’s tiered KV-cache storage. Zhipu also uses asynchronous reinforcement-learning infrastructure and has adapted GLM-5.2 inference for multiple domestic Chinese chips. Hardware matters here only as context for model costs: broader compatibility expands available inference capacity, which must ultimately translate into better API availability, lower unit costs, and improved gross margins.
Agents Are Shifting Competitive Metrics from Token Volume to Task Output
Enterprises are beginning to constrain agent budgets based on how much work is completed. Enterprise cases cited by Goldman Sachs show that heavy AI users consumed ten times as many tokens as other users but generated only twice the output; some companies exhausted their annual AI budgets within four months. Enterprises are therefore shifting their focus from token consumption to daily active agents, agent work units, the number of background automations, and cost per task.
This shift benefits stronger models while exposing the false prosperity of low-cost alternatives. A cheaper model may ultimately have a higher cost per completed task if it requires more retries, longer contexts, or greater human intervention. High-value coding tasks will continue to concentrate among models with higher completion rates, while simpler agent tasks may continue to support multiple models. Investment analysis should track both token volume and output per task; invocation volume alone can overstate revenue quality.
First-party workflows can amplify model advantages into retention. Products such as Z Code and MiniMax Code embed models into code-repository indexing, context management, memory, permissions, tool execution, and testing loops. Joint optimization by model and product teams may give the same model a higher completion rate in its proprietary workflow than through third-party wrappers. Providers thereby gain direct customer relationships and real-world feedback data, while their API calls become harder for routers to replace.
Multimodal Remains One of the Few Areas with Relatively Strong Pricing
Video generation currently has better supply-demand dynamics and margins than general-purpose text. Goldman Sachs expects ByteDance’s Seedance, Kuaishou’s Kling, and MiniMax’s Hailuo/H3 to continue benefiting in the second half from global adoption, feature upgrades, and compute supply shortages. Citing industry sources, the report states that Seedance is operating at an ARR run rate of more than $2 billion with a gross margin of approximately 70%. This figure indicates that features such as native audio, longer videos, storyboarding, and reference inputs can still support differentiated pricing.
Multimodal risks are also more concentrated. Video models entail higher inference costs per generation, while content liability, intellectual property, and generation-safety issues are more pronounced. Future comparisons should assess model Arena scores, per-minute pricing for equivalent specifications, generation time for a five-second 1080p video, and feature breadth together, rather than judging commercial value from a single demo.
Open- vs. Closed-Source Competition, Benchmarks, and the Developer Ecosystem
Open Weights Have Changed Revenue Distribution, Not Eliminated Official APIs
Public weights expand reach, while official endpoints monetize quality and service. JPMorgan notes that a public release is more akin to a checkpoint at a particular point in time, while the official API continues to incorporate post-training, instruction-following improvements, code and tool-use tuning, caching strategies, context handling, and inference-kernel optimization. Seeing the same model name does not mean developers receive the same quality of service.
Simple tasks are more readily displaced by low-cost third-party deployments, while high-value tasks are more sensitive to model freshness, long-context stability, tool use, caching, and service-level agreements. Strong models can continue monetizing through official APIs, officially supported endpoints, cloud-marketplace SaaS, enterprise deployments, and technical support; weaker models are more likely to face high download volumes but low paid conversion.
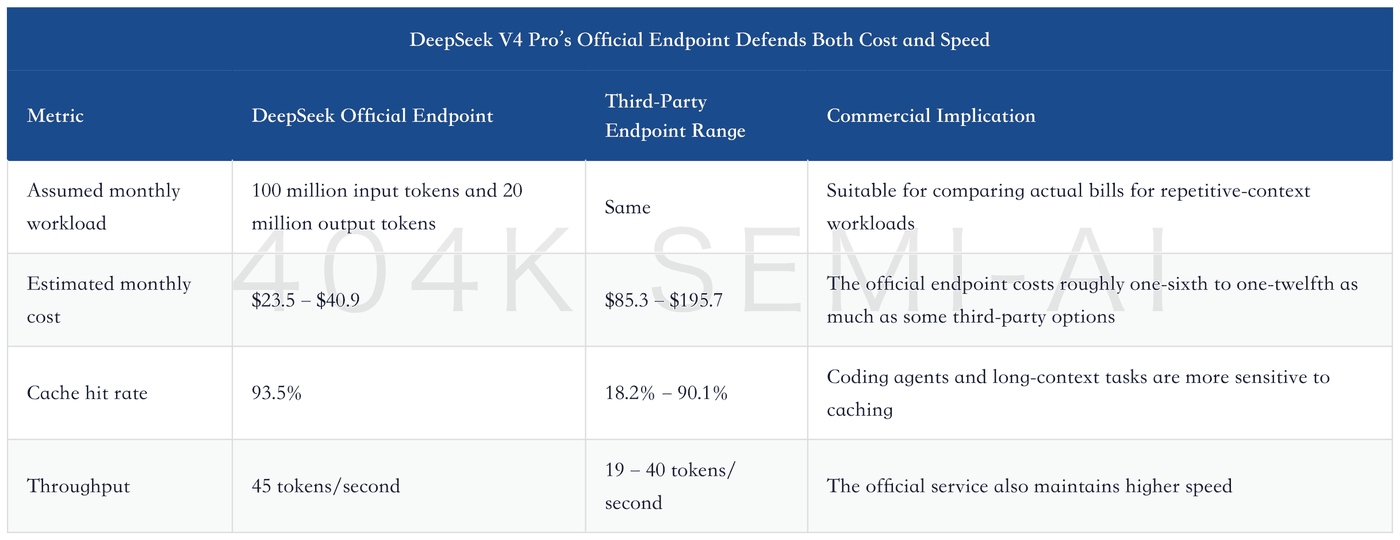
Cache economics gives official endpoints an additional advantage beyond low headline pricing. For coding agents and retrieval-augmented generation, substantial portions of system prompts, repository context, and tool structures recur. Official endpoints have deeper control over both the model and caching strategy, so the effective input price actually paid by customers may be far below the headline rate. Future API price comparisons should prioritize effective cost, completion rate, and stability rather than relying solely on listed prices per million tokens.
Open Source, Open Weights, and Closed Source Are Forming a Tiered Mix
Chinese model providers are applying different licenses by generation and use case. Alibaba’s Qwen family has long followed an open-source strategy, although the highest-performing Qwen-Max remains closed; DeepSeek is closer to permissive open weights; Zhipu uses an open GLM base flagship to expand adoption while retaining Turbo and certain multimodal versions on hosted channels; MiniMax M3 uses a community license with commercial conditions; and ByteDance’s Seed remains closed.
